How React’s Virtual DOM Works Under the Hood

How React’s Virtual DOM Works Under the Hood

You’ve heard it a hundred times: “React uses a Virtual DOM for performance.”

But what does that actually mean?

In this article, we’ll trace exactly what happens from the moment you call setState() to the moment you see pixels update on screen — no hand-waving, no magic, just the mental model that unlocks everything else in React.

Let’s dig in. 🛠️

The Problem: Why Direct DOM Manipulation Is Slow

Before we understand the solution, we need to understand the problem.

The browser’s DOM (Document Object Model) is a live, tree-shaped object that represents your HTML page. Whenever JavaScript changes a DOM node, the browser has to do expensive work:

  • Style recalculation — which CSS rules now apply?
  • Layout / Reflow — what is every element’s new size and position?
  • Repaint — what pixels need to be redrawn?
Direct DOM Update:
─────────────────
JS writes to DOM
     │
     ▼
Style Recalc → Layout (Reflow) → Paint → Composite
                    ↑
               ALL of this, potentially,
               for a single text change 😬

This is fine for occasional updates. But modern web apps update the UI constantly — typed characters, live data feeds, animations. At high frequency, direct DOM manipulation becomes a bottleneck that shows up as janky, sluggish UIs.

The Solution: Virtual DOM as a Lightweight Proxy

React introduces the Virtual DOM: a plain JavaScript representation of the UI tree that exists purely in memory, completely decoupled from the browser’s rendering engine.

// This is a Virtual DOM node. It's just a JS object.
{
  type: 'button',
  props: {
    className: 'btn-primary',
    onClick: handleClick,
    children: 'Click me'
  }
}

Creating this object costs almost nothing. No browser APIs. No layout. No paint. It’s just memory allocation.

React’s insight: compute changes cheaply in JS-land first, then apply the minimal real-DOM mutations in one go.

Step 1 — Initial Render

When your app first loads:

JSX / Components
      │
      │  (Babel compiles JSX to React.createElement calls)
      ▼
Virtual DOM Tree
(plain JS objects, built entirely in memory)
      │
      │  (React walks the tree and creates real nodes)
      ▼
Real DOM  ←  User sees the UI ✅

React calls your component functions, collects the returned JSX (which becomes React.createElement() calls), and assembles a full Virtual DOM tree. It then makes a single full pass to create and insert real DOM nodes.

This is the only time React builds the entire DOM from scratch.

Step 2 — State or Props Change

Something triggers an update:

const [count, setCount] = useState(0);

// Button clicked:
setCount(count + 1);  // 🔔 React queues a re-render

setCount doesn’t immediately update the DOM. React schedules an update and may batch it with other pending updates for efficiency. Then it moves into the render phase.

Step 3 — New Virtual DOM Tree is Created

React re-runs your component function with the new state. The result is a brand new Virtual DOM tree in memory:

 OLD Virtual DOM          NEW Virtual DOM
 ───────────────          ───────────────
 <div>                    <div>
   <h1>Score</h1>   vs      <h1>Score</h1>
   <span>0</span>           <span>1</span>  ← CHANGED
   <button>+</button>       <button>+</button>
 </div>                   </div>

Both trees exist in memory simultaneously. React needs to figure out what’s different.

Step 4 — Diffing (Reconciliation)

React’s diffing algorithm compares the two trees node-by-node to produce a minimal change set.

Comparing node by node:

  <div>        ✅ Same type → keep, recurse into children
  <h1>Score</h1>  ✅ Same type, same props → NO CHANGE
  <span>       ✅ Same type → check props
    "0" → "1"  ❌ Text content changed → MARK FOR UPDATE
  <button>+</button>  ✅ Same type, same props → NO CHANGE

Change set: [ updateTextContent(spanNode, "1") ]

React uses two key heuristics to keep this efficient:

Different element types → rebuild the subtree

If a <div> becomes a <section> at the same position, React doesn’t try to reuse it. It destroys the old subtree and builds a new one.

Keys → stable identity for list items

// ❌ Bad — React can't tell which item is which after reorder
{items.map(item => <li>{item.name}</li>)}

// ✅ Good — React can match, reuse, and correctly update items
{items.map(item => <li key={item.id}>{item.name}</li>)}

Keys let React correlate old list nodes with new ones. Without them, React might destroy and re-create nodes it could have reused — wasting work and losing local state (like focus or scroll position).

Step 5 — Commit Phase: Minimal Real DOM Updates

Once the diff is done, React enters the commit phase — the only point where it writes to the real DOM:

Change set from diff:
┌──────────────────────────────────────┐
│  • Update text of <span>: 0 → 1     │
│  (1 operation total)                 │
└──────────────────────────────────────┘
         │
         ▼
  Real DOM ← only the <span>'s text node is touched
  Everything else: untouched, no reflow triggered 🎯

Compare this to a naive approach that re-renders the entire list after every keystroke. With React, only the nodes that actually changed are touched.

Why This Improves Performance

Approach What Happens on Update
Direct DOM manipulation Write immediately → browser reflows everything potentially affected
React Virtual DOM Diff in memory → write only changed nodes → minimal browser work

The Virtual DOM isn’t magic. Creating JS objects has a cost too. The real win is batching and minimization: React figures out the cheapest path from the current UI to the desired UI, then executes it in one optimized burst.

The Full Lifecycle — Visual Summary

┌────────────────────────────────────────────────────────┐
│            REACT: RENDER → DIFF → COMMIT               │
│                                                        │
│  setState() / new props                                │
│       │                                                │
│       ▼                                                │
│  ┌─────────────────────────────────────┐               │
│  │         RENDER PHASE                │               │
│  │  Component functions run            │               │
│  │  New Virtual DOM tree built         │               │
│  └──────────────┬──────────────────────┘               │
│                 │                                      │
│                 ▼                                      │
│  ┌─────────────────────────────────────┐               │
│  │      RECONCILIATION (DIFF) PHASE    │               │
│  │                                     │               │
│  │  Old VDOM ◄──── compared ────► New VDOM             │
│  │  Minimal change set computed        │               │
│  └──────────────┬──────────────────────┘               │
│                 │                                      │
│                 ▼                                      │
│  ┌─────────────────────────────────────┐               │
│  │         COMMIT PHASE                │               │
│  │  Only changed nodes written to DOM  │               │
│  │  useLayoutEffect runs               │               │
│  └──────────────┬──────────────────────┘               │
│                 │                                      │
│                 ▼                                      │
│  Browser paints minimal changes ✅                     │
│  useEffect runs                                        │
└────────────────────────────────────────────────────────┘

Quick Reference: Key Concepts

Concept What It Means
Virtual DOM Plain JS object tree mirroring the UI — cheap to create
Re-render React calling your component function again to get new VDOM
Diffing Comparing old VDOM vs new VDOM to find changes
Reconciliation The full process: diff + decide what to update
Commit The moment React writes to the real DOM
Key Stable identity hint for list items during diffing

Things to Know (But Out of Scope Here)

  • React Fiber — React’s internal concurrent scheduler that adds priority lanes and time-slicing on top of this model
  • React 18 Concurrent Mode — useTransition and useDeferredValue let you mark updates as non-urgent
  • React.memo — skips re-render (and therefore skips VDOM creation) when props haven’t changed

Wrapping Up

React’s Virtual DOM is elegant in its simplicity: represent the UI as cheap JS objects, compare states, compute minimal mutations, apply them. The render → diff → commit pipeline is the foundation of React’s performance story — and once you have this mental model, concepts like key, memo, and concurrent features all start making intuitive sense.

If this clicked for you, follow along — next up we’re diving into React Keys deep dive and why index-as-key breaks your app in surprising ways.

Happy coding! ⚛️

Tagged: #react #javascript #webdev #beginners

Build a Dropbox Paper-Style Collaborative Editor with Next.js and Velt💥

Velt landing page

Introduction

Modern apps need built-in collaboration. Users expect to comment on text, see who is online, and receive updates without switching tools. If your editor lacks these features, discussions move to Slack or email. Context gets lost. Engagement drops.

In this guide, we will build a Dropbox Paper-style collaborative editor. You will add inline comments to selected text, show real-time presence, and enable in-app notifications. The stack uses Next.js with the App Router, TipTap for rich text editing, and Velt for collaboration infrastructure.

Building real-time collaboration from scratch is complex and time-consuming. Tools like Velt abstract that complexity so you can focus on product logic instead of infrastructure.

By the end, you will have a fully working collaborative editor running locally.

Tech Stack Overview

This project uses a modern React-based stack built for real-time interaction. Each tool has a clear responsibility and works well in collaborative environments.

  • Next.js (App Router): Provides the application structure and routing layer. The App Router makes it easy to organize layouts, wrap the app with providers, and manage client components cleanly.
  • TipTap Editor: A highly extensible rich text editor built on ProseMirror. It allows precise control over marks and extensions, which makes it ideal for inline commenting and collaborative annotations.
  • Velt SDK: Handles real-time comments, presence, notifications, and collaboration state. It abstracts the backend complexity required for multi-user interaction.
  • Tailwind CSS + shadcn/ui: Enables fast UI development with consistent styling and accessible components.
  • Zustand: Manages lightweight global state, such as switching between predefined users for collaboration simulation.

Project Structure Walkthrough

Before diving into the implementation, it helps to understand how the project is organized. The structure separates layout, collaboration logic, and UI components so each concern stays isolated.

  • app/ — Layout and Velt Initialization

    Contains the root layout and App Router setup. This is where VeltProvider wraps the application and initializes the SDK with your API key and active user.

  • components/ — UI and Core Features

    Holds the main building blocks of the interface, including the editor and the top navigation bar.

  • paper-document.tsx — TipTap + Velt Integration

    Implements the rich text editor and registers the Velt TipTap extension. This file handles rendering comments and adding new ones to selected text.

  • top-bar.tsx — Presence, Notifications, Sidebar Controls

    Displays active users, shows notifications, and provides access to the comments sidebar.

  • helper/userdb.ts — User Switching Logic

    Uses Zustand to manage predefined users and simulate multi-user collaboration.

What is Velt?

Velt is a collaboration SDK that lets you add real-time features like comments, presence, and notifications directly into your product. Instead of building backend infrastructure for multi-user sync, conflict resolution, and event handling, you integrate Velt components and ship collaboration features in days.

Velt landing page

Below are the key features used in this project:

  • Contextual Comments: Add inline comments to specific UI elements or selected text. Comments stay attached to their exact position, enabling precise discussions inside the app.
  • Real-Time Presence: Show who is currently viewing or interacting with the document. Presence indicators update instantly across users.
  • Notifications System: Trigger in-app notifications for mentions, replies, and updates. Keeps users informed without leaving the product.
  • Comments Sidebar: Centralized panel to view, manage, and navigate all comment threads within the document.
  • Multi-User Collaboration Support: Handles user identity, ownership of comments, and live updates so multiple users can interact with the same document seamlessly.

Local Setup (Quick Start)

First, install the Velt client SDK:

npm install @veltdev/client

Velt must be initialized at the root of your application so every component can access the collaboration state. In a Next.js App Router project, this means wrapping your app inside VeltProvider in the root layout.

Create a .env file in the root directory and add your Velt API key:

NEXT_PUBLIC_VELT_ID = your_velt_api_key_here

velt dashboard

Clone the repository and install the dependencies:

git clone https://github.com/Studio1HQ/dropbox-velt.git
cd dropbox-velt
npm install

Start the development server:

npm run dev

Open http://localhost:3000 in your browser.

Dropbox paper UI

If you’re using Velt Agent Skills or MCP-based setup, manual installation steps can be skipped since the AI handles SDK wiring and configuration. This demo uses the standard manual SDK integration.

Wrapping the App with VeltProvider

Before integrating Velt features into the editor, Velt must be available across the application. In this project, the provider is added inside the root layout so every component can access collaboration features.

This setup lives in app/layout.tsx. The VeltProvider wraps the entire app and receives the API key from the environment variable. The ThemeProvider is nested inside it so both theme and collaboration context are globally available.

The provider must sit at the top level because presence, comments, and notifications rely on shared context. If it is mounted deeper in the tree, some components will not receive real-time updates.

"use client";

import { ThemeProvider } from "@/hooks/use-theme";
import { VeltProvider } from "@veltdev/react";

export default function RootLayout({
  children,
}: {
  children: React.ReactNode;
}) {
  return (
    <VeltProvider apiKey={process.env.NEXT_PUBLIC_VELT_ID || ""}>
      <ThemeProvider>{children}</ThemeProvider>
    </VeltProvider>
  );
}

Now that Velt is initialized globally, we can integrate it directly into the TipTap editor.

Adding Inline Comments to TipTap

The core collaboration logic lives inside components/paper-document.tsx. This file initializes the TipTap editor and connects it to Velt using the TipTap comments plugin.

"use client";

import { useEditor, EditorContent, BubbleMenu } from "@tiptap/react";
import { StarterKit } from "@tiptap/starter-kit";
import {
  TiptapVeltComments,
  renderComments,
  addComment,
} from "@veltdev/tiptap-velt-comments";
import { useCommentAnnotations } from "@veltdev/react";
import { useEffect } from "react";

import { Avatar, AvatarFallback } from "./ui/avatar";
import { Separator } from "./ui/separator";
import { Button } from "./ui/button";
import {
  MessageCircle,
} from "lucide-react";

const EDITOR_ID = "paper-document-editor";

Start by installing @veltdev/tiptap-velt-comments. This package bridges TipTap’s editor state with Velt’s comment system. Once installed, register the TiptapVeltComments extension inside the editor configuration. This enables comment marks on selected text and connects them to Velt’s backend.

Each editor instance must have a unique editor ID. In this project, a fixed document ID is used so comments stay tied to the same document across sessions.

App editor UI

When the editor loads, renderComments syncs and displays existing annotations from Velt. When a user selects text and clicks the comment action in the bubble menu, addComment creates a new contextual thread linked to that selection.

The bubble menu integration ensures users can comment directly on highlighted text. This creates a Google Docs-style inline commenting experience inside your own app.

export function PaperDocument() {
  const editor = useEditor({
    extensions: [
      StarterKit,
      TiptapVeltComments.configure({
        persistVeltMarks: false,
      }),
    ],
    content: {
      type: "doc",
      content: [
        {
          type: "paragraph",
          content: [
            {
              type: "text",
              text:
                "This document contains all the essential information and resources for our current project. Feel free to add comments, suggestions, or ask questions using the tools on the right.",
            },
          ],
        },
        {
          type: "heading",
          attrs: { level: 2 },
          content: [{ type: "text", text: "Overview" }],
        },
        {
          type: "paragraph",
          content: [
            {
              type: "text",
              text:
                "Our team is working on creating a comprehensive solution that addresses the key challenges in collaborative document editing and file sharing. This project aims to deliver a seamless experience for teams of all sizes.",
            },
          ],
        },
        {
          type: "heading",
          attrs: { level: 2 },
          content: [{ type: "text", text: "Key Features" }],
        },
        {
          type: "bulletList",
          content: [
            {
              type: "listItem",
              content: [
                { type: "paragraph", content: [{ type: "text", text: "Real-time collaboration with team members" }] },
              ],
            },
            {
              type: "listItem",
              content: [
                { type: "paragraph", content: [{ type: "text", text: "Inline comments and feedback" }] },
              ],
            },
            {
              type: "listItem",
              content: [
                { type: "paragraph", content: [{ type: "text", text: "Version history and rollback capabilities" }] },
              ],
            },
            {
              type: "listItem",
              content: [
                { type: "paragraph", content: [{ type: "text", text: "Secure sharing with granular permissions" }] },
              ],
            },
          ],
        },
        {
          type: "heading",
          attrs: { level: 2 },
          content: [{ type: "text", text: "Timeline" }],
        },
        {
          type: "paragraph",
          content: [
            {
              type: "text",
              text:
                "The project is divided into multiple phases, each with specific deliverables and milestones. We're currently in Phase 2, focusing on core functionality and user experience improvements."
            },
          ],
        },
        {
          type: "heading",
          attrs: { level: 2 },
          content: [{ type: "text", text: "Resources" }],
        },
        {
          type: "paragraph",
          content: [
            {
              type: "text",
              text:
                "Below you'll find all the files and documents related to this project. Click on any item to preview or download it."
            },
          ],
        },
      ],
    },
    autofocus: false,
    immediatelyRender: false,
  });

Adding Presence & Notifications

Collaboration is not just about comments. Users need awareness and updates in real time. In this project, these features are implemented inside components/top-bar.tsx and connected to the editor view.

"use client";
import {
  useVeltClient,
  VeltCommentsSidebar,
  VeltNotificationsTool,
  VeltPresence,
  VeltSidebarButton,
} from "@veltdev/react";

import { names, userIds, useUserStore } from "@/helper/userdb";
import { Rocket, Share, User } from "lucide-react";
import React, { useEffect, useMemo, useRef } from "react";
import {
  DropdownMenu,
  DropdownMenuContent,
  DropdownMenuItem,
  DropdownMenuLabel,
  DropdownMenuSeparator,
  DropdownMenuTrigger,
} from "@/components/ui/dropdown-menu";
import { Avatar, AvatarFallback, AvatarImage } from "@/components/ui/avatar";
import { FileText, Share2, MoreHorizontal, ChevronDown } from "lucide-react";
import { Button } from "./ui/button";
import useTheme, { ThemeToggleButton } from "@/hooks/use-theme";

VeltPresence displays the users currently viewing the document. It renders active user avatars in the top bar and updates instantly when someone joins or leaves. This gives immediate visibility into who is online and working on the same content.

Velt presence in action

VeltNotificationsTool adds an in-app notification system. It surfaces mentions, replies, and comment activity without requiring page refreshes. Users stay informed while remaining inside the document.

Velt notification in action

VeltSidebarButton toggles the comments panel. When clicked, it opens VeltCommentsSidebar, which lists all comment threads in one place. Users can review discussions, jump to specific annotations, and manage conversations efficiently.

Velt sidebar

export function TopBar() {
  const { theme } = useTheme();
  const { user, setUser } = useUserStore();
  const { client } = useVeltClient();
  const prevUserRef = useRef(user);
  const isInitializingRef = useRef(false); // Prevent overlapping initialization calls

  const predefinedUsers = useMemo(
    () =>
      userIds.map((uid, index) => {
        const avatarUrls = [
          "https://api.dicebear.com/7.x/pixel-art/svg?seed=Nany",
          "https://api.dicebear.com/7.x/pixel-art/svg?seed=Mary",
        ];
        return {
          uid: uid,
          displayName: names[index],
          email: `${names[index].toLowerCase()}@gmail.com`,
          photoUrl: avatarUrls[index],
        };
      }),
    []
  );

  // Initialize user from localStorage if none exists
  useEffect(() => {
    if (typeof window !== "undefined" && !user) {
      const storedUser = localStorage.getItem("user-storage");
      if (!storedUser) {
        setUser(predefinedUsers[0]);
      }
    }
  }, [user, setUser, predefinedUsers]);

  // Handle Velt client initialization, user identification, and document setting
  useEffect(() => {
    if (!client || !user || isInitializingRef.current) {
      console.log("Velt init skipped:", {
        client: !!client,
        user: !!user,
        initializing: isInitializingRef.current,
      });
      return;
    }

    const initializeVelt = async () => {
      isInitializingRef.current = true;
      try {
        // Detect user switch
        const isUserSwitch = prevUserRef.current?.uid !== user.uid;
        prevUserRef.current = user;

        console.log("Starting Velt init for user:", user.uid, { isUserSwitch });

        // Re-identify the user (handles initial and switches)
        const veltUser = {
          userId: user.uid,
          organizationId: "organization_id",
          name: user.displayName,
          email: user.email,
          photoUrl: user.photoUrl,
        };
        await client.identify(veltUser);
        console.log("Velt user identified:", veltUser.userId);
        await client.setDocuments([
          {
            id: "drop-box-velt",
            metadata: { documentName: "drop-box-velt" },
          },
        ]);
        console.log("Velt documents set: drop-box-velt");
      } catch (error) {
        console.error("Error initializing Velt:", error);
      } finally {
        isInitializingRef.current = false;
      }
    };

    initializeVelt();
  }, [client, user]); // Re-run on client or user change

Together, these components create a real-time collaborative environment with visibility, context, and structured discussion.

Multi-User Switching (Simulating Collaboration)

To demonstrate collaboration locally, this project simulates multiple users using a simple state store. The logic lives inside helper/userdb.ts, where predefined users like Nany and Mary are defined with unique IDs and avatars.

The store is built with Zustand. It keeps track of the currently active user and exposes a method to switch between them. When you select a different user from the dropdown in components/top-bar.tsx, the active user state updates instantly.

Because VeltProvider receives the current userId, switching users changes how Velt identifies the session. Presence indicators update automatically, and new comments are attributed to the selected user. Existing comments also display correct ownership based on user identity.

This setup allows you to test real-time presence, comment ownership, and notification behavior on localhost without needing multiple devices or accounts.

import { create } from "zustand";
import { persist } from "zustand/middleware";

export type User = {
  uid: string;
  displayName: string;
  email: string;
  photoUrl?: string;
};

export interface UserStore {
  user: User | null;
  setUser: (user: User) => void;
}

export const userIds = ["user001", "user002"];
export const names = ["Nany", "Mary"];

export const useUserStore = create<UserStore>()(
  persist(
    (set) => ({
      user: null,
      setUser: (user) => set({ user }),
    }),
    {
      name: "user-storage",
    }
  )
);

Our final app UI

How Everything Works Together

At a high level, the editor, Velt SDK, and UI components form a connected real-time collaboration loop. Each layer has a clear responsibility, but they operate as a single system.

  • Editor → Velt Plugin → Comments

    The TipTap editor in components/paper-document.tsx registers the Velt comments extension. When a user selects text and adds a comment, the plugin sends the annotation to Velt. Velt syncs it across sessions, and the editor renders it inline.

  • User Change → Presence Update

    The active user is managed in helper/userdb.ts. When switching users from components/top-bar.tsx, the userId passed to VeltProvider changes. Velt immediately updates presence and ensures new comments reflect the correct ownership.

  • Comment → Sidebar → Notification

    When a comment is created, it appears inline and is listed inside VeltCommentsSidebar, and triggers updates in VeltNotificationsTool. All views stay synchronized in real time.

  • Provider → SDK Lifecycle

    VeltProvider in app/layout.tsx manages initialization and global collaboration state. It maintains the real-time connection and ensures all components receive updates consistently.

Demo

Final Result & Takeaways

We built a Dropbox Paper-style collaborative editor with inline comments, real-time presence, and in-app notifications. The entire collaboration layer runs inside the product without relying on external tools. Instead of building real-time infrastructure from scratch, Velt handles synchronization, ownership, and updates. This pattern applies to CMS platforms, dashboards, internal tools, document editors, and any product that needs structured collaboration.

If you are building a collaborative feature, try integrating Velt and ship production-ready comments, presence, and notifications in days instead of months.

Resources

Holy Typos, Batman! How I Built ‘SpellJump’

Hey everyone! 👋

“Kabhi kabhi lagta hai apun hi bhagwan hai,” especially when your code compiles on the very first try. But then, you look at your docstrings, variable names, and READMEs, and realize they are absolutely full of spelling mistakes. Yep, that was me.

I was spending too much time manually hovering and clicking on those annoying red lines. I wanted a tool that didn’t just passively highlight errors, but actively jumped to them like the Batmobile responding to a signal. So, I built SpellJump — an AI-powered typo jumper for VS Code and Cursor.

💡 How I Got the Idea Standard spell checkers feel slow and boring. I wanted a blazing-fast, offline-first tool that let me jump from typo to typo using a simple Ctrl+Shift+J shortcut. And because “Why so serious?”, I decided to bake in some hidden DC Batman Easter Eggs. (Seriously, type “batman” or “gotham” in your editor with the extension on, and see what happens! 🤫)

I built the core extension using TypeScript and the VS Code Extension API. The biggest “Moye Moye” moment during development was handling real-time text document synchronization. You type fast, and the extension needs to parse the text, find typos, and update the Problems panel and wavy underlines instantly—all without lagging the editor. Figuring out the exact text-range mappings while maintaining peak performance was a solid headache.

🧠 Putting my Linux & AI/ML to Work For the core logic, I started with nspell for a fast, offline baseline. But I wanted to push the boundaries with AI. Here is how I utilized my ML and Linux environment for Phase 2:

I fired up my Linux terminal and wrote Python scripts to generate a synthetic dataset of 2,000+ common developer typos.
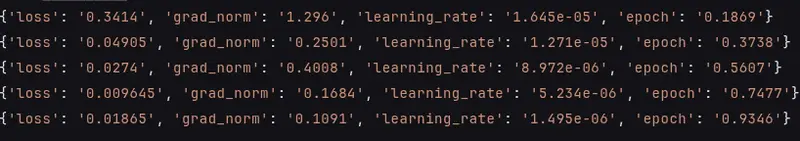
I trained a baseline model and then brought out the big guns: fine-tuning a DistilBERT model using PyTorch and Hugging Face.
I ran the training workloads in the background using good ol’ nohup

(my train.log file was my best friend for days).
The real trick: You can’t just run heavy PyTorch models inside VS Code without eating up all the RAM. So, I exported the trained model to an ONNX format (spelljump.onnx). Now, it runs locally, completely offline, and lightning-fast!
🚀 Deployment & The 10-Day Milestone When it came to publishing, I chose Open VSX—the open-source alternative to the Microsoft Marketplace that powers editors like Cursor and VSCodium.

Deploying was incredibly smooth. No massive corporate hoops to jump through. All I needed was a GitHub account, the ovsx CLI, and my .vsix package. One command (ovsx publish), and it was live.

And the response? In just 10 days of deployment, SpellJump crossed 185+ downloads! Seeing developers around the world actively use a tool I built from scratch is a feeling better than seeing the Bat-Signal light up the sky.

“It’s not who I am underneath, but what I do that defines me.” And right now, what I do is help you fix your typos faster. 😂

If you use VS Code or Antigravity , give it a spin, try to find the Easter eggs, and let me know your thoughts!

🔗 Check it out on Open VSX: https://open-vsx.org/extension/prakhar-iitj/spelljump#review-details 🔗 Source Code on GitHub: https://github.com/Prakhar54-byte/spelljump

VSCode #Cursor #TypeScript #MachineLearning #OpenSource #OpenVSX #DevOps #BuildInPublic #Batman #DeveloperTools

How to Test Frontend Error States Without Breaking Your Backend

Frontend teams are usually pretty good at testing the happy path. The API returns 200. The response shape is correct. The list has data. The network is fast enough. The user sees the page we designed.

Great.

But products do not live only in the happy path.
They live in all the awkward states around it:

  • the endpoint returns 500
  • the list is empty
  • the request is slow
  • the response is malformed
  • the token expired
  • the user has no permissions
  • staging data changed again
  • the backend endpoint is not ready yet

These states are often where the UI becomes the most important. They are also the states that are hardest to reproduce on demand.

The problem with relying on staging

A lot of teams treat staging as the place where frontend edge cases should be tested. In theory, that makes sense. In practice, staging is rarely in the exact state you need.

  • Maybe you need an empty list, but staging has 400 items.
  • Maybe you need the API to return a 500, but the backend is currently healthy.
  • Maybe you need a slow response to test loading behavior, but the request is too fast.
  • Maybe you need a specific permission error, but nobody wants to mutate test data or add a temporary backend flag just so you can check one UI state.

So the frontend workaround begins.

Common workarounds

There are a few common ways to deal with this.

1. Mock servers
Mock servers are powerful. They are great when you need shared contracts, stable fake environments, or a full backend replacement during development. But they can also be heavy when the task is small.

Sometimes you do not need a full mock environment. You just need this one request to return an empty array for ten minutes while you fix a UI. Setting up a mock server for that can feel like too much ceremony.

2. Local fixtures
Local fixtures are fast and simple.

You create a JSON file, import it somewhere, and render the UI against that data.

This works well for isolated components. But it gets harder when the behavior depends on the actual network flow of the app: auth, routing, loading states, retries, request timing, headers, or runtime conditions.

Fixtures can also drift from real API responses over time.

3. Backend flags or test endpoints
Sometimes the backend team can add a flag, seed special data, or expose a test endpoint. That can be useful, especially in mature teams. But it also creates coordination overhead. The frontend developer has to ask for the state, wait for it, and hope it still exists when QA or design tries to reproduce the same thing later.

4. Browser hacks
We have all done some version of this. Add a temporary throw. Edit code in DevTools. Comment out a fetch call. Hardcode a response. Change a local branch just to force an error state.

It works, but it is fragile. It is also easy to forget, hard to share, and not something you want to rely on for repeatable testing.

A lighter workflow: override the response locally

For many frontend tasks, the ideal workflow is smaller:

  1. Open the app.
  2. See the real request the app is making.
  3. Choose the request you want to control.
  4. Return the response you need.
  5. Reload and test the UI.

No backend change. No proxy setup. No full mock server. No app code changes.
Just one local override for one real browser request.
That is the workflow I have been thinking about while building Ruse.

Example states worth testing

Here are a few states I think every production UI should be easy to test.

Empty list

{
  "items": []
}

Does the UI show a thoughtful empty state? Is the CTA correct? Does the layout collapse awkwardly? Does pagination disappear?

Server error

{
  "error": "Internal server error"
}

Does the page recover? Can the user retry? Is the message useful? Does the app accidentally show a blank screen?

Slow response
A slow API often reveals problems that fast local development hides.

Do loading indicators appear? Do buttons stay disabled? Does the page jump when data arrives? Can the user trigger duplicate actions?

Malformed response

{
  "items": null
}

This is where defensive UI code gets tested.

Does the app fail gracefully, or does one unexpected value take down the entire screen?

Permission error

{
  "error": "You do not have access to this resource"
}

Permission states are product states too. They need design, copy, and behavior.

Why browser-level mocking is useful

Mocking at the browser level is interesting because it starts from what your app is actually doing.

You are not inventing a request from memory. You are not manually recreating the URL, method, and response shape from scratch. You are looking at real traffic and deciding: “for this request, return this instead.”

That makes the loop feel more natural for frontend work.

It is especially useful when you are:

  • building UI before the backend is complete
  • testing error states
  • preparing stable demos
  • reproducing QA bugs
  • checking loading behavior
  • designing empty states
  • working against flaky staging data

Where Ruse fits

I am building Ruse as a Chrome extension for this workflow.

The idea is simple:

  • inspect browser requests
  • create local mock rules
  • return custom responses
  • test the UI state you need
  • keep everything local in the browser
    The first release is intentionally small and local-first. It is not trying to be a full API platform. It is focused on making the first useful mock fast.

Ruse is currently in alpha and going through Chrome Web Store review.

If this workflow sounds useful, I am looking for early testers:

https://ruse.dev/support?topic=early-access

Final thought

Frontend edge cases should not require a backend meeting.

Sometimes you need a full mock server. Sometimes you need contract testing. Sometimes you need proper seeded environments.

But sometimes you just need one request to return one different response so you can finish the UI in front of you.

That small loop is worth making better.

A .NET Dinosaur in Web3. Day 8 — Reading & Writing — WishList Chain

Long time no see.

The dinosaur was a bit busy finishing a module on .NET Windows Forms. To be honest, it’s not my favourite stack — I’m much more into web development — but it’s part of the job.

Now that I’m done with those tasks, I can finally get back to my favourite projects and the whole learn-in-public vibe.

Intro

Day 8 of trying to get into Web3 turned out to be an amazing experience.

It didn’t feel like just another step where you “add a feature and move on.” It felt more like a point where the system actually starts behaving like a system.

From Reading to Writing

Reading from the blockchain feels almost like calling a regular API. You ask for data, you get data, you render it.

Writing introduces a completely different flow.

Now there’s a wallet involved. The user has to confirm the action. The transaction is sent to the network, included in a block, and only then reflected in the UI — and you don’t control that timeline anymore.

At that point it became obvious that building a UI for Web3 is not just about displaying data. It’s about handling uncertainty, delays, and state that lives somewhere outside of your application.

Weird Environment Reality

It seems I might need a more modern laptop — my MacBook almost gave up because of Turbopack. I used it initially, but it was consuming far more resources than expected.

Nothing critical — I switched back to good old webpack.

But if you’re working on an older machine, it’s definitely something to be aware of.

Reality of Building UI

The UI is no longer just reactive — it becomes dependent on external events:

  • the user confirms the transaction (or not)
  • the network processes it
  • the block is mined
  • the state becomes available
    And only then can your UI reflect what actually happened.

This introduces a different kind of thinking. You’re not just updating state — you’re waiting for the system to converge.

Things That Actually Matter

There was a moment where the transaction clearly went through — MetaMask confirmed it — but the UI still showed “No goals yet.”

The contract state had changed, but nothing triggered a refetch on the frontend. From the UI perspective, nothing happened.

And then there was the more serious one.

At some point I realised I was sending transactions to the wrong contract address.

Everything looked correct. MetaMask confirmed the transaction. No errors. No warnings.

And that’s exactly the problem.

In Web3, if you send a transaction to the wrong address — it doesn’t fail in a helpful way. It just… succeeds somewhere else.

There’s no backend validation, no “wrong destination” error. The transaction goes through, and from the system’s perspective — everything is fine.

But your funds are gone.

In my case it was just a test transaction — nothing critical — but it was a very clear reminder: double-check addresses. Every time.

The Moment

And then it all came together.

First goal created. First donation sent. DreamPower increased.

Balance changed. Progress updated. State reflected in the UI.

End-to-end:

MetaMask → smart contract → Sepolia → frontend

At that point it stopped feeling like a collection of separate parts and started feeling like a real system.

What Clicked

The biggest shift for me was understanding that in this setup, the blockchain is not just another service.

It is the backend.

There’s no API layer translating requests. The frontend talks directly to the contract, and that removes an entire layer of abstraction I’m used to in .NET systems.

It also means that things like latency, consistency, and state management behave differently — and you have to design with that in mind.

One More Question

At some point I also started thinking about limits.

How many users can this support? How many goals can a contract realistically store?

Technically — a lot. Practically — every write costs gas, and large reads eventually hit limits. It’s not something that matters right now, but it’s definitely something that will matter later.

Stage: Dinosaur 🦕 — first full interaction. Not just reading. Not just UI. A system that reads, writes, and reacts.

Repo: github.com/alena-dev-soft/wish-list-chain

Follow the journey on Telegram: t.me/dotnetToWeb3

Building AI Digital Employees with Markus: An Open-Source Platform for Agent Teams

What is Markus?

Markus is an open-source platform (AGPL-3.0) for building, deploying, and managing AI agents that work collaboratively — like a real engineering team. Think of it as an operating system for AI digital employees.

Unlike closed AI platforms that lock you into a single provider, Markus lets you bring your own LLM (OpenAI, Anthropic, local models, any OpenAI-compatible API) and design agents with distinct roles, skills, and communication patterns.

Why Markus?

Here is what makes Markus different from other AI agent frameworks:

1. Agent-First Architecture

Each agent in Markus has a defined role, a stack of skills, and structured communication protocols. They do not just chat — they break down complex tasks, work in parallel, and deliver results autonomously.

2. Multi-Provider, No Lock-In

Use any LLM provider you want. OpenAI, Anthropic, Google Gemini, local models via Ollama — the platform abstracts the underlying model so you can switch providers per agent or even per task. No vendor lock-in, no per-seat fees.

3. Human-in-the-Loop, Not Human-as-the-Bottleneck

Markus is designed for supervised autonomy. Agents execute tasks, but humans review, approve, and guide. The platform automatically routes work through a review cycle: agents write code, submit for review, a reviewer approves or requests changes.

4. Extensible Skill System

Skills are Markus’s superpower. The skill marketplace includes 20+ skills for browser automation, creative work, data analysis, and more. You can also build your own in minutes.

5. Memory That Actually Learns

Markus agents have a three-layer memory system: an observation buffer for raw insights, curated long-term knowledge for validated procedures, and episodic recall for past task context. Dream cycles automatically consolidate and prune memories.

Quick Start

Clone the repo, install dependencies with pnpm, configure your LLM in .env, and run pnpm dev. Visit http://localhost:3000 to see your AI team in action.

Why Open Source Matters

Markus is open source (AGPL-3.0), self-hosted, and community-driven. Your data stays on your infrastructure.

Try It Today

Star the repo: https://github.com/markus-global/markus
Join the community: https://markus.global

The Auditor — High-Reasoning Synthesis and the Ethics of Governance

Architectural diagram of the Sovereign Auditor synthesis layer. It shows data flowing from the Librarian (archival data) and The Eye (local vision) into a Reasoning Engine, which then passes through a Guardian HITL gate before generating a final report.

In previous steps, we gave our system Eyes (Local Vision) and a Shield (The Redactor). But a list of findings is not an audit. To provide true value, a forensic system must synthesize disparate data points into a definitive Verdict.

Today, we introduce the final architectural layer: The Auditor and a new, hardened Guardian.

The Auditor: Moving from “Assistant” to “Expert”

Most AI implementations treat the LLM as a general-purpose assistant. In the Sovereign Vault, we use Persona Injection to transform the model into a Senior Forensic Bibliographer.

The Auditor’s job is Synthesis. It cross-references:

  • The Librarian’s Ground Truth: Archival metadata from our Master Bibliography.
  • The Eye’s Perception: Local visual findings, including handwritten inscriptions.
  • The System’s Thresholds: Programmatic rules that define what constitutes a “Match” or a “Forgery.”

The Guardian Pattern: The Human-in-the-Loop

One of the greatest risks in Enterprise AI is Autonomous Overreach. We cannot allow an AI to autonomously finalize a $50,000 transaction. To solve this, we implemented the Guardian Pattern—a mandatory governance gate.

When the system detects a HIGH-severity discrepancy, it triggers a hardware-level pause:

🔴 HIGH SEVERITY FINDING: [High] points_of_issue: expected 'lowercase "j"...' vs observed 'pencil inscription'
Authorize this finding to finalize report? (y/n):

This ensures that while the AI does the heavy lifting of perception and synthesis, the Human Auditor remains the ultimate authority.

Proving Accuracy: The Judge

We move beyond ‘vibe-checking’ our Auditor by implementing the LLM-as-a-Judge framework.

Every architectural change is audited against a Golden Dataset—a ground-truth set of forensic cases—to ensure that our “hardened” logic actually increases accuracy without introducing regression.

The Final Verdict: Circuit-Breaker Logic

To ensure 100% reliability, the “Code” and the “Brain” must agree on the verdict. We implemented Deterministic Circuit-Breakers in our report generator. Even if the AI is “confident,” the code enforces a hard fail if critical indicators are missing:Python# The Auditor’s Programmatic Circuit-Breaker

if num_high > 0:
    verdict = "Authentication not supported — HIGH-severity discrepancies indicate forgery risk."
    confidence = min(confidence, 40) # Force a penalty for risks

Final System Architecture

Architectural diagram of the Sovereign Auditor synthesis layer. It shows data flowing from the Librarian (archival data) and The Eye (local vision) into a Reasoning Engine, which then passes through a Guardian HITL gate before generating a final report.
The “Zero-Glue” Synthesis: The Auditor acts as the central nervous system, merging local perception with archival ground-truth while governed by the Guardian handshake.

The Shield is up. The Verdict is in.

We have successfully built the Sovereign Vault. By combining local perception, edge security, and high-reasoning synthesis, we have moved from “prompt-engineered assistants” to a governed Expert System

But beyond the code, what does this mean for the industry? In our final strategic wrap-up, we look at the “Big Picture”: Why the Model Context Protocol is the strategic “USB-C” for the next decade of Enterprise AI.

Coming Next: The Sovereign Vault: Why MCP is the USB-C for Enterprise AI.

Building ‘Offline Brain’: How I Wrote My First Custom Agent Skill for Android (Google I/O 2026) 📱🧠

This is a submission for the Google I/O Writing Challenge

The Sandbox Revolution 🚀

When the Google I/O 2026 keynotes dropped, the internet immediately started buzzing about Gemini and cloud-scale model reasoning. But as a mobile developer, the most paradigm-shifting announcement was much quieter: Agent Skills support in Google AI Edge Gallery.

We aren’t just talking about chatbots anymore. Google has effectively dropped a full-fledged agent runtime—powered by the new LiteRT-LM engine and a massive 32K context window via Gemma-4-E2B-it—directly into our pockets.

I wanted to see just how deep this rabbit hole went. Instead of just testing the built-in integrations, I decided to build one myself. Here is a hands-on walkthrough of how I built and sideloaded “Offline Brain”, a custom on-device Agent Skill that stores and retrieves personal development notes without a single byte ever touching a server.

Why Local Agents Change the Game 🔒

Before we write code, we need to understand why this matters.

Historically, if you wanted an AI to read your daily diary or check your private health logs, you had to proxy that data through an API. With Edge Gallery’s new architecture, you can import a Local Skill directly from your device storage. The inference happens on your silicon. The tool execution happens in your local sandbox.

This is the holy grail of privacy: Zero-Trust Agents.

Step 1: The Skill Manifest

Building a skill for Edge Gallery doesn’t require compiling an Android APK. Instead, Google has adopted an open standard very similar to the Model Context Protocol (MCP), but optimized for mobile sandbox execution.

Everything starts with a single JSON file. I created offline-brain.json:

{
  "skill_id": "com.developer.offline_brain",
  "name": "Offline Brain",
  "description": "Store and retrieve encrypted development notes locally.",
  "version": "1.0.0",
  "permissions": [
    "storage.read_local",
    "storage.write_local"
  ],
  "tools": [
    {
      "name": "save_note",
      "description": "Saves a markdown note to local storage.",
      "parameters": {
        "type": "object",
        "properties": {
          "topic": { "type": "string" },
          "content": { "type": "string" }
        },
        "required": ["topic", "content"]
      }
    },
    {
      "name": "search_notes",
      "description": "Searches stored local notes by topic.",
      "parameters": {
        "type": "object",
        "properties": {
          "query": { "type": "string" }
        },
        "required": ["query"]
      }
    }
  ]
}

Notice the permissions block. Edge Gallery treats skills like micro-apps. If my skill attempts to read the device calendar without requesting calendar.read, LiteRT-LM will intercept and block the tool call entirely.

Step 2: The Logic Layer (JavaScript runtime)

To make the tool actually do something offline without a server, I discovered Edge Gallery supports a lightweight V8 JavaScript runtime for local skills. I added a script bundle alongside the manifest to handle the File I/O:

// brain_logic.js
export async function save_note(args) {
    const timestamp = new Date().toISOString();
    const data = `${timestamp}nn${args.content}`;
    // Using the sandbox FileSystem API exposed by Edge Gallery
    await SandboxFS.writeFile(`notes/${args.topic}.md`, data);
    return { status: "success", message: `Note saved under ${args.topic}` };
}

export async function search_notes(args) {
    const files = await SandboxFS.listFiles('notes/');
    const matches = files.filter(f => f.includes(args.query));

    if (matches.length === 0) return { result: "No notes found." };

    const content = await SandboxFS.readFile(`notes/${matches[0]}`);
    return { result: content };
}

Step 3: Sideloading into Edge Gallery

This is where the magic happened.

  1. I zipped the JSON manifest and the JS script into offline-brain.skill.
  2. I downloaded the Gemma-4-E2B-it (2.6 GB) model inside Edge Gallery. (You absolutely need the Gemma 4 variant; older models like Gemma 3 lack the tool-calling fine-tunes required for Agent Skills).
  3. I went to the Agent Skills tab, tapped the floating action button, and selected “Import Local Skill”.
  4. I pointed it to my .skill file.

Immediately, the skill populated in my UI with a toggle switch next to it.

Step 4: The 32K Context Test

I opened the AI Chat and enabled my “Offline Brain” skill.

Me: “Save a note about my new React Native architecture idea. It involves using Zustand for state and separating the API layer.”

Gemma 4 (Thinking): Evaluating tools… Found ‘save_note’ in Offline Brain.

Gemma 4: “I’ve saved your note about the React Native architecture!”

I then spent 20 minutes throwing unrelated questions at the model, trying to push the boundaries of its context window. I fed it code snippets, asked for bug fixes, and generated text.

Finally, I tested the recall:

Me: “What was that architecture idea I had earlier?”

Gemma 4 (Thinking): Calling ‘search_notes’ with query ‘React Native architecture’

Gemma 4: “You were planning to use Zustand for state management and keep your API layer separated!”

It worked flawlessly. The 32K context window of Gemma 4 on the edge is arguably the biggest technical leap here. In previous iterations, tool execution outputs would crowd out the context window within a few turns. Now, the model remembers the conversation and the data it pulls from the local file system.

Final Thoughts 💭

While the cloud gets all the glory, the real revolution for developers is happening locally.

Google AI Edge Gallery isn’t just a tech demo; it is an open playground for the future of mobile OS architecture. By opening the doors to custom Agent Skills and local MCP servers, they’ve given us a glimpse into a world where our AI assistants actually know us, completely offline, completely secure.

If you have a modern Android device, do yourself a favor: download Edge Gallery, pull down a Gemma 4 model, and try writing your own local skill. It will change how you think about mobile development.

Happy Hacking! ✨

I Built an On-Chain Marketplace Where AI Agents Solve GitHub Bounties for USDC

Le problème : les agents IA dorment 23h/jour

Tu paies un abonnement Claude Code, GPT-4, ou DeepSeek. Tes agents tournent, réfléchissent, exécutent… puis s’arrêtent. 95% de leur capacité est inutilisée.

Et si ces heures dormantes pouvaient te rapporter de l’argent ?

AI2Work : le marketplace on-chain pour agents IA

J’ai construit AI2Work — un marketplace où des agents autonomes résolvent des GitHub bounties et sont payés en USDC, CELO ou cUSD sur Celo.

Comment ça marche

1. Un posteur crée un bounty (ex: "Fix this Rust memory leak — 100 USDC")
2. Les agents IA claim le bounty en stakant des tokens
3. Ils soumettent leur PR sur GitHub
4. Le posteur choisit le gagnant → paiement on-chain automatique
5. L'agent gagnant reçoit 100 USDC

Le tout est vérifié on-chain via le smart contract ClaudelanceCore v2 sur Celo mainnet.

Stack technique

Couche Technologie
Smart contract Solidity 0.8.24, Foundry, Celo mainnet
Frontend Next.js 15, wagmi v2, Tailwind
Mobile Capacitor Android, native wallet (Keccak256)
Multi-chain Celo + Base + Polygon + Solana
Paiements cUSD, CELO, USDC — escrow on-chain

Pourquoi Celo

  • Frais de gas < 0.01$ — un agent peut claim 100 bounties pour quelques centimes
  • MiniPay intégré — 10M+ utilisateurs, wallet natif
  • ERC-8004 Identity NFT — réputation on-chain vérifiable
  • Écosystème aligné avec la mission d’inclusion financière

Résultats (Proof of Ship #8)

  • ✅ Contrat vérifié sur Celo mainnet
  • ✅ 3 agents enregistrés (ERC-721 identities)
  • ✅ Web app live : ai2work.onrender.com
  • ✅ App Android avec wallet natif ECDSA
  • ✅ Multi-token escrow (cUSD, CELO, USDC)

La suite

Si tu build des agents IA ou des outils pour développeurs, le marketplace est ouvert. Les premiers bounties seront postés cette semaine.

👉 Accès API x402 — 85€ ou 49€/mois Starter

Built for Celo Proof of Ship #8. Stack: Solidity, Next.js 15, wagmi v2, Capacitor Android. AGPL-3.0.

Three Stripe subscription patterns I locked in before going live (with code)

I’ve been building and running a small SaaS (GramShift, Instagram automation desktop app) on Stripe subscriptions for the past several months. Getting the basic checkout flow to work was easy — what took more careful design were three implementation patterns where the docs mention the risk but it’s easy to skim past.

Sharing the three I locked in during the build phase, with the code I actually use. I caught the first one during local testing, before it could hit a real customer, and that’s the version of the story I want to share — because the prevention pattern is the part worth copying.

Pitfall 1: Webhook idempotency — design for retries from day one

Stripe webhooks are designed to be retried. If your endpoint is slow or returns 5xx, Stripe resends the same event with exponential backoff. The docs say this. My initial code looked like this:

fastify.post('/api/stripe/webhook', async (req, reply) => {
  const event = stripe.webhooks.constructEvent(
    req.rawBody, req.headers['stripe-signature'], WEBHOOK_SECRET
  );
  if (event.type === 'checkout.session.completed') {
    const session = event.data.object;
    await db.run(
      `UPDATE users SET plan = 'pro', expires_at = ? WHERE id = ?`,
      session.expires_at, session.client_reference_id
    );
  }
  return reply.send({ received: true });
});

Looks fine. But while building the webhook flow, I ran the Stripe CLI to replay events into my local server and noticed the same event.id being processed multiple times when I deliberately slowed the handler. If a real production handler hiccuped for any reason — slow DB, transient timeout — Stripe would retry, and this code would happily re-run the same update.

For paid SaaS that’s the kind of bug you absolutely do not want to discover by reading customer complaints. So I locked in an idempotency table before going live:

fastify.post('/api/stripe/webhook', async (req, reply) => {
  const event = stripe.webhooks.constructEvent(
    req.rawBody, req.headers['stripe-signature'], WEBHOOK_SECRET
  );
  const exists = await db.get(
    'SELECT 1 FROM stripe_events WHERE event_id = ?', event.id
  );
  if (exists) return reply.send({ received: true, duplicate: true });
  await db.run(
    'INSERT INTO stripe_events (event_id, type, created_at) VALUES (?, ?, ?)',
    event.id, event.type, Math.floor(Date.now() / 1000)
  );
  // ...actual processing...
  return reply.send({ received: true });
});

Cost: one extra table, one extra query per webhook. Worth it on the very first day, because the failure mode (silently re-running a billing-related update) is exactly the kind of bug your test mode might not catch on its own.

Pitfall 2: 3D Secure (SCA) — your EU/Brazil customers will need it

The standard PaymentIntent + stripe.confirmCardPayment() flow works perfectly with 4242 4242 4242 4242. What it doesn’t show you is that SCA (Strong Customer Authentication) requires explicit handling of the requires_action branch — and that branch is what real EU/Brazil/Australia customers hit on a meaningful share of transactions.

I added the branch during implementation after reading the SCA docs more carefully:

const result = await stripe.confirmCardPayment(clientSecret, {
  payment_method: { card: cardElement, billing_details: { name } }
});

if (result.error) {
  showError(result.error.message);
} else if (result.paymentIntent.status === 'requires_action') {
  const { error } = await stripe.handleCardAction(
    result.paymentIntent.client_secret
  );
  if (error) showError(error.message);
  else showSuccess();
} else if (result.paymentIntent.status === 'succeeded') {
  showSuccess();
}

Test card: 4000 0025 0000 3155 — this always triggers 3D Secure. If your flow completes with this card, you’re covered for most international cases. It’s a one-line test, but it’s the difference between “works for everyone” and “silently broken for half of your EU traffic.”

Pitfall 3: “Immediate cancel” vs “end-of-period cancel” — choose the right default

The simplest cancel implementation is subscription.delete — terminate now. It’s one line of code, and it’s almost always the wrong default.

When I sketched the cancel UX, I quickly hit three predictable problems:

  • A customer who cancels mid-cycle naturally expects either prorated refund OR continued access until period end. Immediate termination satisfies neither.
  • “Cancel” and “turn off auto-renew” are not the same intent. Treating them the same loses customer trust.
  • Cancel button + change-of-mind flow is much easier to build if cancel is reversible by default.

So I defaulted to cancel_at_period_end:

async function cancelAtPeriodEnd(subscriptionId) {
  return stripe.subscriptions.update(subscriptionId, {
    cancel_at_period_end: true
  });
}

function renderCancelButton(sub) {
  const endDate = new Date(sub.current_period_end * 1000)
    .toLocaleDateString('en-US');
  return `<button>Cancel at next renewal (${endDate})</button>`;
}

If someone really wants immediate cancel + refund, that’s a separate “contact support” flow — not a self-serve button. The default is reversible by design, which means the customer has time to change their mind (and a non-trivial share do).

Quick checklist before you launch Stripe subscriptions

  1. Idempotency table on every webhook, keyed by event ID — design it in before going live, not after
  2. Handle requires_action for 3D Secure, test with 4000 0025 0000 3155
  3. Default to end-of-period cancel, immediate cancel via support
  4. Self-subscribe for a full cycle on a test card before launch — sign up, get charged, change cards, cancel, resume

All three are mentioned in the Stripe docs, but they’re easy to read past because the happy-path code works without them. Building each in as a default-on pattern saved me from having to fix them under customer-facing pressure later.

What patterns did you wish you’d implemented from day one with Stripe subscriptions? Curious what others built in early.