The AI ecosystem moves fast.
A few months ago, almost every discussion around AI agents included one keyword: MCP (Model Context Protocol).
Today, the conversation feels different.
The hype is quieter.
The excitement is less explosive.
Some developers even started asking:
“Is MCP already declining?”
The short answer is:
Yes, the hype cycle is cooling down. But MCP is still very important.
And in many cases, it may become more valuable precisely because the noise is fading.
The Rise of MCP
MCP was introduced as a standardized way for AI systems to communicate with tools, APIs, databases, and external services.
Instead of building custom integrations for every AI workflow, developers could rely on a common protocol layer.
That idea was powerful.
Very quickly, major companies and tools began adopting it:
Anthropic
OpenAI
Google
Cursor
Windsurf
JetBrains
VS Code ecosystem
Many developers compared MCP to:
REST APIs for AI
USB for agent tooling
Kubernetes for interoperability
Those comparisons may sound exaggerated, but they explain why the ecosystem expanded so aggressively.
Why The Trend Feels Slower Now
The downtrend is real — at least socially.
You can observe it across:
X/Twitter discussions
YouTube trends
Hacker communities
startup pitches
The reason is simple:
1. The “MCP wrapper” era is ending
At one point, many startups simply added:
“MCP-compatible”
“AI agents”
“tool orchestration”
…without solving a meaningful problem.
As the market matured, people became more selective.
Infrastructure alone is no longer enough.
2. Security concerns became more visible
As adoption increased, researchers started discovering real vulnerabilities inside MCP ecosystems.
Some problems included:
unsafe tool execution
prompt injection
poisoned MCP servers
weak permission boundaries
This changed the industry mindset.
Companies moved from:
“How fast can we integrate MCP?”
to:
“How safely can we deploy MCP in production?”
That naturally slowed the hype.
3. Too many low-quality MCP servers
A large portion of public MCP projects are abandoned, duplicated, or low-value.
This is a common pattern in every fast-growing ecosystem.
We saw it with:
npm packages
crypto projects
browser extensions
AI wrappers
Rapid growth creates noise before standards mature.
But MCP Is Still Good — And Here’s Why
The important thing is this:
MCP is shifting from “trend” to “infrastructure.”
That is a very different phase.
1. Standardization still matters
AI agents without standardized tooling quickly become messy.
Without MCP:
every integration becomes custom
portability decreases
maintenance costs increase
agent systems become fragile
MCP solves a real engineering problem:
structured context and tool communication.
That problem does not disappear.
2. Enterprise adoption is still growing
While social hype cooled, enterprise usage continued increasing.
This is an important distinction:
consumer hype may decline
infrastructure adoption may continue quietly
Many successful technologies follow this pattern.
For example:
Docker
GraphQL
Kubernetes
gRPC
The loud phase ends.
The real deployment phase begins.
3. AI agents genuinely need interoperability
The future of AI is likely multi-agent and tool-driven.
Agents increasingly need to:
access databases
execute workflows
communicate with SaaS platforms
retrieve contextual memory
coordinate across systems
MCP provides a practical structure for that ecosystem.
Even critics of MCP often admit that the underlying problem is real.
The Real Future of MCP
MCP may not remain the only protocol.
That is important to understand.
We will probably see:
new standards
enterprise variants
secure extensions
protocol competition
orchestration layers above MCP
But even if the implementation changes, the core idea remains valuable:
AI systems need a universal way to interact with tools and context.
That concept is unlikely to disappear.
Final Thoughts
MCP is no longer in its explosive “gold rush” phase.
The market is becoming more realistic:
fewer buzzwords
more production concerns
more focus on reliability and security
That is actually healthy.
A technology becomes durable when:
hype decreases
practical usage increases
standards stabilize
infrastructure matures
So, is MCP still good?
Yes.
But today, it is less about excitement — and more about discipline, architecture, and long-term interoperability.
And honestly, that may be a stronger foundation than hype ever was.
Have you ever wondered why some applications load instantly while others make you stare at a loading screen for 10 seconds? In modern software development, data retrieval speed is everything.
When an application relies purely on fetching data from a massive backend database, it inevitably hits a performance bottleneck. To solve this, software engineers use a high-speed memory layer called a Cache. But here is the catch: Cache memory is physically limited. When it gets full, the system faces a critical choice—which data do we delete?
As a computer engineering student at Çukurova University focusing on data infrastructure, I built a Toy Technical Demo in Java to explore the most elegant solution to this problem: The LRU (Least Recently Used) algorithm.
The Human Experience in Code
What fascinates me most about the LRU algorithm is how it perfectly mirrors human biology. Our brains cannot remember every single detail of our lives. To learn new things, our short-term memory naturally forgets the oldest, least accessed information, while keeping recent and frequently used memories at the forefront.
LRU does exactly this for computers.
To visualize this invisible backend process, I designed a Java Swing simulation using a “Wardrobe” analogy. Imagine a wardrobe with a strict capacity of only 4 hangers.
1. The Standard Allocation 🟢
When you buy a new shirt, you hang it up. It becomes your ‘Most Recent’ item. —
2. The Re-prioritization 🔵
If you wear a pair of pants you already own, they don’t just stay in the back. They are moved to the absolute front of the wardrobe because they are popular again. This protects them from being deleted.
3. The Eviction (The Magic of LRU) 🔴
What happens when the wardrobe is full (4/4) and you buy a new hat? The system doesn’t crash. It identifies the ‘Least Recently Used’ item—the old sweater you haven’t worn in months—throws it away, and safely makes room for the hat.
Under the Hood: No Shortcuts
To make this simulation run in O(1) time complexity, I didn’t rely on heavy external libraries. I built the architecture using fundamental Java structures.
I combined a HashMap (for instant memory address lookup) with a custom Doubly Linked List (to seamlessly update the chronological order of the data nodes). Here is a sneak peek at how the data nodes are structured to keep track of the timeline:
// The Doubly Linked List Node StructurestaticclassNode{Stringkey;Stringvalue;Nodeprev,next;publicNode(Stringkey,Stringvalue){this.key=key;this.value=value;}}
Whenever an item is used, it is instantly detached from its current prev and next nodes and moved right next to the head. The item left at the tail is our victim for eviction.
Why It Matters
Without smart eviction policies like LRU, global platforms would require infinite server RAM to function, which is physically and economically impossible.
As software engineers, our job isn’t just about writing code that works; it’s about building robust infrastructures that manage limited resources intelligently. I am not just predicting future system bottlenecks; I am actively learning how to prevent them.
State management is a fundamental concept in React applications. As applications grow, managing and sharing state between components becomes increasingly complex.
While React provides built-in hooks like useState and useContext, they are often not sufficient for large-scale applications with deeply nested components and complex data flow.
Redux addresses this problem by providing a centralized and predictable way to manage application state.
What is Redux?
Redux is a state management library that maintains the entire application state in a single object called the store.
It follows a strict pattern that ensures:
State is predictable
Changes are traceable
Data flow is controlled
Redux is based on the idea of a single source of truth, meaning all application data is stored in one place.
Why Redux is Needed
In React, data is usually passed from parent to child using props. In large applications, this leads to:
Prop drilling (passing data through multiple layers)
Difficult debugging
Scattered state logic
Redux solves these problems by:
Allowing global access to state
Making state changes predictable
Separating logic from UI components
Core Principles of Redux
Redux follows three fundamental principles:
1. Single Source of Truth
The entire state of the application is stored in one central object (store). This makes debugging and tracking changes easier.
2. State is Read-Only
You cannot directly modify the state. Instead, you must dispatch an action that describes what should change.
3. Changes are Made with Pure Functions
Reducers are pure functions. Given the same input, they always return the same output without side effects.
Core Components of Redux
1. Store
The store holds the complete state of the application.
conststore=createStore(reducer);
It provides methods to:
Access state (getState)
Dispatch actions (dispatch)
Subscribe to changes (subscribe)
2. Actions
Actions are plain JavaScript objects that describe what happened.
{type:"INCREMENT"}
They must have a type property and can optionally include additional data.
3. Reducers
Reducers specify how the state changes in response to an action.
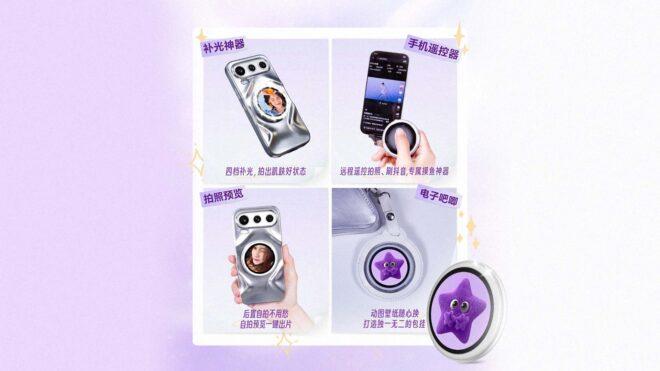
Honor, resmi olarak Türkiye’de satılan 600 serisine odaklanan ilginç bir aksesuar hazırladı. 25 Mayıs’ta detaylandırılacak ürün, temel olarak yuvarlak formda bir dokunmatik ekran ve telefonların arkasına özel bir kılıf aracılığıyla tutturulabiliyor. Aynı zamanda tek başına kullanıma özel bir kılıfı da bulunan ürün, arka kamera ile selfie çekilmesini kolaylaştırıyor (canlı vizör), bir dolgu ışığı olarak kullanılabiliyor veya uzaktan kumanda olarak görev yapabiliyor. Honor 600 serisi ortak olarak 6,57 inç boyutunda 120 Hz AMOLED ekranla geliyor. 600 modeline Snapdragon 7 Gen 4, 600 Pro modeline ise Snapdragon 8 Elite işlemciyle güç veren şirket, her iki telefonda da silikon temelli 7.000 mAh batarya (Avrupa’da 6.400 mAh) kullanıyor. 600 Pro’ya 50W kablosuz şarj desteği ekleyen şirket, ortak kablolu şarj hızını ise 80W olarak açıklıyor. Kamera tarafına geçildiğinde 600 ve 600 Pro’nun arkasında 200 megapiksellik 1/1.4 inç geniş açı ve 12 megapiksellik ultra geniş açı kameralar bir araya getiriliyor. 600 Pro’da bunlara ek olarak CIPA […]
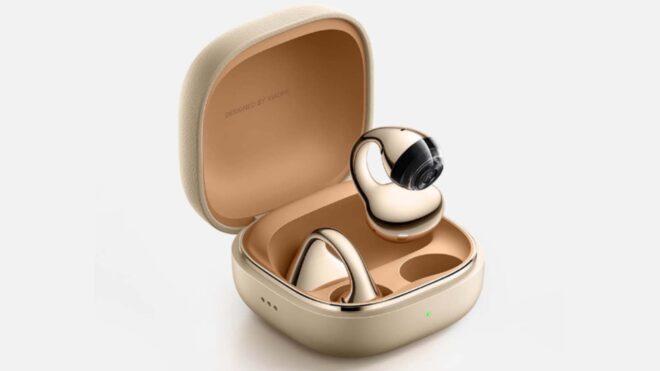
Xiaomi Clip-On kablosuz kulaklık modeli, Smart Band 10 Pro akıllı bileklik ve bataryasıyla dikkat çeken 17 Max bugün resmi olarak tanıtıldı. Yeni ürünlerden “Clip-On”, “açık yapılı” ses deneyimi sunuyor, yani ürün müzik dinlerken çevrenin duyulmasına da imkan tanıyor ve doğrudan kulağın yanına takılarak kullanılıyor. 11 mm dinamik sürücülere ve IP67 sertifikasına sahip olan kulaklık, LHDC 5.0 desteğiyle geliyor. Yapay zeka destekli çeviri özelliğinin de bulunduğu 124 dolarlık model, şarj kutusuyla birlikte 38 saatlik batarya ömrü vadediyor. İlk olarak Çin’de satılacak 630 dolarlık Xiaomi 17 Max ise 100W kablolu / 50W kablosuz şarj destekli 8.000 mAh silikon bataryasıyla dikkat çekiyor. 6,9 inç boyutunda 1-120 Hz OLED ekran taşıyan cihaz, gücünü Snapdragon 8 Elite Gen 5 işlemciden alıyor ve arkasında 200 megapiksellik geniş açı (HP9), 50 megapiksellik ultra geniş açı ile 50 megapiksellik 3x periskop telefoto kameraları bir araya getiriyor. Bugün tanıtılan bir diğer ürün olan Smart Band 10 Pro ise 2024’te […]
In this tutorial, we’ll build an Excalidraw-style collaborative whiteboard using Next.js, HTML5 Canvas, and Velt. You’ll add real-time features like live cursors, comments, presence, and huddles directly into your app. Instead of wiring everything manually, we’ll use Velt MCP and AI agents to handle the integration. We’ll also look at how CRDT-based sync keeps everything in real time.
By the end, you’ll have a fully working multi-user canvas app with production-ready collaboration built in.
What we are building
Excalidraw-style infinite whiteboard
Real-time collaboration with cursors, comments, huddle, notifications, and presence
Multi-user canvas with shared state
Why add collaboration to Canvas apps
Single-user by default: Most canvas apps work locally and don’t support multiple users out of the box
Real-time sync is complex: Handling state sync, conflicts, and updates across users is not trivial
Lack of shared context: Without comments, cursors, and presence, collaboration feels disconnected
Why use Velt
Velt is a collaboration SDK that lets you add real-time, multi-user features directly into your app without building the backend infrastructure yourself. It handles presence, syncing, communication, and UI components out of the box, so you can focus on your product.
Drop-in collaboration layer: Add features like comments, cursors, and presence without building from scratch
Real-time features built in: Cursors, comments, presence, notifications, and huddles
CRDT-based sync support: Enables conflict-free real-time state updates for multi-user apps
AI-powered setup with MCP: Use Velt MCP and agent skills to automatically install and configure features
No infra needed: No need to manage WebSockets, sync engines, or backend services
Customizable UI components: Easily integrate collaboration UI into your existing design system
Prerequisites
Node.js 18+
Velt API key (from Velt dashboard)
AI coding editor (Anitgravity is used in this demo)
Tutorial: Building Velt-powered Excalidraw-like App
Step 1: Set up Velt MCP
Velt MCP lets your editor (Antigravity) run the Velt installer and guide the integration.
Now, add the Velt MCP installer to Antigravity using the command below:
npx -y @velt-js/mcp-installer
Add it to the Antigravity MCP server configuration with command: "npx" and args: ["-y", "@velt-js/mcp-installer"].
Also, Velt Agent Skills guides the AI on what to implement using best practices, while MCP gives it access to the tools needed to actually execute those changes. Together, they make the integration accurate, structured, and reliable. We have both installed and will be used accordingly.
Get your Velt API key:
Go to the Velt Dashboard
Create a project
Copy your API key
Add it to your .env:
NEXT_PUBLIC_VELT_API_KEY=your_api_key_here
Step 2: Start Velt installation using AI
Now that MCP is set up, we can let the AI agent handle the Velt integration for us.
Open your editor (Antigravity) and type:
install velt
This triggers the Velt MCP installer, which runs as a guided setup inside your editor.
Instead of manually adding SDKs and wiring things, the agent walks you through the setup step by step.
It will ask you for a few inputs:
Your project directory
Your Velt API key and auth token
The features you want to enable (comments, presence, cursors, CRDT, etc.)
Where to place the VeltProvider (recommended: app/page.tsx)
UI placement preferences (like corner position)
You can answer each step directly in chat. The flow is simple and guided.
Step 3: Provide the prompt for MCP
At this point, we already have a working whiteboard built manually. Now, instead of integrating Velt step by step ourselves, we use Velt Agent Skills to analyze this existing app and plan how collaboration should be added.
In your editor, after running install velt, provide the following prompt:
I want to start the Velt integration. Review my project structure and use your Velt Agent Skills to plan the CRDT store implementation.
Once you provide this, the agent starts analyzing your codebase. It looks at how your canvas is structured, how state is managed, and where real-time sync can be introduced. Based on this, it generates an integration plan tailored to your whiteboard.
Instead of manually deciding how to structure CRDT or where to wire Velt, the agent uses its skills to plan it correctly for your app.
After reviewing the plan, you can approve it, and the agent will apply the changes step by step.
Step 4: Understand the existing project structure
Before we look at what MCP added, let us understand how this project is structured. Since the agent analyzes your codebase before integrating Velt, this gives context for what it is working with.
The app/ folder contains the core application logic. This is where the whiteboard is rendered and all canvas interactions like drawing, selecting, and updating elements are handled.
The components/ folder contains UI elements and collaboration integrations. This is where Velt features are connected to your app, including user identity, comments, and UI-level controls.
The lib/ folder handles state management and shared logic. It manages canvas data, document context, and sync-ready state, making it easier to extend the app with real-time collaboration.
Step 5: Add real-time collaboration features (Using MCP)
Now that the whiteboard is working, we layer Velt on top to make it collaborative. This is where users start seeing each other, interacting in real time, and sharing context.
After you provide the prompt and approve the plan, the MCP installer integrates Velt into your project. It sets up the foundation required for collaboration to work correctly with your existing whiteboard.
Presence and cursors
In app/layout.tsx, the VeltProvider enables real-time awareness across your app. Then in VeltSetup.tsx, each user is identified using. This is what allows Velt to track who is online.
In CanvasCommentLayer.tsx, comments are rendered as an overlay on top of the canvas. Instead of attaching comments to DOM elements, we attach them to canvas coordinates.
{// Use bounds or specific fields// Normalized rect provided by normalizeRect helper? not available here easily.// Just use raw coords if available, or approximate.// Rect/Ellipse/Diamond have x1,y1,x2,y2 usually?// Wait, types.ts says DrawingElement...// Let's assume standard shape propertiesif ("x1"inelement&&"y1"inelement&&"x2"inelement&&"y2"inelement){worldX=(element.x1+element.x2)/2;worldY=(element.y1+element.y2)/2;}}elseif (element.type==="line"||element.type==="arrow"){worldX=(element.x1+element.x2)/2;worldY=(element.y1+element.y2)/2;}}}if (typeofworldX!=="number"||typeofworldY!=="number"){returnnull;}constscreenX=(worldX+pan.x)*zoom;constscreenY=(worldY+pan.y)*zoom;return (<divkey={annotation.annotationId}style={{position:"absolute",left:`${screenX}px`,top:`${screenY}px`,transform:"translate(-50%, -100%)",zIndex:50,pointerEvents:"auto",}}><VeltCommentPinannotationId={annotation.annotationId}/></div>);})}</div>
);
From app[/page.tsx](https://github.com/Studio1HQ/Velt-Demos/blob/main/excalidraw-velt-demo/app/page.tsx), you trigger comments like this:
Capture the (x, y) position on click
Pass context to Velt
Optionally attach to a specific element using elementId
This enables:
Freeform comments anywhere on the canvas
Context-aware discussions linked to shapes
This is very similar to how tools like Miro or Figma handle comments.
Sidebar and UI controls
These files handle user-facing UI around collaboration.
ProfileMenu.tsx shows user identity and active participants
ThemeToggle.tsx syncs your app theme with Velt UI
ProfileMenu.tsx
"use client";importReact,{useEffect,useState}from"react";import{ChevronDown,User,Check,LogOut,RefreshCwIcon}from"lucide-react";// import { useVeltClient } from "@veltdev/react";import{TEST_USERS}from"@/lib/users";exportfunctionProfileMenu(){const[isOpen,setIsOpen]=useState(false);const[currentUser,setCurrentUser]=useState(TEST_USERS[0]);// Default to first user// Initialize from URL on mountuseEffect(()=>{constparams=newURLSearchParams(window.location.search);constuserIndex=params.get("user");if (userIndex){constindex=parseInt(userIndex);if (!isNaN(index)&&TEST_USERS[index]){setCurrentUser(TEST_USERS[index]);}}},[]);consthandleUserSelect=(user:(typeofTEST_USERS)[0],index:number)=>{setCurrentUser(user);setIsOpen(false);// Update URL and reload to ensure clean session isolation via VeltProvider authProviderconsturl=newURL(window.location.href);url.searchParams.set("user",index.toString());window.location.href=url.toString();};
Velt components (like comments sidebar) automatically adapt to your app’s theme. This keeps the experience consistent across your UI and Velt overlays.
Up to this point, the whiteboard works, and collaboration features like comments and presence are in place. But for a real collaborative canvas, the most important piece is shared state. Every shape, line, or text element needs to stay in sync across all users in real time.
This is where CRDT comes in.
In a typical canvas app, state lives locally. When a user draws something, it updates only their view. To make this collaborative, we need a shared state that all users can read and write to.
This creates a shared store that is automatically synced across all connected users.
The id acts as a unique identifier for this piece of state. As long as users are in the same document, they are all connected to this store. The map structure is used to store canvas elements, where each element is indexed by its ID.
When a user draws a new shape or updates an existing one, the change is not stored locally. Instead, it is written to the CRDT store.
Functions like adding or updating elements internally call the update function provided by useVeltCrdtStore. Once updated, the change is automatically propagated to every other user connected to the same session.
There is no need to manage WebSockets, events, or manual syncing. Velt handles all of that behind the scenes.
The storageProxy.ts file acts as a thin abstraction layer between your canvas logic and the shared store. Instead of directly interacting with the CRDT store everywhere, this layer helps keep the code clean and organized.
It separates:
Canvas logic
State update logic
This makes the system easier to maintain and extend.
"use client";/**
* Validates if the code is running in a browser environment
*/constisBrowser=typeofwindow!=="undefined";/**
* Proxies localStorage to redirect specific keys to sessionStorage
* This allows Velt to have isolated sessions per tab (using sessionStorage)
* while the rest of the app continues to use localStorage.
*/exportfunctioninitStorageProxy(){if (!isBrowser)return;// Store the original localStorage implementationconstoriginalLocalStorage=window.localStorage;constoriginalSessionStorage=window.sessionStorage;// Keys that should be redirected to sessionStorage// Velt uses keys starting with 'velt', 'snippyly', or '_v' (e.g., _viu, _vv)// Also proxying firebase keys as Velt likely uses them for auth/presenceconstisVeltKey=(key:string)=>{constk=key.toLowerCase();return (k.startsWith("velt")||k.startsWith("snippyly")||k.startsWith("_v")||k.startsWith("firebase"));};
Step 7: Multi-user simulation
The user setup lives in lib/users.ts. This file defines a small set of users with basic details like name, color, and avatar. These are used by Velt to represent each participant across features like cursors, comments, and presence.
In components/velt/VeltSetup.tsx, one of these users is selected when the app loads. A random user is picked and passed to Velt. This is what establishes the session.
Every time the app loads, a different user can be assigned. From Velt’s perspective, each session is now a unique participant in the same document.
Step 8: Run and test the app
Now let’s run the app and see everything working together.
Start the development server:
npm run dev
Once the app is running, open it in your browser at http://localhost:3000.
To test collaboration, open the same app in another window. You can use an incognito tab or a different browser. Each session will act as a different user.
As you interact with the canvas, you’ll start noticing the real-time behavior. Drawing a shape in one window reflects instantly in the other. You’ll see users appearing in presence, and comments syncing across both sessions.
At this point, your whiteboard is fully collaborative, with multiple users interacting on the same canvas in real time.
We started with a simple canvas and turned it into a fully collaborative whiteboard. Along the way, we added real-time cursors, presence, comments, notifications, and even voice huddles using Velt. Instead of building sync logic and infra from scratch, we used Velt MCP and agent skills to handle the heavy lifting and get everything working quickly.
The key takeaway here is simple. You don’t need to spend weeks building real-time systems to make your app collaborative. With the right tools, you can focus on your product and let the platform handle sync, presence, and communication.
From here, you can extend this further:
Connect real authentication instead of simulated users
Improve CRDT logic for more complex canvas operations
Customize Velt UI components to match your product
If you’re building any product where users need to collaborate, this is a pattern worth exploring.
What would your app look like if it supported real-time collaboration from day one?
One quiet way to waste months on a SaaS product is to build before you understand the user’s language.
Reddit can help here when the work starts with research instead of posting.
For RedditFind, we analyzed SaaS-related subreddits by community fit, weekly activity, rules, posting risk, and representative posts.
Start with the right communities
Community
Fit
Weekly visitors
Weekly contributions
Best use
r/SaaS
98%
298K
18K
SaaS founder stories, MRR, pricing, validation
r/microsaas
93%
74K
12K
Micro SaaS, early revenue, first users
r/micro_saas
90%
36K
7K
SEO, directories, Reddit growth, long-form playbooks
r/SideProject
87%
361K
17K
Product demos, launch stories, feedback
r/startups
84%
137K
4.8K
Startup methodology and strategy
Size is a weak default sort. A 36K weekly visitor community with specific micro SaaS threads can beat a much larger, noisier community when you are trying to understand first users or pricing.
Search for validation signals
Useful query patterns:
"SaaS" AND "nobody uses"
"validate my idea" OR "idea validation"
"first paying user" OR "first customer"
"alternative to" AND [competitor]
"[competitor] pricing" OR "[competitor] too expensive"
"looking for a tool" OR "does anyone know a tool"
These phrases sit close to useful moments: failed validation, replacement demand, pricing complaints, and people actively looking for a tool.
Separate launch communities from research communities
Some communities regularly accept feedback or launch-style posts:
r/SideProject
r/alphaandbetausers
r/nocode
r/indiehackers
r/microsaas
Other communities are stronger for reading and commenting:
r/SaaS
r/startups
r/Entrepreneur
r/b2bmarketing
r/sales
r/ProductManagement
r/GrowthHacking
The second group can still be the better source. You may never post a product link there, yet you can learn how buyers and builders describe the problem.
Capture reusable language
When reading threads, save:
Exact problem statements
Workarounds people use today
Competitor names and complaints
Pricing objections
Onboarding confusion
Sales objections
Retention problems
Phrases that show buying intent
This language can improve landing pages, feature naming, onboarding copy, email sequences, and support docs.
Participate before promoting
Basic safety rules:
Do not mass-message people.
Do not use fake users.
Do not hide your relationship to the product.
Do not copy the same post into many communities.
Do not force a product link into strict communities.
A safer reply pattern:
Answer the user’s actual question.
Add a detail from your own research or experience.
Disclose your relationship when it matters.
Mention the product only when it clearly fits the thread.
Many good Reddit replies do not include a link at all.
Let me tell you about the moment I knew we had a problem. We’d just shipped our content repurposing tool. A fitness YouTuber pasted in a video URL. Out came a LinkedIn post that opened with “In today’s fast-paced digital landscape…” The man deadlifts 200kg for a living. That’s when we decided our AI needed to actually learn who it was writing for, not just parrot generic marketing speak into a different shaped box.
Most AI tools for content creators work like a photocopier with a thesaurus. You paste text in, pick a platform, and out comes something that sounds like it was written by a committee of people who’ve never watched a YouTube video. We wanted something different. We wanted an AI that gets better at sounding like you the more you use it. Not because we fine-tuned a model (we don’t have that kind of GPU budget, and frankly, neither do you), but because the system actually remembers what you do and why.
This is the story of how we built that system, what broke along the way (spoiler: a lot), and why the combination of Hindsight’s agent memory and cascadeflow’s multi-model orchestration turned out to be the two pieces we didn’t know we needed until 3 AM on a Tuesday when everything else had failed.
What the System Actually Does
The elevator pitch: you give our system a YouTube URL. It downloads the video, transcribes it, finds the strongest 30 to 90 second moments, and generates production-ready briefs for Instagram Reels, YouTube Shorts, and LinkedIn. Each brief includes a hook, a full spoken script with editing cues like [CUT] and [PAUSE], a platform-native caption, and even a visual prompt for AI-generated b-roll. Basically, it does what a $5,000/month content team does, except it doesn’t take Fridays off.
But here’s the thing. Plenty of tools can chop a video into clips. That’s table stakes. The interesting part is what happens after the creator starts reviewing those briefs. Every edit, every approval, every rejection, every “regenerate this but make it less corporate” gets silently observed and stored as a memory. The next time the system generates content, it recalls those memories and adjusts.
The creator never fills out a settings page and checks boxes next to adjectives like “casual” and “bold.” (We all know nobody reads those forms honestly anyway. Everyone thinks they’re “authentic and relatable.”) The system just watches what they actually do and converges on their personality over time.
Think of it like hiring a new editor. Day one, they’re guessing. They write your hooks like a BuzzFeed intern from 2014. By week three, they know you hate exclamation marks, you always cut filler words, and your hooks work best when they open with a question, not a command. That’s the loop we built. Except this editor doesn’t ask for a raise and doesn’t have opinions about your Slack status.
What you’re looking at above: The pipeline flows left to right, from a YouTube URL through seven stages (Ingest, Transcribe, Recall, Extract, Clip, Generate, Review). The key detail is the feedback loop at the bottom, the red arrow that makes the whole thing worth building. Every editing action in the Review stage feeds observations back into Hindsight’s memory bank. On the next pipeline run, the Recall stage pulls those memories and injects them into both moment extraction and content generation. The system literally gets smarter with each review cycle. It’s like git for personality, except you never have to write a commit message.
The Memory Loop: Where Hindsight Fits
Here’s a confession. The first version of our system had no memory at all. Zero. Zilch. The kind of amnesia that makes Memento look like a documentary about a guy with excellent recall. It generated the same generic hooks regardless of who was using it. A fitness creator and a fintech newsletter writer got output in the same tone. That’s obviously wrong, but the fix isn’t obvious.
The naive approach: build a preferences form. Let the creator pick “casual” or “professional,” choose their platforms, list words to avoid. We built that too (it helps with the cold start problem, and honestly it makes the onboarding screen look impressive in screenshots). But it turns out people are terrible at describing their own style. A creator will tell you “I’m casual and direct” and then consistently reject every draft that doesn’t open with a specific data point. Ask anyone what kind of music they like. Now watch what they actually play in the car. Two completely different playlists.
Their stated preferences and their revealed preferences are two different universes. We needed to observe the second one.
That’s where Hindsight enters the picture. Instead of asking creators to describe themselves (an exercise roughly as accurate as asking a cat to describe its relationship with furniture), we observe what they do and store those observations as memories.
The loop in plain English: The creator reviews drafts and edits/approves/rejects them. Each action fires retain_diff_observation(), which stores a tagged observation in Hindsight’s memory bank. On the next pipeline run, recall() fetches relevant memories and reflect() synthesizes them into a compact paragraph. That paragraph gets injected into Claude’s generation prompt. The drafts come back better. The creator edits less. The loop tightens. Rinse and repeat until the AI sounds more like the creator than the creator does on a Monday morning.
Here’s the function that fires every time someone saves an edited draft. It’s not clever. It doesn’t need to be:
Nothing fancy happening here. No PhD required. We compute a rough diff, classify whether it was a trim, expansion, or rewrite, and store a human-readable observation via Hindsight’s retain API. The tags are important, though. They let us query memories by type later without building our own taxonomy from scratch. (We tried building our own taxonomy once. It lasted two days before we set it on fire.)
The real magic shows up on the next pipeline run. Before we generate any content, we call two functions that sound like they belong in a therapist’s office:
recall_result=awaitrecall_memories(query="How does this creator prefer their content? ""Hook styles, editing preferences.")reflection=awaitreflect_on_creator(query="Summarise this creator's content preferences, ""voice, and style.")
recall fetches the raw observations. reflect synthesizes them into a compact paragraph, like a friend who can summarize your entire personality in three sentences (and is somehow right about all of them). That paragraph gets injected straight into the generation prompt as a ## Creator Voice & Preferences section. Claude doesn’t need fine-tuning. It just needs good context, and Hindsight provides exactly that.
The result is genuinely satisfying to watch. After three or four review sessions, the system stops generating hooks with exclamation marks for creators who always delete them. It starts opening LinkedIn posts with data points for creators who approve those. It learns that one creator shortens every tweet to under 120 characters and begins generating tighter drafts automatically. No retraining, no config files, no “please describe your brand voice in 500 words” forms. Just memory doing what memory does.
Keeping It Cheap: Where cascadeflow Fits
Here’s a problem we didn’t anticipate, which in retrospect we absolutely should have. After a creator completes a review session, we need to analyze all their editing events and extract style observations. That’s an LLM call. We also use LLM calls during moment extraction from transcripts, and for the actual brief generation. Each project can easily rack up 15 to 20 LLM calls. Our moment extraction needs to be accurate (you can’t miss the best 45 seconds of a 30-minute video, that’s literally the whole point), but our synthesis calls are simple text classification that a slightly motivated intern could do.
Using the same expensive model for everything felt like hiring a Michelin-star chef to make toast. Sure, the toast would be excellent. But your budget would be gone by Tuesday. That’s where cascadeflow saved us real money and possibly our sanity.
cascadeflow lets you define a drafter model (fast and cheap) and a verifier model (slower and accurate), and it routes each call to whichever model meets a quality threshold you set. The key insight is that different parts of the pipeline have different accuracy requirements:
defget_extraction_agent()->CascadeAgent:"""Higher quality: moment extraction needs accuracy."""returnbuild_agent(quality_threshold=0.8)defget_generation_agent()->CascadeAgent:"""Lower threshold: drafter handles most generation cheaply."""returnbuild_agent(quality_threshold=0.65)defget_synthesis_agent()->CascadeAgent:"""Synthesis uses drafter only: observations are simple text."""returnbuild_agent(quality_threshold=0.5)
Three agents, three thresholds, same two underlying models. It’s like having a junior dev and a senior dev, and only paging the senior when the junior says “I’m not sure about this one.” The synthesis agent (which extracts observations like “creator always removes filler words”) runs on the drafter almost exclusively because the task is straightforward. The extraction agent, which needs to identify the strongest 30-second moments from a transcript, escalates to the verifier more often because getting that wrong means the whole project is useless. We didn’t have to think about routing logic or write a single if/else. We just set a quality number and cascadeflow handles the rest.
We also built a CostAccumulator that tracks every call and computes what we would have spent if everything went to the expensive model. Think of it as the “what if we hadn’t been smart about this” meter:
This surfaces in the UI as a cost breakdown per project. Creators don’t care about it (they shouldn’t have to), but we stare at it like it’s a stock ticker. It tells us that roughly 70 to 80 percent of calls get handled by the drafter, which means cascadeflow is doing exactly what we hoped: using the expensive model only when it actually matters. The other 20 to 30 percent? Those are the calls where quality genuinely required the bigger model. We sleep better knowing we’re not burning money on tasks a smaller model handles perfectly.
The Seven-Stage Pipeline
The full pipeline is a background task triggered when a creator submits a YouTube URL. Each stage updates the project status in Supabase so the frontend can show a live progress stream (because nothing says “your money’s being well spent” like a progress bar that actually moves). Here’s the sequence:
Ingest: Detect input type, try YouTube auto-captions first (faster than transcription).
Transcribe: If no captions exist, download audio via yt-dlp and run Groq Whisper. Files over 25 MB get automatically chunked.
Recall: Pull creator memory from Hindsight. If no memories exist yet (cold start), the system falls back to universal heuristics.
Extract: Claude Haiku 4.5 analyzes the transcript in parallel chunks and identifies the 3 to 5 strongest moments. Each moment is scored on hook quality, narrative arc, and standalone clarity.
Clip: yt-dlp downloads just the relevant segments (no full-video download), ffmpeg crops to 9:16 vertical. All clips extracted in parallel.
Generate: Claude Sonnet 4.5 produces a full production brief per moment per platform, with the creator’s memory reflection injected into every prompt.
Review: The creator edits, approves, or rejects. Every action feeds back into Hindsight. The loop closes.
The pipeline runs entirely as an async background task. If clip extraction fails for a particular moment (network issues, YouTube deciding it doesn’t like you today), it falls back to embedding a YouTube player with start/end timestamps. The frontend never shows a broken state. This is important. Nothing kills user trust faster than a loading spinner that never stops.
The Intelligence Graph: Making Memory Visible
Here’s something we learned the hard way: if the system is learning from you, you have to let the user see what it learned. Nobody trusts a black box. Especially not creators who’ve spent years building a personal brand and have strong opinions about whether they’re “witty” or “sarcastic” (it’s always sarcastic, by the way).
So we built a knowledge graph visualization. It runs three parallel Hindsight recall queries across different memory domains (style/tone, editing behavior, profile preferences), deduplicates by text, and classifies each memory into a node type using the tags that Hindsight already stores:
def_classify_memory_with_tags(text:str,tags:list[str])->tuple[str,str,float]:"""Classify using real Hindsight tags first, fall back to keyword heuristic."""fortagin(tagsor[]):kind=_TAG_KIND.get(tag.lower().strip())ifkind:returnkind,_short_label(text),0.80return_classify_memory(text)
Tags from Hindsight act as a first-class classification signal. We only fall back to keyword heuristics when tags are missing (which is like using a map when your GPS dies, except the map is made of regex and tears). The graph renders with five node types: root (the creator identity), traits (tone, style), platforms, preferences (editing patterns), and topics (niche). Edges encode semantic similarity, temporal proximity, and causal relationships (platform preferences causing editing patterns).
The creator can hover over any node and see the full observation text. It’s the difference between “the AI is learning” and “here’s exactly what the AI thinks it knows about you, and you can see it evolving in real time.” One tester told us it felt like reading their own therapy notes. We’re choosing to take that as a compliment.
Lessons Learned (a.k.a. Things We Wish Someone Had Told Us)
Memory is more useful than configuration. We have a preferences page. Creators fill it out during onboarding. But the observations extracted from actual editing behaviour are consistently more specific and more accurate than what people self-report. “I prefer casual tone” is less useful than “Creator consistently removes the word ‘essentially’ and shortens hooks to under 8 words.” If you’re building a personalization system, observe behavior first and ask questions second. People don’t know what they want until they see what they don’t want.
Quality thresholds beat manual routing. We initially wrote if task_type == "synthesis": use_cheap_model() branching logic. It was ugly. It was fragile. It was the kind of code that makes future-you send angry Slack messages to past-you. Replacing that with cascadeflow’s quality threshold was simpler and more robust. The threshold is a single number, and the system figures out when to escalate. We spent less time debugging routing decisions and more time tuning the threshold values themselves, which is the right knob to turn.
Tag your memories at write time. We initially stored observations as plain text and tried to classify them at read time using keyword heuristics. It worked about as well as you’d expect, which is to say it didn’t. Switching to Hindsight’s tag parameter (e.g., tags=["editing-behaviour", "draft-edit", "linkedin"]) meant that recall queries and graph construction could use structured metadata instead of parsing free text. The 30 seconds of effort at write time saved us hours of heuristic maintenance and approximately three existential crises.
Show the user what you learned. The intelligence graph isn’t a gimmick. In our early testing, creators would see observations they disagreed with (“Creator prefers formal tone” when they thought they were casual) and immediately edit a few more drafts to correct the signal. The memory system self-corrected because the creator could see the model’s assumptions and naturally generated counter-evidence. Transparency creates a better feedback loop than any amount of prompt engineering. Your users will train your system for free if you just show them what it thinks.
Fail gracefully at every stage. YouTube throttles downloads. Whisper sometimes hallucinates timestamps (it once confidently transcribed silence as a TED talk). Claude occasionally returns malformed JSON that would make a parser weep. Every stage of our pipeline has a fallback: failed clips become YouTube embeds, missing memories trigger universal heuristics, broken JSON gets regex-parsed as a last resort. The system never shows a blank screen. It always shows something, and that something improves as the infrastructure cooperates. Ship the 80% solution. The remaining 20% will fix itself when you’re not looking.
As an engineering manager and developer, I constantly look for ways to eliminate repetitive business friction using automation. One of the most common manual bottlenecks is bookkeeping—specifically, reading utility bills or vendor invoices and logging them into financial trackers.
To solve this, I built a production-ready, self-hosted AI Agent using a pure automation stack. It allows users to simply snap a photo of an invoice, send it over WhatsApp, and have the structured data extracted and logged automatically in seconds.
Here is a breakdown of the actual system architecture, the code nodes, and how to handle it using an AI-first approach.
The System Architecture
A robust automation pipeline requires strict separation of concerns. This entire Proof of Concept (POC) runs without an external Node.js server, relying entirely on a self-hosted orchestration engine:
Ingress: WhatsApp Business API Cloud Webhooks (configured with a temporary developer test number).
Orchestration & Data Flow: Self-hosted n8n environment.
Cognitive Layer: Gemini 1.5 Flash (chosen for its native multimodal capabilities, large context window, and fast inference speeds).
Data Formatting: Native n8n Code Nodes running isolated JavaScript.
App Creation: Follow the Meta App Setup Guide to create a new App. Select Other -> Business as your app type.
Add WhatsApp Product: Inside your app dashboard, add the WhatsApp product. Meta will instantly provision a free temporary test number and a test Business Account (WABA) for development.
Configure Webhooks: Point Meta’s webhooks to your n8n production webhook URL to start capturing real-time message payloads.
Step 1: Handling Multimodal Input via Webhooks
When a user uploads an invoice image or PDF via WhatsApp, the webhook doesn’t deliver the file directly; it delivers a media ID.
We use an HTTP Request node to securely request the download URL using your Meta Access Token, pull the binary data, and hold it in the workflow memory to pass directly to our AI node.
Step 2: Designing the System Prompt for Document Extraction
Instead of relying on fragile, traditional OCR software that breaks if a vendor moves a logo, we pass the raw image straight to Gemini 1.5 Flash. The magic lies in instructing the model to act as a strict data parser.
Here is the sample System Prompt structure used in the model configuration:
“You are an expert financial data extraction AI. Your sole task is to analyze the provided invoice or utility bill image and extract data with absolute accuracy.
Follow these strict formatting rules:
Extract the primary Vendor Name.
Extract the Invoice Date and normalize it into standard YYYY-MM-DD format.
Extract the Grand Total Amount as a pure floating-point number.
Extract individual line items into an array containing description, quantity, and total price.
Do not include any conversational text, markdown formatting, or wrappers. Your response must be a single, raw, valid JSON object.”
Step 3: Formatting Data with n8n Code Nodes (JavaScript)
Once Gemini returns the text string, we avoid spinning up an external server or application layer. Instead, we pipe the model’s output directly into an internal n8n Code Node configured to execute JavaScript.
This node isolates the extraction logic, runs a quick safety validation, and formats the properties perfectly for our target database or sheet.
Here is the exact layout of the JavaScript snippet inside the n8n Code Node:
// Loop through incoming items from the Gemini nodefor (constitemof$input.all()){try{// Parse the raw string response from the AI modelconstextractedData=JSON.parse(item.json.output);// Format and return the details explicitly for downstream nodesitem.json.formattedInvoice={vendor:extractedData.vendor_name||'Unknown Vendor',date:extractedData.invoice_date||newDate().toISOString().split('T')[0],total:parseFloat(extractedData.grand_total)||0.0,lineItems:extractedData.line_items||[]};}catch (error){// Handle parsing errors safely if the response was malformeditem.json.formattedInvoice={vendor:'Parsing Error',error:error.message,rawOutput:item.json.output};}}return$input.all();
By keeping this execution inside the internal JavaScript node, the data mapping remains incredibly fast, entirely self-contained, and exceptionally easy to debug directly from the execution logs.
Handling Edge Cases in Production
Building a POC is easy; making it production-ready is where the real engineering begins. When deploying this system, you must design around:
Rate Limiting: Managing concurrent incoming webhooks from active users by placing a lightweight Redis queue ahead of the API calls.
Data Security: Ensuring that processed invoice data is deleted from local temporary server storage immediately after database insertion to protect PII.
What’s Next?
This pattern proves that you can build highly sophisticated AI Agents entirely inside a visual workflow manager when paired with robust system prompts and minor inline JavaScript engineering. Next up, I am scaling this to run automated cross-matching against incoming banking transactions.
The full workflow JSON schema will be open-sourced on my GitHub profile soon. Follow along as I map out more production-ready AI engineering architectures.
Enterprise RAG — A practitioner’s build log | Post 3 of 6
A retrieval pipeline has more design surface than it appears. The technology choices — vector search, LLM provider, storage engine — get most of the attention. The structural choices — where filtering happens, how evaluation is wired, what the dashboard connects to — determine whether the system actually works correctly in a production environment.
This post documents three structural decisions I made in Enterprise RAG, the constraint that drove each one, and the cost I accepted.
Decision 1: Lexical retrieval before semantic — sequencing, not a permanent choice
The default retrieval implementation uses token cosine similarity against a local SQLite chunk store (RAG_RETRIEVAL_PROVIDER=local). Not vector embeddings. Not a managed search index. Lexical scoring.
This was a sequencing decision, not a technology preference.
The constraint: Access control validation requires a deterministic retrieval baseline. If retrieval results vary across runs — because embedding models update, because vector indices are rebuilt, because approximate nearest neighbor algorithms introduce non-determinism — the evaluation set becomes unreliable. A restricted_leak_count of zero means nothing if retrieval is non-deterministic and the same query might return different chunks tomorrow.
Lexical retrieval is fully deterministic. Given the same document corpus and the same query, it returns the same ranked chunk list every time. That makes the evaluation set a reliable regression test rather than a probabilistic snapshot.
The accepted cost: Lexical scoring does not capture semantic similarity. A question about “headcount reduction” will not retrieve a chunk that uses the phrase “workforce restructuring” unless there is token overlap. Semantic retrieval closes that gap — at the cost of determinism in the local validation environment.
The Azure AI Search adapter (RAG_RETRIEVAL_PROVIDER=azure_ai_search) is implemented for production use, where semantic and hybrid query modes are available. The retrieval provider is a configuration switch, not a code change. Switching from local to Azure AI Search does not alter the access control layer, the evaluation runner, or the API surface.
Decision 2: API-backed dashboard — not direct database access
The Streamlit dashboard (dashboard/app.py) connects to the FastAPI API layer, not the database directly. Every dashboard operation — querying documents, fetching metrics, running evaluations, reviewing the citation log — goes through an authenticated API call.
This was not a minor implementation choice. It was a deliberate architectural boundary.
The constraint: A dashboard that reads the database directly cannot be deployed in a containerized or cloud environment without granting the dashboard container database credentials. That creates a credential distribution problem: every new environment where the dashboard runs needs database access, which widens the credential surface.
An API-backed dashboard has a single credential requirement: the DASHBOARD_API_URL and optionally DASHBOARD_ADMIN_TOKEN. The dashboard container never holds database credentials. It holds only the API location and the management token. The API enforces authorization. The database credentials stay with the API container.
The accepted cost: Every dashboard operation adds one network hop compared to direct database access. For a local development setup this is negligible. For a cloud-deployed dashboard querying an API on the same virtual network, it is also negligible. The cost is only relevant if the dashboard is running in a significantly different network zone from the API — which would itself be an unusual deployment topology.
The secondary benefit: the API-backed dashboard tests the public API surface on every dashboard interaction. If the dashboard shows correct data, the API is returning correct data. That is a form of continuous integration that direct database access cannot provide.
Decision 3: Evaluation runner as a live API endpoint — not an offline script
The evaluation runner is exposed as POST /eval/run — a standard API endpoint that runs the evaluation set against the live query pipeline and returns metrics directly.
Most RAG evaluation setups I have seen are offline scripts: pull a golden set, run retrieval, compare results, write a report. The script does not call the production API. It calls the retrieval components directly, often with mocked or simplified versions of the access control layer.
The constraint: If the evaluation script bypasses the access control layer, it cannot detect access control failures. A restricted_leak_count computed by calling the retriever directly — without going through the role filter — will always be zero, regardless of whether the filter is actually working in production.
By routing evaluation through POST /eval/run, which calls POST /query internally, the evaluation runner tests the entire pipeline: authentication handling, role filter, retrieval, generation, and citation assembly. Every evaluation case exercises the same code path that a real user request exercises.
The accepted cost: Live evaluation runs against the production database. In a high-traffic environment, running a large evaluation set could add query load. The mitigation is to run evaluations at low-traffic windows or against a staging environment — not to move evaluation back to a disconnected script.
The current evaluation set is small and optimized for repeatable access-control checks. Extending it with larger golden sets, human relevance labels, and answer correctness checks is a documented roadmap item.
One decision I made explicitly not to make yet
Role metadata is currently embedded in document front matter — each markdown document has a allowed_roles field that specifies which roles can retrieve it. This is correct for a local deterministic environment where document metadata is under engineering control.
In production, role context should come from the identity provider — Entra ID claims or OIDC bearer token attributes — not from request body parameters or document-embedded metadata alone. I did not implement full Entra ID role claim integration because it requires a live Azure tenant to validate. The configuration path is documented and the AUTH_PROVIDER=entra setting is implemented. The end-to-end test of role-from-identity-claim requires a real identity provider.
That is a known gap. It is in the production considerations section of docs/security.md, not hidden in implementation comments.
Current limits
Lexical retrieval does not capture semantic similarity. Queries with no token overlap with document chunks will not retrieve relevant results even when the content is semantically related.
Evaluation set size is calibrated for local access-control validation. Answer quality evaluation — correctness labels, human relevance ratings — is a planned extension.
Entra ID role claim integration requires a live Azure tenant for end-to-end validation. The local implementation uses request-body role parameters, which must not be trusted in production without API key authentication.
The POST /eval/run endpoint requires the ADMIN_TOKEN when management protection is enabled. Evaluation runs in protected environments require the admin credential.
Next engineering step
Add one document to the corpus with allowed_roles: ["finance"], run POST /eval/run, and verify that the new document appears in the blocked count for non-finance evaluation cases. That single test confirms the role filter is reading document metadata correctly and applying it before scoring.
One question for you
Does your internal RAG evaluation pipeline call the same API endpoints that production queries use, or does it call retrieval components directly? If it bypasses the access control layer, does your restricted_leak_count metric actually measure anything?
Next post: The evaluation metrics that matter for enterprise RAG — and why pass rate alone is not enough to validate a system that handles restricted documents.



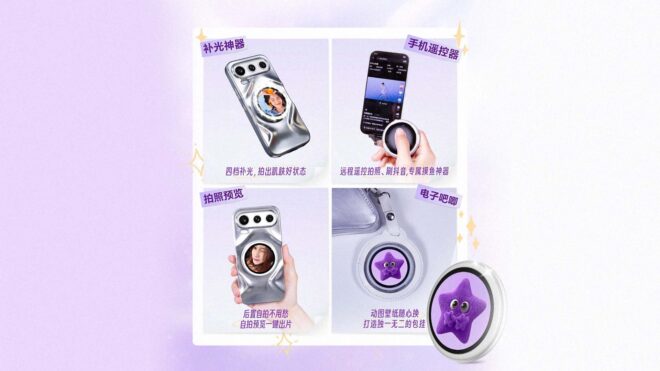 Honor, resmi olarak Türkiye’de satılan 600 serisine odaklanan ilginç bir aksesuar hazırladı. 25 Mayıs’ta detaylandırılacak ürün, temel olarak yuvarlak formda bir dokunmatik ekran ve telefonların arkasına özel bir kılıf aracılığıyla tutturulabiliyor. Aynı zamanda tek başına kullanıma özel bir kılıfı da bulunan ürün, arka kamera ile selfie çekilmesini kolaylaştırıyor (canlı vizör), bir dolgu ışığı olarak kullanılabiliyor veya uzaktan kumanda olarak görev yapabiliyor. Honor 600 serisi ortak olarak 6,57 inç boyutunda 120 Hz AMOLED ekranla geliyor. 600 modeline Snapdragon 7 Gen 4, 600 Pro modeline ise Snapdragon 8 Elite işlemciyle güç veren şirket, her iki telefonda da silikon temelli 7.000 mAh batarya (Avrupa’da 6.400 mAh) kullanıyor. 600 Pro’ya 50W kablosuz şarj desteği ekleyen şirket, ortak kablolu şarj hızını ise 80W olarak açıklıyor. Kamera tarafına geçildiğinde 600 ve 600 Pro’nun arkasında 200 megapiksellik 1/1.4 inç geniş açı ve 12 megapiksellik ultra geniş açı kameralar bir araya getiriliyor. 600 Pro’da bunlara ek olarak CIPA […]
 Xiaomi Clip-On kablosuz kulaklık modeli, Smart Band 10 Pro akıllı bileklik ve bataryasıyla dikkat çeken 17 Max bugün resmi olarak tanıtıldı. Yeni ürünlerden “Clip-On”, “açık yapılı” ses deneyimi sunuyor, yani ürün müzik dinlerken çevrenin duyulmasına da imkan tanıyor ve doğrudan kulağın yanına takılarak kullanılıyor. 11 mm dinamik sürücülere ve IP67 sertifikasına sahip olan kulaklık, LHDC 5.0 desteğiyle geliyor. Yapay zeka destekli çeviri özelliğinin de bulunduğu 124 dolarlık model, şarj kutusuyla birlikte 38 saatlik batarya ömrü vadediyor. İlk olarak Çin’de satılacak 630 dolarlık Xiaomi 17 Max ise 100W kablolu / 50W kablosuz şarj destekli 8.000 mAh silikon bataryasıyla dikkat çekiyor. 6,9 inç boyutunda 1-120 Hz OLED ekran taşıyan cihaz, gücünü Snapdragon 8 Elite Gen 5 işlemciden alıyor ve arkasında 200 megapiksellik geniş açı (HP9), 50 megapiksellik ultra geniş açı ile 50 megapiksellik 3x periskop telefoto kameraları bir araya getiriyor. Bugün tanıtılan bir diğer ürün olan Smart Band 10 Pro ise 2024’te […]


