Hermes Meter: A Physical Desk Display for Local Agent Status, Usage, and Runtime Health

This is a submission for the Hermes Agent Challenge

What I Built

I built Hermes Meter, a Hermes Agent application-layer concept for turning AI agent activity into a local-first physical desk display.

The project is based on my AI Desk Meter repo.

Live project page:

The idea is simple:

Hermes Agent should not only work in the background. It should have a visible local status surface that tells the developer what the agent is doing, how active it is, whether it is stale, and whether the local runtime is healthy.

AI agents are becoming more capable, but they often feel invisible.

A task starts. The model thinks. Tools run. Tokens generate. Usage changes. The agent may be active, idle, stalled, offline, or rate-limited.

But the developer often has to guess what is happening.

Hermes Meter turns that invisible agent state into a tiny local dashboard.

The first hardware direction is an ESP32-S3 AMOLED desk display that can show agent/runtime state such as:

  • active / idle / stale / error
  • current usage percentage
  • weekly usage percentage
  • reset countdowns
  • burn-rate state
  • connection status
  • data confidence
  • local model / provider state
  • optional pixel mascot or “Musing…” style status animation

The goal is not to bypass usage limits or scrape private dashboards.

The goal is visibility, diagnostics, and local-first agent awareness.

Demo

The core Hermes Meter flow looks like this:

Hermes Agent / local AI tool / runtime logs
  ↓
Python host daemon
  ↓
Normalized JSON payload
  ↓
Wi-Fi POST / BLE / stdout
  ↓
ESP32-S3 AMOLED display
  ↓
Physical desk status meter

Instead of checking a browser tab, cloud dashboard, or terminal log, the developer gets an always-visible local device.

Example display states:

Hermes: Musing...
Mode: active
Current: 50%
Weekly: 11%
Burn: normal
Reset: 01:22:00
Source: local/mock
Confidence: estimated

Example JSON payload:

{
  "schema": "ai-desk-meter.v1",
  "service": "hermes-agent",
  "current_percent": 50,
  "weekly_percent": 11,
  "current_reset_seconds": 4920,
  "weekly_reset_seconds": 547200,
  "burn_rate": "normal",
  "status": "Musing...",
  "mode": "active",
  "updated_at": 1760000000,
  "source": "local-runtime",
  "confidence": "estimated"
}

Example Hermes Agent state mapping:

agent.planning        → Musing...
agent.tool_running    → Working
agent.streaming       → Generating
agent.waiting         → Idle
agent.no_output       → Stalled
agent.timeout         → Timeout
agent.offline         → Offline
agent.error           → Error

That gives Hermes Agent a physical, glanceable status surface.

Code

Core repository:

  • AI Desk Meter — local-first physical desktop usage dashboard for AI coding tools, with an ESP32-S3 AMOLED target, Python host daemon, JSON protocol, docs, examples, firmware scaffold, and enclosure notes.

Live project page:

Supporting local-agent infrastructure:

  • ARC-Neuron LLMBuilder — local AI build-and-memory system focused on model promotion, benchmark receipts, and governed model improvement.
  • arc-lucifer-cleanroom-runtime — local-first runtime direction for receipts, replay, rollback, ranked memory, and sandboxed AI execution.
  • LuciferAI_Local — local/offline assistant direction using local model execution and GGUF / llamafile workflows.
  • ARC-StreamMemory — local visual/session memory direction for agent-readable frame and screen evidence.
  • TizWildin Entertainment HUB — public hub for the broader software, AI, automation, and audio ecosystem.

This Hermes Agent challenge build focuses on the physical status-meter pattern:

Hermes Agent
  ↓
runtime/provider state
  ↓
host daemon
  ↓
meter payload
  ↓
ESP32-S3 display
  ↓
glanceable local agent awareness

My Tech Stack

  • Hermes Agent
  • AI Desk Meter
  • ESP32-S3 AMOLED display target
  • Python host daemon
  • JSON state protocol
  • Wi-Fi POST / BLE direction
  • local runtime/provider adapters
  • mock/manual providers
  • firmware scaffold
  • C++ / PlatformIO direction
  • local-first diagnostics
  • physical desk display UX
  • optional mascot/status animation

The core pattern is:

Agent state
  ↓
normalized meter payload
  ↓
local transport
  ↓
tiny hardware display
  ↓
developer awareness

How I Used Hermes Agent

Hermes Agent is the agentic workflow that benefits from a visible local meter.

A Hermes-style agent can plan, call tools, stream model output, inspect files, run tasks, and produce results.

Hermes Meter focuses on the operator side:

What is the agent doing right now?

In this pattern, Hermes Agent emits or exposes simple state changes:

  • planning
  • using tools
  • generating
  • waiting
  • retrying
  • stalled
  • timed out
  • completed
  • offline
  • error

The AI Desk Meter host daemon converts those states into a normalized payload.

The physical display renders the result.

That gives the developer a small hardware “agent heartbeat.”

Instead of wondering whether the agent is frozen, still working, or disconnected, the developer can glance at the desk meter.

Why This Matters

Agent UX is not only about chat windows.

If agents become part of real developer workflows, they need better local presence.

A physical meter can show:

  • whether the agent is alive
  • whether generation is active
  • whether a run is stale
  • whether usage is high
  • when reset windows are approaching
  • whether a provider is offline
  • whether the current state is exact, estimated, mock, or unknown

This is especially useful for local-first and multi-provider setups.

A developer might use:

  • Hermes Agent
  • local GGUF models
  • cloud coding tools
  • CLI assistants
  • local ARC runtimes
  • desktop dashboards
  • physical meters

Hermes Meter gives those systems a shared output surface.

It makes the agent visible outside the terminal.

What Makes It Different

Most agent projects focus only on the model or the tool call.

Hermes Meter focuses on the human operator loop.

The model can be powerful, but the developer still needs to know:

Is it working?
Is it idle?
Is it stuck?
Is it offline?
Is usage getting high?
Can I trust this reading?
When does it reset?

The meter turns that state into a simple, local, glanceable display.

That matters because invisible automation is harder to trust.

Visible automation is easier to supervise.

Safety / Ethics Boundary

This project is for visibility and diagnostics only.

It is not designed to:

  • bypass usage limits
  • evade quotas
  • rotate accounts
  • scrape private dashboards
  • automate abuse
  • hide usage

The goal is to show local state and make agent/runtime behavior easier to understand.

The meter is an awareness tool, not a bypass tool.

Current Status

AI Desk Meter is currently a DIY starter package with:

  • README and GitHub Pages project page
  • Python host daemon direction
  • mock/manual provider flow
  • normalized JSON payload
  • ESP32-S3 AMOLED firmware scaffold
  • examples
  • enclosure notes
  • polished HTML spec guide
  • roadmap toward multi-AI meter support

The first target is a small ESP32-S3 AMOLED board.

The host computer does the usage collection and estimation.

The display receives a simple JSON state and renders it.

Future Roadmap

Next steps for Hermes Meter:

  • Add a Hermes Agent provider adapter
  • Add local runtime state mapping
  • Add “Musing / Working / Generating / Stalled / Timeout” display modes
  • Add local GGUF / llamafile status integration
  • Add ARC runtime receipt/status integration
  • Add BLE pairing
  • Add OTA update path
  • Add more display skins
  • Add multi-agent / multi-provider mode
  • Add physical alert states for stalled generation
  • Add a tiny “agent heartbeat” animation

Closing Thought

Open agents should not be invisible.

If Hermes Agent is planning, thinking, generating, stalled, or complete, the developer should be able to see that state locally.

That is the core idea of Hermes Meter:

Hermes Agent for work.

AI Desk Meter for visibility.

Local JSON for state.

ESP32-S3 for physical presence.

A tiny display for agent awareness.
🐝 Real-Life Debugging Story + Home Network Analysis: Peekyport 🫣

Peekyport Logo

There is, for the second time in a month, a yellow jacket in the basement. You know what else is in my basement? My favorite machine.

The first time this happened, it was early and I was getting ready for work. I saw something moving on my bottle of heat-protectant spray. It looked like a really fat caterpillar, but it had wings. I sat there for a second pretending like nothing was happening. It was distracted by the smell of the heat protectant.

I slowly turned off my hair straightener and set it down, backing away semi normally. (Ladies, who hasn’t done their hair in front of their device. 😂) I realized that this was not an average bee. This was not a regular puffy bumble bee, or a sweat bee, or a honey bee. This bee looked like it was a soulless attacker.

I alerted my boyfriend immediately. I did not want anything bad to happen to him while he was sleeping. These yellow jackets attack for no reason. While I was at work, he picked a fight with the yellow jacket and thankfully won. I was so scared for him. The following morning, I saw a dead yellow jacket inside my computer case. 😭

That sounds like 2 yellow jackets so far. After a month passes, I am sitting there minding my own business and BAM, another one! I saw it just barely land on the top of the bookshelf out of the corner of my eye! I think to myself: “**** this, I am moving out!”

My boyfriend got traps and crack sealer for the basement, seeing my state of petrification. They have been setting out for a few days. But he went to work and could not save me until he came back. (Yes, it is save the princess when there is a direct threat buzzing around.) Therefore, I must stay up on the second floor. I am not moving until I see a dead bee. I have not been in the basement and I absolutely refuse to go down there until there is undeniable evidence.

But my computer is in the basement…

My 7-year-old mac is no match for my 2-year-old custom desktop. I must use it. But how? I had one of those moments where a tiny lightbulb went on. I wanted to get to a specific project of mine so I could share the tiny excitement with everyone.

Remote Access for the win

I remembered that I installed a remote app on my phone so I could see my pc screen whenever and wherever. (LOVE that btw). Since it’s all synced through google anyways, I was like well hey, let me pull that bad boi up! Like butter, I see my pc desktop. I messed around with it but my pc desktop is much wider than my laptop, so it wasn’t a perfect situation. I discovered I couldn’t record my pc screen while remoting in from mac. I tried it a few times with no luck. (What’s up with that?)

Then I remembered I had made a shared folder for my local network. (Just to prove to myself I knew how at the time.) I saw that it was still there. Ah! So this is what networking is really for! To save us from ourselves and evil bugs!

So then, I copy over the project folder of interest to shared location, and then put a copy on my macbook. So, as you likely know, we can not just open up a project and run it on mac, if it was built on a windows pc. There is some convertabobbing involved. I had copilot CLI do the fantabulous converting.

All of this so I could share:

Project Peekyport

Peekyport Logo

It’s a home network analysis and organization tool that I am building from scratch. Well, yes from scratch but ai-assisted because I am just learning Java. Which btw Java appears to be more verbose than Python and Ruby I am also finding. Why do I have to tell you it’s a string? Python and Ruby are not like that. I digress.

App Name: Peekyport

Tech used:

  • JavaFX
  • Nmap
  • tshark
  • Custom CSS
  • Draggable topology
  • Local storage
  • and an interface to connect your router of choice.

This is not a web app. It is a thick-client JavaFX network tool with direct OS integration and minimal dependency footprint. I made it over-the-top with “levels” to represent the floors in a building. One can place nodes around and get a better idea of what your topology actually looks like!

I built this because all the cool-looking tools are not free, and I wanted an engaging one. This is by no means perfect or a finished product, but I wanted to share my excitement.

Quick Layout Overview

Peekyport Overview

Before Peekyport becomes interesting, we need to scan the network in question. You can run a lightweight scan that covers only the most common ports, or a deep scan which would take much longer. A light scan is adequate for tinkering purposes. When the scan is run, I created a visual console display so the actual scanning can be seen in real time with a progress bar. The visual feedback is nice to clarify that things are actually happening. Bonus: it looks cool.

Here you can see a scan in progress in Peekyport:

Scan in progress

After scanning your network, nodes will display in the central area in the Topology Tab. With each node you can edit:

  • Name
  • Category
  • Group
  • Floor Number
  • Shape and color to differentiate items
  • Upload images to help you additionally identify

Node interface

Connect to your router by navigating to the router page and entering the details.

Connecting home router

Connecting your router, scanning your network, and comparing it to your wireshark packets gives you a good peek into possible security holes. This allows a user to draw actionable insights for tightening things up on a home network. Being careful with what you are exposing ensures you are less prone to security issues.

Cool! Now having our basic network topology from the grass-roots network scan and our router connected to allow more specific details, we can run a small wireshark scan and import the saved pcap file. About 2,000 packets or so should give you enough to poke around with. 🤔

Heading to the Web Traffic Tab, we select a packet capture for analysis.

pcap file uplaoder

Here is a screenshot of the per device traffic activity after upload:

Traffic by device

Depending on your scan and what network you are connected to, you will see the corresponding devices. On a wifi network scan, you will only see wifi links. If you run a scan connected to ethernet directly, you will choose “hardwire” in the link view. If you do not have the right one selected, you won’t see the links because they do not exist. Makes sense.

I really, really like the network topology link visualization. I feel like I can gain a much better understanding by see what devices speak to each other, through what ports, and how much. Now I can confront household memembers when they overtake the network bandwidth, with my new network facts. Empowering, isn’t it? 😂 JK, my bandwidth has actually not been a problem thanks to dynamic quality of service.

logical wifi links

Network safety by severity is found in the safety tab:

Overview findings

This provides a snapshot of home network security. Many internet users do not have the need or resources to have a fancy enterprise grade network solution for their home. This app empowers a single individual to investigate their home network with a home router, keeping data secure by running it locally.

For everyone

This app pulls web traffic together with IP addresses, mac addresses, and conversations between these addresses to gain insights about what can be addressed to improve security. It’s super nice to be able to monitor traffic in such a specific modular way, with each device and all of is ports listed.

It makes learning about your home network fun and de-mystifies the seemingly intangible network activity for all. I think every home network should have something like this.

For the future

I am struggling a bit with the drag and drop interface, it behaves in an unexpected manner and there is a lot of weird layering and processes happening if other processes happen. It was so bad at one point I was about to trash the whole thing. But I have been powering through it, and I am slightly less frustrated although it’s still not great. The data part is working gracefully. I will continue to fight with the UI until I am satisfied. (So, no end in sight for the foreseeable future. LOL)

What network analysis tools have you built? Comments, tips, questions?

Thank you for reading my tiny story. 💜

I Ran Hermes Agent Locally on CPU-Only Hardware With llamafile — No GPU, No Server, No Cloud API

This is a submission for the Hermes Agent Challenge

What I Built

I built a CPU-first Hermes Agent runtime pattern that removes the hard requirement for a GPU server, hosted model endpoint, cloud API, or always-online backend.

Most AI agent demos quietly assume access to expensive infrastructure.

This one asks a different question:

What if Hermes Agent could run local GGUF model generation on CPU-only hardware, stream output visibly as it generates, track every output unit, and timeout safely when generation stalls?

The runtime pattern uses llamafile as the local execution layer for compatible GGUF models.

That means the agent can run directly on a normal machine without requiring:

  • a GPU
  • a hosted inference server
  • a rented cloud backend
  • a remote model API
  • an always-online agent service

Instead, the local flow is:

Hermes Agent
  ↓
local runtime wrapper
  ↓
llamafile
  ↓
compatible GGUF model
  ↓
CPU inference
  ↓
streamed tracked output
  ↓
timeout-safe result

This is grounded in my existing local AI work in LuciferAI_Local, which focuses on local/offline assistant behavior, llamafile / GGUF model use, and privacy-first execution without requiring cloud infrastructure.

The goal is not to claim every model will be fast on every CPU.

The goal is to remove GPU/server access as a hard requirement for local agent experimentation.

The Problem

Agent systems are only useful if developers can actually run them.

But many local AI workflows break down because they require one of these:

  • a GPU workstation
  • a hosted model server
  • a paid cloud API
  • a remote inference endpoint
  • or enough hardware power to hide slow generation

That blocks a lot of people from experimenting with local agents.

It also creates privacy and portability problems.

If the model call has to leave the machine, then the agent is not truly local-first.

This project focuses on the opposite path:

Hermes Agent → local llamafile → compatible GGUF on CPU → streamed tracked output → timeout-safe result

Demo

The basic runtime flow looks like this:

User task
  ↓
Hermes Agent receives the task
  ↓
Runtime sends the prompt to local llamafile / GGUF backend
  ↓
The model runs locally on CPU
  ↓
Output streams back word-by-word or chunk-by-chunk
  ↓
Each generated unit is tracked
  ↓
A watchdog monitors the time since the last output
  ↓
If nothing new appears, the run times out safely
  ↓
Partial output and generation metadata are preserved

Example successful run:

$ hermes-local run --model ./models/example.gguf --timeout 20

[engine] llamafile
[model_format] GGUF
[mode] cpu-first
[gpu_required] false
[server_required] false

Hermes
is
running
locally
through
llamafile
with
tracked
generation
...

[status] completed
[generated_units] 11
[timeout_triggered] false

Example timeout-safe run:

$ hermes-local run --model ./models/example.gguf --timeout 20

[engine] llamafile
[model_format] GGUF
[mode] cpu-first
[gpu_required] false
[server_required] false

Hermes
started
locally

[watchdog] no new output detected for 20s
[status] timed_out
[partial_output_preserved] true

Example successful generation record:

{
  "run_id": "cpu-gguf-demo-001",
  "engine": "llamafile",
  "model_format": "GGUF",
  "execution_mode": "cpu_first",
  "gpu_required": false,
  "server_required": false,
  "stream_mode": "word_or_token_chunk_streaming",
  "generated_units": 11,
  "last_generated": "generation",
  "status": "completed",
  "timeout_triggered": false
}

Example timeout record:

{
  "run_id": "cpu-gguf-demo-002",
  "engine": "llamafile",
  "model_format": "GGUF",
  "execution_mode": "cpu_first",
  "gpu_required": false,
  "server_required": false,
  "stream_mode": "word_or_token_chunk_streaming",
  "generated_units": 4,
  "last_generated": "locally",
  "status": "timed_out",
  "timeout_triggered": true,
  "partial_output_preserved": true,
  "reason": "no new generation detected inside timeout window"
}

The important part is that the model call becomes observable.

The agent is no longer blindly waiting for a local model process to finish.

The runtime can see whether generation is alive, slow, stalled, completed, or failed.

Code

Main proof/reference repo:

  • LuciferAI_Local — local/offline assistant direction using llamafile / GGUF execution without a required cloud API.

Supporting local-agent infrastructure:

  • ARC-Neuron LLMBuilder — local AI build-and-memory system focused on model promotion, benchmark receipts, and governed model improvement.
  • arc-lucifer-cleanroom-runtime — local-first runtime direction for receipts, replay, rollback, ranked memory, and sandboxed AI execution.
  • ARC-Core — event/receipt spine for tracking state changes and execution records.
  • ARC-StreamMemory — local visual/session memory direction for agent-readable frame and screen evidence.
  • omnibinary-runtime — binary-first runtime direction for intake, classification, planning, and execution records.
  • Arc-RAR — archive/rollback direction for preserving runs and project state.
  • TizWildin Entertainment HUB — public hub for the broader software, AI, automation, and audio ecosystem.

My Tech Stack

  • Hermes Agent
  • llamafile
  • compatible GGUF models
  • CPU-first local inference
  • Python runtime wrapper
  • local process / local HTTP streaming
  • word-by-word or token/chunk streaming
  • generation progress tracking
  • timeout watchdog
  • partial output preservation
  • JSON / JSONL generation records
  • local-first execution
  • optional ARC-style receipt/event logging

The core runtime pattern is:

Prompt
  ↓
llamafile / GGUF
  ↓
CPU generation
  ↓
streamed words or token chunks
  ↓
generation tracker
  ↓
timeout watchdog
  ↓
final or partial result

Conceptual Python-style loop:

import time

last_output_time = time.time()
generated_units = []
timeout_seconds = 20

for chunk in stream_from_llamafile(prompt):
    units = tokenize_or_split_output(chunk)

    for unit in units:
        generated_units.append(unit)
        last_output_time = time.time()
        print(unit, flush=True)

    if time.time() - last_output_time > timeout_seconds:
        raise TimeoutError("No new generation detected.")

The important part is the watchdog.

The agent does not wait forever.

The runtime tracks whether new output is arriving.

If generation stops for too long, the runtime can timeout safely, preserve partial output, and let the agent decide whether to retry, fallback, or stop.

How I Used Hermes Agent

Hermes Agent is the agentic workflow layer that benefits from this CPU-first runtime.

The runtime gives Hermes Agent a local model execution path that does not require a GPU server or remote inference endpoint.

That matters because local agent execution should be accessible.

A developer should be able to experiment with an agent on a normal machine, using a compatible GGUF model, without needing to deploy a backend server or rent GPU time just to see the agent think.

In this pattern:

  • Hermes Agent supplies the agent workflow.
  • llamafile supplies the local GGUF execution path.
  • The CPU supplies the inference hardware.
  • The stream tracker supplies liveness.
  • The tokenizer/chunker turns raw output into trackable generation units.
  • The timeout watchdog supplies safety.
  • The local record preserves final or partial output.

Together, it creates an agent runtime that can answer:

  • Did the local model start generating?
  • Is it still generating?
  • Is it generating slowly or normally?
  • How much has it generated?
  • What was the last token, word, or chunk?
  • Did it stall?
  • Did it timeout safely?
  • Is there partial output worth preserving?
  • Should the agent retry, fallback, or stop?

That turns local model generation into an observable process instead of a blind wait.

Why This Negates the Usual GPU / Server Requirement

A GPU can make inference faster.

A server can make deployment easier for teams.

But neither should be mandatory for a basic local agent runtime.

llamafile makes this practical because it packages local model execution into a developer-friendly form that can run compatible GGUF models directly on the machine.

That means the agent runtime can be designed around:

  • local files
  • local processes
  • CPU execution
  • local streaming
  • local generation tracking
  • local timeout rules
  • local logs
  • local privacy

The practical result:

Instead of:
Hermes Agent → remote API/server/GPU backend → response

Use:
Hermes Agent → local llamafile → compatible GGUF on CPU → streamed tracked response

This does not mean every GGUF will be fast on every CPU.

Large models still need enough RAM, and model size/quantization matter.

But the runtime no longer requires a GPU or external server as a hard dependency.

That is the key win.

It makes agent experimentation more accessible, more private, and more portable.

What This Changes

Usual agent setup CPU-first Hermes setup
Cloud API required Local model file
GPU server expected CPU-first execution
Remote endpoint dependency Local llamafile process
Waits silently Streams visibly
Can hang forever Timeout watchdog
Final answer only Tracked generation record
Failure loses output Partial output preserved

Tokenized / Chunked Output Tracking

Streaming alone is useful, but tracking the stream is what makes it agent-safe.

The runtime should not only print output.

It should record generation progress.

That can include:

  • generated token/chunk count
  • generated word count
  • time of first output
  • time of last output
  • tokens or chunks per second
  • timeout threshold
  • final status
  • partial output
  • error reason
  • retry/fallback decision

Example run metadata:

{
  "run_id": "tracked-local-generation-001",
  "first_output_after_ms": 812,
  "last_output_after_ms": 6912,
  "generated_units": 42,
  "timeout_seconds": 20,
  "status": "completed",
  "partial_output_preserved": true
}

This gives Hermes Agent a much better local model boundary.

Instead of asking only, “What was the answer?” the runtime can ask:

Did generation begin?
Did it keep moving?
Did it stall?
Did it finish?
What partial state can be saved?

For agents, that difference matters.

Older Hardware Direction

This runtime pattern is designed to be friendly to older CPU-only machines.

The goal is not to pretend old hardware will run huge models quickly.

The goal is to make the runtime graceful:

  • small compatible GGUF models can run locally
  • output appears progressively
  • slow generation is still visible
  • stalls are detected
  • partial output is not lost
  • timeouts prevent infinite waits
  • the agent can fallback instead of freezing

That means limited hardware can still participate in local AI workflows.

The machine does not need to be a GPU workstation to be useful.

Current Status

This is an experimental Hermes Agent challenge submission focused on a local-first runtime pattern.

The current focus is:

  • CPU-first compatible GGUF execution through llamafile
  • removing hard GPU dependency for local agent experiments
  • removing hard server/API dependency for local agent experiments
  • word-by-word or token/chunk streaming
  • generation progress tracking
  • timeout detection when no new output appears
  • partial output preservation
  • older-hardware-friendly execution direction
  • future ARC-style run receipts and replay logs

It is not presented as a finished production inference framework.

It is a practical runtime direction for making local Hermes Agent workflows more observable, safer, more portable, and easier to debug.

Future Roadmap

Next steps:

  • Add a clean demo script for running a compatible GGUF through llamafile
  • Add configurable timeout windows
  • Track generated words, chunks, and token timing
  • Save generation records as JSONL
  • Add retry and fallback behavior
  • Add ARC-style receipts for each generation run
  • Add replayable local run manifests
  • Connect successful and failed runs into the broader ARC runtime archive
  • Add UI indicators for “generating,” “slow,” “stalled,” “timed out,” and “completed”
  • Document old-hardware test profiles from LuciferAI_Local-style runs
  • Add model-size guidance for CPU-only GGUF usage

Closing Thought

A local agent should not need a GPU server just to begin thinking.

Hermes Agent gives the workflow.

llamafile gives the local GGUF execution path.

The stream tracker gives liveness.

The timeout watchdog gives safety.

That is the whole point:

Run locally.

Require no GPU.

Require no server.

Stream visibly.

Track generation.

Timeout safely.

Preserve the run.

Huawei’nin fotoğraf yarışmasında dünya ikincisi olan Mehmet Emin Coruş, “imha edildi” denilen ödülüne kavuştu

Mehmet Emin Coruş

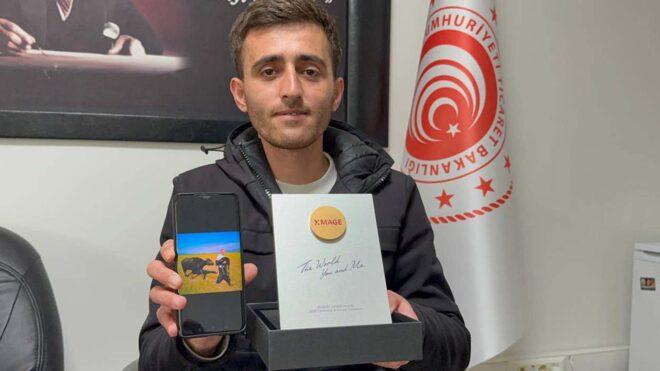
Mehmet Emin CoruşHuawei’nin uluslararası “XMAGE” fotoğraf yarışmasında dünya ikincisi olan Mehmet Emin Coruş, vize alamadığı için ödül törenine katılmadı ancak Fransa’dan gönderilen ödül plaketi ve sertifikasına sonunda kavuştu. Geçtiğimiz günlerde “ödül paketi imha edildi” haberleriyle gündeme gelen Coruş, olumlu sonuçlanan durum ile alakalı olarak İHA’ya şunları söyledi: “Firma tarafından gönderilen İngilizce mailin Türkçeye çevrilmesiyle bir yanlış anlaşılma yaşandığını söyleyen amatör fotoğrafçı Mehmet Emin Coruş ise “Bildiğiniz üzere 2025 yılında uluslararası fotoğraf yarışmasında ben bir ödül kazanmıştım. Maalesef vize alamadığım Paris’e için gidememiştim. Ödülüm Türkiye’ye gelmişti. Kupamla sertifikam da gümrük sürecine takılmıştı. Gümrük yetkilileriyle yaptığımız görüşmelerden sonra XMAGE şirketiyle görüşmeye başladım. Onlar da bana bir mail attılar. XMAGE firmasından bana gelen mail İngilizce yazıyordu. Bu metni Türkçe metne çevirdiğimde imha edildiği yazıyordu. Biz de bunu haber yaptık. Bunun üzerine bakanlık devreye girdi. Bana ulaştılar. ’Ödülünüz imha edilmemiş, gümrükte bekliyor’ dediler. Bakanlığımız bu olaya hızlıca müdahale etti” Ticaret İl Müdürü Ali Osman Sakar ise […]

Huawei’nin fotoğraf yarışmasında dünya ikincisi olan Mehmet Emin Coruş, “imha edildi” denilen ödülüne kavuştu yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Ultimate Guide on React cleanup function

If you’ve been using React for some time you may be familiar with the term “cleanup function” when working with side effects, it may be confusing at first or sometimes you don’t make sense out of it.

In this guide I will explain the use of cleanup function so you can start using it with confidence and clarity.

Table of Contents

  • What is a cleanup function
  • Why use a cleanup function (with example)
  • Summary

What is a cleanup function

A cleanup function in React is the function you return from inside a useEffect, React calls cleanup function when the component unmounts or before the effect re‑runs, so you can stop timers, cancel requests, or remove event listeners.

In development, StrictMode intentionally mounts, unmounts, and re‑mounts components once to check that your cleanup logic works correctly. This helps catch bugs with side effects early.

Not every effect needs cleanup — only those that start something ongoing (like a subscription or fetch).
Without cleanup, you risk inconsistent UI updates or memory leaks.

Why use a cleanup function (with example)

Let’s take an example of fetching data from an API and have the pagination in place and a select menu to select where you to start fetching data.

First create a function to fetch the comments using a dummy API (https://dummyjson.com/comments) that receives an argument of where to start while fetching the data.

export default function CleanUpComponent(start) {
  function fetchComments(start) {
    return new Promise((resolve) => {
      setTimeout(() => {
        fetch(`https://dummyjson.com/comments?skip=${start}`)
          .then((res) => {
            resolve(res.json());
          })
          .catch((err) => Error(err));
      }, 3000);
    });
  }
}

In the function you return a new promise and then we add setTimeout function to wait for three (3) second before returning the response,

Note: “that the setTimeout here is just to simulate a slow network for demonstration purposes — in a real app you wouldn’t need it”.

why setTimeout? to observe the importance of having the cleanup function we need to delay the time it may take to respond for the users with poor network signals or in any case where we the network may be slow for some reason.

And then create a state that will track the selected starting id when fetching and then the state to store and display the fetched data.

import { useEffect, useState } from "react";

export default function CleanUpComponent() {

  const [dataDisplay, setDisplay] = useState([]);
  const [loading, setLoading] = useState(true);
  const [start, setStart] = useState(0);

  function fetchComments(start) {
    return new Promise((resolve) => {
      setTimeout(() => {
        fetch(`https://dummyjson.com/comments?skip=${start}`)
          .then((res) => {
            resolve(res.json());
          })
          .catch((err) => Error(err));
      }, 3000);
    });
  }

  useEffect(() => {
    setLoading(true);

    fetchComments(start)
      .then((res) => setDisplay(res["comments"]))
      .catch((err) => console.error(err))
      .finally(() => setLoading(false));
  }, [start]);
}

Inside the component then add a useEffect to perform the fetch operation and synchronize the application with you’re react application, and we can display the data on the screen.

  return (
    <>
      <select
        name=""
        id=""
        onChange={(e) => setStart(Number(e.currentTarget.value))}
      >
        <option value="select an option">--select an option to start with</option>
        <option value="5">5</option>
        <option value="10">10</option>
        <option value="15">15</option>
      </select>

      {loading && <p>loading....</p>}

      {!loading &&
        dataDisplay.slice(0, 6).map((element) => {
          return (
            <p key={element.id}>
              {element.id}: {element.body}
            </p>
          );
        })}
    </>
  );
}

This approach works but there is an issue in the above snippet, if you try choosing a different number in the option menu to start with fetching while the previous fetching is still going on.

The UI will show inconsistent data which can cause frustration to user using the site.

If you observe the above demo example you can see that we first select 10 as the starting point while it is still fetching,

we change the number to start at 5 and after a few seconds in our case 3 seconds remember we’ve used it as a delay for the timer to call a function,

the screen shows the data from 11 but then suddenly that UI changes to data from 6.

This kind of data inconsistency is known as a race condition. A race condition occurs when multiple async requests finish out of order, and an outdated request updates the UI after a newer one.

if you were reading through fetched data and suddenly the UI changes the data that a big frustration and a red flag to a site.

Cause

The cause for this kind of behavior is that when fetching the useEffect will send the first request while it is still going on we fire another fetch and then the first request will resolve after a few seconds the last request will also resolve and updates the existing state and component re-renders which updates the UI.

Solution:

The solution is to use a cleanup function in the useEffect to clear out any previous running task and instead continue with the current requested request, the cleanup function is defined by returning function that will clear out the previous request.

For this example, use the abortController to cancel any previous running task in the background, change the function to fetch to receive the second argument which will be a controller which will use to cancel the previous request.

if you are not familiar with abortController you can read more about it using this AbortController – Web APIs | MDN

 function fetchComments(start, controller) {
    return new Promise((resolve) => {
      setTimeout(() => {
        fetch(`https://dummyjson.com/comments?skip=${start}`, {
          signal: controller.signal,
        })
          .then((res) => {
            resolve(res.json());
          })
          .catch((err) => Error(err));
      }, 3000);
    });
  }

There is the signal option on fetch API that helps to abort or cancel request based on the signal provided, and abortController we have a signal property that ties together the current fetch call signal with the abortController and then abort the previous request in the cleanup function.

useEffect(() => {
     //creation of abortcontroller.
    const controller = new AbortController();

    setLoading(true);
    fetchComments(start, controller)
      .then((res) => setDisplay(res["comments"]))
      .catch((err) => console.error(err))
      .finally(() => setLoading(false));

   // cleanup function to abort the previous request.
    return () => {
      controller.abort();
    };
  }, [start]);

Create a controller variable to hold the abortController instance and the pass it in the function you have created to fetch the data and in the cleanup function call the abort() on the controller instance to stop the request that was not finished.

Now if we try switching the options instantly the data will be consistence and they will be no race conditions.

I have added logs before the cleanup and after to show you how the cleanup works, if you want you can add a console log before the abort and another one after aborting the request.

now if you were to switch to another number while there are some fetching that are going on they will be aborted and then fetch the latest request now you can see that there are no flash data changes like we had before.

Summary

The cleanup function is essentially used to remove and clear side effects tasks that are still running in the background when the component is unmounted, or the effect is going to re-run.

To avoid problems like race conditions, memory leaks and many more issues that can be caused the side effects fetching.

How I Test My Node.js Apps: A Practical Guide (2026)

How I Test My Node.js Apps: A Practical Guide (2026)

Testing doesn’t have to be complicated. Here’s the minimal setup that catches real bugs.

The Truth About Testing

Most developers know they should test.
Few actually do it consistently.

Why?
→ "I don't have time"
→ "My code is too simple to test"
→ "Setting up tests is annoying"
→ "Tests break when I refactor"

Here's my counter-argument:
→ Tests catch bugs before users do
→ Tests document how your code works
→ Tests give you confidence to refactor
→ The "minimal" setup takes 15 minutes

My Testing Stack

Layer Tool Why
Unit tests Node.js built-in test runner Zero dependencies
HTTP APIs node:test + undici dispatch Built into Node.js 18+
Integration Custom scripts with supertest Simple, predictable
E2E Playwright Reliable, fast, free

Total cost: $0. Everything here is free and open source.

Step 1: Unit Testing with Node.js Built-in Runner

No need for Jest or Mocha anymore. Node.js has its own test runner since v18:

# No installation needed — it's built in
node --test

Basic Example

// math.js
export function add(a, b) {
  return a + b;
}

export function divide(a, b) {
  if (b === 0) throw new Error('Division by zero');
  return a / b;
}
// math.test.js
import { describe, it } from 'node:test';
import assert from 'node:assert/strict';
import { add, divide } from './math.js';

describe('Math utilities', () => {
  it('should add two numbers', () => {
    assert.equal(add(2, 3), 5);
  });

  it('should handle negative numbers', () => {
    assert.equal(add(-1, 1), 0);
  });

  it('should throw on division by zero', () => {
    assert.throws(() => divide(10, 0), {
      message: 'Division by zero'
    });
  });
});
$ node --test
✓ Math utilities (4.8ms)
✓ should add two numbers
✓ should handle negative numbers
✓ should throw on division by zero

ℹ tests 3
ℹ pass 3
ℹ fail 0
ℹ duration 15ms

Async Code Testing

import { describe, it } from 'node:test';
import assert from 'node:assert/strict';

describe('API calls', () => {
  it('should fetch data successfully', async () => {
    const response = await fetch('https://api.example.com/data');
    const data = await response.json();

    assert.ok(data.items);
    assert(Array.isArray(data.items));
  });

  it('should timeout after 5 seconds', async () => {
    const controller = new AbortController();
    setTimeout(() => controller.abort(), 5000);

    await assert.rejects(
      async () => fetch('https://slow-api.example.com', {
        signal: controller.signal
      }),
      { name: 'AbortError' }
    );
  });
});

Step 2: Testing Express.js APIs

This is where most side projects need testing:

// app.js
import express from 'express';

const app = express();
app.use(express.json());

let items = [];

app.get('/api/items', (req, res) => {
  res.json({ items });
});

app.post('/api/items', (req, res) => {
  const { name } = req.body;
  if (!name) return res.status(400).json({ error: 'Name required' });

  const item = { id: Date.now(), name };
  items.push(item);
  res.status(201).json(item);
});

export default app;
// app.test.js
import { describe, it, beforeEach } from 'node:test';
import assert from 'node:assert/strict';
import createApp from './app.js';

describe('Items API', () => {
  let app;

  beforeEach(() => {
    app = createApp();
  });

  it('GET /api/items returns empty array initially', async () => {
    // We'll use undici's MockAgent for mocking HTTP
    // Or use supertest-style approach
  });

  it('POST /api/items creates an item', async () => {
    // Test implementation below
  });
});

Using Supertest for API Testing

npm install --save-dev supertest
// app.test.js (with supertest)
import { describe, it, beforeEach } from 'node:test';
import assert from 'node:assert/strict';
import request from 'supertest';
import createApp from './app.js';

describe('Items API', () => {
  let app;

  beforeEach(() => {
    app = createApp();
  });

  it('GET /api/items returns empty array initially', async () => {
    const res = await request(app).get('/api/items');
    assert.equal(res.status, 200);
    assert.deepEqual(res.body, { items: [] });
  });

  it('POST /api/item creates item with valid data', async () => {
    const res = await request(app)
      .post('/api/items')
      .send({ name: 'Test Item' })
      .expect('Content-Type', /json/);

    assert.equal(res.status, 201);
    assert.equal(res.body.name, 'Test Item');
    assert.ok(res.body.id);
  });

  it('POST /api/items rejects missing name', async () => {
    const res = await request(app)
      .post('/api/items')
      .send({})
      .expect(400);

    assert.equal(res.body.error, 'Name required');
  });
});

Step 3: Testing Database Operations

For SQLite (what I use in production):

// db.test.js
import { describe, it, beforeEach, afterEach } from 'node:test';
import assert from 'node:assert/strict';
import Database from 'better-sqlite3';
import fs from 'fs';
import path from 'path';

const TEST_DB_PATH = path.join('/tmp', `test-${Date.now()}.db`);

describe('Database operations', () => {
  let db;

  beforeEach(() => {
    db = new Database(TEST_DB_PATH);
    db.exec(`CREATE TABLE users (
      id INTEGER PRIMARY KEY,
      email TEXT UNIQUE NOT NULL,
      created_at TEXT DEFAULT CURRENT_TIMESTAMP
    )`);
  });

  afterEach(() => {
    db.close();
    try { fs.unlinkSync(TEST_DB_PATH); } catch {}
  });

  it('inserts and retrieves a user', () => {
    const stmt = db.prepare('INSERT INTO users (email) VALUES (?)');
    const result = stmt.run('[email protected]');

    assert.ok(result.lastInsertRowid);

    const user = db.prepare('SELECT * FROM users WHERE id = ?').get(result.lastInsertRowid);
    assert.equal(user.email, '[email protected]');
  });

  it('rejects duplicate emails', () => {
    const stmt = db.prepare('INSERT INTO users (email) VALUES (?)');
    stmt.run('[email protected]');

    assert.throws(() => {
      stmt.run('[email protected]');
    }, /UNIQUE constraint failed/);
  });
});

Key pattern: Use a fresh database file for each test run (Date.now() ensures uniqueness).

Step 4: Running Tests Automatically

package.json Scripts

{
  "scripts": {
    "test": "node --test",
    "test:watch": "node --test --watch",
    "test:coverage": "node --experimental-test-coverage --test"
  }
}

With GitHub Actions (Free CI)

# .github/workflows/test.yml
name: Tests
on: [push, pull_request]
jobs:
  test:
    runs-on: ubuntu-latest
    strategy:
      matrix:
        node-version: [18, 20, 22]
    steps:
      - uses: actions/checkout@v4
      - uses: actions/setup-node@v4
        with:
          node-version: ${{ matrix.node-version }}
      - run: npm install
      - run: npm test

This runs your tests on 3 Node.js versions every push. Free for public repos.

What I Actually Test (And What I Skip)

✅ TEST thoroughly:
   → Business logic (calculations, validations, transformations)
   → API endpoints (request/response format, error handling)
   → Database queries (CRUD operations, constraints)
   → Authentication flows (login, token validation)

⚠️ TEST lightly:
   → Utility functions (simple pure functions)
   → Configuration loading
   → Basic CRUD scaffolding

❌ SKIP (usually):
   → UI/CSS (use visual testing tools instead)
   → Third-party library behavior (they have their own tests)
   → Static content pages

The 80/20 Rule of Testing

20% of your code handles 80% of the complexity → TEST THIS PART

Focus on:
1. Conditional logic (if/else, switch/case)
2. Error handling paths
3. Data transformations
4. External API integrations
5. Authentication & authorization

Don't waste time testing getters/setters or trivial components.

Common Mistakes I Made (So You Don’t Have To)

Mistake #1: Testing Implementation Details

// ❌ Bad — tests internal structure
it('calls save() once', () => {
  assert.equal(mockSave.callCount, 1);
});

// ✅ Good — tests observable behavior
it('persists data correctly', () => {
  const saved = db.query('SELECT * FROM users');
  assert.equal(saved.length, 1);
});

Mistake #2: Over-mocking

// ❌ Bad — mocking everything makes tests fragile
const mockDb = { query: mockFn, exec: mockFn, prepare: mockFn };

// ✅ Good — use real database (SQLite is fast enough)
const db = new Database(':memory:');

Mistake #3: Ignoring Error Paths

// Most developers only test happy path
it('returns user data', () => { ... });

// Also test what happens when things go WRONG
it('handles database connection failure', () => { ... });
it('returns 404 for non-existent user', () => { ... });
it('validates malformed input', () => { ... });

Quick Reference: Assertion Cheatsheet

import assert from 'node:assert/strict';

// Equality
assert.equal(actual, expected);       // ==
assert.notEqual(actual, expected);    // !=
assert.deepEqual(actual, expected);   // deep object compare

// Types & existence
assert.ok(value);                     // truthy
assert.strictEqual(a, b);             // ===
assert.typeOf(value, 'string');       // type check

// Exceptions
assert.throws(fn, { message: /.../ }); // must throw matching error
assert.doesNotThrow(fn);              // must not throw

// Promises
await assert.rejects(asyncFn);        // promise must reject
await assert.doesNotReject(asyncFn);  // promise must resolve

What’s your testing setup? Are you using the built-in test runner yet?

Follow @armorbreak for more practical Node.js guides.

Resources:

Catch docs-to-code drift in TypeScript PRs before merge

A PR changes API docs. Tests pass.

But during review, there is still an awkward question: which code path is
supposed to back this doc claim?

I built AnchorMap, an open-source CLI for TypeScript repositories, for that gap.

AnchorMap makes that link explicit.

A documented claim can start with an anchor:

### DOC.ROUTING.REQUEST_CONTEXT Request context propagation

You map that anchor to one or more TypeScript seed files:

mappings:
  'DOC.ROUTING.REQUEST_CONTEXT':
    seed_files:
      - 'src/router.ts'

From src/router.ts, AnchorMap walks the parts of the local TypeScript
import/export graph it can currently analyze and publishes a Markdown report in
the GitHub Actions workflow summary and artifacts.

For example, if a session-security claim is added without a mapping, the PR
report says so:

- {"kind":"unmapped_anchor","anchor_id":"UTILS.SESSION.COOKIE_SECURITY"}

The result is a review trail, not a verdict: reviewers can inspect whether a
documented claim still points to the TypeScript files expected to support it.

The review gap

In TypeScript projects, docs and implementation can drift during normal
maintenance:

  • a new API behavior is documented before the implementation lands;
  • a refactor moves code that used to satisfy a documented behavior;
  • a stale spec-like statement stays in Markdown after code changes;
  • reviewers know the code, but not every requirement captured in Markdown.

Tests, docs linters, PR templates, and CODEOWNERS can all help. They usually do
not show the doc-to-code link reviewers need to inspect.

AnchorMap makes that gap visible in the PR workflow output.

What the report shows

The small example above is the failure shape. A full report also shows summary
counts, policy decisions, change impact, and suggested actions.

Here is a trimmed report from the unmapped-anchor demo PR, with the anchor used
in that demo:

# AnchorMap traceability report

## Summary
- Analysis health: clean
- Observed anchors: 4
- Usable mappings: 3
- Covered product files: 31/58 (53%)
- Findings: 1

## Policy violations
Decision: FAIL
- {"kind":"finding_kind_present","finding_kind":"unmapped_anchor","count":1}

## Change impact
- Comparability: same_scope
- Findings added: 1

## Findings
- {"kind":"unmapped_anchor","anchor_id":"PREVIEW.UNMAPPED_ANCHOR"}

## Suggested actions
- Add a mapping for "PREVIEW.UNMAPPED_ANCHOR".

In this report, “product files” means TypeScript files inside the configured
review scope. A file can be inside that scope but no longer traced from any
mapped anchor.

The report can also flag untraced_product_file when a TypeScript file is
inside the configured scope but no longer reached from any mapped anchor. That
is a review prompt, not dead-code proof.

The demo intentionally sets fail-on-policy: "false", so readers can inspect
failure reports without making the preview PR checks turn red. GitHub may show a
green check while the AnchorMap report says Decision: FAIL in the job summary
or artifact. For this demo, the report is the thing to inspect.

What AnchorMap checks

AnchorMap reads explicit local inputs:

  • Markdown heading anchors or YAML root id anchors;
  • a local anchormap.yaml config;
  • explicit mappings from anchors to TypeScript seed files;
  • for diff-style reports, an explicit baseline scan artifact.

For YAML sources, the anchor can be the root id value:

id: DOC.ROUTING.REQUEST_CONTEXT
title: Request context propagation

It then writes local artifacts that show the scan result, check result, diff,
and review report.

Mappings are explicit. Someone has to write them down, which adds maintenance
cost. The upside is auditability: reviewers can see exactly what was mapped and
why a report changed.

From those inputs, AnchorMap reports findings such as:

  • unmapped anchors, where a doc or spec anchor exists without a code mapping;
  • stale mappings, where a mapping points to an anchor that is no longer
    observed;
  • degraded analysis, where the report still renders but warns that part of the
    TypeScript graph could not be trusted or followed.

The output is meant to be read from the workflow summary or artifact, not in a
separate dashboard.

What the h3 demo shows

The public demo does not cover all of h3, the TypeScript HTTP framework. It
focuses on a small slice and gives readers four no-install PR scenarios: clean,
unmapped anchor, stale mapping, and degraded analysis.

Full setup details: anchormap-h3-demo

The demo PRs are:

Start with the clean demo PR. It shows the passing preview path without asking
you to interpret a failure first.

If you want the shortest failure case after that, open the unmapped-anchor PR:
it shows a spec-like anchor added without a mapping. The report excerpt above
comes from that PR.

Design boundaries

AnchorMap is intentionally narrow.

It reports traceability, not correctness: reviewers still decide whether the
behavior is implemented correctly or safe to delete.

It reads repository files and explicit local artifacts; it does not upload
source code to an AnchorMap service, require a SaaS account, or use AI to guess
mappings.

The preview GitHub Action does not create PR comments by default. It uses
workflow artifacts and job summaries, so the first demo does not need PR comment
permissions.

What I need feedback on

Generating the report is the easy part. The real question is whether maintainers
of TypeScript repositories find explicit mappings useful enough to maintain.

That is why the demo is no-install: inspect the report first, then decide
whether the mapping cost makes sense.

If you maintain a TypeScript repo with docs, API references, or spec-like
Markdown, I am mostly interested in what would block a real trial: mapping
overhead, noisy reports, bad CI fit, or simply not worth maintaining.

Hello, Donna (A new Programming Language)

In the past few months, I have been designing and implementing a new programming language called Donna.

Before I explain more about it, I want to be honest and mention that its development has been heavily assisted by AI.

What’s Donna

Donna is a functional, statically typed, self-hosted programming language that compiles to native binaries using QBE as its compiler backend.

Donna’s syntax is inspired mostly by Gleam, with a few Python-like touches.

Bootstrap story

The current compiler is the Stage 2 compiler (there were previously Stage 0 and Stage 1 compilers) and is independent from the previous implementations.

Before every release, the compiler is tested and built through GitHub Actions. The release pipeline then generates assembly sources for each supported target and stores them in a separate repository. These generated sources are later used to build the next compiler release, continuing the bootstrap process.

Easy to learn

As mentioned before, Donna takes heavy inspiration from Gleam, so it is relatively easy to pick up and build a small project over a weekend.

Donna is intentionally small and aims to stay that way. The vision is:

  • small language
  • great developer experience
  • native binaries that are easy to distribute

Where Donna is strong

In my opinion, some of Donna’s strongest points are:

  • Successfully self-hosted (the Donna compiler is written in Donna)
  • QBE supports the full C ABI, making FFI in Donna very straightforward
  • Clean and pleasant syntax
  • Native binaries
  • Statically typed

Visit us

If you want to check Donna out, try it, discuss it, contribute, or simply follow the project, you can find it here: