Almost 8 Months Building Formgrid From Ghana: $86 MRR, 290+ Users, and What I Actually Learnt

About 7 months ago, I started building Formgrid alone in Ghana with no funding, no audience, and no guarantee anyone would care.

Today, Formgrid has 290+ registered users, 8 paying customers across Europe, Asia, and North America, and $86 MRR. Every single paying customer came from organic content. Zero paid advertising. Zero investors.

This is the honest story of what those 8 months actually looked like.

Why I Built It

I kept running into the same problem as a developer. Every time I built a landing page or a static site, I needed a contact form.
And every contact form meant setting up a backend, configuring email, handling spam, and maintaining infrastructure forever.

All of that overhead just to receive a message from a visitor.

The tools that existed either charged too much, locked basic features behind expensive plans, or stopped at the inbox. A form submission
would arrive as an email, and then what? There was no way to track whether you followed up, whether the lead converted, or whether
it went cold while buried in your inbox.

I built Formgrid to solve both problems at once.

Point your HTML form at a Formgrid endpoint, and every submission becomes a tracked lead with email notifications, Google Sheets sync,
follow-up reminders, and a conversion pipeline. No backend needed. No Zapier. No $90 per month Google Sheets plans.

What Formgrid Looks Like Today

Here is the form builder with landing page templates. Non-technical users can build a complete branded form page without touching
any code:

Formgrid form builder with landing page template selector

Every form submission becomes a tracked lead in the dashboard. New, Contacted, and Converted stages give you a clear picture of your pipeline at a glance:

Formgrid leads tab showing tracked submissions with pipeline stages

You can add private notes to every lead after each conversation so you always know where things stand before you follow up:

Lead detail view showing notes field in Formgrid

You can change the status of a lead as you move it through the pipeline:

Lead status dropdown showing New Contacted Converted options

And you can set a follow-up reminder on any lead. On that date, Formgrid emails you with the lead details and your notes:

Follow up date picker on lead detail page

Follow up reminder email from Formgrid showing lead details and notes

This is the feature that separates Formgrid from every other form tool at this price point. Formspree collects submissions. Formgrid
manages leads.

The Numbers After Almost 8 Months

I want to be completely honest here because I think most building in public posts either cherry-pick good metrics or hide the disappointing ones.

Here are the real numbers:
Registered users: 290+
Paying customers: 8
Monthly recurring revenue: $86
Indexed pages on Google: 42+
Monthly organic clicks from Google: 200+
Best single-day signups: 6
Product Hunt upvotes: 7
Reddit ad conversions: 0

Yes. Product Hunt gave me 7 upvotes and Reddit ads gave me zero conversions. I am including those because they are
part of the real story.

What Actually Worked

SEO Blog Posts Targeting Competitor Alternatives

This is by far the most important thing I learned in seven months.

The posts that brought paying customers were not tutorials. They were not niche use case posts about roofing companies or restaurant websites. They were comparison posts targeting frustrated users of competing tools.

My Formspree alternatives post has 159 views and brought my most valuable customer.
Annie is a San Diego event manager who was using a basic form backend and receiving raw data dumps that her 75-year-old ride manager could not read. She found my post by searching for Formspree alternatives,
signed up the same day, and upgraded to the Business plan at $29 per month within days after I built a custom email template for her endurance horse ride registrations.

That single blog post paid for itself many times over and keeps bringing traffic every month without any additional work from me.

The formula is simple:
Frustrated competitor user

targeted search your blog post is the answer = paying customer

I have now written over 40 blog posts following this formula. Every post targeting a competitor, alternative, or a specific pain
point compounds over time. Each one brings traffic permanently.

Personal Emails to Every New Signup

Every time someone signs up for Formgrid, I send them a personal email within 24 hours. Not an automated sequence. A real email from
me asking what they are building and offering to help them get set up.

Most people do not reply. But the ones who do often become paying customers. Jose replied and told me he needed file uploads for the design files his clients sent through his quote request form. He upgraded to Premium within days.

The personal email also means that when someone hits a bug, they know exactly who to contact, and they trust that a real person will fix it
fast.

Fixing Bugs Fast

Angeline was a bride using Formgrid for her wedding RSVP form. She found a bug where apostrophes in names were being corrupted
in the database. I fixed it the same day she reported it.

She did not just get a fix. She got proof that the person behind Formgrid actually cares about making it work properly for real people using it for real things.

What Did Not Work

Reddit Ads

I ran ads targeting developer subreddits for several weeks. Zero confirmed conversions. Not a single paying customer came from Reddit ads.

Organic helpful replies to people asking about form backends worked far better than paid ads in the same communities.

Product Hunt

I launched on Product Hunt and got 7 upvotes.
No meaningful traffic. One signup.

The honest reason is that Product Hunt rewards founders with large existing audiences. Without thousands of Twitter followers or a newsletter lists that, the launch ceiling is low, regardless of how well you prepare.

Product Hunt gave me a permanent listing and a backlink to formgrid.dev, which has SEO value. But as a growth channel, it did not work for me at this stage.

Niche Use Case Posts

I wrote several posts targeting specific industries like roofing companies and restaurant websites. They get almost no
views and zero conversions.

The reason is search volume. Someone searching “roofing contact form” is much rarer than someone searching “Formspree alternatives.”
I stopped writing those and focused entirely on competitor alternative posts.

The Google Sheets Integration

One of the most searched keywords in my space is connecting forms to Google Sheets without Zapier. Formspree charges $90 per
month for this. Formgrid includes it on every plan.

Here is what the Google Sheets connection looks like once set up. Every submission appears as a new row automatically within
seconds:

Google Sheets showing form submissions as rows with automatic sync

Google Sheets showing form submissions as rows with automatic sync

The blog post I wrote about Formspree charging $90 for Google Sheets got 40 views on my blog and 50 readers on dev.to within
the first day of publishing. It contributed to my best signup day ever with 6 new users.

The Customer That Meant the Most

A developer from Brazil living in the UK replied to one of my survey emails. He said:

“I have also just realised you are a guy from Ghana who is challenging the big corps with this, so this also makes it very special to me.
Your family must be very proud of you. Now I want to help spread the word and help Formgrid towards greater success.”

I was not expecting that. Most days, building Formgrid is just me and the code and music in my ears. Hearing from someone on the other side of the world, those who found meaning in what I am building from Ghana made the whole journey feel worthwhile.

He is a member of the Free Software Foundation and deeply values open source software. Formgrid is fully open source under the
MIT license is not just a feature for me. It is the whole point. You own your data. You can read the code. You can run it yourself
if you want to. No black boxes.

The Technical Stack

For anyone curious about how Formgrid is built:
Frontend: React, TypeScript, Vite
Backend: Node.js, Express, TypeScript
Database: PostgreSQL with Prisma ORM
Payments: Paddle
Email: Resend
Deployment: Render with Docker

Everything is open source and self-hostable. You can run your own instance for free with Docker if you do not want to use the managed
version.

GitHub: github.com/allenarduino/formgrid

The Competitive Landscape

Formspree charges $15 per month for a basic form backend with no lead management. They charge $90 per month for Google Sheets.

Web3Forms charges $18 per month for their
Pro plan.

Jotform charges $34 per month.

The Pricing Decision

I recently raised the price of the Premium plan from $8 to $12 per month for new customers.

It was not an easy decision. At $8, the competitive comparison was already strong:
Formspree Basic: $15 per month
Web3Forms Pro: $18 per month
Basin: $15 per month
Formgrid Premium: $8 per month

But $8 felt too cheap for what the plan includes. File uploads up to 1GB, Google Sheets sync, auto-responder emails, up to
3 notification recipients, CSV export, and a full lead pipeline. That feature set at $8 was genuinely underpriced.

At $12, Formgrid Premium is still cheaper than every competitor while feeling like a real sustainable product price rather than something suspiciously cheap.

The 8 existing paying customers are permanently grandfathered at $8 per month. They trusted Formgrid early when it was
unproven. That trust deserves to be rewarded. Their price will never change.

New customers pay $12. Existing customers
keep $8. That felt like the right way to handle it.

Formgrid Premium is $12 per month and includes
1,000 submissions, file uploads up to 1GB,
Google Sheets sync, auto-responder emails, up to 3 notification recipients, and a full lead pipeline.

Formgrid Business is $29 per month and adds custom HTML email templates, unlimited Google Sheets sync, webhooks, and Zapier integration.

The lead pipeline is what makes Formgrid genuinely different from every competitor at this price point.

What I Am Working on Next

The focus for the next 6 months is simple.

More targeted blog posts. More competitor alternative pages. More platform-specific tutorials. Every post compounds on the ones before it.

The goal is $500 MRR by month 12. Based on my current publishing pace, the compounding effect of SEO is achievable.

What Building From Ghana Actually Means

I want to say something directly about this.

Building a SaaS product from Ghana that gets paying customers in San Diego, Europe, and North America is not easy. The payment
infrastructure is harder. The network is different. The timezone gaps are real.

But the internet does not care where you are building from. Annie does not know or care that the person who built her custom
email template is in Accra. She just knows her ride manager can finally read the registration emails clearly.

That is what building software is about. Solving real problems for real people. Geography is irrelevant to whether your solution works.

If you are building something from a place where people tell you it cannot be done, keep going. The customers will find you
through Google, the same way they find anyone else.

The Honest Summary

Seven months in. $86 MRR. 8 paying customers.
290+ signups.

It is not a rocketship. It is a real product that real people pay for, built by one person with no funding from a country, most people
do not associate with SaaS products.

The next 8 months will be faster than the first 8. The content library is growing. The domain authority is building. The product
is more complete. And I now know exactly what works.

If you are building something similar or have questions about Formgrid, I would love to hear from you. Reply in the comments or
email [email protected] directly.

And if Formgrid solves a problem you have,
try it free at formgrid.dev. No credit card required.

Allen Jones is the founder of Formgrid,
an open-source form backend and lead pipeline.
He builds and writes from Accra, Ghana.

Anthropic Picked Tulsa

Anthropic launched Claude for Small Business on May 13. Every read I’ve seen has focused on the product surface: 15 prebuilt agentic workflows, 7 named SaaS integrations, a trust posture built around in-the-loop approval and no-training-on-data defaults.

The product is fine. The strategic signal is somewhere else.

Read past the workflow list to the bottom of the announcement. Anthropic is taking Claude for Small Business on a 10-city physical workshop tour: Chicago, Tulsa, Dallas, Hamilton Township NJ, Baton Rouge, Birmingham, Salt Lake City, Baltimore, San Jose, Indianapolis. Free half-day live AI fluency training. 100 local small-business leaders per stop. Local partner organizations in each city. Plus credits to a Workday Foundation Solopreneurship Accelerator run with LISC, and Claude credits + technical support to three CDFIs — Accion Opportunity Fund, Community Reinvestment Fund USA, Pacific Community Ventures.

That is not a marketing budget. That is a ground game.

The Two Ways to Win SMB Distribution

There are two structural paths to small-business AI distribution at scale.

The first is bundling onto an existing install base. Microsoft has Office 365 in the hands of millions of small businesses. Microsoft 365 Copilot Business is $21/user/month, priced and packaged for SMB consumption, and shipped through the same Office channel partners that have been selling to small businesses for two decades. If you’re a 20-person business already paying for Microsoft 365 Business Premium, Copilot Business is a checkbox.

The second is building a ground game. Find the small businesses that aren’t on a single dominant productivity stack. Show up in the cities where the consulting class doesn’t fly. Partner with the organizations those businesses already trust — CDFIs that fund them, accelerators that mentor them, training nonprofits that work with them. Convert those relationships into installs.

Anthropic doesn’t have an installed base to bundle onto. They chose path two. The tour cities are the first visible artifact of that choice.

The Integration List Is a Leaderboard

Look at who’s named in the launch: QuickBooks, PayPal, HubSpot, Canva, Docusign, Google Workspace, Microsoft 365. Those are the revenue-touching tools — cash, sales, design, contracts, productivity. Each integration partner traded co-marketing for default position inside the Claude SMB workflow.

Now look at who’s not on the list. Shopify. Stripe. Square. Mailchimp. Slack. Notion. Salesforce is the most interesting absence — they have their own Einstein/Agentforce play, so this reads as competitive choice rather than oversight.

If you run an SMB-tier SaaS product and you weren’t asked to integrate, your category got assessed as either too small to matter, too replaceable to integrate, or close enough to a competitor’s space that you got passed over. The leaderboard is also a list of products that just learned their position is more fragile than they thought.

This is the Build Like the Capex Already Left thesis playing out at the SMB tier in real time. Workflow automation as a pure interface — bookkeeping point solutions, contract-review SaaS, marketing-automation tools, fractional-CFO platforms — is the category most at risk. Anthropic made a list of which interfaces survive as integrations and which get eaten as features.

Trust as the Scale-Down Moat

Anthropic’s own survey, cited in the launch: half of small-business owners name data security as their single biggest hesitation about AI. The Claude for Small Business response is structural: “every task is initiated by you,” “your existing permissions hold,” “we don’t train on your data by default.”

That posture is harder for larger competitors to make credibly. A small-business owner who has read about cloud-provider data settlements, who has seen platform vendors fold AI features into existing license agreements, who has watched training-data policies quietly evolve — that owner reads “we don’t train on your data by default” differently from how a Fortune 500 CIO reads it. The trust posture scales asymmetrically down-market.

Anthropic’s PBC structure and explicit Constitutional AI framing make this credible in the small-business segment in a way that’s hard for larger players to match. That’s not an accident.

The Tour Cities, Again

Tulsa is ranked second in Oklahoma for new business formation, with metro population over 1 million. Birmingham, Baton Rouge, Hamilton Township NJ, Indianapolis, Salt Lake City, Baltimore — mid-size metros with active SMB economies and minimal native AI marketing presence. The tour avoids the Bay Area and skips New York entirely.

The CDFI partnerships matter for the same reason. Accion Opportunity Fund, Community Reinvestment Fund USA, and Pacific Community Ventures lend to small-business owners that traditional banks underserve. Putting Claude credits and technical support inside those institutions reaches a population that Anthropic could not reach through coastal startup networks.

This is also where the PwC alliance expansion fits the same pattern at the enterprise tier. Anthropic doesn’t have native large-enterprise GTM, so they’re buying it via consulting alliance. The SMB tour is the bottom-up version of the same problem-solving: manufacture distribution.

The Diagnostic

For SMB operators considering Claude for Small Business: the question isn’t whether the workflows save time — they will. The question is which of your current vendors becomes redundant once Claude handles the cross-tool layer. The bookkeeper who only reconciles to QuickBooks. The fractional marketer who only schedules HubSpot campaigns. The contract reviewer who only flags Docusign sends. Those are the access-rents, and the rent just dropped to subscription pricing.

For SMB SaaS founders: if you’re not on the integration list, you have months to decide whether to compete with the integration layer or fold into it. The companies that picked the integration path bought time. The ones that bet on direct SMB acquisition without an installed base have to build distribution the way Anthropic is building it — geographically, partnership-by-partnership, in cities that don’t make it onto a coastal startup deck.

What Tulsa Means

The product launch is the surface. The tour is the strategy. Anthropic is testing whether a public-benefit corporation with strong technical product but limited native distribution can manufacture a GTM motion in the SMB segment through geographic, institutional, and demographic outreach that the existing distribution channels haven’t covered.

If it works, it becomes the playbook for any AI company without a consumer-brand head start or an installed software base to bundle onto. Pick the cities. Find the partners. Build the relationships. Ship the credits. Skip the conference circuit.

Anthropic picked Tulsa. The rest of the playbook follows.

How I Built an AI Hotel Review Intelligence Platform in a Weekend (Prompts Included)

Hotel Grande Bretagne in Athens has a 9.3/10 on Booking.com.

Here’s what that score hides:

  • Small rooms appear in 22% of reviews across all traveler types. Guests still give 10/10. The pattern is consistent: acknowledge the room, pivot immediately to the Acropolis view to justify the score.
  • The rooftop restaurant closed without warning for months in 2024. Zero impact on the overall rating.
  • Three specific staff members are named positively across reviews written in English, Turkish, and Polish. One department is carrying the entire experience.

Star ratings are broken. Not because they’re gamed (though they often are), but because averaging thousands of opinions into one number destroys the signal.

So I built WrongStay — an AI platform that extracts what’s actually in hotel reviews. Persona scores, buried complaints, staff patterns, temporal signals. Athens and Zurich live now, 39 hotels analyzed.

Here’s exactly how I built it.

The Stack

  • Replit — development and deployment (Reserved VM)
  • Express + TypeScript — backend API
  • React + Vite — frontend
  • PostgreSQL via Neon — database
  • Claude API (Sonnet 4) — AI synthesis
  • Outscraper — Booking.com review collection
  • Serper.dev — hotel cover photos
  • Chart.js + react-chartjs-2 — radar charts
  • Plausible — privacy-friendly analytics

Total infrastructure cost to run: under $50/month.

Getting the Data

The first problem: where do you get hotel reviews without building a scraper?

I chose Booking.com over TripAdvisor for one specific reason: verified guests only. You can’t review a hotel on Booking.com unless you actually booked and stayed there. Less noise.

Booking.com also pre-labels reviewer type which feeds directly into persona scoring without any NLP.

And also: they split pros and cons into separate fields. The review_disliked_text field alone is where most of the real signal lives.

For data collection I used the Outscraper API:

const response = await axios.get(
  'https://api.outscraper.cloud/booking-reviews',
  {
    params: {
      query: hotelUrls, // up to 1000 in one request
      limit: 200,
      sort: 'f_recent_desc',
      language: 'en',
      region: 'GR',
      async: true
    },
    paramsSerializer: params =>
      qs.stringify(params, { arrayFormat: 'repeat' }),
    headers: { 'X-API-KEY': process.env.OUTSCRAPER_API_KEY }
  }
);

Key insight: Outscraper supports batching up to 1000 queries in one request. I submitted all 40 hotel URLs simultaneously, got one job ID, and polled for completion. Total cost for 40 hotels × 200 reviews: $16.

The Database Schema

Five tables: hotels, reviews, synthesis, persona_scores, translations.

The reviews table captures everything from Outscraper:

CREATE TABLE reviews (
  id SERIAL PRIMARY KEY,
  hotel_id INTEGER REFERENCES hotels(id),
  review_liked_text TEXT,
  review_disliked_text TEXT,
  review_score NUMERIC,
  author_type VARCHAR(100),
  author_country VARCHAR(100),
  review_date DATE,
  review_id VARCHAR(255)
);

The Synthesis Prompt

This is the core of the product. The prompt took multiple iterations to get right. The key insight: don’t ask the AI to summarize. Ask it to find what standard review systems miss.

Here’s the actual prompt used in production:

You are a hotel intelligence analyst. You extract 
signals from guest reviews that standard review 
platforms miss. You always respond with valid JSON 
only. No preamble, no explanation, no markdown.

Analyze these hotel reviews and return ONLY a JSON 
object with this exact structure:

{
  "traveler_mismatch": "Which specific traveler type 
    consistently loves this hotel and which consistently 
    doesn't — and the precise reason why. Be specific, 
    not generic.",

  "buried_complaint": "The complaint that appears in 
    15-40% of disliked fields but that positive 
    reviewers always rationalize or excuse. Name the 
    exact pattern, not just the complaint.",

  "star_agreement": "One specific thing that both 
    low-scoring AND high-scoring reviewers mention, 
    despite disagreeing on everything else.",

  "temporal_signal": "Do reviews from the last 6 
    months differ meaningfully from older ones? What 
    specifically changed and approximately when? If 
    no meaningful change, say so.",

  "marketing_gap": "Something the hotel implies or 
    that positive reviewers praise, that negative 
    reviewers experienced very differently.",

  "staff_pattern": "Any specific staff role, 
    department, or named individual mentioned 
    repeatedly — positively or negatively.",

  "verdict_book_if": "Complete this: Book this hotel 
    if you are [specific traveler type and reason]. 
    Max 20 words.",

  "verdict_avoid_if": "Complete this: Avoid this 
    hotel if you are [specific traveler type and 
    reason]. Max 20 words.",

  "persona_scores": [
    {
      "persona": "Couples",
      "score": "A|B|C|D|F",
      "reasoning": "One specific sentence based on 
        actual review patterns.",
      "review_count": N
    }
    // Couples, Families, Solo Travelers, 
    // Business, Foodies, Active/Outdoors
  ]
}

If a persona has fewer than 5 reviews, set score 
to null and reasoning to 'Insufficient data'.

Reviews:
[INSERT_REVIEWS_JSON_HERE]

The instructions that made the biggest difference:

  1. “Not just the complaint — the exact pattern” forces specificity instead of generalities
  2. “15-40% of disliked fields” gives the AI a statistical frame rather than anecdotal
  3. “Positive reviewers always rationalize” is the mechanism that makes the buried complaint actually useful
  4. Letter grades (A/B/C/D/F) instead of numbers — they communicate judgment, not false precision

What the AI Actually Found

Here’s a real example from Athens Was Hotel (10/10 on Booking.com):

Buried complaint: “The split-mattress double bed complaint appears in roughly 20-25% of couple reviews with lower scores, where one mattress sits higher than the other making shared sleeping uncomfortable. Positive reviewers either don’t mention it or describe the bed as ‘very comfortable’ — suggesting room assignment variance. Negative reviewers name it explicitly as a physical discomfort issue, while positive reviewers who got proper beds praise comfort without knowing the problem exists for others.”

Staff pattern: “Anna (breakfast service) is the most frequently and specifically named individual, praised by name across multiple reviews in multiple languages (English, Turkish, Polish) for warmth, language skills, and making the à la carte breakfast easy to navigate. Themis (front desk) and Katerina (restaurant) are also named positively in multiple reviews.”

Neither of these appear in the star rating. Both are immediately useful to someone deciding whether to book.

Translation Pipeline

After synthesis I translate all 8 text fields into German, French, Spanish, and Italian — one Claude API call returning all four languages simultaneously:

const prompt = `
Translate all fields below into German (de), 
French (fr), Spanish (es), and Italian (it).

Preserve the specific, analytical tone. Do not 
soften or generalize. Keep named people and 
places in their original form.

Return ONLY this JSON structure, nothing else:
{
  "de": { "traveler_mismatch": "...", ... },
  "fr": { ... },
  "es": { ... },
  "it": { ... }
}

English source:
${JSON.stringify(englishFields)}
`;

Four languages in one API call. Stored in a translations table, fetched via ?lang=de param on the frontend.

pSEO Architecture

40 hotels generates a large URL surface:

/athens                               → city page
/athens/hotel-grande-bretagne         → hotel page
/athens/hotel-grande-bretagne/couples → persona page
/athens/best-hotels-for-couples       → aggregate page

The sitemap is fully DB-driven — new hotels appear automatically within 1 hour (cache TTL) of having synthesis run. No manual sitemap edits ever.

The critical SEO problem with React SPAs: every URL returns the same index.html to Googlebot, which means every hotel page has identical meta tags.

Fix: bot detection middleware that returns server-rendered HTML with correct meta tags for crawlers, while regular users still get the React SPA:

const BOT_AGENTS = [
  'googlebot', 'bingbot', 'twitterbot',
  'linkedinbot', 'facebookexternalhit'
];

function isBot(req) {
  const ua = (req.headers['user-agent'] || '')
    .toLowerCase();
  return BOT_AGENTS.some(bot => ua.includes(bot));
}

if (isBot(req)) {
  const hotel = await getHotelWithSynthesis(city, slug);
  return res.send(renderBotHTML(hotel));
}
res.sendFile(REACT_INDEX);

Each bot response includes correct title, meta description, Hotel schema, and FAQ schema as JSON-LD. Unknown slugs return HTTP 404 with noindex.

The Design

I wanted editorial authority, not another AI dashboard.

Key decisions:

  • Playfair Display serif for headings — signals trusted publication, not tech startup
  • Amber accent (#BA7517) — warmer than the typical blue/green SaaS palette
  • Two dark inverted sections: verdict cards and buried complaint spotlight — creates visual hierarchy and makes the intelligence feel premium
  • Radar chart for persona scores — the polygon shape communicates the hotel’s personality at a glance before you read anything
  • Bento grid for insights — varied card sizes encode importance without explicit ranking

The Admin Pipeline

A single admin page runs the full pipeline:

Import → Synthesize → Translate → Photo fetch

With the Outscraper API integration, the full pipeline for 40 hotels runs unattended. Server-Sent Events stream progress to the admin UI so I can watch it without the HTTP connection timing out. When done, cache is automatically invalidated.

Distribution Strategy

Building was the easy part. Distribution is where most projects die.

The approach that worked: lead with the insight, not the product.

The LinkedIn post that drove the first wave of traffic started with the buried complaint finding — not “I built a thing.” Nobody clicks “I built a thing.” People click specific, surprising data.

The long game is pSEO. “Is [Hotel Name] good for couples?” has real search volume and almost no competition for AI-synthesized answers. That’s 240 pages from 40 hotels, each targeting a specific high-intent query.

What I’d Do Differently

Start with the prompt. The synthesis prompt is the product. Everything else is infrastructure. Test the AI output quality on day one before building anything else.

Test the data source immediately. I built the full pipeline before verifying the API worked. Backwards. One test call on day one would have saved hours.

Build pSEO from the first commit. Adding the prerender middleware after launch is harder than including it from the start.

Live

wrongstay.com — 39 hotels, Athens and Zurich, free to use.

The full synthesis prompt is above — adapt it, use it, let me know what patterns you find in your own data.

What cities should I add next?

Why Your Computer Reads Numbers Backwards: Byte Order Explained

What is Byte Order?

Before understanding byte order, we need to understand one thing:

A byte = 8 bits

Many data types use multiple bytes.

For example:

Data Type   Size
char           1 byte
short          2 bytes
int            4 bytes
long long      8 bytes

When a number takes multiple bytes, the computer has to decide:

“In what order should I store these bytes in memory?”

That storage order is called:

Byte Order (Endianness)
1.little order endian
2.big order endian

Most people assume memory stores it like this:

12 34 56 78

But here comes the surprise…

On many computers, it is actually stored like this:

78 56 34 12

Wait… what?

Did the computer reverse the number?

No. Your computer is not confused — this behavior is called Byte Order, also known as Endianness.

In this article, we’ll understand byte order from scratch using diagrams, memory examples, and a practical C program.

*Understanding With an Example
*

Let’s take this hexadecimal number:

0x12345678

This number contains 4 bytes:

12 34 56 78

Now imagine memory locations like this:

Address → 1000 1001 1002 1003

The question is:

Which byte should be placed first?

This is where endianness comes in.

Type 1: Little Endian

In Little Endian, the smallest byte (Least Significant Byte) comes first.

Memory stores:


Address →   1000   1001   1002   1003
Data    →    78      56      34      12

Here:

78 is stored first
12 is stored last

This may look backward, but internally it helps processors perform arithmetic efficiently.

Why is it called “Little” Endian?

Because the little end (least significant byte) is stored first.

Type 2: Big Endian

In Big Endian, the largest byte (Most Significant Byte) comes first.

Memory stores:


Address →   1000   1001   1002   1003
Data    →    12      34      56      78

This looks more natural because humans usually read numbers from left to right.

Why is it called “Big” Endian?

Because the big end (most significant byte) comes first.

Visual Comparison
Number = 0x12345678


Little Endian
┌───────┬───────┬───────┬───────┐
│  78   │  56   │  34   │  12   │
└───────┴───────┴───────┴───────┘
 1000    1001    1002    1003


Big Endian
┌───────┬───────┬───────┬───────┐
│  12   │  34   │  56   │  78   │
└───────┴───────┴───────┴───────┘
 1000    1001    1002    1003

I built my own VS Code theme from scratch because nothing felt right at 2am

Aura Dark color palette showing purple #C792EA, blue #82AAFF, green #C3E88D, yellow #FFCB8B and dark background #1E1F29

It was 2am. I was deep in a coding session and my theme just looked… off.

I’d tried everything — One Dark Pro, Dracula, Tokyo Night, Catppuccin. All great themes. None of them felt mine.

So instead of sleeping like a normal person, I built my own. 😭

The Story Behind It 🌙

I remember the exact night I decided to build this. It was maybe 1am, I was working on a React project, and I kept getting distracted by how my code looked. One Dark Pro felt too flat. Dracula felt too harsh. Tokyo Night was close but the purple felt cold.

I started tweaking colors in a JSON file just to see what happened. One color led to another. Before I knew it, it was 4am and I had something that actually felt right.

That was the beginning of Aura Dark.

Meet Aura Dark 💜

A deep purple VS Code theme built specifically for long coding sessions. Warm background, rich colors, every token means something different. Not just “slap some purple on it” — every single language has dedicated rules written manually.

What Makes It Different 🎨

Most themes pick colors that look good in screenshots. I wanted colors that feel good after hour 3 of coding.

Every color has a specific job:

  • #C792EA Purple – keywords and decorators. Most important tokens get the most distinctive color
  • #82AAFF Blue — functions and methods. Your eye naturally follows blue
  • #C3E88D Green — strings. Calm and readable, never harsh
  • #FFCB8B Yellow/Orange — class names and components. Warm and inviting
  • #1E1F29 Background — warm dark, not cold black. Reduces eye strain significantly

Aura Dark color palette showing purple #C792EA, blue #82AAFF, green #C3E88D, yellow #FFCB8B and dark background #1E1F29

Features ✨

  • 35+ languages with dedicated rules — not just copy paste colors
  • Warm #1E1F29 background — easy on eyes at 2am
  • Every syntax element has its own distinct color
  • Works beautifully on CSS, JS, Python, Rust, PHP and more

Language Support 🌍

One thing I’m really proud of is the language coverage. Most themes handle JavaScript well and then just… guess for everything else. Aura Dark has dedicated token rules for every single one of these:

Frontend: TypeScript, JavaScript, React/JSX, HTML, CSS, SCSS, Vue, Svelte
Backend: Python, Java, Go, Rust, PHP, C#, Ruby, Swift, Kotlin, Dart
DevOps: Docker, Bash, YAML, JSON, Terraform, GitHub Actions
Other: SQL, Markdown, GraphQL, Regex, Git Diff and more
Every language was tested manually. Not just “it probably works.”

Recommended Setup ⚙️

To get the full Aura Dark experience:
Font: JetBrains Mono or Fira Code with ligatures enabled
Add this to your settings.json:

{
  "editor.fontFamily": "JetBrains Mono",
  "editor.fontSize": 14,
  "editor.lineHeight": 1.6,
  "editor.fontLigatures": true
}

What’s Next 🚀

Planning to add:

  • Aura Dark for JetBrains IDEs
  • Aura Dark for terminal (iTerm2, Windows Terminal)
  • Maybe a light variant someday (scary thought lol 😂)

Open to suggestions — drop them in the comments or open a GitHub issue!

Try It Yourself

🔗 VS Code Marketplace: https://marketplace.visualstudio.com/items?itemName=vinaycodes-io.aura-dark-theme
🔗 GitHub: https://github.com/vinaycodes-io/aura-dark-theme
🔗 Preview: https://vscodethemes.com/e/vinaycodes-io.aura-dark-theme/aura-dark

Would love honest brutal feedback — what looks off, what could be better, what language support is missing. Drop it in the comments! 😄

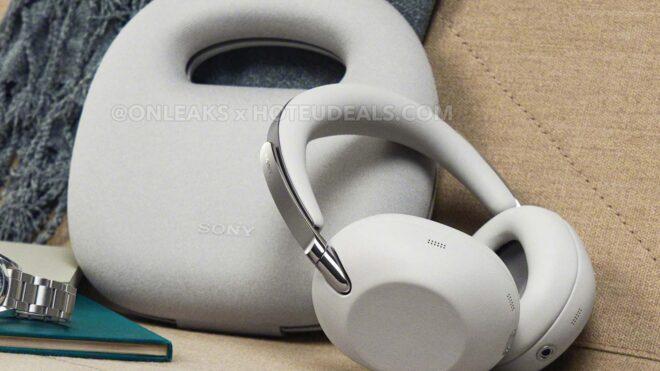
Sony 1000X The ColleXion için yeni fotoğraflar ve detaylar sızdırıldı

Sony 1000X The ColleXion için yeni fotoğraflar ve detaylar sızdırıldı

Sony 1000X The ColleXion için yeni fotoğraflar ve detaylar sızdırıldıBir süredir gündemde olan Sony 1000X The ColleXion kablosuz kulaklık modeli için yeni fotoğraflar ve detaylar sızdırıldı. Avrupa’da 629 euro fiyatla (kıyaslamak adına WH-1000XM6 modeli 429 euro) satılacağı aktarılan üst seviye model, son paylaşıma göre 19 Mayıs’ta karşımıza çıkarılacak ve pazara iki farklı renk seçeneğiyle çıkarılacak. Metal gövde parçalarının kullanıldığı ürün, Sony’nin QN3 ile V3 çiplerini taşıyacak, etkili ANC (Aktif Gürültü Engelleme) için 12 farklı mikrofonla donatılacak, 6 farklı mikrofon aracılığıyla yüksek kalitede telefon görüşmeleri getirecek ve ANC ile 24 saat, ANC olmadan 32 saatlik batarya ömrü sunacak. 5 dakikalık şarjla 1,5 saat müzik çalabilecek kulaklık, kayıpsız ses deneyimi için 1,5 metrelik kablo ve özel bir taşıma kılıfıyla geliyor. Battery Studios ve Sterling Sound & Coast Mastering desteğiyle ayarlanan sürücüler taşıdığı aktarılan “The ColleXion”, çıtayı her kalemde oldukça yukarıya taşıyacak gibi görünüyor. Sony’s most expensive wireless headphones ever – the 1000X “The ColleXion” have fully leaked! • Launching May 19, […]

Sony 1000X The ColleXion için yeni fotoğraflar ve detaylar sızdırıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

LLM Model Routing: How to Automatically Pick the Right AI Model for Each Task

Using one LLM for everything is like using a chainsaw to cut butter. It works, but you’re overpaying massively.

Model routing is the practice of automatically directing each AI request to the most cost-effective model that can handle it. Complex reasoning goes to Claude Opus. Simple edits go to DeepSeek. Structured extraction goes to GPT.

Here’s how to build it.

The Cost Problem

A typical AI coding pipeline without routing:

All requests → Claude Sonnet 4.6 → $3/$15 per 1M tokens
200 requests/day × 75K tokens/request = 15M tokens/day
Daily cost: ~$135
Monthly cost: ~$4,050

The same pipeline with routing:

Complex (20%) → Claude Opus: $5/$25 per 1M tokens
Standard (30%) → Claude Sonnet: $3/$15 per 1M tokens
Structured (15%) → GPT-5.5: $3/$12 per 1M tokens
Bulk (35%) → DeepSeek V3: $0.27/$1.10 per 1M tokens

Monthly cost: ~$1,200
Savings: 70%

Architecture

┌─────────────┐
│   Request    │
└─────┬───────┘
      │
┌─────▼───────┐
│  Classifier  │ ← Rule-based or ML
└─────┬───────┘
      │
  ┌───┼───┬───────┐
  │   │   │       │
  ▼   ▼   ▼       ▼
Opus Son. GPT   DeepSeek
  │   │   │       │
  └───┼───┴───────┘
      │
┌─────▼───────┐
│  Fallback    │ ← Retry on failure
└─────┬───────┘
      │
┌─────▼───────┐
│  Response    │
└─────────────┘

Implementation

The Router

from openai import OpenAI
from enum import Enum

class ModelTier(Enum):
    COMPLEX = "complex"
    STANDARD = "standard"
    STRUCTURED = "structured"
    BULK = "bulk"

MODEL_MAP = {
    ModelTier.COMPLEX: "claude-opus-4-7",
    ModelTier.STANDARD: "claude-sonnet-4-6",
    ModelTier.STRUCTURED: "gpt-5.5",
    ModelTier.BULK: "deepseek-chat",
}

FALLBACK_MAP = {
    "claude-opus-4-7": "claude-sonnet-4-6",
    "claude-sonnet-4-6": "gpt-5.5",
    "gpt-5.5": "claude-sonnet-4-6",
    "deepseek-chat": "gpt-5.5",
}

client = OpenAI(
    base_url="https://api.futurmix.ai/v1",
    api_key="your-key"
)

The Classifier

import re

def classify_request(prompt: str, metadata: dict = None) -> ModelTier:
    """Classify a request to determine the optimal model tier."""

    prompt_lower = prompt.lower()
    tokens = prompt.split()
    word_count = len(tokens)

    # Check metadata hints first
    if metadata:
        if metadata.get("tier"):
            return ModelTier(metadata["tier"])
        if metadata.get("json_output"):
            return ModelTier.STRUCTURED

    # Structured output detection
    structured_signals = [
        "json", "csv", "xml", "schema", "extract",
        "parse", "format as", "return as", "structured"
    ]
    if any(s in prompt_lower for s in structured_signals):
        return ModelTier.STRUCTURED

    # Complex task detection
    complex_signals = [
        "refactor", "architect", "design system", "debug",
        "race condition", "security audit", "performance optimize",
        "explain the trade-offs", "compare approaches",
        "root cause", "memory leak", "deadlock"
    ]
    if any(s in prompt_lower for s in complex_signals):
        return ModelTier.COMPLEX

    # Also complex: very long prompts with code context
    if word_count > 1000:
        return ModelTier.COMPLEX

    # Bulk task detection
    bulk_signals = [
        "generate tests", "add docstrings", "translate all",
        "add comments", "rename variable", "format code",
        "boilerplate", "template", "placeholder", "stub"
    ]
    if any(s in prompt_lower for s in bulk_signals):
        return ModelTier.BULK

    # Default: standard
    return ModelTier.STANDARD

The Execution Layer

def route_and_execute(
    prompt: str,
    system_prompt: str = None,
    metadata: dict = None,
    max_retries: int = 2
) -> dict:
    """Route request to optimal model and execute with fallback."""

    tier = classify_request(prompt, metadata)
    model = MODEL_MAP[tier]

    messages = []
    if system_prompt:
        messages.append({"role": "system", "content": system_prompt})
    messages.append({"role": "user", "content": prompt})

    current_model = model
    for attempt in range(max_retries + 1):
        try:
            response = client.chat.completions.create(
                model=current_model,
                messages=messages,
                max_tokens=4096
            )
            return {
                "content": response.choices[0].message.content,
                "model_used": current_model,
                "tier": tier.value,
                "attempt": attempt + 1,
                "usage": {
                    "input": response.usage.prompt_tokens,
                    "output": response.usage.completion_tokens
                }
            }
        except Exception as e:
            fallback = FALLBACK_MAP.get(current_model)
            if fallback and attempt < max_retries:
                current_model = fallback
                continue
            raise

Usage

# Automatically routed to Claude Opus (complex)
result = route_and_execute(
    "Design a distributed caching system that handles partition tolerance "
    "and maintains consistency across 3 regions. Consider the CAP trade-offs."
)
print(f"Tier: {result['tier']}, Model: {result['model_used']}")
# → Tier: complex, Model: claude-opus-4-7

# Automatically routed to GPT (structured output)
result = route_and_execute(
    "Extract all API endpoints from this codebase and return as JSON with "
    "method, path, description, and parameters for each.",
    metadata={"json_output": True}
)
# → Tier: structured, Model: gpt-5.5

# Automatically routed to DeepSeek (bulk)
result = route_and_execute(
    "Generate unit tests for all 15 functions in this utils module."
)
# → Tier: bulk, Model: deepseek-chat

Advanced: Quality Verification

For critical tasks, add a verification step — route to a cheap model first, then verify quality with a better one:

def verified_execution(prompt: str, quality_threshold: float = 0.8):
    """Execute with cheap model, verify with expensive model if needed."""

    # First pass: cheap model
    result = route_and_execute(prompt)

    # If already using complex tier, no verification needed
    if result["tier"] == "complex":
        return result

    # Quick quality check with a more capable model
    verification = route_and_execute(
        f"Rate the quality of this response on a scale of 0-1. "
        f"Just return the number.nnOriginal prompt: {prompt}nn"
        f"Response: {result['content']}",
        metadata={"tier": "standard"}
    )

    try:
        score = float(verification["content"].strip())
        if score < quality_threshold:
            # Re-execute with higher tier
            return route_and_execute(prompt, metadata={"tier": "complex"})
    except ValueError:
        pass

    return result

Advanced: Request Batching

When processing many similar items, batch them for the cheap model:

async def batch_route(items: list, prompt_template: str):
    """Process items in parallel using the cheapest suitable model."""
    import asyncio

    async def process_one(item):
        prompt = prompt_template.format(item=item)
        return route_and_execute(prompt)

    tasks = [process_one(item) for item in items]
    return await asyncio.gather(*tasks)

Monitoring Dashboard

Track routing decisions and costs:

class RoutingMetrics:
    def __init__(self):
        self.decisions = []

    def record(self, result):
        self.decisions.append({
            "tier": result["tier"],
            "model": result["model_used"],
            "tokens": result["usage"],
            "fallback": result["attempt"] > 1
        })

    def summary(self):
        total = len(self.decisions)
        by_tier = {}
        for d in self.decisions:
            tier = d["tier"]
            by_tier.setdefault(tier, 0)
            by_tier[tier] += 1

        fallback_rate = sum(1 for d in self.decisions if d["fallback"]) / total

        return {
            "total_requests": total,
            "tier_distribution": {k: v/total for k, v in by_tier.items()},
            "fallback_rate": fallback_rate
        }

Key Takeaways

  1. Classification doesn’t need to be perfect — even a simple keyword-based classifier saves 50%+ over using one model
  2. Fallback chains are essential — providers have downtime, your pipeline shouldn’t
  3. Monitor and tune — track which tier each request hits and adjust thresholds
  4. Use a gateway — one endpoint that supports all models makes routing trivial

Get Started

FuturMix provides all 22+ models through one OpenAI-compatible API at 10-30% off. Perfect for building routing pipelines.

client = OpenAI(
    base_url="https://api.futurmix.ai/v1",
    api_key="your-key"
)

Start with the simple keyword classifier, monitor for a week, then optimize.

How do you handle model routing in your AI pipelines? Share your approach in the comments.

MCP Security is Broken — So I Built a Scanner

MCP (Model Context Protocol) is the new standard for connecting AI agents to tools. The security is a disaster right now.

BlueRock Security scanned 7,000+ live MCP servers 36.7% were vulnerable to SSRF. Hundreds had zero authentication or encryption.

So I built AgentWarden — a CLI tool that scans MCP servers for real vulnerabilities:

  • Unauthenticated endpoints
  • SSRF via tool parameters
  • Prompt injection in tool descriptions (tool poisoning)
  • Path traversal in file tools
  • Tool shadowing and typosquatting
  • Missing rate limiting
  • TLS misconfigurations
  • Sensitive data exposure

Usage:
agentwarden scan https://your-mcp-server.com -v
agentwarden scan https://your-mcp-server.com -o report.html

GitHub: https://github.com/Agent-Warden/Agent-Warden

Scanned several live MCP servers already. Would love feedback/contribution from anyone in the security space building on MCP.

What Is an OpenAI-Compatible API? How It Works and Why Every AI Tool Supports It

If you’ve used any AI coding tool in the past year, you’ve used an OpenAI-compatible API — whether you knew it or not.

Claude Code, Cursor, Aider, Continue, Cline, LangChain, LlamaIndex — they all speak the same protocol. Here’s what that means and why it matters for your stack.

The Standard

An “OpenAI-compatible API” is any HTTP endpoint that accepts the same request format as OpenAI’s Chat Completions API:

curl https://any-provider.com/v1/chat/completions 
  -H "Authorization: Bearer $API_KEY" 
  -H "Content-Type: application/json" 
  -d '{
    "model": "any-model-name",
    "messages": [{"role": "user", "content": "Hello"}],
    "max_tokens": 1024
  }'

The response follows the same schema:

{
  "id": "chatcmpl-abc123",
  "object": "chat.completion",
  "model": "any-model-name",
  "choices": [{
    "index": 0,
    "message": {"role": "assistant", "content": "Hi there!"},
    "finish_reason": "stop"
  }],
  "usage": {"prompt_tokens": 10, "completion_tokens": 5, "total_tokens": 15}
}

That’s it. Any server that accepts this request format and returns this response format is “OpenAI-compatible.”

Why It Matters

The OpenAI wire protocol has become the HTTP of AI. Just like every web browser speaks HTTP regardless of the server behind it, every AI tool speaks the OpenAI protocol regardless of which model you’re actually using.

This means:

  1. Model portability — Switch from GPT to Claude to DeepSeek without changing your code
  2. Tool interoperability — Any tool that works with OpenAI works with any compatible provider
  3. No vendor lock-in — Your integration code doesn’t depend on any single provider
  4. Gateway compatibility — Route through proxies, load balancers, and gateways transparently

Who Supports It

Model providers with native OpenAI-compatible endpoints:

Provider Endpoint Models
OpenAI api.openai.com/v1 GPT-5.5, GPT-5 Mini, o3, etc.
DeepSeek api.deepseek.com/v1 DeepSeek V3, R1
Mistral api.mistral.ai/v1 Mistral Large, Codestral
Groq api.groq.com/v1 Llama 3, Mixtral (fast inference)
Together AI api.together.xyz/v1 100+ open source models
Fireworks AI api.fireworks.ai/v1 Llama 3, Mixtral, custom models

Providers accessible through OpenAI-compatible gateways:

Provider Native API Via Gateway
Anthropic (Claude) Messages API (different format) OpenAI-compatible via gateway
Google (Gemini) Vertex AI / Gemini API OpenAI-compatible via gateway

Tools that consume OpenAI-compatible APIs:

Tool How to Configure
Claude Code ANTHROPIC_BASE_URL env var
Cursor Settings → Models → Custom API Base
Aider --openai-api-base or .aider.conf.yml
Continue config.json → provider apiBase
Cline Settings → API Provider
Roo Code Settings → API Configuration
OpenAI Codex CLI OPENAI_BASE_URL env var or config.toml
LangChain ChatOpenAI(base_url=...)
LlamaIndex OpenAI(api_base=...)
AutoGen config_list with base_url

How to Use It: Practical Examples

Python (openai SDK)

from openai import OpenAI

# Point to any OpenAI-compatible endpoint
client = OpenAI(
    base_url="https://api.futurmix.ai/v1",
    api_key="your-key"
)

# Works with any model the endpoint supports
response = client.chat.completions.create(
    model="claude-sonnet-4-6",  # or "deepseek-chat", "gpt-5.5", etc.
    messages=[{"role": "user", "content": "Explain async/await in Python"}],
    max_tokens=1024
)
print(response.choices[0].message.content)

Node.js

import OpenAI from 'openai';

const client = new OpenAI({
  baseURL: 'https://api.futurmix.ai/v1',
  apiKey: 'your-key'
});

const response = await client.chat.completions.create({
  model: 'claude-sonnet-4-6',
  messages: [{ role: 'user', content: 'Write a React hook for debouncing' }]
});

cURL

curl https://api.futurmix.ai/v1/chat/completions 
  -H "Authorization: Bearer your-key" 
  -H "Content-Type: application/json" 
  -d '{"model":"claude-sonnet-4-6","messages":[{"role":"user","content":"Hello"}]}'

Streaming

stream = client.chat.completions.create(
    model="claude-sonnet-4-6",
    messages=[{"role": "user", "content": "Write a sorting algorithm"}],
    stream=True
)

for chunk in stream:
    if chunk.choices[0].delta.content:
        print(chunk.choices[0].delta.content, end="")

The Gateway Pattern

The most powerful use of OpenAI-compatible APIs is the gateway pattern: one endpoint that routes to multiple providers.

Your Code (OpenAI SDK)
    │
    ▼
┌──────────────────┐
│  API Gateway      │ ← One endpoint, one key
│  (OpenAI-compat)  │
└──────────────────┘
    │
    ├── model="claude-sonnet-4-6"  → Anthropic
    ├── model="gpt-5.5"           → OpenAI
    ├── model="deepseek-chat"     → DeepSeek
    └── model="gemini-2.5-pro"    → Google

Benefits:

  • One API key for all models
  • Automatic failover — if one provider is down, route to another
  • Cost optimization — gateways negotiate volume discounts (10-30% off)
  • Usage dashboard — see all model usage in one place

Common Pitfalls

1. Not all endpoints support all features

The core chat/completions endpoint is universal, but advanced features vary:

Feature OpenAI Claude (via gateway) DeepSeek
Chat completions ✅ ✅ ✅
Streaming ✅ ✅ ✅
Function calling ✅ ✅ ✅
JSON mode ✅ ✅ ✅
Vision (images) ✅ ✅ ❌
Responses API ✅ Varies ❌

2. Model names differ between providers

Always check the provider’s model list. Common mistakes:

  • claude-3.5-sonnet vs claude-sonnet-4-6 (naming conventions changed)
  • gpt-4o vs gpt-5.5 (model generations)
  • deepseek-chat vs deepseek-v3 (aliases)

3. Rate limits are provider-specific

Even through a gateway, each upstream provider has its own rate limits. The gateway may return 429s from the underlying provider.

Building Your Own OpenAI-Compatible Server

If you’re serving a local model, here’s the minimum viable implementation:

from fastapi import FastAPI
from pydantic import BaseModel
import time, uuid

app = FastAPI()

class Message(BaseModel):
    role: str
    content: str

class ChatRequest(BaseModel):
    model: str
    messages: list[Message]
    max_tokens: int = 1024
    temperature: float = 0.7

@app.post("/v1/chat/completions")
async def chat(request: ChatRequest):
    # Your model inference here
    response_text = your_model.generate(
        request.messages[-1].content,
        max_tokens=request.max_tokens
    )

    return {
        "id": f"chatcmpl-{uuid.uuid4().hex[:8]}",
        "object": "chat.completion",
        "created": int(time.time()),
        "model": request.model,
        "choices": [{
            "index": 0,
            "message": {"role": "assistant", "content": response_text},
            "finish_reason": "stop"
        }],
        "usage": {
            "prompt_tokens": sum(len(m.content.split()) for m in request.messages),
            "completion_tokens": len(response_text.split()),
            "total_tokens": 0  # calculated
        }
    }

Now any OpenAI-compatible client can talk to your local model.

Get Started

FuturMix provides an OpenAI-compatible API with 22+ models. One endpoint, one key, 10-30% off official pricing.

from openai import OpenAI
client = OpenAI(base_url="https://api.futurmix.ai/v1", api_key="your-key")

Works with every tool listed in this article — Claude Code, Cursor, Aider, LangChain, and more.

Are you using OpenAI-compatible APIs in production? What patterns have worked best for you?

I built an LLM-powered compliance scanner that points at the actual line of code

A few weeks ago I went down a rabbit hole. I’d been reading about how every SaaS company eventually has to deal with GDPR / SOC 2 / HIPAA, and how the existing tooling space basically goes like this:

“Do you have a password policy document?”
“Yes.”
“Great, you’re compliant.”

That checks the policy. It doesn’t check whether your login route actually stores passwords with MD5. Which felt like… kind of the wrong layer to look at?

So I built Themida — an open-source compliance scanner that reads the actual code.

What it does

Point it at a GitHub repo (or a local directory). It returns findings like this:

src/auth/login.ts:41
CRITICAL  GDPR Art. 5(1)(f), 32(1)(a)
Password hashed with broken MD5
Maximum fine: €20M or 4% of revenue
Fix → bcrypt at cost 12+, or Argon2id

Every finding has:

  • The exact file and line number
  • The legal article that the code violates
  • The maximum fine for context
  • A code fix you can paste straight into a PR
  • A severity rating (CRITICAL / HIGH / MEDIUM / LOW)

You can export the whole report as a PDF if you need to share it with someone non-technical.

Why an LLM and not regex?

Honest answer: I tried regex first. It was awful.

Pattern-matching catches the easy cases (crypto.createHash('md5')) but produces a tidal wave of false positives on real codebases. MD5 used to hash a password is a crime. MD5 used as a cache key is fine. A regex can’t tell the difference. An LLM can! If you give it enough context and the right prompt.

The scanner runs three passes:

  1. Recon : small/cheap LLM scans the file tree and picks ~15 suspect paths
  2. Deep scan : bigger LLM reads those files line by line and produces findings
  3. Verify : a final pass that drops hallucinated paths and findings already mitigated nearby

Splitting it this way keeps the cost under control. A scan of a medium-sized repo costs around 5–20 cents depending on which models you pick.

Provider-agnostic

You bring your own LLM key. The scanner ships adapters for:

  • Anthropic (Claude)
  • OpenAI
  • Anything that speaks OpenAI’s Chat Completions API, OpenRouter, Groq, Together, vLLM, llama.cpp server, Ollama, LiteLLM

Pick one with one env var:

LLM_PROVIDER=openai
OPENAI_API_KEY=sk-...
OPENAI_BASE_URL=https://openrouter.ai/api/v1  # optional, defaults to OpenAI

Self-hosters running a local model are first-class citizens, the cost tracker just records 0 cents and moves on.

What’s done, what’s not

Done: GDPR (5 rules), EU AI Act (5 rules), full scan pipeline, dashboard, real-time progress, PDF export, GitHub App integration, local CLI path (pnpm dev:scan).

Open issues, PRs welcome: HIPAA, SOC 2, ISO 27001, OWASP Top 10, PCI DSS. Each rule pack is a single TypeScript file with a fairly readable schema, adding rules is the easiest way to contribute.

On the roadmap: Better local-LLM ergonomics, VS Code extension, eval suite for measuring rule accuracy as packs grow.

Try it

git clone https://github.com/Nikolaospet/themida
cd themida
pnpm install
cp .env.example .env.local
# edit .env.local — pick a provider
pnpm dev:scan

There’s also a sample report on OWASP NodeGoat you can poke around without setting anything up.

This is a personal project

I want to be upfront about this: Themida isn’t a company, it doesn’t have funding, there’s no “managed version” hiding behind the OSS face. It’s a side project I’m building in the open because I find the problem interesting and I think devs are tired of compliance tools that don’t read code.

It’s released under AGPL-3.0 , use it, modify it, run it for your team, fork it. The license just stops someone wrapping it in a SaaS and closing it back up.

If you try it and something breaks, open an issue. If you want to add a rule pack, an LLM adapter, or improve the eval suite, PRs are warmly welcomed, there’s a CONTRIBUTING.md and a PR template ready to go.

The repo is here: github.com/Nikolaospet/themida

If you build software in regulated industries, fintech, health, EU-anything, anywhere with AI Act exposure, I’d love to hear which rule packs would be most useful to ship next. Drop a comment.

Thanks for reading 🙏