Mert
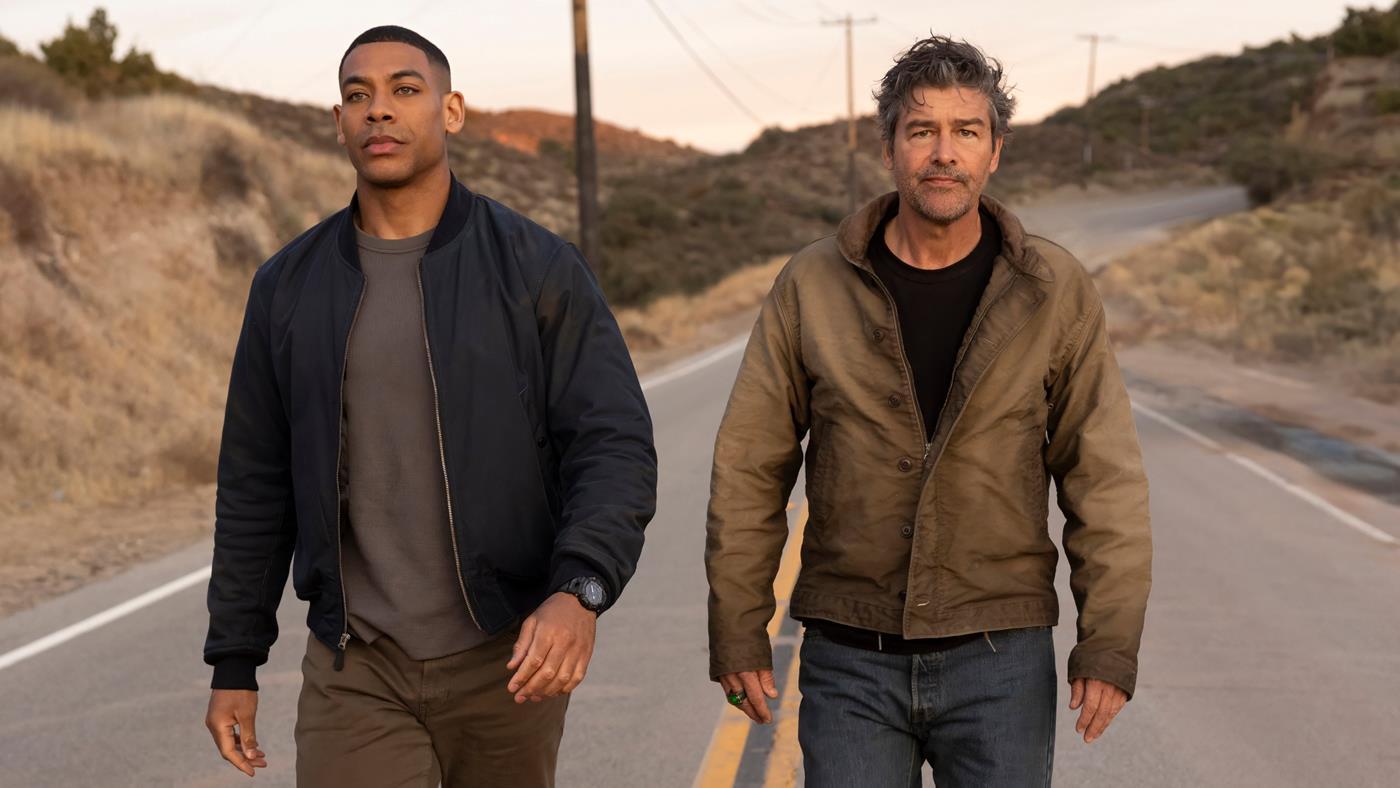
HBO’dan süper kahraman dizisi: DC yapımı Lanterns’in yeni fragmanı yayınlandı
DC’nin Green Lantern karakterine alışık olduğumuzdan daha karanlık, daha ayakları yere basan bir yorum getiren Lanterns dizisinden yeni fragman yayınlandı. Bu yaz HBO’da izleyici ile buluşacak.Bilim insanları, beyindeki hasarlı bağlantılar yerine yeni yollar oluşturmayı başardı
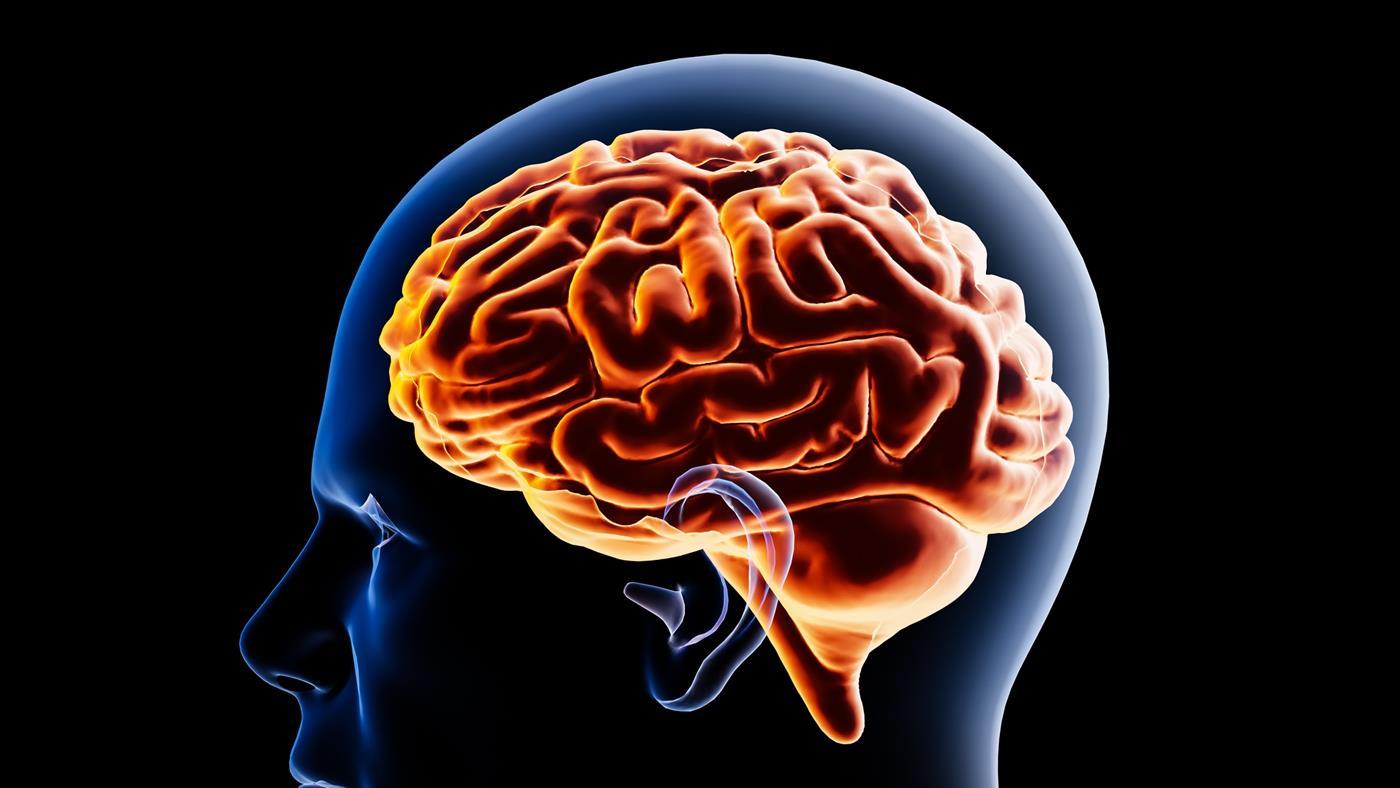
Araştırmacılar, beyindeki hasarlı sinir devrelerinin etrafından yeni bağlantılar kurabilen bir teknoloji geliştirdi. Sistem, nörolojik hastalıkların tedavisinde yeni bir dönemin kapısını aralayabilir.My Watchlist: From 70s Basements to Victorian Crime Scenes
Originally published at harshit.cloud on 2025-01-12.
When I’m not wrestling with Kubernetes clusters or debugging infrastructure at 2 AM, you’ll find me binging shows that either make me laugh or make me think. Here’s my watchlist confession.
The Sitcom Holy Trinity
That 70’s Show
There’s something timeless about a bunch of teenagers sitting in a basement, roasting each other. The circle scenes, Red’s threats about putting his foot somewhere uncomfortable, and Kelso’s stupidity that somehow loops back to genius. It’s comfort TV at its finest.
Arrested Development
“I’ve made a huge mistake.” Haven’t we all? This show rewards rewatching like no other. The layered jokes, the callbacks, the narrator’s deadpan delivery – it’s a masterclass in comedy writing. The Bluth family dysfunction hits different when you’ve seen enough corporate chaos yourself.
How I Met Your Mother (HIMYM)
Yes, I have opinions about the finale. But everything before that? Legendary. Barney’s suits, Marshall and Lily’s relationship goals, and Ted’s endless romantic optimism somehow never got old. The slap bet alone deserves its own appreciation post.
The Detective Obsession
I’m an avid detective movie and show enthusiast. Something about watching brilliant minds piece together impossible puzzles scratches an itch that debugging production issues just can’t reach.
Sherlock
Benedict Cumberbatch’s Sherlock is peak detective content. The mind palace sequences, the rapid-fire deductions, the chemistry with Watson – it redefined what a detective adaptation could be. “The game is on” still gives me chills.
Detective Conan
Shinichi Kudo trapped in a kid’s body, solving murders that somehow happen everywhere he goes. The Japanese detective anime that’s been running since 1996 and I’m still invested. The Black Organization arc is chef’s kiss.
High Potential
This one’s newer, but it has a lot of potential (pun intended). The premise of a high-IQ cleaning lady solving crimes that stump detectives? Count me in. It’s fresh, it’s fun, and it’s finding its groove.
The Common Thread
Whether it’s a sitcom or a detective thriller, I gravitate toward smart writing. Shows that respect their audience, plant seeds that pay off later, and create characters you’d want to grab a beer with (or solve crimes with).
What’s on your watchlist? Always looking for recommendations – especially if it involves either a laugh track or a magnifying glass.
GitHub Actions vs GitLab CI: a practical comparison
Originally published at harshit.cloud on 2024-12-20.
GitHub Actions vs GitLab CI: a practical comparison
Two years, 50 microservices, two CI platforms running side by side. Some repos on GitHub, some on GitLab, same team writing the YAML for both. Here is what stuck after the marketing slides wore off.
syntax and configuration
GitHub Actions
name: CI Pipeline
on:
push:
branches: [main]
pull_request:
jobs:
test:
runs-on: ubuntu-latest
steps:
- uses: actions/checkout@v4
- uses: actions/setup-node@v4
with:
node-version: '20'
- run: npm ci
- run: npm test
The YAML is readable, the marketplace has an action for almost everything, and matrix builds are a single block. The nesting gets verbose once you have reusable workflows, and environment variable precedence is its own small religion.
GitLab CI
stages:
- test
- build
test:
stage: test
image: node:20
script:
- npm ci
- npm test
only:
- main
- merge_requests
Flatter than GitHub’s nesting, Docker is a first-class citizen, and the stages concept maps cleanly to how you think about a pipeline. There is no marketplace, so reusable components come from include: files and Docker images you assemble yourself.
performance and speed
build times
A typical Node.js app on our setup builds in 3 to 5 minutes on GitHub Actions and 4 to 6 minutes on GitLab CI. Close enough that I never picked a platform on speed alone.
parallelization
Both handle parallel jobs well. GitHub Actions has cleaner syntax for matrix builds:
strategy:
matrix:
node-version: [18, 20, 22]
os: [ubuntu-latest, windows-latest]
GitLab requires more manual setup for the same result.
ecosystem and marketplace
GitHub Actions marketplace
Over 20,000 actions, and the caching one is the example I keep coming back to:
- uses: actions/cache@v4
with:
path: ~/.npm
key: ${{ runner.os }}-node-${{ hashFiles('**/package-lock.json') }}
One block, content-addressed cache keyed off the lockfile. The first time you delete the manual cache logic you wrote for GitLab and replace it with this, you feel it.
GitLab’s approach
GitLab does not have a marketplace. You write scripts or use Docker images:
test:
image: node:20
cache:
key: ${CI_COMMIT_REF_SLUG}
paths:
- node_modules/
script:
- npm ci
- npm test
More control, but more work.
docker integration
GitLab CI wins here
GitLab CI was built with Docker in mind:
build:
image: docker:latest
services:
- docker:dind
script:
- docker build -t myapp .
- docker push myapp
It just works. No weird permissions issues.
GitHub Actions
Needs more setup for Docker.
- name: Set up Docker Buildx
uses: docker/setup-buildx-action@v3
- name: Build and push
uses: docker/build-push-action@v5
with:
context: .
push: true
tags: myapp:latest
Works fine, but requires more marketplace actions.
secrets management
GitHub
env:
API_KEY: ${{ secrets.API_KEY }}
Simple. Secrets are org/repo scoped. Works well.
GitLab
variables:
API_KEY: $CI_DEPLOY_TOKEN
More flexible with group-level variables and environments. Better for complex setups.
cost
GitHub Actions gives private repos 2,000 minutes/month on the free tier, public repos are unlimited, and overage is $0.008/minute. GitLab SaaS gives 400 minutes/month free and charges $10 per 1,000 additional minutes, but self-hosted runners are unlimited. If you can run your own runners, GitLab gets cheaper fast at scale. If you can’t, GitHub’s free tier outlasts it.
self-hosted runners
GitHub
./config.sh --url https://github.com/org/repo --token TOKEN
./run.sh
Setup is straightforward. Runners are repo or org-scoped.
GitLab
gitlab-runner register
gitlab-runner run
More flexible. Can be project, group, or instance-wide. Better for large organizations.
debugging experience
GitHub Actions has clear, searchable logs, lets you re-run individual jobs, and exposes a debug mode behind two secrets. You can SSH into a runner via a third-party action, but it is not a native feature.
GitLab is the one I reach for when a pipeline is genuinely stuck. The log viewer is good, individual job retries are good, but the real difference is interactive debugging. SSH into the runner mid-job, or open a web terminal from the failed job in your browser, and poke at the filesystem while the build is still alive. The first time you do this on a Docker-in-Docker failure that only repros on CI, you stop missing it everywhere else.
when to pick which
GitHub Actions wins when you are already on GitHub, want the marketplace, and your pipelines are small to medium. GitLab CI wins when your Docker workflows are non-trivial, your runner fleet is large, your deployment strategies are gnarly, or you need to debug pipelines without a redeploy loop.
my setup
I use both. GitHub Actions for open-source and frontend, GitLab CI for infrastructure code and the deployments that involve five stages and a manual approval.
common pitfalls
GitHub Actions has a 6-hour hosted-runner job timeout, a 90-day artifact retention default (configurable up to 400 days for public repos, 90 for private), and tight concurrent-job limits on the free tier. Plan around them or pay.
GitLab’s shared runners get sluggish at peak, Docker builds need docker:dind as a service container, and CI/CD variable precedence has at least six rules you will need to read twice. The one that bites me most: project-level variables silently override group-level ones with the same name.
migration tips
GitHub to GitLab
# GitHub
- uses: actions/checkout@v4
# GitLab equivalent
git clone $CI_REPOSITORY_URL
cd $CI_PROJECT_NAME
GitLab to GitHub
Most scripts translate directly. The win is collapsing a few of them into marketplace actions you no longer have to maintain.
Starting fresh, pick whichever platform already hosts your code. The integration tax of running CI on the other vendor outweighs every syntax preference in this post. Whichever one you pick, the only investment that pays back is making the pipeline fast. A slow CI is worse than no CI; it just costs more to ignore.

Git Interactive Rebase: Clean Up Your Commit History
Originally published at harshit.cloud on 2024-12-19.
TIL: Git Interactive Rebase: Clean Up Your Commit History
Discovered git rebase -i today. Turns five “fix typo” commits into one clean commit before the PR review notices.
the problem
My commit history looked like this:
fix typo
WIP
fix typo again
actually fixed it
remove console.log
Not exactly professional for a PR review.
the solution
Interactive rebase lets you edit, squash, and reorder commits:
# Rebase last 5 commits
git rebase -i HEAD~5
# Or rebase everything since branching from main
git rebase -i main
This opens your editor with:
pick 1a2b3c4 fix typo
pick 5d6e7f8 WIP
pick 9g0h1i2 fix typo again
pick 3j4k5l6 actually fixed it
pick 7m8n9o0 remove console.log
# Commands:
# p, pick = use commit
# r, reword = use commit, but edit message
# e, edit = use commit, but stop for amending
# s, squash = meld into previous commit
# f, fixup = like squash, but discard commit message
# d, drop = remove commit
my workflow
Change it to:
pick 1a2b3c4 fix typo
fixup 5d6e7f8 WIP
fixup 9g0h1i2 fix typo again
fixup 3j4k5l6 actually fixed it
fixup 7m8n9o0 remove console.log
Result: one clean commit.
pro tips
Reword commit messages:
pick 1a2b3c4 fix typo
reword 5d6e7f8 add user authentication
Reorder commits:
pick 3j4k5l6 add tests
pick 1a2b3c4 add feature
Split a commit:
edit 1a2b3c4 huge commit with multiple changes
Then:
git reset HEAD^
git add file1.js
git commit -m "feat: add feature A"
git add file2.js
git commit -m "feat: add feature B"
git rebase --continue
warning
Never rebase commits that have been pushed to a shared branch! You’ll rewrite history and cause conflicts for your team.
Safe:
# Your feature branch, not pushed yet
git rebase -i main
Dangerous:
# Main branch that others use
git checkout main
git rebase -i HEAD~5 # DON'T DO THIS!
useful aliases
Add to your ~/.gitconfig:
[alias]
# Interactive rebase with the given number of latest commits
rb = "!f() { git rebase -i HEAD~$1; }; f"
# Rebase on main
rbm = "!git fetch origin main && git rebase -i origin/main"
Now you can do:
git rb 5 # Rebase last 5 commits
git rbm # Rebase on main
This has saved me so much embarrassment in code reviews.
Prometheus and Grafana: from zero to production monitoring
Originally published at harshit.cloud on 2024-12-18.
Prometheus and Grafana: from zero to production monitoring
We started shipping monitoring after a string of outages where customers paged us before our own dashboards did. This is the stack we landed on, written like you’re standing it up tomorrow.
why Prometheus and Grafana
After trying CloudWatch, Datadog, and New Relic, we landed on Prometheus and Grafana for the same reason most teams do. Prometheus is open source, pull-based, and fits Kubernetes without protest. Grafana puts the dashboards on top, talks to almost anything, and costs nothing. Self-hosted, the bill is server time. The commercial options were running us $500 a month and climbing.
setup with Docker Compose
For development or small deployments, Docker Compose is perfect:
services:
prometheus:
image: prom/prometheus:latest
container_name: prometheus
volumes:
- ./prometheus.yml:/etc/prometheus/prometheus.yml
- prometheus_data:/prometheus
command:
- '--config.file=/etc/prometheus/prometheus.yml'
- '--storage.tsdb.path=/prometheus'
- '--storage.tsdb.retention.time=30d'
ports:
- "9090:9090"
restart: unless-stopped
grafana:
image: grafana/grafana:latest
container_name: grafana
volumes:
- grafana_data:/var/lib/grafana
- ./grafana/provisioning:/etc/grafana/provisioning
environment:
- GF_SECURITY_ADMIN_PASSWORD=changeme
- GF_USERS_ALLOW_SIGN_UP=false
ports:
- "3000:3000"
restart: unless-stopped
depends_on:
- prometheus
node_exporter:
image: prom/node-exporter:latest
container_name: node_exporter
command:
- '--path.procfs=/host/proc'
- '--path.sysfs=/host/sys'
- '--collector.filesystem.mount-points-exclude=^/(sys|proc|dev|host|etc)($$|/)'
volumes:
- /proc:/host/proc:ro
- /sys:/host/sys:ro
- /:/rootfs:ro
ports:
- "9100:9100"
restart: unless-stopped
volumes:
prometheus_data:
grafana_data:
Run it:
docker-compose up -d
Done. Prometheus is on :9090, Grafana on :3000.
prometheus configuration
Create prometheus.yml:
global:
scrape_interval: 15s
evaluation_interval: 15s
external_labels:
cluster: 'production'
region: 'us-east-1'
# Alertmanager configuration (we'll get to this)
alerting:
alertmanagers:
- static_configs:
- targets: ['alertmanager:9093']
# Load rules
rule_files:
- 'alerts/*.yml'
# Scrape configurations
scrape_configs:
# Prometheus itself
- job_name: 'prometheus'
static_configs:
- targets: ['localhost:9090']
# Node metrics (CPU, memory, disk)
- job_name: 'node'
static_configs:
- targets: ['node_exporter:9100']
labels:
instance: 'production-server-1'
# Example: monitoring a web app
- job_name: 'webapp'
static_configs:
- targets: ['webapp:8080']
metrics_path: '/metrics'
instrumenting your application
Node.js / Express example
const express = require('express');
const promClient = require('prom-client');
const app = express();
const register = new promClient.Registry();
// Collect default metrics (CPU, memory, event loop)
promClient.collectDefaultMetrics({ register });
// Custom metrics
const httpRequestDuration = new promClient.Histogram({
name: 'http_request_duration_seconds',
help: 'Duration of HTTP requests in seconds',
labelNames: ['method', 'route', 'status_code'],
buckets: [0.1, 0.5, 1, 2, 5]
});
const httpRequestTotal = new promClient.Counter({
name: 'http_requests_total',
help: 'Total number of HTTP requests',
labelNames: ['method', 'route', 'status_code']
});
register.registerMetric(httpRequestDuration);
register.registerMetric(httpRequestTotal);
// Middleware to track requests
app.use((req, res, next) => {
const start = Date.now();
res.on('finish', () => {
const duration = (Date.now() - start) / 1000;
const labels = {
method: req.method,
route: req.route?.path || req.path,
status_code: res.statusCode
};
httpRequestDuration.observe(labels, duration);
httpRequestTotal.inc(labels);
});
next();
});
// Metrics endpoint
app.get('/metrics', async (req, res) => {
res.set('Content-Type', register.contentType);
res.end(await register.metrics());
});
app.listen(8080, () => {
console.log('Server running on :8080');
console.log('Metrics available at /metrics');
});
Python / Flask example
from flask import Flask, request
from prometheus_client import Counter, Histogram, generate_latest
import time
app = Flask(__name__)
# Metrics
request_count = Counter(
'http_requests_total',
'Total HTTP requests',
['method', 'endpoint', 'status']
)
request_duration = Histogram(
'http_request_duration_seconds',
'HTTP request duration',
['method', 'endpoint']
)
@app.before_request
def before_request():
request.start_time = time.time()
@app.after_request
def after_request(response):
duration = time.time() - request.start_time
request_count.labels(
method=request.method,
endpoint=request.endpoint,
status=response.status_code
).inc()
request_duration.labels(
method=request.method,
endpoint=request.endpoint
).observe(duration)
return response
@app.route('/metrics')
def metrics():
return generate_latest()
if __name__ == '__main__':
app.run(host='0.0.0.0', port=8080)
the queries you’ll actually use
CPU usage
# CPU usage percentage
100 - (avg by (instance) (rate(node_cpu_seconds_total{mode="idle"}[5m])) * 100)
# Per core
rate(node_cpu_seconds_total{mode!="idle"}[5m])
memory usage
# Memory usage percentage
(1 - (node_memory_MemAvailable_bytes / node_memory_MemTotal_bytes)) * 100
# Available memory
node_memory_MemAvailable_bytes / 1024 / 1024 / 1024
disk usage
# Disk usage percentage
(1 - (node_filesystem_avail_bytes / node_filesystem_size_bytes)) * 100
# Filter to only important mounts
(1 - (node_filesystem_avail_bytes{mountpoint="/"} / node_filesystem_size_bytes{mountpoint="/"})) * 100
HTTP request rate
# Requests per second
rate(http_requests_total[5m])
# By status code
sum by (status_code) (rate(http_requests_total[5m]))
HTTP latency
# 95th percentile latency
histogram_quantile(0.95, rate(http_request_duration_seconds_bucket[5m]))
# Average latency
rate(http_request_duration_seconds_sum[5m]) / rate(http_request_duration_seconds_count[5m])
grafana dashboards
import community dashboards
- Go to Grafana → Dashboards → Import
- Use these IDs:
- 1860: Node Exporter Full
- 3662: Prometheus 2.0 Overview
- 7362: MySQL Overview
Or create custom dashboards with the queries above.
auto-provisioning the datasource
Create grafana/provisioning/datasources/prometheus.yml:
apiVersion: 1
datasources:
- name: Prometheus
type: prometheus
access: proxy
url: http://prometheus:9090
isDefault: true
editable: false
alerting that actually works
Create alerts/rules.yml:
groups:
- name: system_alerts
interval: 30s
rules:
# High CPU
- alert: HighCPUUsage
expr: 100 - (avg by (instance) (rate(node_cpu_seconds_total{mode="idle"}[5m])) * 100) > 80
for: 5m
labels:
severity: warning
annotations:
summary: "High CPU usage on {{ $labels.instance }}"
description: "CPU usage is {{ $value }}%"
# High Memory
- alert: HighMemoryUsage
expr: (1 - (node_memory_MemAvailable_bytes / node_memory_MemTotal_bytes)) * 100 > 85
for: 5m
labels:
severity: warning
annotations:
summary: "High memory usage on {{ $labels.instance }}"
description: "Memory usage is {{ $value }}%"
# Disk Space
- alert: DiskSpaceLow
expr: (1 - (node_filesystem_avail_bytes{mountpoint="/"} / node_filesystem_size_bytes{mountpoint="/"})) * 100 > 85
for: 5m
labels:
severity: critical
annotations:
summary: "Disk space low on {{ $labels.instance }}"
description: "Disk usage is {{ $value }}%"
# Service Down
- alert: ServiceDown
expr: up == 0
for: 1m
labels:
severity: critical
annotations:
summary: "Service {{ $labels.job }} is down"
description: "{{ $labels.instance }} has been down for 1 minute"
# High Error Rate
- alert: HighErrorRate
expr: (sum(rate(http_requests_total{status_code=~"5.."}[5m])) / sum(rate(http_requests_total[5m]))) * 100 > 5
for: 5m
labels:
severity: critical
annotations:
summary: "High error rate detected"
description: "Error rate is {{ $value }}%"
production considerations
data retention
Prometheus stores data locally. Retention is set via command-line flags (which is why the Compose example passes them in command:), not in prometheus.yml:
--storage.tsdb.retention.time=30d
--storage.tsdb.retention.size=50GB
For longer retention, use:
- Thanos: Distributed Prometheus
- Grafana Mimir: Multi-tenant, horizontally scalable Prometheus; the actively-maintained successor to Cortex
- VictoriaMetrics: Drop-in replacement, more efficient
high availability
Run multiple Prometheus instances with identical configs. Use a load balancer or Thanos for deduplication.
security
# Add basic auth
global:
external_labels:
cluster: 'production'
# In Grafana datasource
basicAuth: true
basicAuthUser: prometheus
basicAuthPassword: supersecret
Better: Put behind VPN or use mutual TLS.
common gotchas
Five things bite people in production. Scrape interval below 10s is almost never what you want and quietly burns disk. Too many labels balloon cardinality and your queries get slow before you notice. Pick the right metric type: Counter for monotonic, Gauge for point-in-time, Histogram for distributions, and not the other way around. Monitoring without alerting is a screensaver. And the inverse: too many alerts and the on-call learns to ignore them, which is worse than no alerts at all.
the golden signals
If you only monitor four things, monitor Google’s golden signals: latency, traffic, errors, saturation. Latency is how long requests take. Traffic is request rate. Errors is the rate of failed requests. Saturation is how full the system is on CPU, memory, and disk. Everything else is a refinement on these four.
what to add next
Add exporters for the data stores you actually use: MySQL, Redis, Postgres, whichever queue you’re on. Wire Alertmanager to Slack and PagerDuty so the alerts land somewhere a human reads. Write a one-line runbook link in every alert annotation so the page tells the on-call what to do. Back up the Prometheus data directory; the whole point of long retention is gone if a disk failure wipes it. A dashboard you never look at is graphs heating the data center.
Bash Parameter Expansion: String Manipulation Without External Commands
Originally published at harshit.cloud on 2024-12-17.
TIL: Bash Parameter Expansion: String Manipulation Without External Commands
Learned that Bash has built-in string manipulation that’s way faster than calling sed, awk, or cut.
the old way (slow)
filename="document.pdf"
name=$(echo "$filename" | sed 's/.[^.]*$//') # document
ext=$(echo "$filename" | sed 's/^.*.//') # pdf
Each echo | sed spawns a new process. Slow in loops.
the new way (fast)
filename="document.pdf"
name="${filename%.*}" # document
ext="${filename##*.}" # pdf
No external processes. Pure Bash.
common patterns
remove file extension
file="archive.tar.gz"
echo "${file%.*}" # archive.tar
echo "${file%%.*}" # archive (remove all extensions)
% = remove from end (shortest match)
%% = remove from end (longest match)
get file extension
file="archive.tar.gz"
echo "${file#*.}" # tar.gz
echo "${file##*.}" # gz (last extension only)
# = remove from start (shortest match)
## = remove from start (longest match)
string replacement
path="/home/user/documents/file.txt"
# Replace first occurrence
echo "${path/user/admin}" # /home/admin/documents/file.txt
# Replace all occurrences
echo "${path//o/0}" # /h0me/user/d0cuments/file.txt
# Replace at start
echo "${path/#/home//root}" # /root/user/documents/file.txt
# Replace at end
echo "${path/%.txt/.md}" # /home/user/documents/file.md
default values
# Use default if variable is unset or empty
echo "${VAR:-default}"
# Assign default if unset
echo "${VAR:=default}"
# Error if unset
echo "${VAR:?Variable is required}"
# Use alternate value if set
echo "${VAR:+value_if_set}"
substring extraction
text="Hello World"
echo "${text:0:5}" # Hello (from pos 0, length 5)
echo "${text:6}" # World (from pos 6 to end)
echo "${text: -5}" # World (last 5 chars, note the space!)
echo "${text::-6}" # Hello (remove last 6 chars)
string length
text="Hello World"
echo "${#text}" # 11
case conversion
text="Hello World"
echo "${text^^}" # HELLO WORLD (all uppercase)
echo "${text,,}" # hello world (all lowercase)
echo "${text^}" # Hello World (first char uppercase)
echo "${text,}" # hello World (first char lowercase)
real-world example
Before (slow with multiple processes):
#!/bin/bash
for file in *.log; do
name=$(basename "$file" .log)
date=$(echo "$name" | cut -d'-' -f1)
gzip "$file"
mv "${file}.gz" "archive-${date}.gz"
done
After (fast, pure Bash):
#!/bin/bash
for file in *.log; do
name="${file%.log}" # Remove .log
date="${name%%-*}" # Get everything before first -
gzip "$file"
mv "${file}.gz" "archive-${date}.gz"
done
cheat sheet
| Pattern | Effect | Example |
|---|---|---|
${var%pattern} |
Remove shortest match from end | ${file%.txt} |
${var%%pattern} |
Remove longest match from end | ${file%%.*} |
${var#pattern} |
Remove shortest match from start | ${file#*/} |
${var##pattern} |
Remove longest match from start | ${file##*/} |
${var/old/new} |
Replace first occurrence | ${text/foo/bar} |
${var//old/new} |
Replace all occurrences | ${text//foo/bar} |
${var:offset:length} |
Substring | ${text:0:5} |
${#var} |
Length | ${#text} |
${var^^} |
Uppercase | ${text^^} |
${var,,} |
Lowercase | ${text,,} |
why this matters
In a script processing 10,000 files:
- With external commands: ~5 minutes
- With parameter expansion: ~10 seconds
That’s a 30x speedup.
one gotcha
Be careful with spaces in substring extraction:
text="Hello"
echo "${text: -3}" # llo (CORRECT - note the space)
echo "${text:-3}" # Hello (WRONG - default value syntax!)
This simple trick has made my shell scripts so much faster. No more unnecessary sed/awk/cut calls.
Instagram Graph API ile Takipçi Sayısı ve Hesap Metriklerini Çekmek (Node.js Rehberi)
Sosyal medya analitiği yapan bir araç, içerik zamanlama uygulaması ya da kişisel bir dashboard yazıyorsanız Instagram’ın resmi API’sini kullanmanız gerekir: Instagram Graph API. Bu yazıda sıfırdan kurulum, kimlik doğrulama ve takipçi sayısı / post insights çekme adımlarını Node.js ile anlatacağım.
Önemli not: “Instagram Basic Display API” Aralık 2024’te kapatıldı. Aktif olan tek resmi yol Instagram Graph API‘dir ve Business veya Creator hesabı ile bir Facebook Page bağlantısı gerektirir.
Neden Resmi API?
Tersine mühendislikle çıkarılmış “private API” veya tarayıcı kazıma (scraping) yöntemleri kısa vadede çalışsa da uzun vadede üç sorun çıkarır:
- Instagram’ın algoritması bot davranışını giderek daha agresif tespit ediyor ve hesabınızı askıya alıyor.
- Yapı her güncellemede değiştiği için kodunuz sürekli kırılır.
- Meta Kullanım Koşulları’nı ihlal eder; ticari bir ürün geliştiriyorsanız hukuki risk taşır.
Resmi Graph API yavaş kurulur ama bir kez kurulduğunda istikrarlı, oran sınırları belli ve dokümante edilmiştir.
Ön Koşullar
Başlamadan önce şunlara ihtiyacınız var:
- Instagram Business veya Creator hesabı (kişisel hesap çalışmaz — Settings → Account → Switch to Professional Account)
- Instagram hesabına bağlı bir Facebook Page
- Meta for Developers hesabı
- Node.js 18+ kurulu bir geliştirme ortamı
1. Adım: Meta Developer Uygulaması Oluşturmak
developers.facebook.com adresine girip “My Apps” → “Create App” deyin. Uygulama tipi olarak Business seçin. Uygulama oluştuktan sonra Dashboard’da sol menüden “Add Product” kısmında Instagram Graph API‘yi ve Facebook Login‘u ekleyin.
App Settings → Basic kısmından App ID ve App Secret değerlerini bir kenara not edin. Bunları kodda environment variable olarak kullanacaksınız.
2. Adım: Erişim Token’ı Almak
Instagram Graph API üç token türü kullanır:
| Token Tipi | Geçerlilik | Kullanım |
|---|---|---|
| Short-lived User Token | 1 saat | İlk OAuth akışında alınır |
| Long-lived User Token | 60 gün | Üretimde kullanılan token |
| Page Access Token | Süresiz* | Sayfa adına Instagram işlemleri için |
* Page token’ı kullanıcı sayfa yetkilerini değiştirmedikçe geçerli kalır.
OAuth Akışı
Test için en hızlısı Graph API Explorer‘ı kullanmaktır: https://developers.facebook.com/tools/explorer/
Üretim için kendi OAuth akışınızı kurarsınız:
// 1. Kullanıcıyı Facebook login'e yönlendir
const loginUrl = `https://www.facebook.com/v21.0/dialog/oauth?` +
`client_id=${APP_ID}` +
`&redirect_uri=${encodeURIComponent(REDIRECT_URI)}` +
`&scope=instagram_basic,instagram_manage_insights,pages_show_list,pages_read_engagement` +
`&response_type=code`;
// 2. Geri dönüşte code'u short-lived token'a çevir
async function exchangeCodeForToken(code) {
const url = `https://graph.facebook.com/v21.0/oauth/access_token?` +
`client_id=${APP_ID}` +
`&client_secret=${APP_SECRET}` +
`&redirect_uri=${REDIRECT_URI}` +
`&code=${code}`;
const res = await fetch(url);
return res.json();
}
// 3. Short-lived token'ı 60 günlük long-lived token'a çevir
async function getLongLivedToken(shortToken) {
const url = `https://graph.facebook.com/v21.0/oauth/access_token?` +
`grant_type=fb_exchange_token` +
`&client_id=${APP_ID}` +
`&client_secret=${APP_SECRET}` +
`&fb_exchange_token=${shortToken}`;
const res = await fetch(url);
return res.json();
}
3. Adım: Instagram Business Account ID’sini Bulmak
Bir kullanıcının Instagram verilerine erişmek için önce Facebook Page ID‘sini, sonra ona bağlı Instagram Business Account ID‘sini bulmanız gerekir:
async function getInstagramAccountId(userAccessToken) {
const pagesRes = await fetch(
`https://graph.facebook.com/v21.0/me/accounts?access_token=${userAccessToken}`
);
const pages = await pagesRes.json();
const pageId = pages.data[0].id;
const pageToken = pages.data[0].access_token;
const igRes = await fetch(
`https://graph.facebook.com/v21.0/${pageId}?fields=instagram_business_account&access_token=${pageToken}`
);
const igData = await igRes.json();
return {
instagramAccountId: igData.instagram_business_account.id,
pageAccessToken: pageToken
};
}
4. Adım: Takipçi Sayısı ve Profil Bilgilerini Çekmek
Asıl olay burada başlıyor. Tek bir istekle username, takipçi sayısı, post sayısı gibi temel bilgileri alabilirsiniz:
async function getAccountInfo(igAccountId, pageToken) {
const fields = [
'username',
'name',
'biography',
'followers_count',
'follows_count',
'media_count',
'profile_picture_url'
].join(',');
const url = `https://graph.facebook.com/v21.0/${igAccountId}` +
`?fields=${fields}&access_token=${pageToken}`;
const res = await fetch(url);
return res.json();
}
// Örnek çıktı:
// {
// username: "ornek_hesap",
// followers_count: 12453,
// follows_count: 188,
// media_count: 247
// }
5. Adım: Post Insights (Etkileşim Verisi)
Belirli bir gönderinin beğeni, yorum, erişim ve gösterim sayılarını almak için:
async function getMediaList(igAccountId, pageToken) {
const url = `https://graph.facebook.com/v21.0/${igAccountId}/media` +
`?fields=id,caption,media_type,permalink,timestamp,like_count,comments_count` +
`&access_token=${pageToken}`;
const res = await fetch(url);
return res.json();
}
async function getMediaInsights(mediaId, pageToken) {
const metrics = 'impressions,reach,saved,engagement';
const url = `https://graph.facebook.com/v21.0/${mediaId}/insights` +
`?metric=${metrics}&access_token=${pageToken}`;
const res = await fetch(url);
return res.json();
}
6. Adım: Hesap Bazında Insights
Hesabın genelinde günlük/haftalık erişim, profil ziyareti gibi metrikler için:
async function getAccountInsights(igAccountId, pageToken) {
const metrics = 'impressions,reach,profile_views';
const period = 'day';
const url = `https://graph.facebook.com/v21.0/${igAccountId}/insights` +
`?metric=${metrics}&period=${period}&access_token=${pageToken}`;
const res = await fetch(url);
return res.json();
}
Hız Sınırları (Rate Limits)
Instagram Graph API uygulama bazında saatte 200 çağrı × hesap sayısı olarak hesaplanır. Yani 100 işletme hesabınız varsa saatte 20.000 çağrı yapabilirsiniz. Hız sınırını aştığınızda error.code === 4 yanıtı dönüyor.
İyi pratikler:
- Sık çağırdığınız verileri (örn. takipçi sayısı) en az 15 dakika cache’leyin
- Insight çağrılarını günde bir kez batch olarak çalıştırın
- Webhook’larla (
instagram_manage_insights) push tabanlı akışa geçin
Sık Karşılaşılan Hatalar
(#10) Application does not have permission for this action — App Review’dan geçmeyen permission istiyorsunuz. Test için kendinizi geliştirici/test kullanıcısı olarak ekleyin.
Invalid OAuth access token — Token süresi dolmuş ya da farklı uygulamaya ait. Long-lived token’ı 50. günde proaktif olarak yenileyin.
Instagram User does not exist — Hesap Business/Creator değil ya da Page’e bağlı değil.
Sonuç
Instagram’ın resmi API’si ilk kurulumda epey kalabalık (Facebook App + Page + Business hesabı + OAuth) ama bir kez ayaklandıktan sonra sağlam bir temel oluşturur. Üzerine; planlanmış yayın aracı, analytics dashboard, içerik öneri sistemi, otomatik DM yanıtlayıcı gibi pek çok proje kurabilirsiniz.
Eğer scraping ya da bot otomasyonu düşünüyorsanız: kısa vadeli kazançtan vazgeçip resmi API’ye yatırım yapın. Üretim ortamında ölçeklenebilen tek yol budur.
Kaynaklar ve Faydalı Bağlantılar
- Meta — Instagram Platform Docs
- Graph API Explorer (test aracı)
- Resmi Facebook Business Node.js SDK
- Instagram Webhooks Dokümanı
- Rate Limits Detayı
- Örnek Uygulama
Sorularınızı yorumlara yazabilirsiniz. Bir sonraki yazıda Instagram’ın Webhooks sistemi ile push tabanlı bildirimleri ele alacağım.
Take your local GitHub sessions anywhere
Kick off work in VS Code or the CLI, finish it from your phone. Remote control for GitHub Copilot sessions is now generally available on github.com and GitHub Mobile.
The post Take your local GitHub sessions anywhere appeared first on The GitHub Blog.