Microsoft ushers in AI-native era with open agentic stack, Linux updates

At the Open Source Summit North America 2026, Microsoft today revealed a sweeping set of updates aimed at strengthening the foundation of the AI-native era. Central to these announcements is the upcoming public preview of Azure Linux 4.0 on Azure Virtual Machines and the general availability of Azure Container Linux. These distributions represent a hardened … continue reading

The post Microsoft ushers in AI-native era with open agentic stack, Linux updates appeared first on SD Times.

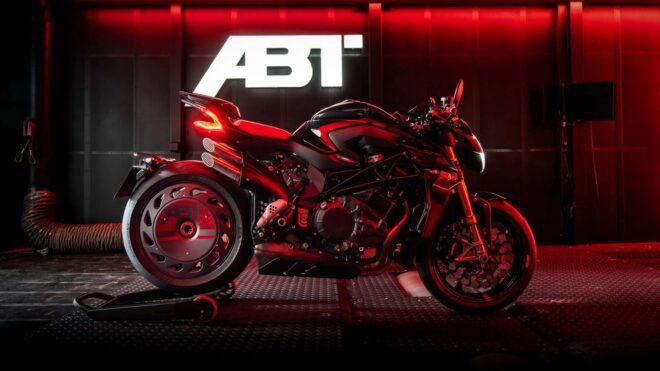
ABT, ilk motosiklet projesini görücüye çıkardı

ABT, ilk motosiklet projesini görücüye çıkardı

ABT, ilk motosiklet projesini görücüye çıkardıDaha çok özel modifiye ettiği Audi modelleriyle tanınan Almanya merkezli ABT, bugün ilk motosiklet projesini görücüye çıkardı. Şirketin 130’uncu yılına özel olarak hazırlanan motosikletin temelinde hali hazırda iddialı “MV Agusta Brutale 1000” yer alıyor. Dördüncü çeyrekte satışa sunulacak özel modelde 19 farklı karbon fiber parça kullanan şirket, arka tekerlekte turbofan olarak geçen bir karbon fiber kapağa yer veriyor. ABT bu parçanın salıncak kolu etrafındaki hava akışını düzenlediğini ve motosikletin sürtünme katsayısını azalttığını belirtiyor. Dikkat çeken modelde 998 cc hacminde sıralı dört silindirli bir motor görev yapıyor. Bu ünite yeni eksantrik milleri, yenilenen motor yönetimi, hassaslaştırılan gaz kontrolü ve daha kısa son dişli oranıyla güçlendirilmiş ancak standart sürümle benzer şekilde 199 beygir güç ile 116 Nm tork sunuyor. Modelin piste özel versiyonunda gücün 205 beygire çıkarıldığı açıklanırken, toplamda 130 adet üretileceği belirtilen motosiklet için kapının 40 bin eurodan açılacağı belirtiliyor. Bunun MV Agusta Brutale 1000’e kıyasla 13 bin euro kadar yüksek […]

ABT, ilk motosiklet projesini görücüye çıkardı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Why I Built All 170 Tools to Run in the Browser (And What I Learned)

Why I Built All 170 Tools to Run in the Browser

When I started building UtilVox, the obvious
approach was server-side processing. Upload file →
process on server → return result. Every major
tool site works this way.

I went the opposite direction. Here’s why —
and what I learned.

The Problem With Server-Side Tool Sites

Most free online tools have a dirty secret:

Your files go to their servers.

When you “compress” a PDF on a popular site,
that file travels to their infrastructure,
gets processed, stored (temporarily or permanently),
and returned. You’re trusting a random website
with potentially sensitive documents.

Contracts. Medical records. Financial statements.
Tax documents. People upload all of this to
“free” PDF tools without thinking about it.

The Client-Side Approach

I rebuilt everything using browser APIs:

  • PDF processing → PDF.js + client-side compression
  • Image manipulation → Canvas API + WebAssembly
  • Currency conversion → Client fetches from forex API directly
  • JWT decoding → Pure JavaScript (it’s just Base64)
  • JSON formatting → JSON.parse() + JSON.stringify()

The result: your files never leave your device.

The Tradeoffs

Nothing is free. Client-side processing has limits:

Memory constraints
Large files (50MB+ PDFs) can crash browser tabs
on low-memory devices. Server processing handles
this better.

Processing speed
WebAssembly is fast but not as fast as native
server code for heavy operations like OCR.

No persistence
Can’t save user history, preferences, or
previous uploads without a backend.

For 90% of use cases, these tradeoffs are
worth it. The 10% who need server-side power
have Adobe Acrobat.

The Stack

  • Next.js 14 App Router — Server Components
    for fast LCP, Client Components for interactivity
  • TypeScript — 170 tools, type safety is essential
  • Tailwind CSS — consistent UI across every tool
  • Vercel — edge deployment, global CDN
  • Cloudflare — DNS, DDoS protection

What I’d Do Differently

Ship faster. I spent too long perfecting
individual tools before launching. Users don’t
care about perfection — they care about
whether the tool works.

Build in public from day one. The tools that
got the most early traffic were ones I tweeted
about while building.

Current Status

170+ tools live at utilvox.com.

Working on: SEO, backlinks, and adding
requested tools from user feedback.

If you’re building something similar or have
questions about the architecture — ask below.

transactional-vs-bulk-email-2026.md

Transactional Email: Definition and Characteristics

Transactional emails are automated, triggered by a specific user action:

  • Order confirmation
  • Password reset
  • Shipping notification
  • Account verification
  • Payment receipt
  • Two-factor authentication codes

Characteristics:

  • One-to-one communication (1 recipient per message)
  • High individual value, low total volume
  • Immediate delivery required (< 30 seconds SLA)
  • Highly personalized content
  • Must reach inbox — users are waiting for these
  • Low complaint risk (user requested it)

SLA requirements:

  • 99.9%+ delivery success rate
  • < 30 second end-to-end latency
  • 24/7 availability (no maintenance windows)

Bulk Email: Definition and Characteristics

Bulk (marketing) emails are one-to-many:

  • Newsletters
  • Promotional campaigns
  • Product announcements
  • Re-engagement campaigns
  • Retention campaigns

Characteristics:

  • One-to-many (single campaign → thousands/millions of recipients)
  • High total volume, moderate individual value
  • Delivery speed less critical (hours acceptable)
  • Campaign-level tracking (open rates, click rates)
  • Higher complaint risk (recipients may not have opted in)
  • CAN-SPAM and GDPR compliance required

SLA requirements:

  • 95%+ delivery success rate
  • < 4 hour campaign completion
  • List-unsubscribe compliance (RFC 8058)
  • Unsubscribe processing within 10 days (CAN-SPAM)

Why Separation Matters

Problem 1: Marketing Traffic Competes With Transactional

If your marketing campaign sends 500K emails over 2 hours, it consumes MTA resources (connections, queue slots, CPU) that your transactional emails need. The result: password resets arriving 10 minutes late.

Problem 2: Reputation Contamination

One bad marketing campaign (high bounce rate, complaints) can damage your IP reputation — which affects your transactional emails’ inbox placement.

Problem 3: Compliance Conflicts

Marketing email requires List-Unsubscribe headers (RFC 8058) and opt-out mechanisms. Transactional email doesn’t. Mixing them in one queue creates compliance complexity.

Problem 4: Monitoring Complexity

Blending transactional and bulk metrics makes it impossible to know if your transactional deliverability is healthy.

Architecture: Separate MTA Stacks

Recommended Architecture for 5M+/month Senders

┌─────────────────────────────────────────────────────────┐
│              Application Layer                          │
│   (Orders, Auth, Marketing Platform, CRM)               │
└──────────────────────┬──────────────────────────────────┘
                       │
         ┌─────────────┴──────────────┐
         │                            │
┌────────▼─────────┐      ┌──────────▼──────────┐
│  Transactional   │      │   Bulk/Marketing     │
│  SMTP Relay       │      │   SMTP Relay         │
│  (KumoMTA-1)      │      │  (KumoMTA-2)         │
│                   │      │                      │
│  - High priority  │      │  - Normal priority   │
│  - 2s SLA         │      │  - 4h campaign SLA   │
│  - Separate IPs   │      │  - Separate IPs       │
│  - P0 alerting    │      │  - P1 alerting        │
└────────┬─────────┘      └──────────┬──────────┘
         │                             │
┌────────▼─────────┐      ┌──────────▼──────────┐
│  Dedicated        │      │  Dedicated           │
│  IPs (warm,       │      │  IPs (warm,         │
│  established rep) │      │  separate rep)      │
└───────────────────┘      └─────────────────────┘

Separate DKIM and Domains

Transactional:

  • From: [email protected]
  • DKIM: mail._domainkey.mx.example.com
  • Separate reputation for critical sending

Bulk/Marketing:

  • From: [email protected]
  • DKIM: mail._domainkey.example.com
  • More tolerant reputation risk

KumoMTA Configuration: Transactional vs Bulk

Transactional Configuration (High Priority)

-- /etc/kumomta/transactional.conf

-- High-priority SMTP listener
kumo.start_smtp_listener {
    listen = "[::]:2525",
    name = "transactional",
    relay_hosts = { "10.0.0.0/8" },
    auth_require_tls = true,
}

-- Prometheus metrics (separate port)
kumo.start_http_listener {
    listen = "[::]:2001",
    trusted_hosts = { "127.0.0.1" },
}

-- Minimal queue depth for low latency
kumo.configure_queue {
    max_queue_depth = 5000,
    retry_interval = "1m",
    max_retry_age = "24h",
}

-- DKIM signing
kumo.configure_dkim_signing {
    domain = "mx.example.com",
    selector = "mail",
    key_file = "/etc/kumomta/keys/mail._domainkey.mx.example.com.pem",
}

Bulk Configuration (Normal Priority)

-- /etc/kumomta/bulk.conf

-- Bulk/marketing listener
kumo.start_smtp_listener {
    listen = "[::]:2526",
    name = "bulk",
    relay_hosts = { "10.0.0.0/8" },
    auth_require_tls = true,
}

-- Prometheus metrics (separate port)
kumo.start_http_listener {
    listen = "[::]:2002",
    trusted_hosts = { "127.0.0.1" },
}

-- Higher queue depth for volume
kumo.configure_queue {
    max_queue_depth = 100000,
    retry_interval = "5m",
    max_retry_age = "72h",
}

-- DKIM signing
kumo.configure_dkim_signing {
    domain = "example.com",
    selector = "mail",
    key_file = "/etc/kumomta/keys/mail._domainkey.example.com.pem",
}

-- RFC 8058 List-Unsubscribe headers
kumo.on("smtp_message_received", function(domain, meta)
    local headers = meta.headers or {}

    -- Only add for bulk campaigns
    if headers["X-Campaign-Type"] == "marketing" then
        kumo.add_header("List-Unsubscribe",
            "<mailto:[email protected]?subject=unsubscribe>")
        kumo.add_header("List-Unsubscribe-Post",
            "List-Unsubscribe=One-Click")
        kumo.add_header("Precedence", "bulk")
    end
end)

Compliance: CAN-SPAM and GDPR

Transactional Exemption

Key fact: CAN-SPAM exempts transactional emails from:**

  • Physical postal address requirements
  • Opt-out link requirements (though still recommended)

Transactional exemption applies when:

  • Email is to facilitate an existing transaction
  • Email is about a purchase or account status
  • Email is a one-to-one communication

Marketing emails are NOT exempt:

  • Newsletters, promotions, announcements
  • Re-engagement campaigns
  • Non-triggered educational content

GDPR Considerations

Email Type Consent Required Legitimate Interest
Transactional No (contractual necessity) N/A
Marketing (explicit opt-in) Yes No
Marketing (existing customer) Yes (soft opt-in in some EU countries) Sometimes
Re-engagement Yes No

For bulk sending to EU residents:

  • Explicit consent required before sending
  • Double opt-in recommended
  • Clear unsubscribe mechanism
  • Data minimization (don’t retain more than needed)

When NOT to Separate

Separating transactional and bulk infrastructure adds operational complexity. Don’t separate if:

  • Your total volume is under 500K/month
  • Your transactional volume is under 10K/month
  • You have no engineering capacity to manage two stacks
  • Your marketing and transactional emails come from the same product (e.g., a marketplace where order confirmations ARE your marketing)

In these cases, use a single MTA with traffic shaping to prioritize transactional:

kumo.on("smtp_message_received", function(domain, meta)
    local headers = meta.headers or {}
    if headers["X-Priority"] == "high" then
        kumo.set_queue_priority("high")
    end
end)

Monitoring: Separate Metrics for Each

Transactional Metrics Dashboard

Metric Target Alert
Delivery success rate > 99.9% < 99.5%
End-to-end latency (p95) < 30s > 60s
Queue depth < 100 > 500
Hard bounce rate < 0.1% > 0.5%
5xx error rate < 0.1% > 0.5%

Bulk Campaign Metrics Dashboard

Metric Target Alert
Campaign delivery rate > 96% < 93%
Campaign completion time < 4 hours > 8 hours
Hard bounce rate < 2% > 5%
Soft bounce rate < 5% > 10%
Complaint rate < 0.1% > 0.3%
Unsubscribe processing < 10 days > 10 days

FAQ

Q: Can I use the same domain for transactional and bulk email?
A: Technically yes, but not recommended. If your bulk sending damages the domain’s reputation, your transactional emails suffer too. Use subdomains (e.g., mx.example.com for transactional, example.com for bulk).

Q: Should I use separate IP addresses for transactional and bulk?
A: Yes — always. This is the most effective way to prevent reputation cross-contamination. Your transactional IP should have established, pristine reputation. Your bulk IP(s) can absorb more risk.

Q: Can I send transactional and bulk through the same KumoMTA instance?
A: Yes, using Lua policies to route and prioritize differently. But for high-volume operations (10M+/month), separate instances on separate infrastructure provide better isolation.

Q: Does SendGrid/Mailgun separate transactional and bulk?
A: Yes — both have separate APIs and infrastructure for transactional (via SMTP/API) and marketing (via marketing campaigns). This is one reason enterprise senders often migrate to self-hosted KumoMTA for full control.

Q: What’s the minimum volume where separation becomes worth it?
A: When your bulk campaigns regularly exceed 100K emails/session, or when transactional SLA < 30s is business-critical. For most organizations, this is around 2-5M total monthly volume.

Get Help With Email Architecture

PostMTA designs email infrastructure for high-volume senders:

  • Transactional/bulk separation architecture
  • KumoMTA multi-stack configuration
  • Compliance audit (CAN-SPAM, GDPR)
  • Reputation management and IP strategy

👉 Talk to our infrastructure team →

For related guides, see SMTP Relay Setup Guide, IP Warmup Strategies, and KumoMTA Setup Guide.

References: RFC 8058 (List-Unsubscribe) | CAN-SPAM Requirements

Migrating 200+ Microsites to a Multi-Tenant CMS: Architecture Patterns That Scale

Cross-posted from my Medium article.

Migrating 200+ Microsites to a Multi-Tenant CMS: Architecture Patterns That Scale

Lessons from consolidating fragmented web properties into a scalable, reusable, governance-friendly digital platform.

Many enterprises accumulate dozens — sometimes hundreds — of microsites over time.

A product team launches one site. A regional team launches another. A campaign creates a temporary site that becomes permanent. A business unit chooses a different template, plugin, hosting model, or content workflow. Over several years, what started as flexibility becomes fragmentation.

At small scale, this may look manageable. At enterprise scale, it creates real operational cost.

Teams begin dealing with duplicate codebases, inconsistent user experience, fragmented SEO, accessibility gaps, security patching complexity, slow global updates, and unclear ownership. Even simple changes — such as updating a header, footer, privacy notice, tracking script, or accessibility component — can become a large coordination effort.

A multi-tenant CMS architecture can help solve this problem.

But successful migration is not just about moving content from old sites into a new CMS. It is about creating a reusable digital platform with shared templates, configurable components, consistent governance, automated delivery, and enough local flexibility for business teams to manage their own content.

This article outlines practical architecture patterns for migrating large groups of microsites into a scalable, reusable, governance-friendly CMS platform.

The Problem With Microsite Sprawl

Microsites usually begin with good intentions.

A team needs speed. A business unit needs independence. A campaign needs a custom experience. A regional group needs local control. Those needs are valid.

The problem appears when every microsite becomes its own mini-platform.

Over time, the enterprise may end up with many different codebases, hosting models, templates, plugins, tracking scripts, accessibility patterns, content workflows, and release processes. This creates fragmentation across technology, content, operations, compliance, and user experience.

Common symptoms include duplicate codebases, inconsistent branding, multiple versions of headers and footers, uneven accessibility compliance, fragmented SEO, different analytics implementations, slow global changes, and high dependency on developers for basic content updates.

The hidden cost is not just technical debt. It is organizational drag.

When simple changes require coordination across dozens or hundreds of sites, the enterprise loses speed. When every site behaves differently, users lose consistency. When governance is unclear, risk increases.

That is why large-scale microsite migration should not be treated as a lift-and-shift exercise. It should be treated as platform modernization.

Why Multi-Tenant CMS Architecture Helps

A multi-tenant CMS architecture allows one platform to support many sites while sharing common capabilities.

Instead of every site having its own templates, components, deployment pipeline, and governance model, a shared platform provides reusable foundations. Individual sites can still maintain local identity and content ownership, but they operate within a consistent architecture.

A good multi-tenant CMS model typically includes shared templates, reusable widgets, common security patterns, standardized analytics, centralized DevSecOps pipelines, consistent accessibility practices, and role-based content governance.

The goal is balance.

Too much central control creates bottlenecks. Too much local freedom recreates fragmentation.

The architecture should give central teams control over platform standards while giving local teams enough flexibility to manage content without developer involvement for every change.

That balance is where multi-tenant CMS architecture becomes powerful.

Pattern 1: Parent/Child Site Architecture

One useful pattern is a parent/child site model.

In this model, a parent or global layer provides shared platform capabilities. Child sites inherit those capabilities while maintaining local content, navigation, and business-specific pages.

The parent layer may define global templates, shared themes, header and footer structure, common navigation patterns, shared assets, analytics configuration, accessibility standards, reusable content blocks, and approved widgets.

Child sites can then use those shared assets while customizing local pages, service lines, landing pages, location information, or business-specific content.

This pattern helps reduce duplication.

For example, if the enterprise needs to update a global footer, privacy link, analytics script, or accessibility component, the change can be made at the shared layer and propagated across sites. Without this architecture, the same change may require separate updates across dozens or hundreds of properties.

The key design question is simple:

What should be inherited globally, and what should remain local?

A scalable architecture defines this boundary clearly.

Pattern 2: Reusable Widgets and Components

A multi-tenant CMS succeeds or fails based on its component model.

If every page requires custom development, the platform will not scale. Content authors will remain dependent on developers, release cycles will stay slow, and the enterprise will continue accumulating one-off solutions.

Reusable widgets and components solve this problem.

Instead of building hundreds of custom page variations, architects can create configurable building blocks such as hero banners, content cards, location finders, call-to-action sections, accordions, forms, search modules, alert banners, and related content sections.

The important word is configurable.

A reusable component should support controlled variation without becoming a free-for-all. Authors should be able to adjust content, ordering, imagery, labels, and layout options within approved boundaries.

This improves delivery speed, brand consistency, accessibility compliance, testing efficiency, reuse across sites, maintainability, and author independence.

The best component libraries are designed with both developers and content authors in mind.

Developers need clean architecture and maintainable code. Authors need practical flexibility. Users need consistency.

Pattern 3: Shared Content With Local Overrides

Large enterprises often have content that applies across many sites.

Examples may include service descriptions, compliance notices, policies, campaign messages, brand assets, or standard calls to action.

Duplicating that content across many sites creates maintenance risk. If content changes, every duplicate must be updated. Inevitably, some copies become outdated.

Shared content reduces that problem.

A strong CMS architecture should support global content blocks, shared descriptions, reusable metadata, common disclaimers, shared media assets, localized variants, regional overrides, approval workflows, and clear content ownership.

But shared content alone is not enough. Local teams often need flexibility.

That is where local overrides matter.

A scalable model allows central teams to define standard content while allowing local teams to override specific fields where appropriate. The architecture should define which fields are global, which are local, and which require approval.

Without those rules, shared content becomes either too rigid or too chaotic.

Good governance turns shared content from a technical feature into an operating model.

Pattern 4: Centralized DevSecOps and Release Management

A multi-tenant CMS platform is not just a content platform. It is also a delivery platform.

If each site has its own deployment process, release calendar, testing strategy, and rollback method, the enterprise still has operational fragmentation.

Centralized DevSecOps helps standardize delivery.

Important practices include common source control, shared CI/CD pipelines, automated build and deployment, environment consistency, security scanning, dependency scanning, accessibility testing, regression testing, performance checks, release approvals, rollback plans, monitoring, and alerting.

This matters because platform changes affect many sites.

A small component change could impact dozens of pages across multiple properties. A shared template change could affect an entire portfolio. A tracking script update could affect analytics across the enterprise.

That requires disciplined release management.

Automation helps, but governance is equally important. Teams need clear rules for what can be released independently, what requires regression testing, and what needs broader stakeholder review.

The larger the platform, the more important release discipline becomes.

Pattern 5: Migration Factory Approach

Migrating hundreds of microsites cannot be handled as a collection of one-off projects.

A repeatable migration factory approach works better.

The migration factory model starts with inventory. Teams identify existing sites, group them by template and content pattern, map old pages to new structures, clean up outdated content, define migration waves, and create repeatable QA checklists.

The first few migrations may be slower because the team is building the playbook. Later migrations become faster because patterns repeat.

This approach also helps with estimation. Once site types are grouped, teams can better predict effort based on complexity rather than treating every site as unique.

The goal is not to eliminate all variation.

The goal is to reduce unnecessary variation.

A good migration factory creates repeatable execution without ignoring legitimate business differences.

Metrics That Matter

Large CMS migrations should be measured.

Without metrics, teams may only know that the migration was completed. They may not know whether the platform actually improved delivery, quality, performance, or maintainability.

Useful metrics include release cycle time, deployment frequency, content publishing velocity, number of reusable components, reduction in custom code, page performance, mobile performance, accessibility score, SEO health, regression testing effort, support tickets, and time required for global updates.

Metrics help prove whether the architecture is working.

For example, if global updates still take weeks, the shared architecture may not be shared enough. If content authors still require developers for basic page updates, the component model may be too rigid. If accessibility issues keep recurring, accessibility may not be built into components and templates.

The right metrics reveal where the platform needs improvement.

Common Mistakes

Large-scale CMS migrations fail or underperform when teams treat the migration as a cosmetic redesign or a content copy exercise.

One common mistake is rebuilding every old site exactly as-is. That preserves old problems inside a new platform. Migration is an opportunity to simplify.

Another mistake is allowing too much customization. Excessive customization recreates fragmentation. The platform needs controlled flexibility.

Teams also underestimate content governance. Without ownership rules, content becomes outdated quickly.

Accessibility is another common gap. It should be built into templates and components from the beginning, not treated as a late-stage checklist item.

Content cleanup also matters. Bad content in a better CMS is still bad content.

Finally, author training is often underestimated. A platform only works if content teams know how to use it properly.

Avoiding these mistakes requires architecture discipline and operating discipline.

Practical Architecture Checklist

Before migrating microsites into a multi-tenant CMS, architects should answer several questions:

  • What is the tenant model?
  • Which capabilities are global?
  • Which capabilities are local?
  • What content should be shared?
  • What content can be overridden?
  • What templates are standardized?
  • What components or widgets are reusable?
  • Who owns global content?
  • Who owns local content?
  • What approval workflows are needed?
  • How are accessibility requirements enforced?
  • How are SEO standards enforced?
  • What analytics model will be used?
  • How are deployments automated?
  • What regression testing is required?
  • How will performance be measured?
  • What is the rollback plan?
  • How will content authors be trained?
  • How will platform adoption be measured?

A checklist does not replace architecture, but it helps keep the migration honest.

Conclusion

A CMS migration is not just a content migration.

It is platform modernization.

When enterprises consolidate large numbers of microsites, the real value comes from reusable architecture, consistent governance, shared components, automated delivery, and clear operating models.

A well-designed multi-tenant CMS can reduce duplication, improve consistency, accelerate global changes, strengthen accessibility, improve maintainability, and give content teams more independence.

But the technology alone is not enough.

The difference between another fragmented platform and a scalable digital foundation is architecture discipline.

Originally published on Medium:

https://medium.com/@anujagrawal4/migrating-200-microsites-to-a-multi-tenant-cms-architecture-patterns-that-scale-b2da69ee69b4

The views expressed here are my own and are based on general enterprise architecture experience. They do not represent any current or former employer or client.

Firewall: only allow specific application server IPs

What Is an SMTP Relay Server?

An SMTP relay accepts outbound email from your applications and delivers it to the final destination mail servers (Gmail, Outlook, Yahoo, etc.). Unlike a local MTA that handles both inbound and outbound, a relay focuses purely on outbound delivery optimization.

Typical architecture:

Application → SMTP Relay → Internet → Recipient Mail Server
              (KumoMTA)   (TLS)

The relay handles:

  • Message queuing and retry logic
  • TLS encryption with certificate management
  • Rate limiting and traffic shaping
  • DKIM signing and SPF passthrough
  • Bounce processing and delivery tracking

Self-Hosted vs Cloud SMTP Relay

Factor Self-Hosted (KumoMTA) Cloud SMTP (SendGrid, Mailgun)
Control Full (server, config, logs) Limited (API only)
Cost at 10M/month ~$1,500 (infra) ~$1,200 (paid plan)
Cost at 100M/month ~$5,000 (infra) ~$15,000+
Throughput ceiling Unlimited (scale infra) Shared, tier-limited
Compliance Full GDPR/CAN-SPAM control Shared responsibility
Setup complexity Medium Low
AI optimization Yes (KumoMTA native) Limited
Custom bounce processing Full Lua control API/webhook only

Choose self-hosted if: You send > 5M emails/month, have engineering capacity, need full compliance control, or want to eliminate per-email pricing.

Choose cloud SMTP if: You’re under 1M emails/month, have no infra engineering, or need rapid setup without infrastructure management.

KumoMTA as SMTP Relay: Production Configuration

Core Relay Configuration

-- /etc/kumomta/relay.conf
-- Production SMTP relay configuration

-- SMTP Listener (accepts from internal apps)
kumo.start_smtp_listener {
    listen = "[::]:2525",  -- Internal relay port
    name = "relay-in",
    relay_hosts = { "10.0.0.0/8", "172.16.0.0/12" }, -- Internal networks only
    auth_require_tls = true, -- Require AUTH from application servers
}

-- HTTP API for application injection
kumo.start_http_listener {
    listen = "[::]:8080",
    trusted_hosts = { "10.0.0.0/8", "127.0.0.1" },
}

-- DKIM signing for all outbound
kumo.configure_dkim_signing {
    domain = "example.com",
    selector = "mail",
    key_file = "/etc/kumomta/keys/mail._domainkey.example.com.pem",
    headers = { "From", "To", "Subject", "Date", "Message-ID" },
}

-- TLS for outbound delivery
kumo.configure_tls {
    min_tls_version = "1.3",
    ciphers = "ECDHE-RSA-AES256-GCM-SHA384",
}

-- Prometheus metrics
kumo.start_http_listener {
    listen = "[::]:2000",
    trusted_hosts = { "127.0.0.1" },
}

Application Integration via HTTP API

Applications inject mail via KumoMTA’s HTTP API:

curl -X POST http://kumomta-relay:8080/v1/message 
  -H "Content-Type: application/json" 
  -H "Authorization: Bearer YOUR_API_KEY" 
  -d '{
    "from": "[email protected]",
    "to": ["[email protected]", "[email protected]"],
    "subject": "Your Order #12345 Has Shipped",
    "headers": {
      "X-Order-ID": "12345",
      "X-Campaign": "shipping-confirmation"
    },
    "html": "<h1>Your order is on its way!</h1>",
    "text": "Your order #12345 has shipped. Track at: https://track.example.com/12345"
  }'

Multi-Tenant Relay Configuration

For SaaS platforms sending on behalf of customers:

-- Per-customer relay configuration
kumo.on("smtp_server_greeting", function(domain, meta)
    local tenant = meta.tenant

    if tenant then
        -- Apply per-tenant rate limits
        local limit = get_tenant_rate_limit(tenant)
        kumo.limit_sending(tenant, limit, { per = "minute" })

        -- Set tenant-specific DKIM
        local dkim = get_tenant_dkim(tenant)
        if dkim then
            kumo.sign_dkim(dkim.domain, dkim.selector, dkim.key_file)
        end
    end
end)

Security: TLS, AUTH, and IP Allowlisting

TLS Configuration (Required for 2026)

-- Enforce TLS 1.3 for all delivery
kumo.configure_tls {
    min_tls_version = "1.3",
    prefer_server_ciphers = true,
}

-- For submission ports (SMTPS)
kumo.start_smtp_listener {
    listen = "[::]:465",
    name = "smtps",
    tls = {
        cert_file = "/etc/kumomta/tls/server.crt",
        key_file = "/etc/kumomta/tls/server.key",
    },
}

Generate self-signed certificates for testing:

openssl req -x509 -newkey rsa:4096 -keyout key.pem -out cert.pem -days 365 -nodes 
  -subj "/CN=mail.example.com"

SMTP AUTH Configuration

-- Require AUTH for submission port
kumo.start_smtp_listener {
    listen = "[::]:587",
    name = "submission",
    auth_require_tls = true,
    -- Supported mechanisms
    auth_mechanisms = { "PLAIN", "LOGIN", "CRAM-MD5" },
}

Application authentication (for HTTP API):

-- API key validation
kumo.on("http_request", function(request)
    local token = request.headers["Authorization"]:gsub("Bearer ", "")
    if not validate_api_key(token) then
        return { status = 401, body = "Unauthorized" }
    end
end)

IP Allowlisting

-- Only accept connections from trusted IPs
kumo.start_smtp_listener {
    listen = "[::]:2525",
    name = "relay-in",
    relay_hosts = { "10.0.0.0/8", "172.16.0.0/12" },
    -- Deny all other IPs
}

For additional security with cloud applications:

# Firewall: only allow specific application server IPs
sudo ufw allow from 10.0.1.0/24 to any port 2525
sudo ufw allow from 10.0.2.0/24 to any port 2525

Performance Tuning for High-Volume Relay

Connection and Thread Tuning

-- /etc/kumomta/tuning.conf

-- Delivery threads (scale with CPU cores)
kumo.configure_delivery {
    threads = 16, -- 2x CPU cores
    max_connections_per_domain = 10,
    max_message_rate = 1000, -- per minute per domain
}

-- Queue management
kumo.configure_queue {
    max_queue_depth = 100000,
    retry_interval = "5m",
    max_retry_age = "72h",
    dead_letter_after = "7d",
}

Monitoring Metrics

Key metrics to track:

Metric Target Alert
kumomta_queue_depth < 10,000 > 50,000
kumomta_delivery_latency_p95 < 30s > 60s
kumomta_smtp_errors_total < 0.1% > 1%
kumomta_tls_failures_total < 0.5% > 2%
Connections per domain < 10 > 20

SMTP Relay for Specific Use Cases

Transactional Email (Order Confirmations, Password Resets)

Requirements:

  • Immediate delivery (< 30 seconds end-to-end)
  • High reliability (99.9% success rate)
  • DKIM signing required
  • Low volume per user, high total volume
-- Transactional: low latency priority
kumo.on("smtp_message_received", function(domain, meta)
    local headers = meta.headers or {}
    if headers["X-Type"] == "transactional" then
        -- Elevate priority
        kumo.set_queue_priority("high")
    end
end)

Bulk/Marketing Email

Requirements:

  • High throughput (100K+ emails/hour)
  • Per-campaign tracking
  • Bounce processing integration
  • List unsubscribe handling (RFC 8058)
-- Bulk: throughput priority
kumo.on("smtp_message_received", function(domain, meta)
    local headers = meta.headers or {}
    local campaign = headers["X-Campaign"]

    if campaign then
        -- Track campaign metrics
        increment_campaign_metric(campaign, "queued")
    end
end)

-- List-Unsubscribe header (RFC 8058 - required for bulk)
kumo.on("smtp_message_received", function(domain, meta)
    if is_bulk_campaign(meta.headers) then
        kumo.add_header("List-Unsubscribe", "<mailto:[email protected]?subject=unsubscribe>")
        kumo.add_header("List-Unsubscribe-Post", "List-Unsubscribe=One-Click")
    end
end)

Troubleshooting Common SMTP Relay Issues

Issue: Connection Timeout / Slow Delivery

Cause: Network latency, remote MX throttling, or TLS negotiation failure
Fix:

# Test SMTP connectivity
telnet gmail-smtp-in.l.google.com 25

# Check TLS
openssl s_client -connect gmail-smtp-in.l.google.com:25 -starttls smtp

# Check KumoMTA queue
curl http://localhost:2000/metrics | grep queue_depth

Issue: 421/429 Throttling from Gmail/MS

Cause: ISP is throttling your IP — you’re sending too fast
Fix: Implement adaptive throttling in your relay policy:

kumo.on("smtp_delivery_result", function(result, meta)
    if result.code == 421 or result.code == 429 then
        -- Reduce rate by 30%
        adjust_domain_rate(meta.domain, -0.3)
        log_warn("Throttled by " .. meta.domain .. ", reducing rate")
    end
end)

Issue: TLS Handshake Failures

Cause: Outdated TLS config or untrusted certificate
Fix: Ensure min_tls_version = "1.2" minimum (1.3 preferred). Check certificate expiration:

openssl x509 -in /etc/kumomta/tls/server.crt -noout -dates

FAQ

Q: What’s the difference between SMTP port 25, 465, and 587?
A: Port 25 is the standard MX port (server-to-server delivery). Port 465 (SMTPS) is for legacy submission with implicit TLS. Port 587 (Submission) is the modern standard for application-to-relay submission with explicit STARTTLS. Use 587 for your application relay integration.

Q: Can KumoMTA relay from Postfix?
A: Yes. Configure Postfix to relay to KumoMTA on an internal port:

relayhost = [kumomta.internal]:2525

Q: How do I handle SMTP relay for WordPress/WooCommerce?
A: Install WP Mail SMTP plugin, configure it to point to your KumoMTA relay at kumomta.example.com:587 with AUTH credentials. KumoMTA will DKIM-sign and deliver all WordPress mail.

Q: Is port 25 blocked by cloud providers — what do I do?
A: Most cloud providers (AWS, GCP, Azure) block port 25 by default. Solutions: (1) Use port 587 submission instead, (2) request port 25 unblock from your provider, (3) use a dedicated SMTP relay service for the “last mile” if needed.

Q: How does KumoMTA compare to Postfix for relay use?
A: KumoMTA has superior multi-tenant traffic shaping, built-in DKIM, and Prometheus metrics. Postfix requires external tools (OpenDKIM, policyd) for equivalent functionality. For high-volume relay, KumoMTA is significantly easier to operate.

Get Help With SMTP Relay Setup

PostMTA provides:

  • Production KumoMTA relay configuration and deployment
  • Secure TLS and AUTH setup
  • Multi-tenant relay for SaaS platforms
  • Integration with existing applications (WordPress, Shopify, custom)
  • 24/7 relay monitoring and alerting

👉 Get SMTP relay consulting →

For related guides, see KumoMTA Setup Guide, Email Authentication Guide, and Open Source Email Infrastructure.

References: RFC 5321 (SMTP) | RFC 8460 (SMTP TLS Reporting)

𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝗽𝗿𝗲𝘃𝗲𝗻𝘁 𝗨𝗜 𝗹𝗮𝗴 𝘄𝗵𝗲𝗻 𝗿𝗲𝗰𝗲𝗶𝘃𝗶𝗻𝗴 𝗼𝘃𝗲𝗿 𝟭𝟬𝟬 𝗪𝗲𝗯𝗦𝗼𝗰𝗸𝗲𝘁 𝗲𝘃𝗲𝗻𝘁𝘀 𝗽𝗲𝗿 𝘀𝗲𝗰𝗼𝗻𝗱?

“𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝗽𝗿𝗲𝘃𝗲𝗻𝘁 𝗨𝗜 𝗹𝗮𝗴 𝘄𝗵𝗲𝗻 𝗿𝗲𝗰𝗲𝗶𝘃𝗶𝗻𝗴 𝗼𝘃𝗲𝗿 𝟭𝟬𝟬 𝗪𝗲𝗯𝗦𝗼𝗰𝗸𝗲𝘁 𝗲𝘃𝗲𝗻𝘁𝘀 𝗽𝗲𝗿 𝘀𝗲𝗰𝗼𝗻𝗱?”

They clarified that the issue is not related to the server or backend but rather how to approach and resolve it on the frontend.

This made me think for a while, and then I realized that we often use these techniques—knowingly or unknowingly. We are familiar with these concepts, but they often come with technical jargon.

Let me explain these techniques as simply as possible.

To stop UI lag from 100+ WebSocket events per second, you must decouple the high-frequency message stream from the main rendering thread.
Throttle or buffer the events, batch your DOM updates using requestAnimationFrame, and offload heavy processing to a Web Worker.

Implementing these targeted strategies will stabilize your frame rate:

1. Throttle or Buffer the Event Stream
Never update the UI on every single WebSocket message. At 100+ events per second, your browser is forced into constant layout recalculations (reflows) and repaints.
  • 𝗧𝗵𝗿𝗼𝘁𝘁𝗹𝗶𝗻𝗴: Use libraries like Lodash to limit state updates to a maximum of 10–15 frames per second
  • 𝗕𝘂𝗳𝗳𝗲𝗿𝗶𝗻𝗴: Push incoming events into an array. Set up an interval or a requestAnimationFrame loop that drains this array, processes the aggregated data, and updates the UI once per cycle.

𝟮. 𝗕𝗮𝘁𝗰𝗵 𝗗𝗢𝗠 𝗨𝗽𝗱𝗮𝘁𝗲𝘀
If you are updating UI components individually for every event, you will overwhelm the event loop.
  • Batch multiple data points into a single state update.
  • Use requestAnimationFrame to schedule your DOM updates so they align perfectly with the browser’s refresh rate.

𝟯. 𝗢𝗳𝗳𝗹𝗼𝗮𝗱 𝗛𝗲𝗮𝘃𝘆 𝗣𝗿𝗼𝗰𝗲𝘀𝘀𝗶𝗻𝗴 𝘁𝗼 𝗮 𝗪𝗲𝗯 𝗪𝗼𝗿𝗸𝗲𝗿
  • If you need to parse, filter, or transform the incoming payload data before displaying it, do not do this on the main JavaScript thread.
  • Move your WebSocket connection and data parsing logic into a Web Worker.
  • The worker can handle the 100+ events per second, aggregate or reduce the data, and only send a condensed, render-ready payload back to the main UI thread periodically.

𝟰. 𝗢𝗽𝘁𝗶𝗺𝗶𝘇𝗲 𝗥𝗲𝗮𝗰𝘁𝗶𝘃𝗶𝘁𝘆 𝗮𝗻𝗱 𝗖𝗼𝗺𝗽𝗼𝗻𝗲𝗻𝘁 𝗥𝗲𝗻𝗱𝗲𝗿𝗶𝗻𝗴
If you are using frameworks like React, Vue, or Angular, uncontrolled state updates will trigger massive re-render cascades.
  • 𝗥𝗲𝗮𝗰𝘁: Use useMemo and useCallback to prevent unnecessary component re-renders. Avoid storing rapidly changing WebSocket data directly in component state; instead, use a mutable ref for the raw data and sync to state on a throttled interval.
  • 𝗩𝗶𝗿𝘁𝘂𝗮𝗹𝗶𝘇𝗮𝘁𝗶𝗼𝗻: If rendering these events in a list or table, use windowing libraries (like TanStack Table or Virtuoso) so the DOM only renders the rows currently visible on the screen.

𝟱. 𝗨𝘁𝗶𝗹𝗶𝘇𝗲 𝗗𝗼𝗰𝘂𝗺𝗲𝗻𝘁 𝗙𝗿𝗮𝗴𝗺𝗲𝗻𝘁𝘀
For vanilla JavaScript implementations, avoid appending elements to the DOM in a loop. Instead, create a DocumentFragment, append your newly processed elements to it, and then append the entire fragment to the live DOM in one single operation

WebSockets #ReactJS #Frontend #JavaScript #Performance #SystemDesign #InterviewPrep #EngineeringMindset

How to bypass corporate MDM and AI gateways on Claude Code

Originally published at harshit.cloud on 2026-05-08.

If you’re reading this, there’s roughly an 80% chance your company rolled out an MDM last quarter, your network team wedged Claude API traffic through an AI gateway around the same time, and now Claude Code boots with MCPs you didn’t pick while forwarding your prompts somewhere you haven’t audited. /mcp shows three servers nothing in your repo touches. env | grep ANTHROPIC returns a base URL on a domain you’ve never seen. The experience got worse and nobody asked you.

This post covers both leashes. The MDM one is fixable in 12 lines of zsh. The AI gateway one depends on how deep your network team went.

what’s an MDM, in three sentences

MDM stands for Mobile Device Management. Jamf, Kandji, Intune, Workspace ONE, whichever agent enrolled your laptop on day one. It owns parts of /Library, can write files there as root with the system-immutable flag set, and re-pushes them on a schedule, which is why a plain rm doesn’t survive. For Claude Code, the relevant directory is /Library/Application Support/ClaudeCode/.

the managed-settings situation

The two files doing the work are /Library/Application Support/ClaudeCode/managed-settings.json and /Library/Application Support/ClaudeCode/managed-mcp.json. Claude Code reads them on startup, treats them as the highest-priority settings layer, and merges them over whatever you have in ~/.claude/settings.json. Anything IT puts in there wins: forced MCPs, forced skills, allowed and denied permission lists, and the env block that can set ANTHROPIC_BASE_URL. That last one is how the AI gateway routing gets wired into Claude Code in the first place.

why rm doesn’t work

First instinct fails, and not in a way that’s obvious:

sudo rm "/Library/Application Support/ClaudeCode/managed-settings.json"
# rm: managed-settings.json: Operation not permitted

Root isn’t enough. The MDM agent sets the file’s system-immutable flag with chflags schg after writing it. That flag blocks deletion even by root until it’s cleared. The macOS chflags(1) man page is the receipt. schg is the “system immutable” flag, and the file “may not be changed, moved, or deleted” while it’s set.

Confirm it on your own machine:

ls -lO "/Library/Application Support/ClaudeCode/managed-settings.json"
# -rw-r--r--  1 root  wheel  schg  482 May 14 09:11 managed-settings.json

schg in column five is the marker.

The detail that matters: managed-settings.json is the same config layer your ~/.claude/settings.json uses. The IT copy just lives under /Library, is owned by root, and has the schg flag set. The merge logic doesn’t know which file came from a human.

the cleanup script

One thing worth flagging before you run this. On macOS, the schg flag is normally clearable by root for files outside SIP-protected paths — and /Library/Application Support/ClaudeCode/ is not SIP-protected. So sudo chflags noschg works as written. If your MDM also writes its config into a SIP-protected location (rare for application config, more common for system extensions), you’d need Recovery Mode Terminal to clear those, which is a different conversation. The script’s 2>/dev/null will silently swallow that failure, so if reruns don’t seem to take, that’s where to look.

Save this as /usr/local/sbin/claudecode-cleanup.sh, make it executable, run with sudo:

#!/bin/zsh
FILES=(
  "/Library/Application Support/ClaudeCode/managed-settings.json"
  "/Library/Application Support/ClaudeCode/managed-mcp.json"
)
for f in "${FILES[@]}"; do
  # Clear immutable flag if file exists, then remove
  [ -e "$f" ] && /usr/bin/chflags noschg "$f" 2>/dev/null
  /bin/rm -f "$f"
done
sudo chmod 755 /usr/local/sbin/claudecode-cleanup.sh
sudo /usr/local/sbin/claudecode-cleanup.sh

Two lines do the real work. chflags noschg clears the immutable bit. rm -f removes the file. The 2>/dev/null swallows the noise on a clean machine where the file isn’t there.

Restart Claude Code. /mcp should be back to whatever you actually installed, and /permissions should be whatever’s in ~/.claude/settings.json instead of whatever IT decided you needed.

the launchd arms race

I’d love to tell you this is permanent. It isn’t.

MDM agents sync on a schedule. Every 15 minutes, every hour, on login, depending on profile. When they sync, they notice the file is gone, put it back, and re-apply the schg flag. You’ll watch managed-mcp.json reappear like a horror-movie villain you keep stabbing.

A few options, in increasing order of trouble you’re inviting:

  • Run the script on a launchd LaunchAgent that fires at login. Once per session. Low impact, low effectiveness, but if your MDM only syncs at login this is enough.
  • Run it on a launchd timer with a 60-second interval. Now you’re in an arms race with the sync schedule. Works until someone in IT notices a config-drift alert for your hostname.
  • Block the MDM agent’s outbound DNS. Effective, loud, and the kind of thing that gets your laptop wiped on the next compliance audit.

I run the first one. The MDM gets its login telemetry, my dev environment isn’t broken for the hour or so between syncs, nobody opens a ticket. Pick the option that matches how much you actually want to fight this.

Minimal ~/Library/LaunchAgents/cloud.harshit.claudecode-cleanup.plist:

<?xml version="1.0" encoding="UTF-8"?>
<!DOCTYPE plist PUBLIC "-//Apple//DTD PLIST 1.0//EN" "http://www.apple.com/DTDs/PropertyList-1.0.dtd">
<plist version="1.0">
<dict>
  <key>Label</key><string>cloud.harshit.claudecode-cleanup</string>
  <key>ProgramArguments</key>
  <array>
    <string>/usr/bin/sudo</string>
    <string>-n</string>
    <string>/usr/local/sbin/claudecode-cleanup.sh</string>
  </array>
  <key>RunAtLoad</key><true/>
</dict>
</plist>

sudo -n only works if you’ve added a NOPASSWD line for that exact script in /etc/sudoers.d/claudecode-cleanup. Which the MDM might rewrite. The arms race goes deeper than you think.

the AI gateway angle

The other leash sits at the network layer. Companies route Claude API traffic through a gateway (Cloudflare AI Gateway, Portkey, LiteLLM, internal proxies) so they can log prompts, strip PII, enforce per-user quotas, or quietly downgrade Opus calls to Haiku when the monthly bill spikes. Claude Code respects ANTHROPIC_BASE_URL and will talk to whatever endpoint it points at, as long as your OAuth token or API key authenticates there.

Two routing patterns to recognize:

  • The env block in managed-settings.json. IT sets ANTHROPIC_BASE_URL=https://ai-gw.corp.example.com/v1 inside the env section of the managed file. Claude Code reads it on startup. Same fix as the MCP file. The cleanup script above already kills this.
  • System proxy plus a corporate root CA. Your laptop has a “Corporate Root CA” in keychain, and either an https.proxy setting or transparent network interception routes api.anthropic.com traffic through the gateway. Deleting managed-settings.json does nothing here. The interception lives below the application layer.

To tell which one you have, run this in a fresh shell:

env | grep -i anthropic
# If you see ANTHROPIC_BASE_URL, it's the env block.

curl -v https://api.anthropic.com/v1/messages 2>&1 | grep -iE 'issuer|subject|server certificate'
# If the cert chain is signed by your corporate CA, it's transparent interception.

bypassing the gateway

For the env-block case, the cleanup script already does the work. Restart your shell after running it:

unset ANTHROPIC_BASE_URL
env | grep -i anthropic
# (empty)

For the transparent-proxy case, your options shrink:

  • Personal hotspot for sensitive sessions. Burns mobile data, leaves no trail through the gateway. Most realistic option for an individual contributor.
  • WireGuard or Tailscale out to a personal node. Works if your MDM profile allows it. Many block third-party VPNs through com.apple.systempolicy.kernel-extension-policy.
  • Personal device for personal work. Boring answer. The one that holds up in HR if it ever comes up.

What doesn’t work: removing the corporate root CA from keychain. It’s pinned by an MDM payload and gets re-added on next sync, same pattern as managed-settings.json.

should you actually do this

Worth saying out loud: both leashes exist because someone at your company had a reason. Compliance, data residency, an incident from six months ago whose postmortem nobody can find.

If the forced MCP is internal-secrets-lookup and the gateway logs prompts to a SOC pipeline, your team probably wants you using it. If the MCP is corporate-docs-mcp pointed at a 404 and the gateway downgrades Opus to Haiku because someone misread an invoice, you’re deleting dead weight.

The script doesn’t know which. Ask before you script. Most MDM platforms support per-user opt-out scopes, and one polite Slack message to IT beats a launchd plist.

what these scripts don’t do

The cleanup clears two files. It does not:

  • Stop the MDM agent.
  • Touch ~/.claude/settings.json. Your settings stay yours.
  • Handle /Library/Application Support/ClaudeCode/managed-permissions.json if your MDM uses one. Add it to the FILES array.
  • Survive a reboot or a sync. The agent re-pushes on next check-in.
  • Defeat a transparent proxy with a pinned corporate CA. Use the hotspot.

If you wanted a permanent escape from corporate IT, you wouldn’t be reading a blog about chflags.

Lazy SRE’s guide to secure systems, part 5: the dev laptop is the perimeter

An animated horizontal bar chart in a dark editorial palette comparing the annual endpoint stack cost for a 15-engineer team across three configurations. Top bar: OSS-only (osquery + Wazuh self-hosted) at roughly $240/year (just the VPS). Middle bar (accented, brighter cyan, coral tip): Defender for Business at $540/year, the recommended default. Bottom bar: CrowdStrike Falcon Go at $900/year. A small note underneath each bar shows what each catches and what each misses; a strip at the bottom reads

Originally published at harshit.cloud on 2026-05-03.

In June 2024, Mandiant published the writeup for the Snowflake mass-extortion campaign. Ticketmaster, Santander, AT&T, LendingTree, Advance Auto Parts — roughly 165 Snowflake tenants in total had data extracted from their warehouses. The defining detail wasn’t sophistication. It was the laptop.

Mandiant traced the entry point to infostealer malware (Lumma, RedLine, Vidar variants) running on contractor and developer machines. Their report described the affected devices as personal systems also used for gaming and downloading pirated software. The infostealer harvested every credential the browser had ever saved, including the Snowflake login that didn’t have MFA enforced. The attackers walked through the front door of a Fortune 500’s data warehouse.

This is part 5. Earlier parts covered npm (Part 1), GitHub Actions (Part 2), the unsexy infrastructure list (Part 3), and DNS auth records (Part 4). Part 5 is about the laptop. The piece of hardware on an engineer’s desk that has every SSH key, AWS profile, kubeconfig, GitHub PAT, Slack token, and Stripe key they have ever used to do their job.

The thesis from Part 1 stands. Future You at 3am will not run an EDR scan after every browser extension install. The config that prevents the extension from being installed in the first place is the one that runs while you sleep: the MDM that whitelists, the disk encryption that protects what gets stolen, the hardware MFA that survives the keylogger.

MDM is the table you set first

Mobile Device Management is the thing every small startup skips and every enterprise has. The bad-faith reason is that it’s expensive and annoying. The honest reason in 2026 is that the free options have caught up.

For a 15-person Apple-heavy team, the lazy stack is Apple Business Manager (free, Apple-only) plus Fleet (OSS, free under 300 endpoints on the self-hosted path, generous free tier on Fleet’s cloud). Apple Business Manager assigns a Mac to your organization at first boot, before the user creates a personal Apple ID on it. Fleet runs the osquery agent on every machine and lets you push configuration profiles (the same plist payloads Jamf would push) plus query inventory in SQL syntax.

The lazy default config profile, in plain English:

  • Require FileVault. Escrow the recovery key to MDM. If the laptop walks, the disk is encrypted; if the user forgets the password, you can recover.
  • Require auto-lock at five minutes idle, password to wake. Not a screensaver.
  • Block unsigned package installs, restrict the Mac App Store to managed Apple IDs only.
  • Require macOS updates within fourteen days of release. The fourteen days lets you skip a known-bad point release; longer than fourteen is negligence.
  • Block AirDrop on the corporate Wi-Fi, restrict USB external storage to read-only (or block entirely if your workflow doesn’t need it).
  • Install osquery via MDM, enrolled to your Fleet server.

For Linux and Windows in the mix, Fleet covers both with the same osquery agent and the same query syntax. The MDM-config-profile half is Windows Intune (free with Microsoft 365 Business Premium) or Workspace ONE’s free tier. Either way, the stack is “Fleet for inventory and detections + a platform-specific MDM for enforcement.”

The lazy fix for the most common gap: a weekly cron that runs one Fleet query, “every laptop without FileVault enabled,” and posts a Slack alert with the user’s name. The conversation that follows is “we found your machine, can you enable it today” — not a six-month audit.

hardware keys, one-time spend

YubiKey 5 NFC is $50. Buy two per engineer: one for the desk, one for the bag. Total for 15 engineers: $1,500, one-time, capital expense, deductible.

What it gets you:

  • WebAuthn / FIDO2 for SSO login (Google, Okta, GitHub, Cloudflare, AWS): a keylogger can record every keystroke and still never get the second factor.
  • SSH key storage in hardware. ssh-keygen -t ed25519-sk -O resident writes the key into the YubiKey. The private key never exists on disk.
  • PIV smartcard for VPN auth, code signing (gpg --card-edit).
  • TOTP fallback for the SaaS that hasn’t shipped WebAuthn yet.

The free alternative for the SaaS that doesn’t support hardware keys is passkeys. Passkeys are WebAuthn under the hood, also phishing-resistant, built into iOS, macOS, Android, Windows Hello, Chrome, and Safari. Free. The catch is sync: if the engineer’s iCloud is compromised, so is the passkey. Hardware keys aren’t synced; they are a physical token. The lazy answer is both: passkeys for low-risk auth, YubiKeys for the keys that gate production.

Cost: $1,500 one-time for 15 engineers. The cheapest line item in this post for what it gets you.

EDR is where the budget goes

Endpoint Detection and Response is the part of this stack that costs real money. For OSS-only, the answer is osquery + Wazuh, which works but requires writing detections by hand. For a 15-person team with one platform engineer, “write your own EDR detections” is not a project anyone will finish.

The honest 2026 small-team answer is Microsoft Defender for Business at $3/user/month. It ships in Microsoft 365 Business Premium (also useful if you’re on M365 anyway), has acceptable macOS coverage, and includes managed detections written by Microsoft’s security team. Cost for 15 engineers: $540/year. CrowdStrike Falcon Go is $60/endpoint/year if you want best-in-class detection at small-team scale; same math, $900/year for 15.

An animated horizontal bar chart in a dark editorial palette comparing the annual endpoint stack cost for a 15-engineer team across three configurations. Top bar: OSS-only (osquery + Wazuh self-hosted) at roughly $240/year (just the VPS). Middle bar (accented, brighter cyan, coral tip): Defender for Business at $540/year, the recommended default. Bottom bar: CrowdStrike Falcon Go at $900/year. A small note underneath each bar shows what each catches and what each misses; a strip at the bottom reads 'one-time YubiKey spend not included ($1,500 for 15 engineers across all three).'

Fig. 2 — three configurations. Pick the middle bar unless you have a reason.

The lazy stance: Defender for Business if you’re on Microsoft 365 already. Falcon Go if you’re not on M365 and want managed detection without the OSS-engineer overhead. osquery + Wazuh only if you have a security engineer with bandwidth to maintain the detections, which most 15-person startups don’t. Pretending otherwise is how you end up with a fancy SIEM nobody reads.

the password manager and browser hygiene argument

1Password Business at ~$8/user/month. Bitwarden Teams at $4. Apple Passwords (or 1Password Families) if you’re Mac-only and don’t need shared vaults. Pick one and stop arguing about it on the team’s #tools channel.

The point of the password manager isn’t strong passwords. The point is:

  • One place for credentials, audited.
  • Shared vaults for vendor logins, instead of “share the password in Slack DM” hygiene.
  • Breach notifications when a saved password appears in a public breach corpus.
  • Masked email aliases (1Password feature, Apple’s Hide My Email equivalent): every signup gets a separate alias, every spam list is contained.

Browser hygiene matters because the Snowflake infostealer harvested credentials from browser local storage. Specifically:

  • Enforce browser auto-updates via MDM. Both Chrome and Edge expose policy keys for this; Firefox via policies.json.
  • Block sync of work browser profiles to personal Google/Apple accounts. The “I signed into Chrome with my personal account and now all my work bookmarks are in someone else’s cloud” leak is real.
  • Block “developer mode” extension installs. Force extensions to come from the Chrome Web Store; force the Web Store to honor the org’s allowlist via the ExtensionInstallAllowlist policy.
  • Disable browser password saving entirely. Everything routes through the password manager.

Total: $1,440/year for 15 engineers on 1Password Business. $720 on Bitwarden Teams. $0 on Apple Passwords if it covers your needs. Pick a line and walk it.

the personal device problem

The Snowflake breach was about contractors using personal Macs for work. The lazy answer at a 15-person startup might surprise: corp-issue every contractor a laptop. Yes, including the four-hour-a-week consultant.

A refurbished MacBook Air with 16GB RAM is roughly $700 from Apple’s Certified Refurbished store. The cost of a Snowflake-scale breach starts at $370K (the reported AT&T ransom) and ends in the customer-churn and legal-exposure column. The break-even point on hardware-for-contractors is under three serious incidents, ever.

An editorial side-by-side system diagram on a dark navy ground. Left panel labeled 'personal device, BYOD' shows a laptop with chaotic state: unenforced FileVault status, a personal iCloud sign-in, a Mac App Store with personal Apple ID, a Chrome browser synced to a personal Google account, a Slack web app session that's been logged in for nine months, a folder labeled 'pirated software' with a red warning. Right panel labeled 'corp-issued, MDM enrolled' shows the same laptop with each item enforced: FileVault ON, MDM-managed Apple ID, App Store restricted, Chrome work profile only, Slack session expires daily, no third-party software installs. Each enforced item has a green check; each unenforced item on the left has a coral X. A title above reads 'where the Snowflake breach lived'.

Fig. 3 — same laptop, different enrollment. The right panel is the one where Mandiant doesn’t write your name down.

What “no work on personal devices” actually requires:

  • Contract clause: hardware is issued, personal-device use for work is prohibited.
  • MDM enrollment at first boot via Apple Business Manager (or Windows Autopilot).
  • Disabled iCloud personal sign-in; only managed Apple IDs.
  • Wipe via MDM on offboarding, before reissue.
  • No “I can just SSH from home for ten minutes” escape hatch. The escape hatch is what the contractor will use the day they get phished.

This is the section of the post that gets the most pushback. The pushback is right about cost and wrong about risk. Run the math at your scale; it runs the same direction every time.

the receipts

For 15 engineers, the first-year laptop security budget:

  • YubiKey 5 × 30 keys (two per engineer): $1,500, one-time.
  • Fleet (OSS self-hosted on a small VPS): $240/year.
  • Microsoft Defender for Business: $540/year. Substitute Falcon Go at $900 if not on M365, or osquery+Wazuh at $0 if you have a security engineer.
  • 1Password Business: $1,440/year. Or Bitwarden Teams at $720. Or Apple Passwords at $0.
  • Refurbished corp laptops for non-employee contractors: ~$700 per, as needed.

Total recurring: roughly $1,020–$2,220/year for 15 engineers, depending on the EDR and password-manager line. Add the one-time YubiKey spend and the first year lands at $2,520–$3,720. Call it $14–$21 per engineer per month.

What it catches: every infostealer that hits a managed laptop (Defender flags it), every credential that lives in the browser (replaced by the password manager), every login that doesn’t have phishing-resistant MFA (the YubiKey is required), every personal device touching production (blocked by the no-BYOD policy).

What it doesn’t catch: a determined adversary with physical access and unlimited time. A laptop in a hotel room with no FileVault is owned. A laptop with FileVault and a YubiKey left in the USB-A port overnight is owned slower. Neither situation is what this stack is built for; it is built for the infostealer that landed on the contractor’s personal Mac.

If you do one thing this week, buy two YubiKeys for yourself, enroll them on GitHub, Google, and Okta, and turn off SMS-based MFA on each. Total cost: $100, one hour. Then do the rest of the team next quarter.