This is a submission for the Gemma 4 Challenge: Build with Gemma 4
Table of Contents
- What We Built
- Demo
- Code
- How We Used Gemma 4
- The Genie Team
What We Built
Most AI assistants are text boxes with a microphone icon. You speak. Your words leave your device. A server somewhere thinks. A server responds. If you’re on a plane, in a rural clinic, or behind a firewall — nothing works.
We built the opposite.
Genie is an autonomous AI agent that runs Gemma 4 directly on your Android GPU through Google’s LiteRT-LM SDK. It doesn’t call an API. It doesn’t stream to a cloud. It sees your screen, controls your apps, reads your documents, remembers your preferences, teaches you concepts on a whiteboard, and executes multi-step tasks — all on-device, all offline.
The Problem: Running an LLM Is Easy. Letting It Touch Your OS Is Not.
Google gave us a great on-device inference SDK. Loading a Gemma model, creating a conversation, streaming tokens — that’s a few method calls. The hard part is everything around it.
When your agent can tap buttons, type into fields, and open apps autonomously, you have a fundamentally different safety problem than a chatbot. A chatbot that hallucinates gives you wrong text. An agent that hallucinates taps “Confirm Payment” on your PayPal screen.
That constraint shaped every architectural decision in Genie.
System Architecture Overview
Here’s the full system at a glance:
Wake Word (Vosk) → STT (Android) → AgentOrchestrator
    ↓
PromptBuilder → Planner → GenieEngine (LiteRT-LM / Gemma 4)
    ↓
Decision.Act → RiskAssessor → [Biometric HITL?] → ToolRegistry → OS Action
    ↓
ToolOutcome → History → SlidingWindow → Next Planning Turn
    ↓
Decision.Finish → Skill Cache Write → TTS Response → Resume Wake Word
Layer 1: The Voice Pipeline — Two Engines, One Microphone
Most voice assistants use a single speech engine. We use two, and the reason is physics.
Vosk is a lightweight, offline speech recognition library. We run it continuously in the background at 16kHz, listening for exactly one word: “Gemma”. It uses ~30MB RAM and has near-zero latency for wake-word detection.
Android SpeechRecognizer is heavier but far more accurate for full sentences. It only activates after Vosk detects the wake word.
// Vosk wake-word detection
override fun onPartialResult(hypothesis: String?) {
    val json = JSONObject(hypothesis)
    val partial = json.optString("partial", "")
    if (partial.lowercase().contains("gemma")) {
        speechService?.stop()           // Kill Vosk
        setUiState(AgentUIState.Waking)  // Show overlay
        startSttListening()              // Start full STT
    }
}

// STT captures the actual command
override fun onResults(results: Bundle?) {
    val text = results?.getStringArrayList(
        SpeechRecognizer.RESULTS_RECOGNITION
    )?.getOrNull(0) ?: ""
    dispatchToAgent(text)  // → AgentOrchestrator
}
Why not just use SpeechRecognizer for everything? Because it’s expensive. Running full-sentence recognition 24/7 drains battery and hogs the microphone. Vosk is purpose-built for always-on keyword spotting with minimal resource usage.
Layer 2: Intercepted Execution (The Inference Bridge)
The GenieEngine wraps Google’s LiteRT-LM SDK. The most important design decision lives in one line:
val newConversation = engine.createConversation(
    ConversationConfig(
        samplerConfig = agentSamplerConfig(),
        systemInstruction = PromptFormatting.buildSystemInstruction(systemPrompt),
        tools = tools,
        automaticToolCalling = false,  // ← This is everything
    )
)
Why automaticToolCalling = false?
In default mode, LiteRT-LM detects a tool call in the model’s output, executes it automatically, and feeds the result back — all without the application knowing. That’s fine for a chatbot generating weather data.
It’s catastrophic for an agent that can tap “Send $500” on your banking app.
By disabling automatic tool calling, every single tool call from the model passes through our code first. We intercept it. We validate it. We optionally require biometric authentication. Only then do we execute.
The Callback-to-Flow Bridge
LiteRT-LM uses a callback-based API (MessageCallback). We convert that into a Kotlin callbackFlow so the agent loop can consume responses asynchronously:
fun sendMessageAsync(contents: Contents): Flow<AgentResponse> = callbackFlow {
    conversation.sendMessageAsync(
        contents,
        object : MessageCallback {
            override fun onMessage(message: Message) {
                if (message.toolCalls.isNotEmpty()) {
                    trySend(AgentResponse.ToolCallRequest(message))
                } else {
                    trySend(AgentResponse.Token(message.toString()))
                }
            }
            override fun onDone() {
                trySend(AgentResponse.Done)
                close()
            }
            override fun onError(throwable: Throwable) {
                val error = if (throwable is CancellationException) {
                    ErrorTaxonomy.TransientErr("Inference cancelled", throwable)
                } else {
                    ErrorTaxonomy.FatalErr("Inference error: ${throwable.message}", throwable)
                }
                trySend(AgentResponse.Error(error))
                close()
            }
        }
    )
    awaitClose { }
}
Layer 3: The Agent Loop — Planning Like a Human
Here’s where Genie diverges from every other “AI assistant.” When you say “Open WhatsApp and send hi to Mom”, a chatbot tries to answer in one shot. Genie plans.
The AgentOrchestrator runs a loop that mirrors human problem-solving:
-
Observe — Read the screen
-
Plan — Decide the next action
-
Act — Execute one tool
-
Evaluate — Check the result
-
Repeat — Until the goal is done or a circuit breaker trips
The State Machine
data class AgentState(
    val goal: String,
    var intent: AgentIntent? = null,
    var plan: AgentPlan? = null,
    var currentStepIndex: Int = 0,
    val history: MutableList<HistoryEntry> = mutableListOf(),
    var retryCount: Int = 0,
    var replanCount: Int = 0,
    val maxRetries: Int = 3,
    val maxReplans: Int = 3,
    var isNovelPlan: Boolean = true,
)
Every tool call, every result, every error — all tracked in history. This history feeds back into the next planning prompt so the model always knows what it has already tried.
The Decision Type System
The planner produces exactly one of three decisions per turn:
sealed class Decision {
    data class Act(val tool: String, val args: Map<String, String>) : Decision()
    data class Finish(val summary: String) : Decision()
    data class Reply(val message: String) : Decision()
}
-
Act → Execute a tool and continue the loop
-
Reply → Speak to the user and stop
-
Finish → Mark the goal complete
Plain text during planning is treated as invalid. The system prompt forces exactly one native tool call per turn:
“Call EXACTLY ONE tool per turn. No markdown, no extra text.”
The Sliding Window
The model has a limited context window. The SlidingWindowManager ensures the model always sees what matters:
- Keeps the first entry (the user’s goal — always visible)
- Keeps the last 9 entries (recent actions and results)
-
Prunes transient errors after a success — if
click("Wi-Fi") failed twice then succeeded, those two failures are removed from history
fun pruneAfterSuccess(history: MutableList<HistoryEntry>) {
    val lastEntry = history.lastOrNull() as? HistoryEntry.ToolResult ?: return
    if (lastEntry.outcome !is ToolOutcome.Ok) return

    val successToolName = lastEntry.toolName
    var index = history.size - 2
    while (index >= 0) {
        val entry = history[index]
        if (entry is HistoryEntry.ToolResult &&
            entry.toolName == successToolName &&
            entry.outcome is ToolOutcome.TransientErr) {
            history.removeAt(index)
        } else {
            break
        }
        index--
    }
}
Layer 4: The Safety Net — Dynamic Risk Assessment + Biometric HITL
Most AI safety systems use static per-tool flags: “this tool is dangerous, always ask for confirmation.” That’s crude. Opening Settings is safe. Opening PayPal and clicking “Send” is not — but both use the same click tool.
Genie’s RiskAssessor is dynamic. It evaluates the current screen context in real time:
object RiskAssessor {
    private val DESTRUCTIVE_VERBS = setOf(
        "send", "transfer", "pay", "confirm", "submit",
        "delete", "remove", "purchase", "authorize",
    )

    private val CURRENCY_REGEX = Regex(
        """[$€£¥₦₹₩₿]s*d+|d+.d{2}s*(USD|EUR|GBP|NGN)""",
        RegexOption.IGNORE_CASE,
    )

    fun assess(
        toolName: String,
        args: Map<String, String>,
        screen: ScreenContext
    ): RiskVerdict {
        if (toolName !in setOf("click", "tap_at", "type_text")) {
            return RiskVerdict.Allow
        }

        val signals = mutableListOf<RiskSignal>()

        if (isFinancialScreen(screen)) signals.add(FINANCIAL_SCREEN)
        if (isSensitiveApp(screen))    signals.add(SENSITIVE_APP)
        if (isDestructiveVerb(target)) signals.add(DESTRUCTIVE_VERB)
        if (isSensitiveField(screen))  signals.add(SENSITIVE_FIELD)
        if (isAuthFlow(screen))        signals.add(AUTH_FLOW)

        return if (signals.size >= 2) {
            RiskVerdict.RequireBiometric(reason)
        } else {
            RiskVerdict.Allow
        }
    }
}
The key insight: ≥2 independent signals required. A single signal (e.g., seeing a dollar sign) doesn’t trigger auth — that would cause false positives everywhere. But a currency symbol plus the word “Send” as a click target? That’s a real financial action. Biometric required.
The Biometric Bridge
When auth is required, HITLInterceptionWrapper launches a transparent activity that shows Android’s BiometricPrompt:
object HITLInterceptionWrapper {
    val authResultChannel = Channel<AuthResult>(capacity = 1)

    suspend fun executeWithAuth(
        tool: GenieTool,
        args: Map<String, String>,
        serviceContext: ToolServiceContext,
        appContext: Context,
        reason: String,
    ): ToolOutcome {
        appContext.startActivity(
            Intent(appContext, BiometricAuthActivity::class.java)
        )

        val result = withTimeoutOrNull(30_000L) {
            authResultChannel.receive()
        }

        return when (result) {
            is AuthResult.Approved -> tool.execute(args, serviceContext)
            is AuthResult.Denied  -> ToolOutcome.AuthErr("User denied")
            else                  -> ToolOutcome.AuthErr("Auth timed out")
        }
    }
}
The BiometricAuthActivity is invisible (Theme.Translucent.NoTitleBar), excluded from recents, and immediately finishes after sending the result.
Layer 5: Error Taxonomy — Four Tiers of Failure
Not all errors are equal. Genie classifies every failure into one of four tiers, each with its own recovery strategy:
sealed class ToolOutcome {
    data class Ok(val result: String) : ToolOutcome()
    data class TransientErr(val message: String) : ToolOutcome()
    data class LogicErr(val message: String) : ToolOutcome()
    data class AuthErr(val message: String) : ToolOutcome()
    data class FatalErr(val message: String) : ToolOutcome()
}
| Tier |
Meaning |
Recovery |
Example |
TransientErr |
Might work if we wait |
Retry with exponential backoff |
UI hasn’t rendered yet |
LogicErr |
Agent made a bad choice |
Error goes into history; model self-corrects |
Wrong tool name |
AuthErr |
User denied authorization |
Hard stop with notification |
Biometric denied |
FatalErr |
Unrecoverable |
Hard stop immediately |
OOM, engine crash |
Circuit Breakers
Two circuit breakers prevent infinite loops:
-
Consecutive failure breaker: 5 consecutive failures of any kind → abort
-
Unknown tool breaker: Same non-existent tool requested 3 times → abort
if (consecutiveFailureCount >= 5) {
    Log.e(TAG, "Circuit breaker triggered")
    return "I ran into repeated errors. Please try again."
}
Layer 6: Self-Improvement — The Skill Cache
Every time Genie completes a novel task, it serializes the successful plan and stores it in a local Room database:
@Entity(tableName = "skills")
data class Skill(
    @PrimaryKey(autoGenerate = true) val id: Int = 0,
    val goalPattern: String,
    val planJson: String,
    val successCount: Int = 0,
    val createdAt: Long = System.currentTimeMillis(),
)
Next time you ask for something similar:
val skills = skillDao.findMatchingSkills("turn on wi-fi")
val bestSkill = skills.maxByOrNull { it.successCount }
If a match is found, Genie replays the cached plan step-by-step without invoking the LLM. No inference needed. Instant execution.
Every successful replay increments successCount. Over time, more reliable skills are prioritized. If a cached plan fails (e.g., UI drift from an app update), the agent falls back to live planning.
Layer 7: The Hands — 53 Tools Across 6 Families
Tools don’t touch the AccessibilityService directly. They go through the ToolServiceContext interface — a seam that lets us mock every OS action in tests:
interface ToolServiceContext {
    suspend fun clickElement(target: String): Boolean
    suspend fun typeText(text: String): Boolean
    suspend fun swipe(direction: String): Boolean
    suspend fun readScreen(): String
    suspend fun openApp(name: String): Boolean
    // ... 48 more
}
Tool Families
| Family |
Tools |
Purpose |
| Core OS |
click, type_text, swipe, scroll, open_app, go_back, go_home
|
Direct UI interaction |
| Awareness |
read_screen, read_screen_summary, where_am_i, read_notifications
|
Situational awareness |
| Memory |
save_fact, retrieve_fact
|
Persistent preference storage |
| Document |
list_device_pdfs, detect_open_pdf
|
File access and PDF extraction |
| Teaching |
board_teach_step, visualize_concept
|
Interactive whiteboard |
| Health |
health_search_topics, health_get_topic
|
WHO fact-sheet queries |
The Gesture System
Every gesture is a suspend function wrapping dispatchGesture() into a coroutine:
private suspend fun dispatchGesture(
    gesture: GestureDescription
): Boolean {
    return suspendCancellableCoroutine { continuation ->
        service.dispatchGesture(
            gesture,
            object : GestureResultCallback() {
                override fun onCompleted(desc: GestureDescription) {
                    if (continuation.isActive) continuation.resume(true)
                }
                override fun onCancelled(desc: GestureDescription) {
                    if (continuation.isActive) continuation.resume(false)
                }
            },
            null
        )
    }
}
The Profile System — 9 Modes, One Agent
Not every task needs full autonomous planning. Genie has 9 specialized profiles:
| Profile |
Architecture |
Use Case |
| Chat |
Agent-driven |
General Q&A, remembering facts |
| AppControl |
Agent-driven, reactive |
Navigating WhatsApp, Settings, Spotify |
| Vision |
Agent-driven, multimodal |
Screen analysis with allergy cross-referencing |
| Reader |
Agent-driven |
Accessibility screen narration |
| Teaching |
Agent-driven, whiteboard |
Step-by-step concept lessons |
| SeeAndTap |
Agent-driven, visual grounding |
Screenshot → numbered elements → tap by ID |
| Document |
Hybrid |
PDF quiz and summary generation |
| Scribe |
UI-driven (no agent) |
Audio → transcription → SOAP notes |
| Health |
UI-driven (no agent) |
Food analysis, WHO health topics |
The key insight: not every feature needs agent autonomy. Scribe and Health have fixed, deterministic workflows. Adding an agent layer would only introduce latency and hallucination risk. Those profiles bypass the orchestrator entirely.
enum class ToolProfile(
    val id: String,
    val toolNames: Set<String>,
) {
    Chat(toolNames = setOf("reply", "save_fact", ...)),
    AppControl(toolNames = setOf("reply", "open_app", "click", ...)),
    Scribe(toolNames = emptySet()),  // UI-driven
    Health(toolNames = emptySet()),  // UI-driven
}
Memory System — Facts and Preferences
When a user says “Remember that I’m allergic to peanuts”, the agent calls save_fact(key="allergy", value="peanuts"). This is stored in Room:
@Entity(tableName = "user_facts")
data class UserFact(
    @PrimaryKey(autoGenerate = true) val id: Int = 0,
    val key: String,
    val value: String,
    val createdAt: Long = System.currentTimeMillis(),
    val updatedAt: Long = System.currentTimeMillis(),
)
Every fact is injected into every prompt:
## User Preferences
- allergy: peanuts
- favorite_restaurant: Mama Cass
- preferred_language: Yoruba
The Teaching Profile — An AI Tutor With a Whiteboard
Most AI tutors dump a wall of text. Genie teaches visually.
When you say “Teach me about photosynthesis”, the agent:
- Creates a teaching board scene
- Places a title card
- Adds content cards with real definitions, formulas, and examples
- Generates
visualize_concept diagrams (flowcharts, timelines, mind maps)
- Narrates each step with synchronized text-to-speech
Each step is one tool call. The user controls pacing — say “next” and the agent adds the next concept. The agent never ends the lesson on its own.
Observability — The Event Logger
Every significant event flows through an async event bus:
📦 Bootstrap: engine_init [3421ms]
⚡ State: idle → planning
🧠 Inference: 847ms, 156 tokens
✅ Tool: open_app({name=Settings}) [234ms]
✅ Tool: click({target=Wi-Fi}) [143ms]
⚡ State: executing → finished
📚 Skill written: 'turn on wi-fi' (3 steps)
Events are emitted with trySend() — non-blocking, never delays the agent loop. A dedicated coroutine consumes the Channel<GenieEvent> and writes to Logcat.
What We Learned
-
automaticToolCalling = false is non-negotiable for agents. If your model can touch the OS, you must intercept every tool call. No shortcut.
-
Two-signal risk thresholds prevent false positives. A single “Send” button doesn’t mean danger. “Send” on a financial screen does.
-
Not every feature needs agent autonomy. Fixed workflows are faster, more reliable, and more predictable with direct UI control.
-
Error history is a feature, not a log. Feeding errors back into the planning prompt lets the model self-correct. Pruning resolved errors keeps context clean.
-
Skill caching is the simplest form of self-improvement. No fine-tuning, no RLHF. Serialize what worked. Replay it next time.
Project Statistics
-
53 registered tools across 6 families
-
9 specialized profiles
-
4-tier error taxonomy with 2 circuit breakers
-
5-signal real-time risk assessor with biometric HITL
-
Room-backed skill cache with success-count ranking
-
0 cloud dependencies
-
0 API keys
Demo
Watch Genie navigate Android, read files, control tools, and manage biometric security locks:
📲 Try it yourself: Download the APK from Google Drive
Code
The complete source code is fully open-source and modularized for Android:
🔗 GitHub Repository: github.com/Akeem1955/Genie
How We Used Gemma 4
Genie is entirely powered by local inference using the following models from Google’sallowlist:
-
litert-community/gemma-4-E2B-it-litert-lm (Effective 2-Bit Quantized) – 2.4 GB file size, 32K context window.
-
litert-community/gemma-4-E4B-it-litert-lm (Effective 4-Bit Quantized) – 3.4 GB file size, 32K context window.
Why Gemma 4 was the right fit:
-
Resource Constrained Optimization: Running a large language model on consumer mobile devices demands aggressive resource control. Gemma 4 E2B is optimized to run at high speed (token generation rate) directly on the mobile GPU using the LiteRT-LM engine. It operates comfortably inside the Android service layer without causing system Out-Of-Memory (OOM) faults.
-
Structured Tool Calls: Even with 2-bit quantization, Gemma 4 is highly capable of generating structured tool calls matching our schema without outputting garbage markdown text.
-
Multimodal Capability: By supporting both audio and image inputs natively, Gemma 4 enables our
Vision and Reader profiles to read screenshots and look up saved allergen data, making on-device safety checks fast.
-
Large Context Window: The 32K context window is crucial because we feed user settings, memory history, layout hierarchies, and tool definitions into the prompt. Gemma 4 holds all of this context on-device without collapsing.
The Genie Team


 ChatGPT’yi geliştiren OpenAI’ın kurucu ortağı Andrej Karpathy, bugün yaptığı resmi açıklama ile Claude’u geliştiren Anthropic’e katıldığını duyurdu. Daha önce Tesla’nın yapay zeka bölümünü de yöneten tecrübeli isim, OpenAI’ın en büyük rakibi olan Anthropic’te yeni nesil “öncü” yapay zeka modelleri üzerinde çalışmalar yapacak.
 Diablo IV: Lord of Hatred, serinin ikinci büyük genişlemesi olarak Nisan 2026’da piyasaya sürüldü ve oyunu kökten değiştiren yeniliklerle dikkat çekiyor. Bu inceleme, teknik detaylardan çok bir oyuncu olarak yaşadığımız deneyime odaklanıyor. Yani ”neler var?” sorusundan ziyade ”nasıl hissettiriyor?” sorusunun cevabı burada. Diablo serisi genelde büyük boss savaşları, yüksek tempolu aksiyon ve net bir iyi-kötü çatışması üzerine kurulu. Lord of Hatred bu formülü tamamen değiştirmiyor ama önemli bir kırılma yaratıyor.
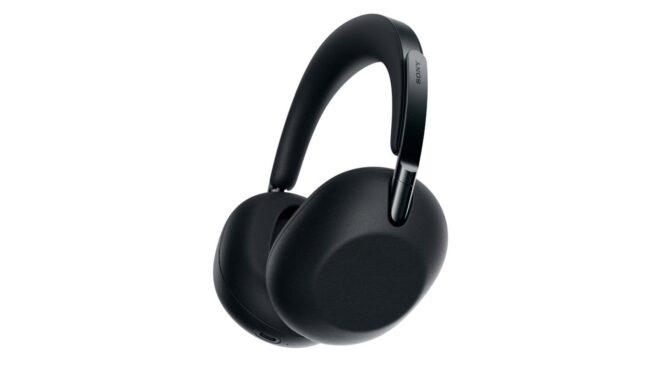
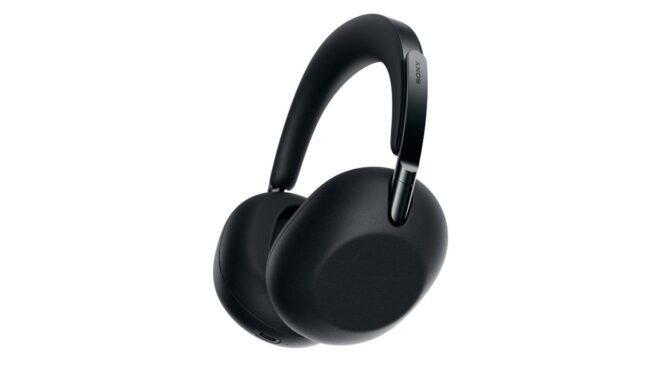 Sony’nin “1000X” kulaklık serisinin 10. yıl dönümüne özel olarak hazırlanan Sony 1000X The ColleXion, bugün resmen görücüye çıkarıldı. Avrupa’da 629 euro fiyatla satılacağı açıklanan (kıyaslamak adına temel alınan WH-1000XM6’nın Avrupa fiyatı 429 euro seviyesinde) üst seviye model, pazara beyaz ve siyah olmak üzere iki farklı renk seçeneğiyle çıkarılıyor. Metal gövde parçalarının kullanıldığı 320 gramlık “The ColleXion”, Sony’nin QN3 ile V3 çiplerini taşıyor, etkili ANC (Aktif Gürültü Engelleme) için 12 farklı mikrofonla geliyor, bu mikrofonlar aracılığıyla yüksek kalitede telefon görüşmeleri sunuyor ve ANC ile 24 saat, ANC olmadan 32 saatlik batarya ömrü sağlıyor. 5 dakikalık şarjla 1,5 saat müzik çalabilen kulaklık, kayıpsız ses deneyimi için 1,5 metrelik kablo ve özel bir taşıma kılıfı/çantasıyla geliyor. Battery Studios ve Sterling Sound & Coast Mastering desteğiyle ayarlanan 30 mm karbon fiber sürücülerin kullanıldığı ürün, Sony’nin açıklamasına göre “DSEE Ultimate” özelliğine sahip ilk kulaklık olarak öne çıkıyor. Bu teknoloji, sıkıştırılmış dijital müzik dosyalarını yapay zekadan […]
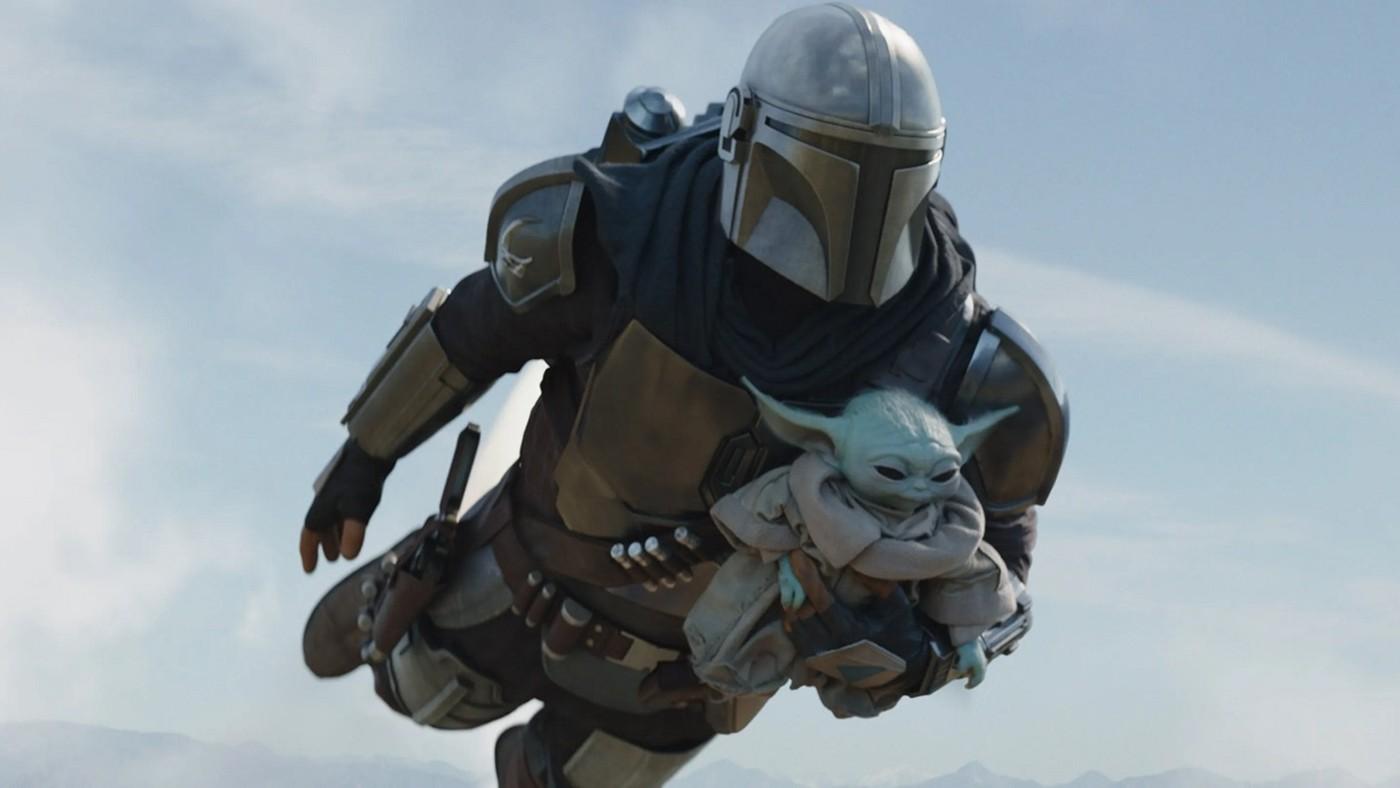
 Bu hafta izleyici ile buluşacak olan Star Wars filmi The Mandalorian and Grogu, hayranları bir kez daha hayal kırıklığına uğratabilir. Bugün belli olan eleştirmen puanları endişe verici.
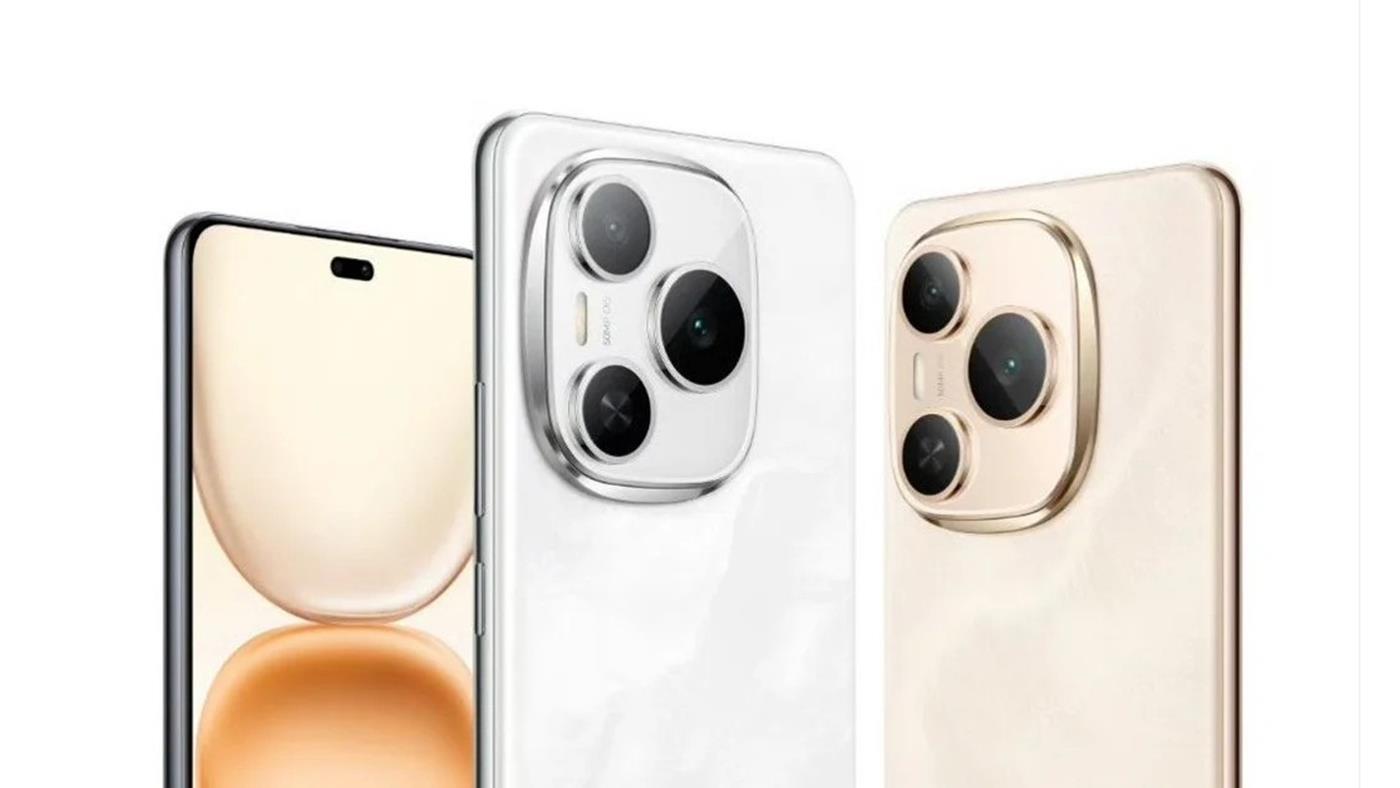
 Honor, devasa bataryalı yeni bir akıllı telefonu üzerinde çalışıyor. Şirket, gelecek yıl tanıtılması beklenen Honor Power 3 modeliyle pil kapasitesini bir kez daha üst seviyeye taşımayı hedefliyor.