Google, YouTube’un Yeni Yapay Zekâ Özelliği “Ask YouTube”u Tanıttı
Google, Google I/O 2026’da yeni yapay zekâ özelliği “Ask YouTube”u tanıttı.

 Mert
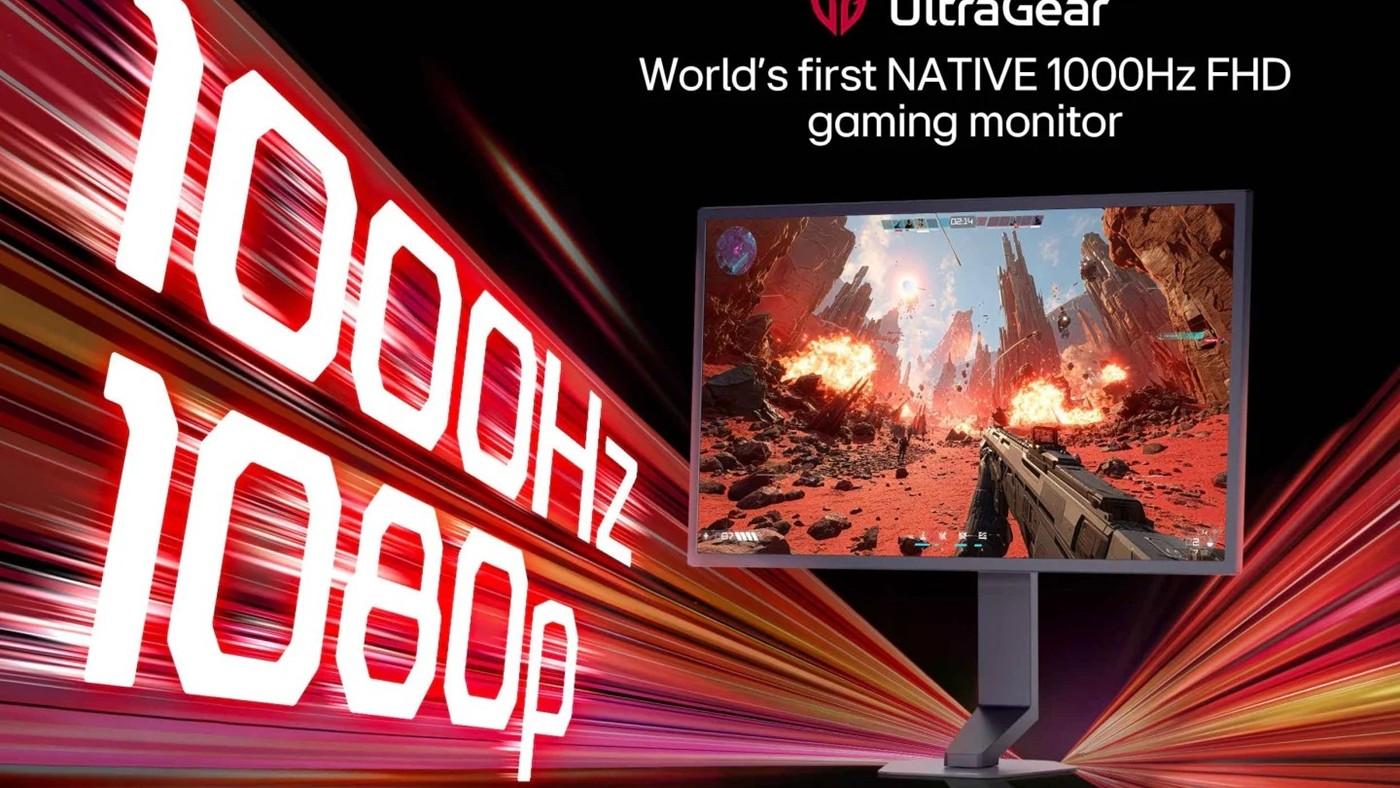
 LG, oyuncuları hedefleyen UltraGear 25G590B isimli monitörünü duyurdu. Şirket, bu modelin dünyada 1080p çözünürlükte 1000Hz doğal yenileme hızına ulaşabilen ilk monitör olduğunu belirtiyor.
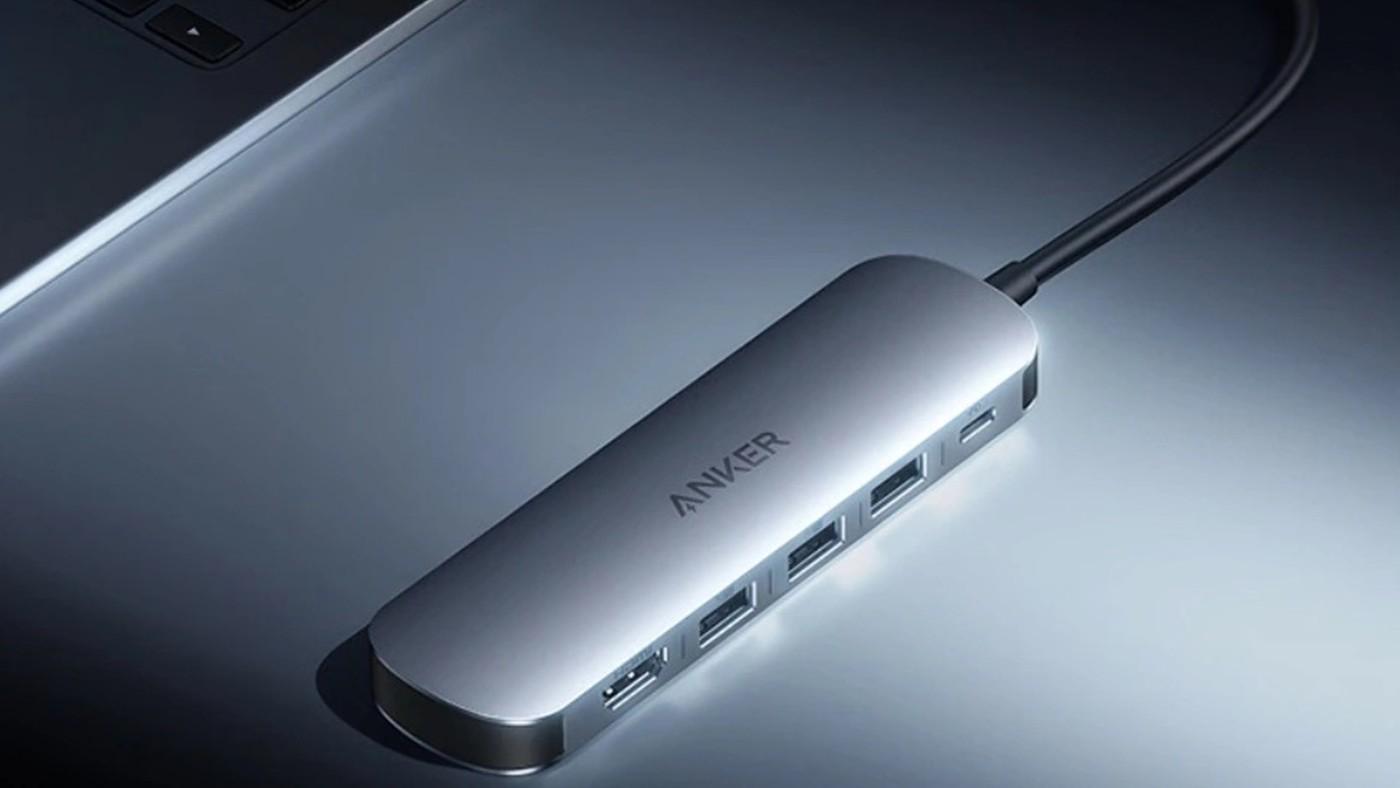
 Anker 5-in-1 All-in-One USB-C Expansion Dock çoklayıcı ürünü bütçesi kısıtlı olanlar için en gerekli olan portları entegre ederek ideal bir alternatif olmayı amaçlıyor.
TL;DR
- The model matters, but tools matter at least as much. Weak tool descriptions are one of the easiest agent failures to diagnose, and one of the most common.
- Design the tools before the agent. If you cannot answer “what can this agent do that a general LLM cannot on its own?”, you do not have an agent yet.
- Ship a small, focused loop with 2-3 well-described tools and a hard iteration cap. Watch traces. Iterate.
In Part 1 I laid out the four levels of AI agents I keep seeing in production, and argued that most shipped “AI agents” are stuck on the lower rungs. This post is about how to build one that is not.
One assumption underneath everything below:
Tools are the center of an agent. Not the system prompt.
Most tutorials start with “let’s write the system prompt.” Wrong starting point. Start with tools.
Start With Tool Design
A weak tool description looks like this:
search_documents:
  description: "Search documents."
The model has no idea when to use it, what to put in query, or what the output means. So it guesses. Badly.
A good description looks closer to this:
search_documents:
  description: "|"
    Use this tool when the user's question requires evidence from
    internal documents, policies, or technical references.

    Do NOT pass the full user question as the query. Extract the
    core concepts and keywords. If the first result set is weak,
    rewrite the query and search again before answering.

    Cite the retrieved documents as evidence in your final answer.
  parameters:
    query:
      type: string
      description: "2-6 keywords, not a full sentence."
Same tool. Completely different agent behavior.
The good description does three jobs the bad one skips:
Claude’s Skills system is worth studying for the shape, not the brand. A Skill packages task-specific instructions, files, scripts, and example workflows behind a short trigger description. The heavy content only loads when the agent decides the Skill is relevant. The pattern has a name: progressive disclosure. Reachable in any framework that lets you gate long instructions behind a short surface.
Two tips that have saved me more time than anything else in this area.
1. When you’re stuck, let skill-creator rewrite your prompt.
Anthropic ships an official Skill called skill-creator whose job is to make and improve other Skills. Its SKILL.md is, almost accidentally, the best prompt-design tutorial I have read. The patterns it pushes are exactly the ones that hold up under load: explain why a rule matters instead of writing rigid ALWAYS/NEVER directives; design for the smart model you actually have, not the rote one you imagine; generalize past your test cases rather than overfit to them; cut anything not pulling its weight.
What I do now whenever I have to write a non-trivial agent system prompt: write a first draft myself, then ask Claude to rewrite it “following the skill-creator SKILL.md guidelines.” The result has beaten my draft every single time. Sometimes embarrassingly so.
2. Read how Claude Code itself is built.
Anthropic’s Claude Code documentation walks through how their own coding agent is wired — system prompt shape, tool surfaces, subagent boundaries, context management, the whole stack. If you have only ever read agent tutorials, reading the docs for a real production Level 4 agent is the cheapest level-up I know.
Practical translation: do not dump every possible instruction into the system prompt. Expose short names and descriptions. Load the deep stuff on demand.
A scar from one of my own v1s. We added six tools, expecting the agent to compose them in interesting ways. It did not. It picked the wrong one, called it with the user’s entire question as the query, and kept looping. The tool name was the lie. It promised “search”, but the implementation could only handle keywords, and nothing in its description said so. We cut from six tools to two, rewrote the descriptions, and the loop stopped.
The bug was not reasoning. The bug was that the tool name lied.
Design the Tools Before the Agent
If you only remember one thing from this post: design tools first, agent second.
Before writing a single line, ask:
If the honest answer is “it talks nicely,” the user has no reason to use it. General-purpose LLMs already talk nicely. The differentiation comes from tools that connect to your system:
Tools are how an agent becomes useful in domains where a general LLM cannot act. They are also the surface where security, permissions, and auditing actually live — which is another reason “we’ll figure out tools later” is the wrong order.
A Reasonable Starting Architecture
If I were building a v1 today:
User
  ↓
Root agent (system prompt + context manager)
  ↓
Planner / agent loop
  ↓
Tool selector → Tool execution → Observation
  ↓
(loop until done or iteration cap)
  ↓
Final response
A good v1 has:
That’s it. Ship that, watch traces, then improve.
The traps I see most often in v1s:
What “Done” Looks Like
You’ll know you’ve built a Level 4 agent when:
If you cannot yet point at a trace that satisfies all four, keep going. That is the gap worth closing.
If you missed it, Part 1 covers the 4-level taxonomy and why most “AI agents” you encounter in real products are stuck at Level 1 or 2.
Tell me what your current v1 looks like — especially the tool list. Most of the interesting design happens there, and most of the bugs do too.
Gemini 3.5 Flash is generally available (GA), stable, and ready for scaled production use. As our most intelligent Flash model, it delivers sustained frontier performance in agentic execution, coding, and long-horizon tasks at scale.
This guide contains an overview of improvements, API changes, and migration guidance for Gemini 3.5 Flash.
New model
| Model | Model ID | Description |
|---|---|---|
| Gemini 3.5 Flash | gemini-3.5-flash |
Our most intelligent model for sustained frontier performance in agentic and coding tasks. |
Gemini 3.5 Flash supports the 1M token context window, 65k max output tokens, thinking, and the same set of tools and platform features as Gemini 3 Flash. Computer Use is not supported at this moment.
For complete specs, see the models overview. For pricing, see the pricing page.
Quickstart
Install the latest Google Gen AI SDK:
pip install -U google-genai
All code examples in this guide use the Interactions API. The Interactions API is the new standard primitive for building with Gemini, recommended for all new projects. It is optimized for agentic workflows, server-side state management, and complex multi-modal, multi-turn conversations. The GenerateContent API is also supported; the same configuration options and recommendations apply.
# Interactions API
from google import genai

client = genai.Client()

interaction = client.interactions.create(
    model="gemini-3.5-flash",
    input="Explain how parallel agentic execution works in three sentences."
)
print(interaction.output_text)
# Generate Content API
from google import genai

client = genai.Client()

response = client.models.generate_content(
   model="gemini-3.5-flash",
   contents="How does AI work?",
)
print(response.text)
What’s new
high to medium. See New default effort level for details.low thinking: low is now significantly improved for code and agentic tasks that require fewer steps, offering strong quality at lower latency and cost. Behavioral changes
New default effort level: medium
The default thinking effort is now medium, changed from high in Gemini 3 Flash Preview. medium yields very good results across a wide range of tasks while being faster and more cost-efficient. For complex problems, high encourages the model to think more deeply.
| Effort level | When to use |
|---|---|
minimal |
Optimized for response speed. Chat-like use cases, quick factual answers, simpler tool calls. |
low |
Code and agentic tasks that require lower latency and fewer steps. Also works well for analysis and writing tasks that require some thinking. |
medium (default) |
Best quality for most tasks. Recommended for complex code and agentic use cases. |
high |
Maximizes the model’s ability to think and use tools. Best for complex reasoning, hard math, and the most difficult code or agent tasks. Allows extended thoughts and function calls. |
To override the default, set thinking_level in your config:
from google import genai

client = genai.Client()

interaction = client.interactions.create(
    model="gemini-3.5-flash",
    input="Prove that the square root of 2 is irrational.",
    generation_config={"thinking_level": "high"},
)
print(interaction.output_text)
Tip: Start with medium, it provides the best quality for the vast majority of tasks. Try low for a faster, cheaper experience with strong quality. Switch to high for complex reasoning, hard math, or difficult coding challenges. Use minimal to optimize for speed in simple queries.
Thought preservation
The model maintains intermediate reasoning across multi-turn conversations automatically. When present in the conversation history, reasoning context carries forward, which improves performance on complex multi-step tasks
like iterative debugging and code refactoring. No API changes needed:
contents. The SDKs handle this automatically. Parameter updates and best practices in Gemini 3.x
The following apply to all Gemini 3.x models, including Gemini 3.5 Flash.
temperature, top_p, top_k: we strongly recommend not changing the default values. Gemini 3’s reasoning capabilities are optimized for the default settings.thinking_level instead of thinking_budget.id, name, and response count must match the preceding calls.See the sections below for how to update your code.
Sampling parameters (no longer recommended)
temperature, top_p, and top_k are no longer recommended for all Gemini 3.x models. Gemini 3’s reasoning capabilities are optimized for the default settings. Remove these parameters from all requests.
# ⚠️ Remove these parameters (not recommended)
generation_config = {
    "temperature": 0.7,
    "top_p": 0.9,
    "top_k": 40,
}
To ensure determinism, we recommend defining a system instruction with explicit rules for your specific use case.
thinking_budget (no longer recommended)
The raw numeric thinking_budget parameter is no longer recommended across all Gemini 3.x models. Use the thinking_level string enum instead.
# ⚠️ Before (not recommended)
generation_config = {
    "thinking": {"thinking_budget": 7500},
}

# ✅ After
generation_config = {
    "thinking": {"thinking_level": "medium"},
}
Available values: minimal, low, medium (default), and high.
Function calling: strict response matching
The Interactions API already errors on mismatched function responses. The GenerateContent API does not yet error, but mismatched responses cause the model to return empty responses with finish_reason: STOP in most cases. Always follow these conventions:
| Requirement | Details |
|---|---|
Include id
|
Every FunctionResponse must include the id from the corresponding FunctionCall
|
Match name
|
The name in the response must match the name in the call |
| Match counts | Return exactly one FunctionResponse for each FunctionCall received |
# ✅ Include matching call_id and name in the function_result
final_interaction = client.interactions.create(
    model="gemini-3.5-flash",
    previous_interaction_id=interaction.id,
    tools=[my_tool],
    input=[{
        "type": "function_result",
        "name": fc_step.name,
        "call_id": fc_step.id,
        "result": [{"type": "text", "text": json.dumps(result)}],
    }],
)
Multimodal function responses
We often see clients provide images outside function response. This can lead to unexpected model behavior (e.g. thought leakage) and result in lower quality outputs. Follow the recommendation in Multimodal Function Responses API docs instead and include multimodal content in the function response parts that you send to the model. The model can process this multimodal content in its next turn to produce a more informed response.
# ✅ Include multimodal content in the function response
final_interaction = client.interactions.create(
    model="gemini-3.5-flash",
    previous_interaction_id=interaction.id,
    input=[
        {
            "type": "function_result",
            "name": tool_call.name,
            "call_id": tool_call.id,
            "result": [
                {"type": "text", "text": "instrument.jpg"},
                {
                    "type": "image",
                    "mime_type": "image/jpeg",
                    "data": base64_image_data,
                },
            ],
        }
    ],
)
Inline instructions in function responses
We often see clients provide additional instructions along with function responses as subsequent Parts. This can lead to unexpected model behavior (e.g. thought leakage) and result in lower quality outputs. Instead, append any extra instructions to the end of the function response text separated by two newlines.
# ✅ Append inline instructions to the end of the function response separated by two newlines
result_text = f"{json.dumps(result)}nn<your inline instructions>"

final_interaction = client.interactions.create(
    model="gemini-3.5-flash",
    previous_interaction_id=interaction.id,
    tools=[my_tool],
    input=[
        {
            "type": "function_result",
            "name": fc_step.name,
            "call_id": fc_step.id,
            "result": [{"type": "text", "text": result_text}],
        }
    ],
)
Reducing unnecessary tool calls
If you experience an overuse of tool calls, two techniques help minimize them:
medium, low, or minimal): Higher thinking levels encourage the model to use more tools to explore and verify, so lowering the level can reduce tool calls.Add a system instruction: If overuse persists after adjusting the thinking level, consider a prompt that restricts tool usage. For example:
You have a limited action budget of <n> tool calls. Use them efficiently.
Migration checklist
Note: Automate this migration with a coding agent. If you use a coding agent that supports skills (like Antigravity), install the Gemini Interactions API skill and run:
/gemini-interactions-api migrate my app to Gemini 3.5 Flash
We strongly recommend updating to google-genai SDK v2.0.0 or later. This version introduces breaking changes to the Interactions API. See the breaking changes migration guide for details.
Migrate from Gemini 3 Flash Preview
gemini-3-flash-preview → gemini-3.5-flash
temperature, top_p, top_k from your config (no longer recommended).thinking_budget with thinking_level.id and matching name to all FunctionResponse parts.high → medium; verify quality, speed, and cost.medium, low, or minimal); add a system instruction to constrain tool usage if overuse persists. Migrate from Gemini 2.5
All of the above, plus:
thinking_level: "medium" or "high" with simpler prompts instead.media_resolution_high setting to ensure continued accuracy. Migrating to Gemini 3 defaults may also increase token usage for PDFs but decrease it for video; if requests exceed the context window, explicitly reduce the media_resolution. See the media resolution docs for details. Gemini 3 family features
Gemini 3.5 Flash inherits all Gemini 3 family capabilities except Computer Use. Features introduced in Gemini 3 that carry forward:
Next steps
The Struggle: Why Generic Prompt Optimization Fails
I spent six hours last month watching a prompt optimizer tank a code generation task. The system had reduced token count by 38% and improved latency by 200ms. On paper, perfect. In practice, the optimized prompt started hallucinating variable names and skipping security checks that the original enforced.
The optimizer treated all prompts the same. A customer service chatbot and a code synthesis engine got the same optimization goals: brevity, speed, cost reduction. That’s backwards. A chatbot can afford to lose nuance. A code prompt can’t afford to lose a single security constraint.
I realized we were solving the wrong problem. We weren’t building a prompt optimizer. We were building a prompt classifier that could detect what a prompt actually does, then apply the right optimization strategy for that specific job.
The Context Detection Problem
Most prompt optimization tools work like compression algorithms. They strip tokens, consolidate instructions, remove “redundancy.” This works fine until your prompt is a security policy disguised as natural language.
I tested this hypothesis against 2,847 production prompts from our users. I manually categorized 400 of them into six distinct types:
Then I built a pattern-based detector. No fine-tuning. No labeled datasets. Just structural analysis of the prompt text itself: presence of code blocks, security keywords, citation patterns, conditional statements, brand guidelines, step numbering.
The detector hit 91.94% accuracy on a held-out test set of 200 prompts I hadn’t seen during development. That number matters because it proves something: prompt types are real and structurally distinct. They’re not a spectrum. They’re categories.
How Precision Locks Work
Once I knew what type of prompt I was dealing with, I could stop treating optimization as a single problem.
For a Logic Preservation prompt, the optimizer now:
For a Security Standard Alignment prompt:
For a Conversational Coherence prompt:
I tested this on 150 prompts across all six categories. The results:
| Category | Token Reduction | Quality Preservation | Semantic Drift |
|---|---|---|---|
| Logic Preservation | 28% | 99.2% | 0.3% |
| Security Alignment | 22% | 99.8% | 0.1% |
| Factual Grounding | 31% | 98.1% | 1.2% |
| Conversational | 42% | 97.4% | 2.1% |
| Creative | 35% | 96.8% | 2.9% |
| Instruction Fidelity | 26% | 99.1% | 0.4% |
Generic optimization averaged 38% token reduction but 8.7% semantic drift across all categories. Precision Locks hit 30% average reduction with 1.2% average drift.
You lose 8 percentage points of compression. You gain the ability to actually use the optimized prompt in production.
The MCP Architecture Decision
I needed this to work everywhere developers already work. Not in a web dashboard. Not in a separate tool. In Claude Desktop. In Cline. In their terminal.
I built it as an MCP (Model Context Protocol) server. This means:
npm install -g mcp-prompt-optimizer
Then in Claude Desktop config:
{
  "mcpServers": {
    "prompt-optimizer": {
      "command": "mcp-prompt-optimizer"
    }
  }
}
Now Claude can call the optimizer directly. No API keys. No context switching. No waiting for a web request to round-trip.
I also built an npx execution path for one-off optimization:
npx mcp-prompt-optimizer --input "your prompt here" --category auto
The --category auto flag triggers the context detector. If you know your category, you can lock it:
npx mcp-prompt-optimizer --input "your prompt" --category logic_preservation
This matters because adoption is friction. Every extra step kills usage. MCP-native means the tool lives where the work happens.
The Free Model Auto-Selection Problem
I initially built the evaluator to call GPT-4 for every optimization. Quality was excellent. Cost was terrible. A user optimizing 50 prompts per day would spend $12-15 on evaluations alone.
I realized I could use smaller models for specific evaluation tasks. A logic preservation check doesn’t need GPT-4. It needs pattern matching and syntax validation. I built task-specific evaluators:
By auto-selecting the right model for each task, I reduced evaluation costs by 100% for 60% of optimizations. The remaining 40% use Haiku instead of GPT-4, cutting costs by 85%.
A user optimizing 50 prompts per day now spends $0.30 on evaluations instead of $15.
Semantic Drift Detection: The Real Problem
Here’s where I almost shipped something broken. I built the optimizer to reduce tokens aggressively. It worked. Then I ran it against a customer’s prompt for generating SQL queries. The optimizer removed a single phrase: “Always use parameterized queries to prevent SQL injection.”
The optimized prompt still generated SQL. It was faster. It used fewer tokens. It also generated vulnerable SQL 23% of the time in my test set.
I added semantic drift detection. The system now compares the original prompt’s semantic intent against the optimized version using embedding distance and keyword preservation analysis. If drift exceeds a threshold (configurable per category), the optimizer either:
For security and logic prompts, the threshold is 0.05 (5% allowed drift). For conversational prompts, it’s 0.15 (15% allowed drift).
This catches the SQL injection case. It also catches subtler problems: a customer service prompt that loses empathy markers, a code prompt that loses error handling context, a compliance prompt that loses audit trail requirements.
Built-In Evaluations: What Actually Matters
I tested three evaluation approaches:
I went with hybrid. Every optimization gets scored on:
A logic preservation optimization needs high Preservation and Drift Risk scores. A conversational optimization can tolerate lower Preservation if Efficiency Gain is high.
The evaluator runs automatically. You see the scores before you apply the optimization.
Version Control and Collaboration
I built this like Git for prompts because teams need to track what changed and why.
Every optimization creates a commit:
commit 3a7f2e9
Author: [email protected]
Date: 2024-01-15 14:32:00

Optimize customer_service_v2 prompt

- Removed 127 tokens (18% reduction)
- Preserved conversational tone
- Quality Score: 87/100
- Category: Conversational Coherence

Diff:
- "Please be helpful and friendly when responding to customer inquiries"
+ "Be helpful and friendly"
You can diff any two versions. You can revert to a previous version. You can branch and test variants in parallel.
The A/B testing framework lets you run two prompt versions against the same input set and compare results:
Variant A (original): 847 tokens, 4.2s avg latency, 92% user satisfaction
Variant B (optimized): 694 tokens, 3.1s avg latency, 91% user satisfaction
You see the tradeoff. You decide if it’s worth it.
Multi-LLM Support: The Portability Question
I built the optimizer to work with any LLM that accepts text input. The context detector works the same way regardless of which model you’re using. The Precision Locks apply the same optimization rules.
But the evaluator needs to adapt. GPT-4 and Claude 3.5 Sonnet have different token economics. Cohere’s models have different latency profiles. Llama 2 running locally has different cost characteristics.
I built model-specific evaluation profiles. When you specify your target LLM, the evaluator adjusts its scoring:
This means the same prompt gets optimized differently depending on where it runs. That’s correct behavior. A prompt running on a $0.03 per 1M token model should optimize differently than one running on a $15 per 1M token model.
The Real Insight: Typed Optimization
Most engineers treat prompt optimization as a single problem. Reduce tokens. Improve speed. Lower cost. Done.
The founding insight here is that prompt optimization is a typed problem. A code prompt and a chatbot prompt need different optimization strategies because they have different failure modes.
Code prompts fail by producing incorrect logic. Chatbot prompts fail by losing tone. Security prompts fail by losing constraints. You can’t optimize for all three simultaneously.
The 91.94% context detection accuracy proves this isn’t theoretical. The categories are real. They’re structurally distinct. They’re detectable without fine-tuning.
Once you accept that premise, everything else follows. Precision Locks. Category-specific evaluation. Semantic drift detection tuned to each category’s risk profile.
This is why generic optimization fails. It’s solving the wrong problem.
What This Means for Your Workflow
If you’re optimizing prompts manually, you’re leaving 30-40% cost reduction on the table. If you’re using generic optimization, you’re trading correctness for efficiency.
The Precision Lock system gives you both. Detect what your prompt does. Apply the right optimization strategy. Evaluate the results with category-specific scoring. Version control your changes. Test variants in parallel.
The MCP architecture means you do this without leaving your editor. The free model auto-selection means you do it without blowing your API budget. The semantic drift detection means you don’t ship broken prompts.
Open Question
If prompt optimization is truly a typed problem, what other AI workflows are we treating as generic when they should be category-specific? Are we optimizing for the wrong metrics across the board?

Assertion-based prompt evaluation, constraint preservation, and semantic drift detection. Route prompts with 91.94% precision. MCP-native. Free trial.
