PROJETO AURORA X
Check out this Pen I made!

 Mert
Check out this Pen I made!
Turning raw infrastructure diffs into decisions engineers can actually understand.
INTRODUCTION
Terraform plans are incredibly precise. They show every resource change, attribute modification, and dependency update that will occur during an apply.
But precision is not the same as clarity.
For many engineers reviewing infrastructure changes, Terraform plans feel more like a wall of text than a meaningful explanation of what is about to happen. The information is there, but extracting the real implications often requires experience and careful reading.
This is exactly where AI can become useful. Not by executing infrastructure changes, but by translating Terraform plans into something humans can reason about.
THE PROBLEM WITH RAW TERRAFORM PLANS
Terraform’s plan output is designed for correctness, not readability.
It faithfully lists changes such as resource replacements, attribute updates, and dependency adjustments. While this is ideal for machines and precise workflows, it can make reviews difficult for humans, especially in larger environments.
A simple plan might include:
What reviewers actually want to know is much simpler:
Terraform itself does not answer those questions.
WHERE HUMAN REVIEW BREAKS DOWN
Experienced engineers eventually develop an instinct for reading Terraform plans. They scan for dangerous signals:
resource replacement
But this intuition takes time to build, and even experienced reviewers can miss subtle interactions when reviewing large changes late in the day or under delivery pressure.
The real problem isn’t lack of information. It’s cognitive load.
Terraform tells us everything. Humans only need to understand the important parts.
WHY AI IS GOOD AT THIS PROBLEM
AI models are particularly good at summarizing structured text and identifying patterns.
A Terraform plan contains many signals that AI can interpret effectively:
Instead of forcing humans to parse hundreds of lines of output, AI can produce a concise summary describing the operational impact.
This transforms the Terraform plan from a raw diff into an explanation.
AI AS A REVIEW ASSISTANT IN CI/CD
A practical place to integrate this capability is within CI/CD pipelines.
After generating a Terraform plan, a pipeline step can feed the plan output into an AI model. The model then produces a human-readable summary that is attached to the pull request.
Instead of reviewing raw plan text alone, engineers see a structured explanation such as:
Risk Summary: This change replaces the EKS node group, which will trigger a rolling replacement of worker nodes.
Security Impact: No IAM policies were expanded.
Cost Impact: Estimated monthly increase: approximately $120 due to increased instance size.
Operational Notes: Node replacement may temporarily reduce cluster capacity during rollout.
This type of explanation does not replace the Terraform plan. It simply helps humans understand it faster.
USING GITHUB ACTIONS FOR AI-ASSISTED PLAN REVIEWS
GitHub Actions provides a natural place to implement this pattern.
A typical pipeline already includes steps like formatting, validation, and plan generation. Adding an AI analysis step is straightforward and can operate entirely in read-only mode.
The workflow might look like:
The key point is that the AI does not change infrastructure or execute Terraform commands. It only interprets the plan and produces a human-readable summary.
This keeps the decision-making process firmly in human hands.
WHY THIS IMPROVES INFRASTRUCTURE SAFETY
When infrastructure reviews fail, it is rarely because Terraform produced incorrect output.
Failures occur because reviewers misinterpret the impact or miss important signals hidden within large plans.
AI-assisted explanations reduce that risk by highlighting the kinds of changes humans care about most:
The AI becomes a second set of eyes, helping reviewers focus their attention where it matters.
THE IMPORTANT BOUNDARY
Even though AI can interpret plans effectively, it should never be allowed to execute them.
Running terraform apply still requires human ownership and operational judgment. AI can explain consequences, but it cannot decide whether those consequences are acceptable.
That boundary is what keeps AI useful rather than dangerous.
CLOSING THOUGHT
Terraform already tells us what will change.
AI helps answer the more useful question: What does this change actually mean?
By turning raw infrastructure diffs into clear explanations, AI allows DevOps teams to review changes faster, understand risk better, and make more confident decisions.
And that is exactly where AI belongs in infrastructure workflows - helping humans think more clearly, not replacing their judgment.
How does your team review Terraform plans today - raw output, custom tooling, or something smarter?
Originally published on Medium:
Routing is one of the most fundamental concepts in any web application. It determines how users move between different pages and how those pages are structured. In Next.js, routing has evolved significantly with the introduction of the App Router, which uses a file-based system to make navigation more intuitive, scalable, and powerful, all without needing external libraries.
Today, for day 53, the goal was to understand routing in Next.js
App Router Mental Model
In Next.js App Router:
Folders = Routes
Files = UI + Behavior
👉 Your project structure defines your entire routing system.
No need for separate route configuration like in traditional React apps.
Core File Conventions (Built-in Superpowers)
Next.js gives you powerful features just by naming files correctly.
page.js
Example:
app/about/page.js → /about
layout.js
👉 Layouts can be nested, which is extremely powerful for dashboards and apps.
loading.js
error.js
"use client" required) not-found.js
notFound() from Next.js👉 Key Insight:
All of this comes without installing any extra libraries.
Nested Routing (Zero Config)
Routing is automatically created from folders.
Example:
app/
  dashboard/
    page.js        → /dashboard
    settings/
      page.js      → /dashboard/settings
👉 No need for route definitions like in React Router.
Dynamic Routes
Dynamic routing is super clean in App Router using square brackets.
Create a dynamic route:
app/blog/[slug]/page.js
Access params:
export default function Page({ params }) {
  return <h1>{params.slug}</h1>;
}
👉 This replaces React Router params.
⚠️ Important Update (Accuracy Fix)
params (as shown above)import { useParams } from "next/navigation";
Route Groups
Route groups help organize your code without affecting URLs.
Example:
app/
  (auth)/
    login/page.js
    register/page.js
👉 URLs will still be:
/login
/register
Navigation Hooks
These hooks come from:
import { useRouter, usePathname } from "next/navigation";
useRouter()
router.push("/dashboard");
usePathname()
⚠️ Important
👉 These hooks only work in Client Components (
"use client"required)
Layout Nesting
App Router allows multiple layout levels:
app/layout.js
app/dashboard/layout.js
Example:
/dashboard → has its own layout/dashboard/settings → inherits dashboard layout automatically
👉 This is perfect for:
Key Takeaways (Quick Recap)
page.js creates routeslayout.js enables shared UI[param]
Final Thoughts
The Next.js App Router simplifies routing by turning your folder structure into a powerful system. Once you understand the core conventions, building scalable and well-structured applications becomes much easier.
“Folders = Routes, Files = Behavior”
Thanks for reading. Feel free to share your thoughts!

written: 15th March, 2026
Motivation:
I was applying for GSoC 2026 – DT Bindings Project. In order to understand this project more, I decided to start off my learning about them first. I had also learnt about ACPI tables in this post while investigating my laptop’s low power bug, and had encountered device trees. This made me curious about the GSoC project and so, I decided to learn about Device trees.
Along the way, I started finding them really interesting and worked on a patch to convert a DT binding to a DT Schema too! (i will talk about that in the next post)
What is a device tree?
A device tree is a data structure that describes hardware.
Hardware can be discoverable or non discoverable.
Non discoverable devices hardware descriptions needed:-
How to discover non discoverable components:
1) Modify OS/Bootloader directly to include the required information to discover devices— but after ARM32 architecture — too tedious to do..
2) ACPI tables — mainly used on x86 architectures (pc, laptop), and some ARM64 platforms
3) Device trees — used for embedded CPU arch, like ARM, RISC-V, MIPS, etc
Device Tree
it’s a tree data structure that descibes hardware
described in –> Device Tree Source (.dts) files
compiled to –> Device Tree Blob (.dtb) format
by –> Device tree Compiler (dtc)
DTB can be directly linked to the bootloader, or passed to the OS by the bootloader
Device Tree Bindings
These are the sets of rules that check if the devicetree provided by the hardware are valid or not?
Eg. Arduino has temperature sensor. Temp sensors has hardware descriptions and device tree. these are validated against device tree bindings, and then identified.
Device Trees bindings are written in YAML format. These are machine readable,
The patch I will analyze is written by Krzysztof Kozlowski. It was provided as a reference in the GSoC Device Tree Bindings Project
Patch Link GSoC Project Details Link
YAML

Extra stuff added later:
This device is supported by only I2C bus. (it’s explained in the next image)
But, some devices are supported by SPI protocol only. SPI protocol has 4 wires. There is no addressing system, and each chip gets a dedicated chip wire.
reg helps answer the question how a CPU identifies and reaches this specific chip of the bus
reg on I2C is the slave address.
Each chip has a dedicated slave address hardwired into it by the manufacturer.
Eg. here, reg=<0x11>
reg on spi identity of chip is the chip select line number. CPU has physical wires, there is no addressing, and reg is the number of wires connected.
Eg. here, reg=<0> –> connected to chip select line 0
maxItems can be > 1 in case of memory mapped peripherals — that live directly inside the CPU’s memory address space, and occupy separate regions of memory.
Eg. A display controller that has config registers at address1
and framebuffer memory at address2
TXT file — old
Traditionally, they used to be written in txt format. These were just documentations written by the developer. These aren’t machine readable, can’t be verified quickly, and the documentation can be incomplete

Things I figured out along the way
DTS (device tree sources) — describes the hardware
DT bindings — how DTS should be constructed
Previously — DT bindings were written in text in past
DT schema — new format — yaml
–new format which follows validation of bindings itself against meta schema
–validation of DTS against bindings
rules for writing bindings — all new bindings must come in DT Schema
rules ->
no need for properties for discoverable hardware
dual licence should be mentioned at start (GPL-2.0-only OR BSD-2-Clause)
bindings file name should be like -> vendor,device.yaml or vendor,soc-ip.yaml
binding patches and driver patches should be different
compatible –> should be specific — no bus suffixes (if bus is there)
simple-mfd
—> simple multi functional device — children does not depend on any features of parent
no reset lines — no clocks –
for very simple devices
syscon – simple — generic register range — many pieces — no 1 specific device
aka system controller — has different bits for different pieces
dont use it to replace imp drivers
properties represent hardware characteristics
Resources:
AI is quickly becoming part of every conversation around software testing. From generating test cases to automating repetitive workflows, Large Language Models have opened up new possibilities for QA teams.
But when you move from experimentation to real production environments, a different picture starts to emerge.
The same model that looks impressive in a demo can become unpredictable in practice. And in testing, unpredictability is not just inconvenient. It is a fundamental risk.
When “Smart” Becomes Unreliable
Large Language Models are designed to be flexible. They generate outputs based on probability, not strict rules. That flexibility is what makes them powerful, but it is also what makes them unreliable for testing.
In a regression scenario, consistency matters more than creativity. If the same input produces slightly different outputs each time, your test results can no longer be trusted.
Over time, teams begin to notice strange behaviors. A test that passed yesterday suddenly fails today without any real change in the system. A generated script looks correct but breaks during execution. In some cases, the model even introduces logic that does not exist in the application at all.
These are not edge cases. They are natural consequences of how LLMs work.
Rethinking the Role of AI in QA
This is where many teams take a step back and ask an important question.
Is AI really the right approach for testing?
The answer is yes, but not in the way most people expect.
The issue is not about whether to use AI. It is about choosing the right kind of AI for the right task.
Why Smaller Models Are Making a Comeback
While LLMs dominate headlines, smaller and more focused models are quietly proving their value in testing environments.
These models are designed to operate within a defined context. They are faster, more predictable, and far more efficient when handling structured workflows. For tasks like executing predefined test steps or validating expected outputs, they often outperform larger models.
However, they are not a complete solution on their own. Their strength lies in execution, not reasoning. They can follow logic very well, but they struggle when asked to interpret intent or handle complex, multi-step scenarios.
The Shift Toward Hybrid Thinking
Instead of choosing between large and small models, forward-looking teams are starting to combine them.
This is where hybrid AI architecture comes into play.
In this setup, different models take on different roles. Smaller models handle execution where stability is critical. Larger models are used for understanding intent and dealing with ambiguity. Sitting on top of both is a coordination layer that ensures everything works together as a system.
This approach changes how we think about AI in testing. It is no longer a single tool, but a structured ecosystem.
From Tools to Intelligent Systems
The real transformation happens when orchestration is introduced.
Rather than relying on one model to do everything, multiple specialized agents begin to collaborate. One agent interprets the test intent. Another generates actions. A third validates outputs. Others handle execution, monitoring, and failure analysis.
Suddenly, testing is no longer just automated. It becomes adaptive.
When something changes in the interface, the system can adjust. When a failure occurs, it can analyze the root cause and suggest a fix. When new code is introduced, it can prioritize the most relevant tests.
This is what people refer to as Agentic AI, but in practice, it feels less like using a tool and more like working with a highly coordinated team.
Making AI Work in Real Pipelines
In modern CI/CD environments, speed and reliability have to go hand in hand.
A hybrid, agent-driven system can continuously analyze code changes and decide which tests actually need to run. It can generate or update execution logic without requiring constant manual input. Most importantly, it can provide feedback quickly enough to keep up with rapid release cycles.
This is where the gap between experimental AI and production-ready AI becomes very clear.
Reliability Is Not an Accident
One of the biggest misconceptions about AI in testing is that better prompts will solve everything.
In reality, reliability comes from structure.
It comes from training models with domain-specific data, validating outputs with human expertise, and grounding decisions in real project context. Techniques like Retrieval-Augmented Generation ensure that the system does not rely purely on what it has learned, but also on what is actually relevant in the moment.
Without this foundation, even the most advanced model will struggle to deliver consistent results.
Why This Matters for Enterprise Teams
For many organizations, the biggest concern is not capability, but control.
They need to know where their data is going, how models are behaving, and whether the system can scale without introducing new risks.
Hybrid approaches address these concerns by allowing deployment in private environments and reducing reliance on heavy infrastructure. They make it possible to bring AI into testing workflows without compromising security or predictability.
Final Thoughts
The conversation around AI in testing is often dominated by the latest models and their capabilities. But in practice, success rarely comes from using the most powerful model available.
It comes from designing the right system.
As testing continues to evolve, the focus is shifting away from individual tools and toward integrated, intelligent workflows. Hybrid, agent-driven approaches are not just a technical improvement. They represent a different way of thinking about automation altogether.
And for teams aiming to build reliable, scalable QA processes, that shift may be the most important change of all.
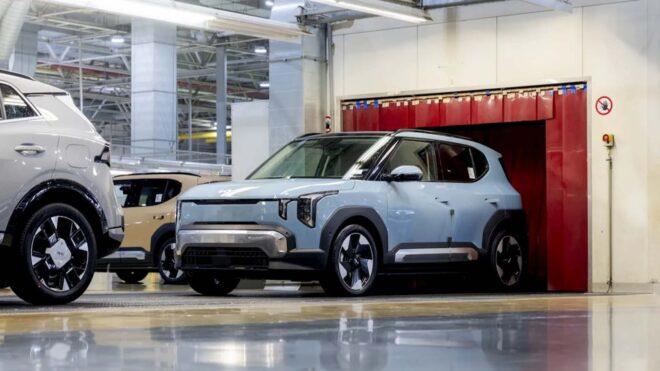
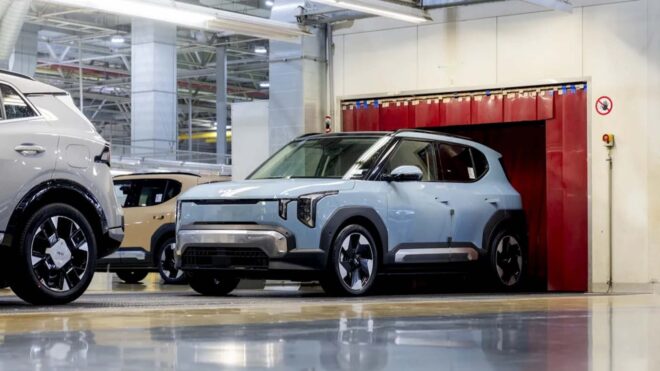 Tamamen elektrikli kompakt otomobil modeli Kia EV2, önümüzdeki ay başlayacak teslimatlar öncesinde şirketin Slovakya’da yer alan fabrikasındaki üretim bandından inmeye başladı. Kia Türkiye Genel Müdürü Can Ağyel, Emre Özpeynirci’nin CNBC-e’deki Oto Ekonomi programında EV2’nin Türkiye satış fiyatı ve tarihi hakkında açıklamalarda bulunmuştu. Merak edilen aracı Türkiye’ye 1 milyon 800 bin TL bandında getirmek istediklerini ve bunun için genel merkezle görüşmeler gerçekleştirdiklerini belirten Ağyel, yüksek sayıda getirmek istedikleri kompakt elektriklinin mayıs sonu ya da haziran ayında Türkiye’de satılmaya başlanacağını söyledi. EV2’nin Türkiye’de uzaktan bağlantılı olarak sunulacak ilk modelleri olacağını da aktaran Ağyel, yeni model yılına sahip diğer elektrikli araçlarda da bağlantılı hizmetlerin bulunacağını ifade etti. EV2 için 42,2 kWh ve 61,0 kWh olmak üzere iki farklı batarya paketi sunuluyor. 42,2 kWh bataryalı versiyon 317 km menzil vadediyor ve 145 beygir gücünde bir elektrik motoru taşıyor. 61,0 kWh bataryalı versiyon ise 448 km menzile sahip. 400 volt mimarili model, 22 kW AC […]
Türkiye’de de satılacak Kia EV2, üretim bandından inmeye başladı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.
 Bugün çok tepki çeken bir adım atan X, Twitter döneminde “TweetDeck” olarak isimlendirilen X Pro’yu herhangi bir ön duyuru yapmadan Premium+ özelliği haline getirdi. Bu konuda yaptığı açıklamada, “26 Mar 2026 itibarıyla Pro’ya yalnızca Premium+ ve üzeri planlarda erişilebilir. Sistemi kullanmak için lütfen planını yükselt.” diyen şirket, X Pro’nun şimdiye kadar aylık 150 TL fiyatı bulunan standart “Premium” aboneliği ile kullanılmasına izin veriyordu. Premium+ için aylık 1.691 TL talep eden şirket, bu beklenmedik hamlesiyle sırf altyapının sağladığı gerçek zamanlı akış ve aynı anda birden fazla akışın takip edilmesine imkan tanıyan yapı için Premium aboneliği alan çok sayıda kullanıcıyı kaybedebilir.
X, X Pro’yu bir anda Premium+ özelliği yaptı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.
In the fast-paced world of software development, businesses need to deliver features quickly, reliably, and at scale. This is where CI/CD (Continuous Integration and Continuous Deployment/Delivery) comes into play. CI/CD is a set of modern practices that automate the process of building, testing, and deploying applications, enabling teams to release software faster while maintaining high quality.
What Is CI/CD?
Continuous Integration (CI)
CI is the practice of frequently merging code changes from multiple developers into a shared repository. Each merge triggers automated builds and tests, helping detect errors early, reduce integration problems, and ensure code quality.
Continuous Deployment/Delivery (CD)
CD automates the process of deploying code to production.
Continuous Delivery: Code is automatically prepared for release but requires manual approval for production deployment.
Continuous Deployment: Every change that passes automated tests is deployed directly to production.
Together, CI/CD ensures faster, reliable, and repeatable software delivery cycles.
Key Components of CI/CD
Source Code Repository – Centralized code management (e.g., GitHub, GitLab).
Build Automation – Compiles and packages code automatically.
Automated Testing – Unit, integration, and end-to-end tests ensure code quality.
Deployment Automation – Scripts and pipelines push code to staging and production environments.
Monitoring & Feedback – Detects issues post-deployment and enables rapid remediation.
Benefits of CI/CD
Faster Time-to-Market: Automates repetitive tasks and reduces manual errors.
Higher Code Quality: Continuous testing catches bugs early, ensuring stable releases.
Improved Collaboration: Developers can merge changes frequently without conflicts.
Reduced Risk: Smaller, incremental updates reduce the impact of errors.
Operational Efficiency: Automated pipelines save time and effort across teams.
Popular CI/CD Tools
Jenkins – Open-source automation server for building and deploying pipelines.
GitLab CI/CD – Integrated CI/CD pipelines in GitLab repositories.
CircleCI – Cloud-based CI/CD for fast and scalable automation.
Travis CI – Continuous integration platform for automated builds and tests.
AWS CodePipeline / Azure DevOps / Google Cloud Build – Cloud-native CI/CD solutions.
CI/CD Best Practices
Automate Everything: Build, test, and deploy without manual intervention.
Use Version Control Effectively: Maintain a single source of truth for code.
Implement Comprehensive Testing: Include unit, integration, and security tests.
Monitor Deployments: Continuously track application performance and errors.
Adopt Incremental Releases: Smaller changes are easier to test and deploy.
CI/CD and Cloud Integration
CI/CD pipelines integrate seamlessly with cloud services, enabling scalable, flexible, and cost-efficient software delivery. Platforms like AWS, Azure, and Google Cloud, along with automation tools like Jenkins, allow developers to deploy globally, manage resources efficiently, and ensure high availability.
Conclusion
CI/CD is the backbone of modern DevOps, helping organizations deliver high-quality software faster, reduce risk, and improve collaboration. By automating integration, testing, and deployment processes, CI/CD empowers teams to focus on innovation and customer value, ensuring software is reliable, scalable, and continuously improving.
In software development, we love to make plans. We plan everything from 2-week sprints to 5 or more year roadmaps. And yet I sometimes think that the point of planning is misunderstood.
The point of having a plan, for me, is not to have a concrete set of steps. Well, it is that, but that’s not the real value of it. The point is understanding the why of the plan, and the how of the steps.
The why of the plan is this: Why does this plan make sense? Why does this plan bring us closer to fulfilling our goals? Without a purpose behind it, a plan is meaningless. I would even go so far as to say that sometimes having a fixed plan at all is counterproductive. Sometimes the product may be in an exploratory phase, and the only plan would be to try a lot of things and see what works. But the why behind this plan is clear: To evaluate a lot of options. Then we could go into the details and schedule the evaluations and timelines for the options we want to explore. The point is that the goal dictates the plan. Not the other way around.
And on a smaller scale we have to understand how the steps of the plan contribute to achieving the goal of the plan, how they contribute to fulfilling the why. The point of this understanding is that often plans can’t be executed exactly as they were initially created. But if we understand how something we can no longer do was supposed to contribute to the end goal, then we can intelligently search for a replacement to that something. We can do this because we understand the new situation we’re in and we know that we need to find something else to do that fulfills the purpose of the step we wanted to take, but can’t.
Actually, I would summarize this whole article with one concrete advice: For every component of a plan, understand the purpose of the component. For the plan as a whole that is the why, and for the steps of the plan that is the how.
Thanks for reading 🙂