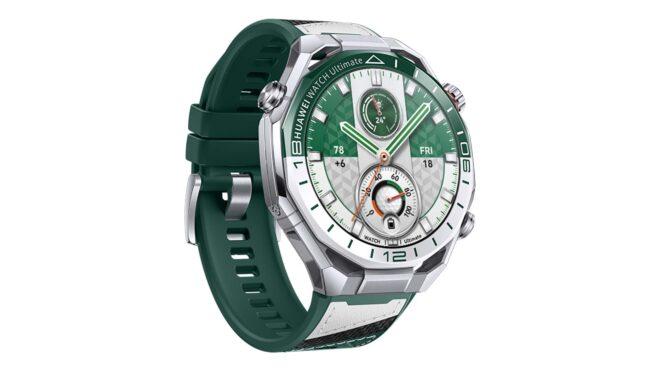
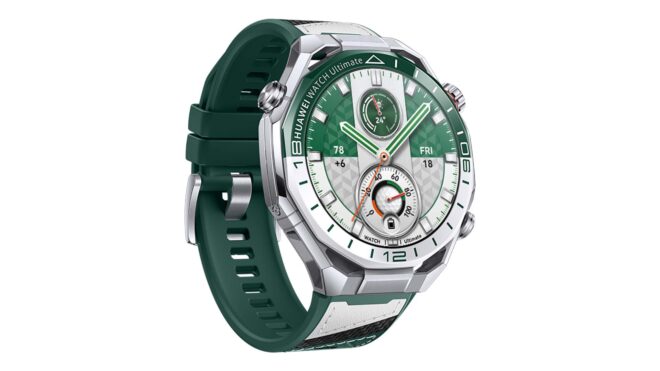
Huawei Watch Ultimate 2’nin “e-SIM” versiyonu da Türkiye’de satışa sunuldu

Huawei Watch Ultimate 2

Huawei Watch Ultimate 2 "e-SİM" Türkiye’de satışa sunulduGelişmiş özelliklere sahip akıllı saat modeli Huawei Watch Ultimate 2 için hazırlanan “e-SIM” versiyonu da Türkiye’de resmi olarak satışa sunuldu. Bluetooth versiyonu 40 bin TL, Bluetooth + e-SİM versiyonu ise 64 bin TL olan saat için Huawei Türkiye şunları aktardı: “Ultimate 2 eSIM versiyonu, akıllı saat endüstrisindeki en büyük batarya sorunlarından birini çözüyor. Cihaz, sektörde ilk kez “Pil Tasarrufu Modu”ndayken bile eSIM aramalarını destekliyor. Yapay zeka (AI) destekli gürültü engelleme teknolojisi ve rüzgar hızı direncine sahip mikrofonu sayesinde, kullanıcılar fırtınalı bir dağ zirvesinde veya dalgalı bir denizde telefonlarına ihtiyaç duymadan kristal netliğinde görüşmeler yapabiliyor. Ultimate 2, sektör standardı olan 10ATM’yi (100 metre) aşarak 20ATM ve 150 metre dalış kapasitesi sunuyor. Rakiplerinden farklı olarak, hava tankına takılan ek bir sensöre veya aksesuara ihtiyaç duymadan, doğrudan saat üzerinden çalışan Sonar Tabanlı Sualtı İletişimi ile geliyor. Dalgıçlar, 30 metreye kadar olan mesafelerde dalış arkadaşlarına sessizce önceden ayarlanmış mesajlar gönderebiliyor ve acil durumlarda 60 […]

Huawei Watch Ultimate 2’nin “e-SIM” versiyonu da Türkiye’de satışa sunuldu yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Deploying to Azure: CI/CD with GitHub Actions

Which method to use: func publish for development, config-zip for legacy scripts, az functionapp deploy for all plans

Azure Functions for .NET Developers: Series

Introduction: from local to production

Local tooling hides four things you have to own in production: packaging, authentication, configuration injection, and rollback. func start handles all of them silently; a CI/CD pipeline does not, and the decisions you make about each one compound quickly.

The gap is easy to miss. Your local environment reads from local.settings.json, authenticates with your personal identity, and recovers from bad deploys by letting you just restart. Azure does none of that for you. You need a packaging step, a way to authenticate from a pipeline without storing secrets, a strategy for injecting environment-specific configuration, and some mechanism for rolling back when a deploy breaks something.

This article covers two stages of that journey. First, manual deployment using the Azure CLI and the Functions Core Tools: useful for quick validation and understanding what the automated pipeline will do under the hood. Then a GitHub Actions workflow with two jobs, OIDC authentication (no stored credentials in your repository), deployment slots for zero-downtime releases, and configuration management that keeps secrets out of your pipeline definition entirely.

Manual deployment options

Before wiring up a full CI/CD pipeline, understand what actually happens when code reaches Azure. Manual deployment gives you that visibility, and it remains useful long after you’ve automated everything: for one-off hotfixes, for validating a packaging issue, or for deploying to a scratch environment without spinning up a workflow run.

func azure functionapp publish

The Core Tools command is the closest thing to a one-stop deploy:

func azure functionapp publish <APP_NAME>

Under the hood, it runs dotnet build --output bin/publish, creates a .zip archive (filtered by your .funcignore), uploads the archive via the Kudu ZipDeploy API (or One Deploy for Flex Consumption plans), and then syncs triggers and restarts the host. By default it also sets WEBSITE_RUN_FROM_PACKAGE=1 on the app, covered in the next subsection.

Flags you’ll reach for regularly:

# Skip the local build — useful when you've already built in CI
func azure functionapp publish <APP_NAME> --no-build

# Deploy to a staging slot instead of production
func azure functionapp publish <APP_NAME> --slot staging

# Push local.settings.json values to app settings (prompts for confirmation)
func azure functionapp publish <APP_NAME> --publish-local-settings -i

# Verify what files will be included before committing to a deploy
func azure functionapp publish <APP_NAME> --list-included-files

Run --list-included-files at least once per project. If your archive includes bin/ debug artifacts, test assemblies, or secrets you meant to .funcignore, you want to catch that before it’s sitting on a production host.

A minimal .funcignore for a .NET project:

*.csproj
*.sln
.git/
.vscode/
local.settings.json
test/

local.settings.json is the most important exclusion: it often contains connection strings and keys meant for local development only.

Azure CLI: two commands, two APIs

The Azure CLI gives you two distinct options, and picking the wrong one for your plan type will fail silently or throw a confusing error.

# Kudu ZipDeploy — works for Consumption, Premium, and Dedicated plans
az functionapp deployment source config-zip 
  -g <RESOURCE_GROUP> -n <APP_NAME> --src ./publish.zip

# One Deploy API — required for Flex Consumption, also valid elsewhere
az functionapp deploy 
  -g <RESOURCE_GROUP> -n <APP_NAME> --src-path ./publish.zip --type zip

The older config-zip command talks directly to Kudu and does no building; you’re responsible for providing a publish-ready zip. It does not support Flex Consumption, the newer serverless plan that bypasses Kudu entirely. If you’re on Flex Consumption, az functionapp deploy is the only CLI path that works. It also gives you --clean to remove files not in the archive and --async to return immediately without polling for completion.

A rule of thumb: if you’re writing a deploy script that needs to work across plan types, use az functionapp deploy. If you’re on a legacy plan and config-zip already exists in your runbooks, it’s fine to leave it.

Run-From-Package and why it matters

When WEBSITE_RUN_FROM_PACKAGE=1 is set, Azure mounts your zip archive as a read-only filesystem at wwwroot rather than extracting files into it. This is the default behavior when you publish with Core Tools, and it has real production benefits: deployment is atomic (the old package stays mounted until the new one is ready), file-copy locking errors disappear, and cold start times improve because the runtime reads directly from the zip.

The constraints: wwwroot becomes read-only (portal-based editing no longer works), the archive has a 1 GB limit, and you should not set this value on Flex Consumption plans, which manage packages differently.

Which method to use

Which method to use: func publish for development, config-zip for legacy scripts, az functionapp deploy for all plans

For anything beyond a one-off fix or an afternoon prototype, these manual commands are the foundation you’ll extract into a pipeline. Knowing what each one does makes the GitHub Actions steps in the next section easier to reason about when something goes wrong.

GitHub Actions workflow setup

The pieces fit together like this:

Deployment pipeline: Push to main, Build Job, Deploy Job with OIDC Login, Deploy to Staging Slot, Swap to Production

The build job produces a single artifact. The deploy job authenticates via OIDC, pushes to a staging slot, and swaps it into production.

The complete workflow is below. Read through it first; the walkthrough after explains the decisions behind each piece.

name: Deploy Azure Functions (.NET 10)

on:
  push:
    branches: [main]

jobs:
  build:
    runs-on: ubuntu-latest
    permissions:
      contents: read
    steps:
      - uses: actions/checkout@v4

      - uses: actions/setup-dotnet@v4
        with:
          dotnet-version: '10.0.x'
          cache: true

      - run: dotnet restore --locked-mode

      - run: >
          dotnet publish src/MyFunctionApp
          --configuration Release
          --output ./output
          --runtime linux-x64
          --self-contained true

      - uses: actions/upload-artifact@v4
        with:
          name: function-app
          path: ./output
          retention-days: 3

  deploy:
    runs-on: ubuntu-latest
    needs: build
    environment: production
    permissions:
      id-token: write
      contents: read
    steps:
      - uses: actions/download-artifact@v4
        with:
          name: function-app
          path: ./output

      - uses: azure/login@v2
        with:
          client-id: ${{ secrets.AZURE_CLIENT_ID }}
          tenant-id: ${{ secrets.AZURE_TENANT_ID }}
          subscription-id: ${{ secrets.AZURE_SUBSCRIPTION_ID }}

      - uses: Azure/functions-action@v1
        with:
          app-name: ${{ vars.FUNCTION_APP_NAME }}
          slot-name: staging
          package: ./output

      - name: Swap staging to production
        uses: azure/cli@v2
        with:
          inlineScript: |
            az functionapp deployment slot swap 
              --name ${{ vars.FUNCTION_APP_NAME }} 
              --resource-group ${{ vars.RESOURCE_GROUP }} 
              --slot staging 
              --target-slot production

This is the same function app from Parts 1 through 7. The complete source is in the azure-functions-samples repository. Every push to main builds it, deploys to a staging slot, and swaps to production. No secrets stored, no manual steps, and a rollback is one swap away.

If your plan doesn’t support slots (Consumption with only one slot available, or Flex Consumption), remove the slot-name parameter and the swap step. The functions-action will deploy directly to production.

Why two jobs instead of one

The split between build and deploy exists for two reasons.

First, the artifact produced by build is reusable. If you add a staging environment later, the deploy job can run twice against the same artifact without rebuilding. Build once, deploy to as many environments as you need.

Second, the id-token: write permission required for OIDC authentication (covered in the next section) is scoped to the deploy job only. If you set it at the workflow level, every job gets that elevated permission. Keeping it on the deploy job limits the blast radius if something goes wrong.

The build job

actions/checkout@v4 pulls your code. actions/setup-dotnet@v4 installs the SDK, and the cache: true option tells it to cache the NuGet package cache between runs.

That cache only works if your project has a lock file. Add this to your .csproj:

<RestorePackagesWithLockFile>true</RestorePackagesWithLockFile>

Then commit the generated packages.lock.json. Without it, cache: true has nothing to hash (so every run misses the cache), and --locked-mode silently regenerates a new lock file instead of validating against a committed one. With both in place, clean builds skip the network entirely for packages that haven’t changed.

The publish step is where .NET 10 requires extra care:

dotnet publish src/MyFunctionApp 
  --configuration Release 
  --output ./output 
  --runtime linux-x64 
  --self-contained true

--self-contained true is required for .NET 10. The Azure Functions v4 host runs on .NET 8. If you publish a framework-dependent app targeting .NET 10, the host cannot find the .NET 10 runtime and the deployment fails with exit code 150 (0x96). A self-contained publish bundles the runtime with your app, so the host’s .NET version becomes irrelevant.

actions/upload-artifact@v4 takes the ./output folder and makes it available to downstream jobs. The name value (function-app) is how the deploy job will refer to it.

The deploy job

needs: build means this job waits for the build to succeed before starting. environment: production ties the job to a GitHub environment, which lets you add required reviewers or protection rules before any deployment proceeds.

actions/download-artifact@v4 retrieves the artifact by the same name used during upload and places it in ./output.

azure/login@v2 handles authentication using OIDC; the specifics of how to configure this are in the next section. This step must come before functions-action, and the three secrets (AZURE_CLIENT_ID, AZURE_TENANT_ID, AZURE_SUBSCRIPTION_ID) must be set in your repository or environment settings.

Azure/functions-action@v1 does the actual deployment. Two parameters are required: app-name (the name of your Function App in Azure) and package (the path to your artifact). An optional slot-name parameter targets a deployment slot if you are using them.

The deployment method the action uses depends on your hosting plan. Flex Consumption plans use One Deploy; all other plans use Zip Deploy. The action picks this automatically based on your app’s plan type, so you do not need to configure it explicitly.

OIDC authentication (no stored secrets)

The workflow above uses three secrets: AZURE_CLIENT_ID, AZURE_TENANT_ID, and AZURE_SUBSCRIPTION_ID. None of them are actual credentials. That’s the point of OIDC.

Why not publish profiles or service principal secrets?

Publish profiles are XML files containing deployment credentials baked into the Function App. They work, but they create problems at scale: they can’t be scoped to a branch or environment, they don’t expire on a schedule, and if one leaks, anyone with the file can deploy to your app until you manually reset it.

Service principal secrets are better (they support expiration and RBAC scoping), but you still have a secret stored in GitHub that needs rotating every 6-24 months. Miss a rotation and your pipeline breaks silently on the next deploy.

OIDC eliminates stored credentials entirely. GitHub mints a short-lived token for each workflow run, Azure validates that token against a federated credential you configure once, and nothing secret ever sits in your repository settings.

How it works

  1. Your workflow requests an OIDC token from GitHub’s token service
  2. The azure/login action sends that token to Microsoft Entra ID
  3. Entra validates the token’s issuer (token.actions.githubusercontent.com), audience, and subject claim (which encodes the repo, branch, and environment)
  4. If the claims match your federated credential configuration, Entra issues an Azure access token
  5. The access token is used for the deployment, then expires

The subject claim is what makes this granular. You can restrict a credential to only work from a specific environment (repo:your-org/your-repo:environment:production), a specific branch, or even pull requests. A token minted from a feature branch won’t match a credential scoped to the production environment.

Setup steps

1. Create an Entra app registration with a service principal:

az ad app create --display-name "github-deploy-my-func-app"
az ad sp create --id <APP_ID>

2. Assign the Website Contributor role scoped to the resource group containing your Function App:

az role assignment create 
  --assignee <APP_ID> 
  --role "Website Contributor" 
  --scope /subscriptions/<SUB_ID>/resourceGroups/<RG_NAME>

Website Contributor is enough for deploying code. Contributor works too but grants more access than the pipeline needs.

3. Configure a federated identity credential:

{
  "name": "github-actions-production",
  "issuer": "https://token.actions.githubusercontent.com",
  "subject": "repo:your-org/your-repo:environment:production",
  "audiences": ["api://AzureADTokenExchange"]
}
az ad app federated-credential create 
  --id <APP_ID> 
  --parameters @credential.json

The subject field must match exactly. If your deploy job uses environment: production, the subject must end with :environment:production. If you deploy from a branch without an environment, use :ref:refs/heads/main instead.

4. Store the IDs as GitHub environment secrets:

Go to your repository Settings > Environments > production > Environment secrets, and add:

  • AZURE_CLIENT_ID: the Application (client) ID from your app registration
  • AZURE_TENANT_ID: your Entra tenant ID
  • AZURE_SUBSCRIPTION_ID: the subscription containing your Function App

These are identifiers, not credentials. Even if someone reads them, they can’t authenticate without a valid OIDC token from your specific repository and environment.

Workflow permissions

The deploy job needs id-token: write to mint the OIDC token:

deploy:
  permissions:
    id-token: write
    contents: read

Set this on the deploy job only, not at the workflow level. The build job doesn’t need token-minting permissions.

One gotcha

The Azure/functions-action supports two authentication methods: publish-profile and the azure/login action. They are mutually exclusive. If you pass a publish-profile parameter while also using azure/login, the action uses the publish profile and ignores your OIDC session. Remove the publish-profile parameter entirely when switching to OIDC.

Deployment slots and zero-downtime releases

Deploying directly to production means every release has a moment where either the old code or the new code is partially running. Deployment slots give you a staging URL to validate before any production traffic sees the new version, and an instant rollback if something goes wrong.

What each plan supports

Deployment slots by plan: Consumption 2, Premium 3, Dedicated 1-20, Flex Consumption not supported

If you’re on Flex Consumption, skip to the rolling updates section below.

The blue-green pattern

Deploy to a staging slot, verify it works, then swap staging into production.

  1. Deploy to staging: your CI/CD pipeline targets the staging slot instead of production
  2. Validate: hit the staging URL (your-func-app-staging.azurewebsites.net) with smoke tests or manual checks
  3. Swap: Azure switches the routing so staging serves production traffic
  4. Rollback if needed: swap again to revert (the old production code is now in the staging slot)

The swap itself takes seconds. Your users see either the old version or the new version, never a half-deployed state.

What swaps and what stays

This trips people up. During a swap, code and most settings travel together from staging to production. But some things are pinned to the slot:

Travels with code (gets swapped): general app settings (unless marked sticky), connection strings (unless marked sticky), handler mappings, public certificates.

Stays with the slot: publishing endpoints, custom domains, TLS/SSL certificates, scale settings, IP restrictions, Always On, FUNCTIONS_EXTENSION_VERSION (sticky by default).

Sticky settings that cause problems

Two settings deserve special attention:

FUNCTIONS_EXTENSION_VERSION is sticky by default. If your staging slot runs ~4 and production also runs ~4, this is invisible. But if you ever need to change the version, the stickiness means the setting won’t swap with the code. To make it travel with the swap, set WEBSITE_OVERRIDE_STICKY_EXTENSION_VERSIONS=0 on all slots.

WEBSITE_CONTENTSHARE is auto-generated per slot and should never be set manually. Each slot needs its own content share to avoid file locking conflicts. If you see deployment failures mentioning “cannot access file,” check whether slots are sharing this value.

Deploy-to-slot and swap in GitHub Actions

Add slot-name to the deploy step, then swap using the Azure CLI:

- uses: Azure/functions-action@v1
  with:
    app-name: 'my-func-app'
    slot-name: staging
    package: ./output

- name: Swap staging to production
  uses: azure/cli@v2
  with:
    inlineScript: |
      az functionapp deployment slot swap 
        --name my-func-app 
        --resource-group my-rg 
        --slot staging 
        --target-slot production

Swap gotchas

Watch for these:

  • Running functions are terminated during a swap. There is no graceful drain. If you have long-running executions, they will be killed. For timer or queue triggers, the runtime will pick up incomplete work after the swap, but HTTP requests in flight will fail.
  • Warm-up matters. After a swap, the new production instances need to initialize. Set WEBSITE_SWAP_WARMUP_PING_PATH to an endpoint (like a health check) that forces initialization before traffic arrives.
  • Keep app names under 32 characters. Longer names can cause host ID collisions between slots, leading to unexpected behavior.

Flex Consumption alternative: rolling updates

Flex Consumption doesn’t support slots, but it offers rolling updates as an alternative. With siteUpdateStrategy.type set to RollingUpdate, Azure replaces instances in batches rather than all at once, giving in-progress executions a 60-minute grace period to complete.

The trade-off: there’s no separate staging URL for validation, no way to split traffic between versions, and rollback means redeploying the previous version rather than an instant swap.

Environment configuration in pipelines

A deployment pipeline needs to put the right configuration in the right environment without leaking secrets into workflow files. GitHub Environments, the secrets hierarchy, and Key Vault references each handle a piece of this.

GitHub Environments

Environments are configured under your repository’s Settings > Environments. Each environment can have:

  • Required reviewers (up to 6 people who must approve before the deploy job runs)
  • Wait timers (a delay before deployment proceeds, useful for change windows)
  • Deployment branches (restrict which branches can target this environment)

In the workflow, environment: production on a job ties it to that environment’s rules. The job will pause and wait for approval if reviewers are configured.

Secrets hierarchy

GitHub secrets exist at three levels:

GitHub secrets hierarchy: Organization, Repository, and Environment levels with scope and examples

When the same secret name exists at multiple levels, environment wins over repository, which wins over organization. This means you can set AZURE_CLIENT_ID at the environment level with different values for development, staging, and production, each pointing to a different service principal scoped to its own resource group.

Setting app configuration during deployment

Your Function App needs configuration values beyond what’s in the code. The most direct approach is the Azure CLI:

- name: Configure app settings
  uses: azure/cli@v2
  with:
    inlineScript: |
      az functionapp config appsettings set 
        --name ${{ vars.FUNCTION_APP_NAME }} 
        --resource-group ${{ vars.RESOURCE_GROUP }} 
        --settings 
          "ServiceBus__Connection=${{ secrets.SERVICEBUS_CONNECTION }}" 
          "FeatureFlags__NewCheckout=true"

Use vars (GitHub Variables) for non-sensitive configuration and secrets for anything you wouldn’t put in a log file.

One warning if you manage settings through Bicep or ARM templates instead: the ARM API replaces all app settings on each deployment. If your template omits a setting that exists on the app, that setting gets deleted. The CLI’s appsettings set command merges instead, which is safer for incremental updates.

Multi-environment workflow

The build-once-deploy-many pattern chains environments with approval gates:

jobs:
  build:
    runs-on: ubuntu-latest
    # ... build steps from earlier ...

  deploy-dev:
    needs: build
    environment: development
    runs-on: ubuntu-latest
    steps:
      # download artifact, azure/login, functions-action
      # (same structure, different secrets per environment)

  deploy-staging:
    needs: deploy-dev
    environment: staging
    runs-on: ubuntu-latest
    steps:
      # deploy to staging slot, run smoke tests

  deploy-production:
    needs: deploy-staging
    environment: production  # approval gate triggers here
    runs-on: ubuntu-latest
    steps:
      # swap staging to production

The same artifact flows through all three environments. The only things that change are the secrets (different AZURE_CLIENT_ID per environment, each scoped to its own resource group) and the deployment target.

Key Vault integration

This ties back to Part 6 (Configuration Done Right). Instead of passing secret values through your pipeline, store them in Key Vault and reference them in app settings:

ServiceBus__Connection=@Microsoft.KeyVault(VaultName=my-kv;SecretName=servicebus-conn)

Your pipeline sets the reference, not the secret value. The Function App’s managed identity resolves the actual value at runtime using the Key Vault Secrets User role. The pipeline never sees the secret, and rotating it in Key Vault takes effect without redeployment.

If you use deployment slots, mark Key Vault references as slot settings when different environments need different secrets (e.g., staging points to a staging Key Vault, production to a production Key Vault).

What goes where

What goes where: GitHub Secrets for IDs, Key Vault for connection strings and keys, avoid secrets in YAML or Bicep

Closing

Eight articles, one function app, and a pipeline that deploys itself. If something in your own setup doesn’t match what’s here, the series navigation links every piece: from the first HTTP trigger through testing to this deployment workflow.

Do you deploy straight to production or use a staging slot? What made you choose one over the other?

Azure Functions for .NET Developers: Series

I built a CLI tool that auto-copies OTPs from Gmail — no more tab switching

*Every time I needed to log into something, the same thing happened:
*

  1. Enter email and password
  2. Wait for the OTP email
  3. Switch to Gmail
  4. Find the email
  5. Copy the 6-digit code
  6. Switch back
  7. Paste it before it expires

It’s maybe 15 seconds. But it happens dozens of times a day, and it’s
just annoying enough to break focus every single time.

So I built OTPilot.

What it does

OTPilot runs silently in the background. When you press a hotkey
(default: Ctrl+Shift+O), it:

  1. Fetches your last 10 emails from Gmail
  2. Finds the OTP
  3. Copies it to your clipboard
  4. Shows a desktop notification

That’s it. No tab switching. No waiting. Just paste.

How to install

pip install otpilot

Requirements:

  • Python 3.8+
  • Gmail account
  • Google Cloud project with Gmail API enabled (free, one-time 5 minute setup)

How to set it up

otpilot setup

The setup wizard walks you through:

  • Importing your Google credentials
  • One-time Gmail sign-in (OAuth — read-only access)
  • Setting your preferred hotkey

Then run:

otpilot start

It sits in your system tray and waits.

Privacy

This was my main concern when building it.

  • Your credentials never leave your machine
  • Gmail access is read-only — it cannot send, delete, or modify anything
  • Emails are fetched only when you press the hotkey — no background polling
  • OAuth tokens are stored locally at ~/.otpilot/

The Google Cloud setup

The one friction point is the one-time Google Cloud setup to get a
credentials.json file. It takes about 5 minutes and the full guide is
in the repo. Once it’s done, you never touch it again.

Platforms

Works on macOS, Linux, and Windows.

Linux users need xclip or xsel for clipboard support:

sudo apt install xclip

Links

MIT licensed. Feedback and contributions welcome — especially around
OTP extraction patterns, since different services format their emails
differently.

I Optimized SEO for 12 Languages — Here’s What Doesn’t Translate

Savekit Languages

Follow-up to I Built a Social Media Downloader and Got 169 Keywords Indexed in 7 Days. That one covered the initial indexing sprint. This one’s about what happened when I tried to scale it to 12 languages.

When I started expanding SaveKit beyond English, I did what most devs would do: handed my keyword list to a translator and called it a day.

That was dumb. Cost me about two weeks of rework.

Quick context

SaveKit’s a social media downloader — Pinterest, Instagram, Facebook, TikTok, Twitter/X, Reddit. 26+ pages total. I wanted to rank in 12 locales: EN, ID, PT, ES, TR, VI, JA, KO, DE, FR, HI, AR.

Savekit Languages

That’s 19 keyword targets per locale. 228 keywords that all needed independent validation. The stack is SvelteKit 2 + Svelte 5 on Cloudflare Pages, with each locale getting its own i18n JSON file for meta titles and descriptions.

The autocomplete test that broke everything

Before I touched any keywords, I did something simple: opened Google in incognito, set it to each target country, and started typing my keyword phrases.

Almost nothing autocompleted.

I’d been writing stuff like “safe instagram downloader” and “secure video downloader” because… that’s what you’d want, right? Turns out nobody actually types that. People assume a tool is safe. They don’t search for it.

“Safe” and “secure” had near-zero autocomplete presence in every single locale. Same for “best” and “free.” These are vanity keywords — they make you feel good about your meta tags but do absolutely nothing.

This became my pre-ship checklist for every keyword:

  1. Does it autocomplete in the target locale?
  2. Do top 3 competitors actually use it in their meta tags?
  3. Is the intent transactional? (someone wanting to download right now)
  4. No vanity words — “safe”, “secure”, “best”?

That fourth rule alone killed ~15% of my keyword list across all locales.

Keywords don’t translate

This is the thing I wish someone had told me earlier. You can’t translate keywords. You have to research each locale from scratch, like it’s a separate product launch.

Translation tells you what words mean. Research tells you what people actually type. Those are very different things.

Portuguese

In Brazil, “baixar” completely dominates over “download.” It’s not even close. The word literally means “to pull down” and it maps perfectly to the user’s mental model.

Title: Baixar Vídeo Instagram - HD, Sem Marca D'água | SaveKit

Spanish

I initially used “guardar” (to save) because it sounded nicer. Bad call — “guardar” is ambiguous. It could mean saving to a Pinterest board or bookmarking something. “Descargar” (to download/unload) is what people actually search. Swapped 8 keywords, confidence went from ~70% to 89%.

Turkish

“İndir” for download. Strongly preferred over English. 95% confidence — actually my cleanest locale because the verb is unambiguous and every competitor uses it the same way.

Vietnamese

This one was interesting. Both “tải” and “lưu” are used roughly 50/50 for download-type actions. That’s unusual — most locales settle on one dominant verb. I went with “tải” as the primary (more transactional) and sprinkled “lưu” in body copy.

Japanese & Korean

CJK users abbreviate everything. インスタ (4 chars) gets searched 3-5x more than インスタグラム (7 chars). Same pattern in Korean: 인스타 >> 인스타그램.

I also had to remove two keywords from JA/KO that I’d basically made up — “pinterest pin gallery” phrasing doesn’t exist in either language. Pinterest doesn’t have a “gallery” feature users identify by name. The autocomplete test caught both in under a minute. Embarrassing that I shipped them at all.

Side note on Korean: Naver holds 59% of search share there. Google SEO only gets you so far. I’ve deprioritized KO for now — Naver needs its own keyword tools and that’s a separate project.

German & French — being honest

These are my weakest locales. DE at 59% confidence, FR at 63%.

German surprised me: “downloaden” (English loan word) shows up 2-3x more than “herunterladen” in competitor meta tags. I didn’t expect that. But the overall keyword picture is murkier — fewer dominant tools in these markets, more variance between competitors.

French is similar. Pinterest keywords do well there (83% viable), but the rest is thin.

I shipped both locales anyway, but flagged them for Q2 validation once GSC data comes in. No point pretending you have high confidence when you don’t.

Arabic — nobody’s competing here

This was the wildest finding. For Arabic Pinterest downloads? There’s basically no one. Near-zero purpose-built competitors. The market’s wide open.

Some non-obvious implementation notes:

MSA only. Modern Standard Arabic. Every competitor uses it. I checked Egyptian dialect autocomplete — zero results. Don’t get creative with dialects.

Transliterate platform names. Arabic users search انستقرام, فيسبوك, تيك توك — not the English names. Confirmed via autocomplete.

RTL is trickier than you think. I set dir=rtl on <html>, but had to explicitly override with dir=ltr on the header, search form, footer, and logo:

<html dir="rtl" lang="ar">
  <body>
    <header dir="ltr">...</header>
    <main><!-- Arabic content flows RTL --></main>
    <footer dir="ltr">...</footer>
  </body>
</html>

Get this wrong and you break the layout for both RTL and LTR users at the same time. Ask me how I know.

“Without watermark” is universal

This was the most consistent pattern across all 12 languages. The #1 keyword modifier for video downloaders, everywhere:

Locale “without watermark”
EN no watermark
ID tanpa watermark
PT sem marca d’água
ES sin marca de agua
TR filigransız
VI không watermark
JA 透かしなし
KO 워터마크 없이
AR بدون علامة مائية
DE ohne wasserzeichen
FR sans filigrane

“Without app” is #2, but only in mobile-first markets (ID, VI, PT, TR, ES, AR). Doesn’t show up much in DE, FR, JA, KO, or EN.

The title formula

After scraping meta tags from 60+ competitor sites across all locales, one pattern held everywhere:

[Primary Keyword] - [Benefits] | Brand

Hyphen separates keyword from benefits. Pipe before brand. 50-65 chars. That’s it.

I’d been using brackets [] based on some older CTR studies. Checked 60+ ranking tools — not a single one uses brackets. Dropped them.

EN: Instagram Video Downloader - HD, No Watermark | SaveKit
PT: Baixar Vídeo Instagram - HD, Sem Marca D'água | SaveKit
TR: Instagram Video İndir - HD, Filigransız | SaveKit
AR: تحميل فيديو انستقرام - بدون علامة مائية، HD مجاناً | SaveKit

Same structure. Different words. That’s the whole point.

What I got wrong

Trusted my gut on CJK. Shipped two fabricated keywords in Japanese and Korean because they “sounded right.” The autocomplete test takes 30 seconds. I skipped it. Don’t skip it.

Treated German/French as “close enough to English.” Roman alphabet made me lazy. They’re not close enough. Both need proper Ahrefs-level validation that I haven’t done yet.

Confused translation with research. Seriously, these are completely different tasks and I mixed them up for the first two weeks.

What’s next

Waiting on GSC data (Q2 2026). That’ll tell me whether the validated keywords actually rank and if the confidence scores map to real traffic.

Arabic Pinterest is the most interesting bet. Either the near-zero competition means there’s a real opportunity, or it means the demand isn’t there. Should know by April.

And Korean — if Naver traffic turns out to be meaningful, the whole KO strategy needs a redo with Naver’s keyword tools. That’s a bigger project.

Takeaways if you’re doing this yourself

  1. Run the autocomplete test on every keyword. 30 seconds each. It’ll kill bad keywords before they waste your crawl budget.

  2. Research the native verb first. baixar, descargar, indir, tải, تحميل — the verb is the keyword. Don’t assume English works.

  3. Document why you removed keywords. If you don’t, someone (probably future you) will add them back in 6 months.

  4. Be honest about confidence. Shipping a locale at 59% validated is fine. Pretending it’s 95% is how you end up rewriting everything later.

I store all of this in packages/config/src/seo-keywords.ts alongside a strategy doc with the research data. Treating keywords as code — with commit history, reasons, and confidence levels — is the only way I’ve found to keep this manageable across 12 locales.

SaveKit is the project. Previous article here. If you’ve done multilingual SEO and found different patterns, I’d genuinely like to hear about it in the comments.

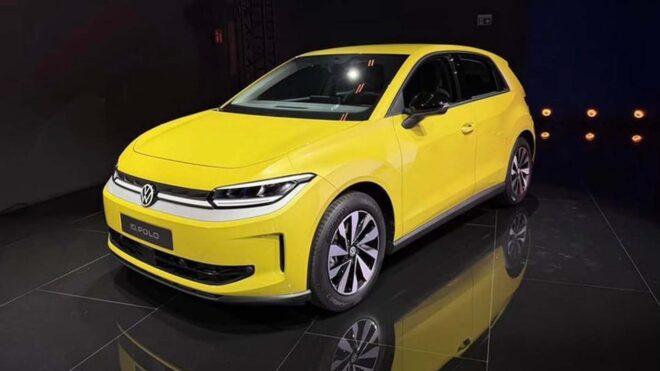
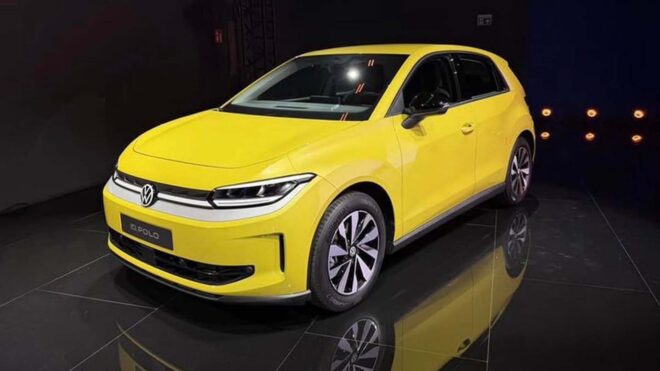
Elektrikli Volkswagen ID. Polo ve ID. Polo GTI için yeni fotoğraflar sızdırıldı

Volkswagen ID. Polo ve ID. Polo GTI için yeni fotoğraflar sızdırıldı

Volkswagen ID. Polo ve ID. Polo GTI için yeni fotoğraflar sızdırıldıTamamen elektrikli Volkswagen ID. Polo ve ID. Polo GTI için yeni fotoğraflar sızdırıldı. Araçların çok da sürpriz olmayan tasarımlarını net olarak gözler önüne seren fotoğraflarda en çok ID. Polo GTI dikkat çekiyor; sportif elektriklinin önümüzdeki yıl 223 beygir güçle yollara çıkarılacağı aktarılıyor. Önden çekişli olarak tasarlanan modelin 52 kWh NMC batarya üzerine kurulacağı ve 450 km civarında menzil sunacağı belirtiliyor. 130 kW DC şarj desteğiyle yolda bulunan araçta, bir GTI olarak daha sportif jantlar ve tamponlara yer veriliyor. Bu yıl yollara çıkarılacak standart ID. Polo ise 114 beygir, 133 beygir ve 208 beygir güç sunan üç farklı versiyona sahip olacak. 37 kWh ve 52 kWh batarya paketleriyle donatılacak elektrikli Polo, en üstte 450 km menzil sunacak. Daha sportif “R-Line” paketinin de hazırlandığı ID. Polo, Türkiye dahil çok sayıda pazarda satışa sunulacak.
Elektrikli Volkswagen ID. Polo ve ID. Polo GTI için yeni fotoğraflar sızdırıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Submitting My First Device Tree Binding Patch for GSoC 2026 — And It Got Accepted!

For the second patch, I looked through many drivers, and first, I had chosen Multi-Inno MI0283QT display panel
However, I found out that this device relied on a lot of complex properties that will probably depend on other files..

So, I decided to temporarily put it aside, and work on a simple file to get the hang of what should be done, and then come back to the bigger file, and work on it.

After looking through all the DT binding files, I decided to settle with this simple DT Bindings file

OLPC XO-1 RTC

OLPC XO-1 RTC
~~~~~~~~~~~~~

Required properties:
 - compatible : "olpc,xo1-rtc"

Understanding the Hardware:

RTC – Real Time Clock
A RTC is an electronic device that measures and tracks time, often in hours, minutes, and seconds. Unlike regular clocks, an RTC is specifically designed to operate within computing systems, even when the device is turned off or disconnected from power. Its primary function is to provide accurate time and date, which is crucial for various applications such as event logging, timestamping, and time-sensitive operations in computing and embedded systems. 1

OLPC = One Laptop Per Child
The OLPC XO (colloquially known as $100 Laptop,Children’s Machineis a low cost laptop computer intended to be distributed to children in developing countries around the world,to provide them with access to knowledge, and opportunities to “explore, experiment and express themselves” (constructionist learning).2

So, OLPC XO-1 RTC is basically an RTC that was developed specially for OLPC XO laptops.

Making a patch

I had already analyzed a patch while understanding Device Trees.
I also referred to the example-schema.yaml found in Documentation/devicetree/bindings

And I started working on my DT Schema patch, it was quite simple and didn’t require much time

# SPDX-License-Identifier: GPL-2.0-only OR BSD-2-Clause
%YAML 1.2
---
$id: [http://devicetree.org/schemas/rtc/olpc-xo1-rtc.yaml](http://devicetree.org/schemas/rtc/olpc-xo1-rtc.yaml)#
$schema: [http://devicetree.org/meta-schemas/core.yaml](http://devicetree.org/meta-schemas/core.yaml)#

title: OLPC XO-1 RTC

maintainers:
  - Alexandre Belloni <[email protected]>

properties:
  compatible:
    enum:
      - olpc,xo1-rtc

required:
  - compatible

additionalProperties: false

examples:
  - |
    rtc {
       compatible = "olpc,xo1-rtc";
    };

link: https://lore.kernel.org/linux-devicetree/[email protected]/

I checked if this works and it does!

anu@laptop:~/kernel-dev/source/linux$ make clean && make -j8 dt_binding_check DT_SCHEMA_FILES=Documentation/devicetree/bindings/rtc/olpc-xo1-rtc.yaml CLEAN Documentation/devicetree/bindings HOSTCC scripts/basic/fixdep HOSTCC scripts/dtc/dtc.o HOSTCC scripts/dtc/flattree.o HOSTCC scripts/dtc/fstree.o HOSTCC scripts/dtc/data.o HOSTCC scripts/dtc/livetree.o HOSTCC scripts/dtc/treesource.o HOSTCC scripts/dtc/srcpos.o HOSTCC scripts/dtc/checks.o HOSTCC scripts/dtc/util.o SCHEMA Documentation/devicetree/bindings/processed-schema.json LEX scripts/dtc/dtc-lexer.lex.c YACC scripts/dtc/dtc-parser.tab.[ch] HOSTCC scripts/dtc/dtc-lexer.lex.o HOSTCC scripts/dtc/dtc-parser.tab.o HOSTLD scripts/dtc/dtc CHKDT ./Documentation/devicetree/bindings LINT ./Documentation/devicetree/bindings DTEX Documentation/devicetree/bindings/rtc/olpc-xo1-rtc.example.dts DTC [C] Documentation/devicetree/bindings/rtc/olpc-xo1-rtc.example.dtb

Reply

I got a reply from the maintainer, Alexandre Belloni!
He told me that this should be moved in trivial-rtc

What is trivial-rtc?
trivial-rtc.yaml is a file where minimal or generic RTC devices’ schema are written. These devices are very simple and have generic properties, so instead of creating a separate DT Schema file, they are added to a common file called trivial-rtc.yaml

Thus, I added my device to the file,

index a2891ceb6344..000000000000
--- a/Documentation/devicetree/bindings/rtc/olpc-xo1-rtc.txt
+++ /dev/null
@@ -1,5 +0,0 @@
-OLPC XO-1 RTC
-~~~~~~~~~~~~~
-
-Required properties:
- - compatible : "olpc,xo1-rtc"
[diff](https://lore.kernel.org/linux-devicetree/[email protected]/#iZ31Documentation:devicetree:bindings:rtc:trivial-rtc.yaml) --git a/Documentation/devicetree/bindings/rtc/trivial-rtc.yaml b/Documentation/devicetree/bindings/rtc/trivial-rtc.yaml
index b47822370d6f..722176c831aa 100644
--- a/Documentation/devicetree/bindings/rtc/trivial-rtc.yaml
+++ b/Documentation/devicetree/bindings/rtc/trivial-rtc.yaml
@@ -65,6 +65,8 @@ properties:
       - microcrystal,rv3029
       # Real Time Clock
       - microcrystal,rv8523
+      # OLPC XO-1 RTC
+      - olpc,xo1-rtc
       # I2C bus SERIAL INTERFACE REAL-TIME CLOCK IC
       - ricoh,r2025sd
       # I2C bus SERIAL INTERFACE REAL-TIME CLOCK IC
--

I checked if it works and it does!

anu@laptop:~/kernel-dev/source/linux$ make -j4 dt_binding_check DT_SCHEMA_FILES=Documentation/devicetree/bindings/rtc/trivial-rtc.yaml
  SCHEMA  Documentation/devicetree/bindings/processed-schema.json
  CHKDT   ./Documentation/devicetree/bindings
  LINT    ./Documentation/devicetree/bindings

I went ahead submitted my patch
https://lore.kernel.org/linux-devicetree/[email protected]/

[25-03-26 23:19:39] HOLY SHIT!!!!!!!!
MY PATCH GOT ACCEPTED!!!!!!!!!!!!!!!
OMGGGGGG!!!!
I AM LITERALLY SCREAMING IN THE MIDDLE OF THE NIGHT!!
I HAVE NEVER FELT SO HAPPY!!!

I AM SO EXCITED THAT I AM JUMPING!

AAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAA

YAY!

I also got a piece of advice by the maintainer who accepted my patch, Conor Dooley:
I had been sending patches of the next version in response to the original patches, inside the same thread,

and that isn’t how it’s done
I should create a different thread in order to send new patches.

Thank you so much Conor! I’ll definitely remember that for my future patches.

Right now, as I write, I am still so excited, my fingers are trembling, lol
AAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAA
;lkdsjgsoegnhgkesjrgnhbseikgujhiu sfkjslfkjaf

End note:
This was my first patch, and making it was a truly enjoyable process, I can’t wait to start working on another patch again!
Although I am a currently beginner, I am learning through my mistakes, that I document on these post series. Someday, I won’t be a beginner and a seasoned contributer. I really look forward to it.
I will definitely continue contributing to the kernel and open source!

References

  1. https://www.lenovo.com/in/en/glossary/real-time-clock/
  2. https://en.wikipedia.org/wiki/OLPC_XO

PlayStation 5 ailesine ve PlayStation Portal’a zam geleceği iddia ediliyor

PlayStation 5 LOG Tasarım

PlayStation 5 LOG TasarımSony’nin yakın bir zaman içerisinde PlayStation 5 konsol ailesine ve PS Portal’a zam yapacağı iddia ediliyor. PS5 ve PS5 Pro’ya 100 avro, PS Portal’a ise 30 avro zam planlandığı öne sürülürken, zam sonrasında “disk sürücülü” PS5’in Avrupa fiyatının 549,99 avrodan 649,99 avroya, PS5 Pro’nun 799,99 avrodan 899,99 avroya, PS Portal’ın ise 219,99 avrodan 249,99 avroya çıkacağı aktarılıyor.
PlayStation 5 ailesine ve PlayStation Portal’a zam geleceği iddia ediliyor yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Google Translate servisinin “Canlı Çeviri” özelliği daha fazla kişiye açıldı

Google Translate

Google TranslateGoogle tarafından bugün yapılan açıklamaya göre Google Translate servisinin “Canlı Çeviri” özelliğininin kapsamı genişletildi. Şimdiye kadar Android tarafında sunulan özellik, artık iOS uygulamasında da kullanılabiliyor. Güncelleme kapsamında ABD, Hindistan, Meksika, Almanya, İspanya, Fransa, Nijerya, İtalya, Birleşik Krallık, Japonya, Bangladeş ve Tayland’a açılan özellik; aralarında Türkçe’nin de olduğu 70’den fazla dile destek veriyor ve kişilerin söylenenlerin çevirisini gerçek zamanlı olarak bağlı kablosuz kulaklıklarından duymasına imkan tanıyor. Dil bariyerini ortadan kaldırma konusunda çok faydalı olan özellik, özel bir yapay zeka modelinden güç alıyor ve her konuşmacının ses tonunu, vurgusunu ve konuşma ritmini olduğu gibi koruyor. Google, bunun sayesinde sohbeti takip etmenin ve kimin ne söylediğini ayırt etmenin daha kolay hale geldiğini belirtiyor.

Google Translate servisinin “Canlı Çeviri” özelliği daha fazla kişiye açıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Grafana Dashboards for Non-Prod Environment Observability: Cost + Performance in One View

Grafana Dashboards for Non-Prod Environment Observability: Cost + Performance in One View

Non-production environments are the most expensive things nobody talks about. Flexera’s 2023 State of the Cloud report puts non-prod at 30–40% of total cloud spend for mature engineering organizations. Yet most teams have zero observability into those environments: no cost tracking, no idle detection, no accountability.

The fix isn’t another tool. You already have Prometheus and Grafana. The missing piece is wiring cost data into the same dashboard your engineers check every morning.

This article shows how to build a single Grafana dashboard that surfaces both environment health (CPU, memory, pod status) and real-time dollar cost, per namespace, per environment, per hour. When an engineer opens the staging dashboard and sees “this cluster cost $89 today and is 4% utilized,” they act.

The Split-Screen Problem

Right now, understanding non-prod environments requires opening at least three things: the cloud billing console for cost, Grafana for performance, and kubectl or Lens for pod status. These tools don’t talk to each other. Cost data in AWS Cost Explorer is delayed by 24–48 hours. Grafana shows real-time utilization but has no dollar context. Non-prod namespaces rarely appear in either.

The result is that nobody knows what non-prod costs in real time. Idle clusters run overnight, on weekends, and during holidays. Not because engineers don’t care, but because the signal that would prompt action doesn’t exist.

The architecture we’re building collapses these three into one Grafana dashboard backed by Prometheus.

What You Need in Prometheus First

The cost dashboard runs on two data sources that you likely already have: kube-state-metrics and cAdvisor (bundled with kubelet). kube-state-metrics exposes over 100 Kubernetes object metrics: pod phase, container resource requests and limits, node allocatable capacity. cAdvisor provides real-time CPU and memory consumption.

Neither exposes dollar cost directly. That requires a recording rule that computes hourly cost per namespace from first principles.

The key metrics you need from kube-state-metrics:

Metric What It Measures Used For
kube_node_status_allocatable CPU/memory available on each node Cost denominator
kube_pod_container_resource_requests CPU/memory requested per container Cost allocation
kube_pod_info Pod-to-namespace mapping Aggregation by team
kube_node_labels Node labels (instance type, zone) Price lookup
container_cpu_usage_seconds_total Actual CPU consumption Utilization %

Recording rules are non-negotiable. Raw PromQL cost calculations across all pods and nodes are slow, taking 2–4 seconds at dashboard refresh. A recording rule pre-computes hourly cost every 5 minutes, reducing query time to under 50 milliseconds.

Building the Cost Allocation Formula

The cost allocation model we use is derived from OpenCost’s specification, adapted for on-demand pricing. The core idea: a container’s cost equals the fraction of node resources it requests, multiplied by the node’s hourly price.

For CPU:

container_hourly_cost_cpu = (cpu_request / node_allocatable_cpu) × node_hourly_price

For memory, the same formula applies with memory units. The total container cost takes whichever resource is the binding constraint: the max of CPU and memory allocation fractions. This prevents double-counting on multi-tenant nodes.

For an 8-node staging cluster running t3.large instances on AWS (us-east-1), the math looks like this:

Namespace CPU Requested Memory Requested Hourly Cost Daily Cost
staging-api 3.2 cores 8 Gi $2.14 $51.36
staging-db 2.0 cores 16 Gi $1.87 $44.88
staging-workers 1.5 cores 4 Gi $0.95 $22.80
staging-infra 0.8 cores 2 Gi $0.48 $11.52
Total 7.5 cores 30 Gi $5.44 $130.56

The Prometheus recording rule that produces cost_per_namespace_hourly aggregates these calculations across all containers in a namespace and stores the result as a time series. This time series is what powers every cost panel in the dashboard.

One practical note on pricing: hardcode your node’s on-demand hourly price as a Prometheus label or a Grafana variable. If you use reserved instances or savings plans, use the effective hourly rate instead of on-demand. Otherwise you’ll overstate cost and confuse engineers.

Designing the Dashboard Layout

The dashboard has three rows. The top row is stat panels: the numbers engineers see in 3 seconds. The middle row is time series: trends over the past 24 hours. The bottom row is a table: the full namespace breakdown with sortable columns.

Panel specifications:

Panel Type Data Source Purpose
Today’s Total Cost Stat sum(cost_per_namespace_hourly) * 24 Instant cost awareness
Average CPU Utilization Stat avg(container_cpu_usage / cpu_request) Idle health signal
Cost by Namespace (24h) Time series cost_per_namespace_hourly Spot when cost spiked
CPU Utilization by Namespace Time series container_cpu_usage / cpu_request Correlate with cost
Namespace Cost Breakdown Table joined query Full accountability view

Set the dashboard’s time range default to Last 24 hours with a 15-minute auto-refresh. The cost panels update every 5 minutes (matching the recording rule interval), so finer refresh gives no new data but wastes browser cycles.

Use Grafana’s threshold feature on the stat panels. Color the idle percentage panel green below 30%, yellow from 30–70%, red above 70%. That means the environment is mostly idle, a visceral signal that doesn’t need explanation.

For the namespace table, add a column that shows hours since last active using time() - last_active_timestamp. If a namespace has had zero HTTP traffic and under 5% CPU for more than 2 hours, flag it as idle. Engineers can sort by this column and immediately see what’s safe to shut down.

The Idle Detection Row

Add a fourth row: idle environment detection. This is the dashboard’s most actionable panel.

Idle detection requires two signals, not one. Low CPU utilization alone is ambiguous: a batch job looks idle between runs. Pair it with inbound request rate. An environment is idle when both CPU utilization is under 10% and request rate is under 0.1 requests per second for a sustained window of 2 hours.

Display this as a state timeline panel: one row per namespace, green for active, red for idle. This gives immediate visual context across all environments simultaneously. An SRE opening the dashboard sees in 5 seconds which namespaces have been red all morning.

Wire a Grafana alert to this panel. When a namespace stays idle for 2 hours, send a Slack message: staging-api has been idle for 2h 15m. Current cost: $4.28. Shut it down? Include a one-click link to a runbook or automation trigger. That message converts observability into action.

From Dashboard to Action

The dashboard does one thing: make the cost of inaction visible. What teams do with that visibility falls into two patterns.

Manual response: An engineer sees the idle flag, runs a teardown script, restarts the environment before the next test run. This works for small teams with high ownership. It fails at scale. Someone is always on leave, someone always forgets.

Automated scheduling: Tools like ZopNight use the same signals (idle threshold + schedule) to automatically suspend non-prod environments overnight and restart them before business hours. The Grafana dashboard becomes the proof layer: engineers see the cost-before and cost-after, which makes the automation’s value concrete rather than theoretical.

Approach Avg. Daily Savings Engineer Effort Reliability
No action (baseline) $0 0h N/A
Manual teardown $62 45 min/day Low, depends on memory
Automated scheduling $89 15 min/week High, runs without intervention

The numbers come from the same cluster we modeled earlier: an 8-node t3.large staging cluster running 24/7. Automated scheduling eliminates 16 hours of idle runtime per day (8pm–8am) and captures weekend spend entirely. The dashboard makes that $89/day saving visible and attributable, which is what gets the automation prioritized and kept running.

Build the dashboard first. The Prometheus data is already there. The recording rules take 20 minutes to write. The Grafana panels take an afternoon. Once engineers see live cost next to live utilization, the conversation about what to automate changes. You stop arguing about whether non-prod costs matter and start deciding what to do about it.

🔁 Terraform Variables, Outputs & State — Make Your Code Reusable (Part 4)

In the previous post, you deployed your first EC2 instance using Terraform.

That was a huge step.

But if you look at your code now, you’ll notice something:

👉 Everything is hardcoded
👉 It’s not reusable
👉 It’s not scalable

Let’s fix that.

🎯 What You’ll Learn

In this guide, you’ll understand:

  • How to use variables
  • How to output useful data
  • How Terraform tracks infrastructure (state)

These are core concepts used in real-world DevOps projects.

🔁 Why Variables Matter

Right now, your code probably looks like this:

instance_type = "t2.micro"

This is fine for learning — but not for real projects.

👉 What if you want:

  • different instance types for dev vs production?
  • reusable code?

🔹 Step 1 — Create Variables

Create a new file:

touch variables.tf

Add:

variable "instance_type" {
  default = "t2.micro"
}

🔹 Step 2 — Use Variables in Your Code

Update your main.tf:

resource "aws_instance" "web_server" {
  ami           = "ami-xxxxxxxxxxxx"
  instance_type = var.instance_type

  tags = {
    Name = "terraform-server"
  }
}

👉 Now your code is flexible.

🔹 Step 3 — Override with terraform.tfvars

Create:

touch terraform.tfvars

Add:

instance_type = "t3.micro"

👉 Now you can change behavior without editing code

📤 Outputs — See What Terraform Created

Sometimes you want to know:

👉 What is the public IP of my EC2?

Create:

touch outputs.tf

Add:

output "instance_public_ip" {
  value = aws_instance.web_server.public_ip
}

After running:

terraform apply

You’ll see:

instance_public_ip = 18.xxx.xxx.xxx

🧠 Terraform State — The Brain of Terraform

Terraform stores everything in:

terraform.tfstate

This file tracks:

  • what resources exist
  • their IDs
  • their current state

🔍 Inspect Your State

Run:

terraform state list

Example output:

aws_instance.web_server

🔎 Deep Dive

terraform state show aws_instance.web_server

👉 You’ll see full details of your EC2.

⚠️ Important Insight

Terraform doesn’t query AWS every time.

👉 It relies on state file

That’s why state is critical in real systems.

💡 DevOps Insight

Right now, your setup is:

Local state → terraform.tfstate

This works for learning.

But in real teams:

❌ Not safe
❌ Not shareable

👉 In the next post, we’ll fix this using:

  • S3 backend
  • DynamoDB locking

🎯 What You Just Learned

  • How to use variables
  • How to make Terraform reusable
  • How outputs work
  • How Terraform state works

💡 Final Thought

You are no longer just writing Terraform.

You are now:

👉 designing reusable infrastructure

That’s the difference between beginner and real DevOps.

👨‍💻 About the Author

Hi, I’m Ahkar — sharing DevOps, AWS, and Infrastructure knowledge to help others grow 🚀

I publish bilingual content (Myanmar 🇲🇲 + English 🇺🇸) focused on real-world cloud learning.

🌐 Blog: https://mindgnite.com

If you found this helpful, consider following for more Terraform & DevOps content 🔥

📚 Terraform Learning Series

  • Part 1: Why Terraform
  • Part 2: Setup Guide
  • Part 3: First EC2 Deployment
  • Part 4: Variables, Outputs & State (this post)
  • Part 5: Modules & Remote Backend (coming next)

👉 Follow to continue the journey 🚀