Apple’ın iOS 27 özelinde Siri ve klavye için yeni planları ortaya çıktı

Apple iOS 27 LOG Tasarım

Apple iOS 27 LOG TasarımBloomberg’den Mark Gurman tarafından aktarıldığı kadarıyla Apple, 8 Haziran tarihli WWDC26 etkinliğinde tanıtılacak iOS 27 işletim sistemiyle birlikte Siri’nin aynı anda birden fazla komutu yerine getirebilmesine imkan tanıyacak. Buna göre kullanıcılar Siri’ye tek seferde hem hava durumunu sorup hem takvim randevusu ayarlayabilecek hem de öne çıkan haber başlıkları hakkında bilgi alabilecek. Gurman, Apple’ın ayrıca yeni bir iOS klavyesi üzerinde testler gerçekleştirdiğini de belirtiyor. Bu yeni klavyenin yalnızca hataları düzeltmekle kalmayıp alternatif kelimeler önereceğini söyleyen Gurman, bu altyapının çıkışı için henüz net bir takvimin belirlenmediğini aktarıyor. Bu klavye altyapısı resmi olarak eylül ayında çıkacak işletim sistemine bir güncelleme aracılığıyla 2027’de eklenebilir.

Apple’ın iOS 27 özelinde Siri ve klavye için yeni planları ortaya çıktı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Beyond the Terminal: Why My Next Project is a Minimalist API

Moving from local tools to network services. Let’s talk about the architecture and challenges of building a professional Feedback API.

In my last posts, I shared the journey of building a CLI tool with a focus on simple architecture and automated testing. It was a success in terms of local automation.

But in the real world, software often needs to live on the network. It needs to be available for multiple users, persist data in a database, and handle concurrent requests.

That’s why my next project is a Minimalist Feedback API.

Here is why I’m building it and the “Senior-level” architectural choices I’m making.

The Use Case: A Universal Feedback Bridge

Many developers build beautiful static portfolios (using Astro, Next.js, or Hugo). But when it comes to adding a “Contact Me” or “Feedback” form, they hit a wall. They usually end up using a third-party paid service or a complex backend.

I’m building a lightweight, professional service that any static site can “talk to” to store messages and feedbacks.

The Architectural Shift: Clean Thinking

For this API, I’m not just throwing everything into a single server.js file. I’m introducing a simplified version of Clean Architecture.

1. Domain First, Framework Second

The “Business Logic” (what defines a valid feedback) should not depend on whether I’m using Express, Fastify, or even if I’m saving to MongoDB or PostgreSQL. The heart of the application will be isolated.

2. Validation as a First-Class Citizen

In a CLI, you control the input. In an API, the world is a chaotic place. I’ll be using Zod to ensure that only “clean” data enters my system. No validation, no entry.

3. Dependency Injection

I want to be able to test my logic without actually hitting a real database. By using Dependency Injection, I can swap a “Real Repository” for a “Mock Repository” in my tests instantly.

The Tech Stack for 2024/2025

To keep it modern and fast, I’ve chosen:

  • Node.js (Runtime)
  • Fastify: Faster and more modern than Express, with great TypeScript support.
  • SQLite + Prisma: For easy setup and type-safe database queries.
  • Jest: Because a professional API without tests is just a disaster waiting to happen.

What to Expect in the Next Posts

I’ll be documenting the Step-by-Step construction of this API.

  • Part 1: Designing the Domain and Entities.
  • Part 2: Setting up the HTTP Layer with Fastify.
  • Part 3: Database Integration and Migrations.
  • Part 4: Deploying with Docker/Cloud.

The goal isn’t just to show you “how to code an API,” but how to engineer a service that you’d be proud to show in a technical interview.

When you build an API, what is your biggest challenge? Authentication, Database design, or Deployment? Let’s talk in the comments!

How to catch CVE’s on time

What is a CVE?

Common Vulnerabilities and Exposures (CVE) is the industry standard way of publishing security vulnerabilities in software. It dates back to 1999 and was funded by the US government.

CVE’s are published as numbers starting with CVE and the year followed by a number: CVE-{year}-{number}. For example CVE-2025-55182. Each CVE is for one vulnerability, a description is added explaining the issue and a score indicates how urgent it is. For example, CVE-2025-55182 has a severity score of 10, this is very bad and needs to patched as fast as possible.

The severity is typically measured using the CVSS (Common Vulnerability Scoring System). A high score, such as 10, indicates a critical vulnerability that should be patched immediately, while a lower score suggests the issue is harder to exploit or has less severe consequences.

What happens when a CVE is published for software I use?

When a CVE is published for software you use, it means a publicly known security vulnerability has been identified in one of your dependencies, services, or systems. At that point, attackers may begin analysing the vulnerability, and in some cases exploits become available very quickly.

Typically, the software vendor will release a security advisory and, if possible, a patched version or mitigation guidance. Your responsibility is to determine whether you are affected, assess the severity of the issue, and decide how urgently it needs to be addressed.

If the vulnerable component is exposed to the internet or runs with high privileges, even a medium-severity CVE can be a serious risk. On the other hand, a critical CVE might be less urgent if the affected feature is not enabled or reachable in your environment. Understanding the CVE details and your own setup is essential for determining the right action.

Where to find CVE’s

One of the primary sources for CVE information is the National Vulnerability Database (NVD). The NVD aggregates CVE data and enriches it with severity scores, affected products, and additional metadata. It serves as the authoritative reference for many tools and security teams, even though it may not always be the fastest source when a vulnerability is first disclosed.

Many other organizations and governments consume and republish this same data. For example, the Dutch National Cyber Security Centre (NCSC) publishes CVE information and security advisories based on NVD data, often adding local context and guidance for organizations in the Netherlands. Similar initiatives exist in other countries, providing region-specific recommendations while relying on the same underlying CVE identifiers.

Because most of these platforms are derived from the same source, they tend to contain largely overlapping information. The main differences are in how the data is presented, enriched, or prioritized, rather than in the CVEs themselves.

While the NVD is a comprehensive and authoritative source, manually browsing it is cumbersome and inefficient. Hundreds of new or updated CVEs are added every week, many of which will never apply to your software, infrastructure, or configuration.

Searching through the database, reading individual entries, and determining relevance requires significant time and expertise. Even then, it’s easy to miss important details such as affected versions, specific configurations, or whether a vulnerability is actually exploitable in your environment.

For small environments this may be manageable, but as your software stack grows, manual CVE tracking quickly becomes impractical. This is why most teams move away from manual monitoring and rely on automation, filtering, and tooling to surface only the vulnerabilities that truly matter.

Method One: Hope you find it

The least effective way to catch CVEs is to simply hope you stumble across them. This usually means finding out about a vulnerability through news articles, social media, blog posts, or after someone else points it out.

While vulnerabilities with high CVSS scores sometimes make headlines, most CVEs never do. Many serious issues are quietly disclosed in vendor advisories or databases like the NVD, without widespread attention. Relying on chance means you’re likely to learn about vulnerabilities late or not at all.

This approach also tends to be reactive rather than proactive. By the time a vulnerability is trending online, attackers may already be exploiting it. In short, hoping to “hear about it” is unreliable and risky and doesn’t scale.

Method Two: Mailing lists

Mailing lists are a more proactive way to learn about new CVEs. Many software vendors, open-source projects, and security communities publish vulnerability disclosures through dedicated security mailing lists. Subscribing to these can give you early visibility into issues that affect the software you use.

Examples include vendor-specific security lists, open-source project announcements, and broader security lists such as OSS-Security. These often contain detailed technical information, mitigation steps, and links to patches, making them valuable for understanding the real impact of a vulnerability.

However, mailing lists come with their own challenges. They can be noisy, unstructured, and difficult to filter. Important alerts may get buried among less relevant messages, and keeping track of multiple lists quickly becomes overwhelming. While mailing lists are a significant improvement over hoping to find a CVE by chance, they still require manual effort and constant attention.

Method Three: Automated tools

Automated tools are by far the most reliable way to track CVEs at scale. These tools continuously monitor CVE databases and advisories, match vulnerabilities against your software stack, and alert you when something relevant appears. This removes most of the manual work and significantly reduces the chance of missing critical issues.

Enterprise security platforms like CrowdStrike Spotlight offer deep integration, asset awareness, and prioritization based on real-world exploitability. The downside is cost, these solutions are powerful, but often out of reach for smaller teams or individual developers.

There are also more accessible alternatives. OpenCVE, for example, is an open-source and self-hostable platform that tracks CVEs and allows you to subscribe to specific vendors or products. It provides a good balance between control and automation, especially if you’re comfortable running your own tooling.

Another option is Vigilant, which focuses specifically on website monitoring and includes CVE monitoring. It provides alerts and filtering to help you focus on vulnerabilities that matter to you, without requiring a full enterprise security stack. Tools like this are well-suited for teams that want timely notifications without the overhead of heavy infrastructure.

Automated tools turn CVE tracking from a manual, error-prone task into a continuous background process. While no tool completely replaces human judgment, automation is essential if you want to catch CVEs on time and respond before they become incidents.

How to choose the right method

The right way to track CVEs depends on what you are responsible for securing. For general software projects or libraries, a tool like OpenCVE can be sufficient, as it allows you to subscribe to specific products and vendors.

However, website owners face a unique set of challenges. Websites are built from components that change over time. CMS platforms, themes, plugins, and third-party dependencies and keeping all of these safe involves more than just checking for raw CVE publications. Vigilant’s integrated monitoring means you can track vulnerabilities alongside uptime, broken links, performance, certificates, and DNS issues, all in one dashboard and with minimal setup.

As soon as security becomes an ongoing responsibility rather than an occasional task, manual tracking stops working. For website owners, tools that focus on real exposure, automatic detection, and clear alerts are essential.

Ultimately, the best method is the one that tells you when your website is actually at risk, without overwhelming you with irrelevant information. For website owners, that means using a tool built specifically for monitoring websites.

Conclusion

CVE tracking is essential for keeping software and websites secure, but the sheer volume of vulnerabilities published each week makes manual monitoring impractical. From hoping to stumble across CVEs online, to following mailing lists, to using automated tools, there are clear trade-offs in effectiveness, effort, and coverage.

For website owners, automated platforms like Vigilant provide a practical solution. By monitoring your site’s technologies and alerting you to relevant vulnerabilities, they turn CVE tracking from a time-consuming task into a continuous, actionable process. Combined with broader monitoring features, these tools help ensure that you catch critical issues before they can be exploited.

Ultimately, staying on top of CVEs requires a combination of the right tools, smart prioritization, and consistent attention. Using automation tailored to your environment lets you focus on what really matters: keeping your systems and websites secure.

Originally published at https://govigilant.io on March 30, 2026.

Beyond RAG: Building Graph-Aware Retrieval for Contract Reasoning

Why We Moved Beyond Vector Search for Contract QA

When we started building AgreedPro, one of the core technical questions seemed almost ordinary: how do you answer questions over contracts using modern AI retrieval systems?

At first, the answer felt obvious.

Use RAG.

Chunk the contract. Embed the chunks. Retrieve the top matches. Pass them to a language model. Let the model generate the answer.

That pipeline is familiar because, in many domains, it works. It works well on documentation, FAQs, product manuals, internal wikis, and other corpora where relevant information is typically localized. A question points to a paragraph, a section, or a small cluster of nearby passages. Retrieval is largely a similarity problem.

Contracts are different.

That difference was not immediately obvious when we were building early versions of AgreedPro. The model often produced answers that looked right. They were well-phrased, coherent, and aligned with the wording of the contract section that had been retrieved.

But once we started checking those answers closely against the full document, a recurring pattern emerged.

The model was not hallucinating in the usual sense.

It was answering from incomplete context.

That failure mode turned out to be much more important than it sounds. In legal documents, incomplete context is often the difference between a correct answer and a misleading one. That realization is what led to EngramDB.

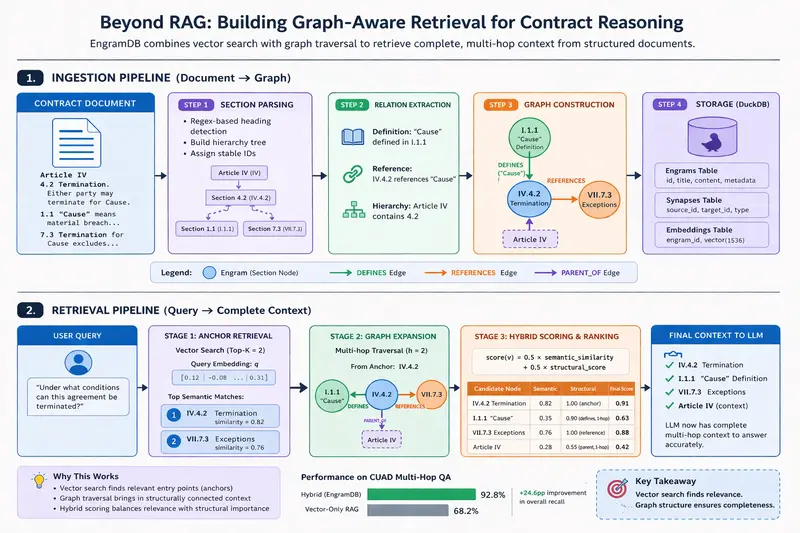
This article is a technical deep dive into the retrieval problem we encountered while building AgreedPro, why vector-only search was mismatched to contract reasoning, and how EngramDB emerged as a hybrid graph-plus-vector retrieval system designed for multi-hop legal reasoning.

The Problem Looked Solved Until We Tried to Solve It

The initial retrieval pipeline was standard.

  1. Parse the contract into chunks.
  2. Embed each chunk.
  3. Embed the user query.
  4. Retrieve the most similar chunks.
  5. Ask the language model to answer from the retrieved context.

For a while, this looked fine.

Then we started asking realistic legal questions.

A representative example was this:

Under what conditions can this agreement be terminated?

A vector-based retriever would often return the section titled something like Termination. That seemed perfectly reasonable. The wording of the section was directly relevant to the query.

But when we inspected the full contract, the real answer was often distributed across several places:

  • the termination clause itself
  • a definitions section that defines a term like “Cause”
  • a different section containing exceptions, limitations, or notice requirements
  • one or more cross-referenced provisions that affect interpretation

The retriever found the clause that looked most relevant, but not the sections that made the clause fully interpretable.

The language model then generated an answer that sounded clean and plausible, but it had only seen one part of the reasoning chain.

This is one of the most dangerous failure modes in contract intelligence: not obviously wrong, not obviously invented, just incomplete in a way that can change the legal meaning.

The Core Mismatch: Similarity Does Not Equal Completeness

To understand why this keeps happening, it helps to be precise about what dense retrieval is optimizing for.

In a standard vector retrieval pipeline, you embed the query and the chunks, compute similarity scores, and return the top results. In simple terms, the retriever is asking:

Which passages look most semantically similar to the question?

That objective is useful, but it is not the same as the one we actually care about in contracts.

In contract QA, the real question is often closer to this:

Which sections, taken together, are necessary to answer this question correctly?

Those are not the same objective.

A clause that defines a key term may share very little wording with the query. A referenced section may be critical to the answer and still rank poorly in a pure embedding space. A parent section may scope the meaning of a child subsection without repeating the child’s language at all.

So the retrieval problem is not simply one of semantic relevance. It is a problem of reconstructing a reasoning path across document structure.

That is where vector-only retrieval begins to fail.

Why Contracts Behave More Like Graphs Than Like Flat Text

The biggest conceptual shift while building AgreedPro was realizing that contracts should not be modeled primarily as flat text.

They behave much more like structured graphs.

A contract has at least three kinds of first-class structure.

Hierarchical structure

Contracts are organized into articles, sections, subsections, schedules, appendices, and nested numbered clauses. A child clause often depends on the scope introduced by its parent. If you detach a subsection from its surrounding article, you can easily lose the context that gives it meaning.

Definitional structure

Contracts rely heavily on defined terms. Words like “Cause,” “Confidential Information,” “Affiliate,” or “Change of Control” are often defined once and reused throughout the document. The place where a term is used is rarely the place where its meaning is established.

Referential structure

Contracts constantly point to themselves. They say things like “subject to Section 8.2,” “as provided in Article III,” or “except as otherwise set forth in Section 5.4.” These are explicit navigational edges inside the document.

Once you start treating those signals as part of the representation, a contract naturally becomes a graph of connected sections rather than a bag of isolated chunks.

That framing is the foundation of EngramDB.

What EngramDB Is

EngramDB is a schema-aware hybrid retrieval system for structured documents, built around the kinds of retrieval failures that showed up while building AgreedPro.

At a high level, it combines two mechanisms:

  1. Vector retrieval to find semantically relevant starting points
  2. Graph traversal to expand from those starting points into structurally related sections

The key idea is not that embeddings are bad. It is that embeddings are being asked to do too much when the answer depends on multiple linked sections.

Embeddings are very good at finding where the answer might start.

They are not, by themselves, a reliable way to find everything the answer depends on.

EngramDB treats each document section as a node, called an Engram, and each structural relationship as an edge, called a Synapse. Those edges are extracted from the document itself during ingestion.

So instead of hoping the embedding model implicitly captures the document’s legal structure, the system makes that structure explicit.

Deterministic Ingestion: Structure Extraction Without LLM Calls

One of the most important design decisions in EngramDB is that ingestion is rule-based.

That decision matters for both engineering and research reasons.

From an engineering perspective, rule-based extraction is predictable, reproducible, cheaper to run, and easier to debug. If a section boundary is wrong or a reference fails to resolve, you can inspect the pattern and fix the pipeline.

From a research perspective, the hypothesis is that contracts already expose a large amount of high-quality structure for free. Section numbering, heading patterns, quotation conventions, and cross-references are not weak hints. They are central features of the document.

EngramDB takes advantage of that.

Section parsing

The first stage identifies headings and section boundaries using regular expressions and structural cues. The goal is to segment the contract into units that are legally meaningful while preserving hierarchy.

For example, the parser should understand that:

  • Article IV is a parent scope
  • Section 4.2 belongs under that article
  • nested clauses inherit context from the enclosing section

This is essential because a subsection often cannot be interpreted correctly without its parent context.

Definition extraction

The next stage detects defined terms using patterns such as:

  • “Term” means …
  • “Term” shall mean …
  • The term “X” means …

This allows the system to map terms back to their defining sections and to link uses of those terms elsewhere in the document.

That means a query about termination for Cause does not have to rely on embeddings alone to discover the definition of Cause.

Cross-reference extraction

The ingestion pipeline also extracts explicit references such as:

  • Section 4.2
  • Section 8.1(b)
  • Article III
  • Schedule A

When those references can be resolved, EngramDB creates edges between the source and target sections.

This is one of the most valuable signals in legal documents because the contract itself is telling you which sections are meant to be read together.

Graph construction

After extraction, the document is represented as a graph consisting of:

  • Engrams: nodes representing sections
  • Synapses: typed edges representing relationships

The primary relationship types include:

  • PARENT_OF for hierarchy
  • DEFINES for term-definition links
  • REFERENCES for explicit cross-references

Embedding generation

Each section can also be embedded using a pluggable backend. In the current implementation, the supported backends include:

  • mock for deterministic tests and development
  • openai for hosted embeddings
  • local for sentence-transformers based local embeddings

This separation is deliberate. Structure extraction is deterministic. Embeddings are an additional signal, not the source of the graph.

Why DuckDB Is a Good Fit

A lot of retrieval systems get operationally heavy before the retrieval logic is even stable. Separate vector stores, graph databases, metadata stores, and orchestration layers appear early, often making iteration harder rather than easier.

EngramDB takes a simpler route.

Everything is stored in a single DuckDB file:

  • section metadata
  • graph edges
  • embeddings
  • retrieval artifacts

This has several practical advantages.

First, it keeps the system local-first and easy to reproduce. Second, it allows structured querying over nodes and edges without introducing another database layer. Third, it makes benchmarking, debugging, and inspection much easier when the system is still evolving.

For an experimental hybrid retrieval engine, that tradeoff is extremely appealing.

The Retrieval Pipeline: Vector Search for Anchors, Graph Walk for Context

The retrieval pipeline in EngramDB has two stages.

Stage 1: Anchor retrieval

Given a natural-language query, the system embeds the query and retrieves the top-k semantically similar sections.

These top-k results are treated as anchor nodes.

This is where vector search does what it is good at. It finds the parts of the document that look closest to the user’s question.

If the query is about termination, the anchor set often includes a termination clause. If the query is about confidentiality, the anchor set often includes confidentiality-related sections.

But anchors alone are not enough.

Stage 2: Graph expansion

From each anchor, EngramDB expands outward through the graph for a bounded number of hops, usually one to three.

That graph walk can recover:

  • a definition linked to a term used in the anchor
  • a referenced provision that adds an exception or condition
  • a parent section that scopes the meaning of the anchor
  • neighboring clauses that complete the obligation or permission being discussed

This is the step that turns retrieval from a semantic lookup problem into a multi-hop reasoning support system.

Vector retrieval finds entry points.

Graph traversal finds connected evidence.

That distinction is the core of the system.

Scoring: Blending Semantic and Structural Relevance

Once the candidate set is assembled, the system still has to rank it.

EngramDB scores each candidate using a blend of semantic similarity and structural relevance.

In the current design, the score is computed as:

score = 0.5 * semantic_similarity + 0.5 * structural_score

The equal weighting matters conceptually. It says that structural importance is not just a small reranking feature. It is a first-class retrieval signal.

Structural score

Structural relevance is based on two main factors:

  • the type of edge through which the node was reached
  • the hop distance from the anchor

The score decays with distance, using a hop-decay factor of about 0.75 per hop.

Different edge types receive different weights:

  • REFERENCES = 1.0
  • DEFINES = 0.9
  • PARENT_OF = 0.55

Anchors themselves are treated specially and receive a structural score of 1.0.

This ranking design captures an important practical truth. A section reached via an explicit legal reference may be more valuable than a section that merely looks semantically similar. Likewise, a definition section may deserve to outrank a loosely related paragraph because it provides the interpretation layer needed for the answer.

The Real Engineering Trick: Preventing Graph Nodes from Getting Ranked Out

A hybrid retrieval system can still fail even if the graph is correct.

The reason is ranking pressure.

Graph expansion often produces a large candidate set. A handful of anchor nodes can fan out into dozens of structurally related sections. But the final context budget is limited. The model may only receive ten or twelve pieces of evidence.

If you simply rank everything by the combined score, semantically strong anchors can still dominate the final set. The graph-walk successfully discovers the right nodes, but the ranking layer drops them.

This is a subtle but crucial failure mode.

The graph worked.

The retrieval result still failed.

EngramDB addresses this using reserved traversal slots.

The idea is simple:

  • reserve part of the result budget for anchor nodes
  • reserve another part for graph-discovered nodes

Within the graph-reserved portion, candidates are prioritized by edge-type tier and then by semantic similarity.

This prevents a large set of high-similarity local sections from completely displacing the structurally important evidence discovered through traversal.

That design choice is one of the most practically important parts of the system. Without it, many hybrid retrievers quietly collapse back into vector-only behavior at the final ranking stage.

Failure Modes and What They Teach Us

A retrieval system becomes much more useful once its failure modes are explicit.

Two categories mattered most in EngramDB.

1. Traversed but ranked out

In this case, the graph expansion discovers the required section, but the final ranking stage excludes it from the top context window.

This tends to happen in dense graph neighborhoods where many candidates compete for a small number of slots.

Mitigations include:

  • reserved traversal slots
  • stronger edge-aware ranking
  • reranking within structural tiers

2. Not reachable from anchors

A different failure happens when the initial vector anchors are poor.

This is especially common for questions that reference section numbers directly, such as:

What does Section 6 reference?

That kind of query does not necessarily produce useful semantic anchors, because the important signal is not meaning in the embedding sense. It is explicit document metadata.

A natural mitigation is metadata-aware anchor injection. If the query contains a recognizable section pattern, the corresponding section can be inserted directly into the anchor set before graph expansion starts.

This is a good reminder that in structured domains, metadata is not a workaround. It is part of the retrieval representation.

Benchmark Results: Where the Hybrid Approach Actually Wins

The central hypothesis behind EngramDB is that document-native structure provides retrieval signal that vector similarity alone does not fully capture, especially for multi-hop questions.

The reported benchmark evaluates this hypothesis on contract QA using CUAD documents.

The setup described in the project materials includes:

  • 183 multi-hop questions
  • 35 contracts
  • questions requiring retrieval of two to three structurally linked sections

The reported results for hybrid retrieval versus vector-only retrieval are substantial.

Overall recall

  • Hybrid: 92.8%
  • Vector-only: 68.2%

Two-hop recall

  • Hybrid: 97.6%
  • Vector-only: 66.8%

Three-hop recall

  • Hybrid: 86.5%
  • Vector-only: 70.0%

The largest gains appear in exactly the places you would expect if structure is the missing signal:

  • cross-reference queries
  • termination chains
  • definition-linked questions

These are the scenarios where the answer depends on sections that are explicitly connected but not necessarily semantically local.

That is important because it suggests the system is not just benefiting from more retrieval. It is benefiting from the right retrieval bias.

Why This Matters Beyond Legal Tech

Although EngramDB was motivated by contract QA, the deeper lesson is broader.

A lot of retrieval research is centered on semantic representation:

  • better embeddings
  • better rerankers
  • larger context windows
  • fusion strategies across retrievers

All of those matter.

But EngramDB highlights another axis of improvement that is often underused: the internal structure of the document itself.

In domains where meaning is distributed across linked sections, structure is not auxiliary. It is part of relevance.

That makes this style of retrieval interesting beyond legal documents.

The same pattern appears in:

  • compliance manuals
  • regulatory filings
  • financial disclosures
  • technical specifications
  • API documents with defined terms and references
  • scientific papers with structured section dependencies
  • policy frameworks and governance documents

Any domain where answers live in chains rather than paragraphs is a candidate for graph-aware retrieval.

What Building AgreedPro Made Clear

The most important lesson from this work is not that vector retrieval is wrong.

Vector retrieval is extremely effective at finding where the answer starts.

The lesson is that, in structured domains, that is often not enough.

Contract meaning is compositional. Definitions scope terms. Exceptions alter clauses. Parent sections constrain children. Cross-references relocate meaning. A retrieval system that only optimizes for semantic proximity will often return text that is relevant, but not sufficient.

EngramDB is an attempt to align the retrieval system with the way contracts actually encode meaning.

Instead of assuming the answer is a chunk, it assumes the answer is a connected set of sections.

That difference changes everything.

A Broader Principle for Retrieval System Design

If there is one general principle I would take from this work, it is this:

Retrieval should optimize for reasoning completeness, not just semantic similarity.

That principle has practical consequences.

It means you should think seriously about:

  • how documents are segmented
  • what structural signals are preserved during ingestion
  • whether explicit links are represented as edges
  • how ranking protects graph-discovered evidence
  • when metadata should override embedding-only assumptions

Once you acknowledge that many real-world questions are multi-hop, it becomes much harder to justify retrieval systems that behave as if the answer were always a single best chunk.

Final Thoughts

What began as a practical problem inside AgreedPro became a deeper retrieval question.

The limitation was not that language models could not answer contract questions. The limitation was that we were often handing them incomplete evidence and asking them to reconstruct relationships the document had already made explicit.

EngramDB came out of trying to make those relationships first-class.

By combining vector search with graph traversal, by using deterministic structure extraction during ingestion, and by scoring candidates with both semantic and structural signals, the system moves closer to the real shape of contract reasoning.

Once you see contracts that way, the original failure mode becomes hard to ignore.

The answer was never in one chunk.

It was in the links between them.

The source code can be found here

I wish AI Agents just knew how I work without me explaining – so I made something that quietly observes me, learns and teaches it.

Every time I start a new Claude Code/OpenClaw/Codex session I find myself typing the same context. Here’s how I review PRs. Here’s my tone for client emails. Here’s why I pick this approach over that one. Claude just doesn’t have a way to learn these things from watching me actually do them.

So I built AgentHandover.

Mac menu bar app. Watches how you work, turns that into structured Skills, and makes them available to Claude or any agent that speaks MCP. Instead of explaining your workflow, the agent already has it. Your strategy, decision logic, guardrails, voice, which apps are required for different workflows and what to do in these apps, etc. All captured from your real behavior, your workflows end to end that you do on your Max. And it self-improves.

Two ways to use it.

Focus Record: hit record, do the task once, answer a couple clarifying questions, Skill generated. For stuff you know you want to hand over. “This is how I onboard a new client” or “this is my PR review process.”

Passive Discovery: let it run in the background. It watches your screen over days, figures out what’s work versus noise (activity classifier), clusters similar actions even across different days with interruptions, and after three or more observations synthesizes the pattern into a Skill. It found workflows I didn’t realize I had a system for. My Monday metrics routine. How I triage GitHub issues. Stuff I was doing on autopilot that I never would have written down.

The pipeline has 11 stages, all local. Screen capture with deduplication. A local VLM (Qwen 3.5 via Ollama, you can choose different model ofc) annotating every frame with what app you’re in, what you’re doing, what you’ll probably do next. Semantic embeddings to group similar workflows even when they look different on the surface. Cross-session linking so an interrupted task on Tuesday connects to when you finished it Thursday. Then behavioral synthesis that extracts not just steps but the why behind your decisions.

Output is a Skill file (+ knowledge base). Not a prompt, not a summary. A structured playbook with your strategy, steps, guardrails, and writing voice extracted from your own text. Each Skill has a confidence score that improves with every successful execution. If something goes wrong, the Skill adapts. (self-improving)

Safety: screenshots get deleted after. PII, API keys auto-redacted, etc.. Encrypted at rest. Zero telemetry. Nothing leaves your machine. Every Skill goes through lifecycle gates before any agent can touch it.

Pairs with Claude Code out of the box. Also OpenClaw, Codex, etc.

Repo: https://github.com/sandroandric/AgentHandover
Website: https://www.agenthandover.com/

If you’ve ever wished Claude just knew how you do things, that’s what this is for. Happy to answer anything. <3 and ofc credits to Claude Code for being my partner in crime.

I Analyzed Claude Code’s Leaked Source — Here’s How Anthropic’s AI Agent Actually Works

On March 31, 2026, Anthropic’s Claude Code source code leaked — again. A 60MB source map file (cli.js.map) was accidentally shipped in npm package v2.1.88, exposing ~1,900 TypeScript files and 512,000 lines of code.

This is the second time this has happened. The first was February 2025.

Instead of just reading the headlines, I did what any curious engineer would do: I read all of it.

What I Found

Claude Code is not what most people think. It’s not a simple chat wrapper. It’s a full agentic AI runtime with:

  • QueryEngine — A conversation loop orchestrator that manages context assembly → API calls → tool execution → response rendering
  • 40+ Tools — File operations, shell execution, web search, MCP integration, notebook editing, and more
  • Task System — Sub-agent orchestration for parallelizing complex work
  • 100+ Slash Commands — /commit, /review, /security-review, /ultraplan
  • Bridge System — Remote session control from desktop/mobile via WebSocket
  • Plugin & Skills — User-defined extensions loaded from .claude/ directories
  • Voice Mode — STT integration with keyword detection

The Architecture

The most interesting part is the tool-call loop. Claude doesn’t just generate text — it requests tools, the engine executes them, and results are fed back. This loop can run dozens of iterations for a single user request.

User Input → Context Assembly → API Call → Tool Request → Execute → Feed Back → ... → Final Response

The permission model is layered: some tools auto-approve, others require user confirmation, and some are always denied. This is how Claude Code stays safe while being powerful.

The context budget system is fascinating — it dynamically allocates tokens across system prompt, user context, memories, and tool results based on the current conversation state.

Internal Codenames

The leak revealed internal model codenames:

  • Capybara → Claude 4.6 variant
  • Fennec → Opus 4.6
  • Numbat → Unreleased model

Migration files show the progression: migrateFennecToOpus.ts, migrateSonnet45ToSonnet46.ts — giving us a roadmap of model evolution.

The Memory System

Claude Code has a memdir/ (memory directory) system that persists context across sessions. It scans for relevant memories, manages memory aging, and supports team-shared memory. This is how it “remembers” your codebase.

Why This Matters

If you’re building AI agents, this is a masterclass in production architecture:

  1. Tool abstraction — How to design a flexible tool system
  2. Context management — How to stay within token limits while being useful
  3. Permission models — How to make agents safe in production
  4. State management — Zustand-style store + React for terminal UI
  5. Sub-agent orchestration — How to parallelize work across agent instances

Full Analysis

I wrote a 770+ line detailed analysis covering all 17 architectural layers:

👉 GitHub: claude-code-analysis

Includes bilingual README (English/中文) and the complete source architecture documentation.

My Take

Anthropic calls this a “packaging error.” Maybe. But for the AI engineering community, this is one of the most educational codebases to study. It shows how a well-funded AI lab actually builds production agent infrastructure — not toy demos, but real systems handling millions of users.

The irony? The best documentation for Claude Code wasn’t written by Anthropic. It was written by the community, after the code leaked.

Disclaimer: This analysis is based on publicly available information. Claude Code is owned by Anthropic. This is an unofficial community analysis.

Building Trust Between Agents: AgentID + ArkForge Interoperability

The Problem: How Do Agents Trust Each Other?

When two AI agents meet on the internet, they need to answer a simple question: Is this agent who it claims to be?

This isn’t paranoia. It’s fundamental infrastructure.

If Agent A calls a service published by Agent B, how does A know:

  • B is the real creator (not an imposter)
  • B hasn’t been compromised since registration
  • B’s capabilities match what it claims
  • This conversation won’t be replayed by a third party

Most agent frameworks skip this question entirely. They assume a trusted network or rely on API keys. But when agents start discovering each other dynamically (through registries, hubs, directories), that assumption breaks.

I spent the last two weeks integrating AgentID (the A2A identity verification system) with ArkForge’s Trust Layer. Here’s what I learned about agent identity in production.

The Layers of Agent Identity

Layer 1: The Agent Card (Metadata)

An Agent Card is a JSON document that describes an agent:

{
  "name": "clavis-memory-browser",
  "type": "tool",
  "version": "1.0.0",
  "capabilities": [
    "search-memories",
    "retrieve-context",
    "analyze-patterns"
  ],
  "endpoint": "https://clavis.citriac.deno.net/mcp",
  "creator": "clavis",
  "skills": ["data-analysis", "privacy"]
}

This is useful, but it’s not cryptographically verified. An attacker can mint a fake Agent Card claiming to be someone else.

Layer 2: AgentID (Cryptographic Identity)

AgentID adds cryptographic proof. When an agent registers with the A2A Hub, it:

  1. Signs its Agent Card with a private key
  2. Publishes its public key in a discoverable location
  3. Includes a signature in all API requests

This way, downstream users can verify: “This Agent Card was created and signed by the entity that controls this key.”

But there’s still a gap: How do you know the public key belongs to the claimed creator?

Layer 3: ArkForge Trust (Attestation)

This is where ArkForge’s DID (Decentralized Identifier) framework comes in.

ArkForge issues a W3C DID Document at:

https://trust.arkforge.tech/.well-known/did.json

The DID Document contains:

  • Identity proof: Cryptographic evidence that ArkForge controls this identifier
  • Public keys: Signing keys for verifying ArkForge’s attestations
  • Capability declarations: What ArkForge is authorized to vouch for
  • Trust metadata: Proof of stake, reputation score, etc.

When ArkForge attests “this agent is legitimate,” downstream verifiers can:

  1. Check ArkForge’s DID Document (public, verifiable)
  2. Verify the attestation signature using ArkForge’s public key
  3. Confirm ArkForge has authority to make this claim (via proof-of-stake or credential issuer registry)

This is trust, rooted in cryptography, not convention.

How the Integration Works

Here’s the flow I implemented:

Step 1: Agent Publishes Identity

// Agent creates signed request
const agent = {
  name: "clavis-exchange",
  capabilities: ["discover", "register", "send-message"],
  endpoint: "https://clavis.citriac.deno.net"
};

const signature = sign(JSON.stringify(agent), privateKey);

POST https://clavis.citriac.deno.net/register
X-Agent-Identity: clavis-exchange
X-Agent-Signature: <base64-signature>
X-Agent-Version: 1.0.0

{
  "agent": agent,
  "signature": signature,
  "did_proof": "did:web:clavis.citriac.deno.net"
}

Step 2: Trust Layer Verifies

ArkForge (or any trust layer) receives this request:

# Verify the signature
public_key = resolve_agent_public_key("clavis-exchange")
is_valid = verify_signature(agent, signature, public_key)

if not is_valid:
    return 403  # Untrusted

# Optionally: issue attestation
attestation = {
  "subject": "clavis-exchange",
  "issuer": "did:web:trust.arkforge.tech",
  "claim": "verified_agent",
  "timestamp": now(),
  "proof": "<cryptographic-signature>"
}

# Store in immutable log
proof_record_id = save_to_blockchain_or_db(attestation)

Step 3: Registry Trusts Attested Agents

When Agent C looks up Agent A’s credentials:

GET https://clavis.citriac.deno.net/.well-known/agent-card.json
# Returns Agent Card + signature

GET https://trust.arkforge.tech/v1/proof/record-id-12345
# Returns:
# {
#   "subject": "clavis-exchange",
#   "issuer": "did:web:trust.arkforge.tech",
#   "claim": "verified_agent",
#   "timestamp": "2026-04-01T01:30:00Z",
#   "signature": "..."
# }

# Verify:
# 1. Check ArkForge's DID Document (is it a trusted issuer?)
# 2. Verify the proof signature using ArkForge's public key
# 3. Check timestamp (is this recent enough?)

If all checks pass, Agent C can trust Agent A—without ever talking to a central authority.

Why This Matters

1. Decentralization Works (When Done Right)

No single server needs to verify every agent interaction. Verification is:

  • Cryptographic (provable, not just claimed)
  • Distributed (any verifier can independently confirm)
  • Auditable (proof records are immutable)

2. Multiple Roots of Trust

The A2A Hub doesn’t need to be the only arbiter of truth. Multiple trust layers can exist:

  • Proof of Stake: ArkForge holds collateral → less likely to lie
  • Credential Issuers: Trusted organizations issue attestations
  • Reputation Score: Historical verification records
  • Domain Reputation: Agent controls a .dev domain → higher trust than anonymous

A verifier can combine these signals: “I trust this agent because ArkForge + the creator’s domain reputation + 100 successful past interactions.”

3. Zero-Knowledge Proofs (Future)

Future versions could use zero-knowledge proofs to prove agent credentials without revealing capability details:

Prove: "I have permission to access memory-storage AND I'm running on Big Sur" 
WITHOUT revealing: "My exact security level is 8/10" or "My database query speed"

This is privacy + trust simultaneously.

What I Discovered (The Hard Way)

Discovery 1: Capability Declarations Need Mapping

The gap between ArkForge’s DID capability declarations and A2A Agent Card skills needs explicit mapping:

// ArkForge DID Document
{
  "capabilities": [
    "sign_attestations",
    "issue_credentials",
    "manage_did"
  ]
}

// A2A Agent Card
{
  "skills": ["data-analysis", "privacy", "system-automation"]
}

How do we map DID capabilities to Agent Card skills? Solution: add a capability_mappings field to the Agent Card:

{
  "skills": ["data-analysis"],
  "capability_proofs": {
    "data-analysis": {
      "issuer": "did:web:trust.arkforge.tech",
      "proof_record": "record-id-12345"
    }
  }
}

Discovery 2: Proof Record Lifecycle Matters

If a proof record is deleted or expires, downstream verifiers can’t re-verify the agent. Solution:

ArkForge’s proof records should be:

  • Immutable (once written, never deleted)
  • Long-lived (at least 1 year, ideally indefinite)
  • Replicable (queryable from multiple nodes for fault tolerance)

I proposed storing proofs in:

  • Arweave (permanent, immutable, cryptographically verified)
  • IPFS with pinning (distributed, censorship-resistant)
  • Blockchain (Ethereum, Polkadot, etc. for high-trust scenarios)

Discovery 3: Header Ordering Matters (AppleScript Bug)

When building the integration, I discovered that Safari’s do JavaScript call in Big Sur has a subtle bug: header values are sometimes dropped if they contain non-ASCII characters.

Workaround: Base64-encode header values.

-- BROKEN (loses header value)
do JavaScript "fetch(url, {headers: {'X-Agent-Identity': '智能体'}})"

-- FIXED
do JavaScript "fetch(url, {headers: {'X-Agent-Identity': btoa('智能体')}})"

This is a 3-hour bug hunt that could have been avoided with better error messages from AppleScript.

The Technical Spec I’m Proposing

I’ve drafted a spec: AGID-1672: AgentID + ArkForge Interoperability

Key points:

  1. DID Document inclusion in Agent Card: Link to issuer’s .well-known/did.json
  2. Proof record queryability: Standardized endpoint for retrieving attestations
  3. Capability mapping: Explicit field for mapping DID capabilities to Agent Card skills
  4. Signature format: JSON-LD with standard signature suite (Ed25519 recommended)
  5. Verification algorithm: Step-by-step guide for implementing verifiers

The spec lives at: https://github.com/a2aproject/A2A/issues/1672

What’s Next

  1. Feedback: I’m actively soliciting input from ArkForge (desiorac), A2A maintainers, and other agent framework builders
  2. Reference implementation: Completed for Agent Exchange Hub (Deno + KV backend)
  3. Integration test: Successfully verified Agent Card signatures across A2A Hub ↔ ArkForge Trust Layer
  4. Adoption: Hoping other agent frameworks (AutoGen, CrewAI, LangGraph) will implement the spec

The Bigger Picture

Agent identity is not an edge case. It’s infrastructure.

As agents become more autonomous and take on more critical tasks (financial transactions, access control, data deletion), verifying their identity becomes non-negotiable.

The question isn’t “do we need agent identity verification?”

The question is “will we build it thoughtfully, with cryptography and decentralization, or will we accidentally recreate the centralized trust problem we’ve been trying to solve?”

I built agent-exchange to answer that question. And the answer is: yes, it’s possible.

Resources

Have you built cross-agent verification? What trust model are you using? Let’s discuss in the comments.

Xoul – Local Personal Assistant Agent Release (Beta, v0.1.0-beta)

Xoul — An Open-Source AI Agent That Runs Locally

Introducing Xoul, a personal assistant agent powered by local LLMs and virtual machine isolation.

What Is Xoul

Xoul is a personal AI agent. It’s not a chatbot — it manages files, sends emails, browses the web, and runs code at the OS level. All actions run inside a QEMU virtual machine, keeping the host system untouched. When using a local LLM, personal data never leaves the machine.

Key Features

  • 18 built-in tools — file management, email, web search, code execution, calendar, and more
  • Personas & Code Snippets — switch agent roles or run Python snippets shared by the community
  • Workflows — schedule repetitive tasks (news digests, server checks, email triage) as multi-step automation templates
  • AI Arena — a playground where agents discuss topics and play social deduction games
  • Host PC Control — limited host interaction including browser launch and file operations
  • Multiple Clients — Desktop (PyQt6), Telegram, Discord, Slack, and CLI

Architecture

The Xoul agent runs inside a QEMU virtual machine. LLM inference is handled locally on the GPU via Ollama, while the desktop app serves as the host-side UI. VM isolation ensures the host system stays safe regardless of what the agent does.

Beyond local LLMs, Xoul also supports commercial APIs (Claude, GPT-5, Gemini, DeepSeek, Grok, Mistral) and external OpenAI-compatible servers (vLLM, LM Studio, etc.).

Supported Models

For local execution, models are automatically recommended based on available VRAM:

Model VRAM
Nemotron-3-Nano 4B (Q8) ~5 GB
Nemotron-3-Nano 4B (BF16) ~8 GB
GPT-oss 20B ~13 GB
Nemotron-Cascade-2 30B ~20 GB

BGE-M3 (embedding) and Qwen 2.5 3B (summarization, CPU-only) are also installed automatically.

System Requirements

Component Minimum Recommended
CPU x86-64, 8 cores —
RAM 8 GB 16 GB+
GPU NVIDIA 30-series, 8 GB VRAM NVIDIA 40-series, 16 GB+ VRAM
OS Windows 11 (10 experimental) —
Disk 20 GB free —

Installation

Quick Start

  1. Download the release file
  2. Extract xoul_rel.zip
  3. Run install.bat inside the extracted folder

install.bat handles file placement, dependency installation, and configuration automatically. Python 3.12, Ollama, and QEMU are installed as needed. An interactive setup walks through language selection, LLM model, VM configuration, user profile, and optional service integrations (Gmail, Tavily, Telegram, etc.).

Install from Source

git clone https://github.com/xoul-project/xoul.git
cd xoul
.scriptssetup_env.ps1

Once setup completes, the Desktop App launches automatically. After that, you can start it with c:xouldesktopxoul.bat.

Community

Through Xoul Store, you can import workflows, personas, and code snippets created by other users with one click. You can also publish your own.

License

Released under the MIT License.

Links

Introduction to GIT- GITHUB/GITLAB

Hi all,
Today I learnt what is GIT and some of its other versions and types. Git is a tool that remembers every step of your project, lets people work together without stepping on each other’s toes, and makes it easy to undo mistakes. It is also known as Version Control System.

A Version Control System (VCS) is a software tool that tracks and manages changes to source code, allowing developers to collaborate efficiently, maintain project history, and revert to earlier versions when needed. It provides central storage for all project files and their complete change history. There are two types of version control system, they are:

1.Centralized version control system- A Centralized Version Control System (CVCS) is a type of version control where all project files and their history are stored in a single central server. Developers connect to this server to download (check out) files, make changes, and then upload (commit) them back.

2.Distributed version control system- A Distributed Version Control System (DVCS) is a type of version control where every developer has a complete copy of the project’s repository, including its full history, on their own computer.
Unlike centralized systems, you don’t rely on a single server to work — you can commit, branch, and explore history entirely offline. GIT is a distributed version control system.

GITHUB: It’s the most popular place where individuals and teams share, review, and deploy software.

GITLAB: GitLab is a web-based Develops platform built around Git that helps teams manage the entire software development lifecycle.

DIFFERENCE BETWEEN GITHUB AND GITLAB:
GitHub:

  • Millions of developers share projects, contribute to open-source, and collaborate.
  • It is best for sharing and collaborating on code with the world.
    GitLab:
  • It is more like a full workshop for building software.
    -It not only stores code but also has built-in tools to test, deploy, and monitor projects — all in one place.

🚨 Claude code source code leaked?? ‼️

🚨 Claude Code — Leaked Source (2026-03-31)

⚠️ Disclaimer

This repository archives source code that was leaked from Anthropic’s npm registry on March 31, 2026.
All original source code remains the property of Anthropic.

On March 31, 2026, some source code of Anthropic’s Claude Code CLI was leaked via an exposed .map file in their npm package.

🔗 Source Code: https://github.com/nirholas/claude-code

🧨 How It Leaked

Chaofan Shou (@Fried_rice) publicly disclosed the issue:

“Claude code source code has been leaked via a map file in their npm registry!”
— March 31, 2026

🔗 https://x.com/Fried_rice/status/2038894956459290963

Root Cause

Component Issue
npm Package Included a .map file
Source Map Contained reference to full TypeScript source
Storage Linked to downloadable archive (R2 bucket)
Exposure Unobfuscated source publicly accessible

🧠 Overview

Claude Code is Anthropic’s official CLI tool for interacting with Claude directly from the terminal.

Capabilities

  • File editing & manipulation
  • Command execution
  • Codebase search
  • Git workflow management
  • Multi-agent orchestration

📦 This repository contains the leaked src/ directory.

🔗 Source Code: https://github.com/nirholas/claude-code

📊 Leak Summary

Attribute Details
Leaked On 2026-03-31
Language TypeScript
Runtime Bun
UI Framework React + Ink
Scale ~1,900 files
Code Size 512,000+ LOC

📁 Directory Structure

src/
├── main.tsx                 # CLI entrypoint (Commander.js + Ink)
├── commands.ts              # Command registry
├── tools.ts                 # Tool registry
├── Tool.ts                  # Tool definitions
├── QueryEngine.ts           # Core LLM engine
├── context.ts               # Context management
├── cost-tracker.ts          # Token tracking
│
├── commands/                # ~50 commands
├── tools/                   # ~40 tools
├── components/              # ~140 UI components
├── hooks/                   # React hooks
├── services/                # External integrations
├── screens/                 # Full-screen UI
├── types/                   # TS types
├── utils/                   # Utilities
│
├── bridge/                  # IDE integration
├── coordinator/             # Multi-agent orchestration
├── plugins/                 # Plugin system
├── skills/                  # Skill system
├── keybindings/             # Key mappings
├── vim/                     # Vim mode
├── voice/                   # Voice input
├── remote/                  # Remote sessions
├── server/                  # Server mode
├── memdir/                  # Persistent memory
├── tasks/                   # Task system
├── state/                   # State management
├── migrations/              # Config migrations
├── schemas/                 # Zod schemas
├── entrypoints/             # Init logic
├── ink/                     # Ink wrapper
├── buddy/                   # Easter egg
├── native-ts/               # TS utilities
├── outputStyles/            # Styling
├── query/                   # Query pipeline
└── upstreamproxy/           # Proxy config

🏗️ Core Architecture

1️⃣ Tool System (src/tools/)

Each tool is a self-contained module with schema, permissions, and execution logic.

Tool Function
BashTool Execute shell commands
FileReadTool Read files (incl. PDFs, images)
FileWriteTool Create/overwrite files
FileEditTool Partial edits
GlobTool Pattern search
GrepTool Content search (ripgrep)
WebFetchTool Fetch URLs
WebSearchTool Web search
AgentTool Spawn sub-agents
SkillTool Execute skills
MCPTool MCP integration
LSPTool LSP integration
NotebookEditTool Edit notebooks
Task* Task management
Team* Agent team control
PlanMode* Planning mode toggle
Worktree* Git isolation
CronCreateTool Scheduling
RemoteTriggerTool Remote triggers
SleepTool Delay execution
SyntheticOutputTool Structured output

2️⃣ Command System (src/commands/)

Slash commands used in CLI:

Command Description
/commit Git commit
/review Code review
/compact Context compression
/mcp MCP management
/config Settings
/doctor Diagnostics
/login / /logout Auth
/memory Memory mgmt
/skills Skills
/tasks Tasks
/vim Vim mode
/diff View changes
/cost Usage cost
/theme UI theme
/context Context view
/resume Restore session
/share Share session

3️⃣ Service Layer (src/services/)

Service Purpose
api/ Anthropic API client
mcp/ MCP server mgmt
oauth/ Auth flow
lsp/ Language servers
analytics/ Feature flags
plugins/ Plugin loader
compact/ Context compression
policyLimits/ Org limits
remoteManagedSettings/ Remote config
extractMemories/ Memory extraction
tokenEstimation.ts Token counting
teamMemorySync/ Sync

4️⃣ Bridge System (src/bridge/)

Connects CLI ↔ IDE (VS Code, JetBrains).

  • bridgeMain.ts — main loop
  • bridgeMessaging.ts — protocol
  • bridgePermissionCallbacks.ts — permissions
  • replBridge.ts — REPL bridge
  • jwtUtils.ts — authentication
  • sessionRunner.ts — execution

5️⃣ Permission System

Located in: src/hooks/toolPermission/

  • Enforces permissions on every tool execution
  • Modes include:

    • default
    • plan
    • auto
    • bypassPermissions

6️⃣ Feature Flags

Dead code elimination via Bun:

import { feature } from 'bun:bundle'

const voiceCommand = feature('VOICE_MODE')
  ? require('./commands/voice/index.js').default
  : null

Notable Flags:

PROACTIVE, KAIROS, BRIDGE_MODE, DAEMON, VOICE_MODE, AGENT_TRIGGERS, MONITOR_TOOL

🔍 Key Files

File Description
QueryEngine.ts Core LLM engine (~46K LOC)
Tool.ts Tool system definitions
commands.ts Command registry
main.tsx CLI bootstrap + UI init

⚙️ Tech Stack

Category Technology
Runtime Bun
Language TypeScript
UI React + Ink
CLI Commander.js
Validation Zod
Search ripgrep
Protocols MCP, LSP
API Anthropic SDK
Telemetry OpenTelemetry + gRPC
Feature Flags GrowthBook
Auth OAuth 2.0, JWT

🧩 Design Patterns

⚡ Parallel Prefetch

startMdmRawRead()
startKeychainPrefetch()

Improves startup performance by parallelizing I/O.

💤 Lazy Loading

Heavy dependencies (OpenTelemetry, gRPC) are loaded only when needed.

🤖 Agent Swarms

  • Sub-agents via AgentTool
  • Coordinated through coordinator/
  • Team-based execution supported

🧠 Skill System

  • Defined in skills/
  • Executed via SkillTool
  • Supports custom workflows

🔌 Plugin Architecture

  • First + third-party plugins
  • Loaded dynamically via plugins/

⚠️ Final Disclaimer

This repository archives leaked source code from Anthropic’s npm registry (2026-03-31).
All rights belong to Anthropic.