How I Built a Privacy-First Offline PWA Expense Tracker

What is Spendly?

Spendly is an offline-first expense tracker PWA I built.
No server. No cloud. Everything stays on your device.

Why I Built It

Most expense apps send your data to their servers.
I wanted something that works 100% offline with real encryption.

Tech Stack

  • React + Vite (frontend)
  • TailwindCSS (styling)
  • Dexie.js (local IndexedDB)
  • AES-256-GCM encryption
  • WebAuthn (fingerprint/PIN lock)

Cool Features

3 Ways to Add Expenses:

  • Manual keypad entry
  • Barcode scan (Open Food Facts API)
  • Bill photo scan (Tesseract.js OCR)

Security:

  • AES-256-GCM encryption
  • PBKDF2 with 600,000 iterations
  • Zero data sent to any server

Live Demo

👉 spendly-24hrs.pages.dev

GitHub

👉 github.com/PDA-DP-Shop/spendly

Drop a ⭐ if you find it useful!

Security Is a Myth | The Axios Supply Chain Attack

CRITICAL INCIDENT SUMMARY

LIVE ALERT: [email protected] and [email protected] removed from npm. RAT dropper confirmed. Exposure window: ~2 hours 53 minutes. If you installed Axios between 00:21 and 03:15 UTC on March 31, assume compromise. C2: sfrclak.com.

What is a Supply Chain Attack?

A supply chain attack is a cyberattack where an adversary compromises a trusted third-party component—such as a software dependency, build system, or update mechanism—to indirectly gain access to downstream systems.

Instead of attacking the primary target directly, the attacker targets a weaker or less monitored link in the supply chain and leverages established trust relationships to propagate malicious code.

Why It Works

Modern software systems rely heavily on external dependencies, automated CI/CD pipelines, and signed update mechanisms. These introduce implicit trust boundaries that are rarely verified at runtime.

Once a trusted component is compromised, its consumers inherit that compromise without additional scrutiny.

Attack Vectors

1. Compromised Dependencies

Attackers inject malicious code into open-source packages (e.g., npm, PyPI). This often includes:

  • Maintainer account takeover
  • Malicious version publishing
  • Dependency confusion (publishing a higher-version package to public registries)

Impact:
Every downstream project that installs or updates the dependency executes attacker-controlled code.

2. Transitive Dependency Exploitation (Critical)

Most projects don’t directly depend on vulnerable packages—they inherit them indirectly.

Example:

Your app → Library A → Library B (malicious)
  • Developers often don’t audit deep dependency trees
  • This makes it a high-leverage attack vector

3. Build Pipeline Compromise

  • Attackers breach CI/CD systems or build servers
  • They inject malicious code during the build process
  • The resulting artifact is legitimately signed and distributed
    This makes detection significantly harder.

4. Software Update Channel Hijacking

Attackers compromise update infrastructure and distribute malicious updates.

Why this is effective:

  • Updates are trusted implicitly
  • Users rarely validate update integrity beyond signatures

What Actually Happened

Metric Detail
100M+ Axios weekly downloads
2h 53m Total exposure window
18 hrs Pre-staged in advance
3 Target platforms (macOS, Windows, Linux)

What and How The Attack Happened

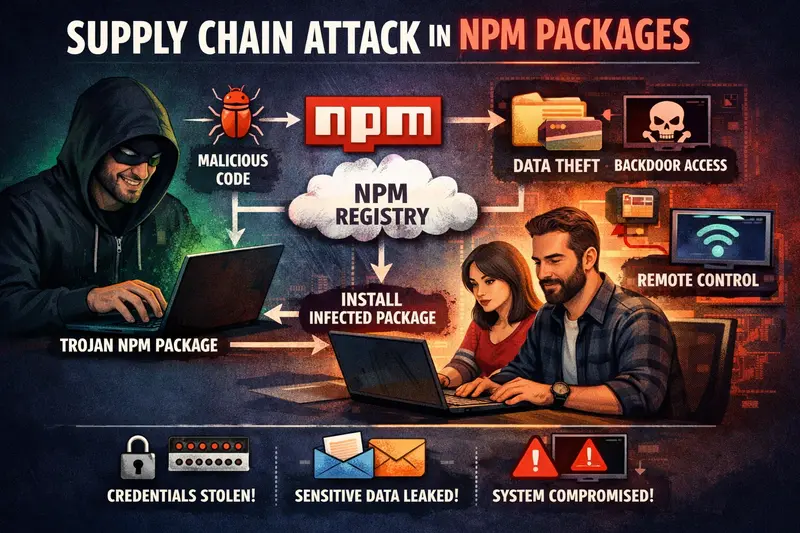
On March 30th, 2026, a hacker compromised the npm account of axios’s primary maintainer. Axios is the industry-standard JavaScript HTTP client, boasting over 100 million weekly downloads. The attacker changed the maintainer’s registered email to a ProtonMail address and published two poisoned versions: [email protected] and [email protected].

Security firm StepSecurity flagged the versions within three hours. However, the damage potential remains high; anyone who downloaded the code during that window is advised to treat their system as fully compromised.

“There are zero lines of malicious code inside axios itself—and that’s exactly what makes this attack so dangerous.”
— StepSecurity Technical Analysis, March 31, 2026

The hacker didn’t modify axios’s source code. Instead, they added a single “phantom” dependency to package.json: [email protected]. When a developer ran npm install, this package triggered a postinstall hook to deploy a cross-platform Remote Access Trojan (RAT).

How the Attack Was Constructed

1. Account Hijack

The attacker targeted jasonsaayman. While legitimate axios releases use OIDC Trusted Publishers (linked to GitHub Actions), [email protected] was pushed manually using a stolen classic npm token. There was no corresponding commit or tag in the GitHub repository.

Legitimate vs. Malicious Metadata:

// axios@1.14.0 - LEGITIMATE
"_npmUser": {
  "name": "GitHub Actions",
  "email": "[email protected]",
  "trustedPublisher": { "id": "github" }
}

// axios@1.14.1 - MALICIOUS
"_npmUser": {
  "name": "jasonsaayman",
  "email": "[email protected]"
  // Missing trustedPublisher and gitHead
}

2. The Decoy (18 Hours Early)

The attacker first published [email protected], a clean copy of the legitimate crypto-js library, to build account history and bypass “zero-history” scanners. 18 hours later, version 4.2.1 was published—this time armed with setup.js, a 4.2 KB obfuscated dropper.

3. The Injection

Exactly one file changed in the Axios package: package.json.

// axios@1.14.1 -- malicious
"dependencies": {
  "follow-redirects": "^2.1.0",
  "form-data": "^4.0.1",
  "proxy-from-env": "^2.1.0",
  "plain-crypto-js": "^4.2.1"  // Never actually imported in the code
}

Attack Timeline (UTC)

  • Mar 30 – 05:57: Decoy published. [email protected] (clean).
  • Mar 30 – 23:59: Weapon armed. [email protected] (malicious) published.
  • Mar 31 – 00:21: Payload deployed. [email protected] hits npm.
  • Mar 31 – 01:00: Legacy branch poisoned. [email protected] published.
  • Mar 31 – 03:15: Takedown. npm removes malicious versions.
  • Mar 31 – 04:26: Package killed. npm replaces plain-crypto-js with a security stub.

Malware Behavior by Platform

The dropper contacts sfrclak.com:8000 within two seconds of installation.

OS Payload Action Indicator (IOC)
macOS AppleScript downloads RAT binary; disguised as system daemon. /Library/Caches/com.apple.act.mond
Windows Persists by copying PowerShell to %PROGRAMDATA%wt.exe. %PROGRAMDATA%wt.exe
Linux Uses curl and nohup to run a Python RAT detached from PID. /tmp/ld.py

Post-Infection Stealth: The dropper deletes setup.js and the malicious package.json entries after execution. npm audit will return clean even while the RAT is active.

Indicators of Compromise (IOCs)

Type Value Status
npm package [email protected] MALICIOUS
C2 Domain sfrclak.com BLOCK NOW
C2 IP 142.11.206.73 BLOCK NOW
Attacker [email protected] THREAT ACTOR

Immediate Action Plan

[!CAUTION]
If you installed Axios during the exposure window, rebuild your environment from scratch. Do not attempt to “clean” the infection.

  • Check Version: npm list axios | grep -E "1.14.1|0.30.4"
  • Check for Dropper: ls node_modules/plain-crypto-js. If this folder exists, you are compromised.
  • Downgrade: Use [email protected] or [email protected].
  • Block Network: Sinkhole sfrclak.com at the firewall level.
  • Rotate Secrets: AWS keys, SSH keys, npm tokens, and .env variables must be cycled.
  • Prevention: Update CI/CD to use npm ci --ignore-scripts.

The Road Ahead: Python & Beyond

The Axios attack is a blueprint. Python’s setup.py and pyproject.toml hooks offer an identical attack surface. The risk in the Python ecosystem is arguably higher; ML and Data Science pipelines often run with direct access to sensitive model weights and production data, often with less outbound monitoring than frontend environments.

The Actual Takeaway

Security industry focus on source code (SAST/DAST) failed here. This attack lived entirely in the metadata and registry-level hooks. Treat package installation as a privileged operation. Pin your dependencies, verify lockfiles, and monitor outbound connections from build environments.

## The Invisible Bug That Broke My React Deployment (and What It Taught Me)

I thought deploying a React app would be the easiest part of the project—until my production build went live and… a blank screen appeared. No errors in the browser. No crashes in the console. Just silence.

Locally, everything worked perfectly. npm start was fine. But once deployed to GitHub Pages/Vercel, the app simply refused to render. That’s when I realized the problem wasn’t React—it was the deployment assumptions I had made.

After hours of debugging, I found the culprit hiding in plain sight: incorrect routing configuration and missing homepage setup in package.json. React Router was trying to handle routes as if it was running on a server, but static hosting doesn’t work that way by default.

// Fix for React Router on static hosting
<BrowserRouter basename={process.env.PUBLIC_URL}>

And in package.json:

"homepage": "https://your-username.github.io/repo-name"

That tiny line fixed everything.

Lesson learned:

Deployment isn’t just “uploading code”—it’s understanding the environment your code runs in. React apps behave differently when they lose their server context.

Now I always ask myself before deploying:

  • Will this run on a static server?
  • Do I need routing adjustments?
  • Did I test the production build locally (npm run build && serve build)?

A simple mistake turned into a valuable reminder: production is a different world than development.

How I Built Secure Firebase Cloud Functions with Admin Permissions and Rate Limiting

If you’re building an admin panel that talks to Firebase Cloud Functions, you need two things before anything else — permission checks and rate limiting. Without these, any authenticated user could call your admin endpoints, and a single bad actor could spam your functions into hitting billing limits.

Here’s how I set this up in a real admin panel, not a tutorial demo.

The problem

I was building an admin panel for a mobile app. The admin needed to send push notifications, search users, and moderate content. All of these were Cloud Functions callable from the client.

The issue? Firebase callable functions don’t have built-in admin role checks. Any authenticated user can call any callable function by default. That’s terrifying.

Step 1: Store admin roles in Firestore

I keep a simple admins collection in Firestore:

// Firestore structure
// admins/{uid}
{
  email: "[email protected]",
  role: "super_admin", // or "moderator", "viewer"
  permissions: ["send_notifications", "manage_users", "view_analytics"],
  createdAt: Timestamp
}

Step 2: The permission verification helper

Every admin Cloud Function calls this before doing anything:

import * as functions from "firebase-functions";
import * as admin from "firebase-admin";

interface AdminData {
  uid: string;
  role: string;
  permissions: string[];
}

async function verifyAdminPermission(
  context: functions.https.CallableContext,
  requiredPermission: string
): Promise<AdminData> {
  // Check if user is authenticated at all
  if (!context.auth) {
    throw new functions.https.HttpsError(
      "unauthenticated",
      "You must be logged in."
    );
  }

  const uid = context.auth.uid;

  // Check if user exists in admins collection
  const adminDoc = await admin
    .firestore()
    .collection("admins")
    .doc(uid)
    .get();

  if (!adminDoc.exists) {
    throw new functions.https.HttpsError(
      "permission-denied",
      "You are not an admin."
    );
  }

  const adminData = adminDoc.data() as AdminData;

  // Check specific permission
  if (
    adminData.role !== "super_admin" &&
    !adminData.permissions.includes(requiredPermission)
  ) {
    throw new functions.https.HttpsError(
      "permission-denied",
      `You don't have the "${requiredPermission}" permission.`
    );
  }

  return { uid, ...adminData };
}

The key design decision — super_admin bypasses all permission checks. Everyone else needs the specific permission listed in their Firestore document. This way I can have moderators who can only view reports but can’t send notifications.

Step 3: Rate limiting with Firestore

I didn’t want to add Redis or any external service just for rate limiting. Firestore works fine for admin-level traffic (not high-throughput APIs, but admin panels with a few users):

async function applyRateLimit(
  uid: string,
  action: string,
  maxRequests: number,
  windowMs: number
): Promise<void> {
  const now = Date.now();
  const windowStart = now - windowMs;

  const rateLimitRef = admin
    .firestore()
    .collection("rateLimits")
    .doc(`${uid}_${action}`);

  const doc = await rateLimitRef.get();

  if (doc.exists) {
    const data = doc.data()!;
    // Filter out old timestamps outside the window
    const recentRequests = (data.timestamps as number[]).filter(
      (t) => t > windowStart
    );

    if (recentRequests.length >= maxRequests) {
      throw new functions.https.HttpsError(
        "resource-exhausted",
        `Rate limit exceeded. Max ${maxRequests} requests per ${windowMs / 1000} seconds.`
      );
    }

    // Add current timestamp
    await rateLimitRef.update({
      timestamps: [...recentRequests, now],
    });
  } else {
    // First request
    await rateLimitRef.set({
      timestamps: [now],
    });
  }
}

Is this the most efficient rate limiter ever? No. But for an admin panel with 3-5 users, it works perfectly and costs basically nothing.

Step 4: Putting it together

Here’s what a real admin Cloud Function looks like with both helpers:

export const sendAdminNotification = functions.https.onCall(
  async (data, context) => {
    // 1. Verify admin has notification permission
    const adminUser = await verifyAdminPermission(
      context,
      "send_notifications"
    );

    // 2. Rate limit: max 10 notifications per minute
    await applyRateLimit(adminUser.uid, "send_notification", 10, 60000);

    // 3. Validate input
    const { title, body, sendMode, filters } = data;

    if (!title || !body) {
      throw new functions.https.HttpsError(
        "invalid-argument",
        "Title and body are required."
      );
    }

    // 4. Build the query based on send mode
    let tokens: string[] = [];

    if (sendMode === "broadcast") {
      const usersSnapshot = await admin
        .firestore()
        .collection("users")
        .where("fcmToken", "!=", null)
        .get();
      tokens = usersSnapshot.docs.map((doc) => doc.data().fcmToken);
    } else if (sendMode === "filtered") {
      let query: admin.firestore.Query = admin
        .firestore()
        .collection("users");

      if (filters?.gender) {
        query = query.where("gender", "==", filters.gender);
      }
      if (filters?.city) {
        query = query.where("city", "==", filters.city);
      }
      if (filters?.tier) {
        query = query.where("tier", "==", filters.tier);
      }

      const snapshot = await query.get();
      tokens = snapshot.docs
        .map((doc) => doc.data().fcmToken)
        .filter(Boolean);
    }

    // 5. Send via FCM (batch if over 500)
    const batchSize = 500;
    let successCount = 0;
    let failureCount = 0;

    for (let i = 0; i < tokens.length; i += batchSize) {
      const batch = tokens.slice(i, i + batchSize);
      const response = await admin.messaging().sendEachForMulticast({
        tokens: batch,
        notification: { title, body },
      });
      successCount += response.successCount;
      failureCount += response.failureCount;
    }

    // 6. Log the notification for history
    await admin.firestore().collection("notificationHistory").add({
      title,
      body,
      sendMode,
      filters: filters || null,
      sentBy: adminUser.uid,
      totalTargeted: tokens.length,
      successCount,
      failureCount,
      sentAt: admin.firestore.FieldValue.serverTimestamp(),
    });

    return { successCount, failureCount, totalTargeted: tokens.length };
  }
);

Organizing Cloud Functions

When you have 10+ admin functions, a single index.ts file becomes unreadable. I split them into a folder structure:

functions/
  src/
    admin/
      notifications.ts    // sendAdminNotification, estimateAudience
      users.ts            // searchUsers, moderateUser
      analytics.ts        // getDashboardStats
      index.ts            // barrel file - re-exports everything
    index.ts              // main entry - exports from ./admin

The barrel file keeps imports clean:

// functions/src/admin/index.ts
export { sendAdminNotification, estimateAudience } from "./notifications";
export { searchUsers, moderateUser } from "./users";
export { getDashboardStats } from "./analytics";

// functions/src/index.ts
export * from "./admin";

Mistakes I made

1. Forgetting to handle expired FCM tokens

First time I sent a broadcast, 30% of tokens were stale. Firebase doesn’t clean them for you. Now I delete tokens that return messaging/registration-token-not-registered errors after each send.

2. Not batching Firestore reads

I was doing individual getDoc() calls in a loop to check user profiles. Switched to a single where() query — went from 3 seconds to 200ms for 500 users.

3. Rate limit document growing forever

My first rate limiter appended timestamps but never cleaned old ones. After a month, each document had thousands of entries. The filter step in applyRateLimit above fixes this — it only keeps timestamps within the current window.

When to use this pattern

This setup works when:

  • You have a small number of admin users (under 50)
  • You want role-based permissions without adding a third-party auth service
  • Your rate limiting needs are basic (not thousands of requests per second)

If you need high-throughput rate limiting, use Redis. If you need complex RBAC, use a proper auth provider. But for most admin panels, Firestore-based checks are simple, free, and good enough.

I’m Abhishek, a full-stack developer building SaaS products and mobile apps with Flutter, Next.js, and Node.js. I write about practical patterns from real projects.

Build a RAG Pipeline Inside Joomla for Intelligent Site Search

Joomla’s built-in search has always had the same fundamental limitation. It is keyword-based. A visitor types “how do I reset my account” and the search engine looks for articles containing those exact words. If your article uses the phrase “recover your login credentials” instead, it does not show up. The visitor gets no results, concludes your site does not have the answer, and leaves.

This is not a Joomla problem specifically. It is what keyword search does. It matches strings, not meaning. RAG, Retrieval-Augmented Generation, solves this at the architecture level. Instead of matching keywords, it converts both your content and the search query into vector embeddings, finds content that is semantically similar, and uses an LLM to generate a direct answer from that content. A visitor asking “how do I reset my account” gets a proper answer even if none of your articles use those exact words.

I will walk through the full implementation. We will cover the three main vector storage options honestly so you can make the right choice for your setup, then go deep on building the complete RAG pipeline inside a custom Joomla component using PostgreSQL with pgvector and OpenAI.

What you need: Joomla 4 or 5, PHP 8.1+, Composer, PostgreSQL with the pgvector extension installed, and an OpenAI API key.

For more details : https://www.phpcmsframework.com/2026/03/joomla-rag-pipeline-intelligent-site-search.html

Stop Giving CEOs Full Access: You’re Engineering a Single Point of Catastrophic Failure

 In modern organisations, access control is often shaped by hierarchy rather than threat modelling.
Senior executives, particularly CEOs, are routinely granted broad, persistent administrative access across systems. The intention is speed. The outcome is risk concentration.
This is not a theoretical concern. It is a structural weakness that continues to appear in real-world breaches.
The CEO is not just another user. From an attacker’s perspective, the CEO is a high-leverage identity. When that identity is compromised, the attacker does not need to escalate privileges. The privileges are already there.
The CEO as an Attack Surface, Not Just a Role
Security teams tend to focus on infrastructure, endpoints, and external threats. What is often underestimated is identity as an attack surface.
The CEO’s identity combines several characteristics that make it uniquely attractive:
Public visibility: names, emails, and communication patterns are easy to discover
High trust: requests from the CEO are rarely challenged
Constant urgency: decisions, approvals, and escalations happen daily
Cross-system presence: added to finance, HR, cloud, and internal tools for convenience
Reduced friction: security controls are often relaxed to “enable leadership”

From a threat modelling standpoint, this is the perfect storm. You have an identity that is both highly exposed and highly privileged.
From Phishing to Full Control: How the Failure Cascades
Most executive compromises do not begin with sophisticated exploits. They begin with simple, well-crafted phishing.
Once access is obtained, the attacker inherits the CEO’s authority.
At that point, the attack shifts from entry to expansion.
Phase 1: Establish Persistence
Inbox takeover and creation of hidden forwarding rules
Silent monitoring of communications
Resetting credentials for connected services

Phase 2: Financial Manipulation
Altering vendor payment details
Injecting fraudulent invoices into approval flows
Redirecting large transfers under the guise of urgency

Phase 3: Organisational Penetration
Accessing HR systems and extracting employee data
Leveraging internal knowledge for targeted lateral phishing
Impersonating leadership to issue instructions across departments

Phase 4: Infrastructure Control
Modifying cloud roles and permissions
Generating API keys and long-lived tokens
Disabling logging or alerting mechanisms

At this stage, the attacker is no longer external. They are operating as an internal authority with strategic visibility.
This is what transforms a security incident into an organisational crisis.
The Core Problem: Standing Privilege in a High-Risk Identity
The issue is not that CEOs are targeted. That is unavoidable.
The issue is that organisations combine high-risk identities with permanent, unrestricted privilege.
This violates a fundamental security principle:
 No single identity should have the ability to compromise the entire system without constraint.
Yet in many environments, the CEO account effectively does.
Rethinking Executive Access: A Security Architecture Perspective
The solution is not to restrict leadership capability. It is to redesign how privilege is assigned, accessed, and controlled.
What follows is a model I have implemented in production systems to reduce blast radius without slowing decision-making.

  1. Identity Separation: Remove Privilege from Daily Exposure
    The CEO should operate with a standard user identity for all daily activities:
    Email and communication
    Document access
    Meetings and collaboration tools

This account should have zero standing administrative privileges.
A separate, tightly controlled identity should exist for administrative actions.
This ensures that everyday exposure such as email phishing does not directly translate into system-wide control.

  1. Privileged Access Isolation: Break the Attack Chain
    Administrative accounts must be:
    Isolated from email and browsing environments
    Used only within controlled contexts
    Protected with stronger authentication and monitoring

This separation introduces friction in the attack chain. Even if the primary account is compromised, the attacker does not automatically gain elevated access.

  1. Just-In-Time (JIT) Access: Eliminate Permanent Privilege
    Standing access is the root of most privilege-related breaches.
    Instead, adopt a Just-In-Time model:
    Privileges are granted only when required
    Access is time-bound and automatically revoked
    Approval workflows enforce accountability
    All actions are logged and auditable

This approach ensures that privilege exists only in context, not by default.

  1. Strong, Phishing-Resistant Authentication
    Traditional MFA methods such as SMS are no longer sufficient against modern adversaries.
    Executive accounts should adopt phishing-resistant authentication:
    Hardware security keys
    Passkeys using device-bound cryptography
    Authenticator apps with number matching

These controls significantly reduce the effectiveness of credential harvesting and session hijacking attacks.

  1. Policy Enforcement: Design for Assumed Compromise
    Security architecture should assume that any identity can be compromised.
    From that assumption, systems must be designed to:
    Limit lateral movement
    Restrict cross-domain privilege
    Detect abnormal behaviour quickly
    Contain impact within defined boundaries

When applied to executive access, this means ensuring that even a compromised CEO account cannot independently control finance, HR, and infrastructure simultaneously.
The Misconception: Access Equals Efficiency
A common justification for broad executive access is speed.
In reality, unrestricted access does not improve operational efficiency. It introduces hidden fragility.
Well-designed systems allow executives to make decisions quickly without exposing critical infrastructure to unnecessary risk.
Efficiency should come from process design, not privilege accumulation.
Real-World Implication: From Incident to Business Failure
When executive accounts are over-privileged, the cost of compromise is not limited to financial loss.
It includes:
Regulatory exposure due to data breaches
Loss of organisational trust
Operational disruption across multiple departments
Long-term reputational damage

In severe cases, it threatens the continuity of the business itself.
Conclusion: Remove the Single Point of Failure
This is not about limiting leadership. It is about strengthening the system that leadership depends on.
A resilient organisation does not rely on the assumption that its most targeted identity will never be compromised.
It designs for the opposite.
If your CEO account can take down your entire organisation, the problem is not the attacker.
The problem is the architecture.

About the Author

Christian Ohwofasa is a Web Systems Developer focused on building secure, production-grade platforms with an emphasis on identity security, access control, and real-world risk mitigation.

Meta Just Killed the Metaverse It Renamed the Entire Company For

On October 28, 2021, Mark Zuckerberg stood in front of a camera and told the world that the future of human connection was the metaverse. He was so certain of this that he renamed a $900 billion company after it. Not a product line. Not a division. The entire company. Facebook — the company that owned Instagram, WhatsApp, and the social graphs of three billion people — became Meta Platforms, Inc.

Yesterday, Meta announced that Horizon Worlds, the flagship VR metaverse application that justified that rebrand, will be removed from Quest headsets on June 15th, 2026.

Let that sink in.

The most expensive corporate vanity project in the history of technology is being killed not with a dramatic announcement, not with a mea culpa, not even with a blog post from Zuckerberg himself. It’s being killed with a support article titled “Updates to Your Meta Quest Experience in 2026,” written by MetaStoreHelp, posted on a community forum.

That’s how the metaverse dies. Not with a bang, but with a FAQ.

The $50 Billion Graveyard

Let’s tally up the damage. Since rebranding to Meta, the company’s Reality Labs division has reported staggering losses: $13.7 billion in 2022, $16.1 billion in 2023, $17.7 billion in 2024, and roughly $18 billion in 2025. That’s north of $65 billion in operating losses in four years — and that’s before counting the billions spent from 2019 to 2021.

For context, that’s more than the GDP of over half the countries on Earth. Meta spent the equivalent of Luxembourg’s entire economic output on a platform that, at its peak, had fewer concurrent users than a mid-tier Minecraft server.

What did that money buy? Legless avatars. Bowling alleys that no one visited. Virtual meeting rooms that made Zoom look like the Holodeck. A platform so empty that Meta’s own employees reportedly refused to use it. Internal memos leaked in 2022 showed that even the people building Horizon Worlds didn’t want to spend time in it. When your own engineers won’t eat the dog food, the dog food is rotten.

The Quiet Dismantling

The June 15th shutdown isn’t a surprise if you’ve been paying attention. Meta has been dismembering its VR ambitions piece by piece, like a surgeon who realizes the patient is terminal but doesn’t want to call time of death in front of the family.

Here’s the kill list from 2025-2026 alone:

  • 10 percent of Reality Labs — laid off in a round of cuts that Meta framed as “focusing on efficiency.”
  • Three VR game studios — Twisted Pixel, Sanzaru, and Armature, all shuttered. These were the studios that were supposed to make VR content compelling enough to justify a headset purchase.
  • Supernatural VR fitness — no longer getting new content. Meta acquired this company in 2022 specifically to prove VR had mainstream utility beyond gaming. It didn’t.
  • Horizon Workrooms — Meta’s metaverse-for-work product, discontinued. The vision of virtual offices replacing Zoom calls turned out to be a solution looking for a problem that didn’t exist.
  • Horizon Worlds VR — the platform that started all of this, now officially dead. Worlds will be removed from Quest by June 15th, with store listings vanishing by March 31st.

Each of these moves was announced separately, buried in blog posts and developer updates, designed to avoid a single headline that reads: “Meta admits the metaverse was a mistake.” But when you lay them out end to end, that’s exactly what happened.

The Pivot Nobody Asked For

Here’s the part that should make you angry if you spent $500 on a Quest headset because Zuckerberg promised you the future.

Meta isn’t abandoning Horizon Worlds entirely. It’s “pivoting to mobile.” In corporate-speak, that means Horizon Worlds will become a mobile app — essentially a Roblox clone competing for the same audience of children and teenagers who already have Roblox, Fortnite, and Minecraft.

Samantha Ryan, Reality Labs’ VP of content, phrased it this way: “To truly change the game and tap into a much larger market, we’re going all-in on mobile.”

Translation: VR doesn’t have enough users to justify the engineering cost, so we’re going where the users already are and hoping nobody notices that we’ve abandoned the thesis that justified our entire corporate identity.

This is the same logic that killed Google Stadia. The same logic that killed Amazon’s phone. “We can’t make people come to our platform, so let’s go to theirs.” It never works when the competition has a five-year head start and your product’s primary differentiator was the thing you just removed.

Roblox has 80 million daily active users. Fortnite has hundreds of millions of registered accounts. Meta’s pitch is… what, exactly? That it can leverage the Facebook and Instagram social graph to drive engagement? The same social graph that teenagers have been fleeing for the better part of a decade?

Zuckerberg’s Escape Hatch

The real story here isn’t about VR. It’s about Mark Zuckerberg’s remarkable ability to spend billions on failed bets and face zero consequences.

When the metaverse pivot was announced in 2021, Zuckerberg controlled Meta through a dual-class share structure that gave him roughly 58% of voting power despite owning about 13% of the company’s stock. That structure still exists. No matter how much money Reality Labs burns, no matter how many studios get shuttered, no matter how embarrassingly the metaverse vision collapses — Zuckerberg cannot be fired. He cannot be overruled. He cannot be held accountable by shareholders in any meaningful way.

And now, conveniently, Zuckerberg has a new shiny object. The company that was definitely, absolutely, unquestionably the metaverse company is now definitely, absolutely, unquestionably the AI company.

Watch how this plays out. Within a year, the Meta rebrand will be quietly repositioned as having always been about artificial intelligence. The $65 billion in Reality Labs losses will be reframed as “investments in spatial computing and AI training data.” And nobody on Wall Street will blink, because the stock is up and the ad revenue keeps flowing.

The VR Industry Deserved Better

VR is a real technology with real applications. It’s not snake oil. Flight simulators, medical training, architectural visualization, accessibility tools for people with disabilities — VR has legitimate, transformative use cases that improve people’s lives.

But Meta’s approach to VR was never about making VR better. It was about creating a walled garden. A platform play. A new Facebook, but in 3D, where Meta could control the social graph, the commerce layer, the advertising pipeline, and the hardware. It was about building the next App Store, not the next computing paradigm.

When Meta acquired Oculus in 2014 for $2 billion, there was genuine excitement in the VR community. Palmer Luckey had built something magical in his garage, and Facebook’s money was going to supercharge it. Instead, Facebook’s money turned Oculus into a data-harvesting appendage of a surveillance advertising company. They required Facebook logins. They killed the open modding scene. They underpriced hardware to crush competition.

And now, after using predatory pricing to establish market dominance and then failing to build a compelling software ecosystem, Meta is pulling back. The VR headset market outside of Meta is a wasteland. HTC is clinging on. Sony’s PSVR2 has been a sales disappointment. Apple’s Vision Pro is priced for a market segment that barely exists. The company that was supposed to make VR mainstream instead made it dependent on a single company that just proved it can abandon the platform whenever it gets bored.

The People Left Behind

Spare a thought for the thousands of people whose careers were collateral damage in Zuckerberg’s vision quest.

The VR game developers who left stable jobs at traditional studios to build for Quest, only to see Meta shutter its first-party studios and deprioritize VR content. The hardware engineers who spent years perfecting display technology and inside-out tracking for a platform that’s being downgraded to a phone app. The 10% of Reality Labs staff who were laid off — people who uprooted their families, moved to Menlo Park or London or Zurich, because they believed in the metaverse.

These aren’t abstract losses. They’re real people who made real sacrifices based on the promises of a CEO who had already moved on to the next thing by the time they unpacked their moving boxes.

What’s Actually Left

After June 15th, here’s what remains of Meta’s VR ambitions:

Quest headsets will still work as standalone VR devices with third-party apps and games. Meta says it has “a robust roadmap of future VR headsets.” But given that 86% of Quest usage time is already on third-party apps — a statistic Meta shared as if it were a point of pride rather than an admission of failure — the question becomes: why would anyone buy a Meta headset over a competitor’s when Meta’s only first-party offering is gone?

The answer, for now, is price. Meta still sells Quest hardware at or near cost, subsidized by the ad revenue from its social media empire. But for how long? Reports suggest future Quest headsets will carry higher price tags. Without subsidized pricing and without a compelling first-party software ecosystem, Meta’s headsets become generic Android VR hardware with a blue logo on them.

The Lesson Nobody Will Learn

The metaverse hype cycle of 2021-2022 will be studied in business schools for decades. It’s a masterclass in how a powerful narrative, backed by unlimited capital, can override all evidence and common sense.

The warning signs were always there. The technology wasn’t ready. The use cases were unclear. The average consumer had no interest in strapping a computer to their face to attend a virtual meeting or visit a virtual bowling alley. Every market research report, every user survey, every beta test screamed that mainstream VR adoption was years — possibly decades — away.

But Zuckerberg had a vision, and at Meta, Zuckerberg’s vision is the only one that matters. So the company spent the GDP of a small nation on building something that nobody wanted, and now it’s pretending that pivoting to a mobile Roblox clone was the plan all along.

The metaverse is dead. Long live whatever Zuckerberg decides to waste money on next.

Originally published on TechPulse Daily.

Macaroon Tokens vs API Keys: Why Capability-Based Auth Beats Identity-Based Auth for AI Agents

API keys tie identity to unlimited access. Macaroon tokens embed capabilities and constraints. For AI agents that need delegation and budget limits, the difference is everything.

Read the full article on SatGate.io: https://satgate.io/blog/macaroon-tokens-vs-api-keys

The Problem with API Keys for AI Agents

Every API authentication system makes a fundamental choice: identify who the caller is, or specify what the caller can do. For twenty years, web APIs have chosen identity. Get an API key, prove you’re legitimate, access everything your account allows.

AI agents break that model. An agent doesn’t just call your API — it delegates to sub-agents, spawns parallel tasks, and operates under budgets set by entities three delegation layers up the chain.

Why Macaroons Solve the Delegation Problem

Macaroons flip the authentication model. Instead of asking “who are you?” they embed the answer to “what can you do?” directly into the token. A macaroon is a capability token — it carries specific permissions, constraints, and delegation rules as part of its cryptographic structure.

# Root macaroon: access to translation API
macaroon = new_macaroon(root_secret, identifier, location)

# Add constraining caveats
macaroon.add_first_party_caveat("budget_max = 50.00")
macaroon.add_first_party_caveat("endpoints = /translate/*")
macaroon.add_first_party_caveat("expires = 2026-04-01T00:00:00Z")

Attenuation: The Secret Sauce of Delegation

Anyone holding a macaroon can add more caveats to create a more restricted token. This is called attenuation, and it’s the foundation of safe delegation.

# Agent A delegates to Agent B with stricter limits
agent_b_macaroon = attenuate(agent_a_macaroon, [
  "budget_max = 10.00",      # Stricter than parent
  "endpoints = /translate/en-es"  # More specific
])

When to Use Each Approach

API Keys work for:

  • Human developers managing credentials manually
  • Simple binary permissions
  • Account-level budget enforcement

Macaroons work for:

  • AI agents needing bounded authority
  • Fine-grained permissions and budgets
  • Safe delegation without manual key management
  • Real-time budget enforcement

The Strategic Advantage

API providers who adopt capability-based authentication early gain a significant competitive advantage in the agent economy. Enterprises can safely integrate AI agents without cost or security risks.

Read the complete analysis with implementation details at: https://satgate.io/blog/macaroon-tokens-vs-api-keys

Reflecting on “dead” communities, engagement, and AI

Admittedly this is a bit ranty, and if that’s not your jam, feel free to skip.

I stopped scrolling most social media feeds when the slop arrived. First it came in the form of images, big awkward hero images that were psychedelic or had too many arms and fingers. Then it shifted to listicle after listicle. Then the articles that inserted a new line after every… single… sentence.

I was over it.

The personal voice and opinions were gone. The images were uncomfortably odd for my brain to process. The attention grabbing tactics were at an all time high and it just wasn’t doing it for me anymore.

So I stopped scrolling. The community that existed on those platforms were dead to me.

This means I missed things like your promotion or new job or even some significant tech news. Eventually the important things did find me, but I never found myself missing scrolling. I took that energy to engage somewhere else.

Fast forward to people saying “this community is dead” or “that community has an engagement problem”. The “community” has likely been taken over by garbage that doesn’t foster engagement, so the people left. Myself included. Communities are living, breathing organisms and when you fill them with trash, they simply cannot thrive.

This isn’t a post to bash on the admins or the moderators, if they even exist on a particular platform, because that’s a hard job, and where do you draw the line in this AI-enabled world? You need content, but you also need engaging content. You need engaged users, but you may need to re-engage users who left. Do we even have the tools and understanding to manage this? Do these platforms have community managers or teams evaluating this?

Now more than ever people are looking for community, on and offline. They crave it for a variety of reasons, but a sense of belonging, trust, and safety remains. They want to be part of something that connects them to other people in a positive way. People will cultivate community spaces when they feel empowered, dare I say emboldened, to do so. Active and engaged participation is the goal, not casual drive-by headline reading. You want people excited and enthusiastic to show up. And show up regularly.

So why mention this? Why post this?

  1. Because I love to complain. But mostly if I’m complaining about something, it’s because I’m passionate about it. I strongly believe active participants in communities encourage others to do the same – be active participants.

  2. Because I think we are over indexing on “communities are dead” and blaming AI. Have you considered that your AI-generated content isn’t engaging? Have you considered comments are more important than views, and provoking a discussion is maybe more meaningful? Have you considered you might be the problem, with or without AI?

2026 is apparently the year where I’m just going to say “we have to live in community” over and over again until I hear people say it back to me. But it’s true! If you want an engaged community, you need to lead by example and cultivate the environment you are looking for.

Does that mean I’m suggesting you can’t use AI in your blogs? No. But it does mean you should evaluate your blogs for engagement, AI or otherwise. Would you read it? Would you comment on it if someone else wrote it?

Are your actions or participation a value-add? Because we can’t put admins, moderators, and community managers solely responsible for supporting healthy communities. There needs to be some level of personal accountability.

And maybe it’s more obvious in offline spaces. You won’t attend another meetup or event where you felt unsafe or uncomfortable. So if a weird AI hero image made you uncomfortable, why would you read the content underneath? Are you seeing the connection here?

So I’m really interested in challenging this idea that a particular community is dead. Is it dead? Did you or do you positively or negatively contribute to it? And what does it mean to you if it’s gone forever?

How important is a community to you? And how actively will you participate going forward?

Photo by mauro mora on Unsplash