Agentic AI Patterns Reinforce Engineering Discipline

Paul Duvall recently discussed his library of engineering patterns for AI assisted development and practices that ground high quality delivery. Related discussions from Paul Stack and Gergely Orosz highlight a shift toward remixing and specification driven development.

By Rafiq Gemmail

Your Ruby CSV Import Ran Successfully — Your Data May Still Be Wrong

Are you sure that Ruby CSV imported all your data — and correctly? 🤔

I wasn’t looking for bugs. I was improving the performance of smarter_csv, then added a new round of tests — including some borrowed from Ruby CSV’s own test suite as a sanity check. Then I started thinking through error scenarios. What I found was genuinely surprising — which also led me to realize that smarter_csv needed a reliable mechanism for bad row quarantine.

I found 10 failure modes in Ruby CSV that produce no exception, no warning, and no indication that anything went wrong. Your import runs. Your tests pass. Your data is quietly wrong.

The one that still gets me: CSV’s numeric conversion silently converts the ZIP code “00123” into 83 🤯. Not a rounding error — a completely different number, because it interprets leading zeros as octal. ZIP codes, customer IDs, order numbers — all silently replaced with wrong integers that pass every validation, look plausible, and get stored in your database.

Or this: a user uploads a tab-separated file named .csv — your file-type guard passes, Ruby CSV sees no commas, treats each entire row as a single field, and returns what looks like valid data. All column structure is silently gone.

I wrote up all 10, with reproducible examples you can download and run yourself:
👉 10 Ways Ruby’s CSV.read Can Silently Corrupt or Lose Your Data

SmarterCSV 1.16 addresses all of these — 1.8×–8.6× faster than CSV.read end-to-end, with a bad-row quarantine system, and instrumentation hooks:
👉 SmarterCSV 1.16 Released

Found something? Issues and feedback and bug reports are always welcome in the GitHub Discussions or Issues.

Do you have a success story you can share? We love hearing back from you.

REST vs GraphQL vs WebSockets vs Webhooks: A Real-World Decision Guide (With Code)

You have used all of these. But when someone asks you, maybe in an interview, or in a system design meeting, why you chose WebSockets over polling, or webhooks over a queue, can you answer precisely?

This isn’t another definitions post. This article is about knowing which tool to reach for and why, with code you can actually use.

Quick mental model before we start:

Communication patterns  →  REST | GraphQL | WebSockets | Webhooks
Code execution model    →  async/await

These live at different layers. Conflating them is the most common source of confusion.

async/await: The Foundation, Not the Feature

Let’s kill one myth immediately: async/await is not a communication pattern. It’s how your server handles waiting.

Every I/O operation — database queries, HTTP calls, file reads — makes your code wait. async/await ensures that waiting doesn’t freeze every other user’s request.

# BAD: blocks the event loop - all other requests stall for 40ms
@app.get("/order/{id}")
def get_order(id: int):
    order = db.execute("SELECT * FROM orders WHERE id = %s", id)  # blocking
    return order

# GOOD: yields control during the wait - other requests run while DB responds
@app.get("/order/{id}")
async def get_order(id: int):
    order = await db.fetch_one("SELECT * FROM orders WHERE id = $1", id)
    return order

When it matters most: High-concurrency services. A delivery platform handling 500 simultaneous drivers checking order status. An NGO dashboard pulling live survey data.

The trap: Calling a synchronous library inside an async function. This blocks the entire event loop.

import requests  # synchronous - don't use this inside async functions
import httpx     # async-capable - use this instead

# WRONG
async def fetch_rate():
    r = requests.get("https://api.exchangerate.host/latest")  # blocks event loop
    return r.json()

# CORRECT
async def fetch_rate():
    async with httpx.AsyncClient() as client:
        r = await client.get("https://api.exchangerate.host/latest")
        return r.json()

REST: Default Choice for Good Reason

Use REST when:

  • The client initiates all interactions
  • Data doesn’t change faster than the user refreshes
  • You’re building standard CRUD
from fastapi import FastAPI
from pydantic import BaseModel

app = FastAPI()

class Order(BaseModel):
    customer_id: int
    items: list[str]
    total: float

@app.get("/orders/{order_id}")
async def get_order(order_id: int):
    order = await db.fetch_one("SELECT * FROM orders WHERE id = $1", order_id)
    return order

@app.post("/orders")
async def create_order(order: Order):
    result = await db.execute(
        "INSERT INTO orders (customer_id, items, total) VALUES ($1, $2, $3) RETURNING id",
        order.customer_id, order.items, order.total
    )
    return {"order_id": result["id"]}

@app.delete("/orders/{order_id}")
async def cancel_order(order_id: int):
    await db.execute("UPDATE orders SET status = 'cancelled' WHERE id = $1", order_id)
    return {"status": "cancelled"}

Real-world scenario: A SACCO member portal. Members log in, check their loan balance, submit a loan application. All request/response. No data is changing while they’re looking at a page. REST is perfect.

Production considerations:

  • Add proper HTTP caching headers (Cache-Control, ETag) – REST can be highly cacheable
  • Version your APIs (/v1/orders) from day one
  • Return proper status codes (201 for created, 404 for not found, 422 for validation errors – FastAPI handles this automatically)

GraphQL: REST With Client-Controlled Queries

Use GraphQL when:

  • Multiple clients (mobile, web, third-party integrations) need different shapes of the same data
  • You’re constantly over-fetching or under-fetching with REST
  • You have deeply nested, relational data
# Using Strawberry (best GraphQL library for FastAPI)
import strawberry
from fastapi import FastAPI
from strawberry.fastapi import GraphQLRouter

@strawberry.type
class Order:
    id: int
    total: float
    status: str

@strawberry.type
class User:
    id: int
    name: str
    email: str
    orders: list[Order]

@strawberry.type
class Query:
    @strawberry.field
    async def user(self, id: int) -> User:
        return await get_user_with_orders(id)

schema = strawberry.Schema(query=Query)
graphql_router = GraphQLRouter(schema)

app = FastAPI()
app.include_router(graphql_router, prefix="/graphql")

Now a mobile app can request exactly what it needs:

# Mobile - bandwidth-conscious, needs minimal data
query {
  user(id: 1) {
    name
    orders(last: 3) {
      id
      status
    }
  }
}

# Web dashboard - needs full details
query {
  user(id: 1) {
    name
    email
    orders {
      id
      total
      status
      items { name price }
    }
  }
}

Real-world scenario: An NGO platform serving both field officers on 2G mobile and HQ analysts on desktops. Field officers need lightweight data. Analysts need full datasets. GraphQL lets one API serve both without maintaining separate endpoints.

Production considerations:

  • Implement depth limiting to prevent abusive nested queries
  • Add query complexity analysis: prevent user → orders → user → orders recursion
  • GraphQL doesn’t cache well at HTTP layer: use DataLoader for N+1 query prevention
  • Don’t default to GraphQL for simple services: it adds real overhead

WebSockets: When the Server Needs to Talk First

Use WebSockets when:

  • Data changes continuously, and the user needs to see updates immediately
  • Polling would generate unacceptable load or latency
  • Both client and server need to send messages freely
from fastapi import FastAPI, WebSocket, WebSocketDisconnect
from typing import dict

app = FastAPI()

# Connection manager for multiple clients
class ConnectionManager:
    def __init__(self):
        self.active: dict[str, WebSocket] = {}

    async def connect(self, user_id: str, websocket: WebSocket):
        await websocket.accept()
        self.active[user_id] = websocket

    def disconnect(self, user_id: str):
        self.active.pop(user_id, None)

    async def send_to_user(self, user_id: str, message: dict):
        ws = self.active.get(user_id)
        if ws:
            await ws.send_json(message)

    async def broadcast(self, message: dict):
        for ws in self.active.values():
            await ws.send_json(message)

manager = ConnectionManager()

@app.websocket("/ws/track/{driver_id}")
async def track_driver(websocket: WebSocket, driver_id: str):
    await manager.connect(driver_id, websocket)
    try:
        while True:
            data = await websocket.receive_json()
            # Driver sent a location update - broadcast to assigned rider
            if data["type"] == "location_update":
                await manager.send_to_user(
                    data["rider_id"],
                    {"type": "driver_location", "lat": data["lat"], "lng": data["lng"]}
                )
    except WebSocketDisconnect:
        manager.disconnect(driver_id)

Real-world scenario: A ride-hailing app showing a driver moving on the map in real time. The driver’s app sends GPS coordinates every 3 seconds over a persistent WebSocket. The rider’s app receives them without polling. This would require: 1,000 REST requests per ride if you used polling at 3-second intervals.

Production considerations:

  • Persistent connections consume server resources — plan for horizontal scaling early
  • Use Redis Pub/Sub to share WebSocket state across multiple server instances
  • Always handle WebSocketDisconnect — clients drop off constantly (network, battery, background app)
  • Heartbeats keep connections alive through load balancers that close idle connections after 60 seconds
# Heartbeat to keep connection alive
@app.websocket("/ws/live")
async def live_feed(websocket: WebSocket):
    await websocket.accept()
    try:
        while True:
            try:
                # Wait for message with 30s timeout
                data = await asyncio.wait_for(websocket.receive_json(), timeout=30.0)
                await handle_message(data)
            except asyncio.TimeoutError:
                # Send ping to keep connection alive
                await websocket.send_json({"type": "ping"})
    except WebSocketDisconnect:
        pass

Webhooks: Event Notification Between Services

Use webhooks when:

  • An external system needs to notify your system that something happened
  • You don’t control the other system’s push mechanism
  • You want event-driven integration without maintaining a persistent connection
import hmac
import hashlib
from fastapi import FastAPI, Request, HTTPException

app = FastAPI()

WEBHOOK_SECRET = "your_flutterwave_webhook_secret"

def verify_flutterwave_signature(payload: bytes, signature: str) -> bool:
    expected = hmac.new(
        WEBHOOK_SECRET.encode(),
        payload,
        hashlib.sha256
    ).hexdigest()
    return hmac.compare_digest(f"sha256={expected}", signature)

@app.post("/webhooks/payment")
async def payment_webhook(request: Request):
    # 1. Verify the request is actually from Flutterwave
    signature = request.headers.get("verif-hash", "")
    body = await request.body()

    if not verify_flutterwave_signature(body, signature):
        raise HTTPException(status_code=401, detail="Invalid signature")

    payload = await request.json()
    event_id = payload["data"]["id"]

    # 2. Idempotency - Flutterwave WILL retry on 500s
    if await db.webhook_event_exists(event_id):
        return {"status": "already_processed"}

    # 3. Acknowledge immediately, process async
    # Don't do heavy work here -- return 200 fast, process in background
    await background_tasks.add_task(process_payment_event, payload)
    await db.mark_webhook_received(event_id)

    return {"status": "received"}

async def process_payment_event(payload: dict):
    order_id = payload["data"]["meta"]["order_id"]
    await db.execute(
        "UPDATE orders SET status = 'paid', paid_at = NOW() WHERE id = $1",
        order_id
    )
    await send_confirmation_email(order_id)

Real-world scenario: Your Kenyan e-commerce platform integrates Mpesa via Daraja API. When a customer pays, Safaricom calls your /webhooks/mpesa endpoint with the transaction details. You mark the order paid and send a confirmation SMS. No polling. No persistent connection.

Production considerations:

  • Always return 200 fast; the webhook caller will retry if you’re slow or error
  • Never trust webhook data without verifying the signature
  • Log every webhook payload for debugging; payment disputes will happen
  • Queue heavy processing (emails, SMS, inventory updates) with a background worker

Real-World Architecture: All Four Together

Here’s how a production fintech app in Kenya uses all of these together:

┌──────────────────────────────────────────────────────────┐
│               Mobile/Web Client                          │
└───────┬───────────────────┬─────────────────┬────────────┘
        │                   │                 │
   REST (CRUD)         WebSocket         GraphQL
   POST /loans         /ws/notifications   /graphql
   GET /balance        (real-time alerts)  (analytics)
        │                   │                 │
┌───────▼───────────────────▼─────────────────▼────────────-┐
│                  FastAPI Backend                          │
│              (all async/await internally)                 │
└───────┬───────────────────────────────────────────────────┘
        │
   Webhook receiver
   POST /webhooks/mpesa   ← Safaricom calls this
   POST /webhooks/credit  ← Credit bureau calls this

Each pattern handles exactly what it’s good at. The async/await inside FastAPI makes sure none of them block each other.

When to Use What: Decision Framework

Signal Use
Client requests data on demand REST
Multiple clients need different data shapes GraphQL
User needs to see live updates without refreshing WebSocket
External service needs to notify your backend of events Webhook
Your code waits on database, HTTP, or file I/O async/await

Hard rules:

  • If polling interval < 5 seconds and data changes frequently → switch to WebSocket
  • If you have > 3 different client types with different data needs → consider GraphQL
  • If you’re integrating a payment provider, shipping tracker, or auth service → expect webhooks
  • If you’re running FastAPI → use async def everywhere there’s I/O, no exceptions

Common Mistakes (Those That Hurt in Production)

1. requests inside async def: blocks the entire event loop. Use httpx with await.

2. No idempotency on webhook handler: payment events get retried. Without idempotency checks, you’ll charge customers twice.

3. WebSocket without reconnection logic: mobile networks drop. Your client-side WebSocket needs exponential backoff reconnection, or users see frozen data silently.

4. Assuming GraphQL is real-time: GraphQL subscriptions require a separate WebSocket-based setup. Standard queries/mutations are still request/response.

5. No signature verification on webhooks: your endpoint is public. Anyone can POST to it. Always verify HMAC signatures.

6. Keeping heavy processing in the webhook handler: the caller expects a fast response. Queue everything with a task worker (Celery, ARQ) and return 200 immediately.

If you found this helpful, please share it with others who it might help. And if you have questions, kindly drop them in the comments below!

Rose Wabere – Data & Analytics Engineer, Nairobi. Building real-world data systems with Python, FastAPI, and whatever tool the problem actually needs.

Cómo crear un chatbot de WhatsApp con n8n, aws y OpenAI

Si quieres crear tu propio chatbot de WhatsApp para recibir mensajes de texto y voz, procesarlos con IA y responder automáticamente, esta guía te muestra una forma práctica de hacerlo con n8n + OpenAI + Meta + AWS.

🧠 ¿Qué vas a aprender?

En este post vas a ver cómo:

  • Conectar los servicios de IA de OpenAI con n8n

  • Conectar los servicios de WhatsApp Business Cloud con n8n

  • Recibir mensajes de texto, voz y responder automáticamente desde un workflow de n8n.

  • Estimar costos básicos de operación

🛠️ Implementación paso a paso

1. Prerrequisitos ✅

Antes de empezar, necesitas:

2. Importa chatbot workflow 💬

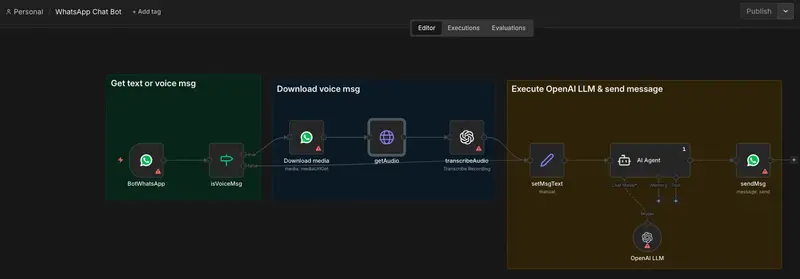
Importar el flujo de proceso (workflow) que se encuentra en la carpeta n8n del repositorio whatsapp-chatbot. Copia y pega el contenido del archivo whatsapp-chatbot.json en n8n. Este proceso permite:

  • Recibir mensajes de texto o voz desde WhatsApp
  • Identificar si el contenido es audio
  • Descargar el audio y transcribirlo
  • Ejecutar modelo de LLM de OpenAI
  • Envíar la respuesta nuevamente a WhatsApp

3. Configurar OpenAI en n8n 🧠

Para ejecutar los modelos Large Language Model (LLM) de OpenAI en n8n se necesita una API Key para autenticar las solicitudes realizadas desde n8n. Los pasos son:

  1. Ingresar a Platform OpenAPI con tu cuenta
  2. En el panel lateral ingresar a API Key para crear la llave
  3. En el flujo de proceso de n8n, con el nodo de Transcribe Recording, configurar las credenciales OpenAI account.

4. WhatsApp Business API 📲

Para recibir y enviar mensajes de voz y texto desde WhatsApp se debe crear una aplicación en META Developer y configurarla para obtener las credenciales necesarias que permitan la conexión desde n8n. Los pasos son:

  1. Crear una aplicación en el portal META Developers.
  2. Añadir caso de uso Connect with customers through WhatsApp.
  3. Confirmar la creación de la aplicación.

Enviar mensajes hacia WhastApp 📤

Para habilitar el envío de mensajes a WhatsApp desde n8n se requieren credenciales de autenticación para que WhatsApp acepte las solicitudes realizadas desde n8n. Los pasos son:

  1. En Meta Developer, ingresar a la personalización del caso de uso de Connect with customers through WhatsApp de la aplicación, en la sección de de configuración de la API, copiar Identificador de la cuenta de WhatsApp Business

  2. En META Business, con el portafolio empresarial usado en la creación de la aplicación, opción usuario del sistema, seleccionar un usuario existente o crear uno nuevo.

  3. Asignar la aplicación de Meta Developer como activo al usuario del sistema.

  4. Generar un identificador para la aplicación seleccionando una vigencia del identificador y la asignación de permisos que deben ser whatsapp_business_messaging.

  5. En el flujo de proceso de n8n, con el nodo de Send Message de WhatsApp Business Cloud, crear las credenciales de WhatsApp account, copiando los valores de los puntos 1 y 4, y probar la conexión.

Recibir mensajes desde WhatsApp 📥

Vamos a usar los números de pruebas de WhatsApp para recibir los mensajes, para usar números propios seguir los siguientes pasos. Cada mensaje recibido desde el número configurado en la aplicación ejecuta un WebHook (Servicio Web de n8n) para notificar la recepción del mensaje y el contenido del mismo. Los pasos para la obtención de la credenciales y la configuración del WebHook son:

  1. En Meta Developer, ingresar a la información Básica de la Aplicación en la sección de Configuración para consultar el App ID y App Secret.

  2. En el flujo de proceso de n8n, con el nodo de WhatsApp Business on Message , crear credenciales WhatsApp OAuth account, con los valores del App ID y App Secret, posteriormente probar la conexión.

  3. Publicar el flujo de proceso de n8n, para que estén expuestos sus servicios en internet.

  4. En el flujo de proceso de n8n, con el nodo de WhatsApp Business on Message de n8n, copiar la URL Post de Producción que es el Servicio Web expuesto por tu instalación de n8n para ser invocado cada vez que se recibe un mensaje en WhatsApp.

  5. En Meta Developer, ingresar a la personalización del caso de uso de Connect with customers through WhatsApp de la aplicación, en la sección de configuración, e ingresa la URL del punto 4 con un identificador de verificación. Posterior probar la conexión.

5. Probar el chatbot 🤖

Utilizando los números de celular de WhatsApp de pruebas podemos ejecutar el flujo de proceso de WhatsApp Chat Bot. Los pasos son:

  1. En META Developer, ingresar a personalizar el Casos Uso WhatsApp de la aplicación, en la opción Configuración de la API, copiar el número de prueba.

  2. Ingresar a tu WhatsApp y enviar mensaje al número del punto 1.

Costos 💰

OpenAI API 🤖

El costo de usar la API de OpenAI depende principalmente de tres variables: el modelo elegido, la cantidad de tokens procesados y el tipo de uso (entrada y salida). El costo se calcula por cada millón de tokens (texto procesado), donde el output (respuesta del modelo) suele ser entre 3 y 6 veces más caro que el input (texto enviado).

Modelo Input ($/1M tokens) Output ($/1M tokens) Contexto Uso recomendado
GPT-5.4 $2.50 $15.00 ~1M tokens Alta complejidad, agentes
GPT-5.4 mini $0.75 $4.50 400K tokens Apps, SaaS, chatbots
GPT-5.4 nano $0.20 $1.25 ~400K tokens Diseñado para: clasificación extracción pipelines masivos

Cálculo mensual estimado 📊:

Conversación en WhatsApp de 1–5 min

  • Mensajes por conversación: 6–12
  • Palabras por mensaje: 8–15
  • Promedio total palabras: ≈ 120 palabras

Conversión estándar:

  • 1 token ≈ 0.75 palabras
  • 120 palabras ≈ 160 tokens
Tipo Tokens
Input usuario 80 tokens
Output modelo 80 tokens
Total 160 tokens

Escenario mensual 📅

Supón: 10,000 conversaciones / mes

Modelo Costo mensual
GPT-5.4 $14 USD
GPT-5.4 mini $4.2 USD
GPT-5.4 nano $0.4 USD

Meta API 📱

El modelo de costos de WhatsApp Business API funciona principalmente bajo un esquema de mensajes por categoría, donde el cobro depende del tipo de interacción y de quién inicia la conversación. Existen cuatro categorías: servicio, utilidad, autenticación y marketing. Los mensajes de servicio (cuando el cliente escribe primero) son gratuitos y permiten responder libremente dentro de una ventana de 24 horas con texto, audio, imágenes o documentos.

Cálculo mensual estimado 📈

  • 600 mensajes de servicio iniciados por clientes → USD 0

Total Meta estimado 💵: USD 0/mes

n8n

Los costo de n8n dependen del la infraestructura y el número de ejecuciones del flujo del proceso, es decir en el número de conversaciones que se reciban en el chatbot. La comparación de opciones de uso de n8n con infraestructura en aws o de n8n.io es:

Variable Self-hosted (AWS) Cloud Starter Cloud Pro
💰 Costo base Bajo (infra + ops) Medio (~€20–€30/mes) Alto (~€50–€100+/mes)
⚙️ Infraestructura Tu responsabilidad (AWS, VPS, etc.) Incluida Incluida
🔁 Ejecuciones (workflows) Ilimitadas (según tu infra) Limitadas (~5k–10k/mes) Más altas (~20k–50k+/mes)
🚀 Escalabilidad Manual Automática (limitada) Automática (mejor)
🔐 Seguridad Total control Gestionada por n8n Gestionada por n8n
🔄 Concurrencia Depende de recursos Limitada Mayor concurrencia
🔌 Integraciones Todas Todas Todas
🛠️ Mantenimiento Alto (requiere DevOps) Bajo Bajo
👥 Multiusuario Configurable manual Limitado Completo (roles y equipos)

Human-AI Interaction Is Here: Why Your Current UX/UI Design Is Already Obsolete

Generative AI is driving at the speed of Ferrari, offering a new type of interaction in digital product user experience: humans and AI are becoming best pals. Instead of buttons, we see prompts; instead of just navigation, we see intent detection, and instead of forms, we see live conversations. All these changes belong to a new paradigm of generative UI, where interfaces respond to human input.

The uncomfortable truth is that many designers intend to leverage the power of AI; however, some end up making their UX even worse. So, how does AI belong in modern digital products? I am going to share with you where smart technologies improve the experience and where traditionally crafted interfaces outperform intelligence.

Did AI Shift Happen Overnight?

At some point, when I opened my Notion tab, I realized that I was no longer navigating the same interface I used to. In the past, I had to search through menus and configure my workflows; now, I see how intelligent systems anticipate my intent.

The same transformation happened to Figma. Their auto-layout suggestions, smart alignment, content-aware spacing, and responsive sizing became natural extensions of the existing functionality.

So, there was no big moment when those products became “AI products”. They gradually dissolved intelligence into their workflows. And now I am not just using AI. I am designing faster, with fewer interruptions, and with less cognitive load.

Where AI Reshapes Interfaces

AI in UI/UX design is not only a flashy “ask AI” button. It is the implementation in the interaction models. Nowadays, you can see such examples where intelligence defines how users search, find, act, and decide through:

  • Intelligent search assistants. Sometimes, I ask myself a question: “Does this search agent understand me better than my partner?” But jokes aside, modern intelligent search assistants understand intent, context, and ambiguity. From a user perspective, this significantly reduces cognitive load while the interface dynamically adjusts.
  • Context-aware UI. One-dashboard-suits-all is no longer interesting. AI enables interfaces to change based on user role, behavior, progress, and past patterns. Users can see highlighted data, prioritized actions, or suggested next steps.
  • Automated data preparation and setup flows. I always feel comfortable when I shop on my favorite service, proceed to the checkout, and see my details already prefilled. This makes me want to buy more and often. AI removes setup friction, making the journey very smooth.

Design Without AI Is the New Technical Debt

AI should not be added to interfaces just because it is trendy. However, some complex data-heavy and context-dependent UX issues can no longer be solved with static rules and screens.

Let’s take adaptive interfaces, for example. Traditional UI/UX design approaches rely on predefined states and decision trees. But AI-powered interfaces can go far beyond. They can use probabilistic reasoning to adjust what is shown on the screen based on real user characteristics and behavioral patterns.

AI also improves the scalability of the experience from an engineering standpoint. As the product evolves, edge cases multiply, user needs diversify, and data volumes explode. How would you expect to design a separate interface path for each scenario? Without AI, it would be impossible to do that. But machine learning can generalize the scenarios and apply shared logic.

AI Is Not Always a Step Forward
AI is a great addition, but not a foundation of the whole digital product. The human remains the center of attention, and not all advancements are easily understood by our brains. Conversational interfaces are not a universal replacement for graphical user interfaces, and here is why:

  • Text and visual scanning. AI assistants present information in blocks of text. In order to get the point, users need to read linearly, sentence by sentence. However, graphic UIs present data spatially through charts, icons, graphs, and layouts. The key insights are grasped in seconds.
  • Cognitive load and information density. Well-crafted interfaces compress meaning by showing icons instead of words, turning sentences into short labels, and transforming flows into diagrams. With AI-generated text, the cognitive load is higher as users need to parse through the output.
  • Action discovery and step-by-step guidance. Graphical interfaces display multiple possible actions at once. Users can quickly choose the needed option. AI agents, by nature, are prone to reveal information sequentially. While beginners might enjoy this interaction, seasoned users will be slowed down.

Where AI Strengthens UX Instead of Replacing It

Smart intelligence delivers real value in the areas where it operates behind the interface. It works well in reducing cognitive load, automating repetitive tasks, and speeding up decision-making. The best implementations don’t use “loud words” to talk to people. They optimize workflows while users focus on what matters the most.

While working on AI-driven products, I noticed that those technologies work best by accelerating workflows and freeing humans to do high-value work, as in the case of the Sully.AI product. This platform is designed for healthcare professionals to eliminate the time-consuming work of nurses, doctors, and administrators.

Instead of a single chatbot, we built nine specialized AI agents who serve clear roles: triage nurses, receptionists, and other medical assistants. Every dedicated AI specialist supports a defined interaction layer, while the graphic UI remains the control center. Thus, medical staff spend less time navigating systems and doing paperwork.

In another case, a U.S.-based construction permit platform has to submit a massive amount of documents to local authorities before starting a project. AI was introduced as a preliminary validation layer inside the existing UI. Before sending documentation to the authorities, AI checks it for compliance and flags inconsistencies or missing data. As a result, developers get a faster feedback loop and public officials have a reduced load.

When AI Should Step Aside

AI is not a solution for every UI/UX challenge. If a task is faster, clearer, and more intuitive to complete through a graphic interface, like filling out a form, complicating it with advanced technologies can slow down the user.

Research comparing conversational interfaces with traditional forms confirms that users complete structured tasks faster and with fewer errors when information is presented visually instead of via chat-based interactions.

This aligns with broader usability findings that people don’t just read, they scan visual information and make choices instantly, while AI might present unnecessary instructions that increase cognitive load. In these cases, sticking to well-designed UI ensured great usability and user satisfaction.

Smart AI Placement
The guessing game is not the best approach in deciding where to integrate AI into your product UI/UX. I recommend teams answer those questions to build a clear implementation framework:

  1. Is the task ambiguous or open-ended? AI excels in processing complex, open-ended queries where setting predefined rules doesn’t work.
  2. Does the workflow require multiple structured steps? If you have repetitive tasks with stepwise processes, be sure to loop in the AI help for automation.
  3. What happens if the AI is wrong? Set your risk appetite and decide whether human oversight is necessary to catch mistakes before they turn into outcomes.
    The overall goal is to improve efficiency, not to introduce unnecessary complexity or friction.

Final Thoughts

AI is opening a door to immense personalized opportunities for UI/UX, but it doesn’t replace a thoughtful and deep human contribution. The real power is to combine those experiences, where smart technologies complement intuitive design.

Intelligent assistants can automate repetitive tasks, optimize workflows, and provide context-aware guidance. And graphical interfaces can ensure clarity, efficiency, and quick information scanning.

By going hybrid, you get the best of both worlds.

How TurboQuant Works for LLMs and Why It Uses Much Less RAM

Most conversations about scaling large language models focus on obvious factors like model size, training data, and GPU power. While those matter, they stop being the main constraint surprisingly quickly. Once you start dealing with long conversations and many users, memory becomes the limiting factor. Not just how much memory you have, but how efficiently you use it.

This is especially true during inference, when the model is actively generating responses. At that point, the system is not just running computations, it is also constantly reading and writing large amounts of intermediate data. That data, more than anything else, starts to define both cost and speed.

How LLMs actually store words like “cat”

When you type a word like “cat,” the model does not store it as text. It converts it into a vector of numbers, often thousands of values long. These numbers represent a position in a high-dimensional space where similar words are located near each other.

For example, in a simplified form:

cat → [0.21, -1.3, 0.7, 2.1, …]
dog → [0.25, -1.1, 0.6, 2.0, …]
car → [-2.0, 0.5, 1.2, -0.3, …]

Words like “cat” and “dog” end up close together, while “car” is far away. This is how meaning is encoded, not through definitions, but through relationships.

In real models, these vectors are much larger. A common size is around 4096 numbers per token. Each number is typically stored using 16 or 32 bits.

Why one word expands into thousands of numbers

What is less obvious is that the embedding vector is only the starting point. As the token moves through the model, it gets transformed at every layer. At each layer, the model produces two new vectors per token, called keys and values. These are stored in what is known as the KV cache so the model can refer back to earlier tokens.

If you actually calculate how many numbers are stored per token in a typical model, it looks like this:

32 layers × 2 (K + V) × 4096 ≈ 262,000 numbers per token

So a single word like “cat” ends up associated with hundreds of thousands of numbers as it moves through the model.

Why the KV cache consumes so much RAM

Once you understand how many numbers are involved, the memory usage becomes easier to grasp. Consider a conversation with around 2000 tokens. That leads to:

2000 × 262,000 ≈ 524,000,000 numbers

Even if each number is stored in 16 bits (2 bytes), that is roughly:

≈ 1 GB of memory for a single conversation

And this is just for the KV cache. In a real system serving many users simultaneously, this memory usage scales quickly into tens or hundreds of gigabytes.

An additional complication is that moving this data is expensive. In many cases, transferring data from memory is slower than performing the actual mathematical operations. This means memory bandwidth becomes a performance bottleneck.

Why reducing precision alone is not enough

A natural solution is to reduce how many bits are used per number. Instead of 16 or 32 bits, you could use 8 bits. This is a standard technique known as quantization.

It works to some extent, but pushing it too far causes problems. The model relies on subtle numerical relationships, especially in attention calculations. If the numbers become too coarse, those relationships break down and accuracy drops.

The key idea behind TurboQuant: scale plus codes

Instead of storing each number directly, TurboQuant and similar approaches store numbers in a structured way using a scale and a small integer code.

For example, instead of storing:

1.44

you might store:

scale = 0.5
code = 3

and reconstruct:

value ≈ scale × code = 1.5

This allows a small set of integers, represented with very few bits, to approximate a wide range of real values.

Here is a small illustrative example:

Original: [0.2, -0.9, 1.4, 0.6]
scale = 0.47
codes = [0, -2, 3, 1]
Reconstructed ≈ [0, -0.94, 1.41, 0.47]

The numbers are not exact, but they are close enough to preserve the overall structure.

How TurboQuant preserves attention accuracy

The main challenge with aggressive compression is that it can distort dot products, which are central to attention. Attention works by comparing vectors and deciding which previous tokens are most relevant.

TurboQuant addresses this by adding a lightweight correction step that reduces systematic errors introduced during compression. The goal is not to perfectly reconstruct every number, but to preserve the relative ordering of attention scores.

For example, suppose the model computes:

Token A → 5.36
Token B → 3.18

After compression, this might become:

Token A → 5.10
Token B → 3.28

The exact values change, but the ordering stays the same. Token A is still more important than Token B, so the model behaves the same way.

How much RAM TurboQuant actually saves

By reducing the number of bits per value to around 3 bits, TurboQuant can significantly shrink the KV cache. In practice, reported results suggest around a 6× reduction in memory usage.

That means a KV cache that previously required about 1 GB could be reduced to roughly:

≈ 150–200 MB

This has several practical benefits:

  • longer context windows become feasible
  • more users can be served per GPU
  • latency improves due to reduced memory movement

A useful way to think about TurboQuant

One way to understand this is to compare a full transcript with a set of notes. Without compression, the model stores a very detailed numerical record of everything it has seen. With TurboQuant, it stores a compressed version that keeps what matters for future decisions.

The details are not perfectly preserved, but the relationships are. And for the model, that is what matters most.

Why this matters for the future of LLMs

As models continue to grow and context lengths increase, memory and memory bandwidth are becoming central challenges. Techniques like TurboQuant suggest that significant efficiency gains are still possible without changing model architecture or training methods.

At a deeper level, this highlights how LLMs actually work. They operate on vectors and relationships in high-dimensional space. Once you accept that, it becomes clear that exact precision is often unnecessary. What matters is preserving the structure of that space well enough for the model to make correct decisions.

TurboQuant is essentially an answer to that question: how much can we compress these representations while keeping the model’s behavior intact? The answer, at least so far, is that we can compress them far more than most people would expect.

Stop Searching, Start Contributing: How GoodFirstGo is Making Open Source Approachable

Remember the first time you tried contributing to open source?

If you were like most developers, the experience involved staring at a massive, complex codebase on GitHub, clicking the Issues tab, and immediately feeling overwhelmed. The ecosystem is massive, and while hundreds of maintainers out there are actively asking for help, finding those rare “beginner-friendly” issues requires sifting through mountains of bugs and features that require deep domain knowledge.

I realized developers shouldn’t have to write custom GitHub API queries or dig through unrelated repositories just to make their first Pull Request.

That’s exactly why I built GoodFirstGo.

What is GoodFirstGo?
GoodFirstGo is a CLI tool built entirely in Go that brings the perfect open-source issues directly to your terminal.

Instead of mindlessly browsing GitHub, you tell the CLI what language you want to work in, and it hands you a curated list of active repositories searching for help with the good-first-issue label.

Key Features Under the Hood
1.Smart Language Filtering: Want to practice your Python? Rust? Go? Just pass a --language flag.
2.Repository Health Filters: Filter out dead projects by mandating a minimum number of stars (--stars 100).
3.Recency: Nobody wants to comment on an issue from 2008. The --age flag ensures you’re only looking at issues created recently, this week, or this month.

  1. Mode: This is my favorite part. By passing the --learning flag, the CLI will output specialized tutorials and resources tailored to the specific language of the issue you are about to tackle!

Seeing it in Action
Because GoodFirstGo compiles down to a single binary, you don’t need any complex runtimes or dependencies to use it. If you have Go installed on your machine, getting started takes ten seconds:

bash
go install github.com/odingaval/GoodFirstGo/cmd/goodfirstgo@latest

Once installed globally, you can query GitHub instantly. Let’s say I want to find a beginner-friendly Go issue in a repository that has at least 500 stars, and I want to see learning resources for Go before I dive in.

I just type:

bash
goodfirstgo --language go --stars 500 --learning --limit 5

Instantly, I get a clean UI output of 5 high-quality repositories looking for help, right in my terminal window. Add a Github Token to your environment, and it bypasses rate limits entirely.

Why build a CLI instead of a website?
Modern web apps are great, but the Terminal is where developers live. By keeping the tool inside the CLI environment, you can search for issues, clone the resulting repository, and open your IDE without your hands ever leaving the keyboard.

Plus, writing a CLI in Go is just incredibly fun. It leverages Go’s standard net/http efficiently alongside Cobra for powerful, responsive shell commands.

Looking to Contribute?
The absolute best part about GoodFirstGo? Because it is a tool explicitly designed to get beginners into open-source software, the project itself is heavily monitored for first-time contributors!

If you’ve never made an open-source contribution before, cloning the repository and adding a small feature to GoodFirstGo is the perfect place to start.

Check out the source code, download the latest binary, or star the repository here: 👉 github.com/odingaval/GoodFirstGo

Let me know what your first Pull Request ends up being!

Engineer’s Guide to Surviving Global Cyber Compliance: Unpacking the OSPS Baseline

For years, open-source maintainers and platform engineers have operated under an unspoken social contract: we build the infrastructure of the internet, and you use it at your own risk.

Today, that contract is being torn up by international regulators.

With a 44% year-over-year increase in the exploitation of public-facing applications and the cost of cybercrime projected to hit $10.5 trillion annually, global legislation is radically shifting the landscape. We are moving from a fragmented, voluntary security culture into an era of strict, punitive frameworks like the EU’s Cyber Resilience Act (CRA), NIS2, and DORA.

For senior engineers, platform architects, and open-source maintainers, this regulatory wave feels like a looming administrative nightmare. However, a architectural Rosetta Stone has emerged to solvethis : OpenSSF OSPS (Open Source Security Practices) Baseline.

Here is the definitive breakdown of how the OSPS Baseline abstracts away the legal chaos, providing with a unified engineering framework to secure your supply chain without assuming commercial liability.

The Core Problem: The Legislative Wall
Currently, 26% of organizations view cyber regulations negatively, primarily because they struggle to ensure third-party and open-source vendor compliance. The legislation driving this panic includes:

  1. NIS2: Impacts 18 critical sectors (from energy to healthcare), indirectly forcing enterprises to secure their entire open-source supply chain to guarantee service continuity.
  2. DORA (Digital Operational Resilience Act): Imposes strict digital resilience and third-party risk management requirements specifically on the financial sector.
  3. Cyber Resilience Act (CRA): This is the most disruptive. It mandates “Security by Design” and “Security by Default,” but critically, it attempts to place strict legal and financial liability on the “manufacturer” (the entity placing the product on the market) for all components used—including open-source libraries.

Because CNCF and OSS projects power the world’s critical infrastructure, enterprise consumers are passing these regulatory burdens upstream, maintainers with endless, disparate security questionnaires.

The OSPS Baseline Architecture, released to bridge the gap between developers and regulators, the OSPS Baseline isn’t just another arbitrary standard; it is a highly prescriptive mapping tool. It translates vague legal requirements into strict engineering realities.

The baseline is structured mathematically around practical execution:

40 Mandatory Requirements: The baseline entirely rejects the ambiguous word “should” in favor of strict “must” controls, ensuring that every required action has a measurable impact on the project’s security posture.
3 Maturity Levels: It scales from Level 1 (Basic Hygiene), to Level 2 (Standardized), up to Level 3 (High Assurance).
8 Critical Areas: The framework maps directly to engineering workflows: Access control, build/release, documentation, governance, legal, quality, security assessment, and vulnerability management.

The true power of the OSPS Baseline lies in its strategic application. Here are the elite takeaways for navigating this new era:

  1. The “One-to-Many” Compliance Hack: You don’t have the engineering cycles to map your CI/CD pipeline to 50 different international laws. The OSPS Baseline acts as a multiplexer. By satisfying a single technical OSPS requirement—such as generating a cryptographic Software Bill of Materials (SBOM)—your project simultaneously checks the compliance boxes for the EU CRA, the US NIST SSDF, the NIST CSF, and Open Chain. Write the pipeline once, and the baseline translates it into global legal compliance.

  2. The Liability Shield (Maintainer vs. Manufacturer)
    There is a massive legal “moat” that OSS maintainers must understand. Under regulations like the CRA, open-source maintainers are not considered “manufacturers” or “economic operators,” meaning they do not bear financial or legal liability for the software.
    However, downstream commercial users do bear that liability. The strategy is to use the OSPS Baseline to provide voluntary, machine-readable signals of your security posture. By adopting the baseline, you hand enterprise users the exact due-diligence checklist they need to pass their audits, building immense trust and adoption, all while explicitly stating via disclaimers that you assume no commercial liability.

  3. Moving from “Trust Me” to Evidence-Based Trust
    The era of putting a “security.md” file in your repo and asking users to trust you is over. The future of operations relies on machine-readable attestations. The OSPS framework is actively driving toward a future of automated evaluation, where your project’s compliance with these 40 requirements is continuously verified and broadcasted to downstream consumers via automated tooling.

Global cyber compliance is no longer just a problem for the legal department; it is a distributed systems engineering challenge.

By adopting the OpenSSF OSPS Baseline, you stop treating security mandates as chaotic, disjointed chores. Instead, you integrate them into a unified, actionable framework. You protect your team from legal ambiguity, drastically reduce the toil of enterprise security audits, and guarantee that your architecture is resilient enough to power the next generation of critical infrastructure.

ERC-8004 Trustless Agents: Onchain Reputation for AI

Giving an AI agent access to your crypto wallet is like handing a toddler your credit card — without proper guardrails, things can go very wrong very quickly. When your agent can execute transactions autonomously, one misconfigured prompt or exploited vulnerability could drain your entire portfolio.

This isn’t a theoretical risk. As AI agents become more sophisticated at managing DeFi positions and executing trades, the attack surface grows exponentially. A compromised agent could approve unlimited token spending, interact with malicious contracts, or transfer funds to attacker-controlled addresses. Traditional wallet security assumes human oversight for every transaction, but autonomous agents break that assumption entirely.

Why Agent Security Requires a New Approach

Most wallet infrastructure treats security as binary — either you have access or you don’t. But AI agents operate in a gray area between full automation and human control. They need enough permissions to be useful (checking balances, executing trades, managing positions) while being restricted enough to prevent catastrophic losses.

The challenge goes beyond technical controls. You need visibility into what your agent is doing, the ability to intervene when something looks wrong, and confidence that your security policies will be enforced even when you’re not actively monitoring. This requires purpose-built infrastructure that assumes agents will eventually encounter edge cases, bugs, or adversarial inputs.

Three Layers of Protection

WAIaaS implements a defense-in-depth security model with three distinct layers between your AI agent and your funds.

Layer 1: Session Authentication with Limited Scope

Instead of giving your agent direct access to private keys, WAIaaS uses session-based authentication. Your agent gets a JWT token that expires and can be revoked instantly:

# Create a session with specific permissions
curl -X POST http://127.0.0.1:3100/v1/sessions 
  -H "Content-Type: application/json" 
  -H "X-Master-Password: my-secret-password" 
  -d '{
    "walletId": "your-wallet-uuid",
    "maxRenewals": 10,
    "ttl": 3600
  }'

The agent gets a session token that automatically expires, preventing long-term credential compromise. You maintain administrative control through the master password, while the agent operates with limited, revocable access.

Layer 2: Default-Deny Policy Engine

This is where WAIaaS differs fundamentally from traditional wallets. Instead of allowing everything by default, WAIaaS blocks all transactions unless explicitly permitted by your policies. Your agent literally cannot touch tokens or contracts you haven’t whitelisted.

Here’s a restrictive policy that only allows small USDC transfers:

curl -X POST http://127.0.0.1:3100/v1/policies 
  -H "Content-Type: application/json" 
  -H "X-Master-Password: your-password" 
  -d '{
    "walletId": "your-wallet-uuid",
    "type": "ALLOWED_TOKENS",
    "rules": {
      "tokens": [{
        "address": "EPjFWdd5AufqSSqeM2qN1xzybapC8G4wEGGkZwyTDt1v",
        "symbol": "USDC",
        "chain": "solana"
      }]
    }
  }'

Without this policy, your agent cannot transfer USDC at all. Even with this policy, you can layer on spending limits:

curl -X POST http://127.0.0.1:3100/v1/policies 
  -H "Content-Type: application/json" 
  -H "X-Master-Password: your-password" 
  -d '{
    "walletId": "your-wallet-uuid",
    "type": "SPENDING_LIMIT",
    "rules": {
      "instant_max_usd": 10,
      "notify_max_usd": 100,
      "delay_max_usd": 1000,
      "delay_seconds": 900,
      "daily_limit_usd": 5000
    }
  }'

This creates a four-tier security system:

  • Under $10: Execute immediately
  • $10-$100: Execute with notification
  • $100-$1000: Wait 15 minutes (cancellable), then execute
  • Over $1000: Require explicit human approval

Layer 3: Human Approval Channels

For high-value or unusual transactions, WAIaaS can require explicit human approval through multiple channels. When your agent tries to execute a transaction that exceeds your policy thresholds, it gets queued for approval rather than rejected:

# Agent attempts large transaction
curl -X POST http://127.0.0.1:3100/v1/transactions/send 
  -H "Content-Type: application/json" 
  -H "Authorization: Bearer wai_sess_your-token" 
  -d '{
    "type": "TRANSFER",
    "to": "recipient-address",
    "amount": "5000"
  }'

# Returns: {"status": "PENDING_APPROVAL", "id": "tx-uuid"}

You receive notifications through your configured channels and can approve via WalletConnect signatures. If something looks suspicious, you can reject the transaction or implement a kill switch to disable the agent entirely.

Contract and Method Whitelisting

Beyond token controls, WAIaaS implements contract-level security. Your agent can only interact with contracts you’ve explicitly approved:

curl -X POST http://127.0.0.1:3100/v1/policies 
  -H "Content-Type: application/json" 
  -H "X-Master-Password: your-password" 
  -d '{
    "walletId": "your-wallet-uuid",
    "type": "CONTRACT_WHITELIST",
    "rules": {
      "contracts": [{
        "address": "JUP6LkbZbjS1jKKwapdHNy74zcZ3tLUZoi5QNyVTaV4",
        "name": "Jupiter",
        "chain": "solana"
      }]
    }
  }'

You can further restrict this to specific function calls using METHOD_WHITELIST policies. This prevents your agent from calling unexpected functions even on approved contracts.

ERC-8004: Onchain Agent Reputation

For environments where agents interact with each other, WAIaaS supports ERC-8004 Trustless Agents — an onchain reputation system that tracks agent behavior and reliability. This allows you to set reputation thresholds for agents your system interacts with:

curl -X POST http://127.0.0.1:3100/v1/policies 
  -H "Content-Type: application/json" 
  -H "X-Master-Password: your-password" 
  -d '{
    "walletId": "your-wallet-uuid",
    "type": "REPUTATION_THRESHOLD",
    "rules": {
      "minimum_score": 80,
      "minimum_interactions": 100
    }
  }'

The WAIaaS MCP integration provides tools for checking agent reputation before interacting:

User: "Check the reputation of agent 0x123... before proceeding"
→ Claude calls erc8004-get-reputation tool
→ Returns reputation score and interaction history
→ Agent can decide whether to proceed based on reputation threshold

Transaction Simulation and Dry Runs

Before executing any transaction, you can simulate its effects without spending gas or risking funds:

curl -X POST http://127.0.0.1:3100/v1/transactions/send 
  -H "Content-Type: application/json" 
  -H "Authorization: Bearer wai_sess_your-token" 
  -d '{
    "type": "TRANSFER",
    "to": "recipient-address",
    "amount": "0.1",
    "dryRun": true
  }'

This returns the expected outcome, gas costs, and any policy violations without executing the transaction. Your agent can use this to validate transactions before submission, catching errors or policy violations early.

Monitoring and Observability

Security is only as good as your visibility into what’s happening. WAIaaS provides comprehensive logging and monitoring of agent activity:

  • All transactions are logged with full context
  • Policy evaluations are recorded with reasons for approval/denial
  • Session activity is tracked with renewal and expiration events
  • Real-time notifications for transactions exceeding thresholds

The 7-stage transaction pipeline provides granular visibility into where transactions succeed or fail: validation, authentication, policy evaluation, delay periods, execution, and confirmation.

Self-Hosted Security

WAIaaS runs entirely on your infrastructure, giving you complete control over the security model. There’s no third-party service that can be compromised or change their policies unexpectedly. Your private keys never leave your server, and you can audit the entire codebase since it’s open source.

The Docker deployment uses non-root containers (UID 1001), includes health checks, and supports Docker Secrets for production credential management:

# Production deployment with secrets
mkdir -p secrets
echo "your-secure-master-password" > secrets/master_password.txt
chmod 600 secrets/master_password.txt

docker compose -f docker-compose.yml -f docker-compose.secrets.yml up -d

Quick Start: Secure Agent Setup

Here’s how to set up a security-hardened agent wallet in five steps:

  1. Install and initialize WAIaaS:
npm install -g @waiaas/cli
waiaas init
waiaas start
  1. Create a restricted wallet:
waiaas wallet create --name "agent-wallet" --chain solana --environment mainnet
  1. Set up default-deny token policy:
curl -X POST http://127.0.0.1:3100/v1/policies 
  -H "Content-Type: application/json" 
  -H "X-Master-Password: your-password" 
  -d '{
    "walletId": "your-wallet-uuid",
    "type": "ALLOWED_TOKENS",
    "rules": {
      "tokens": [{"address": "EPjFWdd5AufqSSqeM2qN1xzybapC8G4wEGGkZwyTDt1v", "symbol": "USDC", "chain": "solana"}]
    }
  }'
  1. Configure spending limits with human approval:
curl -X POST http://127.0.0.1:3100/v1/policies 
  -H "Content-Type: application/json" 
  -H "X-Master-Password: your-password" 
  -d '{
    "walletId": "your-wallet-uuid",
    "type": "SPENDING_LIMIT",
    "rules": {
      "instant_max_usd": 1,
      "notify_max_usd": 10,
      "delay_max_usd": 100,
      "delay_seconds": 300,
      "daily_limit_usd": 50
    }
  }'
  1. Create a session and test restrictions:
waiaas session prompt --wallet your-wallet-uuid
# Agent now has limited access - test by attempting transactions above limits

Your agent can now operate within strict boundaries. It can check balances and execute small USDC transfers instantly, but anything significant requires your approval.

What’s Next

This security model scales from simple trading agents to complex DeFi portfolio managers. As your confidence grows, you can gradually relax policies while maintaining safety nets. The key is starting restrictive and expanding permissions based on observed behavior rather than hoping nothing goes wrong.

Explore the complete security reference and deployment guides at the official documentation: https://waiaas.ai. The full source code, including all security implementations, is available for audit at https://github.com/minhoyoo-iotrust/WAIaaS.

Building a LEGO-like remote Agent – Jean2

I’m a huge fan of coding agents. My daily consumption is at about 7 million tokens and growing. I started on Cursor, fell in love with OpenCode, got into customizing setups with MCPs, Skills, and subagent orchestration — all while daily-driving GLM, Minimax, GPT models, and everything I could get my hands on at OpenRouter just for the new and shiny.

I love squeezing the best possible answers from small models with the right prompts. At some point, I wanted to use OpenCode for everything, not just coding.

And then I kinda hit a wall.

The Wall

Baked-in steering

Coding agents come with baked-in prompts that already steer them in a certain direction — great for an out-of-the-box solution, not so great when you want full control. You can create your own agent with custom steering, but it’s always appended to whatever the system’s baked-in prompt already says.

Rigid tooling

Built-in tools are already great, but you can’t alter, remove, or modify them — not their prompts, not the tools themselves. Adding your own usually doesn’t feel the same. These systems aren’t really built around the concept of bringing your own tools. Want an extra capability? Bring an MCP or a skill.

Session management

The TUI is great, but managing multiple projects or conversations not tied to any specific project just wasn’t a comfortable experience. There are now GUI and Web options that handle it much better, but at the time, there weren’t really stable, comfortable choices.

Multi-device continuity

Throw the phone into the mix, and it wasn’t really there yet either. I just wanted to be able to create a spec doc with the agent on my phone, hand it off for execution, and review it on my laptop — seamlessly.

Enter Jean2

(Why Jean2 and not just Jean? Because Jean was kinda “not good.”)

So I started building. Here’s what came out of it:

Always running, seamless experience

Jean2 runs as a daemon with sockets and HTTP. The goal is a seamless experience — open a desktop client on your laptop, prompt what you want, pick up your phone, watch progress, and handle permissions. You can close the clients and leave it running with an 80–100 MB memory footprint across 3 different projects.

Absolutely and completely dumb

No baked-in prompts. Your agent system message and your AGENT.md files are the only things that form a system message. This means you’re not limited to building “your coding agent” — you can build “your [anything] agent.”

No baked-in tools

Well — that’s not completely true. Technically, handling MCP, skill lookup, and subagents are tools, but nothing else is baked in. Tools are completely language-agnostic. They’re spawned on demand and undergo an explicit, upfront security check that you define (if you want). You can yank anything out and drop anything in. All input is sent to tools via JSON stdin, and all results are expected in JSON stdout.

There’s also a built-in visualization property that lets the tool decide how to display its results: diff, code, markdown, table, todo list — you name it. (These data are omitted when making API requests to the LLM, naturally.)

Important: You are in control of the tool definition and its description. If you notice a model not using a tool properly, you can just change it.

What’s Next

Jean2 is still in active development — but it’s very usable. I’ve been coding with it for over a week.

The next steps are:

  • SDK & structured output — so you can create your own apps with agent orchestration
  • Multimodal model support
  • Expanded tool offering — fal.ai tools for image generation seem like a natural fit

If this sounds even a little interesting, check out jean2.ai.

Got questions, ideas for tools, or tried it out and got lost in the setup? Hit me up at @danielbilekq0.