İçişleri Bakanı Mustafa Çiftçi’den APP plaka ve araç içi multimedya sistemlerine yönelik yeni açıklamalar geldi

İçişleri Bakanı Mustafa Çiftçi,

İçişleri Bakanı Mustafa Çiftçi,İçişleri Bakanı Mustafa Çiftçi, APP plaka ve araç içi multimedya sistemlerine yönelik yeni açıklamalarda bulundu. TRT Haber’in programına katılan Çiftçi, bu kapsamda hedeflerinin ceza kesmek değil, vatandaşların can ve mal güvenliğini korumak olduğunu belirterek, Türkiye Şoförler ve Otomobilciler Federasyonu (TŞOF) tarafından basılan standart veya standart dışı plakaları kabul ettiklerini kaydetti. Çiftçi sürücülere TŞOF tarafından basılmayan yani herhangi bir güvenlik unsuru taşımayan mühürsüz “APP” plakaları vakit geçirmeden değiştirmeleri tavsiyesinde bulundu. Çiftçi, araçlardaki multimedya sistemlerine yönelik açıklamasında ise, “Bu da kafa karışıklığına sebebiyet veren konulardan birisi. Bununla ilgili kanun yönetmelikle bir düzenleme yapılacağını söylüyor. Burada da temel alınan, yani esas alınan husus şu: Görüntü sistemleri ile ilgili bir sürücünün görüş açısını etkilemeyecek. Bu ekran sistemleri, müzik sistemleri, ses ve görüntü sistemleri dediğimiz konu. İkincisi de sürücünün dikkatini dağıtmayacak. Bu ikisinin gerçekleşmesi gerekiyor. Tabii yönetmelikle düzenleneceği belirtilmiş kanunda. Şu anda yönetmelik çalışmalarımız devam ediyor. Nisan ayının sonuna kadar da yönetmeliği çıkaracağız, bu ekran […]

İçişleri Bakanı Mustafa Çiftçi’den APP plaka ve araç içi multimedya sistemlerine yönelik yeni açıklamalar geldi yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Why Developers Should Build Native AI Applications

The Web5/WebAI Model of Ascoos OS: A Self‑Sufficient, User‑First Approach to Artificial Intelligence on the Web

Introduction

Artificial Intelligence has become a core component of the modern web. However, the way it is integrated into most applications remains dependent on external services and remote systems, creating limitations in performance, privacy, cost, and independence.

Ascoos OS proposes a different philosophy: a web where AI is not a service located somewhere else, but a capability owned by the user. A web where applications do not rely on third parties to function, and where data never leaves the user’s environment. This is the Web5/WebAI model.

1. The Need for Native AI Applications

Traditional approaches to AI integration rely on external providers. While functional, these architectures have inherent limitations:

  • Data is transferred outside the user’s environment.
  • Performance depends on latency and connectivity.
  • Functionality is not available offline.
  • Costs increase as usage increases.
  • AI has no access to system‑level data and mechanisms.
  • The user lacks true ownership and self‑sufficiency.

In a world where privacy, autonomy, and independence are becoming essential values, this model is no longer adequate.

2. The Ascoos OS Approach: AI as Infrastructure

Ascoos OS integrates Artificial Intelligence directly into the core of the web kernel. It does not treat AI as an add‑on, but as a foundational component of the system’s architecture.

This enables:

  • Local AI execution without external services.
  • Full ownership and control of data by the user.
  • Complete offline functionality.
  • Direct AI access to DSL, macros, events, files, and system data.
  • Applications that operate with true self‑sufficiency.
  • The ability for AI to influence system flow in real time.

The result is a web that does not depend on third parties, but is built around the user.

3. Examples of Native AI in Ascoos OS

The following examples demonstrate how AI behaves when it is part of the kernel rather than an external service. Their value lies in the fact that they form unified, locally executed pipelines.

3.1 Neural Workflow Composer – Learning from the System and Executing Macros

$composer = new TNeuralNetworkHandler();
$composer->compile([
    ['input' => 3, 'output' => 4, 'activation' => 'relu'],
    ['input' => 4, 'output' => 1, 'activation' => 'sigmoid']
]);
$composer->fit($systemData, $actions, epochs: 1000, lr: 0.01);

$score = $composer->predictNetwork([$currentState])[0];

if ($score > 0.5) {
    $macroHandler = new TMacroHandler();
    $macroHandler->addMacro(fn() => print("Executing optimized macro"));
    $macroHandler->runNext();
}

AI operates as part of the system, learns from its data, and influences its behavior in real time.

See Full Article

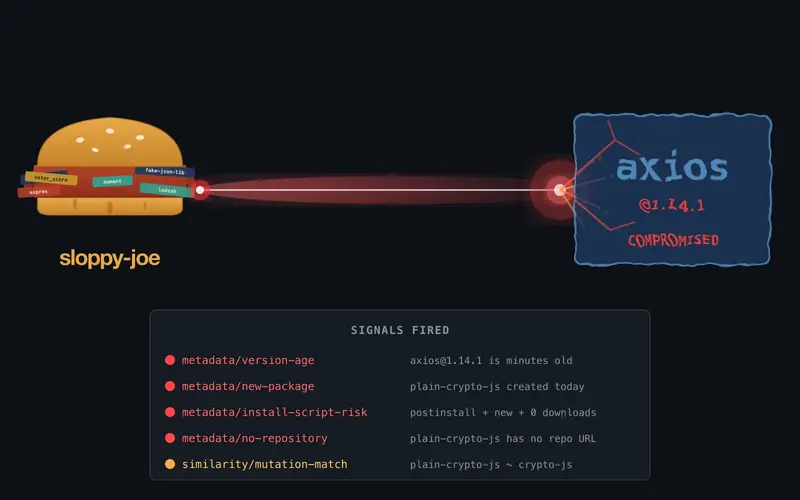
How a sandwich defeats North Korea’s hackers (and the US couldn’t for 70 years)


Two days ago, Google’s Mandiant team attributed the axios npm compromise to UNC1069 — a North Korean threat group previously linked to cryptocurrency theft and attacks on DeFi platforms. The malicious code shares significant overlap with WAVESHAPER, a C++ backdoor Mandiant attributed to the same group in February.

North Korea just weaponized the most popular HTTP client in JavaScript. 100 million weekly downloads. The payload: a cross-platform RAT that harvests credentials, SSH keys, and cloud tokens from every developer machine that runs npm install.

The United States has spent 70 years and trillions of dollars trying to contain North Korea. Nuclear negotiations, sanctions, carrier groups, diplomatic pressure, UN resolutions. None of it has stopped the DPRK from becoming one of the most effective cyber threats on the planet.

A sloppy joe sandwich stops them in 3 seconds.

What happened

On March 30, the attacker compromised the npm account of axios’s lead maintainer (jasonsaayman) using a stolen access token. They changed the account email to a Proton Mail address and published two malicious versions:

Both versions injected a new dependency: [email protected]. This package was never imported anywhere in the axios source. Its sole purpose was to run a postinstall hook that deployed platform-specific RATs:

  • macOS: Binary at /Library/Caches/com.apple.act.mond, executed via AppleScript
  • Windows: PowerShell RAT with Registry persistence and in-memory binary injection
  • Linux: Python RAT script via nohup

The dropper script deleted itself after execution to hide forensic evidence. The attacker staged plain-crypto-js 18 hours in advance, pre-built three platform payloads, and hit both release branches within 39 minutes. This was not amateur hour.

How sloppy-joe blocks every layer of this attack

sloppy-joe is an open-source supply chain security tool. It runs before npm install. It reads your package-lock.json and checks every dependency — direct and transitive — against multiple independent signals. No packages are downloaded. No code is executed.

Signal 1: Version age gate

ERROR axios [metadata/version-age]
      Version '1.14.1' of 'axios' was published 0 hours ago (minimum: 72 hours).
      New versions need time for the community and security scanners to review them.
 Fix: Wait until the version is at least 72 hours old, or pin to an older version.

The compromised versions were live for 2-3 hours before npm yanked them. A 72-hour gate means they never get installed. Period. This requires zero knowledge of the attack — it works purely on the principle that new versions should survive community review before hitting production.

This single check stops the attack.

But sloppy-joe doesn’t stop at one signal. With --deep transitive scanning, plain-crypto-js gets demolished by five independent checks:

Signal 2: New package detection

ERROR plain-crypto-js [metadata/new-package]
      'plain-crypto-js' was first published 0 days ago. New packages are higher
      risk — verify this is a legitimate, maintained project before depending on it.
 Fix: Verify 'plain-crypto-js' at its registry page and source repository.

plain-crypto-js was created the day before the attack. Brand new packages as transitive dependencies of 100M-download packages are inherently suspicious.

Signal 3: Install script risk amplifier

ERROR plain-crypto-js [metadata/install-script-risk]
      'plain-crypto-js' has install scripts AND was published 0 days ago and with
      0 downloads. Install scripts on new, low-download packages are the #1
      malware delivery vector.
 Fix: Do not install this package. Verify it is legitimate before proceeding.

Install scripts + new package + zero downloads. This is the exact fingerprint of a supply chain attack. sloppy-joe’s install script risk signal combines multiple weak signals into a high-confidence detection. Every real-world npm supply chain attack in the last 5 years has matched this pattern.

Signal 4: No source repository

WARNING plain-crypto-js [metadata/no-repository]
        'plain-crypto-js' has no source repository URL and is a new package
        (< 30 days old). Legitimate packages almost always link to their source code.
 Fix: Verify 'plain-crypto-js' at its registry page.

Legitimate packages link to their GitHub/GitLab repo. Malicious packages created as payload delivery vehicles don’t bother.

Signal 5: Name similarity

WARNING plain-crypto-js [similarity/mutation-match]
        'plain-crypto-js' is suspiciously similar to existing package 'crypto-js'
 Fix: Verify this is the package you intend to use.

plain-crypto-js is a clear attempt to look like crypto-js — a real, popular cryptography package with hundreds of millions of downloads. sloppy-joe’s mutation generators catch this.

Five signals. One sandwich. Zero dollars.

Here’s what’s remarkable: none of these detections require threat intelligence feeds, malware signature databases, or AI-powered behavioral analysis. They’re all variations of the same primitive: cross-reference what the code claims to use against what actually exists on the registry.

  • Is the version too new? Flag it.
  • Is the transitive dep brand new? Flag it.
  • Does a brand new package have install scripts? Block it.
  • Does it have no source repository? Flag it.
  • Does the name look like a popular package? Flag it.

Each signal alone is informational. All five firing together on the same package is a certainty.

The cost of this defense

# Add to any CI pipeline
npx sloppy-joe check

That’s it. One line. Runs in 5-15 seconds. No account needed. No API key. No subscription. Open source, MIT licensed.

The DPRK’s UNC1069 spent 18 hours staging payloads, pre-building RATs for three platforms, and compromising a maintainer account. sloppy-joe catches it in the time it takes to read a package-lock.json.

What sloppy-joe can’t catch

Honesty matters: sloppy-joe would not have detected the credential theft itself. The attacker hijacked the real maintainer’s account — the npm _npmUser field still shows jasonsaayman. There’s no publisher change to detect. npm’s provenance attestation (OIDC-based publishing via GitHub Actions) is the real defense against token theft — the malicious versions were published manually, bypassing axios’s CI pipeline.

sloppy-joe catches the payload, not the compromise. But the payload is what hurts you.

Get started

# Install
cargo install sloppy-joe

# Run
sloppy-joe check

# In CI (GitHub Actions)
- uses: brennhill/sloppy-joe-action@v1

GitHub logo

brennhill
/
sloppy-joe

Shields against supply-chain, slopsquatting, and typosquatting attacks from dependencies and code.

sloppy-joe

Catch hallucinated, typosquatted, and non-canonical dependencies
before they reach production.

cargo install sloppy-joe

The LiteLLM supply chain attack (March 2026) compromised a package with 97M monthly downloads. Attackers stole publishing credentials, pushed malicious versions that harvested SSH keys, cloud credentials, and K8s secrets. sloppy-joe’s default 72-hour version age gate would have blocked both poisoned versions — they were discovered within hours, well before the gate would have opened. If you run sloppy-joe check in CI, this attack fails. Full analysis

AI code generators hallucinate package names ~20% of the time. Attackers register those names and wait. sloppy-joe catches them in CI before npm install or pip install runs.

How to Use

# Install (single static binary, no runtime dependencies)
cargo install sloppy-joe
# Or download an auditable binary archive from GitHub Releases
# https://github.com/brennhill/sloppy-joe/releases

# Check current project — auto-detects ecosystem from manifest files
sloppy-joe check

# Check a

…

sloppy-joe is an open-source supply chain security tool that catches hallucinated, typosquatted, and compromised dependencies before they reach production. It runs before your package manager, requires no code execution, and blocks attacks like axios, LiteLLM, event-stream, and ua-parser-js.

AI Transcription Fails When It Matters Most – Here’s Why

AI speech-to-text tools like OpenAI Whisper, Otter.ai, and Google Speech-to-Text are genuinely impressive – in the right conditions. Claim a clean recording, one speaker, no background noise, and these models can hit word error rates below 5%. That is near-human accuracy.

The problem is that most professionally relevant audio is nothing like that. Focus groups, field interviews, remote meetings, and real-world recordings are noisy, overlapping, and acoustically messy. In these conditions, AI transcription does not gradually degrade – it collapses. And it does so in ways that are both predictable and poorly communicated by vendors.
Here are the four core failure modes that practitioners encounter most often, and why they happen.

1. Background Noise Destroys Accuracy Fast

Modern ASR models process audio as mel-spectrograms – visual representations of sound frequencies over time. They learn to associate these patterns with words during training. The fundamental issue: training data is overwhelmingly clean, studio-quality audio. Real-world noise introduces spectral patterns the model has never learned to separate from speech.
The result is a steep accuracy cliff tied to Signal-to-Noise Ratio (SNR). At 20 dB SNR – a reasonably quiet office – most leading models still perform well. Drop to 10 dB (an open-plan office with HVAC) and accuracy falls to 75–88%. In a busy café at 5 dB SNR, you are looking at 50–70% accuracy on a good day.

⚠ Hallucination risk: Below a certain SNR threshold, transformer-based models do not produce [inaudible] markers – they generate plausible-looking but entirely fabricated text. Whisper is specifically documented to hallucinate repetitive phrases or unrelated sentences when processing low-SNR segments. A transcript that looks complete may contain invented content.
Common culprits in professional recordings include HVAC systems, room echo (hard surfaces reflect and smear the speech signal), Bluetooth audio compression, and VoIP codec artifacts from tools like Zoom or Teams – especially under network congestion.

2. Overlapping Speech Breaks Speaker Attribution Entirely

Focus groups are the stress test that exposes every weakness in an AI transcription pipeline simultaneously. When participants talk over each other – which happens constantly in group discussion – the diarization system (the component responsible for ‘who said what’) faces an impossible task.
Speaker diarization works by embedding short audio segments into a vector space and clustering them by speaker identity. This works tolerably for two people taking clear turns. It fails badly when:
• Three or more speakers are present
• Participants interrupt or respond simultaneously
• Speakers vary significantly in volume or distance from the microphone
• Background noise distorts the speaker embeddings

During overlap, the model typically picks the loudest speaker and treats the others as noise. Quieter or more distant participants – often including introverted group members whose contributions may be analytically important – are systematically underrepresented or lost entirely.
📊 Data point: Published research on the DIHARD diarization benchmarks shows Diarization Error Rate (DER) climbing from under 5% in clean two-speaker audio to 20–40%+ in multi-speaker spontaneous conversation with background noise. In qualitative research contexts, that means you often cannot reliably determine who said what – even if the words themselves were transcribed correctly.

3. Accents and Spontaneous Speech Expose Training Data Bias

Every ASR model’s performance ceiling is set by its training data distribution. For English-language models, that distribution skews heavily toward American English, prepared speech, and studio recording conditions. The practical consequences are well-documented:
• Non-native English speakers see WER increases of 30–80% relative to native speakers, depending on accent strength
• Regional and minority language varieties (AAE, Scottish English, Irish English) show consistent performance gaps across all major commercial systems
• For Dutch-language transcription – including Flemish dialects and Belgian Dutch with French code-switching – most models are trained on Standaardnederlands and perform significantly worse on regional speech

Spontaneous conversational speech adds another layer of difficulty: filled pauses, false starts, reduced phonetic forms (‘gonna’, ‘kinda’), and emotional prosody are systematically underrepresented in training corpora. These are not edge cases – they are the normal texture of natural human conversation.

4. Post-Correction Is More Expensive Than It Looks

A common response to AI transcription errors is ‘just have someone fix it afterwards.’ This underestimates the cognitive cost of error correction. Fixing a transcript requires the reviewer to simultaneously monitor the audio, read the incorrect text, identify discrepancies, and retype corrections. Research in cognitive ergonomics suggests that correcting a 15% WER transcript takes roughly 60–70% as long as transcribing from scratch.
For use cases where accuracy genuinely matters – qualitative research data, legal or compliance documentation, HR investigations, medical records – the efficiency case for AI-only transcription weakens considerably once post-correction time is included.

The Practical Takeaway
AI transcription is fast and cost-effective for clean, single-speaker recordings in standard conditions. It is the wrong tool – or at minimum, an insufficient tool without substantial human review – for:
• Focus groups and multi-speaker discussions
• Field recordings or interviews in non-controlled environments
• Participants with strong accents or non-standard speech patterns
• Any recording made over VoIP or with consumer-grade equipment
• Documents where attribution, precision, or legal weight matters

For these scenarios, human-led or hybrid transcription workflows remain the reliable standard. Specialist services like Outspoken.be are specifically built for the difficult cases – focus groups, noisy field interviews, dialect-heavy recordings, and multi-speaker meetings – where AI output alone consistently falls short. The acoustic physics of real-world audio have not changed; what matters is choosing a workflow that accounts for them.

This article is a condensed version of a longer technical deep-dive covering WER measurement, diarization architectures, SNR physics, and codec artifacts. The full version is available at outspoken.be.

I open-sourced alternative to ReplyGuy — AI replies on Reddit, Twitter/X & HN for $50/month

I built MentionMaster as a paid SaaS, ran it for a year,
and today I’m open-sourcing the full backend.

Here’s what it does, how it works, and how to run 600 AI-powered mentions/month for ~$50.

🎬 Demo

The Problem

If you’re a founder or indie hacker, you know this loop:

  1. Someone on Reddit asks “what tool helps with X?” — your product is the perfect answer
  2. You never see it
  3. A competitor replies, gets the customer

Manual monitoring doesn’t scale. Paid tools like ReplyGuy charge $49–$299/month.
So I built my own and now I’m giving it away.

What It Does

MentionMaster monitors Reddit, Twitter/X, Hacker News, YouTube, and TikTok for
posts matching your product keywords. When it finds a relevant post, it:

  1. Scores it for relevance (saves OpenAI API costs — no point replying to irrelevant posts)
  2. Generates a context-aware reply using GPT-4o-mini
  3. Queues it for your review
  4. Publishes on approval, with auto-translation if your product targets non-English markets

Tech Stack

Layer Tech
API FastAPI
Background jobs Celery + Redis
Database Firebase Firestore
Auth Firebase Admin SDK
AI OpenAI GPT-4o-mini
Reddit PRAW
Twitter/X Selenium scraper
Payments LemonSqueezy
Observability Prometheus + Grafana + OpenTelemetry
Deploy Docker Compose

Architecture

FastAPI (REST API)
    │
    ├── Redis (Celery broker)
    │       │
    │       └── Celery Workers
    │               ├── Scrape Reddit every 12h
    │               ├── Scrape Twitter/X every 12h
    │               ├── Scrape HN, YouTube, TikTok
    │               └── Approve queued posts every 2h
    │
    └── Firebase Firestore (users, projects, posts)

The Interesting Parts

Relevance scoring before AI generation

Before calling OpenAI, every scraped post goes through a relevance check:

def is_post_suitable_for_help(text, product_description):
    prompt = (
        f"Given: '{text}', can our product '{product_description}' "
        f"solve this problem? Return only True or False."
    )
    result = client.chat.completions.create(
        model='gpt-4o-mini',
        messages=[{"role": "user", "content": prompt}]
    )
    return result.choices[0].message.content.strip() == "True"

This cuts OpenAI costs by ~60% — you only generate full replies for posts
where your product is actually relevant.

Scheduled scraping with Celery + APScheduler

# Runs every 12 hours in production
scheduler.add_job(create_scrape_reddit_task, CronTrigger(hour='*/12'))
scheduler.add_job(create_scrape_twitter_task, CronTrigger(hour='*/12'))

# Promotes unpublished → approved every 2 hours
scheduler.add_job(create_move_posts_to_approved, CronTrigger(hour='*/2'))

Multi-language support

If your product targets non-English markets, replies are auto-translated
before publishing:

if product_language != 'en':
    ai_response = GoogleTranslator(
        source='auto', 
        target=product_language
    ).translate(ai_response)

💰 How to Run 600 Mentions/Month for $50

If you want to scale beyond one account, here’s the setup I used:

Tools needed:

  • Dolphin{anty} antidetect browser — $10/mo for 20 profiles
  • Proxy per profile — ~$2/mo each

The math:

20 profiles × 5 social networks × 30 posts/month = 600 mentions/month
Total cost: $10 (Dolphin) + $40 (20 proxies) = $50/month
Cost per mention: ~$0.08

Each profile posts every 4 hours automatically — frequent enough to
cover conversations, slow enough to look natural.

Compare: ReplyGuy charges $49–$299/month for similar volume.

Getting Started

git clone https://github.com/youlast/mentionmaster_backend.git
cd mentionmaster_backend
cp .env.example .env   # fill in your keys
docker compose up --build

You’ll need:

  • OpenAI API key
  • Firebase project (Firestore + Auth)
  • Reddit app credentials (free at reddit.com/prefs/apps)

Full setup guide in the README.

Links

If you found this useful, a ⭐ on GitHub goes a long way.
And if you have questions about the architecture or scraping approach — drop them below!

Your AI Agent Spent $500 Overnight and Nobody Noticed

Agent Mesh Dashboard

Friday 5 PM. You deploy a research agent that processes customer tickets. It calls GPT-4 for each one. Expected load: 200 tickets a day, about $8 in API costs.

Friday 11 PM. A bug in ticket deduplication. The agent reprocesses the same tickets in a loop. Each iteration makes 4 LLM calls at $0.03 each. The loop runs 50 times per hour.

Saturday 3 AM. The agent has made 12,000 LLM calls. Cost so far: $360. Nobody is watching.

Monday 9 AM. OpenAI billing alert fires at the $500 threshold you set months ago. Total damage: $487. No logs showing which agent caused it, which task triggered the loop, or when it started.

This is not hypothetical. Every team running AI agents in production has a version of this story.

Why Standard Monitoring Doesn’t Help

OpenAI gives you total organization spend. Not per-agent. Not per-task. Not in real time.

If you have 5 agents calling GPT-4, and one goes haywire, your OpenAI dashboard shows a line going up. Which agent? You don’t know. Which task caused the spike? You don’t know. When did it start? You can guess from the slope of the graph.

Cloud monitoring (Datadog, Grafana) tracks CPU and memory. It doesn’t know about LLM tokens. You could instrument it yourself – custom metrics, Prometheus counters, StatsD gauges – but now you’re building a cost monitoring system instead of building your product.

Billing alerts are too late and too coarse. A $500 alert tells you the money is already gone. A per-API-key alert doesn’t map to individual agents.

What you actually need:

  • Cost per agent, in real time
  • Cost per task (not just per agent)
  • Budget limits that actually stop the agent
  • Alerts before the damage is done

Tracking Cost Through the Agent Heartbeat

AXME agents send heartbeats every 30 seconds – standard health reporting. The insight is that cost is just another metric in that heartbeat.

from axme import AxmeClient, AxmeClientConfig

client = AxmeClient(AxmeClientConfig(api_key=os.environ["AXME_API_KEY"]))

def call_llm(prompt: str) -> str:
    response = openai.chat.completions.create(
        model="gpt-4",
        messages=[{"role": "user", "content": prompt}],
    )

    # Calculate cost from token usage
    tokens_in = response.usage.prompt_tokens
    tokens_out = response.usage.completion_tokens
    cost_usd = (tokens_in * 0.03 + tokens_out * 0.06) / 1000

    # Report cost alongside the regular heartbeat
    client.mesh.report_metric(
        agent="agent://myorg/production/research-agent",
        intent_id=current_intent_id,
        cost_usd=cost_usd,
        metadata={"model": "gpt-4", "tokens_in": tokens_in, "tokens_out": tokens_out},
    )

    return response.choices[0].message.content

Two lines of actual logic: calculate the cost, report it. The gateway accumulates it per agent, per intent, per time window. No Prometheus setup. No custom Datadog metrics. No StatsD.

Budget Limits That Actually Stop Agents

Reporting cost is useful. Enforcing limits is essential.

client.mesh.set_cost_policy(
    agent="agent://myorg/production/research-agent",
    rules=[
        {
            "period": "day",
            "limit_usd": 50.00,
            "action": "pause",
            "notify": ["[email protected]"],
        },
        {
            "period": "intent",
            "limit_usd": 5.00,
            "action": "alert",
            "notify": ["[email protected]"],
        },
    ],
)

Three actions: alert sends a notification and the agent continues. pause stops delivering new intents to the agent. kill terminates active intents immediately.

The gateway checks policies on every heartbeat. When the research agent hits $50 for the day, it pauses. Not after $500. Not after the invoice. At $50, in real time.

The per-intent limit catches the more subtle problem. If a single customer ticket costs $5 in LLM calls, something is wrong with that ticket or with how the agent is processing it. Alert before it becomes a pattern.

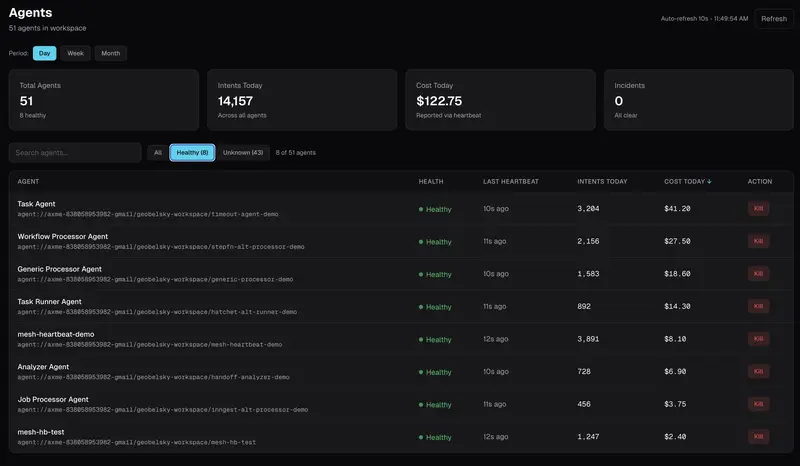
What the Dashboard Shows

The AXME mesh dashboard shows cost alongside agent status:

Agent Mesh Dashboard

Drill into any agent and you see cost per intent, per model, per hour. Agents that hit their daily limit are paused automatically. No surprises.

Cost policies are managed visually alongside agent health:

Policies

Multi-Model Visibility

Most agents don’t use just one model. They use GPT-4 for complex reasoning, GPT-4o for routine tasks, GPT-4o-mini for classification. Each has different pricing. Each needs separate tracking.

MODEL_COSTS = {
    "gpt-4":       {"input": 0.03,  "output": 0.06},
    "gpt-4o":      {"input": 0.005, "output": 0.015},
    "gpt-4o-mini": {"input": 0.00015, "output": 0.0006},
}

def call_llm(model: str, prompt: str) -> str:
    response = openai.chat.completions.create(
        model=model,
        messages=[{"role": "user", "content": prompt}],
    )
    rates = MODEL_COSTS[model]
    cost = (
        response.usage.prompt_tokens * rates["input"]
        + response.usage.completion_tokens * rates["output"]
    ) / 1000

    client.mesh.report_metric(
        cost_usd=cost,
        intent_id=current_intent_id,
        metadata={"model": model},
    )
    return response.choices[0].message.content

The dashboard breaks it down:

research-agent cost breakdown (today):
  gpt-4:          $9.20  (73.8%)
  gpt-4o:         $2.85  (22.8%)
  gpt-4o-mini:    $0.42  (3.4%)

Now you can ask the right question: can we move some of those GPT-4 calls to GPT-4o-mini and cut costs by 60%?

The Alternative

Without this, you build it yourself:

  1. Instrument every LLM call with token counting
  2. Send custom metrics to Prometheus/Datadog/CloudWatch
  3. Build dashboards per agent (Grafana? Retool? Custom?)
  4. Write alerting rules with the right thresholds
  5. Build the “pause agent” mechanism yourself
  6. Map OpenAI costs to individual agents in your billing system
  7. Maintain all of this as models and pricing change

That is a real project. Weeks of work. And it is not your product.

Or: report cost_usd in the heartbeat your agent already sends. Set a policy. Done.

Try It

Working example with cost reporting, budget limits, and multi-model tracking:

github.com/AxmeAI/ai-agent-cost-monitoring

Built with AXME – agent coordination with durable lifecycle and cost controls. Alpha – feedback welcome.

From 10x Developer to 10x Multiplier: Surviving the Lead/Principal Glow-Up 🚀

🎬 The Identity Crisis

You got promoted to Principal Engineer. Congratulations! 🎉

It’s been 3 months. You’ve attended 47 meetings. You’ve written 3 Architecture Decision Records that nobody read. You haven’t committed code in 2 weeks and you feel profoundly useless.

A junior engineer asks you for help with a Terraform module. You pair with them for 2 hours, fix the issue in 10 minutes, and spend 110 minutes explaining WHY the fix works, what patterns to use, and how to avoid the problem in the future.

You think: “I could have fixed that in 10 minutes myself.”

But here’s the thing — that junior engineer will never make that mistake again. And they’ll teach the next person. And the next. Your 2-hour investment just saved the team 200 hours over the next year.

Welcome to being a multiplier. It feels weird. It’s supposed to.

🧠 The Mindset Shift: Senior → Principal

This is the hardest part. Nobody prepares you for it.

                Senior Engineer              Principal Engineer
                ═══════════════              ═══════════════════
Question:       "What's the best            "What's the right
                 solution?"                  solution for the ORG?"

Impact:         What YOU build              What OTHERS build
                                             because of your guidance

Code:           Write a lot                 Write strategically
                                             (prototypes, critical fixes)

Scope:          Your team's project         Multiple teams,
                                             department, company

Time horizon:   This sprint, quarter        This year, next year

Meetings:       "Ugh, another one"          "This IS the work"

Success:        "I shipped it!"             "The team shipped it,
                                             and they didn't need me"

The Hardest Truth

Your value is no longer measured by the code you write.

It’s measured by:

  • Decisions you make that save the org months of wasted effort
  • Engineers you mentor who grow into the next generation of leaders
  • Technical debt you prevent before it’s created
  • Systems you design that scale without constant firefighting
  • Alignment you create between engineering and business goals

If that makes you uncomfortable, you’re in the right place. Let’s work through it.

📊 How to Spend Your Time (The Reality Check)

If you're writing code 60%+ of your time, you're doing
a senior engineer's job with a principal title.

Healthy time allocation for a Principal:

  30% │████████████████████│ Architecture & Strategy
      │                    │ ADRs, tech strategy, research,
      │                    │ roadmapping, system design
      │                    │
  25% │█████████████████│   Collaboration & Influence
      │                 │   Design reviews, cross-team
      │                 │   alignment, stakeholder mgmt
      │                 │
  20% │█████████████│       Mentoring & Teaching
      │             │       1:1s, pair programming,
      │             │       tech talks, documentation
      │             │
  15% │██████████│          Hands-On Technical Work
      │          │          Prototypes, POCs, critical
      │          │          fixes, proof of concepts
      │          │
  10% │██████│              Learning & Community
      │      │              Industry trends, conferences,
      │      │              writing (like this blog!)

Warning Signs You’re Not Operating at Principal Level

🚩 You're the only person who can deploy to production
🚩 You fix bugs instead of teaching others to fix them
🚩 You don't have time for strategy because you're always coding
🚩 Other teams don't know who you are
🚩 You can't explain what you did last quarter without listing PRs
🚩 You haven't written a document that influenced a decision
🚩 Nobody has mentioned learning something from you recently

📝 Architecture Decision Records: Your Decision Paper Trail

ADRs are how Principal engineers make their impact visible and lasting. When you make a technical decision that affects the organization, write it down.

Why ADRs Matter

Without ADRs:
  2026: "Let's use Kafka for event streaming!" (decision made in meeting)
  2027: Half the team left. New engineers join.
  2027: "Why are we using Kafka? Can we switch to Azure Event Hubs?"
  2027: 3 months debating the same decision again
  2027: "Wait, we tried that before and it didn't work because..."
  2027: Nobody remembers why

With ADRs:
  2026: ADR-042: Event Streaming Platform Selection
  2027: New engineer asks "Why Kafka?"
  2027: Reads ADR-042 in 5 minutes
  2027: "Oh, we evaluated Event Hubs but it didn't support
         schema registry at the time. That's changed now.
         Maybe we should revisit." (Productive conversation!)

ADR Template That Actually Gets Used

# ADR-042: Event Streaming Platform Selection

## Status: Accepted (2026-01-15)

## Context
We need an event streaming platform for our microservices
architecture. Currently, services communicate via synchronous
HTTP calls, causing cascading failures and tight coupling.

## Decision Drivers
- Team has 2 engineers with Kafka experience
- Must support schema evolution (backward compatible)
- Need at least 100K events/second throughput
- Budget: $2,000/month maximum

## Options Considered

| Criteria       | Kafka (Confluent) | Azure Event Hubs | Azure Service Bus |
|----------------|-------------------|-------------------|-------------------|
| Throughput     | ★★★★★            | ★★★★             | ★★★              |
| Schema support | ★★★★★ (Registry) | ★★★ (basic)      | ★★               |
| Team expertise | ★★★★             | ★★               | ★★★              |
| Cost           | ~$1,800/mo        | ~$1,200/mo       | ~$800/mo          |
| Ops overhead   | ★★ (self-managed) | ★★★★ (managed)   | ★★★★★ (managed)  |

## Decision
Use Azure Event Hubs with Schema Registry.

## Rationale
- Kafka expertise exists but managing Kafka clusters is expensive
  in engineer time (estimated 20% of one engineer)
- Event Hubs is Kafka-compatible (apps use Kafka client libraries)
- Schema Registry is now available in Event Hubs
- Managed service reduces operational burden
- Fits within budget

## Consequences
- Teams must use Kafka client libraries (not Event Hubs SDK)
  to maintain portability
- Schema Registry enforces backward compatibility
- We accept Event Hubs' partition limit (100 vs Kafka unlimited)

## Review Date: 2026-07-15 (6 months)

Decision Types: Know Which Ones Need ADRs

Type 1: One-Way Door (Irreversible)
  "Which cloud provider?"
  "What's our platform technology?"
  → Broad consensus required. ADR mandatory. Exec approval.
  → Take your time. Get it right.

Type 2: Two-Way Door (Reversible)
  "Which monitoring tool?"
  "Terraform vs Pulumi?"
  → Principal decides with team input. ADR recommended.
  → Don't over-deliberate. You can change it later.

Type 3: Team-Level (Delegate)
  "Which testing framework?"
  "How to structure this service internally?"
  → Team decides. Principal advises only if asked.
  → Don't micromanage. Trust your people.

The Principal skill: knowing which type each decision is.
Common mistake: Treating Type 2 as Type 1 (over-thinking)
                or Type 1 as Type 2 (under-thinking)

👥 Mentoring: The Highest Leverage Activity

The Mentoring Spectrum

Teaching              Mentoring             Sponsoring
═════════             ═════════             ══════════
"Here's how to do X"  "What do you think    "I recommend Alex
                       about X?"             for this project"

One-time knowledge     Ongoing relationship  Using YOUR influence
transfer               Growth over months    to advance THEIR career

Low leverage           Medium leverage       Highest leverage
(helps one person)     (grows an engineer)   (creates new leaders)

How to Mentor Effectively (Without Being a Bottleneck)

❌ Bad mentoring:
  Junior: "How should I implement this?"
  You: "Use pattern X with library Y. Here's the code."
  Result: Junior learns nothing, keeps asking you.

✅ Good mentoring:
  Junior: "How should I implement this?"
  You: "What options have you considered?"
  Junior: "I was thinking about pattern X or pattern Z."
  You: "What are the tradeoffs between them?"
  Junior: "X is simpler but Z scales better..."
  You: "And which matters more for this use case?"
  Junior: "...simpler, because we only have 100 users."
  You: "Great thinking. Go with X. If we scale beyond 10K
        users, we can revisit. Write it up in a mini-ADR
        so the team knows why."
  Result: Junior learned to think. Won't need to ask next time.

The 30-Minute 1:1 Template

First 10 minutes: THEIR agenda
  → "What's on your mind?"
  → "What's blocking you?"
  → "What are you struggling with?"

Next 10 minutes: Growth
  → "What did you learn this week?"
  → "What would you like to get better at?"
  → "Here's a stretch opportunity I think you'd be great for..."

Last 10 minutes: Feedback (both directions!)
  → "Here's something you did really well..."
  → "Here's something to think about..."
  → "Is there anything I could do differently to help you?"

🤝 Stakeholder Management: Speaking Business

The Communication Translation Table

To Engineers:
  "We need to migrate from VMs to Kubernetes for better
   resource utilization, automated scaling, and to enable
   GitOps-based deployment workflows."

To Engineering Manager:
  "Migrating to Kubernetes will reduce our deployment time
   from 2 hours to 15 minutes, and reduce infrastructure
   costs by 30% while improving reliability."

To VP of Engineering:
  "The platform migration will reduce time-to-market for
   new features by 40% and save $180K annually on
   infrastructure, with a 3-month break-even point."

To CTO:
  "This enables us to ship features 3x faster than
   competitors while reducing operational risk."

Same project. Different audiences. Different language.

🚨 Real-World Disaster: The RFC Nobody Read

What Happened: A Principal Engineer wrote a 42-page RFC (Request for Comments) for a major platform migration. It was technically brilliant. It covered every edge case, every migration step, every rollback plan.

Nobody read it. Not the VP. Not the other teams. Not even the author’s own team (they skimmed the intro).

Result: The migration was approved based on a 5-minute conversation in a meeting, without the nuance of the RFC. Key assumptions were missed. Migration hit problems that were addressed in section 7.3 of the RFC that nobody read.

The Fix: TL;DR First, Detail Below

# RFC: Platform Migration to Kubernetes

## TL;DR (Read this. It's 30 seconds.)
We're moving from VMs to AKS. It saves $180K/year, cuts deploy
time by 85%, and takes 3 months. Risk is medium — mitigated by
a parallel-run strategy. I need approval by March 15.

## One-Page Summary (Read this if you're a decision-maker)
[1-page executive summary with key points and ask]

## Detailed Proposal (Read this if you're implementing)
[The full 42 pages for people who need the detail]

🛣️ Building a Technical Roadmap

The Vision Statement

Every roadmap starts with where you’re going:

Vision: "Enable any team to deploy a production-ready service
         in under 1 hour with enterprise-grade reliability."

That's the North Star. Every quarter maps toward it:

Q1: Foundation
  ├── AKS cluster standardization (2 clusters → 1 standard)
  ├── Pipeline template library v1 (golden paths)
  └── SLO framework for tier-1 services

Q2: Developer Experience
  ├── Self-service namespace creation (< 5 min)
  ├── Standardized observability stack (auto-instrumented)
  └── Cost dashboard per team

Q3: Maturity
  ├── Canary deployments by default
  ├── Chaos engineering program (game days)
  └── Internal Developer Platform v1

Q4: Excellence
  ├── Multi-region capability  
  ├── Platform API for self-service
  └── DORA metrics: Elite level

How to Get Buy-In for Your Roadmap

Step 1: Start with PAIN, not technology
  ❌ "We should adopt Kubernetes because it's industry standard"
  ✅ "Teams wait 3 days for infrastructure. Let's fix that."

Step 2: Quantify the business impact
  ❌ "This will improve our architecture"
  ✅ "This will save $180K/year and cut delivery time by 40%"

Step 3: Show quick wins AND long-term vision
  ❌ "In 18 months, we'll have an amazing platform"
  ✅ "In 2 weeks, we'll have templated pipelines. In 3 months,
     self-service deployments. In 12 months, the full platform."

Step 4: Address risks honestly
  ❌ "There's no risk"  (nobody believes this)
  ✅ "Risk: team needs 4 weeks of K8s training.
     Mitigation: phased rollout, starting with non-critical services."

⚖️ Navigating Technical Debt

The Technical Debt Quadrant

                              Deliberate
                    ┌───────────────────────────┐
                    │                           │
                    │  "We'll ship now and       │
         Prudent ──▶│   refactor later"         │◀── This is OK
                    │  (Known risk, tracked)    │    (if you actually do it)
                    │                           │
                    ├───────────────────────────┤
                    │                           │
     Reckless ────▶ │  "We don't have time      │◀── This is dangerous
                    │   for design"             │
                    │  (Shortcuts, no plan)     │
                    │                           │
                    └───────────────────────────┘

                             Inadvertent
                    ┌───────────────────────────┐
                    │                           │
         Prudent ──▶│  "Now we know how we      │◀── This is learning
                    │   should have done it"    │    (natural, improve it)
                    │                           │
                    ├───────────────────────────┤
                    │                           │
     Reckless ────▶ │  "What's layered          │◀── This is a skills gap
                    │   architecture?"          │    (training needed)
                    │                           │
                    └───────────────────────────┘

How to Sell Technical Debt Reduction

Never say: “We need to refactor the codebase.”
(Leadership hears: “Engineers want to play with code instead of building features.”)

Instead, say: “Our deployment failure rate is 30% because of the legacy pipeline. Investing 2 sprints to modernize it will drop failures to 5% and save 4 engineer-hours per week in debugging.”

The formula that works:

"[Business metric] is impacted because of [technical debt].
 Investing [effort] will improve [metric] by [amount],
 resulting in [business outcome]."

🎯 Key Takeaways

  1. Your impact is measured by what others accomplish because of your work
  2. ADRs are your legacy — they outlast code and save the org from repeating debates
  3. Mentor by asking questions, not giving answers
  4. Translate tech to business language — same project, different story for each audience
  5. TL;DR everything — if it’s longer than 1 page, add a summary at the top
  6. Sell debt reduction with metrics, not technical arguments
  7. The best code you write is the code that enables 10 others to write better code

🔥 Homework

  1. Write one ADR for a decision you made recently. Share it with your team.
  2. In your next 1:1 with a junior, ask 5 questions before giving a single answer.
  3. Identify one technical debt item. Write a 3-sentence business case for fixing it.

Next up in the series: **Distributed Systems: Where Physics, Murphy’s Law, and Your Career Collide* — where we decode CAP theorem, resilience patterns, and the system design thinking that separates staff engineers from everyone else.*

💬 What was the hardest part of transitioning from IC to lead/principal? Was it letting go of the keyboard? The meetings? The imposter syndrome? Share below — we’ve all been there. 🫂

10 Must-Have Features of an Azure DevOps (ADO) Migration Tool

Microsoft Azure DevOps has become synonymous with modern SDLC management and agile product delivery. Leading organizations across the globe use the platform to build and deliver products at a faster pace and foster collaboration.

However, teams may find themselves compelled to move within the Azure DevOps landscape. Often for reasons like cloud adoption (TFS-VSTS migration), consolidating multiple instances, or re-organizing project hierarchies.

No matter the business use case, the success of your Azure DevOps re-organization or migration largely depends on the migration tool you partner with.

This article dissects the critical factors that underpin the selection of a migration tool capable of delivering a non-disruptive, high data-fidelity transition. Read ahead to learn more.

Factors Affecting the Choice of an Azure DevOps Migration Tool

It’s critical to be sure of these core aspects in order to get clarity on the choice of migration tool for your business:

Technical Aspects

  • Is the target Azure DevOps org empty?

  • What all needs to be migrated? – History, test results, inline content, work item and user mention.

  • Does source and target ADO have the same template? If templates are different then migration tool should have a way to map fields and transform data.

Team Size and Structure

The number of teams involved in the migration (teams using the systems and dependent on the data + teams leading the migration) and their technical expertise will impact the tool’s complexity and user-friendliness requirements.

Downtime Tolerance

Evaluate the acceptable level of downtime during the migration process. Some tools offer features like staged migration or zero-downtime options. Also, look for tools which offer reverse-sync capabilities, ensuring you have access to data in both systems till the migration is complete.

Data Volume and Complexity

The size and structure of your data will determine the tool’s processing capabilities and performance. Opt for an enterprise-grade migration tool to ensure a scalable transition for your teams.

Common Use Cases for Azure DevOps Migration

Azure DevOps Server (TFS) to Azure DevOps Services

This is a classic migration scenario where organizations move from an on-premises Team Foundation Server environment to the cloud-based Azure DevOps Services for better scalability and integration options.

Consolidation of Multiple Instances

Many organizations have multiple Azure DevOps instances due to acquisitions, mergers, or decentralized development teams. Merging these instances improves management and cost efficiency.

Reorganization of Project Hierarchy

Over time, project structures can become complex and inefficient. Reorganizing the project hierarchy is done to re-align with business units, teams, or product lines.

Selective Project Migration

Organizations might need to move specific projects or teams from one Azure DevOps organization to another without disrupting ongoing work. This could be due to restructuring, team reorganization, or compliance reasons.

Upgrade to Latest Azure DevOps Server (TFS) Version

Keeping Azure DevOps Server (TFS) up to date is essential for accessing new features and security patches. Upgrading to the latest version might involve data migration and configuration changes.

Key Features of an Azure DevOps Migration Tool

To successfully migrate large-scale enterprise environments with numerous teams and complex projects, an enterprise-grade migration tool is indispensable.

It should offer the following essential features:

Non-Disruptive Migration

  1. Agile Migration: The ability to migrate data in batches or phases minimizes disruptions to ongoing business processes.

  2. Zero Downtime: Ideal for mission-critical systems, this feature ensures uninterrupted operations during the migration.

  3. Minimal Impact on Productivity: The tool should be designed to avoid hindering team productivity throughout the migration process.

Compliance and Data Integrity

  1. Reverse Synchronization: The capacity to synchronize data between the source and target systems ensures data consistency and enables access to information from both environments until the migration is complete.

  2. Audit Trail: A comprehensive record of data changes and migration activities is crucial for compliance and troubleshooting purposes.

User-Friendliness

  1. Centralized Interface: A unified platform for monitoring migration progress, managing configurations, and resolving issues streamlines the process.

  2. Error Reporting and Retrying: The tool should consolidate all errors at a single place with an easy-to-grasp layout, and enable users to retry the migration with ease.

Comprehensive Data Migration

  1. Full Data Capture: The tool must migrate all relevant data, including work items, code, builds, releases, attachments, and comments.

  2. Historical Data Preservation: Maintaining complete data history is essential for analysis, auditing, and troubleshooting.

  3. Data Transformation: The ability to transform data during migration is crucial for addressing inconsistencies or schema differences between source and target systems.

Common Migration Tools and Techniques

Azure DevOps Data Migration Tool

Microsoft’s Azure DevOps Data Migration tool provides a baseline for migrating data from Azure DevOps Server to Azure DevOps Services.

While it offers a streamlined approach for transferring core artifacts like work items, source code, and test cases, it can only “lift and shift” one Azure DevOps Server collection to one new Azure DevOps Services organization, with no modifications.

Best Practices: To maximize the effectiveness of this tool, thorough planning, data preparation, and testing are essential. Consider using it when moving from TFS (latest version) to ADO services. ADO Org needs to be empty and whole migration needs to be completed in one-go, ideally over a weekend.

OpsHub Migrator for Microsoft Azure DevOps (OM4ADO)

OM4ADO stands out as a leading industry Azure DevOps migration service, developed in partnership with Microsoft, offering a robust solution for enterprise-scale migrations.

  • Zero Downtime Migration: By minimizing disruptions to ongoing development activities, OM4ADO ensures business continuity and productivity.
  • Rich Data Transfer: It supports a wide range of data types, including work items, code, builds, releases, test cases, and more, preserving historical context and relationships.
  • Scalability: Designed to handle large-scale migrations efficiently, OM4ADO accommodates enterprises with numerous teams and complex projects.
  • Reverse Synchronization: This feature enables seamless data management by maintaining consistency between source and target environments until the migration is complete.
  • Ability to Transform Data: OM4ADO can eliminate and organize inconsistent project structures, remove duplicates, etc. to ensure teams don’t fall into a trap to the ‘garbage-in, garbage-out’ approach and use the migration as an opportunity for growth.

Manual Migration

While seemingly cost-effective, manual migration through lift-and-shift or CSV import methods is often fraught with challenges.

  • Disruption: Manual processes can significantly impact team productivity and project timelines.
  • Error Prone: Human intervention increases the risk of data loss, corruption, or inconsistencies.
  • Lack of Scalability: Manual methods struggle to handle large datasets and complex migration scenarios.
  • High Opportunity Cost: The time and resources invested in manual migration could be better utilized for value-added activities.

In conclusion, carefully evaluating your organization’s specific needs and the capabilities of different migration tools is crucial for a successful Azure DevOps migration. While the Azure DevOps Data Migration tool provides a basic foundation, tools like OM4ADO offer advanced features and capabilities to streamline the process and minimize risks.

Cybersecurity 2026: Identity, Autonomy, and the Collapse of Passive Control

Cybersecurity 2026: Identity, Autonomy, and the Collapse of Passive Control

The latest industry discussions around AI governance reinforce a reality many engineering teams are already experiencing: identity governance was designed for humans — but the majority of identities executing code today are not.

AI agents, CI/CD pipelines, service accounts, and ephemeral workloads now authenticate, act, and mutate infrastructure faster than traditional controls can observe.

We are moving from a world of User Access to a world of Machine Execution.

This shift is not philosophical. It is architectural.

1. Non‑Human Identities Operate at Machine Speed

In July 2025, a widely discussed incident described how an autonomous AI agent deleted 1,206 database records in seconds, ignoring an active code freeze. The example was highlighted in a Cloud Security Alliance industry roundup on AI and identity governance.

The lesson was not about “AI intelligence failure.” The agent behaved according to its permissions.

The problem was privilege without boundary enforcement.

Autonomous systems inherit the scope we assign to them. If that scope is excessive, autonomy becomes amplification.

Traditional IAM models assume:

  • Human pacing
  • Manual review windows
  • Observable change cycles

Agentic systems violate all three assumptions.

Engineering Implication

Security controls must operate at the same velocity as execution. Detection after commit is too late when mutation happens in seconds.

Architectural Response: Pre‑Commit Enforcement

Instead of relying purely on runtime detection or post‑merge scanning, enforcement can shift closer to developer intent:

  • Intercept commits before merge
  • Validate secrets and tokens
  • Analyze infrastructure changes semantically
  • Block unsafe mutations deterministically

This model replaces passive observation with active boundary control.

Sentinel Core implements this pattern by operating as a real‑time enforcement layer in the development workflow, preventing unsafe commits before they enter the repository history.

2. Offboarding Is No Longer a Human Problem

In high‑pressure transitions or rapid restructuring events, disabling Slack or email access is insufficient.

Machine identities persist:

  • Long‑lived service tokens
  • CI runners with inherited permissions
  • Infrastructure‑as‑Code with embedded credentials
  • Kubernetes service accounts with cluster‑wide scope

If infrastructure state is not continuously validated against declared intent, drift accumulates silently.

Drift plus stale privilege equals latent risk.

Engineering Implication

Governance must expand beyond user access revocation into verifiable infrastructure integrity.

Architectural Response: Immutable Audit + IaC Guardrails

Embedding enforcement directly into Infrastructure as Code workflows ensures:

  • Terraform plans are validated before merge
  • Kubernetes manifests are policy‑checked pre‑deployment
  • Docker configurations are scanned for privilege escalation

Each blocked violation can be logged as an immutable artifact tied to:

  • Commit hash
  • Machine identity
  • User mapping

This creates an auditable chain of intent, not just activity.

Sentinel Core integrates this enforcement into repository workflows, generating traceable records for every rejected mutation.

3. Compliance Must Become Computable

Static documentation cannot keep pace with dynamic AI‑driven systems.

With evolving updates to ISO 27701 and SOC 2 guidance, compliance cannot rely solely on narrative evidence or spreadsheet tracking.

It must be derived from system state.

Engineering Implication

Technical findings must map deterministically to governance frameworks.

A vulnerability or misconfiguration should:

  1. Be machine‑detectable
  2. Map to a specific control requirement
  3. Produce reproducible evidence
  4. Generate tamper‑evident reporting

Architectural Response: Compliance as Code

Auditor Core transforms raw technical signals into structured audit evidence by mapping findings to:

  • SOC 2 Trust Services Criteria
  • ISO/IEC 27001:2022
  • CIS Controls v8

Findings are aggregated into a derived posture score and packaged into integrity‑sealed reports using SHA‑256 hashing to provide tamper‑evident verification.

This shifts compliance from documentation theater to computational integrity.

The Structural Reality

Agentic AI does not introduce new security principles.

It exposes weaknesses in our existing ones.

  • Identity without scope discipline becomes privilege escalation.
  • Automation without integrity guarantees becomes systemic risk.
  • Compliance without computation becomes performance art.

Organizations that adapt will not simply add more policies.

They will redefine trust boundaries around execution itself.

References

I built a collection of free DevTools to speed up my Laravel workflow (and yours too! 🚀)

Hey everyone!

As a Laravel developer, I often found myself jumping between browser tabs just to format JSON, generate secure keys, or debug regex patterns. While there are plenty of tools out there, many are cluttered with intrusive ads or feel slow.

So, I decided to build a dedicated hub for these daily utilities: tools.ananddesign.in

Why I built this?
The goal was simple: Speed and Privacy. I wanted a clean interface where the tools load instantly and don’t get in the way of the actual work.

What’s inside?
I’ve started with the essentials that I use almost every day during backend development:

JSON Formatter & Validator: No more “Invalid JSON” headaches.

String Converters : Quickly switch between camelCase, snake_case, and slugify (super handy for Laravel migrations and models).

Code Minifiers: To keep those frontend assets lean.

Secure Password/Key Generators: For your .env files.

Unit Converters & More.

The Tech Stack
Being a fan of the ecosystem, I built this using Laravel to ensure it’s robust and easy to scale. It’s hosted on a optimized VPS environment to ensure the response time is snappy.

I need your feedback! 🤝
This is a work in progress. I want to build tools that actually help our community.

What is the one tool you use every day but wish was better?

Are there any Laravel-specific utilities you’d like to see (e.g., Blade snippet generators or Validation rule builders)?

Check it out here: Web Tools

If you find it useful, a bookmark or a shout-out would mean the world! Happy coding! ❤️