Stop Letting AI Agents Break Your Database: Transactional Multi-Agent Workflows with Temporal and Spring AI

Stop Letting AI Agents Break Your Database: Transactional Multi-Agent Workflows with Temporal and Spring AI

In 2026, AI agents are no longer just glorified chatbots summarizing PDFs; they are executing real-world financial transactions, booking flights, and mutating production databases. But when an LLM tool call succeeds and the subsequent step fails due to a rate limit or a hallucinated parameter, you cannot just throw a 500 Internal Server Error and leave your database in an inconsistent state.

Why Most Developers Get This Wrong

  • Relying on @Transactional: Standard database transactions completely fail when dealing with asynchronous, non-blocking, and external LLM API calls.
  • Trusting LLMs to “Self-Correct”: Believing that a Claude 3.5 or GPT-4o agent can reliably invoke its own “undo” tools when a downstream system fails is a recipe for data corruption.
  • Homegrown State Machines: Writing fragile, database-backed polling mechanisms to orchestrate agent retries and rollback states instead of using durable execution.

The Right Way

Treat LLM tool execution as a series of distributed, unreliable steps orchestrated by a Temporal workflow using the Saga pattern.

  • Decouple Brains from State: Use Spring AI’s ChatClient to handle the non-deterministic reasoning and tool routing, but let Temporal handle the execution state.
  • Register Compensations Immediately: For every successful tool execution, register its compensating rollback action inside a Temporal Saga builder.
  • Isolate LLM Calls in Activities: Never call an LLM directly inside a Temporal Workflow method; wrap Spring AI calls in Temporal Activities to keep the workflow deterministic.

Shameless plug: javalld.com has full LLD implementations with step-by-step execution traces — free to use while prepping.

Show Me The Code

Here is how you orchestrate an agentic transaction with Spring AI and Temporal’s Saga API:

@WorkflowMethod
public void executeAgenticBooking(String userPrompt) {
    Saga saga = new Saga(new Saga.Options.Builder().build());
    try {
        // Spring AI parses prompt and decides on the tool execution path
        AgentDecision decision = aiActivities.consultLLM(userPrompt);

        bookingActivities.chargeCard(decision.getAmount());
        saga.addCompensation(bookingActivities::refundCard, decision.getAmount());

        bookingActivities.reserveSeat(decision.getSeatId());
        saga.addCompensation(bookingActivities::releaseSeat, decision.getSeatId());
    } catch (ActivityFailure e) {
        saga.compensate(); // Guaranteed, durable rollback across microservices
        throw e;
    }
}

Key Takeaways

  • Deterministic Orchestration: LLMs are inherently non-deterministic; your workflow engine must be 100% deterministic.
  • Spring AI for Mapping, Temporal for Execution: Use Spring AI to bind prompts to Java POJOs, then pass those POJOs to Temporal Activities.
  • Never Trust the Agent: Always assume the LLM will hallucinate a tool parameter at step 3, and design your compensating Sagas to handle the cleanup automatically.

How I use Postman’s “Send and Download” to debug ZIP responses from an API

If you’ve ever tried to debug an API endpoint that returns a binary file — a ZIP, a PDF, an exported report — using the regular Send button in Postman, you’ve probably hit this: Postman tries to render the response in the preview pane, the bytes get garbled, and you have no way to actually open the file and look inside.

I run into this almost daily. I’m a backend developer working on the routing layer of a logistics product, and one of the things we ship is a bundle of route data as a ZIP — multiple files inside, generated server-side, downloaded by clients. When something looks off in production (wrong file count, corrupted entries, missing manifest), the fastest way for me to triage is to hit the endpoint myself in Postman, get the ZIP onto my machine, and unpack it.

This post covers the workflow I’ve landed on. It’s nothing exotic, but it took me longer to discover than it should have, so writing it down in case it saves someone else a couple of hours.

## The problem with regular Send

When you hit Send on a request whose response has a binary Content-Type like application/zip, application/octet-stream, or application/pdf, Postman buffers the bytes into its response viewer. You can technically scroll through hex output, but you can’t double-click and open the file. Worse, if you try to copy the response into a .zip file manually, Postman’s text encoding silently corrupts non-UTF-8 bytes — the file you save won’t unzip.

For a while I was working around this with curl --output route.zip from the terminal. That works, but loses everything Postman gives me: request history, environment variables for staging vs. prod tokens, collection runners, and the ability to share the exact request with a teammate.

## The fix: Send and Download

Postman has a separate option next to the Send button. Click the dropdown arrow and you’ll see Send and Download.

This sends the request, receives the response, and instead of trying to render it, prompts you for a file location and writes the raw response body to disk. Filename, extension, location — your choice. The bytes hit the file system exactly as the server sent them.

For my routing ZIPs that means:

  1. POST to the route-bundle endpoint with the right auth headers and body
  2. Click the dropdown arrow next to Send → Send and Download
  3. Save as route-bundle-prod.zip in a scratch folder
  4. Open the file with my OS’s archive tool, or unzip -l route-bundle-prod.zip to list contents

If the file count is wrong or one of the inner files is empty, I know it before the client team has to file a ticket.

## A few things I’ve learned

1. Status codes still matter. Send and Download doesn’t surface the status code as obviously as Send does — you have to glance at the response status bar. If the server returned a 500 with an HTML error page but the Content-Type was still application/zip, you’ll save a 4 KB “ZIP” that’s actually an HTML error. Always check the status first.

2. Authorization headers carry over. This caught me out early. I’d switched environments to staging but the request still had a prod bearer token. The file downloaded successfully but unzipped to the wrong tenant’s data. Now I double-check the {{baseUrl}} and {{token}} variables in the request URL before hitting Send and Download, especially after switching environments.

3. Save into a scratch directory, not Downloads. If you do this often, your Downloads folder fills up with download.zip (3).zip files. I have a ~/postman-downloads/ folder I clear out weekly.

4. Pair it with the Scripts tab for assertions. You can write a quick pm.test in the Scripts tab that asserts the response Content-Length is above some minimum threshold — useful to catch empty-ZIP regressions automatically when
you’re running a collection.

## Wrap-up

Send and Download isn’t a flashy feature. It’s a small option two clicks deep. But if your API surface includes any kind of file export endpoint, it removes the only real reason to drop out of Postman and into curl. I haven’t touched curl for downloading API responses since I found it.

If you’re working on a similar binary-response endpoint and Postman feels like it’s fighting you, give it a try.

How to build a visual uptime monitor with Go and headless Chrome

Most uptime monitors work by making an HTTP request and checking the response code. It’s fast, cheap, and catches about half the things that actually go wrong in production.

The other half – JavaScript crashes, CDN serving stale cache, React hydration failures, missing elements – only show up when you look at what the page actually renders, not what the server returns.

This is a walkthrough of how I built GrabDiff – the visual monitoring piece specifically: capture screenshots with headless Chrome, diff them against a baseline, and send an alert when something looks wrong. I’ll use Go and chromedp, which is what GrabDiff runs under the hood. If you’d rather just use the thing than build it, GrabDiff has a free plan with three monitors and no card required.

The architecture

The core loop is simple:

  1. On a schedule, capture a screenshot of a URL using headless Chrome
  2. Compare it pixel-by-pixel against a stored baseline image
  3. If the diff percentage exceeds a threshold, send an alert with the diff image attached
  4. Otherwise, store the new screenshot (optionally updating the baseline over time)

The interesting engineering is in steps 2 and 3 – getting the diff right and making alerts actionable.

Capturing screenshots with chromedp

chromedp is a Go library that controls Chrome via the DevTools Protocol. It handles the browser lifecycle, navigation, and screenshot capture.

package screenshot

import (
    "context"
    "time"

    "github.com/chromedp/chromedp"
)

func Capture(url string) ([]byte, error) {
    opts := append(chromedp.DefaultExecAllocatorOptions[:],
        chromedp.Flag("headless", true),
        chromedp.Flag("disable-gpu", true),
        chromedp.Flag("no-sandbox", true),
        chromedp.WindowSize(1280, 800),
    )

    allocCtx, cancel := chromedp.NewExecAllocator(context.Background(), opts...)
    defer cancel()

    ctx, cancel := chromedp.NewContext(allocCtx)
    defer cancel()

    ctx, cancel = context.WithTimeout(ctx, 30*time.Second)
    defer cancel()

    var buf []byte
    err := chromedp.Run(ctx,
        chromedp.Navigate(url),
        chromedp.Sleep(2*time.Second), // wait for JS to settle
        chromedp.FullScreenshot(&buf, 90),
    )
    if err != nil {
        return nil, err
    }
    return buf, nil
}

A few things worth noting:

chromedp.Sleep(2*time.Second) is a blunt instrument but effective. For most pages, 2 seconds is enough for the JavaScript to execute and the page to reach a stable state. For pages with complex async data fetching you might need more, or you can use chromedp.WaitVisible to wait for a specific element.

chromedp.FullScreenshot captures the entire page height, not just the viewport. This is usually what you want for monitoring – you care about the whole page, not just what happens to be visible above the fold.

The 90 in FullScreenshot is JPEG quality. You can use chromedp.CaptureScreenshot instead for PNG (larger files, lossless).

Pixel diffing

Once you have a screenshot, you need to compare it against the baseline. The core operation is straightforward: decode both images, iterate over pixels, count how many differ by more than some per-channel threshold.

package screenshot

import (
    "bytes"
    "image"
    "image/color"
    _ "image/jpeg"
    "image/png"
    "math"
)

type DiffResult struct {
    DiffPercent float64
    DiffImage   []byte // PNG with differences highlighted
}

func Diff(baseline, current []byte) (*DiffResult, error) {
    baseImg, _, err := image.Decode(bytes.NewReader(baseline))
    if err != nil {
        return nil, err
    }
    currImg, _, err := image.Decode(bytes.NewReader(current))
    if err != nil {
        return nil, err
    }

    bounds := baseImg.Bounds()
    diffImg := image.NewRGBA(bounds)

    var diffPixels int
    totalPixels := bounds.Dx() * bounds.Dy()

    for y := bounds.Min.Y; y < bounds.Max.Y; y++ {
        for x := bounds.Min.X; x < bounds.Max.X; x++ {
            br, bg, bb, _ := baseImg.At(x, y).RGBA()
            cr, cg, cb, _ := currImg.At(x, y).RGBA()

            // RGBA() returns values in [0, 65535]
            dr := math.Abs(float64(br) - float64(cr))
            dg := math.Abs(float64(bg) - float64(cg))
            db := math.Abs(float64(bb) - float64(cb))

            // threshold: 10% channel difference (6553 out of 65535)
            if dr > 6553 || dg > 6553 || db > 6553 {
                diffPixels++
                // highlight in red
                diffImg.Set(x, y, color.RGBA{R: 255, G: 0, B: 0, A: 255})
            } else {
                // keep original, slightly dimmed for context
                r, g, b, a := currImg.At(x, y).RGBA()
                diffImg.Set(x, y, color.RGBA{
                    R: uint8(r>>8) / 2,
                    G: uint8(g>>8) / 2,
                    B: uint8(b>>8) / 2,
                    A: uint8(a >> 8),
                })
            }
        }
    }

    diffPercent := float64(diffPixels) / float64(totalPixels) * 100

    var buf bytes.Buffer
    if err := png.Encode(&buf, diffImg); err != nil {
        return nil, err
    }

    return &DiffResult{
        DiffPercent: diffPercent,
        DiffImage:   buf.Bytes(),
    }, nil
}

The diff image produced here shows changed pixels in red against a dimmed version of the current screenshot. This gives you at a glance where the change is – useful when you’re trying to tell whether it’s a minor layout shift or something more serious.

On threshold tuning: 1% is a good starting point for DiffPercent. Anything above that is almost certainly a real change. Below 0.1% is usually antialiasing noise. The right number depends on how dynamic your pages are.

Storing baselines

You need to store the baseline image somewhere. For a simple setup, an object store (S3, Backblaze B2, R2) works well – store the baseline under a key like {monitor_id}/baseline.jpg and update it when the user explicitly marks a new baseline.

// On first check, or when user resets the baseline
func (s *Store) SetBaseline(ctx context.Context, monitorID string, img []byte) error {
    key := fmt.Sprintf("%s/baseline.jpg", monitorID)
    return s.upload(ctx, key, img, "image/jpeg")
}

// On each check
func (s *Store) GetBaseline(ctx context.Context, monitorID string) ([]byte, error) {
    key := fmt.Sprintf("%s/baseline.jpg", monitorID)
    return s.download(ctx, key)
}

One design decision worth thinking about: should the baseline update automatically? There are arguments either way. If you update it automatically after every “clean” check, you adapt to intentional page changes without manual intervention. If you require explicit resets, every change that slips past your threshold accumulates silently, and you’ll eventually be diffing against something that looks nothing like your original known-good state.

GrabDiff requires explicit baseline resets. The reasoning: if you’re updating the baseline automatically, you can drift into a state where “clean” means “whatever the page looked like yesterday” rather than “the page as I intended it.” Explicit resets keep you honest.

Alerting

When DiffPercent exceeds your threshold, you want to notify someone fast. The two most useful channels are email (with the diff image attached) and webhooks.

type Alert struct {
    MonitorURL  string
    DiffPercent float64
    DiffImage   []byte
    CheckedAt   time.Time
}

func (s *EmailSender) SendAlert(ctx context.Context, to string, a Alert) error {
    body := fmt.Sprintf(
        "Visual change detected on %snnDiff: %.2f%% of pixels changednChecked at: %snnSee attached diff image.",
        a.MonitorURL, a.DiffPercent, a.CheckedAt.Format(time.RFC1123),
    )

    msg := gomail.NewMessage()
    msg.SetHeader("From", s.from)
    msg.SetHeader("To", to)
    msg.SetHeader("Subject", fmt.Sprintf("[GrabDiff] Change detected: %s", a.MonitorURL))
    msg.SetBody("text/plain", body)
    msg.AttachReader("diff.png", bytes.NewReader(a.DiffImage))

    return s.dialer.DialAndSend(msg)
}

The diff image as an attachment is the key thing. An alert that just says “something changed” is nearly useless – you have to go look at the site yourself to know if it matters. An alert with a diff image attached tells you immediately whether this is “someone changed a button color” or “the entire main content area is gone.”

Scheduling

For the scheduling loop, a simple approach is a ticker per monitor:

func (w *Worker) Run(ctx context.Context, monitor Monitor) {
    ticker := time.NewTicker(monitor.Interval)
    defer ticker.Stop()

    for {
        select {
        case <-ctx.Done():
            return
        case <-ticker.C:
            if err := w.check(ctx, monitor); err != nil {
                slog.Error("check failed", "monitor", monitor.ID, "err", err)
            }
        }
    }
}

For anything beyond a handful of monitors, you’ll want a proper job queue (River, Asynq, or even a simple Postgres-backed queue) rather than in-process goroutines. In-process schedulers don’t survive restarts gracefully and make horizontal scaling harder.

The tradeoffs you’ll hit in production

False positives from dynamic content. Timestamps, “last updated” labels, live counters, personalized greetings – these change on every screenshot and will trigger alerts constantly. You either need to mask those regions before diffing, or accept a higher threshold that makes you insensitive to small changes everywhere.

Headless Chrome resource usage. A single Chrome instance capturing a screenshot uses roughly 200-400MB of RAM and takes 3-8 seconds depending on page complexity. If you’re running hundreds of monitors at frequent intervals, you need a pool of browser instances and careful scheduling to avoid spiking resource usage.

Authentication. Monitoring pages behind a login requires scripting the auth flow:

chromedp.Run(ctx,
    chromedp.Navigate("https://app.example.com/login"),
    chromedp.SendKeys(`input[name="email"]`, email),
    chromedp.SendKeys(`input[name="password"]`, password),
    chromedp.Click(`button[type="submit"]`),
    chromedp.WaitVisible(`#dashboard`),
    chromedp.Navigate(targetURL),
    chromedp.FullScreenshot(&buf, 90),
)

This works, but it’s fragile – login flows change, CAPTCHAs appear, session handling has edge cases. Plan for maintenance.

SSRF. If you’re accepting URLs from users, you need to validate them against a blocklist before passing them to Chrome. Users will point your monitor at http://169.254.169.254/latest/meta-data/ or internal network addresses. Validate the resolved IP against RFC 1918 and link-local ranges before making any request.

What this gets you

A working version of the above – capture, diff, alert – is maybe 500 lines of Go. It’ll catch blank pages, missing elements, major layout regressions, and CDN serving stale content. It won’t catch every failure, but it catches the ones that HTTP monitors miss entirely.

If you want to run it yourself, the full approach is essentially what I described. If you’d rather not manage the Chrome instances and the storage and the scheduling, I built GrabDiff to handle all of that – it does the screenshot diffing, sends you the diff image in the alert, and handles SSL/domain/cron monitoring alongside the visual checks. Free plan, three monitors, no credit card.

The point is that “HTTP 200” and “the page works” are not the same thing, and the gap between them is where the interesting production failures live. Visual monitoring is how you close that gap.

OpenAI Files for IPO: What Every Developer Building on OpenAI Needs to Know (2026)

OpenAI filed its IPO prospectus confidentially this week, targeting a September 2026 public listing at a valuation above $1 trillion — and every developer building production applications on the OpenAI API needs to understand what that means for their business. IPOs do not just create paper wealth for insiders; they fundamentally reshape how companies operate. Pricing decisions, model release cadence, research openness, and API reliability all shift when public market accountability enters the picture. This guide breaks down OpenAI’s financial position, what the Microsoft partnership restructure actually changes, and the concrete steps developers should take before the S-1 becomes public.

The filing is happening in the middle of the most competitive moment in AI history. Anthropic is targeting an October 2026 IPO. SpaceX filed its own S-1 on May 20. Both companies share overlapping infrastructure deals, investors, and developer mindshare. The AI infrastructure layer — APIs that millions of developers depend on — is about to become part of the public markets conversation in a way it never has been before. The implications are not theoretical.

What We Know About OpenAI’s Financials

OpenAI’s March 2026 funding round disclosed approximately $2 billion in monthly revenue — roughly $25 billion annualized, up from $20 billion at the close of 2025. The company closed a $122 billion funding round in late March 2026 at an $852 billion post-money valuation, making it one of the largest private financings in technology history. Those are staggering numbers, but they come with important context that the public S-1 will either confirm or complicate.

What investors and developers still cannot see — until the public S-1 drops — is gross margin after compute costs. Large language model inference is extraordinarily capital-intensive. Training and serving frontier models like GPT-5.5 requires GPU clusters at a scale that makes compute cost one of the largest variables in the economics. A company earning $25 billion in revenue but spending $22 billion on compute, salaries, and infrastructure has a very different financial profile than the headline revenue number suggests.

CFO Sarah Friar’s blog post in January 2026 confirmed that the company crossed $20 billion annualized. What she did not disclose was burn rate, capex obligations, or the gross margin after infrastructure costs. Public market investors will demand those numbers. If compute economics are tighter than the valuation assumes, the pressure to raise API prices or cut model availability will intensify after the IPO.

For developers, watch the S-1 filing for three specific disclosures. First, gross margin — anything below 50% signals sustained price pressure. Second, API revenue as a percentage of total revenue — if enterprise subscriptions (ChatGPT Enterprise, OpenAI for Business) are growing faster than API revenue, that signals a de-prioritization of the developer tier. Third, capex guidance — if the company is committing to $30+ billion in infrastructure spend annually, the capital needs will put pressure on monetization timelines.

The Microsoft Restructure: What Actually Changed for Developers

The most underreported aspect of OpenAI’s IPO preparation is the renegotiated Microsoft partnership finalized in May 2026. Under the new terms, OpenAI’s total revenue-share payments to Microsoft are capped at $38 billion through 2030 — down from a projected $135 billion under the prior agreement. That $97 billion difference is structural improvement in OpenAI’s cash flow position that directly affects how much financial pressure the company faces to aggressively monetize the API.

Microsoft retains approximately 27% of OpenAI on a diluted basis, valued at roughly $135 billion at the $852 billion round valuation. As the company moves toward an IPO, Microsoft’s role shifts from a capital provider to a major shareholder with public market exposure. That alignment of interests changes the dynamic: Microsoft now has an incentive for OpenAI’s public valuation to hold, which creates pressure to demonstrate stable, growing API revenue rather than subsidizing below-market pricing.

For developers building on Azure OpenAI Service, the restructure matters directly. Azure OpenAI pricing and model availability has historically tracked the direct API — but as the commercial interests of both companies sharpen around the IPO window, divergence is possible. A developer team with major Azure commitments may find its OpenAI model access governed through a different SLA and cadence than a team using the direct API. Mapping your specific integration path now, before the IPO paperwork locks in new commercial frameworks, is worth doing proactively.

API Pricing Under Public Market Pressure

The core developer concern with any AI company IPO is straightforward: does going public accelerate price increases? The honest answer is that it depends on where the company sits in its growth phase — and OpenAI’s trajectory suggests measured caution is warranted.

OpenAI has historically used aggressive pricing as a growth lever. GPT-4o remains available on the free tier. GPT-5.5 dropped to $2/$8 per million tokens within weeks of launch. The company has subsidized developer adoption with below-cost pricing while scaling user growth. That strategy is sustainable with private capital and venture backing. It becomes structurally harder to justify on a quarterly earnings call when public investors are watching gross margin compress against capex commitments.

The historical precedent from SaaS infrastructure companies that went public is instructive. Twilio raised prices twice in the 18 months following its 2016 IPO. Snowflake restructured its pricing from on-demand to committed-use contracts to smooth revenue recognition for Wall Street analysts. Stripe’s private pricing flexibility narrowed significantly as the company grew closer to IPO readiness. These are not failures — they are the predictable consequence of public market accountability requirements.

What this means in practice for OpenAI: the most likely scenario is not sudden price spikes but gradual reduction in free-tier generosity, more aggressive promotion of committed-use enterprise contracts, and slower pass-through of model cost reductions to API pricing. The era of GPT-4-class models becoming free-tier access almost certainly ends within 12 months of the IPO. Developers should baseline their current costs now and build cost-increase scenarios into runway models before the S-1 drops.

Model Release Cadence and Research Openness

Public companies in AI face a contradictory pressure: investors want predictable recurring revenue, but AI capability advances on an inherently unpredictable research timeline. OpenAI’s current strategy of releasing models when they are ready — GPT-5.5 released May 2026, GPT-5.5 Instant for ChatGPT in the same month — gives the company maximum technical flexibility but creates inconsistent revenue recognition that equity analysts will push back on.

Post-IPO, expect more structured release cadences aligned with the quarterly earnings calendar. Research releases that previously happened when ready will increasingly align with quarterly announcements. This is not necessarily bad for developers — predictability in model updates makes API versioning and migration planning considerably easier — but it reduces the sense that you are always accessing the frontier model as fast as research progress allows.

Research openness is the more significant long-term concern. OpenAI’s name grows increasingly ironic — the company has not open-sourced a frontier model in several years. The commercial pressures of being a public company make sharing model weights even less likely. If competitive advantage lives in the model, and the model is the primary revenue-generating asset, the incentive to open-source any meaningful component of that asset disappears entirely under public market scrutiny. Developers building on OpenAI should assume that access to model internals, fine-tuning endpoints on frontier models, and research previews will become more restricted rather than more open over the next 18 months.

Building a Multi-Provider Strategy Before the IPO

The most actionable response to OpenAI’s IPO is to reduce API-level lock-in now, while switching costs are still manageable. Teams that built exclusively on the OpenAI API have accumulated technical debt in the form of provider-specific features: OpenAI function calling syntax, OpenAI Assistants API patterns, OpenAI file handling and thread management. Migrating those to provider-agnostic interfaces after a price increase happens under pressure — the worst possible conditions for careful engineering.

The multi-provider pattern that has emerged as the production standard in 2026 uses a routing layer — LiteLLM, OpenRouter, or a custom abstraction — that normalizes the OpenAI-compatible API interface across multiple providers. Anthropic’s Claude, Google’s Gemini, and OpenAI’s GPT all accept requests in compatible formats when routed through these layers. The incremental engineering cost is a few hours; the optionality created is substantial.

A minimal provider hedge for a production application looks like this: route non-latency-sensitive tasks — batch summarization, classification, document extraction — to whichever provider currently offers the best cost-per-quality ratio. Route latency-sensitive tasks such as real-time chat and code completion to your primary provider. Keep model-specific integrations in an adapter layer that can be swapped without touching business logic. Evaluate at least one alternative provider monthly to maintain institutional familiarity and keep your routing configuration current.

The goal is not to abandon OpenAI. GPT-5.5 and its successors will likely remain among the strongest models for many use cases throughout the IPO period and beyond. The goal is to ensure that a price increase or API policy change is a decision you make deliberately, from a position of optionality, rather than a crisis you react to from a position of lock-in.

The Competitive Landscape After Three Public AI Companies

OpenAI’s IPO does not happen in isolation. Anthropic is targeting an October 2026 public listing. Google’s Gemini business is already public through Alphabet, with AI revenue now broken out separately in quarterly reports. The era of private AI companies competing on research timelines without public accountability is ending for all three major API providers simultaneously.

This convergence creates a meaningful developer opportunity: all three companies will be competing for developer mindshare under public market scrutiny, which historically increases investment in developer tools, documentation, pricing competitiveness, and ecosystem programs. The 18-24 months following the OpenAI IPO are likely to be the most actively competitive period for API pricing and developer tooling in AI history. Each company will be demonstrating developer ecosystem health to public market investors and analysts who can compare them directly.

Developers who maintain active integrations with multiple providers are positioned to benefit from this dynamic. Being a credible alternative-ready customer gives leverage in enterprise contract discussions that a provider-locked developer simply does not have. When three public companies are competing for the same developer spend on the same earnings cycle, the developer with optionality is the one with pricing power.

Three Things Developers Should Do This Week

The IPO filing is happening now. Here is what is worth doing before the public S-1 drops and the market narrative solidifies:

Audit your OpenAI API spend by feature. Break down your monthly spend by which specific capabilities you use: which models, which endpoints, which features have no direct equivalent elsewhere. Identify the 20% of your OpenAI usage that is genuinely irreplaceable versus the 80% that could be routed to an alternative today. The audit itself is valuable even if you never migrate a single workload — it gives you a clear picture of your actual exposure.

Set up a parallel environment with one alternative provider. Register for Anthropic API access or Gemini API access if you have not already. Run a representative sample of your production workloads against the alternative. Measure quality, latency, and cost. This takes a few hours of engineering time and removes the knowledge gap that makes migration feel more daunting than it actually is.

Define your cost escalation thresholds now. If your OpenAI costs increase by 25%, 50%, or 2x, what happens to your product economics and unit margins? Define those thresholds explicitly. Build a simple cost dashboard that surfaces provider spend on a daily basis. When the IPO-driven pricing pressure arrives — and historical precedent suggests it will — you will know immediately rather than discovering it in the next monthly invoice.

OpenAI going public is a genuine milestone for the AI industry — the company that sparked the modern large language model era will be accountable to public markets for the first time. For developers, the filing week is the right moment to stress-test your infrastructure dependency and build the optionality that keeps you in control of your own product economics, regardless of what any single provider decides to do with its pricing strategy in the quarters ahead.

Originally published at wowhow.cloud

We discovered the real workflow during lunch conversations.

Official process:
Create request
Manager approval
System update
Done

Real process:
Someone messages on WhatsApp
Another person updates Excel
Manager approves verbally
System gets updated later

The company was not running on the documented workflow.

It was running on habits.

This happens a lot in BrainPack deployments. The real operating system of a company usually exists between people long before it exists inside software.

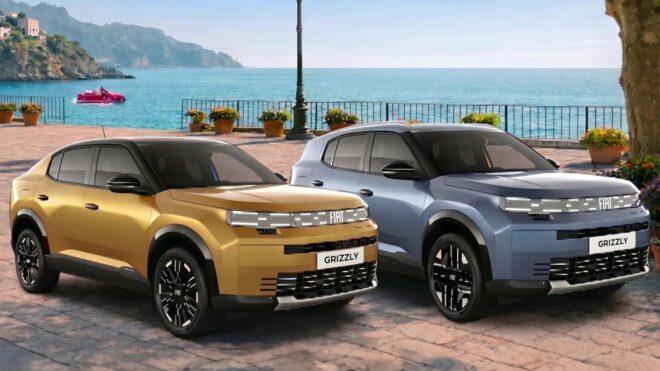
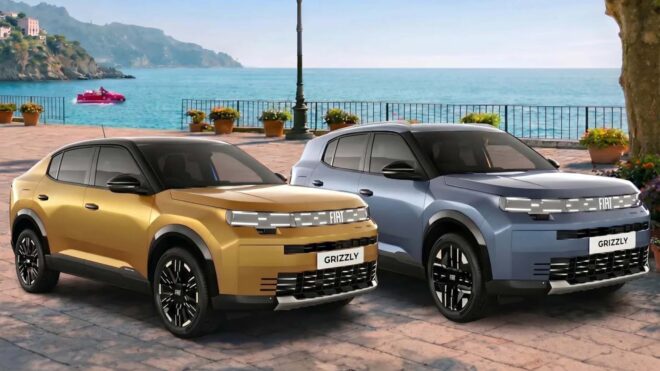
Yeni model Fiat Grizzly için tasarım resmi olarak paylaşıldı

Fiat Grizzly için tasarım resmi olarak paylaşıldı

Fiat Grizzly için tasarım resmi olarak paylaşıldıAvrupa, Latin Amerika, Orta Doğu ve Afrika merkezli çok sayıda ülkede satılacak Fiat Grizzly için tasarımı resmi olarak paylaşıldı. Grande Panda’nın daha büyük versiyonu olarak tanımlanan araç, ailelere yönelik bütçe dostu bir SUV ve daha sportif “Coupe-SUV” versiyonu da bulunuyor. Araç hakkında ABD’nin Michigan eyaletinde düzenlenen etkinlikte konuşan Fiat CEO’su Olivier Francois, “Yeni Fiat Grizzly’nin burada iki farklı silüetini görüyorsunuz çünkü bu araç dünyanın üç farklı bölgesi için tasarlandı. Yeni model, Panda ve Grande Panda ailesini tamamlıyor. Aynı DNA’yı taşıyorlar ve yine Smart Car platformu üzerine inşa edildiler ancak bu kez karşımızda daha büyük bir araç var.” ifadelerini kullandı. Pazara benzinli, elektrikli ve hibrit altyapılarla çıkarılması beklenen Grizzly, resmi olarak Türkiye pazarına da getirilebilir.

Yeni model Fiat Grizzly için tasarım resmi olarak paylaşıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

I automated 80% of my email replies with a free n8n workflow — full JSON inside

I was spending 2+ hours a day responding to the same 4 types of emails: pricing questions, support requests, meeting requests, and general inquiries.

The replies were nearly identical every time. So I built a simple n8n workflow to handle them automatically — and I’ve been running it for months with zero issues.

Here’s how it works, and the full workflow JSON at the end.

What the workflow does

  1. Gmail Trigger — polls for new unread emails every minute
  2. Skip No-Reply filter — prevents reply loops from automated senders
  3. Intent detector — scans subject + body for keywords: pricing, support, meeting, general
  4. Auto-reply — sends the appropriate template reply
  5. Google Sheets log — every auto-reply is logged for review

Time to set up: ~15 minutes

n8n version: 1.40+

Cost: Free (no paid nodes)

The intent detection logic

This is the key node — a Code node that does simple keyword matching:

const subject = ($json["subject"] || "").toLowerCase();
const body = ($json["snippet"] || "").toLowerCase();
const text = subject + " " + body;

let intent = "general";
if (text.includes("price") || text.includes("cost") || text.includes("pricing") || text.includes("how much")) {
  intent = "pricing";
} else if (text.includes("support") || text.includes("help") || text.includes("issue") || text.includes("problem")) {
  intent = "support";
} else if (text.includes("meeting") || text.includes("call") || text.includes("schedule") || text.includes("demo")) {
  intent = "meeting";
}

Simple and reliable. No LLM needed for basic intent detection — keyword matching handles 90% of cases correctly.

4 things I learned building this

1. The no-reply filter is critical.

Without it, the workflow replies to automated emails, which often reply back, which you then reply to again — infinite loop. Filter any sender containing “noreply”, “no-reply”, “mailer-daemon”, “bounce”.

2. Poll every 5 minutes, not every minute.

Polling every minute works but hammers the Gmail API. Every 5 minutes is effectively the same experience for email — nobody notices a 4-minute delay in an auto-reply.

3. Always log to a spreadsheet.

The log is how you catch edge cases. After a week, review what got auto-replied and tune your keyword lists. I added “pricing inquiry” and “price check” after seeing them in the logs.

4. Test with a throwaway Gmail account first.

I cannot stress this enough. Point it at a throwaway first, send test emails with different subjects, verify the right replies go out. Takes 10 minutes and saves you from accidentally spam-replying your entire inbox.

Full workflow JSON

Import this into n8n: Workflows → New → ⋮ → Import from JSON → paste.

{
  "name": "Email Auto-Responder",
  "nodes": [
    {
      "parameters": {
        "pollTimes": { "item": [{ "mode": "everyMinute" }] },
        "filters": {}
      },
      "id": "e1",
      "name": "Gmail Trigger",
      "type": "n8n-nodes-base.gmailTrigger",
      "typeVersion": 1,
      "position": [240, 300]
    },
    {
      "parameters": {
        "conditions": {
          "string": [
            {
              "value1": "={{ $json["from"] }}",
              "operation": "notContains",
              "value2": "noreply"
            }
          ]
        }
      },
      "id": "e2",
      "name": "Skip No-Reply",
      "type": "n8n-nodes-base.if",
      "typeVersion": 1,
      "position": [460, 300]
    },
    {
      "parameters": {
        "jsCode": "const subject = ($json["subject"] || "").toLowerCase();nconst body = ($json["snippet"] || "").toLowerCase();nconst text = subject + " " + body;nnlet intent = "general";nif (text.includes("price") || text.includes("cost") || text.includes("pricing")) {n  intent = "pricing";n} else if (text.includes("support") || text.includes("help") || text.includes("issue")) {n  intent = "support";n} else if (text.includes("meeting") || text.includes("call") || text.includes("schedule")) {n  intent = "meeting";n}nnconst replies = {n  pricing: "Hi,\n\nThanks for reaching out! Here is our current pricing:\n\n[PASTE YOUR PRICING HERE]\n\nBest,\nAlex",n  support: "Hi,\n\nThanks for contacting us. We will respond within 24 hours.\n\nBest,\nAlex",n  meeting: "Hi,\n\nYou can book a call here: [YOUR CALENDLY LINK]\n\nBest,\nAlex",n  general: "Hi,\n\nThanks for your message! We will get back to you within 24 hours.\n\nBest,\nAlex"n};nnreturn [{ json: { ...items[0].json, intent, replyText: replies[intent] } }];"
      },
      "id": "e3",
      "name": "Detect Intent",
      "type": "n8n-nodes-base.code",
      "typeVersion": 2,
      "position": [680, 300]
    },
    {
      "parameters": {
        "sendTo": "={{ $json["from"] }}",
        "subject": "Re: {{ $json["subject"] }}",
        "message": "={{ $json["replyText"] }}",
        "options": {}
      },
      "id": "e4",
      "name": "Send Reply",
      "type": "n8n-nodes-base.gmail",
      "typeVersion": 2,
      "position": [900, 300]
    }
  ],
  "connections": {
    "Gmail Trigger": { "main": [[{ "node": "Skip No-Reply", "type": "main", "index": 0 }]] },
    "Skip No-Reply": { "main": [[{ "node": "Detect Intent", "type": "main", "index": 0 }]] },
    "Detect Intent": { "main": [[{ "node": "Send Reply", "type": "main", "index": 0 }]] }
  }
}

What to customize

  • The reply templates for each intent (fill in your actual pricing, FAQ URL, calendar link)
  • Add more intent keywords for your specific inbox patterns
  • Change everyMinute to everyFiveMinutes to reduce API calls

Want the extended version?

The free workflow above handles the basics. The paid version (part of a template pack I’ve been building) adds:

  • AI-powered intent detection using OpenAI for edge cases keyword matching misses
  • Attachment handling — flags emails with attachments for human review
  • Priority routing — escalates emails from VIP senders to Slack immediately
  • Unsubscribe handling — detects “unsubscribe” requests and logs them without replying
  • Multi-inbox support — handles multiple Gmail accounts in one workflow

Full pack: https://stripeai.gumroad.com — 15 n8n workflows, all with setup guides.

Happy to answer questions on the free version in the comments.

The ‘Why is it floating?!’ Problem in Blender — I Made a Free Add-on for That

Have you ever run into any of these situations in Blender?

  • You placed an object at Z = 0, but it’s floating in the air (or half-buried in the floor)
  • An imported model has its origin at the mesh center instead of the bottom
  • You tried to move the origin to the bottom, and it took way more steps than it should

If the origin is at the bottom center, you can just snap it to Z = 0 and it sits perfectly on the floor.
But getting there requires a few annoying steps:

  1. Switch to Edit Mode, select the bottom face/vertices, and snap the 3D Cursor there
  2. Switch back to Object Mode and set the origin to the 3D Cursor

When you’re building an interior scene with a bunch of furniture, doing this over and over gets old fast.

So I made an add-on that handles it with a right-click.

Origin to Bottom Center

A simple Blender add-on that automatically moves an object’s origin to the center of its lowest point (bottom face).

Select multiple objects and it updates each one individually — no need to do them one by one.

When it comes in handy

Placing furniture and props
With the origin at the bottom, dropping something at Z = 0 places it perfectly on the floor. No manual height adjustment needed.

Fixing imported models
Models from other apps often have inconsistent origin positions. Select them all and fix in one shot.

Organizing a scene
When arranging multiple objects side by side, having consistent origin positions makes placement a lot easier.

Download (Free)

Available for free on Booth:

👉 https://epartworks.booth.pm/items/8275371

Wrapping up

I’m planning to keep building small add-ons for operations that feel like they should be in Blender already but aren’t.

If this was useful, a follow would make my day 😊

I built an audit-friendly SQLite viewer for VSCode because I stopped trusting marketplace extensions

Atalaya — main view: tables sidebar, paginated data, status bar with row counts and active filters

Atalaya — Spanish for “watchtower”. A high vantage point with a clear view over the territory below.

The uncomfortable question

Open VSCode. Search “SQLite”. Pick the most popular extension. Run find node_modules -type d | wc -l after installing it locally. Most of them sit somewhere between 200 and 500 packages in their transitive dependency tree, plus native code bundled per platform.

For a tool whose single job is to read a .db file.

[TODO: drop a personal anecdote here — when did supply-chain risk in editor extensions stop being abstract for you? a coworker affected, a compromised package you remember, the recent xz-utils backdoor narrative, whatever feels honest. one paragraph max.]

When that’s the surface a tool sits on, every extension you install is a trust decision you’re making against your entire workspace: source code, environment variables, git credentials, the lot. And the threat is not theoretical — compromised VSCode extensions have shipped credential-stealers to thousands of developers in the last two years.

So I built one I could actually audit.

Meet Atalaya

Atalaya is a SQLite viewer for VSCode with a deliberately minimal footprint:

  • One runtime dependency in the shipped .vsix: sql.js, the official SQLite compiled to WebAssembly
  • Zero native modules — no node-gyp, no platform-specific compilation
  • Zero network calls, zero telemetry, zero remote resource loading
  • Strict CSP in the webview (default-src 'none' + per-load cryptographic nonce)
  • All SQL identifiers are allowlist-validated; all SQL values bound via prepared statements
  • MIT licensed, ~2,300 lines of code total

Atalaya — main view: tables sidebar, paginated data, status bar with row counts and active filters

Features that actually matter

It opens .db, .sqlite, .sqlite3 files as a custom editor. From there:

  • Browse any table with pagination, type-aware coloring, sortable headers, per-column filters
  • Run arbitrary SQL from the Query tab with Ctrl/Cmd+Enter
  • Edit cells inline by double-clicking; Enter saves to memory, Cmd+S writes to disk
  • Undo and redo anything you ran in the SQL editor or edited inline — natively via VSCode’s edit stack
  • Export any table or query result to CSV or JSON
  • Read-only fallbacks for views, tables without a primary key, and BLOB columns — the UI gets out of your way when it can’t safely edit

The SQL editor has autocomplete — implemented in plain JS

I refused to pull in Monaco Editor because that’s another ~5 MB of code I’d ask you to trust. So the autocomplete is hand-rolled vanilla JS. About 250 lines. It scopes column suggestions to whatever tables your query already references.

SQL editor autocomplete suggesting columns after a WHERE clause

After FROM, JOIN, INTO, UPDATE it suggests tables. After SELECT, WHERE, AND, OR, ON, ,, ( and friends it suggests columns. Arrow keys navigate, Enter / Tab insert, Esc closes. Cmd+Enter runs the query — the popup never intercepts it.

It’s not Monaco. It doesn’t do alias resolution or syntax highlighting. That’s the point. You can read every line of it.

Query results don’t surprise you

Query results panel with row count, mutated indicator, and per-result tables

Anything that modifies data — INSERT, UPDATE, DELETE, or DDL — marks the document as modified and goes onto the undo stack. Nothing touches the disk until you press Cmd+S. Close without saving to throw away mutations.

What “audit-friendly” actually means

I want to be honest about what this label does and doesn’t promise, because it’s the most important claim I’m making.

It doesn’t mean invulnerable. Nothing is invulnerable.

It does mean every line of the runtime surface is short enough to read. Let me make that concrete:

  • TypeScript source (4 files): ~810 lines
  • Webview JS / CSS (viewer.js, viewer.css): ~1,460 lines
  • That’s the whole story. ~2,300 lines.
  • Plus the bundled sql-wasm.js glue (~46 KB of code wrapping the WASM blob)
  • Plus the sql-wasm.wasm binary — opaque, but compiled from public, well-reviewed SQLite source

You can read all of the JS and TS in an afternoon. The WASM blob is what it is, but it’s the SQLite the world has been using for decades.

I also paid for that minimalism in features. Things Atalaya does not have:

  • Schema visualization (coming, but only if I can do it without adding deps)
  • Multi-file workspace, query history, saved snippets
  • AI assistants, copilots, “smart suggestions”
  • Subscription, account, sync, anything cloud

This isn’t a “minimum viable product”. It’s a deliberately small tool with a specific posture.

The receipts

Don’t take my word. Verify it yourself:

git clone https://github.com/Marioloez/atalaya
cd atalaya
npm ci --ignore-scripts          # neutralize any postinstall hooks
npm ls --omit=dev --all          # show the production dep tree

That last command prints exactly two lines:

atalaya@<version>
└── sql.js@<version>

Then read src/sqlite/service.ts and src/editor/sqliteEditor.ts. They’re short. They do exactly what they look like they do.

And if you find something I missed — open an issue. The whole point of this is that finding things is supposed to be possible.

A small clarification about the dev install

There’s one caveat I want to surface, because anyone running npm install will see it immediately: my devDependencies tree pulls in @vscode/vsce (the marketplace packager), which transitively pulls keytar (a native module for credential storage). That keytar binary runs a postinstall script during npm install.

None of it ships in the .vsix. I verified by running unzip -l atalaya-*.vsix — only my own compiled code, sql-wasm.js, sql-wasm.wasm, README, LICENSE, CHANGELOG, and the icon. Zero @azure/*, zero keytar, zero native binaries.

But if you intend to clone and inspect the source, run npm ci --ignore-scripts to keep the install hermetic. I documented this in the README. The “audit-friendly” claim is about the shipped artifact, not about the build chain. Clarity matters more than marketing.

Install

code --install-extension marioloez.atalaya

Or search Atalaya in the VSCode Extensions view.

GitHub: github.com/Marioloez/atalaya
Marketplace: marketplace.visualstudio.com/items?itemName=marioloez.atalaya

Why this matters beyond Atalaya

I’m not trying to replace every SQLite viewer. Some people genuinely need the feature-rich ones, and that’s fine — it’s a tradeoff worth taking when the cost is acceptable to them.

But the default trust posture of “install the popular extension, accept the 300 transitive packages, move on” deserves more scrutiny than it currently gets in developer workflows. The cost of that trust is hidden right up until someone exploits it.

Build small. Show the receipts. Make verifying easy.

[TODO: close with a short personal line in your voice — what would you ask a reader to do next? “audit a single extension in your editor this week” / “let me know what you’d improve” / “tell me what other tools deserve a minimal-trust rewrite”. keep it one sentence.]

Built with sql.js, the VSCode Custom Editor API, and a refusal to add dependencies.

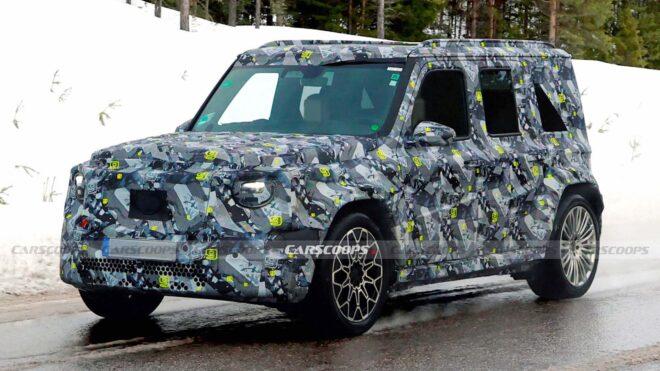
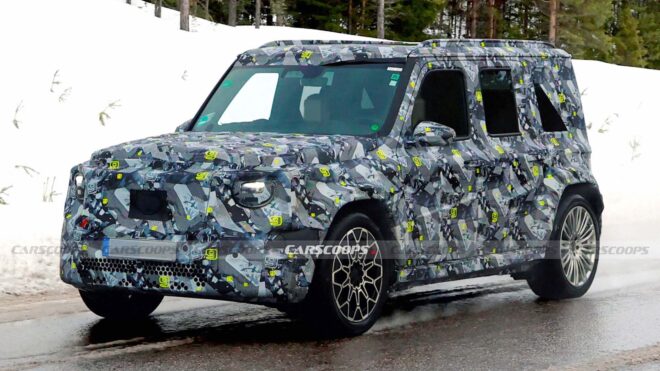
“Ufak” Mercedes-Benz G-Class, bayi talebi nedeniyle içten yanmalı motor kazanmış

Ufak Mercedes-Benz G-Class

Ufak Mercedes-Benz G-ClassGeliştirme çalışmaları uzun süredir devam eden küçük boyutlu Mercedes-Benz G-Class, bugün bir kez daha gündeme getirildiği kadarıyla hem elektrikli hem de hibrit olarak sunulacak. AMG’nin başındaki isim Michael Schiebe tarafından yapılan açıklamaya göre, bu önemli kararın arkasında ABD’deki bayilerin büyük talebi yer alıyor. Bayilerin elektriğe kıyasla çok daha yüksek satış potansiyeli bulunduğu için “mutlaka içten yanmalı motora sahip bir versiyonu da sunulmalı” dediği araç, CLA’da da kullanılan turbo destekli 1.5 litrelik dört silindirli hibrit üniteyi temel alabilir. İlk aşamada tamamen elektrikli olarak sunulması hedeflenen aracın, bu tarafta iki farklı elektrik motoru ve yaklaşık 724 km menzil sunacak 85 kWh kapasiteli NMC batarya ile donatılması bekleniyor. Resmi tanıtımının 2026 bitmeden yapılacağı, yollara ise 2027’de çıkarılacağı öne sürülen “Little G”, uzun süredir kamuflajlı olarak gerçek yol şartlarında test ediliyor.

“Ufak” Mercedes-Benz G-Class, bayi talebi nedeniyle içten yanmalı motor kazanmış yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.