Avatar: The Last Airbender’ın 2. sezonundan yeni fragman geldi
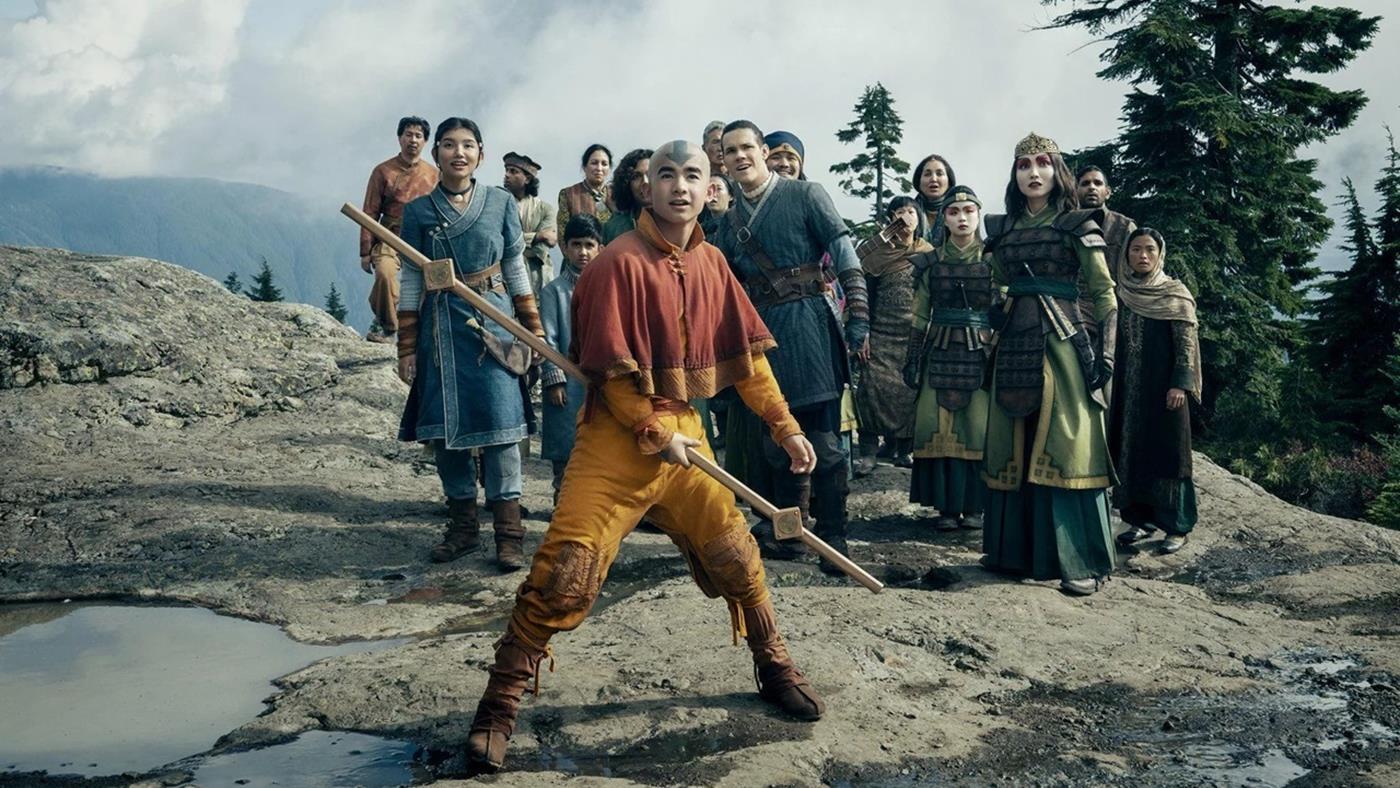
 Netflix’in canlı aksiyon (animasyon olmayan) Avatar: The Last Airbender dizisi 2. sezonuyla geri dönüyor. 25 Haziran’da yayınlanacak 2. sezondan yeni fragman paylaşıldı.

 Mert
Netflix’in canlı aksiyon (animasyon olmayan) Avatar: The Last Airbender dizisi 2. sezonuyla geri dönüyor. 25 Haziran’da yayınlanacak 2. sezondan yeni fragman paylaşıldı.
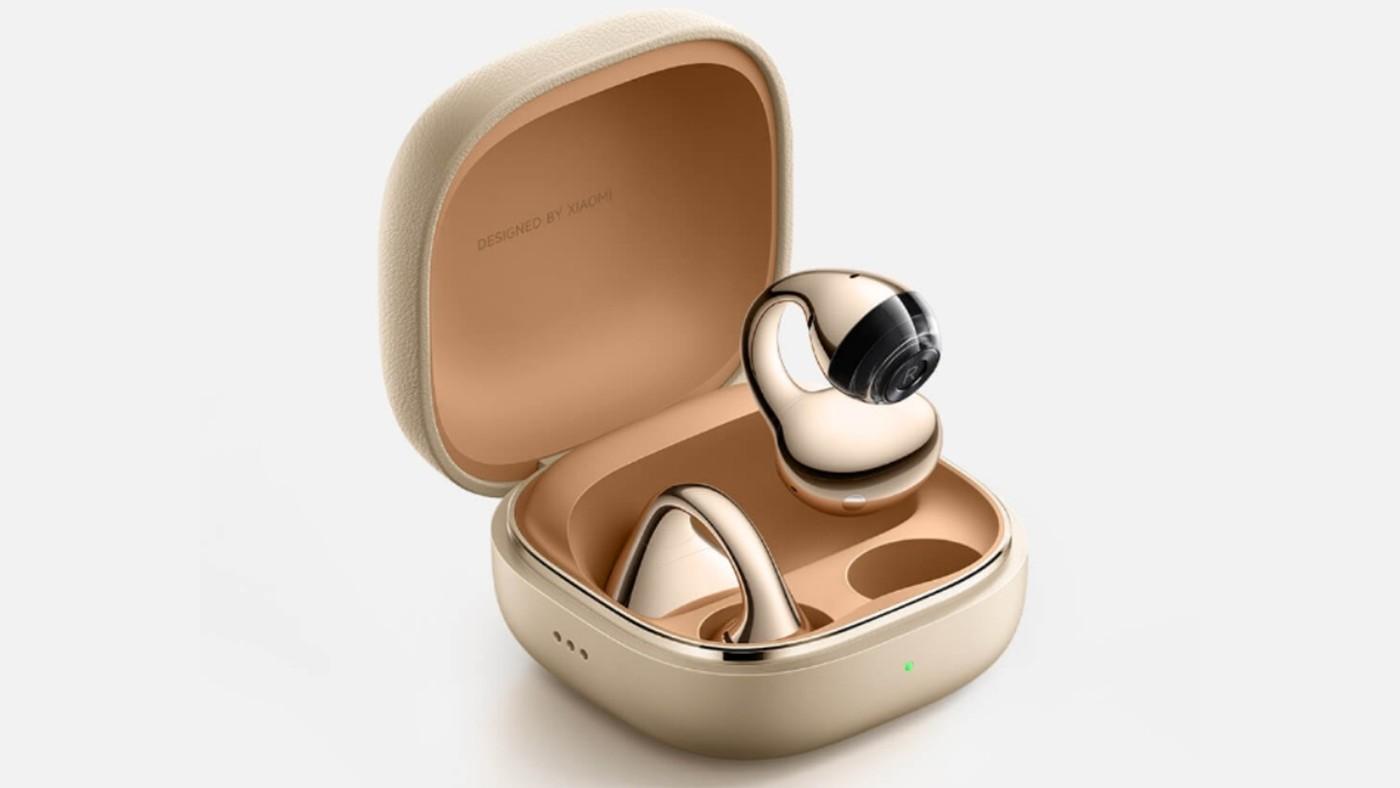
 Xiaomi, açık kulak yapılı ilk klipsli kulaklığını tanıttı. Şık tasarıma ve gelişmiş teknolojilere sahip kulaklığın fiyatı ve özellikleri neler?
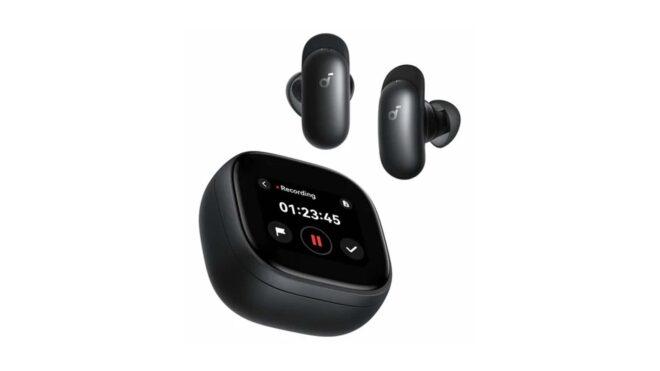
 Anker bugün özel “Thus” çipine sahip ilk ürünleri Soundcore Liberty 5 Pro ve Soundcore Liberty 5 Pro Max’i tanıttı. Yeni kablosuz kulaklıklarda özellikle şirketin kendi geliştirdiği yapay zeka odaklı Thus çipi dikkat çekiyor. Bu çip ile yeni nesil cihazlarına daha önce olmadığı seviyede lokal yapay zeka gücü katmayı hedefleyen şirket, çipte yüksek güç tüketimini önlemek için “compute-in-memory” mimarisinin kullanıldığını belirtiyor. Sekiz mikrofon ve iki kemik iletimli sensörü kontrol eden Thus sayesinde arka plan gürültüsü ile kişilerin sesini birbirinden etkili şekilde ayırarak, çok yüksek görüşme kalitesi ve Liberty 4 Pro’ya kıyasla 2 kat daha güçlü ANC (Aktif Gürültü Engelleme) performansı ortaya koyabildiği söylenen 170 dolarlık Soundcore Liberty 5 Pro ve 230 dolarlık Soundcore Liberty 5 Pro Max, şarj kutularında ortak olarak renkli dokunmatik ekranlar barındırıyor. Thus’un çok sayıda komutu destekleyen sesli kontrol altyapısına da güç verdiğini söyleyen Anker, kardeşinden daha büyük (1,78 inç AMOLED vs 0,96 inç TFT) ekranla gelen Soundcore […]
Anker, özel “Thus” çipine sahip ilk ürünleri Soundcore Liberty 5 Pro ve Soundcore Liberty 5 Pro Max’i tanıttı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Lorsque les entreprises introduisent des chatbots basés sur l’IA, la conversation commence rarement par les capacités du produit. Elle commence par une question sur laquelle les équipes juridiques travaillent depuis 2018 : qui est responsable du traitement des données et quelles sont exactement ses obligations.
La plupart des déploiements commencent dans le support client. C’est là que le retour sur investissement est le plus évident et que le volume de demandes répétitives rend l’automatisation facile à justifier. Mais au moment où un chatbot se connecte à un CRM ou accède à l’historique des tickets, quelque chose change. Il cesse d’être une simple fonctionnalité produit pour devenir un processeur de données, et cette requalification fait intervenir un tout autre ensemble d’acteurs. Les achats veulent savoir ce que prévoit le contrat. Les équipes juridiques veulent savoir où vont les données. Le délégué à la protection des données veut des réponses précises sur ces deux sujets, par écrit, avant toute mise en production.
Aucune de ces équipes ne travaille rapidement, et c’est normal.
Comprendre pourquoi cela se produit, et ce que cela implique pour les délais de déploiement et les choix de plateformes, est précisément l’objectif de cet article.
Pourquoi les chatbots GPT sont considérés comme des systèmes opérationnels
L’hypothèse la plus répandue est qu’un chatbot est un outil frontal. Il répond aux questions, réduit le volume des tickets et reste à la périphérie de l’expérience client. En pratique, il ne reste presque jamais à cet endroit.
Dès qu’un chatbot se connecte à des données clients en direct, historiques de commandes, dossiers de comptes, interactions précédentes, il devient une partie intégrante de la couche opérationnelle. Il lit, traite et parfois réécrit des informations dans les mêmes systèmes que ceux sur lesquels le reste de l’entreprise fonctionne. À partir de ce moment, la question n’est plus de savoir si l’outil fonctionne. La question devient : à quelles données a-t-il accès, que conserve-t-il, et qui est responsable si quelque chose tourne mal.
C’est ce changement qui surprend de nombreux projets. Une preuve de concept fonctionnant avec des données fictives ressemble à une fonctionnalité produit. Le même système connecté à des données de production se comporte comme une infrastructure, et il est traité comme telle. Le processus de validation interne change, les parties prenantes changent, et les délais évoluent avec elles.
Comment le RGPD influence chaque décision autour du déploiement de l’IA
La CNIL (Commission Nationale de l’Informatique et des Libertés) est l’autorité qui donne au RGPD son poids concret en France. En 2024, elle a infligé 55 millions d’euros d’amendes. En 2025, ce chiffre a atteint 486 millions d’euros, soit environ neuf fois plus. Le volume des sanctions est resté relativement stable. Les conséquences financières, elles, ont radicalement changé.
Pour les équipes juridiques en entreprise, cette trajectoire modifie considérablement l’évaluation du risque. Un chatbot qui gère des échanges clients n’est plus seulement une décision produit. C’est une question de responsabilité qui apparaît directement sur un bilan financier.
En juillet 2025, la CNIL a publié des recommandations détaillées sur l’application du RGPD au développement des modèles d’IA, couvrant la gestion des données d’entraînement, les exigences de sécurité et les cas dans lesquels un modèle déployé constitue un traitement de données personnelles. Les entreprises qui menaient jusque-là des pilotes dans une zone réglementaire floue se sont soudainement retrouvées face à un cadre formel.
L’AI Act européen ajoute une couche supplémentaire. Il est entré en vigueur en août 2024, avec l’application des interdictions concernant les systèmes d’IA à risque inacceptable dès février 2025 et les obligations complètes pour les systèmes à haut risque attendues pour août 2026. Un chatbot qui gère des demandes standard dans le commerce de détail sera probablement considéré comme à faible risque. En revanche, un système utilisé pour des décisions de crédit, des évaluations d’assurance ou du triage médical entre dans une catégorie totalement différente, avec des exigences beaucoup plus strictes en matière de documentation, de supervision humaine et de conformité.
Pour les entreprises des secteurs financier ou de la santé, la conformité signifie désormais naviguer simultanément entre le RGPD, l’AI Act et les réglementations sectorielles propres à leur industrie.
Ce que signifie réellement la “conformité” lorsqu’une IA est utilisée en production
L’expression « chatbot conforme au RGPD » apparaît dans presque tous les discours commerciaux des fournisseurs. Dans les achats en entreprise, elle a une signification beaucoup plus précise, et quatre éléments comptent réellement lorsqu’on l’évalue sérieusement.
Le premier est un accord de traitement des données signé (Data Processing Agreement ou DPA). Tout fournisseur agissant comme sous-traitant doit en disposer avant que des données de production ne transitent dans le système. C’est un prérequis fondamental, pourtant encore absent chez certaines plateformes intermédiaires, ce qui suffit à les exclure des appels d’offres d’entreprise, indépendamment de la qualité du produit.
Le deuxième point concerne la clarté sur la conservation des données. Les entreprises doivent savoir si les conversations sont stockées, pendant combien de temps, sur quelle base légale et selon quel processus elles sont supprimées. Un chatbot qui conserve indéfiniment les journaux de conversation pour améliorer son modèle sous-jacent traite les données au-delà de leur finalité initiale. Ce n’est pas un détail technique. C’est un problème direct de conformité.
Le troisième point concerne l’utilisation des conversations clients pour l’entraînement des modèles. C’est l’une des questions auxquelles les fournisseurs répondent le plus difficilement de manière claire. La plupart des équipes juridiques et DPO des grandes entreprises l’interdisent totalement et exigent une confirmation écrite avant de valider un déploiement.
Le quatrième point concerne les contrôles d’accès et la visibilité des audits. Si un régulateur demande quelles données le chatbot a consultées et à quel moment, la réponse ne peut pas être reconstruite après coup. Les journaux d’audit doivent faire partie intégrante de l’architecture dès le départ, structurés autour des permissions déjà définies par les équipes juridiques et conformité.
La résidence des données dans l’Union européenne sous-tend l’ensemble de ces sujets. Pour les plateformes hébergées aux États-Unis, le cadre légal qui a remplacé le Privacy Shield invalidé fournit un mécanisme de transfert, mais il reste entouré d’incertitudes politiques et de préoccupations persistantes concernant l’accès potentiel des autorités américaines aux données détenues par des entreprises américaines, même lorsque les serveurs sont physiquement situés en Europe.
Les organisations bancaires, de santé et du secteur public ont largement réagi en considérant l’hébergement européen comme une exigence non négociable plutôt qu’une préférence. Les fournisseurs proposant des déploiements sur site ou des infrastructures privées européennes ont trouvé une réelle traction commerciale dans les secteurs réglementés, car ils suppriment entièrement une catégorie de risque juridique au lieu de simplement la gérer.
Meilleures plateformes de chatbots GPT
Les décisions de plateformes en entreprise se jouent rarement sur les fonctionnalités. Elles se jouent sur la solidité de la documentation de conformité et sur la capacité du système à s’intégrer dans des workflows déjà existants.
1. Intercom

Intercom est une plateforme de messagerie client conçue pour les équipes commerciales, marketing et support. Elle propose du chat en direct, de la messagerie automatisée et un support assisté par IA via son système Fin AI, permettant aux équipes de gérer les conversations sur le chat et les applications avec automatisation du routage et des résolutions.
Idéal pour
Les équipes qui disposent déjà d’opérations de support structurées y trouveront une intégration de l’IA qui s’ajoute à leur organisation existante plutôt que de les forcer à tout reconstruire autour du produit.
2. YourGPT

YourGPT est une plateforme orientée IA conçue pour créer et déployer des agents capables de gérer le support client, les ventes et les workflows opérationnels sur les sites web, applications et canaux de messagerie sans nécessiter une infrastructure d’ingénierie complète. Son constructeur no-code et son AI Studio permettent de créer des agents basés sur des workflows capables d’exécuter des tâches en plusieurs étapes, avec des intégrations vers Shopify, WordPress, Webflow, Crisp, Intercom, Stripe et Zapier. La plateforme prend en charge le texte, l’image et l’audio, ce qui la rend adaptée à des interactions plus complexes que de simples échanges textuels.
Idéal pour
Les équipes de taille moyenne à grande qui ont besoin d’automatisations structurées pour le support, la qualification commerciale ou les workflows internes, tout en souhaitant avancer rapidement sans équipe de développement dédiée.
3. Zendesk

Zendesk est une plateforme de service client construite autour de la gestion des tickets, des workflows de support et du suivi des interactions. Elle fournit des outils de gestion des dossiers, de routage automatisé, d’exploitation du support et d’analyse, avec des fonctionnalités IA couvrant la classification des tickets, les réponses suggérées et l’automatisation des processus.
Idéal pour
Sa valeur apparaît surtout dans les organisations où le support dispose de ses propres lignes hiérarchiques, procédures d’escalade et objectifs de performance. Les petites équipes y verront souvent une plateforme plus lourde que nécessaire.
4. Ada

Ada est une plateforme d’automatisation du service client basée sur l’IA, conçue pour résoudre les demandes via des workflows conversationnels. Elle interprète les requêtes des clients, génère des réponses et guide les utilisateurs vers des parcours de résolution, avec la capacité d’accéder à des informations clients provenant des systèmes backend pendant la conversation.
Idéal pour
Les environnements de support à très fort volume où une grande partie des interactions est répétitive et où l’objectif est une automatisation de bout en bout sans transférer chaque demande à un humain.
5. Crisp

Crisp est une plateforme de messagerie client qui combine chat en direct, email, automatisation chatbot et fonctionnalités CRM légères. Elle permet aux équipes de gérer les communications sur plusieurs canaux avec automatisation des questions fréquentes et routage des conversations.
Idéal pour
Les petites équipes qui souhaitent réunir chat en direct, email et automatisation dans un seul outil sans payer pour une infrastructure pensée pour des entreprises dix fois plus grandes.
6. Tidio

Tidio est une plateforme de communication client combinant chat en direct, automatisation chatbot et réponses pilotées par IA pour les sites web et boutiques en ligne. Elle inclut des workflows conversationnels automatisés, le suivi des visiteurs et des intégrations e-commerce pour gérer les demandes et les interactions commerciales.
Idéal pour
Les boutiques en ligne qui cherchent à capter les clients au bon moment du parcours d’achat, ce qui en fait une solution plus adaptée au commerce électronique qu’aux équipes gérant des files de support complexes après-vente.
Comment évaluer les chatbots GPT avant une adoption en entreprise
Les évaluations qui commencent par comparer les fonctionnalités rencontrent souvent des problèmes plus tard. Les questions liées à la gestion des données, aux contrôles d’accès et aux responsabilités des fournisseurs devraient être posées avant même qu’une plateforme soit présélectionnée, et non après la signature du contrat.
Commencez par examiner la documentation du fournisseur sur le traitement des données. Avant toute chose, il faut comprendre où vont les données de conversation, combien de temps elles sont conservées, si elles servent à entraîner les modèles et comment fonctionne leur suppression. Si un fournisseur ne peut pas répondre précisément à ces questions, cette absence de réponse est déjà une réponse.
Vérifiez les limites d’intégration avant les tests. L’accès du chatbot aux systèmes internes, dossiers CRM, tickets de support et historiques clients doit être défini et limité avant toute utilisation de données de production. La capacité d’intégration et la gouvernance des intégrations sont deux choses différentes, et les fournisseurs sont généralement plus à l’aise pour démontrer la première que pour documenter la seconde.
Considérez le DPA comme un prérequis et non comme une étape finale.
Un accord de traitement des données signé devrait être en place avant que l’évaluation n’entre dans une phase proche de la production. Le négocier après les tests techniques crée une pression qui pousse souvent à accepter des conditions auxquelles les équipes juridiques se seraient opposées plus tôt.
Demandez l’architecture des journaux d’audit, pas simplement une liste de fonctionnalités. La question n’est pas de savoir si des logs existent, mais s’ils sont structurés de manière à répondre aux exigences de traçabilité et de contrôle d’accès définies par les équipes conformité. Cette différence devient cruciale lorsqu’un régulateur demande des justificatifs.
Limitez le premier déploiement à un périmètre restreint. Les entreprises qui réussissent leurs déploiements commencent généralement par un cas d’usage où les données sont clairement catégorisées, les périodes de conservation sont défendables et le périmètre est suffisamment étroit pour garder une traçabilité propre. L’expansion vient ensuite, à partir d’une base stable.
Conclusion
Les entreprises qui progressent réellement ne sont pas celles qui ont résolu toutes les questions de conformité. Ce sont celles qui ont défini suffisamment clairement ce que le chatbot peut et ne peut pas faire pour pouvoir opérer avec confiance dans ces limites.
Ce qui bloque souvent les déploiements, c’est le fait de traiter la conformité comme une simple checklist de lancement, puis de découvrir en plein projet que l’architecture des logs du fournisseur ne répond pas réellement aux besoins du juridique, ou que certaines données ont été manipulées d’une manière jamais précisée dans le contrat.
L’escalade des sanctions de la CNIL, passées de 55 millions à 486 millions d’euros en une seule année, n’est pas un simple contexte de fond. C’est l’environnement opérationnel dans lequel les entreprises évoluent désormais. Celles qui considèrent encore la conformité des chatbots comme une formalité d’achat prennent un risque qu’elles n’ont pas correctement évalué.
La technologie n’est plus l’incertitude principale. Ce qui reste encore en construction, c’est tout le cadre qui l’entoure, et se tromper sur cette partie aujourd’hui entraîne des conséquences qui n’existaient pas il y a deux ans.
Modern e-commerce platforms are no longer competing only on price or product variety. Today, customer experience and personalization have become major factors influencing conversion rates, customer retention, and long-term revenue growth. Businesses that can intelligently recommend products based on customer behavior are gaining significant competitive advantages in the digital marketplace.
Amazon Web Services (AWS) provides powerful cloud infrastructure and machine learning tools that allow companies to build scalable recommendation systems capable of analyzing user behavior in real time.
Understanding the Role of Recommendation Systems
Recommendation engines are intelligent systems designed to analyze customer activity and suggest products that align with user interests, browsing patterns, and purchasing history. These systems improve customer engagement by making product discovery easier and more personalized.
Companies such as Amazon Web Services have helped businesses build recommendation systems capable of processing massive volumes of customer interactions without compromising speed or reliability.
Using Amazon Kinesis for Real-Time Data Processing
Real-time customer behavior tracking is one of the most important parts of a recommendation system. Every click, search, purchase, and interaction generates valuable data that can help businesses understand customer preferences more effectively.
With Amazon Kinesis, organizations can process streaming customer data instantly, allowing recommendation systems to react to user behavior in real time.
For example, if a customer searches for smartphones repeatedly, the recommendation engine can immediately begin displaying related products such as phone accessories, smartwatches, and protective cases.
This improves:
Product visibility
Customer engagement
Sales conversion rates
User experience personalization
Building Machine Learning Models with Amazon SageMaker
Machine learning plays a major role in improving recommendation accuracy. Instead of relying only on simple product categories, AI models can analyze customer patterns deeply and identify relationships between products automatically.
Using Amazon SageMaker, developers can train machine learning models capable of predicting what customers are most likely to purchase based on historical behavior and behavioral trends.
These models continue improving over time as they process more customer interactions and transaction data.
Businesses benefit from:
Smarter recommendations
Improved customer retention
Higher average order values
Better user engagement
Leveraging AWS Lambda for Serverless Automation
Managing infrastructure manually can become expensive and difficult as applications scale. This is why many businesses are adopting serverless architectures for recommendation systems.
With AWS Lambda, businesses can automatically process events and customer interactions without managing servers directly.
Whenever users interact with products, Lambda functions can:
Trigger recommendation updates
Process behavioral events
Update databases
Send personalized notifications
This reduces operational overhead while improving scalability and performance.
Importance of Scalability in E-Commerce Platforms
E-commerce traffic can increase dramatically during sales events, festive seasons, and marketing campaigns. Traditional infrastructure often struggles to handle sudden spikes in demand, leading to downtime and poor customer experiences.
AWS cloud infrastructure helps businesses scale automatically based on user demand, ensuring stable performance even during periods of extremely high traffic.
Scalable cloud systems help businesses:
Prevent service interruptions
Improve application reliability
Reduce infrastructure costs
Maintain consistent customer experiences
The Future of Personalized Shopping
Recommendation systems are becoming a core part of modern e-commerce strategy. Businesses that successfully personalize user experiences are more likely to improve customer loyalty and long-term profitability.
As AI and cloud technologies continue evolving, recommendation systems will become even more intelligent, predictive, and deeply integrated into digital shopping experiences.
AWS continues providing the infrastructure and AI capabilities helping businesses build faster, smarter, and more personalized e-commerce platforms globally.

This is a submission for the GitHub Finish-Up-A-Thon Challenge
What I Built
I completed Qwertymates — a multi-functional digital platform designed to be the home for doers, sellers, and creators.
Live: https://www.qwertymates.com/wall
Qwertymates is more than just a marketplace. It’s a connected ecosystem that brings together:
🛒 QwertyHub – Buy from verified suppliers
🌍 QwertyWorld – Social interactions and discovery
🏪 MyStore – Personal storefront management
🚚 Errands – Service-based task execution
💳 ACBPayWallet – Wallet and payments
📺 QwertyTV – Media streaming
🎵 QwertyMusic – Audio experiences
💬 Morongwa – Communication and messaging
The vision is simple:
Build a platform where users don’t need multiple apps to live, work, trade, and create online.
Demo
🔗 Live Platform: https://www.qwertymates.com
📂 https://github.com/ArielMadisha/Qwertymates
Key Screens (from the build)
Landing Page
Clean product-focused design with messaging:
“The Digital Home for Doers, Sellers & Creators.”
Clear CTAs: Get Started, Register, Sign In
Authentication System
Modern login experience with username/email/phone support
Clean UI over a visual background for a polished feel
Marketplace Feed (Wall)
Product posts from stores (e.g., handbags listing with prices in ZAR)
Social + commerce blended into one experience
Sidebar navigation across ecosystem features
Real-time interaction options (view product, resell, etc.)
The Comeback Story
Before this challenge, Qwertymates was:
💤 Sitting incomplete despite having a powerful vision
🧩 Fragmented across multiple ideas without cohesion
🚧 Missing polish and key integration points
What I fixed and completed:
✅ Unified the platform into a single cohesive ecosystem
✅ Completed authentication and navigation flows
✅ Built a working marketplace + social feed experience
✅ Refined UI for a modern SaaS-level look and feel
✅ Improved structure across modules (Hub, Wallet, TV, Music, etc.)
✅ Polished the user journey from landing → login → interaction
The biggest shift:
Moving from “a collection of ideas” → “a usable platform people can actually explore.”
My Experience with GitHub Copilot


GitHub Copilot played a critical role in helping me finish Qwertymates:
⚡ Speed & Momentum
Copilot helped generate:
UI components
Form handling logic
Reusable structures across modules
This allowed me to focus on architecture and product vision, not repetitive coding.
🧠 Problem Solving
Whenever I hit blockers, Copilot:
Suggested fixes
Helped debug faster
Offered alternative implementations
🧹 Refactoring & Cleanup
Improved code readability
Helped standardize patterns across the platform
Reduced technical debt
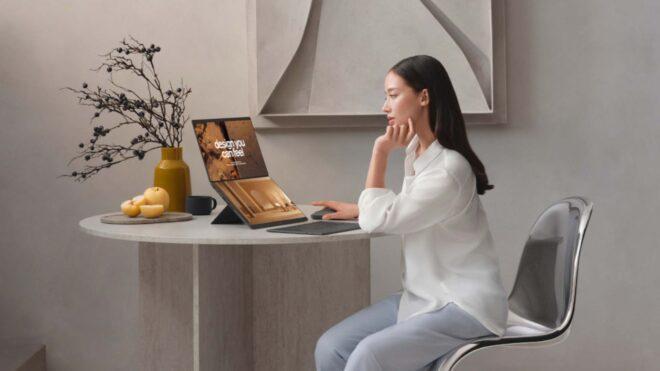
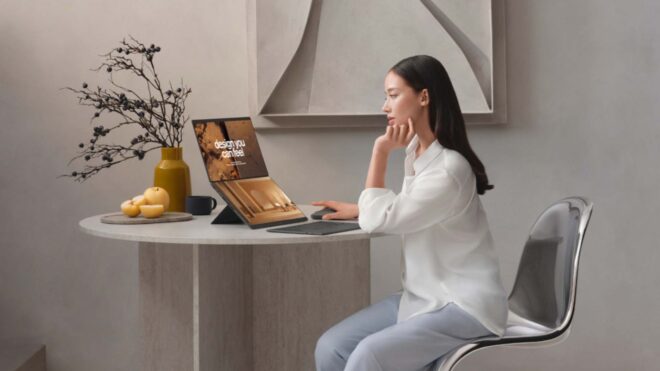 ASUS bugün yeni Zenbook DUO dizüstü bilgisayar modelinin 17 Haziran tarihinde Türkiye’de satışa çıkacağını duyurdu. 99 bin TL’den başlayacağı aktarılan hibrit dizüstü için yapılan resmi açıklamada, “2026 model Zenbook DUO’nun tasarım felsefesinin merkezinde dayanıklılık ve mobilite yatıyor. Cihaz, ASUS’a özgü bir inovasyon olan ve seramiğin sıcak dokunuşunu alüminyumun dayanıklılığıyla birleştiren tam boy Ceraluminum şasi ile geliyor. Önceki nesle göre %5 daha küçük bir kasaya sahip olan cihaz, seyahat halindeki profesyonellerin tüm ihtiyaçlarına yanıt veriyor. Yeniden tasarlanan entegre kickstand (destek ayağı) ve gizli menteşe yapısı, tüm kullanım modlarında sarsılmaz bir denge sunuyor. Cihazın güçlendirilmiş Bluetooth klavyesi, yeni MagLatch yerleştirme sistemi ve geri çekilebilir pogo pinleri sayesinde iki OLED panel arasına zahmetsizce ve güvenle yerleşiyor.” Zenbook DUO, akıllı güç mimarisiyle performansı dayanıklılıkla buluşturuyor. Cihazın kalbinde yer alan yeni nesil Intel Core Ultra X9 Serisi 3 işlemci, bilgi işlem ve grafik verimliliğinde büyük bir sıçrama yaratarak 180 TOPS’a kadar yapay zeka (AI) performansı […]
ASUS, yeni Zenbook DUO’yu Türkiye’de satışa çıkarıyor yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.
Most DevOps engagements don’t fail because of bad tooling. They fail because the wrong firm was chosen.
The pattern shows up the same way every time. An engineering leader signs a contract based on a polished proposal and an impressive client list. Six months later, the CI/CD pipeline is half-built, the team is dependent on an outside firm for every config change, and the internal engineers are no more capable than when they started.
Choosing a DevOps consulting partner is a consequential decision. The wrong one locks you into broken pipelines, stalled cloud migrations, and a knowledge gap that takes years to close. This article gives you a concrete framework for evaluating a partner before any contract is signed.
What DevOps Consulting Actually Covers
DevOps consulting is not a single service. It spans a wide range of work, and the differences matter when you’re evaluating who can actually help you.
Typical scope includes:
One distinction worth making early: DevOps consulting is not the same as DevOps staffing. A staffing firm places engineers in your org on a time-and-materials basis. A consulting firm is accountable to outcomes. If you’re hiring a firm to “do DevOps work,” you should be clear on which model you’re signing up for — because the contractual accountability is very different.
Also note that Azure DevOps and AWS DevOps are distinct ecosystems. A firm with deep AWS experience may have limited Azure expertise, and vice versa. Platform-specific depth matters more than generic cloud familiarity.
Why Partner Selection Fails
Before getting into evaluation criteria, it helps to understand what goes wrong. The failure modes are specific.
Choosing a generalist for a specialist problem. A firm with broad technology consulting experience may not have the depth to handle a Kubernetes migration or a GitOps implementation. General IT consulting and platform engineering require different skills. A firm that excels at project management and delivery governance is not automatically qualified to design your deployment architecture.
Evaluating on credentials, not execution history. Certifications — AWS Partner status, Microsoft Gold competency, various DevOps framework accreditations — tell you a firm met a threshold. They don’t tell you whether that firm has delivered a working pipeline at your scale, with your constraints, under real project pressure. Credentials screen for eligibility, not capability.
No clarity on what “done” looks like. Vague scope is the single most common reason DevOps engagements run over budget and under-deliver. If neither party can describe what a successful engagement produces in concrete, measurable terms before the SOW is signed, the engagement will expand indefinitely.
Ignoring team model fit. DevOps consulting firms operate in fundamentally different ways: embedded teams that work inside your organization, advisory engagements that design and supervise, and managed service models that run your infrastructure on an ongoing basis. Each has appropriate use cases. Choosing the wrong model for your situation is a problem no amount of technical skill will fix.
6 Questions to Ask Before You Sign
These are the questions that separate firms worth engaging from those that look the part.
1. What’s your delivery model?
Does the firm embed engineers in your team, operate in an advisory capacity, or run a managed service after implementation? The right answer depends on your goals. If you want your team to own the outcome, you need a firm that builds with you and transfers knowledge. If you need steady-state operations management, a managed service may be appropriate. The wrong answer is when the firm can’t articulate its model clearly, or shifts the answer based on what you seem to want to hear.
2. Can you show a comparable engagement?
Ask for a reference from an engagement that mirrors yours: similar stack, similar scale, similar industry constraints. A logo wall is not a reference. A 10-minute call with an engineering director who can tell you what the firm built, what it cost, and what went wrong is a reference. If the firm can’t provide that, treat it as a meaningful signal.
3. Who actually does the work?
Some DevOps consulting firms sell with senior engineers and deliver with junior subcontractors or offshore staff. Ask directly: who are the named engineers on this engagement, what are their backgrounds, and will they be consistent throughout the project? Firms with high staff turnover or opaque delivery structures tend to produce inconsistent work and difficult knowledge transfers.
4. How do you handle CI/CD pipeline ownership after handoff?
There are two fundamentally different approaches to delivery: build and leave, or build and enable. The first produces a pipeline your team can’t maintain without ongoing vendor involvement. The second produces a pipeline your team understands and owns. Ask what the firm’s standard knowledge transfer process looks like. If they don’t have a standard answer, plan accordingly.
5. What’s your depth on our specific cloud platform?
Ask specifically about AWS, Azure, or GCP — whichever is relevant to your environment. Ask about Azure DevOps pipelines, specific AWS DevOps tooling (CodePipeline, CodeBuild, ECS, EKS), or GCP-native tooling as appropriate. A firm that has delivered on your platform at scale will answer differently than one that has general cloud familiarity.
6. How do you measure success?
If the firm responds with vague language about “improved velocity” or “better collaboration,” ask them to be more specific. Mature DevOps consulting firms measure outcomes with DORA metrics: deployment frequency, lead time for changes, mean time to recovery (MTTR), and change failure rate. If the firm can’t talk about your current baseline and where you should be at the end of the engagement, they don’t have a clear definition of done.
What Strong DevOps Consulting Firms Actually Look Like
The difference between a strong partner and a weak one shows up in specifics, not in proposal quality.
| Area | Strong Partner | Weak Partner |
|---|---|---|
| References | Specific client outcomes with named contacts | Logo walls and case study PDFs |
| Toolchain stance | Opinionated, with clear rationale | “Tool-agnostic” with no actual recommendation |
| Delivery team | Named, consistent engineers from day one | Rotating cast after kickoff |
| Handoff plan | Documented from proposal stage | Treated as a future conversation |
| Platform depth | Certified with proof of delivery at scale | Certifications without real project history |
| Pricing model | Milestone-tied or outcome-based | Pure T&M with no accountability structure |
| Knowledge transfer | Embedded in the engagement design | An afterthought billed separately |
One signal worth singling out: a firm that says it’s “tool-agnostic” may be positioning to avoid difficult conversations. A firm with real experience has opinions. They’ve seen what works in specific contexts. “It depends” is a valid answer to architecture questions — but if a firm won’t tell you what it actually recommends and why, that’s a problem.
Enterprise vs. Mid-Market DevOps Consulting
Scale changes what you need from a partner, and not all firms serve both markets well.
Enterprise DevOps consulting typically involves compliance requirements, multi-cloud or hybrid environments, large change management programs, and governance structures that affect every decision. Firms that operate at this level tend to have dedicated practices around security, compliance automation, and scaled Agile frameworks.
Mid-market and growth-stage engineering teams usually need speed over process rigor. Over-engineering a pipeline for a 40-person team wastes time and budget. The right firm for this context moves quickly, avoids unnecessary abstraction, and builds something the team can actually own.
A firm that excels at Fortune 500 DevOps transformation may not be the right fit for a 50-person engineering team moving fast. The reverse is also true.
Ask the firm directly: what’s the smallest engagement you’ve run, and what’s the largest? The answer tells you where they’re most comfortable and where their processes are actually calibrated.
Red Flags to Watch Before the Contract Is Signed
Some problems announce themselves early if you know what to look for.
Questions to Ask on the Discovery Call
The discovery call is the fastest way to assess whether a firm has real experience or polished positioning. These questions expose the difference.
How do you structure a typical DevOps engagement?
A strong answer describes phased delivery with defined checkpoints: assessment, design, implementation, hardening, handoff. It names what gets delivered at each stage and what decisions the client makes. A weak answer describes a general process that could apply to any consulting engagement.
What does your knowledge transfer process look like?
Firms that have done this well have a standard answer. They can describe how documentation is created, how pairing works between their engineers and your team, and what “ready to own” looks like at handoff. Firms that haven’t solved for this will treat it as a customization question.
How do you handle disagreements on architecture or tooling decisions?
This question reveals whether the firm is genuinely advisory or just executing to spec. You want a firm that will push back when they see a problem, explain the tradeoff clearly, and defer to you once the decision is made. A firm that always agrees isn’t protecting your interests.
What’s your experience with our specific cloud platform?
Listen for specifics: named services, version-specific details, failure patterns they’ve seen, architectural decisions they’ve made under real constraints. Generic answers signal breadth without depth.
How to Structure the Evaluation Process
Once you’ve done the first round of outreach, a structured process protects you from selecting based on proposal quality rather than delivery capability.
Before You Sign
The right DevOps consulting partner is not the largest firm on the list or the one with the most certifications. It’s the one whose delivery model, team structure, and platform depth match what you’re actually trying to build — and who has proof of doing it before.
Evaluating a partner takes more deliberate effort than evaluating a tool. The cost of the wrong choice isn’t a canceled subscription. It’s six to eighteen months of rework, dependency, and lost momentum for your engineering team.
IT
InstaTunnel Team
Published by our engineering team
Zero-Install Tunneling in 2026: The Developer’s Complete Guide to Agentless Localhost Proxies
How a single SSH command replaces bloated CLI daemons — and what your InfoSec team needs to know about it.
The Problem: When Your Laptop Won’t Let You Install Anything
Modern corporate endpoints are locked down tighter than ever. Endpoint Detection and Response (EDR) platforms like CrowdStrike Falcon, SentinelOne, and Microsoft Defender for Endpoint actively flag and block the installation of unsigned or unrecognized binaries — including popular tunneling CLIs written in Go or Rust. Application whitelisting policies mean that even legitimate developer tools can be quarantined before they ever run.
For a developer trying to share a locally running React app for a quick stakeholder review, or expose a webhook endpoint to test a Stripe integration, this creates a frustrating paradox: the tools that would solve the problem are themselves blocked by policy.
The elegant workaround is already sitting on every developer’s machine, pre-approved by every IT department on the planet: OpenSSH.
What Is Agentless Localhost Tunneling?
Agentless tunneling (also called zero-install tunneling) refers to exposing a local port to the public internet using nothing more than the native SSH client already bundled with your operating system — no downloaded binary, no npm package, no elevated install permissions required.
The technique relies on SSH’s Remote Port Forwarding (-R) flag, which instructs a remote server to accept public traffic and relay it down an encrypted SSH tunnel to a port on your local machine. The remote relay server acts as the public-facing endpoint; your laptop acts as the hidden origin.
The architecture looks like this:
[ Public Internet User ]
│
▼ (HTTPS Request)
Relay Server
│
│ SSH Reverse Tunnel (Port 443)
▼
Your Laptop
│
▼ (Internal Routing)
Local App
Dissecting the One-Liner
Here is a typical zero-install tunnel command:
ssh -p 443 -R0:localhost:3000 [email protected]
Each flag does something specific:
ssh — Invokes the native OpenSSH binary. No download needed; it ships with macOS, every major Linux distro, and Windows 10⁄11.
-p 443 — Connects over port 443 instead of the default SSH port 22. This is a deliberate engineering choice: corporate firewalls almost universally allow outbound HTTPS traffic on 443, whereas port 22 is frequently blocked for workstations. The SSH handshake rides through the same channel as normal web traffic.
-R — Activates Remote Port Forwarding. This tells the remote server to open a port and forward traffic back to you.
0:localhost:3000 — The 0 asks the relay to dynamically assign an available public port or subdomain. localhost:3000 tells the relay where to send that traffic on your machine.
[email protected] — The relay server’s address, with free as the username prefix (Pinggy uses this field for parameter injection, explained later).
On execution, the relay server issues an autogenerated public URL — something like https://rkyxl-12-34-56.a.pinggy.link — printed directly to your terminal and ready to share.
Why Port 443 Is the Critical Trick
Most enterprise firewalls are configured to block outbound port 22 from developer workstations to prevent unauthorized remote management. Port 443 is reserved for HTTPS web traffic and is almost always open — blocking it would break normal web browsing for the entire organization.
By running SSH over 443, the tunnel’s initial handshake is indistinguishable from a standard TLS connection to a web server. Deep Packet Inspection (DPI) appliances see it as high-volume encrypted HTTPS traffic. As noted in security research from JUMPSEC Labs, many corporate environments still allow outbound SSH even when they believe they don’t, because monitoring SSH as a “living off the land” binary (LOLBIN) is not standard practice for blue teams focused on malware detection.
Important note for security teams: This dual-use nature is covered in detail in the Security section below.
The Leading Agentless Tunneling Platforms in 2026
Because every user runs the same standard SSH binary, differentiation between zero-install services lies entirely in the relay server’s capabilities. Here are the platforms worth knowing:
Key capabilities: – Protocol support for HTTP, HTTPS, TCP, and UDP (UDP tunneling is something neither ngrok nor Localtunnel offer) – A built-in web debugger accessible at http://localhost:4300 when combined with a local port forward (-L 4300:localhost:4300), allowing inspection of HTTP headers, payloads, and request replay – Advanced traffic control injected through the SSH username string (authentication, IP whitelisting, CORS overrides, custom headers — all without touching a config file) – Free tier sessions cut off after 60 minutes; paid tiers start at $3/month for persistent tunnels
Confirmed working (as of March 2026 testing by the NousResearch Hermes Agent team): a single SSH command produces both HTTP and HTTPS public URLs instantly, with free Let’s Encrypt certificates, no account required.
Performance caveat: In a 100 MB file transfer benchmark conducted by LocalCan in 2025, Pinggy delivered approximately 1.10 MB/sec (8.81 Mbps), which was the slowest among tools tested. This is largely a consequence of the TCP-over-TCP problem inherent to SSH-based tunneling: both the inner application TCP layer and the outer SSH tunnel perform their own congestion control, and a single lost packet on the outer layer can stall the inner connection. For webhook testing and UI sharing this is rarely an issue; for large file transfer scenarios, it matters.
ssh -R 80:localhost:3000 [email protected]
The server returns a clean HTTPS link and stays quietly in the background — ideal for automated bash scripts, CI/CD pipeline validations, and situations where terminal real estate must be preserved. It supports HTTP and HTTPS only (no TCP or UDP), and works on any OS with SSH available. No account is required to start tunneling immediately.
ssh -R mysubdomain:80:localhost:5000 serveo.net
If the subdomain is available, the server binds it immediately. This is useful for persistent webhook URLs during development. As a community-supported free resource, availability can fluctuate under load compared to commercial infrastructure — worth keeping in mind for anything time-sensitive.
As of January 2026, Localtonet is priced at $2 per tunnel per month and offers multi-region redundancy, UDP support, SSO integration, and 99.9% uptime — making it the most complete option for teams needing more than a quick demo URL.
How These Compare to Traditional Tools
Feature Pinggy localhost.run Serveo ngrok Cloudflare Tunnel
Installation Required None (SSH) None (SSH) None (SSH) CLI binary cloudflared daemon
Protocol Support HTTP, HTTPS, TCP, UDP HTTP, HTTPS HTTP, HTTPS, TCP HTTP, HTTPS, TCP HTTP, HTTPS, gRPC
Terminal Dashboard Yes (interactive TUI) No (text only) No (text only) Yes (custom CLI) No (cloud console)
Web UI Inspector Yes (via local port) No No Yes (localhost port) Yes (cloud console)
Custom Domains Paid tiers Paid tiers Yes (if available) Paid tiers Yes (free via DNS)
Free Tier Limit 60 min sessions Unlimited Unlimited 1 GB/month Unlimited bandwidth
UDP Support Yes No No No No
Throughput (100 MB test) ~1.10 MB/s Not benchmarked Not benchmarked ~0.84 MB/s ~3.47 MB/s
ngrok pricing as of early 2026: Free tier (1 GB/month, random domains, session interstitial warning), Personal at $8/month (5 GB, 1 persistent domain), Pro at $20/month (15 GB, edge config, load balancing). Cloudflare Tunnel remains entirely free for HTTP/HTTPS with no bandwidth cap, making it exceptional value for teams already in the Cloudflare ecosystem — though it requires installing the cloudflared daemon.
Advanced Features Without a Client: Parameter Injection via SSH Username
A common misconception is that going agentless means losing access to advanced features like authentication, header manipulation, and CORS control. Pinggy’s engineering team solved this by using a feature of the SSH protocol that most developers overlook: the SSH username field can carry arbitrary strings.
Since the SSH connection protocol allows any string as the username, Pinggy parses this string on their edge nodes to dynamically apply traffic configurations before packets enter the tunnel. You pass your parameters by separating them with +.
Basic Authentication
Lock a public URL behind username/password credentials — useful when exposing internal tools to external stakeholders:
ssh -p 443 -R0:localhost:3000 “b:admin:[email protected]“
Pinggy’s edge intercepts incoming requests and issues a standard HTTP Basic Auth browser prompt. Your local server never receives an unauthenticated request.
IP Whitelisting (CIDR)
Restrict access to a specific IP range — e.g., your company’s VPN egress IP:
ssh -p 443 -R0:localhost:3000 “w:192.0.2.0/[email protected]“
Custom HTTP Header Injection
Useful for simulating specific environments, bypassing API gateway checks, or validating webhook signatures:
ssh -p 443 -R0:localhost:3000 “a:X-Environment:[email protected]“
Global CORS Override
When testing microservices across different origins and cross-origin blocking is halting frontend execution:
ssh -p 443 -R0:localhost:3000 “[email protected]“
Parameters can be chained. A tunnel with basic auth, CORS enabled, and a custom header looks like:
ssh -p 443 -R0:localhost:3000 “b:admin:pass+co+a:X-Environment:[email protected]“
This moves complex routing and security logic onto edge servers, controlled entirely through string parsing in the SSH handshake.
Dealing with Restrictive Proxies
If your network blocks outbound port 443 as well, or requires all traffic to route through an HTTP proxy, Pinggy documents a workaround using ncat and openssl:
ssh -p 443 -R0:localhost:4000
-o ProxyCommand=”ncat –proxy-type http –proxy 192.168.2.2:3128 %h %p”
a.pinggy.io
This routes the SSH tunnel through your corporate HTTP proxy, making it viable even in environments with aggressive outbound filtering.
The Security Perspective: What InfoSec Teams Need to Know
Zero-install tunneling is fundamentally dual-use. The same properties that make it frictionless for developers — encrypted traffic over 443, no binary to flag, no install events to log — make it a viable data exfiltration vector if misused or exploited.
What developers gain
From a data-in-transit standpoint, agentless proxies are genuinely secure. The link between the developer’s machine and the relay server is wrapped in SSH encryption (AES-GCM or ChaCha20-Poly1305). Traffic on the public side travels over standard HTTPS to the provider’s edge, where it is decrypted and re-encrypted via SSH before arriving on the local machine. On open or compromised local networks — coffee shop Wi-Fi, conference hotel networks — corporate code payloads cannot be sniffed or intercepted.
What security teams should monitor
Because the traffic rides inside an encrypted SSH wrapper over port 443, traditional DPI appliances classify it as generic HTTPS traffic. There is no binary installation event, no registry modification, no process with an unusual name. The only signal is an outbound SSH connection to an unfamiliar domain.
Practical governance approaches that forward-looking security teams are adopting:
Relay Infrastructure Whitelisting. Rather than attempting to block all SSH tunneling (which risks blocking legitimate uses), enterprises partner with commercial zero-install providers like Pinggy Pro or Localtonet Enterprise. The organization configures a dedicated custom domain (e.g., *.tunnels.company.com) and whitelists the static IP spaces of those specific relay nodes at the firewall. Unauthorized relay providers are blocked by default.
SSH Key Enforcement. Security teams require that any SSH tunnel initiated from a corporate asset must authenticate using an authorized corporate SSH key pair tied to an employee’s Identity Provider (IdP) account. This ensures complete auditability: which account opened the tunnel, when it opened, and how much bandwidth was transferred.
Embracing Ephemeral Lifespans. Pinggy’s free tier enforces automatic 60-minute session cutoffs. InfoSec teams can adopt this as a feature rather than a limitation, establishing policy that tunnels are ephemeral assets — spun up on demand for a specific debugging task, torn down immediately after. This minimizes the attack surface available to internet scanners and persistent threat actors.
Behavioral Detection. Security tools like Zeek and modern EDR platforms with SSH behavioral rules can be configured to alert on unusual port-forwarding patterns — for example, a workstation establishing an -R type forward to an external host, or sustained high-bandwidth SSH sessions to non-corporate domains. This is a more sustainable detection strategy than trying to block SSH entirely.
When to Use What: A Decision Framework
Use Pinggy if: You need something running in under 30 seconds with zero installs, want a request inspector, need UDP support, or want to share a QR code for mobile testing.
Use localhost.run if: You’re scripting automation, running CI/CD validation, or need a quiet background process with no terminal dashboard overhead.
Use Serveo if: You need a memorable, persistent subdomain during a specific development sprint and can tolerate occasional availability hiccups.
Use Localtonet if: You’re on a team, need multi-region reliability, SSO integration, or UDP support with a proper SLA.
Use Cloudflare Tunnel if: You’re already in the Cloudflare ecosystem, need production-grade reliability, HTTP/HTTPS bandwidth is unlimited, and you don’t mind installing cloudflared. It delivered 3.47 MB/s in throughput benchmarks — the fastest of any hosted tunnel option tested in 2025.
Use ngrok if: You need the broadest ecosystem of integrations and are willing to pay for persistence and volume. Its throughput benchmark of 0.84 MB/s makes it the slowest of the major options despite being the most widely recognized.
Conclusion
The case for zero-install tunneling in 2026 is not merely about convenience — it’s about working with the security architecture enterprises have built rather than constantly fighting against it. A native SSH binary is pre-trusted. It generates no install events. It requires no elevated permissions. And when tunneled over port 443, it passes through corporate egress filters without friction.
The platforms built on top of this model — Pinggy, localhost.run, Serveo, Localtonet — have reached a level of maturity where they genuinely match or exceed the developer-facing features of traditional CLI clients. The addition of parameter injection for auth, CORS, and header manipulation means that the username string in a single SSH command can replicate what previously required a full configuration file and a running daemon.
For InfoSec and NetOps teams, the right response is not to block SSH (which introduces more problems than it solves) but to structure governance around approved relay infrastructure, key-based authentication auditing, and behavioral detection. The tools exist; the frameworks are evolving.
For the developer navigating a locked-down endpoint: stop fighting installer permissions. The most powerful tunneling client you need is already on your machine.
ssh -p 443 -R0:localhost:3000 [email protected]
That’s it.
Last updated: May 2026. Pricing and feature details for Pinggy, ngrok, Cloudflare Tunnel, and Localtonet verified against current documentation and third-party benchmarks.
Related Topics
zero-install tunneling, agentless localhost proxy, Pinggy SSH tunnel alternatives, localhost.run configuration, SSH reverse tunnels, native SSH client proxy, enterprise security compliance, bypassing corporate IT restrictions, no-binary tunneling, browser-based local testing, secure port forwarding, ssh remote port forwarding, exposing localhost safely, developer infrastructure 2026, shadow IT mitigation, ngrok alternative ssh, serveo alternatives, cloudflared vs agentless, secure localhost ingress, native macOS ssh tunnel, native linux reverse proxy, zero-trust ssh gateway, corporate laptop security, developer productivity tools, endpoint protection compliance, command-line port forwarding, remote access without binaries, enterprise-safe localhost sharing, ssh port map, light-weight reverse proxy, automated webhooks local testing, public URL native SSH, secure tunneling for developers, agentless infrastructure 2026, web development tools, proxying without install, bypassing software blocks, devops port forwarding, cloud-to-local agentless bridge, public entrypoint via SSH
The site was “up.” The monitor said so. HTTP 200, response times normal, no alerts.
What the monitor didn’t know – what I didn’t know – was that our SSL certificate had expired 87 minutes earlier and every user hitting the site was getting a certificate error in their browser. Not a down page. Not a 5xx. A cert error. The kind where browsers show a big red warning screen and most users immediately close the tab.
For a checkout flow, that’s about as bad as the server being down. Worse, actually, because at least a down server triggers your uptime alert.
This is the post-mortem.
What happened
We were running Let’s Encrypt with certbot and auto-renewal configured. The renewal was supposed to happen when the cert had 30 days left. It had been working fine for about 18 months.
Then it didn’t.
The renewal job ran, hit a DNS validation error – our DNS provider had a 30-minute API hiccup that day – and failed silently. Certbot logged the failure, but nobody was watching certbot logs. The retry ran 12 hours later, same issue. Then it was fine. But by then, the “success” window had passed and the cert expired before the next attempt.
Let’s Encrypt auto-renewal fails for reasons that feel random at the time:
In our case it was DNS validation timing plus a log nobody was watching. The cert expired at 3:14 PM. The Slack alert – from a user, not a monitor – came in at 4:58 PM.
Why my uptime monitor missed it for four hours
GrabDiff monitors SSL expiry now, which is part of why I built it. But at the time I was using a basic HTTP ping monitor. Here’s what it was doing:
The problem is step 1. The monitor was connecting via HTTP (port 80) and following the redirect to HTTPS. The redirect itself returned 301, healthy. Then the HTTPS request… also returned 200?
Sort of. The monitor wasn’t validating the SSL certificate. It was making the HTTPS request with cert verification disabled, because false positives from cert issues in test environments made that the default in a lot of ping monitoring setups. So it dutifully checked the response code, got a 200 (from behind the expired cert that browsers were rejecting), and marked everything green.
Four hours of “everything is fine.”
What proper SSL monitoring actually checks
SSL expiry monitoring should check a few distinct things:
1. Certificate expiry date – the obvious one. Get the cert’s Not After field and alert at configurable thresholds. I alert at 30 days and 7 days. If you’re using Let’s Encrypt with 90-day certs, a 30-day warning gives you two full renewal windows to fix it.
2. Full-chain validation – not just that a cert exists, but that the entire chain from your cert to the root CA is valid. Intermediate cert issues cause browser errors even when your cert itself hasn’t expired.
3. Cert actually served matches expected domain – if something went wrong with your load balancer config and it’s serving the cert for a different domain, that’s a browser error even with a valid cert.
4. Port 443 is actually accepting connections – a “port not open” situation is different from “cert expired” but both cause the same user-facing result.
5. The cert returned matches what’s on disk – this catches the case where renewal succeeded but the service didn’t reload and is still serving the old, expired cert.
A ping monitor does none of these. A lot of “SSL monitoring” tools only do #1, which misses the cases that actually catch you off guard.
What I’d do differently
Monitor the cert directly, not via HTTP. Connect to port 443, do the TLS handshake, and inspect the cert that’s actually being served. Don’t just check the expiry date – validate the chain.
Set alert thresholds that give you time to fix things manually. Let’s Encrypt certs renew at 30 days remaining. I alert at 30 days (something’s wrong with auto-renewal) and 7 days (it’s still not fixed and now it’s urgent). That gives me 23 days between “something’s wrong” and “now panic.”
Watch the renewal logs. Not the SSL cert itself, but the renewal process. Set up a heartbeat – certbot’s --deploy-hook can ping a monitoring URL on successful renewal. If the heartbeat doesn’t arrive within period + grace, alert. This catches the “cert renewed but didn’t reload” case too.
Test your renewal before it matters. certbot renew --dry-run in your staging environment, regularly. Not just once when you set it up.
The monitoring stack I run now
For SSL specifically: I use GrabDiff for the cert expiry checks – it connects directly to port 443, validates the full chain, and alerts at 30 days and 7 days with enough context to know what’s actually wrong (expiry date, issuer, which check failed).
For the renewal heartbeat: I have certbot’s --deploy-hook send a ping to a GrabDiff heartbeat monitor after each successful renewal. If it doesn’t ping within 93 days (the Let’s Encrypt cert lifetime plus a week), I get alerted. That catches the silent renewal failures before they become a problem.
The six-hour checkout outage cost us – I’d rather not quantify it. The monitoring stack that would have caught it costs $9/month. That math is not complicated.
The broader lesson
SSL expiry is one of the most embarrassing categories of outage because it’s entirely predictable. You know the cert will expire. You have the date. The only question is whether you catch it before your users do.
The same is true for domain expiry, for that matter. I’ve seen teams let their primary domain expire because the renewal email went to a former employee’s address and nobody caught it. The monitoring there is trivial – check the WHOIS expiry date, alert 60 days out. But people don’t do it until they have to learn the hard way.
If your current monitoring setup would have missed the scenario I described above – HTTP 200 from an expired-cert server – it’s worth spending 20 minutes fixing that before you have your own version of this post-mortem to write.
I wrote this mostly to stop myself from having to explain this incident verbally ever again. Now I can just link it.
But seriously – SSL expiry outages are embarrassing in a specific way because they’re so avoidable, and I’ve seen them happen to teams that clearly knew what they were doing otherwise. If you’ve had your own cert-expiry story (or a renewal failure that was weirder than mine), I’d like to hear it in the comments. Knowing the failure modes other people have hit is the only way to build a monitoring checklist that actually covers the real world.