
My side project gets most of its traffic from ChatGPT, not Google. Here is the schema work behind it.

My side project gets most of its traffic from ChatGPT, not Google. Here is the schema work behind it.

A few weeks ago I opened Google Analytics for a passport-photo tool I build and maintain, and the traffic-source breakdown stopped me:

  • chatgpt.com — 65% of sessions
  • google / organic — about 6%
  • direct — the rest

Then I checked Bing Webmaster Tools, which has a new “AI Performance” tab, and saw the site had picked up 45 citations from Microsoft Copilot over three months.

The site is barely three months old. It has almost no backlinks. On Google it ranks on page 3-5 for anything competitive. And yet AI answer engines were sending it the bulk of its visitors.

This post is the honest engineering breakdown of what I did to make the site machine-citeable — what I think worked, what I cannot attribute, and the code. It is a Next.js App Router project, but the techniques are framework-agnostic.

Why this happens at all

AI answer engines (ChatGPT search, Perplexity, Copilot, Gemini) do not rank ten blue links. They synthesise an answer and cite a few sources. For a new site this is a genuinely different game from classic SEO:

  • Classic SEO: you need domain authority and backlinks to rank. That takes 6-12 months minimum for a new domain.
  • AI citation: the engine needs a page that clearly and verifiably answers the user’s question, is crawlable, and is structured so the answer is easy to extract. Domain age matters far less.

A three-month-old site cannot outrank an established competitor on Google. But it absolutely can be the cleanest, most extractable answer to a specific question — and that is what gets cited.

What I shipped

1. llms.txt

There is an emerging convention, llmstxt.org, for a plain-text file at /llms.txt that gives AI systems a curated, readable summary of your site — what it is, key pages, key facts, citation guidance. It is the robots.txt idea applied to LLMs.

Mine includes the brand entity, the canonical fact list, the most important pages, the audience, and a short “how to cite this” section. It costs nothing to maintain and it is the single most direct way to hand an AI engine a clean model of your site.

2. Schema.org structured data — the parts that matter

Not all schema is equal for AI extraction. The types that earned their place:

  • FAQPage with Question / acceptedAnswer pairs. Every Q&A is a discrete, extractable answer. I put one on the homepage and a big one on a dedicated facts page.
  • Question as mainEntity on individual pages — the page declares the one question it primarily answers, with the answer attached. This is the cleanest possible signal: “this page answers exactly this.”
  • Dataset (Schema.org) on the page documenting my public data API. Google Dataset Search and AI engines treat Dataset JSON-LD as a citation-worthy source.
  • SpeakableSpecification — marks which parts of the page are suitable for text-to-speech, used by voice assistants.
// Per-page primary question — the cleanest "this page answers X" signal
const pageSchema = {
  '@context': 'https://schema.org',
  '@type': 'WebPage',
  url: pageUrl,
  mainEntity: {
    '@type': 'Question',
    name: `What is the photo specification for ${country} ${doc}?`,
    acceptedAnswer: {
      '@type': 'Answer',
      text: factualAnswerAssembledFromStructuredData,
      url: pageUrl,
    },
  },
}

3. A canonical facts page

I built a /facts page: ~45 question/answer pairs, each grounded in an official government source, each rendered as real HTML with FAQPage JSON-LD and inline microdata (itemScope / itemProp). The first sentence of every answer is the direct answer — no preamble. AI engines extract the first authoritative sentence; give it to them cleanly.

4. Open data with a real endpoint

The dataset behind the tool is published two ways: an MIT-licensed GitHub repo, and a live JSON-LD API endpoint that returns a Schema.org Dataset. When an AI engine wants to verify a claim about coverage, there is a machine-readable source to point at. Being verifiable is itself a citation signal.

5. Server-side rendering — non-negotiable

If your content only exists after client-side JavaScript runs, many crawlers will not see it. Everything that matters — the schema blocks, the FAQ text, the tables — is in the server-rendered HTML. Quick check:

curl -s https://yoursite.com/ | grep -c "the answer text you expect"

If that returns 0, AI crawlers see an empty page.

6. Tables, not prose, for structured facts

This one is underrated, especially for Perplexity. If you have comparison data — sizes, prices, specs — render it as a real HTML <table>. AI engines lift tables into answers almost verbatim. A paragraph describing the same data is much harder for them to use.

7. robots.txt — explicitly allow the AI crawlers

GPTBot, OAI-SearchBot, PerplexityBot, ClaudeBot, Google-Extended, CCBot, Bingbot and others. If you want AI citations, do not block the bots that produce them. I also added a tiny middleware that tags each AI-bot request, so I can see in logs which engines actually crawl and how often.

// middleware.ts — detect and log AI crawler hits
const AI_BOTS = [/GPTBot/i, /PerplexityBot/i, /ClaudeBot/i, /OAI-SearchBot/i, /Google-Extended/i]
const ua = request.headers.get('user-agent') ?? ''
if (AI_BOTS.some((re) => re.test(ua))) {
  console.log(JSON.stringify({ event: 'ai_bot_crawl', ua, path: request.nextUrl.pathname }))
}

8. IndexNow — push, do not wait

ChatGPT search and Copilot lean on the Bing index. IndexNow lets you push new and changed URLs to Bing the moment you deploy, instead of waiting for a crawl. One POST per deploy.

What I cannot honestly claim

I cannot prove causation for any single technique. I shipped these together over a few weeks; traffic rose over the same period. It is correlation. What I can say:

  • The AI-citation traffic is real and measurable (GA4 source = chatgpt.com, Bing AI Performance citation count).
  • The pages AI actually cites are the most structured ones: the homepage, a tool-feature page, and timely explainer posts about recent regulation changes.
  • Domain authority did not drive this — the domain has almost none.

Takeaways

If you have a small or new site and want AI engines to send you traffic:

  1. Add llms.txt. Lowest effort, highest signal density.
  2. Use FAQPage and per-page mainEntity Question schema. Make every page declare what it answers.
  3. Server-render everything that matters. Verify with curl.
  4. Render structured facts as HTML tables.
  5. Lead every answer with the direct answer in sentence one.
  6. Allow the AI crawlers in robots.txt; push updates with IndexNow.
  7. Publish verifiable primary data if you have any.

None of this requires domain authority or a backlink budget. It requires being the clearest, most machine-readable answer to a real question. For a new site, that is a far more winnable game than classic SEO.

I build IDPhotoSnap, a free browser-only passport photo tool. The country-spec dataset is open at github.com/whitetirocket/passport-photo-specs. Happy to answer questions about the schema setup in the comments.
Comment simuler une API pour les tests: Guide pratique

Les tests qui dépendent d’une API réelle échouent souvent pour de mauvaises raisons : serveur de staging indisponible, limite de débit atteinte, donnée modifiée par un collègue, latence réseau. La simulation d’API supprime cette fragilité : vous remplacez l’endpoint réel par un substitut contrôlé qui renvoie la réponse attendue, de manière répétable.

Essayez Apidog aujourd’hui

Ce guide montre comment simuler une API pour vos tests : définir un schéma, générer des réponses mockées, exposer un serveur de simulation, configurer vos tests pour l’utiliser, puis couvrir les erreurs difficiles à déclencher sur un serveur réel. Les exemples utilisent une API de commandes avec GET /orders/{id}, mais la méthode s’applique à toute API REST ou GraphQL.

Quand utiliser la simulation d’API

Simulez l’API lorsque vous voulez tester votre code, pas le réseau.

Cas typiques :

  • tests unitaires ;
  • tests d’intégration ;
  • parsing de réponses 200 ;
  • gestion des 404 ;
  • logique de retry sur 503 ;
  • timeout côté client ;
  • fallback UI ou métier.

Gardez l’API réelle pour :

  • les tests de contrat ;
  • quelques tests end-to-end ;
  • la validation que le mock correspond toujours au service réel.

La règle pratique :

Mockez pour la vitesse et l’isolation. Interrogez le service réel pour valider le contrat.

Pour approfondir, consultez les cas où la simulation d’API est rentable et la différence entre un serveur de simulation et un serveur réel.

Le processus en cinq étapes

Pour simuler une API dans une suite de tests :

  1. Définissez le schéma de l’API.
  2. Générez des réponses simulées, statiques ou dynamiques.
  3. Exécutez un serveur de simulation accessible via une URL.
  4. Configurez vos tests pour pointer vers le mock.
  5. Testez les chemins d’erreur : 404, 500, 429, timeouts, JSON invalide.

Nous allons utiliser ce endpoint comme fil conducteur :

GET /orders/{id}

Étape 1 : Définir le schéma

Un mock fiable commence par un contrat clair. Si votre API possède déjà un document OpenAPI, utilisez-le. Sinon, écrivez un schéma minimal pour l’endpoint testé.

Exemple pour GET /orders/{id} :

paths:
  /orders/{id}:
    get:
      parameters:
        - name: id
          in: path
          required: true
          schema: { type: string }
      responses:
        '200':
          content:
            application/json:
              schema:
                type: object
                properties:
                  id: { type: string }
                  status: { type: string, enum: [pending, shipped, delivered] }
                  total: { type: number }
                  items: { type: array, items: { type: object } }
        '404':
          description: Order not found

Ce schéma sert à deux choses :

  • indiquer au mock quels champs renvoyer ;
  • fournir une source unique de vérité pour les tests et le backend.

Quand le contrat change, mettez à jour le schéma. Les mocks générés depuis ce schéma restent alors alignés. C’est la base des tests de contrat d’API.

Étape 2 : Générer des réponses simulées

Vous avez deux approches principales.

Réponses statiques

Une réponse statique est un JSON fixe. Elle est idéale quand le test doit vérifier une valeur précise.

Exemple :

{
  "id": "order_8842",
  "status": "shipped",
  "total": 149.99,
  "items": [
    {
      "sku": "book_001",
      "quantity": 1
    },
    {
      "sku": "pen_002",
      "quantity": 3
    }
  ]
}

Utilisez ce type de réponse pour des assertions déterministes :

expect(order.status).toBe('shipped');
expect(order.total).toBe(149.99);

Réponses dynamiques

Une réponse dynamique est générée à chaque requête. Le mock peut produire :

  • un UUID pour id ;
  • une valeur autorisée pour status ;
  • un montant réaliste pour total ;
  • des données variables pour items.

Cette approche aide à détecter des bugs cachés par une seule fixture statique : chaînes longues, valeurs nulles, nombres inattendus, tableaux de tailles différentes.

La plupart des équipes combinent les deux :

  • statique pour les tests précis ;
  • dynamique pour une couverture plus proche du fuzz testing.

Avec Apidog, vous pouvez générer automatiquement des endpoints mockés à partir du schéma. Les champs comme email, phone ou avatar sont associés à des types de données cohérents, sans écrire manuellement chaque payload.

Quand vous écrivez vos fixtures à la main, évitez les données trop simplistes :

{
  "id": "1",
  "status": "pending",
  "total": 0,
  "items": []
}

Préférez des données proches de la production :

{
  "id": "order_8842",
  "status": "shipped",
  "total": 149.99,
  "items": [
    {
      "sku": "sku_123",
      "name": "Mechanical keyboard",
      "quantity": 1,
      "price": 129.99
    },
    {
      "sku": "sku_456",
      "name": "USB-C cable",
      "quantity": 1,
      "price": 20
    }
  ]
}

Étape 3 : Exécuter le serveur de simulation

Une réponse mockée doit être servie par une URL. Vous avez deux options.

Option 1 : serveur de simulation local

Un mock local tourne sur votre machine, par exemple :

http://127.0.0.1:4010

C’est l’option recommandée pour les tests unitaires et d’intégration :

  • rapide ;
  • utilisable hors ligne ;
  • pas d’état partagé entre builds ;
  • pas de latence réseau externe.

Avec Prism, vous pouvez démarrer un mock depuis un fichier OpenAPI :

prism mock openapi.yaml
# Serveur de simulation écoutant sur http://127.0.0.1:4010

Votre endpoint devient alors disponible localement :

curl http://127.0.0.1:4010/orders/order_8842

Option 2 : serveur de simulation cloud

Un serveur cloud expose une URL publique. Utilisez-le quand :

  • une app mobile doit appeler le mock ;
  • un runner CI externe doit y accéder ;
  • un collaborateur hors réseau local doit tester l’API ;
  • vous préparez une démo.

Apidog fournit une URL de Cloud Mock par projet, ce qui permet à toute l’équipe d’utiliser le même endpoint simulé.

Pour les tests automatisés, préférez le local. Pour les démos, tests multi-appareils ou collaborations externes, le cloud est plus pratique.

Étape 4 : Pointer vos tests vers le mock

Votre code ne doit pas contenir l’URL de production en dur. Rendez l’URL de base configurable.

Exemple avec une variable d’environnement :

// orderClient.test.js
import { getOrder } from './orderClient.js';

const BASE_URL = process.env.API_BASE_URL || 'http://127.0.0.1:4010';

test('analyse une commande expédiée', async () => {
  const order = await getOrder('order_8842', BASE_URL);

  expect(order.status).toBe('shipped');
  expect(typeof order.total).toBe('number');
});

Le client reçoit l’URL de base en argument :

// orderClient.js
export async function getOrder(id, baseUrl) {
  const response = await fetch(`${baseUrl}/orders/${id}`);

  if (!response.ok) {
    throw new Error(`Failed to fetch order: ${response.status}`);
  }

  return response.json();
}

En local :

API_BASE_URL=http://127.0.0.1:4010 npm test

En CI, définissez API_BASE_URL vers l’adresse du mock avant d’exécuter la suite.

Ce modèle garde la simulation hors de la logique applicative. La même approche s’applique quand vous automatisez les tests API en CI/CD.

Étape 5 : Tester les chemins d’erreur

C’est souvent l’étape la plus rentable.

Un serveur réel ne renvoie pas forcément un 500, un 429 ou une réponse lente au moment où vous en avez besoin. Un mock, oui.

Configurez des scénarios d’échec explicites :

Scénario Le mock renvoie Ce que vous affirmez
Enregistrement manquant 404 Le client lève une erreur claire “non trouvé”
Défaillance serveur 500 Le client réessaie, puis affiche un fallback
Limite de débit atteinte 429 avec Retry-After Le client applique un backoff approprié
Réponse lente 200 après un délai de 5s Le client expire et récupère proprement
Corps de réponse malformé 200 avec JSON invalide Le client échoue sans crash

Exemple de test pour un 404 :

test('renvoie une erreur lisible si la commande est introuvable', async () => {
  await expect(getOrder('order_404', BASE_URL))
    .rejects
    .toThrow('Failed to fetch order: 404');
});

Exemple de test pour un timeout :

test('échoue proprement si la réponse est trop lente', async () => {
  const controller = new AbortController();

  const timeout = setTimeout(() => {
    controller.abort();
  }, 1000);

  await expect(
    fetch(`${BASE_URL}/orders/order_slow`, {
      signal: controller.signal
    })
  ).rejects.toThrow();

  clearTimeout(timeout);
});

Les règles de simulation avancées d’Apidog permettent de renvoyer des réponses différentes selon la requête. Par exemple :

  • GET /orders/order_404 renvoie 404 ;
  • GET /orders/order_rate_limited renvoie 429 ;
  • tout autre ID renvoie 200.

Associez ces scénarios à des assertions API robustes pour tester le comportement, pas seulement les codes de statut.

Organiser les mocks dans une suite de tests qui grandit

Un seul mock est facile à gérer. Une centaine de mocks peut rapidement devenir ingérable.

Adoptez quelques conventions dès le début.

1. Regrouper par service

Organisez les mocks selon le service qu’ils remplacent :

mocks/
  orders/
    order-shipped.json
    order-not-found.json
    order-rate-limited.json
  payments/
    payment-authorized.json
    payment-declined.json

Évitez de les ranger par test :

tests/
  order-page/
    mock1.json
  checkout-page/
    mock2.json

Quand l’API de paiement change, vous voulez modifier un seul dossier clair, pas chercher des fixtures dispersées.

2. Nommer les scénarios explicitement

Préférez :

order-shipped.json
order-delivered.json
order-rate-limited.json

À :

response1.json
test-data.json
mock-success.json

Un test qui échoue doit être lisible rapidement.

3. Versionner les mocks

Les mocks font partie de vos tests. Gardez-les dans le contrôle de version, à côté de la suite automatisée.

src/
tests/
mocks/
openapi.yaml

Une pull request qui modifie un contrat API doit inclure la mise à jour du schéma et des mocks associés.

4. Créer une réponse de base

Évitez de dupliquer des payloads complets dans chaque test. Définissez une base réaliste et surchargez uniquement ce qui change.

Exemple :

const baseOrder = {
  id: 'order_8842',
  status: 'shipped',
  total: 149.99,
  items: [
    { sku: 'sku_123', quantity: 1 },
    { sku: 'sku_456', quantity: 2 }
  ]
};

const cancelledOrder = {
  ...baseOrder,
  status: 'cancelled'
};

Cette discipline rend les mocks maintenables, comme pour une suite de tests d’automatisation d’API.

Maintenir l’intégrité du mock

Le risque principal d’un mock est la dérive.

Exemples :

  • le backend ajoute un champ ;
  • total devient amount;
  • une valeur d’énumération change ;
  • un champ devient nullable ;
  • une erreur retourne un nouveau format.

Si le mock n’est pas mis à jour, vos tests restent verts alors que la production peut casser.

Pour éviter cela, appliquez deux pratiques.

1. Générer le mock depuis le même schéma que le backend

Si le mock vient du fichier OpenAPI, il peut être régénéré quand le contrat change.

Un mock écrit à la main ne suit pas automatiquement ces changements.

2. Exécuter des tests de contrat contre l’API réelle

Ajoutez une petite suite qui vérifie que l’API réelle respecte toujours le schéma.

Objectif :

  • pas tester toute l’application ;
  • pas remplacer les mocks ;
  • seulement détecter une dérive entre le contrat et la production.

Exemple de stratégie :

Tests unitaires et intégration
→ utilisent le mock

Tests de contrat planifiés
→ appellent l’API réelle

Tests end-to-end critiques
→ couvrent quelques parcours complets

Lorsqu’un test de contrat échoue, mettez à jour le schéma, le backend ou les mocks selon l’origine du changement.

Pendant la revue de code, vérifiez aussi les mocks. Si une PR modifie une réponse API, elle doit modifier le mock correspondant.

Si vous voulez centraliser le schéma, le serveur de simulation et les tests dans un même environnement, téléchargez Apidog. Pour comparer les options disponibles, consultez ce tour d’horizon des outils de simulation d’API REST.

Questions fréquemment posées

Dois-je simuler l’API pour chaque test ?

Non. Utilisez des mocks pour les tests unitaires et d’intégration où vous vérifiez votre code. Gardez une petite suite de tests de contrat et quelques tests end-to-end contre l’API réelle pour valider que le mock correspond toujours à la production.

Quelle est la différence entre une réponse statique et dynamique ?

Une réponse statique est un JSON fixe, utile pour des assertions précises et répétables. Une réponse dynamique est générée à chaque requête avec des valeurs réalistes, utile pour exposer des bugs qu’une fixture unique pourrait masquer.

Comment m’assurer que mon mock reste précis ?

Générez-le depuis le même schéma que le backend, idéalement un document OpenAPI. Ensuite, exécutez régulièrement des tests de contrat contre l’API réelle pour vérifier que la réponse live respecte toujours ce schéma.

Un mock peut-il simuler des réponses lentes ou échouées ?

Oui. Vous pouvez configurer un mock pour renvoyer un 500, un 429 avec Retry-After, un 404, un JSON invalide ou un 200 retardé. C’est utile pour tester les retries, les timeouts et les fallbacks.

Serveur de simulation local ou cloud pour les tests ?

Utilisez un serveur local pour les tests automatisés : il est rapide, isolé et sans latence réseau externe. Utilisez un mock cloud lorsqu’un appareil mobile, un runner CI ou un collaborateur externe doit accéder au mock sans dépendre de votre machine.

Build an AI customer support bot with n8n — handles tickets automatically (free workflow)

My inbox had 47 unanswered support tickets on a Monday morning. Most were the same 4 questions: pricing, setup help, refund requests, and “how do I…?” questions.

I built an n8n workflow that handles 80% of them automatically. Here’s the full JSON — free.

What it does

  • Webhook receives support ticket (from your contact form or email)
  • GPT-4o-mini classifies the ticket: pricing / technical / billing / general
  • Sends an appropriate auto-reply for each category
  • Escalates complex tickets to Slack for human review
  • Logs everything to Google Sheets for tracking

Setup time: 15-20 minutes | Cost: ~$0.001 per ticket | n8n version: 1.40+

The workflow JSON

{"name":"AI Customer Support Bot","nodes":[{"parameters":{"httpMethod":"POST","path":"support-ticket","responseMode":"responseNode","options":{}},"id":"cs1","name":"Webhook","type":"n8n-nodes-base.webhook","typeVersion":1,"position":[240,300]},{"parameters":{"jsCode":"const body = $input.first().json.body || $input.first().json;nconst email = body.email || body.from || '[email protected]';nconst subject = body.subject || body.title || 'Support Request';nconst message = body.message || body.content || body.text || '';nreturn [{ json: { email, subject, message, receivedAt: new Date().toISOString() } }];"},"id":"cs2","name":"Parse Ticket","type":"n8n-nodes-base.code","typeVersion":2,"position":[460,300]},{"parameters":{"resource":"chat","operation":"complete","model":"gpt-4o-mini","messages":{"values":[{"role":"system","content":"You are a support ticket classifier. Classify the ticket into exactly one category: PRICING, TECHNICAL, BILLING, or GENERAL. Then write a helpful, friendly auto-reply (2-3 sentences max). Reply in JSON: {"category": "...", "reply": "..."}"},{"role":"user","content":"=Subject: {{ $json.subject }}nMessage: {{ $json.message }}"}]},"options":{"temperature":0.3}},"id":"cs3","name":"AI Classify & Reply","type":"n8n-nodes-base.openAi","typeVersion":1,"position":[680,300]},{"parameters":{"jsCode":"const raw = $input.first().json.message.content;nlet parsed;ntry { parsed = JSON.parse(raw); } catch(e) { parsed = { category: 'GENERAL', reply: 'Thanks for reaching out! Our team will get back to you within 24 hours.' }; }nconst needsHuman = parsed.category === 'BILLING' || parsed.category === 'TECHNICAL';nreturn [{ json: { ...$input.first().json, category: parsed.category, autoReply: parsed.reply, needsHuman } }];"},"id":"cs4","name":"Parse AI Response","type":"n8n-nodes-base.code","typeVersion":2,"position":[900,300]},{"parameters":{"conditions":{"boolean":[{"value1":"={{ $json.needsHuman }}","value2":true}]}},"id":"cs5","name":"Needs Human?","type":"n8n-nodes-base.if","typeVersion":1,"position":[1120,300]},{"parameters":{"sendTo":"={{ $json.email }}","subject":"Re: {{ $json.subject }}","message":"={{ $json.autoReply }}nnBest,nSupport Team","options":{}},"id":"cs6","name":"Send Auto-Reply","type":"n8n-nodes-base.gmail","typeVersion":2,"position":[1340,420]},{"parameters":{"authentication":"webhook","resource":"chat","operation":"post","channel":"#support-escalations","text":"=🎫 *New {{ $json.category }} ticket needs review*n*From:* {{ $json.email }}n*Subject:* {{ $json.subject }}n*Message:* {{ $json.message }}n*Auto-reply sent:* {{ $json.autoReply }}","otherOptions":{}},"id":"cs7","name":"Slack Escalation","type":"n8n-nodes-base.slack","typeVersion":1,"position":[1340,180]},{"parameters":{"operation":"append","documentId":{"value":"YOUR_SHEET_ID"},"sheetName":"Tickets","columns":{"mappingMode":"defineBelow","value":{"Date":"={{ $json.receivedAt }}","Email":"={{ $json.email }}","Subject":"={{ $json.subject }}","Category":"={{ $json.category }}","AutoReply":"={{ $json.autoReply }}","EscalatedToHuman":"={{ $json.needsHuman }}"}},"options":{}},"id":"cs8","name":"Log to Sheets","type":"n8n-nodes-base.googleSheets","typeVersion":4,"position":[1560,300]}],"connections":{"Webhook":{"main":[[{"node":"Parse Ticket","type":"main","index":0}]]},"Parse Ticket":{"main":[[{"node":"AI Classify & Reply","type":"main","index":0}]]},"AI Classify & Reply":{"main":[[{"node":"Parse AI Response","type":"main","index":0}]]},"Parse AI Response":{"main":[[{"node":"Needs Human?","type":"main","index":0}]]},"Needs Human?":{"main":[[{"node":"Slack Escalation","type":"main","index":0}],[{"node":"Send Auto-Reply","type":"main","index":0}]]},"Slack Escalation":{"main":[[{"node":"Log to Sheets","type":"main","index":0}]]},"Send Auto-Reply":{"main":[[{"node":"Log to Sheets","type":"main","index":0}]]}}}

Import: Workflows → New → ⋯ menu → Import from JSON → paste above.

Setup (15 min)

1. Webhook

  • Copy the webhook URL after activating the workflow
  • Point your contact form’s POST action to it
  • Or use Zapier/Make to forward emails to the webhook

2. OpenAI credentials

  • Add your OpenAI API key in n8n credentials
  • GPT-4o-mini costs ~$0.15/1M input tokens — extremely cheap for support

3. Gmail

  • Connect your Gmail account for the auto-reply node
  • Change Send Auto-Reply sender name/signature to match your brand

4. Slack

  • Add a Slack webhook URL for the escalation channel
  • Or swap this node for an email node if you don’t use Slack

5. Google Sheets

  • Create a sheet with columns: Date, Email, Subject, Category, AutoReply, EscalatedToHuman
  • Replace YOUR_SHEET_ID with your sheet’s ID (from the URL)

How the AI classification works

The system prompt forces GPT-4o-mini to return structured JSON with a category and a reply. The Parse AI Response code node handles malformed output gracefully — if parsing fails, it defaults to GENERAL category with a generic reply.

Categories and their handling:

  • PRICING → Auto-reply with your pricing info → no escalation
  • GENERAL → Auto-reply with helpful generic response → no escalation
  • TECHNICAL → Auto-reply + escalate to Slack (needs human follow-up)
  • BILLING → Auto-reply + escalate to Slack (always needs human review)

Tips

1. Customize the system prompt
The real power is in the prompt. Add your actual pricing, your product name, your refund policy. The more context you give GPT, the better the auto-replies.

2. Add a confidence score
Ask the AI to also return "confidence": 0.0-1.0. Only send auto-replies when confidence > 0.8, escalate the rest.

3. Track auto-reply rate
After 1 week, check your Sheets log. What % of tickets got a good auto-reply vs escalation? Tune the system prompt based on what’s failing.

4. Add a delay before sending
Add a Wait node (2-5 min delay) before the auto-reply. Instant replies feel robotic; a short delay feels more human.

5. Handle attachments
The webhook node can receive file uploads. Add a check in Parse Ticket for attachments and route those directly to escalation.

What this replaces

Before: checking email every hour, copy-pasting the same replies, drowning in tickets.

After: webhook fires, AI replies in 30 seconds, you only see the edge cases that need you.

I built this as one of 15 n8n automation templates I use for client projects. If you want the full version with setup guide, Slack alert templates, and error handling — they’re all at https://stripeai.gumroad.com.

The JSON above is the complete working core. Happy to answer questions in the comments.

Building an E2EE Chat App in Flask – Part 1: Why Encryption Matters

Hey everyone! I’m building an encrypted chat application in Flask and documenting the journey. Here’s Part 1.
Why E2EE Matters
Most messaging apps claim to be secure, but they’re not. Your messages sit on their servers where anyone with access can read them.

End-to-End Encryption (E2EE) = only you and the recipient can read messages. The server can’t see anything.

Example:
WhatsApp uses E2EE. Facebook Messenger doesn’t. Your choice matters.

Why I Built This
I wanted to understand encryption by building it, not just reading about it. This project taught me way more than any tutorial.

What’s Next
Part 2: How to handle passwords safely without storing them in plain text.

Questions? Drop them in comments!

Framework de Tests Automatisés API avec Pytest: Tutoriel Pratique

Les développeurs Python choisissent souvent pytest pour tester des API parce qu’il reste simple : un test est une fonction test_*, une assertion est un assert, et le runner s’occupe de l’exécution. Avec requests, vous obtenez une base légère et maintenable pour automatiser des tests d’API directement en code.

Essayez Apidog aujourd’hui

Dans ce guide, vous allez construire une suite de tests d’API avec pytest : initialisation du projet, premier test HTTP, fixtures partagées, tests paramétrés, assertions sur les réponses et validation de schéma JSON. Les exemples utilisent une API fictive de style réaliste pour que vous puissiez adapter la structure à votre propre backend.

Configuration du projet

Créez un environnement virtuel, puis installez les dépendances :

python -m venv .venv
source .venv/bin/activate
pip install pytest requests jsonschema

Utilisez une structure simple dès le départ :

api-tests/
  conftest.py        # fixtures partagées
  test_users.py      # tests des endpoints utilisateurs
  test_orders.py     # tests des endpoints commandes
  pytest.ini         # configuration pytest

Pytest découvre automatiquement les tests si vous respectez ces conventions :

  • les fichiers commencent par test_ ou se terminent par _test.py ;
  • les fonctions commencent par test_ ;
  • les classes commencent par Test et n’ont pas de méthode __init__.

Exemple :

test_users.py
test_orders.py

Si les tests automatisés sont nouveaux pour vous, commencez par cette introduction sur ce qu’est le test automatisé.

Pourquoi pytest pour les tests d’API ? requests gère les appels HTTP, tandis que pytest fournit la découverte des tests, les assertions lisibles, les fixtures, la paramétrisation et le reporting. Vous pouvez donc garder vos tests proches du code applicatif, dans le même dépôt, et détecter les régressions directement dans les pull requests.

Écrire votre premier test d’API

Un test d’API pytest suit généralement trois étapes :

  1. envoyer une requête ;
  2. lire la réponse ;
  3. vérifier le statut, le corps ou les en-têtes.

Exemple avec un endpoint utilisateur :

import requests

BASE_URL = "https://api.example.com/v1"

def test_get_user_returns_200():
    response = requests.get(f"{BASE_URL}/users/42")

    assert response.status_code == 200

def test_get_user_returns_expected_fields():
    response = requests.get(f"{BASE_URL}/users/42")
    body = response.json()

    assert body["id"] == 42
    assert "email" in body
    assert body["status"] == "active"

Lancez la suite :

pytest -v

En cas d’échec, pytest affiche les valeurs réelles et attendues à partir de simples instructions assert. Vous n’avez pas besoin de méthodes d’assertion spécifiques.

Pour approfondir les vérifications utiles sur une réponse HTTP, consultez ce guide sur les assertions d’API.

Partager la configuration avec les fixtures

Évitez de répéter l’URL de base, les headers ou la session HTTP dans chaque test. Utilisez des fixtures.

Une fixture est une fonction décorée avec @pytest.fixture. Un test l’utilise simplement en déclarant son nom comme paramètre.

Placez les fixtures communes dans conftest.py :

# conftest.py
import pytest
import requests

BASE_URL = "https://api.example.com/v1"

@pytest.fixture(scope="session")
def api_session():
    session = requests.Session()
    session.headers.update({"Accept": "application/json"})

    yield session

    session.close()

@pytest.fixture
def auth_token(api_session):
    response = api_session.post(
        f"{BASE_URL}/auth/login",
        json={
            "email": "[email protected]",
            "password": "test-pass",
        },
    )

    return response.json()["token"]

Ici :

  • scope="session" crée une seule session HTTP pour toute l’exécution ;
  • le code avant yield prépare la ressource ;
  • le code après yield nettoie la ressource.

Un test peut ensuite demander uniquement ce dont il a besoin :

def test_create_order(api_session, auth_token):
    response = api_session.post(
        f"{BASE_URL}/orders",
        headers={"Authorization": f"Bearer {auth_token}"},
        json={
            "product_id": 7,
            "quantity": 2,
        },
    )

    assert response.status_code == 201
    assert response.json()["status"] == "pending"

Les fixtures remplacent avantageusement les anciens modèles setup_function et teardown_function. Elles se composent mieux, rendent les dépendances explicites et supportent plusieurs scopes. La documentation officielle des fixtures pytest les recommande comme approche par défaut.

Exécuter un test sur plusieurs entrées

Les endpoints doivent être testés avec plusieurs valeurs : cas valides, invalides et limites. Au lieu de dupliquer les fonctions, utilisez @pytest.mark.parametrize.

import pytest

BASE_URL = "https://api.example.com/v1"

@pytest.mark.parametrize(
    "user_id, expected_status",
    [
        (42, 200),
        (99999, 404),
        (0, 404),
        (-1, 400),
    ],
)
def test_get_user_status_codes(api_session, user_id, expected_status):
    response = api_session.get(f"{BASE_URL}/users/{user_id}")

    assert response.status_code == expected_status

Cette fonction génère quatre cas de test indépendants. Si un cas échoue, les autres continuent à s’exécuter et apparaissent séparément dans le rapport.

Quand la liste d’entrées devient longue, chargez les données depuis un fichier CSV ou JSON. Ce guide sur les tests d’API pilotés par les données avec CSV et JSON couvre ce modèle.

Si vous hésitez sur les statuts HTTP à attendre, utilisez cette référence sur les codes de statut HTTP que les API REST devraient utiliser.

Assertions sur le corps de réponse et le schéma

Un code 200 ne suffit pas. Une réponse peut réussir côté HTTP tout en renvoyant un JSON incomplet ou incorrect.

Commencez par des assertions directes sur le corps :

def test_order_response_shape(api_session, auth_token):
    response = api_session.post(
        f"{BASE_URL}/orders",
        headers={"Authorization": f"Bearer {auth_token}"},
        json={
            "product_id": 7,
            "quantity": 2,
        },
    )

    body = response.json()

    assert isinstance(body["id"], int)
    assert body["quantity"] == 2
    assert body["total"] > 0
    assert response.elapsed.total_seconds() < 1.0

Pour vérifier toute la structure de la réponse, validez le JSON contre un schéma :

from jsonschema import validate

order_schema = {
    "type": "object",
    "required": ["id", "product_id", "quantity", "status", "total"],
    "properties": {
        "id": {"type": "integer"},
        "product_id": {"type": "integer"},
        "quantity": {"type": "integer", "minimum": 1},
        "status": {"type": "string"},
        "total": {"type": "number"},
    },
}

def test_order_matches_schema(api_session, auth_token):
    response = api_session.post(
        f"{BASE_URL}/orders",
        headers={"Authorization": f"Bearer {auth_token}"},
        json={
            "product_id": 7,
            "quantity": 2,
        },
    )

    validate(instance=response.json(), schema=order_schema)

La validation de schéma détecte les champs manquants, renommés ou de mauvais type. Elle évite aussi de multiplier les assertions champ par champ.

La bibliothèque jsonschema est le choix courant pour ce besoin. Sa documentation de validation détaille les mots-clés disponibles.

Exécuter la suite en CI

Une suite pytest devient réellement utile lorsqu’elle s’exécute automatiquement à chaque changement.

Pytest renvoie un code de sortie non nul si un test échoue, ce qui permet à votre pipeline CI de bloquer un build ou une pull request.

Générez aussi un rapport JUnit :

pytest -v --junitxml=results.xml

Cette commande peut être appelée depuis GitHub Actions, GitLab CI, Jenkins ou tout autre outil CI.

Pour une configuration complète, y compris les secrets et la sélection d’environnement, consultez cette présentation des tests d’API dans les pipelines CI/CD.

Deux pratiques rendent la suite plus fiable en CI.

D’abord, ne codez pas en dur les secrets ni les URL d’environnement. Lisez-les depuis les variables d’environnement :

import os

BASE_URL = os.environ.get(
    "API_BASE_URL",
    "https://staging.example.com/v1",
)

Ensuite, exécutez les tests indépendants en parallèle si la suite devient lente. Le plugin pytest-xdist permet de répartir les tests sur plusieurs cœurs :

pip install pytest-xdist
pytest -n auto

Les tests parallèles exigent des données isolées. Évitez les tests qui dépendent de l’ordre d’exécution ou d’un état partagé.

Maintenir une suite pytest

Une suite de cinquante tests reste simple à gérer. Une suite de plusieurs centaines nécessite des conventions.

Regroupez les tests par domaine :

test_users.py
test_orders.py
test_payments.py

Utilisez les classes seulement lorsqu’elles apportent une configuration commune. Des fonctions explicites dans des modules bien nommés sont souvent plus lisibles.

Ajoutez des marks pour exécuter des sous-ensembles :

import pytest

@pytest.mark.smoke
def test_get_user_returns_200(api_session):
    response = api_session.get(f"{BASE_URL}/users/42")

    assert response.status_code == 200

Déclarez-les dans pytest.ini :

[pytest]
markers =
    smoke: tests rapides à exécuter à chaque commit
    slow: tests plus longs à exécuter moins souvent

Puis lancez uniquement les tests smoke :

pytest -m smoke

Centralisez aussi la configuration :

  • URL de base ;
  • headers communs ;
  • fixtures d’authentification ;
  • schémas JSON ;
  • helpers de création ou nettoyage de données.

Ne dupliquez pas ces éléments entre les fichiers de test. Si vous écrivez la même logique deux fois, extrayez-la dans une fixture ou une fonction utilitaire.

Cette discipline est la même que pour tout framework de test automatisé. Ce guide sur comment écrire des scripts de test automatisés détaille ces principes.

Quand utiliser plutôt une plateforme

Un framework pytest est adapté si votre équipe écrit en Python et veut conserver les tests dans le même dépôt que le code applicatif.

Il devient moins pratique lorsque :

  • les équipes QA ou produit doivent contribuer sans écrire de Python ;
  • vous voulez concevoir, mocker et tester les API dans un même outil ;
  • vous ne souhaitez pas maintenir de code de fixtures, de helpers et d’assertions.

Apidog couvre ce cas d’usage. Il propose la construction visuelle de tests, la validation de schéma par rapport à une spécification OpenAPI, des exécutions pilotées par CSV ou JSON, et un runner CLI pour la CI.

Beaucoup d’équipes combinent les deux approches : pytest pour les scénarios avec beaucoup de logique métier, et Apidog pour une couverture plus large, la conception d’API et le mocking. Vous pouvez télécharger Apidog et comparer les deux approches sur un endpoint réel.

Questions fréquemment posées

Pourquoi utiliser pytest plutôt que le module unittest intégré de Python pour les tests d’API ?

Pytest demande moins de boilerplate. Les tests sont de simples fonctions, les assertions sont de simples assert, et les fixtures gèrent la configuration plus souplement que les méthodes de classes de unittest.

Pytest dispose aussi d’un vaste écosystème de plugins et d’un support intégré de parametrize pour les tests pilotés par les données. Il peut toujours exécuter des tests existants de style unittest, ce qui facilite une migration progressive.

Quelle est la différence entre une fixture et parametrize ?

Une fixture fournit une ressource réutilisable à un test : session HTTP, token d’authentification, utilisateur de test, configuration, etc.

parametrize exécute le même test plusieurs fois avec différentes valeurs d’entrée.

En pratique :

  • les fixtures partagent la configuration ;
  • parametrize multiplie les cas de test ;
  • les deux peuvent être utilisés ensemble.

Devrais-je faire des assertions sur le temps de réponse dans les tests d’API pytest ?

Vous pouvez utiliser response.elapsed.total_seconds() pour détecter de fortes régressions :

assert response.elapsed.total_seconds() < 1.0

Gardez toutefois une limite assez large. Pytest est adapté aux tests fonctionnels, pas aux tests de charge. Pour mesurer précisément les performances, utilisez un outil dédié.

Comment garder les tests d’API indépendants dans pytest ?

Chaque test doit créer ou recevoir ses propres données via des fixtures. Évitez de dépendre :

  • de l’ordre d’exécution ;
  • d’une ressource créée par un autre test ;
  • d’un état partagé non nettoyé.

Des tests indépendants sont plus faciles à paralléliser, à déboguer et à exécuter isolément.

Pytest peut-il valider les réponses par rapport à une spécification OpenAPI ?

Pytest ne le fait pas directement. Vous pouvez valider les réponses avec jsonschema, ou ajouter des plugins capables de vérifier les réponses contre un document OpenAPI.

Si cette validation est centrale dans votre workflow, une plateforme comme Apidog peut automatiser la validation contre votre spécification OpenAPI et réduire la configuration côté pytest.

Epic Games Store, dört farklı oyun hediye ediyor

Epic Games Store, dört farklı oyun hediye ediyor

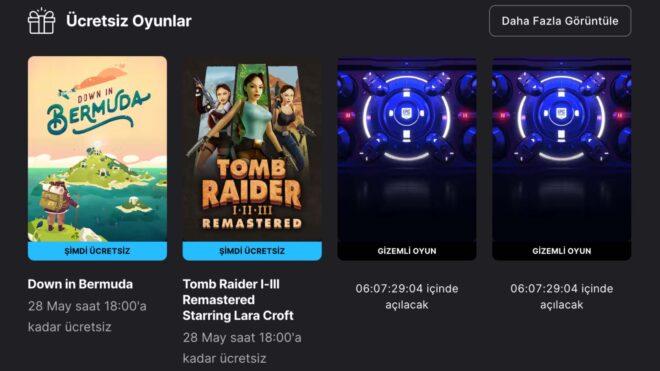
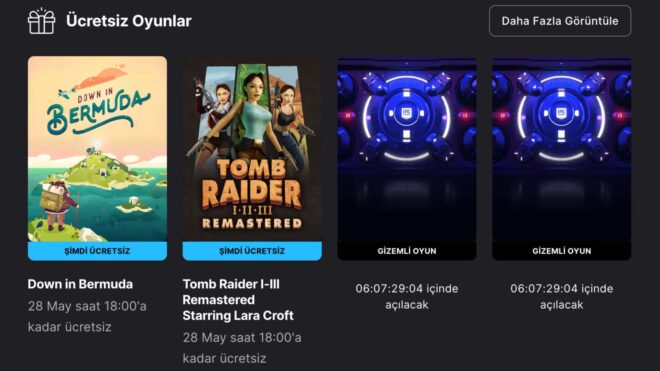
Epic Games Store, dört farklı oyun hediye ediyorEpic Games Store, bu sefer dört farklı oyun hediye ediyor. Şirketin verdiği ilk hediye “Down in Bermuda” oldu. Daha önce 33 TL’ye satılan oyun için şu açıklama yapıldı: “Tuhaf bir fırtına, maceracı bir pilotun kötü şöhretli Bermuda bölgesine düşerek onlarca yıl burada kapana kısılmasına sebep oluyor. Eve dönüş yolunu ararken derinliklerden gelen yaratıkların üstesinden gelin ve adanın sırlarını açığa çıkarın.” Epic Games aynı zamanda içerisinde Tomb Raider I (Unfinished Business genişleme paketiyle), Tomb Raider II (Golden Mask genişleme paketiyle) ve Tomb Raider III (The Lost Artifact genişleme paketiyle) oyunlarının yer aldığı “Tomb Raider I-III Remastered Starring Lara Croft” paketini de hediye ediyor. Daha önce 229 TL’ye satılan paket için, “Orijinal Üç Tomb Raider Macerasını Oynayın: Bu kapsamlı koleksiyon sayesinde tüm ekstra içerikler ve gizli bölümler de dahil olmak üzere Tomb Raider deneyiminin tamamını ilk kez modern sistemlerde oynayabilirsiniz.” açıklaması yapılıyor.

Epic Games Store, dört farklı oyun hediye ediyor yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

useEffect Hook in React

React provides many Hooks that make functional components powerful and easy to manage. One of the most important Hooks is useEffect.

The useEffect Hook is used to perform side effects in React components.

What is a Side Effect?

A side effect is any action that happens outside the normal rendering process of a component.

Examples:

Fetching data from an API
Updating the webpage title
Using timers
Adding event listeners

Syntax of useEffect

useEffect(() => {

}, []);

The first part is a function containing the side effect.
The second part is the dependency array.
Example of useEffect

import { useEffect } from "react";
function App() {
useEffect(() => {
        console.log("Component Rendered");
    }, []);

    return (
        <h1>Hello React</h1>
    );
}

export default App;
Explanation
The message prints when the component renders for the first time.
The empty dependency array [] means it runs only once.
Dependency Array

The dependency array controls when the effect runs.

Empty Array

useEffect(() => {
    console.log("Runs once");
}, []);

Runs only once after the first render.

With Dependency
useEffect(() => {
    console.log("Runs when count changes");
}, [count]);

Runs whenever count changes.

Why Use useEffect?

useEffect helps developers:

Handle API calls
Manage timers
Update DOM content
Perform actions after rendering

Day 16: +51 reader spike in 85 min on dev.to. 0 sales. Here’s what actually moved.

Day 16: I got a +51 reader spike on dev.to in 85 minutes. 0 sales. Here’s what actually moved.

I’m 16 days into trying to make my first $10 USD on Gumroad with no audience, no Twitter following, no email list. The product is a small freelancer Gmail inbox triage tool. PWYW $0, $19 self-host, $99 done-for-you.

Today the dev.to dashboard showed something I haven’t seen before:

  • 194 → 245 readers in 85 minutes (~36 readers/hour vs baseline 1/hour)
  • Bing organic: 30 → 40 views
  • Reactions: 1 (unchanged)
  • New followers: 0 (unchanged)
  • Comments: 2 (unchanged, both mine on other people’s posts)
  • Gumroad sales: still 0

That’s a 36x baseline traffic surge. And it converted nothing.

Here’s what I think actually happened, and what it taught me about the gap between “engagement metric went up” and “someone gave me a dollar.”

What I shipped this morning

Three things, all in a ~90 minute window:

  1. Batch-updated 18 of my dev.to articles to add UTM tracking on every Gumroad link in the body. So instead of foxck.gumroad.com/l/freelancer-gmail-tracking-pack, every link became ...?utm_source=devto&utm_medium=article&utm_campaign=devto-{article_id}. Per-article attribution.
  2. Posted 2 outbound comments on other dev.to creators’ posts in the same niche — one on a “cold email” article, one on a “turn your email into a SQL database” article. Both substantive (200+ char), no links, just trying to be the smartest comment on the page. (Day 15 covered why I switched to this strategy.)
  3. Published Day 15 itself.

I expected: maybe +5 readers from Day 15, maybe a follower or two from the comments.

Got: +51 readers in 85 minutes. None of them bought anything.

My honest theory of why the spike happened

I think the dev.to algorithm “noticed” the author was active again. 18 article edits + 2 outbound comments + 1 publish, all from the same account, in a tight window, looks like an active creator. The platform’s home feed and “more from this author” rails re-surfaced older posts.

That’s a temporary halo. It re-prices existing inventory, it doesn’t create new conversion paths.

I can test this theory: the same effect should decay in 24h as the activity signal fades. I’ll report Day 17.

The thing that didn’t move at all

Followers. 0.

That’s the actual leading indicator for “did anyone find my work worth coming back for.” 245 people landed on a page. 0 of them clicked the follow button. 0 of them clicked through to the Gumroad page (Gumroad analytics shows 0 incoming devto-tagged sessions today).

The traffic was real. The intent wasn’t. The articles got read by people who were also-reading something else, then closed the tab.

What this changes about my strategy

I had been hoping that “more articles + more comments = compounding visibility = sales.” Sixteen days in, the compounding visibility part is real. The sales part still isn’t.

The honest read is:

  • Top of funnel is fine. 194 readers/week with 0 paid promotion isn’t bad for a 16-day-old account.
  • Middle of funnel is broken. Articles are getting read but not converting reader → follower or reader → Gumroad click.
  • Bottom of funnel might be fine, but I have no data on it because no one is reaching it.

The fix is not “more articles.” It’s “make one article actually convert.”

That probably means:

  1. The Gumroad listing page itself is the bottleneck (the $0 PWYW page especially — $0 should be a strong CTA and it isn’t converting).
  2. The “click through to Gumroad” friction is too high. Articles mention the product as a footnote, not as the main thing the reader leaves with.
  3. The free thing (PWYW $0) doesn’t have a strong “what you get right now if you click this” pitch above the fold.

Day 17 plan: stop publishing. Take the next 24 hours and rewrite the Gumroad PWYW $0 page and one article cold open. Then watch what 245 readers/week does with a better landing surface.

The Day 15 / Day 16 lesson, condensed

Engagement metrics can spike without revenue moving. If you don’t have a working middle of funnel, more top of funnel just makes the failure louder.

If you’re also trying to ship a tiny product to no audience, I’d love to know: what’s the conversion-rate test that finally moved your numbers? Drop it in the comments.

— Day 16 of /ZERO-TEN — cold start a $0 PDF/actor with no audience/

The product I keep talking about: foxck.gumroad.com/l/freelancer-gmail-cold-thread-finder (PWYW $0, the friction-reducing version).

My thoughts on Spatie/Piper

When I saw a library for the pipe operator I needed to check it out.

People that read my posts before know I’m a big fan of the pipe operator feature. The main benefit is that it is less likely that the functions have side effects, because they don’t depend on a master object that comes with a builder pattern.

The good

I like that they moved the collecting function inside the functions.

function map(callable $callback): Closure
{
    return function (array $items) use ($callback): array {
        $result = [];

        foreach ($items as $key => $value) {
            $result[$key] = $callback($value, $key);
        }

        return $result;
    };
}

For people that are less aware how the pipe operator works in PHP 8.5 a short introduction.
The pipe operator passes a single variable on to whatever function is called next in the chain, [1, 2] |> array_sum(...). From the moment you want to use predefined arguments for a function, you need to wrap it in a function that collects that single variable, [1, 2] |> (fn($arr) => array_map(fn (int $i) => pow($i, 2), $arr)).
By moving the collecting function into the actual function they reduced the amount of code you need to write to [1, 2] |> map(fn (int $i) => pow($i, 2)).
In PHP 8.6 this verbosity problem will be solved, and then you can write [1, 2] |> array_map(fn (int $i) => pow($i, 2), ?).
But because the goal of the library is to mimic the Laravel builder pattern methods, I think it is a great choice.

I like that all the functions are in separate files. The functions.php file is there just to collect them all.

The misses

It is not to hard to see where the name comes from. The problem I have with it is that is too generic. Is it possible they are going to add other pipe operator categories?

That brings me to the following missed opportunity, why not split the library. There could be a collection-piper and string-piper library. This way the support functions and exceptions context will be clearer.
And you can choose which Laravel builder pattern you want replace, instead of adding functions you are never going to use.

Because functions are loaded upfront it might be a good idea to have a way to choose the ones the project is really going to use.
It is a problem that has not been addressed by PHP libraries and frameworks, including my own.
By having the functions in separate files this could be more easily achieved than having all the functions in a single file.

The negative consequence of having the collecting function in the functions, they can’t be used for non pipe operator situations.

// plain use, pipe operator php 8.6 use
function map(array $items, callable $callback): array
{
    $result = [];

    foreach ($items as $key => $value) {
       $result[$key] = $callback($value, $key);
    }

    return $result;
}
// pipe operator PHP 8.5/8.6 use
function pMap(callable $callback): Closure
{
   return function(array $items) use ($callback) {
       return map($items, $callback);
   }
}

Conclusion

I am a bit of an anti-abstractionist. If you can achieve something with no abstraction, array_map(fn (int $i) => pow($i, 2), [1, 2]), do that. As you can see from the example even the pipe operator can be an abstraction.
And that is why Laravel collections and string builders were never my favourite additions to the framework. Even while they have functions that are genuinely helpful. I used map in the examples, but for me that is not one of the helpful functions.

By having more pipe operator libraries the use of the functions will be more versatile than with builder pattern methods. But we need to be aware of the limitations if they only target the pipe operator.

This is quite a short post but I had to get those thoughts out of my head.

Building a Serverless AI Model Evaluation Platform on AWS

AWS Architecture Overview

The Problem

A media company needed to evaluate which AI model produces the best podcast-style summaries from news articles. They wanted to:

  • Send an article to multiple AI models simultaneously
  • Compare the outputs side by side
  • Score each output automatically
  • Generate a visual comparison report

Doing this manually, copying articles into different model playgrounds, reading outputs, judging quality, doesn’t scale. They needed an automated evaluation pipeline that could run experiments on demand and produce consistent, comparable results.

What We Built

A fully serverless evaluation platform on AWS that accepts an article, runs it through multiple foundation models in parallel, scores each output using a separate AI judge, and produces an HTML comparison report. All triggered by a single API call.

The system handles the entire lifecycle:

  1. Prompt optimization — an AI agent refines the user’s instructions into an effective prompt
  2. Parallel model invocation — multiple Bedrock models generate summaries simultaneously
  3. Automated scoring — a scoring agent evaluates each output against quality criteria
  4. Report generation — produces a formatted HTML comparison page

Architecture Overview

AWS Architecture Overview

The 6-Step Workflow

The core of the system is a Step Functions state machine that orchestrates six Lambda functions in sequence. Here’s what each step does and why it exists as a separate step.

6 Step Pipeline

Step 1: Validate

def validate(event):
    """Read and validate the experiment definition from S3."""
    definition = s3.get_object(Bucket=BUCKET, Key=f"definitions/{experiment_id}/definition.json")
    # Validate required fields: article, models, prompt
    # Fail fast if inputs are malformed
    return validated_definition

Why a separate step? Fail-fast validation before incurring any Bedrock costs. If the definition is malformed, we stop here — no wasted model invocations.

Step 2: Invoke Models (Parallel)

This is where it gets interesting. We invoke multiple Bedrock models simultaneously using Python’s ThreadPoolExecutor:

from concurrent.futures import ThreadPoolExecutor, as_completed

def invoke_models(definition):
    models = definition['models']  # e.g., ["meta.llama3-70b", "deepseek-r1", "amazon.nova-lite"]
    prompt = definition['prompt']
    article = definition['article']

    results = {}

    with ThreadPoolExecutor(max_workers=len(models)) as executor:
        futures = {
            executor.submit(invoke_bedrock, model_id, prompt, article): model_id
            for model_id in models
        }
        for future in as_completed(futures):
            model_id = futures[future]
            response = future.result()
            results[model_id] = {
                "output": response['output']['message']['content'][0]['text'],
                "usage": {
                    "input_tokens": response['usage']['inputTokens'],
                    "output_tokens": response['usage']['outputTokens']
                }
            }

    return results

Why ThreadPoolExecutor inside Lambda? Bedrock API calls are I/O-bound. Running them in parallel within a single Lambda invocation means we pay for one Lambda execution instead of three, and the total wall-clock time is roughly equal to the slowest model rather than the sum of all models.

Step 3: Store Outputs

Writes comparison.json to S3 — containing all model outputs but no scores yet. This creates a checkpoint: if scoring fails, we don’t lose the generated content.

Step 4: Score (Parallel)

The scoring agent (Claude Haiku) evaluates each model’s output against quality criteria. Again, parallel execution via ThreadPoolExecutor:

def score(outputs):
    scoring_prompt = """Rate this podcast summary on:
    - Accuracy (1-10): Does it faithfully represent the article?
    - Engagement (1-10): Would a listener find this compelling?
    - Structure (1-10): Is it well-organized for audio?
    Respond with JSON only."""

    with ThreadPoolExecutor(max_workers=len(outputs)) as executor:
        futures = {
            executor.submit(invoke_bedrock, SCORING_MODEL, scoring_prompt, output): model_id
            for model_id, output in outputs.items()
        }
        # ... collect scores

Why a separate scoring model? Using a different model (or at minimum, a separate invocation with a scoring-specific prompt) as the judge avoids self-evaluation bias. The scoring agent doesn’t know which model produced which output.

Step 5: Store Scores

Updates comparison.json with the scores attached to each model’s output.

Step 6: Generate HTML

Produces a formatted comparison.html report that displays all outputs side by side with their scores. This is the final deliverable the user downloads.

Why Amazon Bedrock’s Converse API?

We use the Converse API rather than the model-specific InvokeModel API. The key advantage: one unified interface across all models.

def invoke_bedrock(model_id, system_prompt, user_message):
    response = bedrock_runtime.converse(
        modelId=model_id,
        messages=[{"role": "user", "content": [{"text": user_message}]}],
        system=[{"text": system_prompt}]
    )
    return response

Switching from Llama to Claude to Nova Lite requires changing only the model_id string. No code changes, no different request formats, no response parsing differences.

The Converse API also returns token usage in every response — which we pass through to the caller for billing:

{
  "results": [
    {
      "model_id": "meta.llama3-70b-instruct-v1:0",
      "summary": "...",
      "usage": { "input_tokens": 1523, "output_tokens": 847 }
    }
  ],
  "total_usage": { "total_input_tokens": 4569, "total_output_tokens": 2541 }
}

Cost Control: The Hardest Part

Here’s the reality of building on top of foundation models: every API call costs money, and costs scale with input size. A single /run request invoking 3 models on a long article can cost $0.10–0.50. That sounds small until someone writes a script that calls it in a loop.

Billing Alarms (Day 1)

We set up CloudWatch billing alarms immediately:

CloudWatch Alarm ($10 threshold) → SNS → Email notification
CloudWatch Alarm ($25 threshold) → SNS → Email notification

This is the bare minimum. You’ll know when costs are climbing, even if you can’t stop them automatically.

API Security (Critical for Any AI-Backed API)

An unprotected API that invokes foundation models is essentially a public credit card. We learned this the hard way and now treat API security as P0 — before any external access:

  • API Keys on every endpoint (immediate protection)
  • Usage plans with per-key quotas (500 requests/day, 5000/month)
  • Rate limiting (10 req/s throttle) to prevent burst abuse
  • Request logging to attribute usage to specific callers
# Every request must include the API key
curl -X POST https://api.example.com/run 
  -H "x-api-key: btk_live_abc123def456" 
  -H "Content-Type: application/json" 
  -d '{"article": "...", "models": ["meta.llama3-70b"]}'

Without this, anyone who discovers your API URL can generate unbounded Bedrock charges.

Lessons Learned

1. Separate validation from execution

Bedrock calls are expensive. Validate everything before invoking any model. Check that the article isn’t empty, the model IDs are valid, the prompt isn’t too long. Fail at Step 1, not Step 2.

2. ThreadPoolExecutor > separate Lambda invocations for parallel model calls

We considered using Step Functions’ native parallel states or invoking separate Lambdas per model. ThreadPoolExecutor within a single Lambda turned out simpler:

  • One Lambda execution to pay for (not N)
  • Shared memory for the article text (no repeated S3 reads)
  • Simpler error handling
  • Total time ≈ slowest model, not sum of all

The tradeoff: if one model times out, the entire Lambda times out. We mitigate this with per-future timeouts.

3. Store intermediate results

Each step writes to S3 before the next step begins. If Step 4 (scoring) fails, we still have the model outputs from Step 3. We can retry scoring without re-invoking the content models.

4. Token usage is free metadata — always capture it

Bedrock returns inputTokens and outputTokens in every response. Capturing and returning this costs nothing but enables:

  • Per-customer billing
  • Cost forecasting
  • Identifying expensive prompts
  • Detecting anomalies (sudden spike in token usage = possible abuse)

5. Start with S3, add a database when you need queries

For the POC, S3 handles all storage. It’s simple, cheap, and sufficient for sequential read/write patterns. We’re adding DynamoDB only now that we need to query experiment history by user — something S3 can’t do efficiently.

What’s Next

The platform is functional but evolving:

  • Selection History — DynamoDB-backed experiment sessions so users can revisit past comparisons and track which model they ultimately chose
  • Frontend UI — Visual interface for running experiments and browsing history
  • Cognito Authentication — User-level access control when the UI ships

Tech Stack Summary

Layer Service Why
API API Gateway (HTTP API) Low latency, pay-per-request
Compute AWS Lambda (Python) Serverless, scales to zero
Orchestration Step Functions Visual workflow, built-in retries
AI Models Amazon Bedrock (Converse API) Multi-model, unified interface
Storage Amazon S3 Cheap, durable, simple
Monitoring CloudWatch + SNS Billing alarms, email alerts
Auth (planned) API Keys + Cognito Layered security
History (planned) DynamoDB Fast queries by user/session

Reach Out to Us

Interested in modernizing your cloud infrastructure and building enterprise-grade solutions? Storm Reply is driven by continuous learning and practical innovation. We specialize in designing and delivering scalable AWS architectures that support customers throughout their cloud journey, from early assessment to production-ready deployment.

With deep experience in AWS architecture, data engineering, and security best practices, we help enterprises migrate with confidence and move faster on their cloud transformation goals.

Let’s connect and explore how we can support your modernization initiatives.

🌐 Website: https://www.stormreply.cloud/

💼 LinkedIn: https://www.linkedin.com/company/storm-reply/posts/?feedView=all
Date: May 2026

The full system runs in eu-central-1 (Frankfurt), costs under $20/month excluding Bedrock usage, and handles the entire evaluation lifecycle in a single API call. Serverless means we pay nothing when nobody’s running experiments, and scale automatically when they are.

If you’re building something similar — any system where API calls trigger expensive downstream operations — lock down your API first, validate inputs aggressively, and always know what each request costs.

Built with AWS Lambda, Step Functions, and Amazon Bedrock.