How we run our newsletter on our own Astro stack instead of Substack

Left: the old newsletter on Substack. Right: the same content now on getbeton.ai/blog, where we control every header and tag.

This is a post about plumbing. We send a newsletter, it goes out from our own site, and over the last few months that setup turned into something I actually like working on. Here is the whole thing.

Why we left Substack

The newsletter used to live on Substack. We moved it for one reason: SEO control.

We were in the middle of fixing indexation on getbeton.ai, working through every factor that could be holding pages back. Substack is a black box for yours truly. You don’t control the sitemap and canonical tags, you can’t set a real lastmod, and the URL lives on a domain that isn’t yours.

When you’re trying to eliminate variables, a platform you can’t configure is usually my first choice.

So the newsletter and the blog became the same thing, on our own domain, where we own every header and every tag.

Left: the old newsletter on Substack. Right: the same content now on getbeton.ai/blog, where we control every header and tag.

The setup: same Astro as the rest of the site

The blog is not a separate system. It’s the same Astro build that runs the rest of getbeton.ai, the same Tailwind tokens, the same deploy to Vercel.

Posts are plain markdown files in a content collection. Each one has frontmatter for title, description, a TL;DR, and an FAQ. Astro renders the markdown to static HTML at build time; there is no CMS and no database in the path. The TL;DR and FAQ aren’t just for readers, they compile into JSON-LD so the structured data is correct without hand-writing it.

Two details that only exist because we own the renderer:

  • Every post has a raw-markdown twin at /blog/<slug>.md, so an LLM or a script can read the clean source instead of scraping HTML.
  • The sitemap’s lastmod comes from the file’s git history, not the build time. Build-time lastmod is a lie that tells Google every page changed on every deploy. Reading git mtime ships the real date.

A blog post's markdown source on the left, the rendered page on the right: same file, frontmatter and all, becomes the live post.

The reading UI we actually wanted

This is the part that made it fun. Once you own the renderer (and have Claude at your side), you can ship small things quickly

The one I use most is sidenotes.[1] On a wide screen, a footnote floats out into the left margin next to the line it belongs to, the way a good print book does it. On mobile it collapses to a tappable reference.

They’re plain HTML in the markdown, styled once in our prose stylesheet, and they double as quiet contextual CTAs where they fit.

We also render a TL;DR block at the top and an FAQ at the bottom of every post, both pulled from the same frontmatter that feeds the structured data.

Owning the renderer pays off in small typographic things too. Monospace text renders the way we want it to, not the way a platform theme decided.

Code snippets look however we choose, with the syntax styling we pick, instead of whatever a generic editor pastes in. 

Imo for a blog that talks about tooling, that matters more than it sounds.

It also makes the structured data trivial. The TL;DR and FAQ already live in frontmatter, so embedding them in JSON-LD is a few lines at render time, not a plugin and not hand-written markup. Cleaner structured data, written once, and the same source feeds both the page and the rich result.

None of this is baseline. A platform gives you a title, a body, and a subscribe box. Owning the stack means the reading experience is yours to shape, and that is reason enough to build a small thing now and then.

Sending: Resend

Sending runs on Resend.

The audience is a Resend audience. New subscribers come in through a form on the site that posts to a small API route and adds them to that audience. The sending domain is verified on getbeton.ai with SPF, DKIM, and DMARC, so mail authenticates as us and lands in the inbox instead of spam.

Each campaign is a small Node script. It builds the email HTML per recipient, pulls the subscribed contacts, and sends with a delay between messages to stay polite. Every send carries a List-Unsubscribe header and an unsubscribe link, and the script skips anyone already unsubscribed.

Analytics: PostHog, on its own dashboard

We didn’t want to lose open and click tracking by leaving a platform, so we rebuilt it with -– surprise-surprise — with Posthog.

Two endpoints do the work. A 1×1 tracking pixel records opens. A click redirector wraps every link, records the click, then 302s the reader to the real destination with UTM tags attached.

Both fire PostHog events, newsletter_opened and newsletter_link_clicked, tagged with the campaign and the recipient. They’re small enough to read in full.

The open pixel is an Astro endpoint that returns a 1×1 gif and captures an event on the way out. The PostHog call is fire-and-forget, so a slow capture never blocks the image:

// src/pages/api/track/pixel.png.ts
const PIXEL = Buffer.from('R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7', 'base64'); // 1x1 gif

export const GET: APIRoute = async ({ url }) => {
  const campaign = url.searchParams.get('c') || 'unknown';
  const email = url.searchParams.get('e') || 'anonymous';

  await fetch(`${POSTHOG_HOST}/capture/`, {
    method: 'POST',
    headers: { 'Content-Type': 'application/json' },
    body: JSON.stringify({
      api_key: POSTHOG_KEY,
      event: 'newsletter_opened',
      distinct_id: email,
      properties: { campaign, source: 'email' },
    }),
  }).catch(() => {});

  return new Response(PIXEL, {
    headers: { 'Content-Type': 'image/gif', 'Cache-Control': 'no-store' },
  });
};

The click redirector does the same, plus one thing that matters: it only redirects to hosts we trust. A naive redirector that forwards anywhere is a phishing tool with your domain on it.

// src/pages/api/track/click.ts
const ALLOWED_HOSTS = ['getbeton.ai', 'www.getbeton.ai', 'inspector.getbeton.ai', 'github.com'];

export const GET: APIRoute = async ({ url }) => {
  const target = url.searchParams.get('u') || 'https://www.getbeton.ai';
  const campaign = url.searchParams.get('c') || 'unknown';
  const label = url.searchParams.get('l') || 'unknown';
  const email = url.searchParams.get('e') || 'anonymous';

  const parsed = new URL(target);
  if (!ALLOWED_HOSTS.some(h => parsed.hostname === h || parsed.hostname.endsWith(`.${h}`))) {
    return Response.redirect('https://www.getbeton.ai', 302); // refuse untrusted targets
  }

  await fetch(`${POSTHOG_HOST}/capture/`, {
    method: 'POST',
    headers: { 'Content-Type': 'application/json' },
    body: JSON.stringify({
      api_key: POSTHOG_KEY,
      event: 'newsletter_link_clicked',
      distinct_id: email,
      properties: { campaign, link_label: label, target_url: target },
    }),
  }).catch(() => {});

  return Response.redirect(target, 302);
};

That’s the whole tracking layer. Two endpoints, no SDK in the email, and the data lands in the same PostHog project as everything else.

All of it rolls up to a dedicated PostHog dashboard, separate from product analytics, so newsletter performance reads cleanly without digging through everything else.

Newsletter analytics in PostHog: a dedicated dashboard with opens per blog post, opens per recipient, and weekly and daily total-vs-unique open trends.

Where Claude fits

Claude doesn’t run this pipeline. It orchestrates it.

The goal is to post every day, and a daily cadence is more than one person wants to hand-crank. So Claude does the research, drafts to the voice guide, and moves a piece through the steps. For the rest of the team, it handles the parts that are easy to forget:

  • clean, ready-to-paste links dropped into Slack when something ships, so amplifying it is a copy-paste
  • cover and hero images generated on request
  • every frontmatter attribute populated, so nothing goes out half-tagged: the TL;DR, the FAQ, the description, the dates

The voice guide it drafts against is a real file in the repo. It encodes the rules we care about: short declarative sentences, no AI-slop adverbs, name the real tool and the real number, recommend a competitor when it actually fits, and a hard cap on em-dashes. A separate concision pass tightens social drafts, so posts get drafted to our voice, not a generic blog voice.

The work is organized as a content skillset. A teardown skill handles the OSS pricing series end to end, from picking a tool to drafting the analysis to generating the hero image. A newsletter skill handles the send: blog verification, image optimization, the tracked HTML, a test send, then the full send behind a preflight checklist. Each piece of content gets its own folder with the blog draft, the LinkedIn post, the Twitter thread, and the infographic, so distribution is part of the same artifact, not an afterthought.

The posting process, start to finish

  1. Draft the post to the voice guide, in its own content folder.
  2. Open a PR to the marketing site, get a green build, merge, deploy.
  3. On deploy, CI pings IndexNow with the URLs from the sitemap, and the sitemap is submitted to Google Search Console. Bing and Yandex recrawl in minutes; Google gets the nudge to come back on its own schedule.
  4. Run the newsletter preflight: confirm the post is live, the hero loads, the tracking pixel and click redirector both work.
  5. Send a test to myself, check the render, the from-name, the links.
  6. Send to the full audience with per-recipient tracking.
  7. Amplify: company post first, then a personal repost, then ask the team.
  8. Watch opens and clicks on the PostHog dashboard.

What’s next

The stack is the point of leverage, so the backlog is mostly things a platform would never let us add:

  • More embed types. Live Metabase and PostHog charts, YouTube and Loom videos, image galleries, all rendered inline instead of linked out.
  • AMP versions for faster loads on mobile and in-feed.
  • Tags, and SEO-indexable pages for tag combinations, so related posts cluster into their own crawlable surfaces.
  • Testing different page layouts to see what actually reads better, not what a theme picked for us.

See the source

The whole site is open on our GitHub: github.com/getbeton/beton-main-site. The tracking endpoints, the sidenote styles, the sitemap-lastmod trick, all of it. Clone it and you have the same technical implementation we run, no platform required.

The actual point

Doing a blog gets more fun when you can build the non-baseline parts yourself. Sidenotes didn’t move a metric. They made the posts nicer to read, they took an afternoon, and they only exist because the newsletter lives on our own stack instead of someone else’s. That trade, a bit more plumbing for full control, has paid for itself in SEO and in the small things we get to build along the way.

Spread the word and share this one with your marketing friend.

— Vlad

Originally posted on the Beton blog: https://www.getbeton.ai/blog/how-we-do-newsletter-at-beton/

I Finally Understood Elasticsearch After Thinking About Libraries

Imagine Elasticsearch as a huge digital library system, and Apache Lucene as the high-performance search engine library working behind the scenes. Elasticsearch is built on top of Lucene to provide distributed storage and extremely fast searching capabilities.

A library contains different corners or sections based on genres like cybersecurity, history, fiction, science, etc. Similarly, Elasticsearch contains indexes, where each index stores a collection of similar types of data.

Inside those sections, shelves contain books. In Elasticsearch, indexes contain documents, which are the actual units of stored data.

Now imagine a librarian helping visitors search for books. That librarian is similar to a node in Elasticsearch.

Technically, a node is a system/server running Elasticsearch that:

  • stores data
  • processes requests
  • searches data
  • communicates with other nodes

Logically:

  • Library system → Elasticsearch Cluster
  • Genre section → Index
  • Book → Document
  • Librarian/server → Node

Now imagine the library becomes extremely large and suddenly 50 visitors arrive at the same time. If only one librarian is responsible for searching every book requested by all 50 visitors, the process becomes very slow and inefficient.

To solve this problem, the library divides the books into smaller portions and distributes them across multiple librarians. In Elasticsearch, this concept is called sharding.

A shard is a smaller partition of an index. Instead of storing the entire index on one node:

  • Elasticsearch splits the data into shards
  • distributes those shards across multiple nodes
  • allows searches to happen in parallel

This improves:

  • performance
  • scalability
  • speed

Elasticsearch also creates replica shards, which are copies of primary shards. Replica shards help with:

  • fault tolerance
  • high availability
  • faster searching

So, shards can be distributed across multiple nodes, and all nodes work together as part of a cluster.

If one node contains information related to a search request, it communicates with other nodes internally to retrieve or share data. This node-to-node communication happens through the transport interface.

Elasticsearch nodes communicate using two interfaces:

1) HTTP Interface (Port 9200)

Used by:

  • clients
  • applications
  • Postman
  • curl
  • Kibana

to interact with Elasticsearch.

When a client sends a request:

  • the node receiving the request becomes the coordinating node
  • this node manages and routes the request internally

The coordinating node checks:

  • which shard contains the required data
  • which node contains that shard

Then, the request is sent to other nodes through the transport layer using TCP communication on port 9300.

Each node searches its own shards in parallel, and the results are returned back to the coordinating node, which merges the responses and sends the final result back to the client through the HTTP interface on port 9200.

Important:
Any node in Elasticsearch can act as a coordinating node.

2) Transport Interface (Port 9300)

Used internally by Elasticsearch nodes for:

  • node-to-node communication
  • shard coordination
  • replication
  • cluster communication
  • remote cluster communication

This communication happens using a high-performance binary TCP protocol.

There is also an important concept called binding address and publish address.

Binding Address

Defines where Elasticsearch listens for incoming traffic.

In simple words:

“Which IP + port should Elasticsearch accept connections on?”

When Elasticsearch starts, it tells the operating system:

“Send incoming traffic for this IP and port to me.”

Publish Address

Defines the address Elasticsearch shares with other nodes and clients.

In simple words:

“Which address should other nodes use to communicate with me?”

Now, how is Elasticsearch optimized for extremely fast searching?

Suppose you search:

"I love cybersecurity"

Elasticsearch does not scan every document one by one.

Instead, when new data is stored, Elasticsearch:

  • breaks text into smaller tokens/words
  • creates an inverted index

An inverted index stores mappings like:

Word Documents
love Doc1, Doc7
cybersecurity Doc1, Doc3
elasticsearch Doc2, Doc5

So instead of checking every document during a search, Elasticsearch directly jumps to the documents containing the required tokens.

This is one of the major reasons why Elasticsearch is extremely fast and scalable even when handling massive amounts of data.

🚀 My First Day in the Cloud: How I Built a Secured Digital Fortress in Azure

Many people think learning “Cloud Computing” means watching videos and memorizing words. But to actually become a real engineer, you have to get your hands dirty.

Today was my very first day building live systems inside Microsoft’s global network (Azure). I didn’t just build a cloud computer; I wrapped it in high-tech security gates to protect it from hackers.

Here is exactly what I did, told in plain, simple English.

🏰 The Analogy: Building a Secret Bank Vault

To understand what I built today, imagine you want to rent a secure vault inside a giant, high-tech fortress (the Cloud Data Center) to store important data.

[ Hacker / Stranger ] ────► ❌ Main Security Guard
│
[ Abhishek’s Laptop ] ────► ✅ Private Gatehouse
│
▼ (Bypassed Router Block via Secret Tunnel)
┌──────────────┐
│ Inside Vault │ ──► [ Your Ubuntu Linux Server ]
└──────────────┘
Here are the 4 steps I took to build it:

🚪 Step 1: Hiring the Ultimate Security Guard (MFA)

Before building my vault, I hired a digital security guard for my main account. I turned on a feature called Security Defaults.

What it means: Think of it like a guard at the front door who checks IDs. If anyone tries to guess my password, the guard stops them instantly and sends a verification code straight to my personal phone. This keeps the bad guys completely out of my account.

🧱 Step 2: Building a Private Gatehouse (The Firewall / NSG)Next, I built a private wall around my vault. In the tech world, this is called a Network Security Group (NSG). It acts like a smart gatehouse with a very specific rulebook.

The Rule: I told the gatehouse, “Only let someone in if they are coming from Abhishek’s exact home Wi-Fi address.” If a hacker from anywhere else in the world tries to knock on the door, the gatehouse completely ignores them.

💻 Step 3: Launching the Computer (The Virtual Machine)Once the security walls were up, I ordered a fresh Linux computer (called a Virtual Machine) to live inside my vault.

The Real-World Twist: At first, the local data centers in India were completely full because so many people were using them! Instead of giving up, I used the power of the cloud to instantly teleport my project across the ocean to Singapore, where there was plenty of room. It worked perfectly and cost me next to nothing from my free credits.

🛠️ Step 4: Solving a Hidden Problem (The Serial Console)This was the most exciting part of the day. When I tried to log into my new Singapore computer from my laptop, the connection kept freezing.

The Problem: It turns out my home internet router is highly restrictive. It blocks the standard pipe (called Port 22) used to connect to Linux computers.

The Fix: Instead of calling my internet provider to complain, I used a secret Azure back-door tool called the Serial Console. It allowed me to bypass my home router’s restriction and open a direct command-line window to my server right inside my Google Chrome browser tab!

💰 Saving Money: Turning off the Lights

Because the cloud operates on a “pay-for-what-you-use” model, keeping the computer running when I’m not using it would waste my free credits. To practice good discipline, I hit the Stop (Deallocate) button. This completely shuts down the physical computer in Singapore, dropping my hourly cost to exactly ₹0 until I turn it back on tomorrow.

🏆 Why this matters

Today, I proved that I can:

  1. Lock down a cloud environment so hackers can’t get in.
  2. Adapt and move my infrastructure across the globe when resources are full.
  3. Troubleshoot tricky network blocks like a real professional.

From a Phone in a “Cave” to Global Open Source: Why Google’s Gemma Models are a Lifeline for Budget Developers

This is a submission for the Gemma 4 Challenge: Write About Gemma 4

Before you dive into reading this blog, I want to share one thing with you straight from the heart. I didn’t just write this blog directly using an LLM or any AI tool. I sat down and drafted every single bit of this story in my notepad first. Then, I put it into AI and said,
Hey, look, don’t add extra artificial content. Just help me organize my thoughts and put this info correctly so I can share my real experience.

What’s Covered in This Blog

  • The Superpower of True Offline Coding

  • What Makes Gemma So Mind-Blowing?

  • Showcasing the Setup: Gemma Natively on My Phone!

  • Step-by-Step: Native Mobile Setup (Termux + spawn.h Fix)

  • My New Setup: Pure Focus Mode on Laptop

  • Step-by-Step: Compiling Gemma 4 on Ubuntu Linux

  • Final Thoughts & Acknowledgments

The Superpower of True Offline Coding

A lot of people ask me, Why do you care so much about running models offline when the cloud exists?

Because I remember my school days. I didn’t have a flashy, high-end laptop. I had a smartphone. I used Termux, Acode, and Anwriter to write code directly on my tiny screen. I still remember the absolute thrill of building my very first Tic-Tac-Toe game using pure HTML, CSS, and JavaScript, entirely offline.

Back then, the absolute biggest roadblock to studying and building things was documentation. If you wanted to learn or look up an error code, you needed an internet network to scroll through endless pages. If your network failed, your learning stopped.

But when you code or study completely offline with an AI tutor, a superpower unlocks: The noise disappears, and the barriers vanish.
Here is exactly what my brain looks like when the Wi-Fi is on versus when I cut the cord:

Image generated using Google Gemini

Now, that entire network problem is completely solved. Anyone can build anything and learn easily without spending a single penny on expensive internet plans or premium data subscriptions.

Historically, the problem with offline AI was hardware. Running a capable LLM required an expensive machine with massive amounts of VRAM. If you didn’t have the cash for a high-end gaming GPU, you were locked out.

Google just shattered that barrier. By releasing the Gemma model family under an open, commercially permissive Apache 2.0 license, they didn’t just give us a powerful model; they gave every single student around the globe access to frontier-level AI on regular, everyday devices. When I spin up a Gemma model to help me generate Go code on an older, struggling laptop and watch it handle the logic flawlessly, I genuinely feel like Tony Stark.

“TONY STARK BUILT THIS IN A CAVE! WITH A BOX OF SCRAPS!” > —— Me screaming at my old laptop when the local Go code compiles perfectly. 😂

What Makes Gemma So Mind Blowing?

Google engineered these lightweight, open-weights models specifically to bring massive reasoning capabilities straight to accessible hardware.

In plain English? It means the model doesn’t choke your device’s RAM. Instead of needing a massive corporate data center to process complex logic, it uses ultra-efficient token processing and smart memory layouts. This drastically shrinks the hardware footprint, allowing you to feed it prompts without crashing your device or causing your phone to overheat like a hot potato.

Whether you are running a lightweight version on a smartphone or a larger variant on a laptop, you are getting incredible coding and debugging help completely locally.

Showcasing the Setup: Gemma Running Natively on My Phone!

To show you that this isn’t just theory I actually live this setup. Check out this video of my actual screen while using it:

Seeing text stream into a mobile terminal screen like that when you are completely disconnected from the outside world is an unmatched feeling. It makes you realize that the barriers to education and software engineering are completely tearing down.

Just to be transparent with you guys on the dates: what you are seeing in that video above is my older mobile setup running the Gemma 2B model. I originally took this screen recording on May 16, 2026, after using the model heavily in Termux, and I just uploaded the clip to YouTube on May 20, 2026, to share it here. I wanted to show you this video because it proves just how smooth and massive the performance is even on a small phone. It makes you think—if a lightweight 2B model can do all this, how crazy is the new Gemma 4 going to be?

Recreating the Magic: Step-by-Step Native Mobile Setup

Want to turn your phone into an offline powerhouse running a model like Gemma 2B? Here are the actual commands to set up Termux and compile llama.cpp directly on Android:

Note: These images reflect the exact workflow from my mobile device. If the upstream repository receives new updates down the line, simply check their latest branch logs and run your build!

Step 1: Install Required Packages & System Headers

pkg update && pkg upgrade -y
pkg install -y git cmake clang make python ndk-sysroot wget

This installs all the essential tools required to compile llama.cpp natively inside Termux.

Step 2: Hitting the Nasty spawn.h Error

While compiling, I encountered a spawn.h error on Termux during the build process.

To fix this issue, I rolled back to a stable build tag and rebuilt the project.

# Roll back to a stable release build tag to bypass the spawn.h error
git checkout b4833

# Clear the old broken build artifacts
rm -rf build

# Reconfigure and trigger the compilation process using 4 threads
cmake -B build
cmake --build build -j4

This successfully compiled the project without errors on Android.

Step 3: Download and Run Your Offline Assistant

# Create a models directory inside llama.cpp
mkdir -p models
cd models

Download your preferred GGUF model and place it inside the models folder.

Example model used:
gemma-2-2b-it-Q4_K_M.gguf

Step 4: Run the Model

./build/bin/llama-server -m models/gemma-2-2b-it-Q4_K_M.gguf -c 512 -t 2 -ngl 0
  • m → Path to the model
  • c 512 → Context size
  • t 2 → Number of CPU threads
  • ngl 0 → Disable GPU layers (recommended for mobile)

Once launched, the model runs completely offline on your Android device.
Below is a screenshot of the model running in my Termux terminal.

My New Setup: Pure Focus Mode (Minus the Distractions)

Right now, I am so eager to test Gemma 4 on my phone next, but for serious coding work, I’ve deployed it on my laptop setup instead.

I have a dual-boot machine running Windows and Ubuntu Linux, and for serious focus sessions, I always boot straight into Ubuntu.

And look, the beauty of llama.cpp is that you can host a local server and run the model directly inside a clean, beautiful browser interface on your local machine. It is absolutely superb. I get to pull up my project files, ask my local model questions, and have zero internet tabs open to distract me. Bye-bye internet, hello focus mode!

Step-by-Step Guide: Compiling Gemma 4 on Ubuntu Linux for High Performance

Step 1: Update System and Install Core Build Tools

sudo apt update && sudo apt install -y git build-essential cmake

Step 2: Download and Compile llama.cpp

git clone https://github.com/ggml-org/llama.cpp.git

cd llama.cpp

cmake -B build
# Build project (e.g., -j4 for 4 cores, or -j$(nproc) for all cores)
cmake --build build -j

Step 3: Create Directories and Download Gemma 4 GGUF

# Create the models directory inside llama.cpp if it doesn't exist
mkdir -p models 

# Download your preferred Gemma 4 GGUF flavor from Hugging Face into the models folder

Step 4: Launch Gemma 4 (Choose Web UI or Terminal)

*Option A: Launch the Local *

./build/bin/llama-server -m models/gemma-4-E4B-it-Q3_K_S.gguf -c 4096 --host 127.0.0.1 --port 8080

Once that server is running, you just open your browser, head to http://127.0.0.1:8080, and you have a stunning interface running 100% locally from your machine!

Here is exactly what it looks like when I boot into Ubuntu and run the Web UI interface. Look at how seamlessly it breaks down complex topics like Deep-First Search (DFS) and Breadth-First Search (BFS):

Option B: Launch Interactive Chat in Terminal

./build/bin/llama-cli -m models/gemma-4-E4B-it-Q3_K_S.gguf -p "Hi" -env

Here is a live screenshot of the terminal variant spinning up on my desktop. You can see htop running on the right side, showing how lightweight and light on resources the execution is on my CPU:

Looking at this laptop setup makes me feel incredibly grateful. I have to give a massive shoutout to Google. A while back, the high-quality technical information and support I got from the Gemma ecosystem actually helped me write high-value blogs on Dev.to. Those blogs gained traction, helped me clear technical hurdles, and ultimately allowed me to make the money I needed to finally step up from just a phone and get this laptop.

Final Thoughts: Thank You, Google

From tinkering with basic text editors in my school days to deploying advanced Go routines on an old, hardware-challenged laptop today, local execution has completely shaped my trajectory as a developer.

AI shouldn’t just be a luxury for those who can afford massive monthly cloud subscriptions or elite hardware. By putting open-weights, highly compressed powerhouses like the Gemma family directly into our hands, Google has leveled the playing field for student developers everywhere who are suffering through hardware or internet constraints.

Thank you, Google, for making things easy for me from my childhood all the way to right now. You always clear the path for devs who are trying to learn and grow.

Now, go clone the repository, download the weights, shut off your internet, and go build something awesome in your own cave!

Before I close this blog completely, I want to say one last thing. If anything I wrote here caused any misunderstanding, or if my blog made any person feel sad or unhappy, I am really, truly sorry. That was never my intention. I just wanted to share the happiness and excitement of a kid coding from his phone and moving up to a laptop. Thank you so much for reading, and good luck with your own builds!

Building a Privacy-First AI App for Patient & Caregiver Doctor Visit Notes

Hi DEV Community,

I wanted to share a project I’ve been working on called AI Doctor Notes. It’s an app built specifically to solve a common problem: walking out of a doctor’s visit and completely forgetting the instructions, medication steps, or follow-up details.

Unlike generic voice-recording or transcription tools, this app focuses heavily on user privacy and specialized workflows tailored for patients and family caregivers.

Key Features:

  • Pre-visit preparation: Track symptoms and organize lists of questions before the appointment.
  • Smart summaries: Securely record details during the visit and instantly generate clear, structured summaries of actual doctor instructions.
  • Caregiver sharing: Easily share visit recaps with family members or other relatives managing a loved one’s health.

We focused heavily on keeping the user experience as simple and clean as possible since medical visits are already high-stress situations.

I’d love to hear any feedback you have on the setup or features!

Check out the site here: https://aidoctornotes.app/

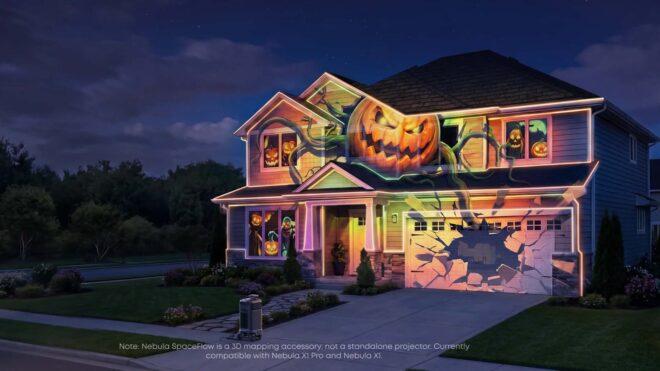
Anker, yeni ürünüyle Nebula X1 ailesine 3D projeksiyon haritalama özelliği ekliyor

Anker, yeni ürünüyle Nebula X1 ailesine 3D projeksiyon haritalama özelliği ekliyor

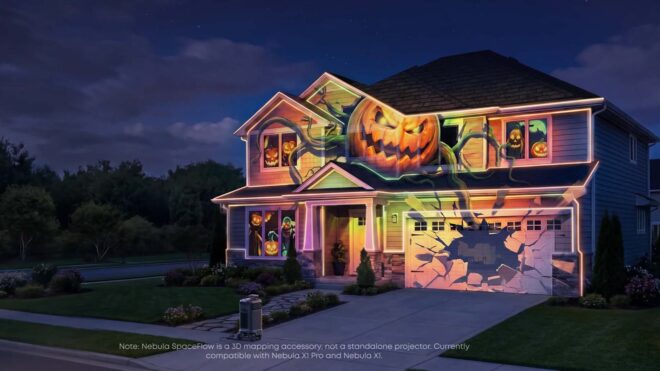
Anker, yeni ürünüyle Nebula X1 ailesine 3D projeksiyon haritalama özelliği ekliyorAnker, “SpaceFlow” adını verdiği yeni ürünüyle Nebula X1 projektör ailesine 3D projeksiyon haritalama özelliği ekliyor. 399 dolardan satışa sunulan ürün, spesifik olarak Nebula X1 ile Nebula X1 Pro’nun üstüne konumlandırılıyor ve baktığı yüzeyin şeklini derinliğiyle birlikte analiz ederek farklı tasarımlar yansıtabiliyor. Ortamdaki kapıları, pencereleri, mobilyaları ve diğer objeleri tespit eden ve projeksiyonu buna göre özelleştiren SpaceFlow, 100’den fazla hazır tasarımla geliyor. Yapay zeka altyapısı sayesinde kişilerin aklından geçen tasarımları da üreterek yansıtabilen ürünün, kampanya dönemi bittikten sonra 799 dolara satılacağı aktarılıyor.

Anker, yeni ürünüyle Nebula X1 ailesine 3D projeksiyon haritalama özelliği ekliyor yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.