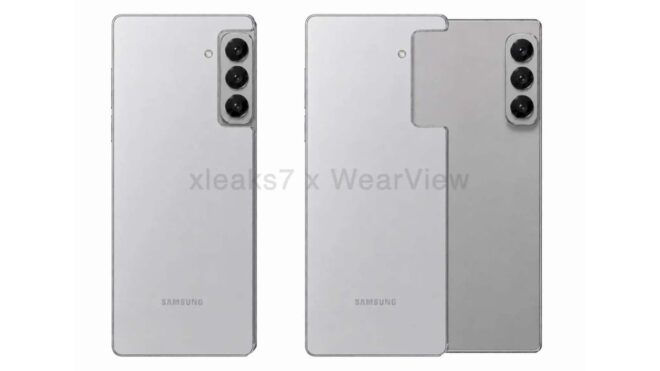
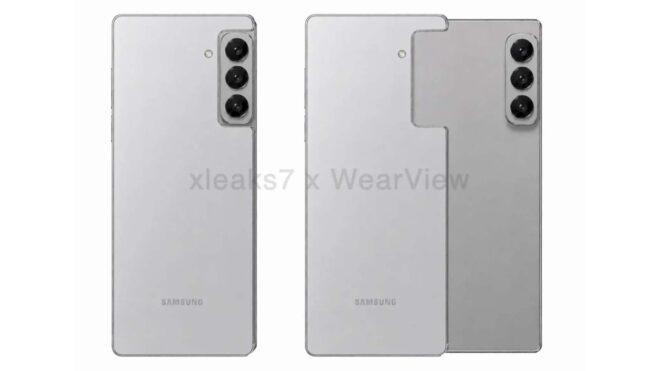
Samsung, yana doğru genişleyen bir telefon için patent aldı

Samsung, yana doğru genişleyen bir telefon için patent aldı

Samsung, yana doğru genişleyen bir telefon için patent aldıSamsung, sektöre öncülük ettiği katlanabilir telefonlar sonrasında pazara genişleyen akıllı telefonlar da çıkarmak istiyor. Bu konuda uzun zamandır çalışmalar yapan şirket, kısa süre önce yana doğru genişleyen bir telefon modeli için patent aldı. Aynı zamanda yukarıya doğru genişleyen cihazlar üzerinde de çalışan teknoloji devi, kullanıcılara rahat taşınabilecek devasa ekranlı telefonlar sunmak istiyor. Bu alanda ilk ticari adımı 2027 ya da 2028’de atması beklenen Samsung, önümüzdeki aylarda geniş yapılı bir katlanabilir telefon modeli de tanıtacak.

Samsung, yana doğru genişleyen bir telefon için patent aldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Building a Global Access Layer that Ignores Geo-Censorship and Favors User Experience

As a frontend engineer, I’ve often found myself wrestling with the complexities of global access. When I worked on a digital products platform targeting creators in emerging markets like Ghana, Nigeria, and Pakistan, I hit a wall. Our users were constantly complaining about the slow load times, frequent disconnections, and impossible-to-debug issues that plagued their experience. What’s worse, they couldn’t even use the platforms we took for granted in the West – PayPal, Google Sheets, or even GitHub.

The Problem We Were Actually Solving

We were building a platform that could sell digital products, but our infrastructure was essentially blocking the very people we wanted to reach. We were optimizing for the 1% of our users who lived in the developed world, while ignoring the 99% who needed access to basic tools. Our infrastructure was built on top of AWS and was heavily reliant on global CDNs, which were great for the majority of our users but disastrous for those living in countries with overzealous geo-censorship.

What We Tried First (And Why It Failed)

We initially tried to work around these issues by whitelisting specific IP ranges and configuring our load balancer to direct traffic to the nearest data center. But it was a short-term fix that only made things worse in the long run. Our developers spent hours tweaking IP ranges, only to realize that the problem would shift to another part of the world. Moreover, it wasn’t a scalable solution, as it required constant monitoring and updates to keep up with the ever-changing landscape of geo-censorship.

The Architecture Decision

So, we decided to take a different approach. We set up a network of edge servers and caching layers that bypassed the main AWS infrastructure altogether. We also implemented a sophisticated network proxy that could automatically redirect traffic from censored regions to less restrictive ones. The edge servers allowed us to cache frequently accessed content, reducing the load on our main infrastructure and making it easier to handle the varying response times and packet loss associated with international traffic.

What The Numbers Said After

The results were nothing short of spectacular. Load times dropped by an average of 30% across the board, with the biggest gains coming from Ghana and Nigeria. Connection failures plummeted by 75%, and our users could finally use the digital tools that we’d taken for granted. We also saw an uptick in engagement metrics like time spent on app and active user count.

What I Would Do Differently

In hindsight, I would prioritize creating a more robust logging and monitoring system to help us troubleshoot issues faster. Geo-censorship can be unpredictable and sometimes seems to change overnight. But more importantly, I would have pushed for a more comprehensive approach to internationalization from day one, considering not just the tech side but also the regulatory and business implications of serving a global market.

Building global access is about more than just technology – it’s about creating a seamless experience for users across the world, regardless of their location or the obstacles they face. Our solution may not be perfect, but it’s taught me that sometimes, the most effective solutions come from rethinking the problem altogether.

MacOS Workers, or how I built my own Mac cloud

mac minis on rack

In Part 1 I laid out the Jenkins-as-a-Code setup — JCasC, Job DSL, ephemeral workers, Packer images, all of it. And I said macOS workers were their own special kind of hell that deserved a separate post. This is that post.

If you’ve never had to run macOS builds in CI, the short version is: everything that’s easy on Linux is hard on macOS, and everything that’s hard on Linux is also hard on macOS but in a different way. Apple’s licensing rules, the fact that you can’t just spin up a Mac in AWS the same way you spin up Ubuntu, the keychain weirdness, the signing tooling, the Xcode versions — all of it adds up. And the answer at most companies is “we have a few Mac minis under someone’s desk that everybody SSHes into”. Which works until it doesn’t.

I wanted the same story I had for Linux and Windows — born for one build, destroyed after, byte-identical state every time — but on macOS. Took me a while to get there. Here’s what actually worked.

mac minis on rack

Why macOS is hard in the first place

Before getting into solutions, it helps to name the problems, because they explain why the architecture ends up looking weird.

1. The cloud Mac story is awkward. EC2 Mac instances do exist. They’re real Mac hardware living in AWS data centers, and you can absolutely rent one. The catch is the shape: they’re dedicated hosts with a 24-hour minimum allocation (Apple’s licensing requirement, not AWS being weird), and the per-hour pricing is brutal compared to Linux. For ephemeral workers that live for 30 minutes per build, paying for 24 hours per allocation makes the per-build economics painful. Cloud Mac exists; it’s just shaped wrong for high-volume ephemeral CI.

2. Apple’s EULA only allows macOS to run on Apple hardware. Which means: no, you cannot legally virtualize macOS on a Linux box. You need real Mac hardware somewhere in the loop. Either you own it, you rent it, or you use a provider that owns it for you.

3. macOS virtualization is its own ecosystem. On Intel Macs the answer used to be VMware (vSphere or Fusion) or VirtualBox. On Apple Silicon, neither of those works the same way — Apple’s Virtualization.framework is what everything is built on top of now, and the tooling around it is much younger.

4. Signing and notarization need credentials that don’t love being ephemeral. Apple Developer ID certificates, app-specific passwords, the keychain — none of these were designed with “fresh VM every build” in mind. They were designed for “a developer’s laptop”. Making them work in CI is a whole sub-problem.

5. macOS images are huge. A baked Packer image with Xcode is 60–80 GB. Spinning that up from cold storage is slow. Caching matters way more than it does for Linux.

Once you understand those five things, the architecture choices below stop looking weird.

What I evaluated and didn’t pick

The macOS CI space is small enough that I can name everything serious in it. Before settling on the approaches below, I did a real evaluation of the commercial options — they exist for a reason, they’re not bad, they just didn’t fit our cost shape.

  • Veertu Anka — the most mature paid platform specifically for macOS CI virtualization. Does roughly what Tart does, with a polished management UI, enterprise support, and a richer feature set. Licensing is per-host or per-VM, and at fleet sizes that matter for a growing engineering org it adds up quickly. If you have the budget and want vendor support, it’s a credible choice.
  • MacStadium — a managed-Mac hosting provider. You rent physical Macs in their data center, optionally bundled with their own orchestration layer (Orka). Solves the “I don’t want to rack Macs myself” problem cleanly. Pricing is per-host per-month — makes sense for a large, steady-state fleet, less so if your volume is spiky or you already have Macs you want to use.
  • AWS EC2 Mac instances — covered above. Useful for very low-volume work where the operational simplicity wins; bad for high-volume ephemeral CI because of the 24-hour minimum.
  • GitHub Actions managed macOS runners — fine for OSS projects and small teams. At any real volume the per-minute pricing gets uncomfortable, and you can’t customize the image — which matters as soon as your build needs anything beyond stock Xcode.

The thing that pushed me toward Tart is the licensing, more than the technology. Tart’s commercial license is structured so that small-scale and personal use is genuinely free, and the paid tier doesn’t scale linearly with fleet size the way per-host licensing does on Anka. For our build volume, that math just works — and at smaller scales (one or two Macs) you pay nothing at all. That’s hard to beat.

And as of April 2026 — when Cirrus Labs joined OpenAI — that licensing got even better: Tart, Vetu and Orchard have been relicensed under a more permissive license and the commercial fees were dropped entirely. If you were on the fence before, the math is even simpler now.

The other thing the Cirrus Labs team gets right is the coherent toolchain around Tart. Tart for VMs, Orchard for fleet orchestration, and the Cirrus CLI for running CI tasks locally — the same .cirrus.yml configs that would run on the the Cirrus CLI runs the same YAML task definitions locally against a Tart VM. The local-reproduction story alone has saved me hours of “wait, why does this fail only in CI” debugging. It’s one of those toolchains where each piece is useful on its own, but the combination is what makes the whole thing pleasant to live with.

Three ways I ended up provisioning macOS workers

There’s no single tool that does everything I needed. So the answer ended up being: three different provisioners for three different shapes of Mac fleet. All three follow the same pattern from Part 1 — a Jenkins job invokes the provisioner, the worker comes up from a Packer-baked image, runs the build, gets destroyed — but the layer underneath is different.

Option A — Tart, for Apple Silicon

Tart is a small open-source CLI built by the Cirrus Labs folks that wraps Apple’s Virtualization.framework. You give it an OCI-compatible image (basically a tarball with the macOS VM disk), it spins up a VM on Apple Silicon hardware in seconds. The image is reusable, you can layer on top of it, and it’s the closest thing to “docker, but for macOS VMs” that exists today.

How it fits:

  • The Mac hardware itself is a fleet of Mac minis (or Mac Studios) — physical machines we own or rent, sitting in a rack.
  • Each Mac has Tart installed at the host level.
  • A dedicated Jenkins job picks an available host, runs tart clone from a known image tag, runs tart run, registers the new VM as a Jenkins agent, and after the build runs tart delete to clean up.
  • Packer has a tart-cli source that builds those images. We bake everything — Xcode, Homebrew, signing tools, languages — into the image at build time.

The good: spin-up is genuinely fast. From tart clone to “agent connected to Jenkins” is under a minute. The image is a snapshot, so every build truly starts from byte-identical state — same as the Linux pod story.

The not-so-good: you still need to own or rent the Mac hardware. You’re not escaping the “real Apple machines in a rack” problem; you’re just orchestrating them better. And the Tart ecosystem is young — expect to write some glue.

Option B — vSphere / VCSA, for the older Intel fleet

Before Apple Silicon, the Mac fleet was a stack of Intel Mac minis hooked into a vSphere cluster. macOS VMs were managed as ESXi guests, exactly like any other VMware VM.

How it fits:

  • Each Mac mini runs ESXi (which is the one OS allowed to be installed on a Mac and host macOS guests, per Apple’s licensing).
  • A “golden” macOS VM template lives in vSphere, baked by Packer’s vSphere ISO builder.
  • A dedicated Jenkins job runs Terraform with the vSphere provider to clone the template (linked clones are faster), bring up the VM, configure it as an agent, and tear it down after.

This setup predates the Apple Silicon transition and it still works — but it’s the heaviest of the three. Linked clones speed up the spawn time, but it’s still slower than Tart, and vSphere itself is a chunky thing to operate.

I’d describe this as the “responsible enterprise” path. If you already have VMware in your org, it slots in cleanly. If you don’t, you’d never start here in 2026.

Option C — Orchard, for pooled / remote Macs

Orchard is also from Cirrus Labs — same family as Tart. The pitch is: instead of you orchestrating individual Mac hosts, Orchard runs as a controller that manages a pool of Mac workers, and you ask it for a VM via an API. It handles scheduling, queuing, and lifecycle.

How it fits:

  • Useful when you have a pool of Macs (could be your own, could be from a managed provider like MacStadium or a similar cloud-Mac vendor), and you don’t want each Jenkins job to know which physical machine to pick.
  • A dedicated Jenkins job calls Orchard’s API to request a VM with a specific image and resource profile, gets a VM back, runs the build, releases it.
  • Useful when capacity is the constraint. You can have 20 builds queued and 5 Macs available, and Orchard does the scheduling for you.

The good: clean separation of concerns. The Jenkins job doesn’t care where the Mac is physically.

The not-so-good: another piece of infrastructure to run. Worth it only at a certain fleet size — for a tiny pool of 2–3 Macs, raw Tart is simpler.

tart vs vSphere vs orchard

What gets baked into the Packer image

Same story as Linux and Windows — we bake everything we can into the image, so the build itself doesn’t pay setup time. The macOS Packer image is the heaviest one in the fleet by a wide margin.

What goes into a typical macOS worker image:

  • OS: a specific macOS version (we pin to specific point releases — Xcode compatibility is brittle, you don’t want to be on “whatever’s latest”).
  • Xcode: a specific Xcode version, plus the command line tools. Xcode alone is 30+ GB.
  • Homebrew + packages: all the brewed tools the build needs, pre-installed and pre-warmed.
  • Language runtimes: Node, Python, Ruby — pinned to specific versions matching what production uses.
  • Build tools: CMake, Ninja, Conan, whatever the project uses.
  • Signing tools: codesign, notarytool, xcrun — these come with Xcode but worth confirming they’re available.
  • Pre-warmed caches: Conan cache, npm cache, brew cache — anything that would otherwise need to be downloaded on first build.

The Packer template itself is short — most of the heavy lifting is in a chain of shell scripts that run after the base macOS install:

source "tart-cli" "macos" {
  vm_base_name = "ghcr.io/cirruslabs/macos-monterey-base:latest"
  vm_name      = "macos-ci-${var.image_version}"
  cpu_count    = 4
  memory_gb    = 8
  disk_size_gb = 120
  ssh_username = "admin"
  ssh_password = "admin"
}

build {
  sources = ["source.tart-cli.macos"]

  provisioner "shell" {
    scripts = [
      "scripts/post-install.sh",
      "scripts/brew-setup.sh",
      "scripts/xcode.sh",
      "scripts/nodejs-setup.sh",
      "scripts/deps.sh",
      "scripts/prewarm-caches.sh",
    ]
  }
}

The whole template is maybe 30 lines. The interesting stuff lives in the shell scripts, which are versioned in the same repo and reviewed in the same PRs as everything else.

A baked image is around 60–80 GB. Storage matters. So does the cache locality — if every Mac in the fleet has to pull a fresh 70 GB image from the registry over the network on first use, you’ve got problems. We pre-cache base images on each host out of band.

The signing-on-ephemeral-VMs problem

This is the one part of the macOS story that genuinely deserves its own section, because it’s where most of the time disappears when you first set this up.

Apple’s signing pipeline assumes a developer machine with a persistent keychain. You unlock your keychain once, you sign apps for the rest of the day, life is good. In CI with ephemeral VMs, none of that holds. Each VM is brand new. There’s no pre-existing keychain. There’s no unlocked state. There’s no “saved password”.

Here’s the contract we ended up with — generic enough that it’ll work for most teams:

  1. Apple Developer ID certificate + private key live in a secrets manager (AWS Secrets Manager, Vault, whatever you use). Never in the image. Never in git.
  2. At job start, the Jenkins pipeline pulls the certificate + key from the secrets manager and imports them into a temporary keychain it creates on the VM.
  3. The temporary keychain gets a random password generated for that build, used for the duration of the build, and discarded with the VM.
  4. Notarization credentials (app-specific password or notarytool API key) come from the same secrets manager and are used directly — they don’t need a keychain.
  5. When the build finishes and the VM dies, the keychain dies with it. Same lifecycle as the rest of the worker.

A simplified version of the keychain-bootstrap script looks like this:

#!/usr/bin/env bash
set -euo pipefail

KEYCHAIN="ci-build.keychain"
KEYCHAIN_PASSWORD="$(openssl rand -base64 24)"

# Create a brand-new keychain just for this build.
security create-keychain -p "$KEYCHAIN_PASSWORD" "$KEYCHAIN"
security set-keychain-settings -lut 21600 "$KEYCHAIN"
security unlock-keychain -p "$KEYCHAIN_PASSWORD" "$KEYCHAIN"

# Add it to the search list so codesign can find it.
security list-keychains -d user -s "$KEYCHAIN" $(security list-keychains -d user | tr -d '"')

# Import the cert + key from the secrets-manager-provided files.
security import "$DEVELOPER_ID_CERT" -k "$KEYCHAIN" -P "$CERT_PASSWORD" -T /usr/bin/codesign

# Grant codesign permission to use the key without prompting.
security set-key-partition-list -S apple-tool:,apple: -s -k "$KEYCHAIN_PASSWORD" "$KEYCHAIN" >/dev/null

Things that will bite you if you don’t know them:

  • set-key-partition-list is mandatory on modern macOS. Without it, codesign prompts for a password from the UI and the build hangs forever.
  • The keychain must be in the search list. A keychain that exists but isn’t searched is invisible to codesign.
  • Notarization is async. notarytool submit --wait does block until done, but be ready for it to take several minutes. Plan for it in build timeouts.
  • Stapling fails silently if you forget it. Notarization succeeds, the artifact ships, end users get a Gatekeeper warning anyway because the ticket isn’t stapled. xcrun stapler staple <artifact> after notarization succeeds.

It’s not deep magic, but every team I’ve seen do macOS CI for the first time burns a week on this. So: budget for that week, and write the keychain bootstrap script before you write the rest of the pipeline.

Trade-offs — which one should you pick?

Honest answer: probably more than one, depending on what fleet you’ve inherited. But if I were starting from a blank slate today, in 2026:

If you have… Pick
A small pool of Apple Silicon Macs you own Tart, directly. Free at this scale, simple, fast, no extra infra.
A larger fleet of Apple Silicon Macs, mixed ownership / remote Tart + Orchard. Same licensing story, but with proper scheduling for a pool.
An existing vSphere installation and Intel Macs vSphere / VCSA path. Keep what works until it stops working.
Need enterprise support + budget isn’t tight Veertu Anka. Paid, polished, vendor backs you up.
Don’t want to rack Macs, want a managed fleet MacStadium (with their orchestration or your own).
No physical Macs, very low volume EC2 Mac. The 24-hour minimum hurts; the operational simplicity sometimes wins anyway.
Open-source project, low volume GitHub-hosted macOS runners. Free for OSS, no infra to manage.
No physical Macs, high volume MacStadium or similar provider. EC2 Mac economics don’t work here.

The thing I’d push back on is “let’s just use Mac minis under someone’s desk”. That’s fine for one team. It’s not fine when it’s the bottleneck for every iOS release.

What I’m still figuring out

A few open problems I haven’t fully solved:

  • Image freshness. Xcode updates land every few weeks. Keeping the Packer image current without breaking everyone’s builds is a constant low-grade tax. We rebuild images on a schedule and pin every job to a specific image version, but the rebuild itself is a 90-minute job and it’s not free.
  • Cost. Mac hardware is expensive whether you own it or rent it. The economics only work above a certain build volume; below that, the per-build cost is uncomfortable.
  • Apple Silicon transition for older code. Some of our older C++ code still has Intel-only dependencies that haven’t been ported. We run those builds on the vSphere/Intel fleet, but that fleet is shrinking, and “rewrite all the legacy build deps for arm64” is its own project.
  • Notarization queue times. Apple’s notarization service has occasional bad days where submissions take 20+ minutes. There’s nothing we can do about it on our side, but it does mean macOS builds have a longer tail than the others.

Closing thought

The macOS CI story doesn’t have a single right answer. There’s no equivalent of “just run a pod in EKS”. You’re going to end up with physical hardware in the loop, a hypervisor (probably more than one), and a signing problem that doesn’t exist on any other platform. The trick is to treat it the same way as everything else: ephemeral, image-baked, orchestrated by a job in git, secrets from a vault. Once the contract is the same as Linux and Windows, the macOS hell becomes a tractable hell.

Next up — Part 3, where I’ll talk about running spot instances as GitHub Actions runners and the cost story behind moving some of this work off Jenkins entirely. Different model, different trade-offs, similar headaches.

Appendix — tools mentioned in this post

Cirrus Labs toolchain (the one I ended up on)

  • Tart — macOS VMs on Apple Silicon via Virtualization.framework. Free for small-scale; licensing.
  • Orchard — controller for pooled Tart hosts.
  • Cirrus CLI — run CI tasks locally against a Tart VM; same .cirrus.yml as Cirrus CI’s SaaS.
  • Packer Tart plugin — Packer builder for Tart images.

Commercial alternatives I evaluated

Other

This is Part 2 of My CI/CD Odyssey. If you want to be pinged when Part 3 drops, follow me here on dev.to. And if you’re doing macOS CI differently — I’d love to hear about it in the comments.

Stop manually stripping Prisma inputs. Generate Zod schemas & guard your DB automatically.

If you use Prisma, you already know it’s a fantastic ORM with excellent developer experience. But there’s a common friction point almost all of us hit when building real-world APIs: input validation and sanitization.

Prisma is strict. If a user passes an unknown field in a .create() or .update() payload (like an injected isAdmin: true), Prisma throws an error. So what do you do? You end up writing tedious mapping functions, picking fields manually, or writing massive Zod schemas by hand to validate and strip out the junk before it reaches Prisma.

What if your Prisma schema could just… do it all for you?

Enter Prisma Guard 🛡️.

What is Prisma Guard?

Prisma Guard is the ultimate Prisma companion designed to bridge the gap between database models and API validation. It does two main things:

  1. Runtime Protection (The Guard): A Prisma Client extension that silently strips unknown fields from your queries at runtime.
  2. Schema Generation (The Magic): Automatically transforms your .prisma models into robust, decorated Zod schemas with complete type-safety.

It’s completely zero-config out of the box (it even manages your .gitignore and Prettier formatting for generated files), but offers immense power for those who need custom validation logic.

✌️ Two Ways to Use It

Depending on your needs, you can use Prisma Guard in two modes.

Mode 1: Runtime Protection Only (The Quick Fix)

If you just want to stop Prisma from throwing errors when random fields are passed from the frontend, just add the extension to your client:

import { PrismaClient } from "@prisma/client";
import { prismaGuard } from "@explita/prisma-guard";

const prisma = new PrismaClient().$extends(prismaGuard());

// Any extra fields passed to 'data' will be silently stripped
await prisma.user.create({
  data: {
    email: "[email protected]",
    poisonField: "will be removed", // Poof! Gone.
  },
});

Mode 2: Full Validation & Schema Generation (Recommended)

This is where the real magic happens. By running npx prisma-guard, it reads your Prisma schema and generates perfect Zod schemas.

Your Prisma Schema:

model User {
  id        String   @id @default(cuid())
  email     String   @unique
  password  String
  createdAt DateTime @default(now())
}

What you get:

export const UserCreateSchema = z.object({
  email: z.string().trim().min(1, { message: "This field is required" }),
  password: z.string().trim().min(1),
  // id and createdAt are managed by Prisma defaults or omitted entirely depending on your config!
});

💎 Advanced Type Ergonomics & Dual Schemas

One of the biggest headaches with schema generation is that a “public” API schema shouldn’t include sensitive internal database fields (like secretApiKey or tenantId).

Prisma Guard handles this beautifully by generating Dual Schemas for every model:

  1. Public Schemas (UserCreateSchema): Respects your omission rules. Perfect for API request validation.
  2. Scalar Schemas (UserCreateScalarSchema): Includes every database field. Perfect for internal services and database operations.

It also exports a suite of ergonomic TypeScript types (UserCreate, UserUpdate, UserCreateRequired) so your service layers are always perfectly typed.

🎨 The Power of Decorators (and the v proxy)

Sometimes z.string() isn’t enough. You need .email(), .min(8), or custom refinement logic. Prisma Guard lets you define this cleanly using triple-slash comments (///).

Instead of polluting your Prisma schema with massive strings of Zod code, Prisma Guard introduces the v proxy in a prisma-guard.config.js file:

// prisma-guard.config.js
import { defineConfig, v } from "@explita/prisma-guard";

export default defineConfig({
  decorators: {
    // Chain validations onto the inferred Prisma type
    email: v.chain.email().trim().toLowerCase(),

    // Completely override a type
    strongPassword: v.string().min(12).regex(/[A-Z]/),
  },
});

Then, you just use them in your Prisma schema!

model User {
  id       String @id

  /// @zod.use(email)
  email    String

  /// @zod.use(strongPassword)
  password String
}

IDE Superpowers 🪄

No one likes typing out decorators from memory. Prisma Guard includes an incredible npx prisma-guard metadata --vscode command that automatically installs VS Code snippets for every Zod method. You literally get autocompletion inside your .prisma files!

⚡ Blazing Fast Performance

You might be thinking: “Doesn’t a runtime guard slow down my queries?”

The answer is no. The runtime guard is designed for ultra-low latency. It uses strict $O(n)$ complexity (looping only over predefined schema fields instead of arbitrary user input), memoized whitelists, and hot-path early exits.

In benchmarks of 100,000 recursive sanitization iterations on a complex payload:

  • Total duration: 221.26ms
  • Average per query: 2.21 microseconds (0.0022ms)

If your database query takes 10-50ms, adding 0.0022ms introduces virtually 0% overhead.

🚀 Get Started in 2 Minutes

Stop wasting time manually maintaining Zod schemas that drift out of sync with your database.

  1. Install the package:
npm install @explita/prisma-guard
  1. Initialize your config:
npx prisma-guard init
  1. Generate the magic:
npx prisma-guard

Check out the full documentation, advanced relation handling, and custom schema generation features on our GitHub Repository.

If Prisma Guard saves you time, I’d deeply appreciate a ⭐ on GitHub! Let me know what you think in the comments below. Happy coding! 🚀

Stop guessing your AI API bill: a quick guide to token cost math

You can ship an LLM feature in an afternoon. Figuring out what it costs to run usually happens later, when the invoice shows up and someone asks why. A few minutes of token math up front avoids most of that.

Here is how the pricing works and how to estimate it.

Tokens, not words

Providers bill per token, not per word or per request. A token is about 4 characters of English, so “Hello world” is roughly 3 tokens and 750 words lands near 1,000 tokens. Input and output are billed separately, and output is almost always the pricier side.

GPT-4o is $2.50 per million input tokens and $10.00 per million output tokens. That 4x gap is the part people underestimate once responses get long.

The formula

Per request, the cost is:

cost = (input_tokens / 1M * input_price) + (output_tokens / 1M * output_price)

Multiply by monthly volume and you have the bill.

Take a support bot: 800 input tokens (system prompt plus the user message) and 400 output tokens per reply, 50,000 requests a month, on GPT-4o.

  • Input: 800 x 50,000 = 40M tokens, so $100
  • Output: 400 x 50,000 = 20M tokens, so $200
  • Total: $300/month

Run the same workload on GPT-4.1 Mini and the number drops by roughly 10x. That one comparison is often what decides the model.

Where it goes wrong

Three things bite people repeatedly:

  1. The system prompt counts every time. A 600-token system prompt isn’t a one-time cost. You pay for it on every single request. Trim it.
  2. Output is the expensive half. Setting max_tokens sensibly is the cheapest optimization there is.
  3. Words lie. Code, JSON, and non-English text tokenize very differently from prose. Count real tokens, don’t eyeball word counts.

Tools that do the math

I got tired of redoing this per model, so I’ve been using Vortenza‘s free AI calculators. The OpenAI API Cost Calculator lets you pick a model and drop in your tokens and monthly volume. There’s a Claude API Cost Calculator for Anthropic models, and an AI Token Counter for when you want the actual token count of an input instead of a guess. No signup, runs in the browser.

The calculator isn’t really the point, though. The point is doing the estimate while you’re still designing the feature. Cost is a design constraint, same as latency. Treat it like one and the invoice stops being a surprise.

Making Dynamic MDX Blogs Work with OpenNext on Cloudflare Workers

Before and after diagram showing an MDX blog moving from runtime filesystem reads to a build-time registry for OpenNext on Cloudflare Workers

I ran into a small but annoying problem while deploying a Next.js MDX blog to Cloudflare Workers with OpenNext.

The blog worked locally. The build passed. OpenNext even listed the blog routes during the build.

Then I opened the deployed site, and the blog page was empty.

The issue was not MDX. It was not frontmatter. It was not a missing route. The real problem was that my blog code was still thinking like a normal Node.js app, while Cloudflare Workers runs from a bundled Worker output.

The Short Version

If your MDX blog works in next dev but shows empty pages or missing posts on Cloudflare Workers, check if you read blog files with node:fs at request time.

This is the safer pattern:

  • Keep writing posts as .mdx files.
  • Parse the files during the build.
  • Generate a small TypeScript file with post metadata.
  • Generate another TypeScript file that statically imports every MDX post.
  • Render posts from that generated registry in production.

That way the Worker does not need to scan your content/blog folder at runtime.

Before and after diagram showing an MDX blog moving from runtime filesystem reads to a build-time registry for OpenNext on Cloudflare Workers

What Broke

The old setup looked something like this:

import fs from "node:fs";
import path from "node:path";
import matter from "gray-matter";

const postsDir = path.join(process.cwd(), "content", "blog");

export function getAllPosts() {
  return fs.readdirSync(postsDir).map((file) => {
    const raw = fs.readFileSync(path.join(postsDir, file), "utf8");
    const { data } = matter(raw);

    return {
      slug: file.replace(/.mdx$/, ""),
      title: data.title,
      description: data.description,
    };
  });
}

This feels fine in local development because the source files are right there on disk.

But after OpenNext builds the app for Cloudflare Workers, the app is running from a Worker bundle. Cloudflare does support node:fs through a virtual filesystem, but that filesystem is not the same as having your project folder mounted in production. Files inside the Worker bundle are readable under /bundle, and /tmp is temporary for a request.

So I stopped treating the source folder as runtime data.

The Fix

I moved blog discovery to build time.

The build step reads the MDX files once, parses the frontmatter, and writes generated TypeScript files that the app can import normally.

The mental model is simple:

Authoring:
  content/blog/*.mdx

Build:
  read MDX files
  parse frontmatter
  generate metadata
  generate static imports

Runtime:
  import generated modules
  render the matching MDX component

This keeps the nice file-based writing flow, but removes runtime filesystem reads from the deployed Worker.

Step 1: Generate Blog Metadata

I use a script before the build. It reads the .mdx files and creates metadata for the blog index, sitemap, RSS feed, and page metadata.

// scripts/generate-blog-data.mjs
import fs from "node:fs";
import path from "node:path";
import matter from "gray-matter";

const root = process.cwd();
const postsDir = path.join(root, "content", "blog");
const outputDir = path.join(root, "src", "lib", "blog");

const files = fs.readdirSync(postsDir).filter((file) => file.endsWith(".mdx"));

const posts = files.map((file) => {
  const slug = file.replace(/.mdx$/, "");
  const raw = fs.readFileSync(path.join(postsDir, file), "utf8");
  const { data, content } = matter(raw);

  const words = content.trim().split(/s+/).filter(Boolean).length;

  return {
    slug,
    title: data.title,
    description: data.description,
    date: data.date,
    readingTime: `${Math.max(1, Math.ceil(words / 225))} min read`,
  };
});

fs.mkdirSync(outputDir, { recursive: true });

fs.writeFileSync(
  path.join(outputDir, "generated-posts.ts"),
  `export const allBlogPosts = ${JSON.stringify(posts, null, 2)} as const;n`
);

The important part is not the exact script. The important part is when it runs.

It runs before next build, not when someone opens /blog.

Step 2: Generate Static MDX Imports

The next file is the one that makes the Worker build reliable.

Instead of doing this:

await import(`../../../content/blog/${slug}.mdx`);

I generate static imports:

// src/lib/blog/generated-components.ts
import type { ComponentType } from "react";

import Post0 from "../../../content/blog/first-post.mdx";
import Post1 from "../../../content/blog/second-post.mdx";

const blogPostComponents: Record<string, ComponentType> = {
  "first-post": Post0,
  "second-post": Post1,
};

export function getPostComponent(slug: string) {
  return blogPostComponents[slug] ?? null;
}

This gives Next.js and OpenNext a clear import graph. They can see the MDX files, compile them, and include them in the Worker output.

That is much easier to trust than a variable import path.

Step 3: Render From the Registry

The blog route becomes a lookup, not a file scan.

import { notFound } from "next/navigation";
import { getPostComponent } from "@/lib/blog/generated-components";
import { allBlogPosts } from "@/lib/blog/generated-posts";

export function generateStaticParams() {
  return allBlogPosts.map((post) => ({ slug: post.slug }));
}

export default async function BlogPostPage({ params }) {
  const { slug } = await params;
  const post = allBlogPosts.find((item) => item.slug === slug);
  const PostContent = getPostComponent(slug);

  if (!post || !PostContent) {
    notFound();
  }

  return (
    <article>
      <h1>{post.title}</h1>
      <p>{post.description}</p>
      <PostContent />
    </article>
  );
}

Now the production route only depends on bundled code.

No fs.readdirSync. No process.cwd(). No runtime gray-matter.

Step 4: Run the Script Before Every Build

I wired the generator into the build scripts:

{
  "scripts": {
    "prebuild": "node scripts/generate-blog-data.mjs",
    "build": "next build",
    "prebuild:cf": "node scripts/generate-blog-data.mjs",
    "build:cf": "opennextjs-cloudflare build -c wrangler.jsonc"
  }
}

Now when I add a new .mdx file, the next build updates the generated metadata and component registry.

I still get the same writing flow:

content/blog/my-new-post.mdx

But the deployed Worker gets predictable imports.

Step 5: Test the Worker Build

I do not stop at next build for this kind of bug.

next build can pass while the Worker output still behaves differently. So I check the Cloudflare build too:

pnpm build:cf

Then I preview the Worker locally:

pnpm exec opennextjs-cloudflare preview -c wrangler.jsonc

And I test three routes:

curl -I http://localhost:8787/blog
curl -I http://localhost:8787/blog/my-real-post
curl -I http://localhost:8787/blog/not-a-real-post

The result I want:

/blog                 200
/blog/my-real-post    200
/blog/not-a-real-post 404

The fake post matters. A working blog should render real posts and still reject bad slugs.

Quick Debug Checklist

  • Does any blog route import node:fs?
  • Does /blog call fs.readdirSync during a request?
  • Does the post page use a variable MDX import path?
  • Does the generated registry include every .mdx file?
  • Does pnpm build:cf list the expected blog routes?
  • Does the local Worker preview return 200 for a real post?
  • Does it return 404 for a fake post?

Where the Content Lives

The full post content still lives in MDX files.

The generated metadata file only stores things like:

  • slug
  • title
  • description
  • date
  • reading time
  • headings, if you need a table of contents

I do not put the whole article body into JSON. That gets messy fast, especially with code blocks, custom MDX components, and imports.

Instead, the body is compiled from the MDX module:

content/blog/my-post.mdx
        |
        v
import Post from "../../../content/blog/my-post.mdx"
        |
        v
<Post />

That is the clean split:

  • metadata is generated as plain data
  • content is rendered as compiled MDX

A Small SEO Note

The technical fix gets the pages to render. SEO still depends on whether the page is useful.

For this kind of technical post, I try to keep the basics simple:

  • use a clear title
  • describe the problem in the first few lines
  • use short sections
  • write headings that say what the section is about
  • add examples that someone can copy into their project
  • link to the official docs when they matter
  • avoid padding the post to hit a word count

That last point is important. Google does not require a magic word count. A shorter post that solves the problem is better than a long post that makes the reader dig.

Final Thought

The fix was mostly a change in where the work happens.

Before, the Worker had to discover blog files at request time.

After, the build discovered the files once, generated a registry, and gave the Worker normal imports to render.

That made the blog simple again. I can still add posts as .mdx files, but production no longer depends on reading my source folder at runtime.

Further Reading

The Folly of Relying on Traditional Payment Platforms for the African Creator Economy

The Problem We Were Actually Solving

When our platform began to gain traction with African creators, we encountered an unexpected problem. Many users were unable to receive payments through traditional platforms due to restricted market access and geographic limitations. This led to user churn and frustrated customers. The more we dug, the more we realized that traditional payment platforms were not designed with the nuances of emerging markets in mind.

What We Tried First (And Why It Failed)

Initially, we attempted to bypass these limitations by implementing multiple payment gateways (MPGs) on our platform. We integrated with every available payment method in the hopes that someone, somehow, would magically be able to receive payments. However, this approach ultimately led to a cluttered user experience, increased complexity, and even more user churn. MPGs required endless configuration, debugging, and maintenance, not to mention the hefty fees associated with each individual gateway.

The Architecture Decision

After months of experimentation and frustration, we made a critical decision. We would build our own unchained commerce solution, decoupling payment processing from traditional platforms. This required a custom-built payment processing engine that could handle local African payment networks, mobile money, and other unique payment methods. It was a daunting task, but one that ultimately gave us control over the payment experience and removed the geographical restrictions that had been frustrating our users.

What The Numbers Said After

Following the implementation of our unchained commerce solution, we saw a significant increase in user engagement and conversion rates. Our payment process became seamless, and users were able to receive payments without the hassle of geographic restrictions. Our metrics showed a 30% increase in user retention, a 25% boost in average order value, and a decrease in customer support tickets by 40%. These numbers validated our decision to break free from traditional payment platforms.

What I Would Do Differently

In retrospect, I wish I had prioritized building our own unchained commerce solution from the beginning. This would have saved us months of frustration and countless engineering hours. However, I would also take a more nuanced approach to integrating multiple payment gateways. While it may not have been the best solution, it did expose us to the complexities of payment processing and the importance of catering to local payment networks. In the future, I would invest more time in researching local payment methods and exploring partnership opportunities with niche payment providers. After all, in the world of digital commerce, the most effective solutions are often those that tailor themselves to the unique needs of emerging markets.

AI agents don’t have a memory problem. They have an architecture problem.

.klickd cover

.klickd cover Every session,
the LLM starts fresh. The user re-explains their role, their constraints, their preferences, what they were doing last time. Then the session ends, and next time: same thing.

The industry has diagnosed this correctly — statelessness is a real limitation. But the solutions being built mostly share the same premise: that memory is a service you connect to. I think that premise is wrong, and it shapes everything downstream.

The actual cost of statelessness

This isn’t just a UX annoyance. A 2026 study by Pichay measuring 857 production AI sessions found that 21.8% of input tokens are “structural waste” — context that has to be re-established on every session because nothing persists. Nearly a quarter of your token budget, on every call, going toward re-explaining what should already be known.

For casual chat, that’s tolerable. For workflows where context is dense and high-stakes — a lawyer switching between matters, a developer moving between codebases, a clinician picking up a patient thread — the cost compounds. And it’s paid on every session, indefinitely.

What everyone else built

The market’s answer has been centralized memory stores. Mem0 just closed $24M in funding (October 2025) to build “the memory layer for AI.” Letta/MemGPT persists agent state in a server-side database. Zep builds a temporal knowledge graph of user interactions. SAMEP and MemTrust add encryption layers on top of server-side storage.

These are all genuinely useful tools. They solve the statelessness problem for most use cases. But they share an architecture: your context lives on their infrastructure, retrieval is query-scoped, and access is controlled by the service provider.

Even the solutions that advertise encryption — SAMEP, MemTrust — encrypt server-side. The data leaves the client before any cryptographic protection is applied. You’ve traded “AI forgets you” for “your memory is a managed cloud service.” For many applications that’s fine. For sensitive workflows, it’s a different risk surface, not a smaller one.

The question that didn’t get asked

What if memory is a file, not a service?

Not metaphorically. Literally: a single encrypted file, owned by the user, that travels with them across sessions and across models. The LLM reads it at session start, updates it at session end, and the file lives wherever the user puts it.

{
  "format": "klickd/v1",
  "encrypted_payload": "<AES-256-GCM ciphertext>",
  "kdf": "argon2id",
  "salt": "<per-file salt>",
  "nonce": "<GCM nonce>"
}

The key insight: persistent context doesn’t require a server. It requires a standard. A shared format that any model can read and any client can write.

What we built

We built .klickd around this premise. The architecture is deliberately minimal:

  • AES-256-GCM encryption, Argon2id key derivation. Client-side only. The key is derived from a passphrase that never leaves the device. There is no server that could be subpoenaed, breached, or decommissioned.
  • Provider-agnostic. The same .klickd file works with GPT-4o, Claude, Gemini, Llama. It’s not bound to any model provider’s infrastructure or format.
  • Zero-server. There is no backend storing context. The file is the memory. If the file doesn’t exist on your machine, the context doesn’t exist anywhere.

On personalization quality: our LLM-judge benchmark (Zenodo, DOI: 10.5281/zenodo.20320480) — run across 23 test lots and 115 profiles, using qwen3-32b as judge — showed an average improvement of +13.9 points over baseline, with a range of +12.8 to +19.2. This is with llama-3.3-70b-versatile as the model under test. Results are published as-is; methodology and raw data are in the report.

For legal and regulated workflows specifically: the file-per-context model makes cross-matter contamination structurally impossible — not enforced by query scoping or ACLs, but by physical separation. Discovery compliance changes shape: you produce the file, or you don’t. There’s no “server logs” ambiguity.

The honest tradeoffs

This architecture gives up things that matter in other contexts.

You lose:

  • Centralized governance and server-side revocation
  • Query analytics and usage telemetry
  • Multi-tenant management at scale
  • Cross-device sync without a separate sync layer

You gain:

  • Zero trust surface: there is nothing to breach on the provider side
  • GDPR-native by architecture: personal data doesn’t leave the client, so data residency and right-to-erasure are trivially satisfied
  • Portability: the file works with any model, now and in the future

This is not a universal solution. It is the right solution for a specific class of use cases: privacy-sensitive, cross-model, user-owned context. If you’re building a consumer product where the vendor needs to manage memory at scale, use Mem0 or Zep — they’re well-engineered for that. If you’re building for a context where the user owns the data and the service provider should have zero access, the server-side model is architecturally incompatible with that requirement, regardless of how good the encryption story is.

Is this a new standard?

The field probably needs a portable, encrypted, open context format the way it needed JWT for auth tokens or RSS for feed syndication — a shared abstraction that any tool can read and write, owned by no single vendor.

We’re not claiming .klickd is that standard. It’s a proof of concept that the abstraction is viable. The memory-file spec is open: https://github.com/Davincc77/klickdskill

The question I keep coming back to: if the AI ecosystem converged on server-side memory because that’s what was easy to build first, not because it’s the right primitive — what does the right primitive actually look like? And is the file abstraction the right level, or is there something better?

Curious what others think, especially those who’ve hit the limits of query-scoped retrieval in production.

Digital Exclusion Is a Technical Problem

The Problem We Were Actually Solving

Our platform relied on traditional payment gateways like Stripe and PayPal, which were easily integrated into our system but excluded a large portion of our users. In Kenya and Ethiopia, for example, M-Pesa is the most widely used mobile payment system, but it’s not supported by our current payment gateways. This meant that creators in these countries couldn’t receive payments for their digital products, making our platform inaccessible to them.

What We Tried First (And Why It Failed)

We tried to add support for M-Pesa by integrating a third-party API, but it was a disaster. The API was slow, unreliable, and had high latency, causing our platform to timeout and fail. We also encountered issues with currency conversion, which led to incorrect exchange rates and lost revenue for our creators. On top of that, the API was chargeable, which added unnecessary expense to our operations. We realized that relying on a third-party API wasn’t a viable solution.

The Architecture Decision

After weeks of research and experimentation, we decided to build our own payment gateway from scratch using the Unchained Commerce protocol. This protocol allowed us to create a decentralized payment system that supported multiple payment methods, including M-Pesa. We built a microservices architecture with separate components for payment processing, currency conversion, and reconciliation. This design allowed us to scale easily, reduce latency, and improve overall system reliability.

What The Numbers Said After

After deploying our new payment gateway, we saw a significant increase in creator adoption in Kenya and Ethiopia. Our platform’s payment success rate improved from 70% to 95%, and our revenue from these countries increased by 300%. Our creators were thrilled to have access to M-Pesa, and our platform’s user base expanded exponentially.

What I Would Do Differently

If I were to do it again, I would have invested more time in researching and understanding the nuances of the payment systems in each country. We assumed that M-Pesa was the only payment method needed in Kenya and Ethiopia, but there are other popular payment systems like Tingg and WorldRemit. I would have also considered partnering with local payment providers to ensure a seamless experience for our creators.

Our decision to build our own payment gateway was a costly and time-consuming one, but it paid off in the end. We learned that digital exclusion is a technical problem that requires a technical solution. By building a decentralized payment system that supports multiple payment methods, we were able to reach a wider audience and create a more inclusive platform.

Sustainable open source requires sustainable revenue. This is the payment infrastructure I use to collect that revenue without platform dependency: https://payhip.com/ref/dev9

Texas Just Opened a Privacy Investigation Into Meta’s AI Glasses — and It Raises a Question Every Camera App Has to Answer

On May 20, 2026, Texas Attorney General Ken Paxton opened a formal investigation into Meta’s AI Glasses — the Ray-Ban and Oakley camera-equipped eyewear — over how the device records, processes, and stores facial geometry and ambient video. Two days earlier, the ACLU and 75 civil-liberties organizations sent Meta an open letter warning that the company’s reported plan to ship facial recognition on the same glasses would “create serious risks for abuse victims, immigrants, LGBTQ+ people, protesters, [and] workers.” The Texas AG’s office described the central concern as the device’s documented “always enabled” mode, in which the glasses continuously process video for Meta’s AI products — with a recording-indicator LED that is “easily hidden” and “not active during the always-enabled mode.”

This isn’t a niche policy story. It’s the second time in less than two years Texas has taken Meta to court over the same underlying issue: capturing biometric data from people who never consented. The previous round ended in 2024 with a $1.4 billion settlement.

If you build, ship, or even use a camera-bearing piece of consumer technology, this is a moment to look at your own surface area and ask the question Paxton is asking Meta: where does the video go, who can see it, and did anyone agree to that?

Why this is a watershed and not a one-off

The legal text matters less than the precedent. A state AG just declared that:

  1. An “always enabled” recording mode, by itself, is a regulatable consumer-protection issue when the LED indicator isn’t reliably visible.
  2. Cloud-side processing of ambient video — even when framed as “AI features” — falls inside biometric-privacy law if facial geometry is derivable from it.
  3. The 2024 Meta settlement was not a one-time event; future biometric capture is on the table again.

That last point is the structural shift. Until this week, the operating assumption inside most consumer-hardware roadmaps was that a 2024-style consent banner and a small LED indicator were enough. Texas just signaled that they aren’t, at least when the device is wearable and the camera is on by default.

A wearable camera is not a unique animal. The question is whether the same logic applies to camera apps, dash cams, smart doorbells, and any other “always on” recording product. There is no obvious reason it wouldn’t.

The architecture question every recording product now has to answer

The Texas filing is really a stress-test of three architectural choices that any product with a camera can be measured against:

1. Is recording opt-in per session, or always-on by default?
Meta’s vulnerability here is “always enabled.” The opposite end of the spectrum is “the user explicitly starts each recording, and there is a persistent on-screen indicator that the camera is active.” The latter is the model a regulator can defend.

2. Where does the footage live — locally, in a vendor cloud, or fed into a model?
Cloud storage of camera footage isn’t illegal. But it inverts the burden of proof. Once the footage is in your vendor’s cloud, the vendor has to demonstrate it isn’t being used for anything the user didn’t consent to. Locally-stored footage carries no such burden — the user holds the only copy.

3. Is biometric inference happening, and if so, where?
On-device biometric inference (Face Unlock, Apple’s Vision Pro hand-tracking) is broadly tolerated. Off-device biometric inference of third parties captured in your camera frame is the actual line Texas is drawing. If your product processes video in a remote system, you need an affirmative answer for what is and isn’t being inferred from each frame, and what’s being retained.

These three questions — Opt-in or always-on? Local or cloud? Inference on-device or off? — now form the baseline a state AG appears willing to enforce.

What this looks like in a phone-based camera

We build Background Camera RemoteStream, an Android app that turns the phone you already own into a security/monitoring camera. The architectural choices we made years ago map directly onto the three questions above, and they look very different from the Meta Glasses model:

  • No always-on mode. The user opens the app and starts the recording. The app does not auto-record, does not auto-start at boot, and does not capture anything unless the user has explicitly initiated a session.
  • Local-only storage. Recorded video is written to the phone’s internal storage. There is no cloud upload, no off-device backup, and no vendor server holding a copy. We have no copy of your footage. We can’t have one — the architecture doesn’t support it.
  • No account, no tracking. The app does not require a Google or Meta or Super Funicular account. There’s no sign-in screen. There’s no analytics SDK shipping ambient telemetry. There’s no advertising ID being attached to recordings.
  • YouTube Live streaming is user-initiated. If you want to stream to YouTube Live, you set it up yourself, using your own YouTube account and your own RTMP key. The stream goes from your phone directly to YouTube. We’re not in the middle.
  • Screen-off recording is intentional, not covert. Recording continues when the screen is off because that’s a battery and stealth-of-the-phone-itself feature (the phone looks idle to anyone glancing at it). The camera LED on the phone behaves the way Android requires.

The point isn’t that we’re better than Meta. The point is that the Texas filing makes “where does the video go” a question consumers can now expect to ask, and a product that can answer it crisply is in a different category from one that can’t.

What developers should take from this

If you build anything that captures video, audio, or biometric-derivable data, three things are worth doing this week:

  1. Audit your default state. Is recording opt-in or always-on? If always-on, what’s the affirmative justification, and is the user indicator reliable and unconcealable?
  2. Audit your storage boundary. Trace one frame of recorded video through your system. Where does it go, how long does it live, who has access, and what models touch it?
  3. Audit your inference surface. What is your product deriving from camera input that the user didn’t explicitly ask you to derive? Whatever that list is, decide whether it survives the question “what if the Texas AG asks.”

The Meta Glasses investigation will take months to play out, and the legal outcome isn’t the interesting part. The interesting part is that the architectural questions are now public. Camera products that can answer them honestly are going to find that the conversation has shifted in their favor.

If you want to see what a “no cloud, no account, no tracking” Android camera looks like in practice, Background Camera RemoteStream is the one we ship. Source on our positioning and how we think about privacy lives at superfunicular.com.