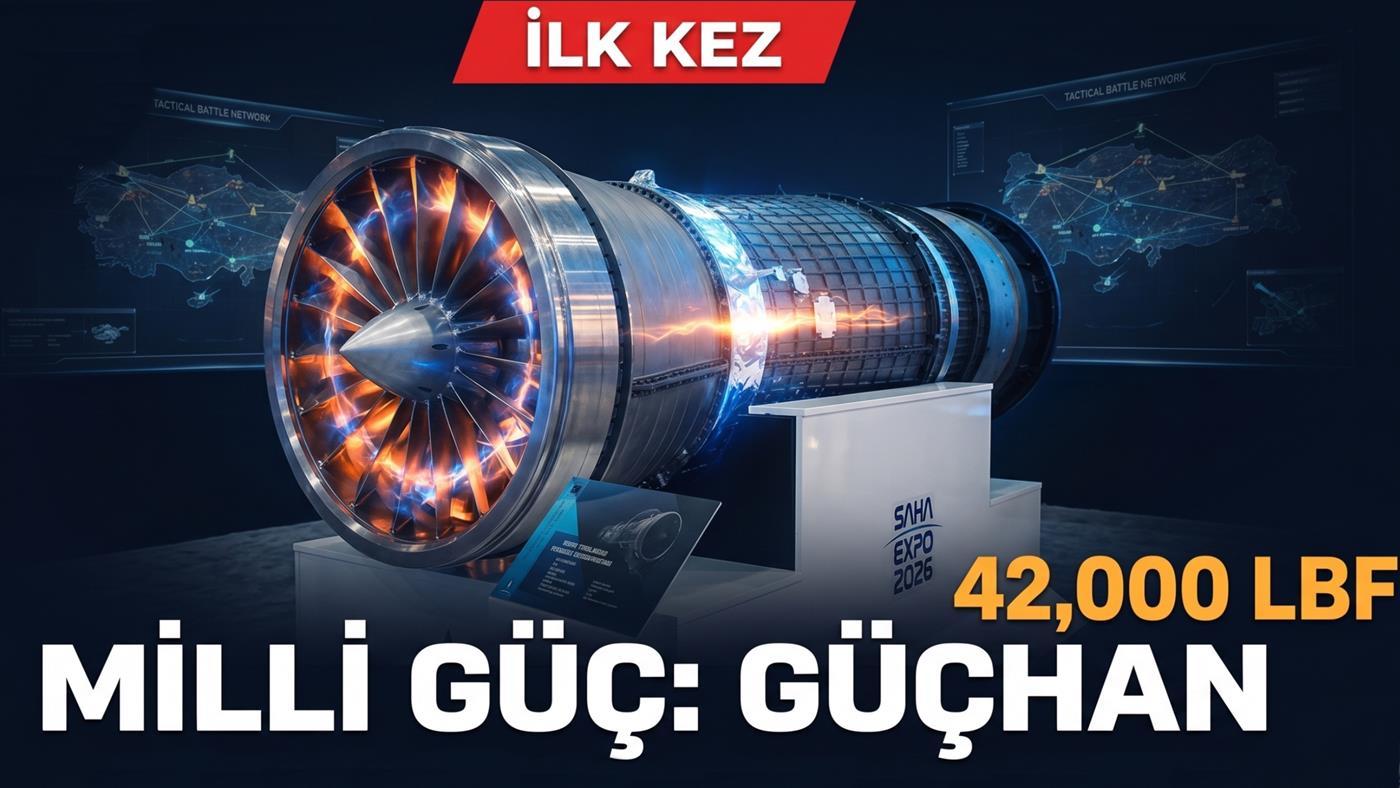
SAHA 2026’nın en büyük sürprizi: MSB AR-GE’nin GÜÇHAN turbofan motoru ilk kez sahnede
MSB AR-GE’den dev sürpriz! Türkiye’nin yeni turbofan motoru GÜÇHAN, SAHA 2026’da sessiz sedasız sahneye çıktı. 42.000 lbf itki gücüyle dünya devleriyle aynı ligte! Rakamlar inanılmaz!Pizza Hut’ın yapay zekalı teslimat sistemi 100 milyon dolarlık krize dönüştü
Pizza Hut’ın yapay zeka destekli teslimat sistemi Dragontail, teslimat sürelerini uzattığı ve satışları düşürdüğü iddiasıyla şirkete 100 milyon dolarlık dava açılmasına yol açtı.“Yapay yumurta” ile 26 civciv dünyaya geldi: Nesli tükenen tür geri getirilecek
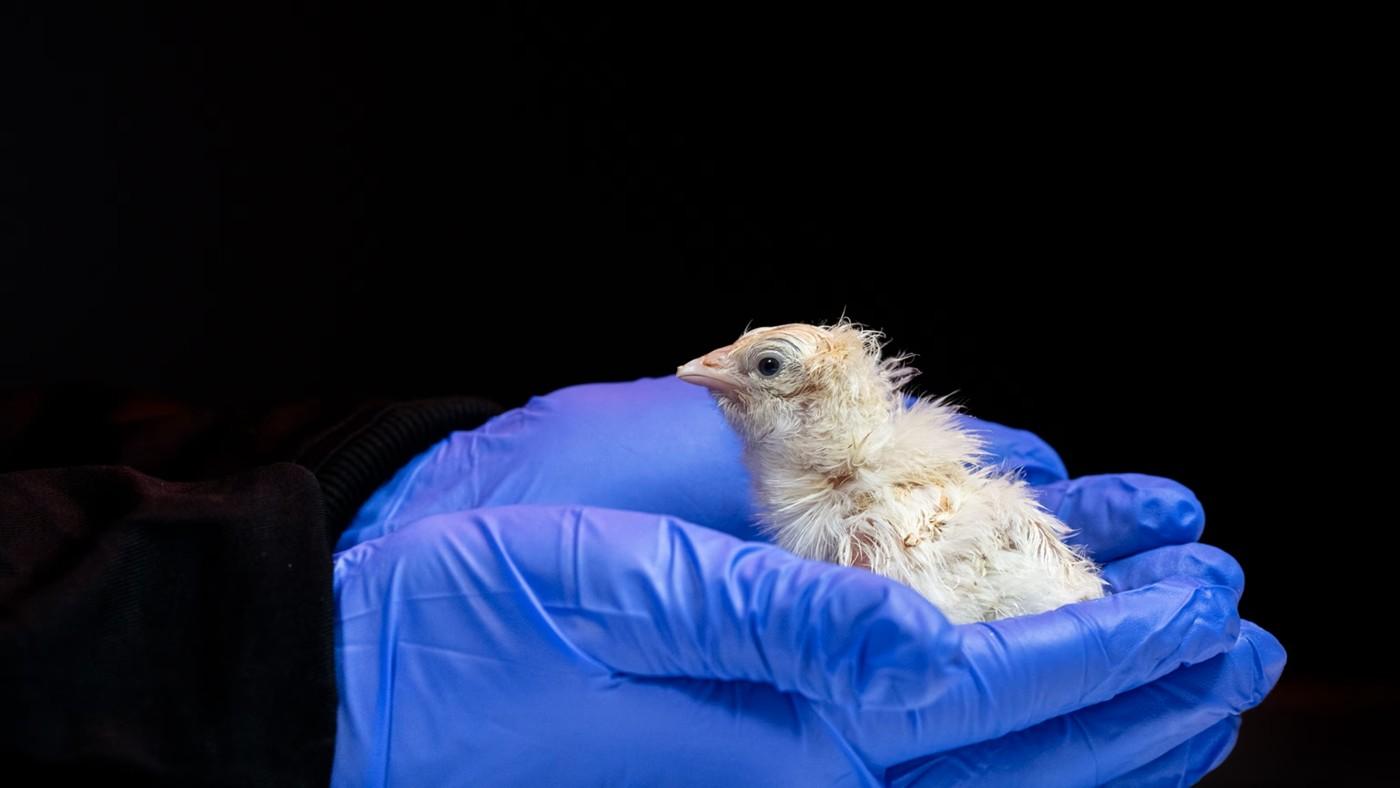
Colossal Biosciences, geliştirdiği yapay yumurta sistemiyle 26 civciv üretmeyi başardı. Teknoloji, dodo ve dev moa gibi nesli tükenmiş kuşların geri getirilmesi için kullanılacak.Stellantis dev planını açıkladı: 15 bin euro altı elektrikli araç geliyor
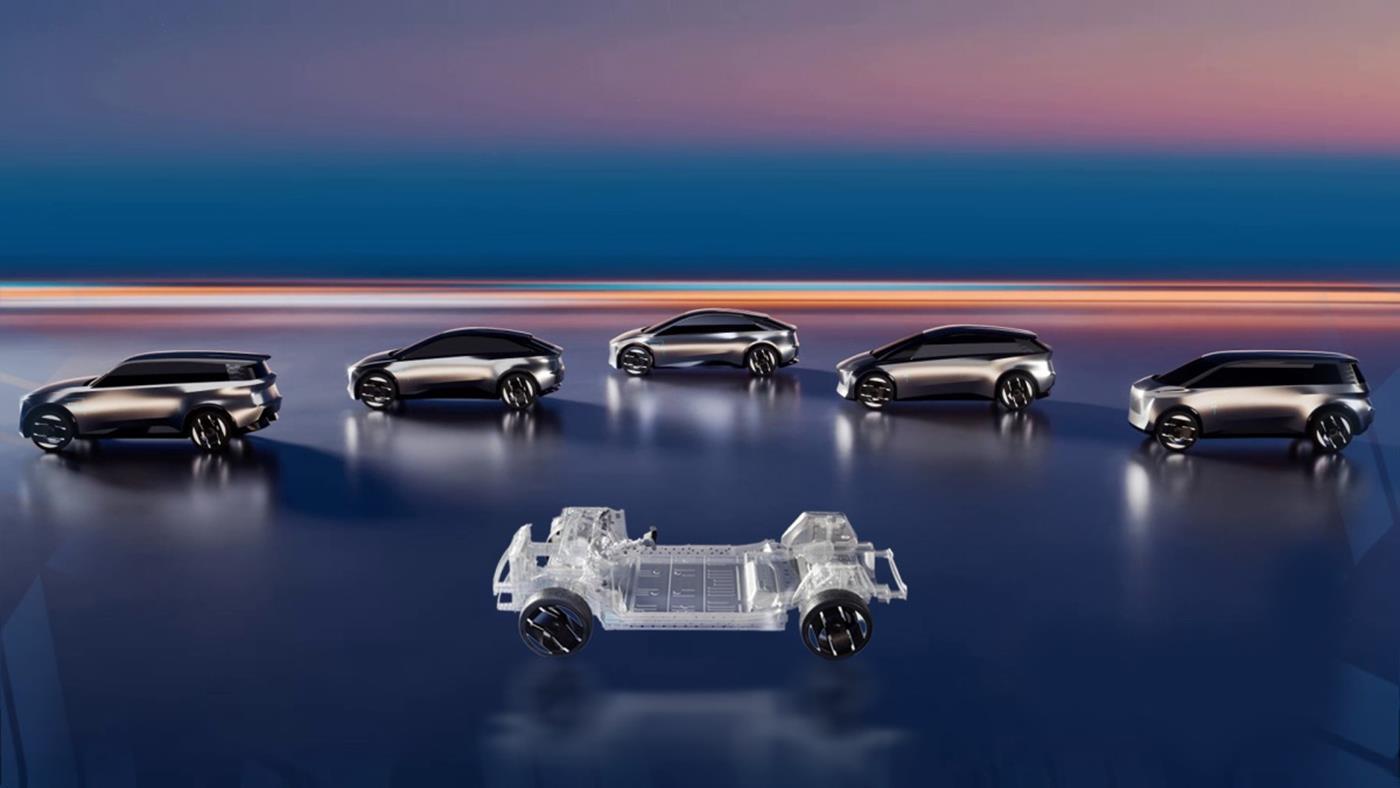
Stellantis, 60 milyar euroluk “FASTlane 2030” planıyla 60 yeni model geliştireceğini açıkladı. Şirket, uygun fiyatlı elektrikli araçlar ve yeni modelleriyle büyümeyi hedefliyor.Real-World Next.js Performance: Moving Beyond standard useEffect and Fetching Hooks
Let’s be honest for a second. When we are first learning React or Next.js, we all do the exact same thing to get data onto a screen: we spin up a useEffect, drop a standard fetch() inside it, point it at an API endpoint, and throw the response into a local useState.
It feels like magic. It works on your local machine (localhost:3000), and your app looks perfect.
But then you push that app into the wild. Real users start clicking around on slow mobile networks, networks drop, users spam the refresh button, and suddenly your clean dashboard turns into a chaotic mess of layout shifts, infinite loading spinners, and redundant API calls that put unnecessary strain on your backend.
When I started transitioning from building simple hobby sites to shipping heavy, production-ready applications, I realized that how you manage data on the frontend is what separates a junior project from an enterprise-grade platform.
If you want to build web apps that feel instantaneous—even on a weak 3G connection—you have to move past basic fetching. Here is how I approached rewriting my frontend architecture to handle data like a pro.
The Silent Killer: Client-Side Fetching Waterfalls
One of the biggest performance bottlenecks on modern web apps is what developers call a fetching waterfall.
Imagine a dashboard with a sidebar, a user profile header, and a main content table. If every single one of those components relies on its own useEffect to fetch data, Component B might wait for Component A to finish loading before it even starts its own API call.
The result? A stuttering, frustrating user experience where elements pop in one by one.
To fix this in modern Next.js, I had to completely re-think my rendering strategies. Instead of forcing the user’s browser to do all the heavy lifting after the page loads, I shifted the heavy data fetching to the server side using Server Components or leveraging Parallel Data Fetching.
By triggering multiple asynchronous requests simultaneously with Promise.all(), you cut down the total loading time to match only the slowest request, rather than stacking them up.
Smart Caching: Stop Pinging the Server for Everything
Another massive wake-up call came when looking at network logs. Why should a user re-download their entire profile information or a static list of options every single time they click back and forth between tabs?
This is where integrating tools like TanStack Query (React Query) or utilizing Next.js’s built-in fetch caching mechanism becomes non-negotiable.
By introducing proper cache validation strategies (like Stale-While-Revalidate), the frontend can instantly display data from the local cache the moment a user clicks a route, while silently fetching the latest updates in the background. If the data hasn’t changed, the UI doesn’t twitch. It feels instantaneous.
+————————————————————-+
| User clicks a tab -> Shows cached data INSTANTLY |
| |
| Simultaneously -> Background sync checks for new updates |
+————————————————————-+
This drastically improves the User Experience (UX) and saves a massive amount of bandwidth on your server infrastructure.
Defeating the “Janky” UI with Optimistic Updates
If you are building an interactive app—like a system where a user can toggle a status, save a bookmark, or check an item off a list—waiting for a server response before showing the visual change feels laggy.
If a user clicks “Like,” and there’s a 500ms delay before the icon turns red, the app feels broken.
To solve this, I started implementing Optimistic Updates.
The concept is simple: when a user triggers an action, you assume the server call will succeed and update the frontend state immediately. If the server comes back with a success, great—everything matches. If the server fails (e.g., a network timeout), you gracefully roll back the UI state to what it was before and show a helpful error toast.
To the end user, your application feels like it’s running locally at 120 frames per second, masking whatever latency is happening behind the scenes on the cloud.
The Takeaway: UX is an Engineering Challenge
As frontend and full-stack engineers, our job isn’t just to look at UI design files and translate them into HTML and CSS. Our true value lies in managing the state of the application across an unpredictable internet.
When you optimize your data-fetching patterns, implement strict caching, and eliminate layout shifts, you aren’t just making the code cleaner. You are directly impacting user retention, keeping conversion rates high, and keeping your server costs under control.
Don’t just settle for code that “works.” Build interfaces that feel alive, predictable, and incredibly fast.
What’s your go-to strategy for keeping your frontend snappy? Are you Team Server Components all the way, or do you heavily rely on client-side state managers? Let’s talk architecture in the comments below! ⚡
Want to see how this fast frontend hooks into a hyper-optimized backend? Keep an eye out for my next post where I talk about ditching Node.js entirely for Bun and ElysiaJS!
How to Build a Human-in-the-Loop AI Agent with LangChain & LangGraph
AI agents are powerful — but sometimes too powerful. What if your agent is about to send an email on your behalf and you want a chance to say “wait, hold on”? That’s exactly what Human-in-the-Loop (HITL) is for.
In this article, we’ll build an AI agent that can send emails, but pauses and asks for your approval before actually doing it. If you approve, it goes through. If you reject, it doesn’t. Simple, safe, and production-ready.
What We’re Building
A LangChain agent powered by an LLM that:
- Receives a user request like “Send an email to [email protected]“
- Decides to call the
send_emailtool - Pauses and waits for human approval
- Sends the email (or drops it) based on your decision
Prerequisites
pip install langchain langgraph
You’ll also need an LLM. In this article we’ll use OpenAI’s GPT-4o-mini via langchain-openai, but you can swap in any LangChain-compatible model.
pip install langchain-openai
Set your API key:
export OPENAI_API_KEY="your-key-here"
Step 1: Set Up the Model
from langchain_openai import ChatOpenAI
# You can swap this for any LangChain-compatible chat model
model = ChatOpenAI(model="gpt-4o-mini", temperature=0)
Using a different provider? LangChain supports Anthropic, Mistral, Groq, and many others. Just replace
ChatOpenAIwith the appropriate class and install its package (e.g.langchain-anthropicfor Claude).
Step 2: Define the Tool
This is the action the agent will want to take. We keep it simple — just a function that prints the email details.
def send_email(email: str, message: str) -> str:
"""Send email"""
print(f"nEMAIL SENT TO: {email}")
print(f"MESSAGE: {message}")
return "Email sent successfully"
In a real app, you’d integrate this with SendGrid, SES, or your SMTP server.
Step 3: Create the Agent with Human-in-the-Loop Middleware
Here’s where the magic happens. We use:
-
create_agent— builds the agent with tools attached -
HumanInTheLoopMiddleware— tells the agent to pause before calling specific tools -
InMemorySaver— a checkpointer that saves agent state so it can be resumed after the pause
import warnings
warnings.filterwarnings("ignore", category=UserWarning)
warnings.filterwarnings("ignore", category=DeprecationWarning)
from langchain.agents import create_agent
from langchain.agents.middleware import HumanInTheLoopMiddleware
from langgraph.checkpoint.memory import InMemorySaver
from langgraph.types import Command
agent = create_agent(
model=model,
tools=[send_email],
middleware=[HumanInTheLoopMiddleware(interrupt_on={"send_email": True})],
checkpointer=InMemorySaver(),
)
The key line is interrupt_on={"send_email": True}. This tells the middleware: “Before you actually run send_email, freeze and hand control back to the human.”
The InMemorySaver checkpointer is what makes resuming possible — it snapshots the agent’s state at the interruption point so you can pick up exactly where you left off.
Step 4: First Invocation — Let the Agent Plan
We kick things off with the user’s request. The agent will reason about what to do and reach the point of calling send_email — then stop.
config = {"configurable": {"thread_id": "test-thread"}}
response = agent.invoke(
{
"messages": [
{
"role": "user",
"content": "Send an email to [email protected] with message 'hello world'",
}
]
},
config=config,
)
print("nAGENT PAUSED FOR APPROVALn")
The thread_id in config is how LangGraph tracks this specific conversation. Use the same thread ID when you resume so it picks up the right checkpoint.
Step 5: Ask the Human
Now we prompt the user in the terminal. This is the “human” part of human-in-the-loop.
decision = input("Approve email? (yes/no): ")
Step 6: Resume Based on the Decision
This is where Command(resume=...) comes in. We send the agent’s paused state a signal telling it whether to proceed or abort.
If Approved
if decision.lower() == "yes":
response = agent.invoke(
Command(resume={"decisions": [{"type": "approve"}]}),
config=config,
)
print("nFINAL RESPONSE:")
print(response["messages"][-1].content)
The agent resumes from the checkpoint, actually calls send_email, and continues to completion.
If Rejected
else:
response = agent.invoke(
Command(
resume={
"decisions": [{"type": "reject", "message": "Human rejected the email"}]
}
),
config=config,
)
print("nEMAIL REJECTED")
The agent is told the action was rejected. It can use the rejection message to inform its final response (e.g., “The email was not sent as per your instruction.”).
Full Code
Here’s everything together:
import warnings
warnings.filterwarnings("ignore", category=UserWarning)
warnings.filterwarnings("ignore", category=DeprecationWarning)
from langchain.agents import create_agent
from langchain.agents.middleware import HumanInTheLoopMiddleware
from langchain_openai import ChatOpenAI
from langgraph.checkpoint.memory import InMemorySaver
from langgraph.types import Command
# ── Model ──────────────────────────────────────────────────────────────────────
model = ChatOpenAI(model="gpt-4o-mini", temperature=0)
# ── Tool ───────────────────────────────────────────────────────────────────────
def send_email(email: str, message: str) -> str:
"""Send email"""
print(f"nEMAIL SENT TO: {email}")
print(f"MESSAGE: {message}")
return "Email sent successfully"
# ── Agent ──────────────────────────────────────────────────────────────────────
agent = create_agent(
model=model,
tools=[send_email],
middleware=[HumanInTheLoopMiddleware(interrupt_on={"send_email": True})],
checkpointer=InMemorySaver(),
)
config = {"configurable": {"thread_id": "test-thread"}}
# ── First call: agent plans and pauses ─────────────────────────────────────────
response = agent.invoke(
{
"messages": [
{
"role": "user",
"content": "Send an email to [email protected] with message 'hello world'",
}
]
},
config=config,
)
print("nAGENT PAUSED FOR APPROVALn")
# ── Human decision ─────────────────────────────────────────────────────────────
decision = input("Approve email? (yes/no): ")
if decision.lower() == "yes":
response = agent.invoke(
Command(resume={"decisions": [{"type": "approve"}]}),
config=config,
)
print("nFINAL RESPONSE:")
print(response["messages"][-1].content)
else:
response = agent.invoke(
Command(
resume={
"decisions": [{"type": "reject", "message": "Human rejected the email"}]
}
),
config=config,
)
print("nEMAIL REJECTED")
Sample Output
When approved:
AGENT PAUSED FOR APPROVAL
Approve email? (yes/no): yes
EMAIL SENT TO: [email protected]
MESSAGE: hello world
FINAL RESPONSE:
The email has been sent to [email protected] with the message "hello world".
When rejected:
AGENT PAUSED FOR APPROVAL
Approve email? (yes/no): no
EMAIL REJECTED
Why This Pattern Matters
Human-in-the-loop isn’t just a safety net — it’s an architectural pattern for building trust between AI and users. Here’s when you’d want it:
| Use Case | Why HITL Helps |
|---|---|
| Sending emails / messages | Prevents accidental or hallucinated sends |
| Database writes | Confirms destructive operations |
| API calls with side effects | Gives humans a veto before real-world actions |
| Financial transactions | Compliance and audit requirements |
| Customer-facing responses | Quality control before publishing |
Taking It Further
-
Async approval: Instead of a terminal
input(), send an approval request to Slack, email, or a web dashboard. - Timeout handling: Auto-reject if no human responds within N minutes.
- Audit logs: Persist every approval/rejection to a database for compliance.
-
Multiple tools: Pass multiple tool names to
interrupt_onto gate any subset of your agent’s capabilities.
Wrapping Up
LangGraph’s checkpointing + LangChain’s middleware make it surprisingly clean to add human oversight to any AI agent. The agent does the thinking; you keep the final say.
If you found this useful, drop a ❤️ and let me know what kinds of agents you’re building in the comments!
Apple, iPhone 17 Pro kullanarak canlı maç yayını gerçekleştirecek
Apple, tamamı iPhone 17 Pro ile çekilecek ilk büyük profesyonel canlı spor müsabakasını ekrana taşımaya hazırlanıyor. 23 Mayıs tarihinde Los Angeles Galaxy ile Houston Dynamo’nun karşı karşıya geleceği “Major League Soccer” maçı, resmi duyuruya göre yalnızca iPhone 17 Pro kullanılarak kaydedilecek. Dignity Health Sports Park stadyumunda oynanacak maçı doğrudan Apple TV üzerinden canlı olarak yayımlayacak teknoloji devi, bu konuda önemli bir gösterim yapmış olacak.
Apple, iPhone 17 Pro kullanarak canlı maç yayını gerçekleştirecek yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.
Off the Grid: How GEMMA 4 Unlocks Private, Local AI
INTRODUCTION:
We talk about being independently building and developing with the help of AI. But, is it what we are actually doing…? Almost every AI applications we build are one way or the other depend on credentials and API keys that constrain us from being independent in building applications.
But now the solution to this rebellious question is blooming: “WHAT IF WE COULD TAKE FRONTIER-LEVEL INTELLIGENCE OFF THE GRID AND COMPLETELY RUN IT ON THE MACHINE IN FRONT OF US ?”
The Cloud Chain and the Shift to Local AI:
Though we developers write scripts, wire up workflows efficiently, we do it completely dependent on an internet connection and someone else’s server.
We are ready to let our data transmit from our system to a corporate cloud cluster
But this cloud-first approach has its own problems:
- Unpredictable Bills
- Latency lag
- Data vulnerability
LET’S WELCOME GEMMA 4 !!!
This is the exact reason why shift towards local computing is becoming a massive movement.
On April 2,2026. Google DeepMind launched Gemma 4. Unlike commercial APIs, Gemma 4 is a family of open-weight models, meaning Google is transparent about the AI’s decision making prospects.
For the first time in the series, it’s released under APACHE 2.0 License, a completely open license.
This gives absolute developer right: you can run it, distribute it, modify it or build with it without paying a single penny.
GOAL:“take our code completely off the grid and handle high-level logic right on our own machines.”
MEETING THE FAMILY:
Models in a local AI development aren’t restricted to an single size. As it could lead to mismanagement of hidden potential or over-exploiting of weaker versions
Thus, Gemma 4 is divided into 4 sizes tailored to specific needs: (parameter count-in billions)
E-> Effective Parameter
-
Gemma 4 E2B and Gemma 4 E4B:
Ultra-lightweight, highly condensed versions engineered specifically to run smoothly on standard laptops, thin notebooks, or even high-end smartphones without draining through your battery. -
Gemma 4 26B A4B
Works on the basis of Mixture of Experts (MoE). Though it has around 26 Billion parameters, it only uses around 4 billion each time choosing a suitable model according to our prompts. More like a heavy model with a high speed processing. -
Gemma 4 31B
It’s built for complex logical tasks, heavy mathematics, and long form coding. Requires a dedicated modern GPU with plenty of video RAM to host this on your desktop.
Gemma 4 also introduces an expansive memory layout:
- Smaller edge models: 128K CONTEXT WINDOW
- Larger workstation models: 256K CONTEXT WINDOW
The Senses (Local Vision & Audio):
Historically a local AI model is meant to be ran on a text-only environment. Even when there existed very few options, these weren’t the part of the model itself, instead these options were bolted inside the model from a dedicated model for the purpose.
But, Gemma 4 has this problem sorted since the models are trained on text, image and audio, allowing it to understand how words, pixels and sound waves connect in real world.
ADVANTAGES OF LOCAL SIGHT:
-> UI and Code:
UI and Code generation based on expected visuals given as wireframe or hand-drawn layout, giving us the functional HTML, CSS or Tailwind code corresponding to out expectations.
-> Document and Chart Parsing:
Extracts the required analysis from dense financial charts and scientific graphs without leaking the information to external servers.
-> Handwriting Recognition:
Features OCR (Optical character recognition), meaning it can accurately read and transcribe handwritten notes into markdown text.
ADVANTAGES OF LOCAL HEARING:
Google added highly specialized features to the smaller models like NATIVE AUDIO INPUT.
These lightweight variants can accept direct audio clips that are up to 30 seconds longer, thus could handle cross-language speech translations seamlessly enabling us to create voice-activated interfaces and translational tools.
Spinning It Up and the Sovereign Future:
In the past, setting up a local LLM required struggling with complex Python dependencies, setting up virtual environments, and manually configuring CUDA drivers for our graphics cards.
Today, its incredibly clean. The absolute easiest way to run Gemma 4 locally is through an open-source tool called Ollama, that could manage model weights and handles hardware acceleration behind the scenes.
A SMALL SET OF INSTRUCTIONS TO SET UP OLLAMA AND RUN THE MODELS:
-
Install Ollama: Download and install the software for your specific operating system (Mac, Windows, or Linux) directly from the official site.
-
Pick the Model: Open your computer’s terminal or command prompt and run a single command to download the model file. For the highly balanced 4-billion parameter version, you simply type:
Bash
ollama run gemma4:4b
-> Start Prompting: Once the download completes, the terminal will transform into a direct chat interface. You can unplug your internet cable entirely and start asking questions, debugging code, or parsing text locally at high speeds.
CONCLUSION:
What’s exciting isn’t just Google’s massive engineering milestones or native audio and visual integration. The real victory is the scope it provides to the future of software building.
Stepping away from costly and restricted AI models that run while compromising your prompts and data is itself a huge success towards the Foundation of Building AI applications.
Be it a student exploring software engineering on a regular laptop or a developer building highly secure enterprise tools, the capability to run a frontier-level intelligence entirely off the grid puts the control exactly where it belongs: “Right inside our code, running on our own system…“
References & Technical Credits
Model Creator: Google DeepMind (Released April 2, 2026)
Licensing: Open-weights distributed under the permissive Apache License 2.0
Local Architecture Tools: Powered by the open-source Ollama runtime ecosystem
Behind the Article (Process & Disclosures)
Research & Fact-Checking: Technical data and architectural configurations were cross-verified using official documentation from the Google AI for Developers platform and open community deep-dives on Hugging Face.
Visuals & Art Direction: Imagery throughout this post was custom-designed and generated using Google’s Imagen 3 architecture.

Code Meets Commerce: What Building Websites for Real Businesses Taught Me About Software Engineering
When you’re learning to code, your focus is entirely on the technical stuff. You worry about clean code, component reusability, state management, and picking the coolest looking UI libraries. You live in a perfect bubble where the user always inputs the right data and the requirements never change.
Then, you get your first real-world freelance client.
And suddenly, that perfect bubble bursts.
A while ago, I took on a project to build a travel agency and rental website for Srikandi Trans Purwokerto and Sandita Rent Car. Up until that point, I had been working on structured school applications like an LMS. But stepping into the SME (Small and Medium-sized Enterprises) sector taught me that in the real world, coding is only half the battle.
Here is what building production websites for real businesses taught me about what it actually means to be a software engineer.
1. Clients Don’t Care About Your Tech Stack (And That’s Okay)
When I started the project, I was incredibly excited to use React.js, Next.js, and Tailwind CSS. I wanted to show off fast rendering speeds, server-side capabilities, and optimized build sizes.
But during my first meeting with the owner, I realized something crucial: They didn’t care. They didn’t know what React was, and they didn’t care about Tailwind. What they cared about was simple:
- “Will this help customers book our travel services easily?”
- “Will it load fast on a cheap smartphone with a weak internet connection?”
- “Will it rank on Google so people in Purwokerto can find us?”
This was a massive shift in mindset for me. As developers, we get obsessed with our tools. But for a business, technology is just a tool to solve a commercial problem. Your job isn’t just to write code, it’s to build a solution that drives business results.
2. The Power of UX Optimization over Over-Engineering
When building a commercial site, every second of loading time and every confusing button costs the business money. If a user gets confused trying to find the contact button or the fleet list, they will simply leave and go to a competitor.
Instead of over-engineering complex animations or features the client didn’t ask for, I focused heavily on UI/UX optimization and site speed.
I spent hours ensuring the mobile responsiveness was flawless, because in the transport sector, almost 80% of your traffic comes from people browsing on their phones while on the move. I optimized images, removed heavy scripts, and streamlined the booking flow so a user could go from landing on the homepage to hitting the WhatsApp booking button in less than three clicks.
Seeing the conversion rates and user reach improve after the launch was infinitely more satisfying than just writing a clever piece of JavaScript.
3. Communication is a Hard Skill, Not a Soft Skill
People often call communication a “soft skill,” as if it’s optional. It’s not. When working with freelance clients, clear communication is just as vital as writing bug-free code.
Local business owners know their industry inside out, but they might not know tech jargon. Part of my job as a developer was to play the role of a translator. Instead of saying, “We need to optimize asset delivery and configure DNS zone records for better propagation,” I learned to say, “We are going to make the images load faster and make sure your domain name correctly points to our new server so customers can access it without issues.”
Simplifying complex technical logic into clear, actionable business value saves time, prevents scope creep, and builds massive trust with your clients.
Final Thoughts
Freelancing while navigating my high school years at SMKN 1 Purbalingga and finishing up my internship has been a wild, exhausting ride. But nothing beats the experience of shipping real code that impacts a real business’s bottom line.
If you’re a junior developer looking to level up, stop just building fictional projects for your portfolio. Go out there and find a local business, a café, a laundry service, or a transport agency. Offer to fix their web presence. The technical challenges, the client meetings, and the pressure of pushing a commercial site live will teach you lessons no bootcamp or tutorial video ever could.
Have you ever built a project for a non-technical client? How did you handle the communication gap? Let’s talk in the comments below!
If you want to check out the rest of my development work or collaborate on a project, feel free to visit my Portfolio or see what I’m breaking next on GitHub.
Cheers,
Ibra 🚀