Mercedes-Benz, 31 Mart’ta makyajlı GLE, GLE Coupe ve GLS’yi tanıtacak

Mercedes-Benz

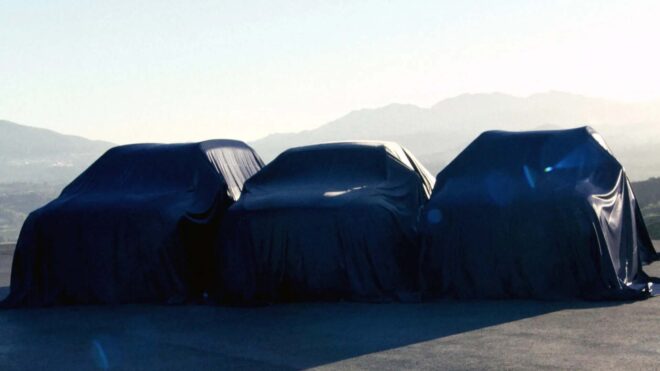
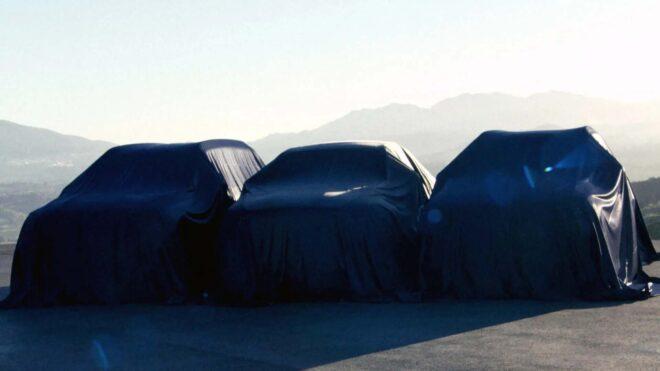
Mercedes-BenzMercedes-Benz, bugün yapılan resmi paylaşıma göre 31 Mart’ta makyajlı GLE, GLE Coupe ve GLS’yi tanıtacak. Kısa süre önce tamamen elektrikli yeni VLE’yi ve yeni S-Class Maybach’ı tanıtan Alman devi, makyajlı GLE, GLE Coupe ve GLS’yi uzun süredir test ediyordu. Hem dış hem de iç tasarımdaki güncellemelerle modernleştirilecek ve büyük ekranlarla donatılacak araçlar, birden fazla içten yanmalı motor seçeneğine sahip olacak. Kaynaklar, 2027 GLS 580’de çift turbo destekli yeni V8 ünitenin kullanılacağını iddia ediyor. Yenilenen S-Class ile beraber tanıtılan bu motor 580 beygir güç ve 750 Nm tork üretiyor. GLS 450’de ise 376 beygir güç üreten 3.0 litrelik turbo destekli sıralı altı silindirli motorun yer alması bekleniyor.

Mercedes-Benz, 31 Mart’ta makyajlı GLE, GLE Coupe ve GLS’yi tanıtacak yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Volkswagen, Osnabrück fabrikasında İsrail için Demir Kubbe parçaları üretecek iddialarına cevap verdi

Volkswagen, Osnabrück fabrikasında silah üretecek iddialara cevap verdi

Volkswagen, Osnabrück fabrikasında silah üretecek iddialara cevap verdiAlman otomobil devi Volkswagen (VW), 2.300 kişinin çalıştığı Osnabrück fabrikasında İsrail’in “Demir Kubbe” savunma sistemi için parça üretecek iddialarına cevap verdi. Deutsche Welle’ye (DW) bu konuda açıklamalarda bulunan şirket sözcüsü, Volkswagen’in gelecekte silah üretmesi gibi bir durumun söz konusu olmadığını ve 2027’de araç üretiminin durdurulacağı Osnabrück fabrikasına ilişkin planlar hakkında spekülasyon yapmayacaklarını belirtti. Ancak şirketin “uygulanabilir seçenekleri araştırmaya devam ettiğini” ve çeşitli “piyasa oyuncularıyla” görüşme halinde olduğunu belirten VW sözcüsü, “Bu, 2027 sonrasına yönelik açık bir değerlendirme sürecinin parçası.” diye konuştu. “Bu fabrikanın gelecekteki yönü konusunda şu an için somut bir karar ya da sonuç yok.” ifadesini kullanan VW sözcüsü, çalışanları da süreçle ilgili olarak bilgilendirmeye devam ettiklerini söyledi. Financial Times (FT), fabrikada füzeleri taşıyan ağır hizmet kamyonları, fırlatıcılar ve jeneratörler dahil olmak üzere çeşitli parçaların üretileceğini, ancak patlayıcı mühimmat/füze üretilmeyeceğini aktarmıştı.

Volkswagen, Osnabrück fabrikasında İsrail için Demir Kubbe parçaları üretecek iddialarına cevap verdi yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

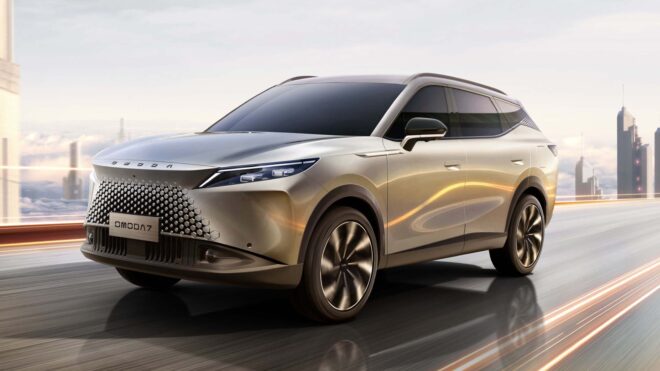
Yeni OMODA 7 için resmi Türkiye fiyatı açıklandı

Yeni OMODA 7,

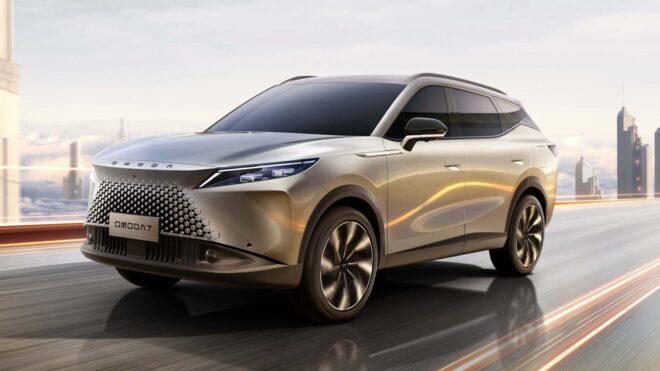
Yeni OMODA 7,OMODA & JAECOO tarafından yapılan resmi açıklamaya göre yeni OMODA 7 modeli Türkiye’de 2  milyon 680 bin TL’ye (7 Neo 4×2 7 İleri Otomatik DCT) satılacak. Chery çatısı altındaki ortak marka, 145 beygir güç sunan 1.6 litrelik (275 Nm tork) turbo benzinli motorla gelen yeni araç hakkındaki son paylaşımda şunları söylemişti: “Markanın amiral gemisi olan OMODA 7, rafine bir yaşam tarzını benimseyen ve bağımsız bir duruş sergileyen kullanıcılar için tasarlandı. Dış tasarımında keskin hatlara sahip “X” formundaki ön yüz, çerçevesiz parametrik ızgara ve entegre LED farlar dikkat çekiyor. Yarı gizli kapı kolları ve akıcı gövde hatları zarafet ile dinamizmi bir araya getirirken, gizli arka silecek ve yıldırım formundaki arka stoplar aracın arka tasarımında görsel bütünlüğü güçlendirerek yolda güçlü bir karakter ortaya koyuyor. İç mekanda ise 256 farklı renkte ambiyans aydınlatması nefes alma ve akış modlarıyla farklı atmosferler yaratıyor. 8,88 inç dijital gösterge paneli ve 15,6 inç 2.5K çözünürlüğe sahip dokunmatik […]

Yeni OMODA 7 için resmi Türkiye fiyatı açıklandı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Tesla Türkiye, İstanbul’da “Cybertruck” sergileyecek

Tesla Türkiye, İstanbul

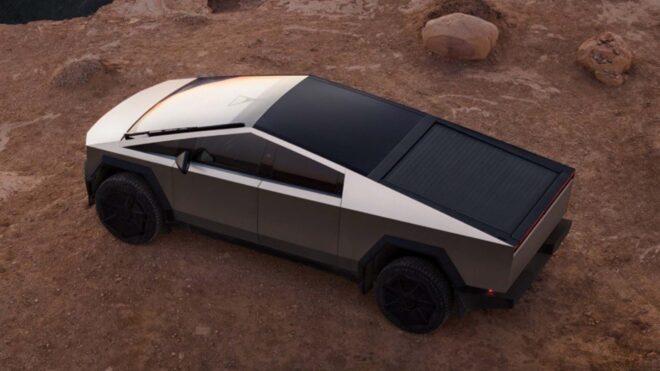
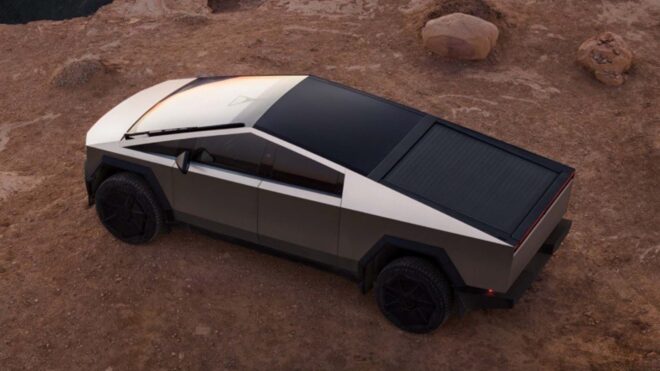
Tesla Türkiye, İstanbul'da "Cybertruck" sergileyecekBugün yapılan resmi açıklama ile duyurulduğu kadarıyla Tesla Türkiye İstanbul’da “Cybertruck” sergileyecek. Bu konuda yaptığı paylaşımda, “8 Mart’tan itibaren Cybertruck, İstanbul Emaar Square Mall’da sergilenmeye başlıyor. Türkiye’de ilk kez, kayıt yaptıran ziyaretçiler Cybertruck’ın içine girerek iç mekanını ve özelliklerini özgürce keşfedebilecek. Etkinlik, 28 Mart – 5 Nisan tarihleri arasında 9 gün boyunca devam edecek. Ziyaretçiler kayıtlarını aşağıdaki link üzerinden veya etkinlik alanında yaptırabilirler. Sizi ağırlamaktan mutluluk duyarız.” diyen şirket, tasarımı hemen hemen kimse tarafından beğenilmeyen Cybertruck’ı Türkiye’de resmi olarak satmıyor. 28 Mart’tan itibaren Cybertruck, İstanbul Emaar Square Mall’da sergilenmeye başlıyor. Türkiye’de ilk kez, kayıt yaptıran ziyaretçiler Cybertruck’ın içine girerek iç mekanını ve özelliklerini özgürce keşfedebilecek. Etkinlik, 28 Mart – 5 Nisan tarihleri arasında 9 gün boyunca… pic.twitter.com/HzGb53pnYT — Tesla Europe, Middle East & Africa (@teslaeurope) March 27, 2026

Tesla Türkiye, İstanbul’da “Cybertruck” sergileyecek yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

How We Cut Browser Agent Costs 7,000x with Collective Intelligence

Every browser agent does the same expensive thing: dump the entire DOM into an LLM, ask “what should I click?”, and repeat for every step. A 10-step workflow costs ~$4 in LLM tokens and ~50 seconds in reasoning time. Multiply that by every agent, every session, every day — and you’re burning cash on knowledge that already exists.

The core problem: amnesia at scale

When Agent A figures out how to search flights on WebsiteA, that knowledge evaporates when the session ends. Agent B starts from scratch. So does Agent C. Every agent pays full price to re-learn what hundreds of agents have already discovered.

This is the browser automation equivalent of every developer rewriting left-pad from scratch, every time, in every project.

What if agents could share what they learn?

We built AIR SDK — an open-source MCP server that maintains a shared capability graph across all connected agents. Three API calls:

browse_capabilities(domain)   → What actions can be performed here?
execute_capability(action, params) → How do I do it? (CSS selectors, API paths, macros)
report_outcome(steps, success)     → Here's what actually worked.

The third call is the key. When your agent reports which CSS selectors worked on a given site, every future agent on that domain benefits instantly. No DOM parsing, no LLM reasoning — just a lookup.

The numbers

We benchmarked AIR SDK against raw DOM-to-LLM browser automation on identical tasks:

Scenario Raw DOM + LLM AIR SDK Reduction
1 action (e.g., click search) $0.24 $0.0006 400x
10-step workflow $4.13 $0.0006 7,000x
Time per action ~5s <100ms 50x

The savings compound. The more agents use AIR, the more capabilities get verified, and the cheaper and faster every subsequent interaction becomes.

agent.json: robots.txt for AI agents

We also built agent.json — a standard for websites to declare what AI agents can do. Think robots.txt, but instead of “don’t crawl this,” it says “here’s how to search, here’s how to add to cart, here’s the API shortcut.”

Over 2,225 domains already indexed. Sites can publish their own at /.well-known/agent.json, or AIR learns capabilities automatically through agent reports.

How it works under the hood

AIR resolves capabilities through a tiered system:

  1. API fast-path — If the site has a known API endpoint, skip the browser entirely
  2. Verified macro — Pre-verified CSS selector sequences from prior agent reports
  3. Selector hints — Partial knowledge that reduces LLM reasoning cost
  4. Heuristic plan — For unknown sites, AIR generates a best-guess execution plan

Each tier is progressively more expensive but handles progressively less-explored territory. Most production traffic hits tiers 1-2 at near-zero cost.

Get started

npm install @arcede/air-sdk

Or add it as an MCP server in Claude Desktop, Cursor, or any MCP-compatible client.

Free tier: 1,000 capability executions/month. No credit card required.

MIT licensed. GitHub repo — stars appreciated.

We’re building AIR at Arcede. If you’re working on browser agents and want to integrate, reach out at [email protected] or open an issue on GitHub.

Discussion: WebGPU Performance and Local AI Inference

The evolution of WebGPU is finally making ‘Local AI’ a reality for the average user. Traditionally, running stable diffusion or large language models required a heavy Python environment or expensive cloud GPUs. However, by leveraging the browser’s access to local hardware via WebGPU, we can now achieve high-performance inference without any server-side logic. In my project, WebGPU Privacy Studio, I’ve seen that moving the compute to the client-side not only slashes latency but also fundamentally solves the privacy issue—since the data never leaves the user’s machine. I’m curious, for those of you working with WASM or WebGPU, what are the biggest bottlenecks you’ve hit when trying to port heavy models to the browser?

Hardening JavaScript JITs: Practical Mitigations for Modern Engines

  • [Why JavaScript JITs Are High-Value Targets]
  • [Common JIT Vulnerability Classes and How Exploits Chain]
  • [Applying CFI, PAC, and Memory Tagging Without Killing Performance]
  • [Process-Level JIT Sandboxing and Isolation Patterns]
  • [Fuzzing JS Engines: Targeted Strategies and Metrics]
  • [Practical Hardening Checklist and Rollout Plan]

The web’s fastest code is also its most dangerous: Just‑In‑Time compilers convert untrusted JavaScript into optimized native code with assumptions that are fragile under adversarial inputs, and those optimizations give attackers powerful primitives when they break. Treating JITs as the high-risk surface—not an afterthought—changes the defensive design choices you make in the renderer and the JS engine.

The browser stack shows the symptoms you already see in incident queues: repeated high-severity V8 crashes tied to type confusion and use‑after‑free, chains that start in JS types and escalate to native code execution and sandbox escapes. Those crash trends are exactly why teams are investing in CFI, pointer authentication, memory tagging, and targeted fuzzing rather than only ad‑hoc patches.

Why JavaScript JITs Are High-Value Targets

  • JITs operate on untrusted input and produce native code that sits immediately adjacent to sensitive state (object maps, inline caches, hidden fields). That combination concentrates leverage: a single type confusion or miscompilation can translate into an arbitrary read/write primitive.
  • The necessary performance tradeoffs (speculation, aggressive inlining, assuming stable hidden classes) create assumptions an attacker can deliberately violate; those assumptions are hard to validate at runtime without cost.
  • The JIT lifecycle—generate, write, then flip writable→executable—creates brief but powerful windows (race conditions, writable-exec races) attackers can weaponize unless memory protections are carefully architected (dual mappings, MAP_JIT semantics on Apple silicon, etc.).
  • Practical hardening must accept that you can’t remove the JIT; you must raise the cost of exploitation via layered mitigations that preserve throughput. This is both an engineering and a risk-management decision.

Common JIT Vulnerability Classes and How Exploits Chain

  • Type confusion (dominant class): Engine optimizers assume types; an object interpreted as a different shape can leak pointers or let arithmetic be interpreted as addresses. Historical and recent high‑severity V8 CVEs are typically in this class.
  • Use‑after‑free (temporal errors): Fast allocators, freelists and promotions create opportunities where freed memory is reallocated as attacker-controlled memory; the JS engine’s object model makes these easier to weaponize.
  • Out‑of‑bounds writes/reads in typed arrays / WebAssembly: Linear memory and typed views give simple, compact primitives for corruption with fewer chasing steps.
  • Integer overflow / miscompilation: Narrow integer math promoted to pointer offsets in JIT output produces OOB index calculations.
  • Information leaks and the_hole-style leaks: Small leaks (addresses, pointer authentication state, internal engine values) convert a crash into a complete exploit by removing ASLR/randomization assumptions.
  • Exploit chains typically follow a pattern: information leak → memory primitive (read/write) → corrupt code pointer or JIT code page → pivot to shellcode/ROP → sandbox escape. Hardening must break one or more of those steps cheaply.

Example (conceptual) warm‑up pattern that attackers use (not an exploit, only a pattern):

  • Warm up a cache to bias an inline cache toward doubles.
  • Trigger optimization that assumes doubles.
  • Feed an object of different shape to cause type confusion and an OOB access that yields an address or arbitrary write.

Applying CFI, PAC, and Memory Tagging Without Killing Performance

This is the meat: how to use modern mitigations in a pragmatic pipeline that keeps the JIT fast while making exploits materially harder.

  • Control‑Flow Integrity (CFI): Use compiler‑enforced CFI to restrict indirect calls and virtual dispatch to valid targets. Clang’s -fsanitize=cfi is production‑grade and was measured to add less than 1% overhead on a browser benchmark (Dromaeo) for forward‑edge checks; it requires LTO and careful handling of shared libraries and visibility.

    • Practical compiler flags example: compile hot modules with CFI and -flto then link statically where possible. See -fsanitize=cfi and the schemes cfi-vcall, cfi-icall.
# minimal example (concept level)
clang++ -O2 -flto -fsanitize=cfi -fvisibility=hidden -fno-sanitize-recover=all 
  -o v8_component.so v8_component.cc
  • Per-thread / pkey sandboxing for JIT code: Use hardware mechanisms (Memory Protection Keys on x86 PKU/pkeys, Partitioned protection) to make JIT code pages non-writable in the fast path and only enable a writable domain transiently when generating code; V8 has experimental pkey-based sandbox support flags and bytecode verification hooks for this model. That reduces write→exec race surfaces with low steady-state cost.
  • Pointer Authentication (PAC) — hardware LR/RET protection: On ARMv8.3+ platforms, PAC signs pointers and thwarts classic ROP/return-target corruption when used correctly. PAC is effective but not invulnerable—the PACMAN attack shows microarchitectural techniques can forge PAC values on some CPUs, so PAC is a strong layer but not sole reliance. Balance PAC with other mitigations.
  • Memory Tagging (ARM MTE / HWASan / GWP‑ASan): MTE provides lightweight spatial/temporal checks via tags (4-bit tag per 16‑byte granule) and has SYNC/ASYNC modes; SYNC is for testing and ASYNC is designed for production, yielding low run‑time overhead when used in sampling or targeted processes. Use MTE in testing or as a production sampling mode to catch UAF/OOB errors with minimal impact; Android’s guidance documents both the modes and integration paths.
  • Pointer‑safety wrappers (MiraclePtr / BackupRefPtr / raw_ptr): Use compiler-assisted checked pointer types to catch/deter use‑after‑free; Chromium’s raw_ptr/MiraclePtr rollout shows this can be automated at scale with controlled perf monitoring.

Table: Mitigations — coverage, expected impact, deployment notes

Mitigation What it raises the attacker cost for Typical perf impact Practical rollout note
CFI (-fsanitize=cfi) Indirect call / vtable abuse (blocks many gadget chains). Low (<1% measured in Dromaeo for forward-edge checks) . Enables via LTO; roll out hot-path modules first.
PKEY sandbox (pkey) Prevents out‑of‑sandbox writes to code/metadata; reduces write→exec races. Very low for steady-state (toggle cost on codegen). V8 experimental support exists; test on linux/x64.
PAC (Pointer Auth.) Prevents forged return/target pointers on ARM hw. Low at hardware level; software emulation expensive (~26% in PTAuth emulation). Use as a layer, not a single point of failure (PACMAN caveat).
MTE (Memory Tagging) Detects UAF/OOB at hardware level (temporal/spatial). SYNC = higher (debug), ASYNC = low (production) per Android guidance. Use in testing (SYNC) and sampled production (ASYNC/reporting).
MiraclePtr / raw_ptr Hardens common UAF vectors via checked pointers. Varies—monitor with bots; Chrome ran experiments. Incremental rewrite with clang plugin; measure perf.

Important: No single mitigation is a silver bullet. PAC and CFI make exploitation harder, MTE/GWP‑ASan find bugs, and pkey protection reduces race exploitation windows; layered deployment stops real attackers, not theoretical ones.

Process-Level JIT Sandboxing and Isolation Patterns

  • Trusted heap / external pointer tables: Move critical metadata (bytecode arrays, code pointers) into a small, trusted region that’s strongly write-protected and only accessible via vetted brokers or syscalls; the V8 sandbox design migrates sensitive items into trusted space to reduce the blast radius of a compromised JITed execution context.
  • Split renderer / utility processes for JIT work: Keep the JIT-enabled renderer tightly sandboxed and, where possible, move non-JIT functionality out-of-process so a compromised renderer cannot access sensitive handles. Site/process isolation remains a strong platform control.
  • Dual-mapping / MAP_JIT and writable staging pages: On platforms like macOS Apple silicon, MAP_JIT semantics and a dual-mapping approach (execute-only mapping + hidden writable mapping) are used to enforce W^X and reduce the readability of writable staging memory; this reduces attackers’ ability to find the writable region and to produce reliable gadgets. Apple’s JIT entitlement rules and MAP_JIT details are relevant here.
  • Sandbox enforcement of system calls (seccomp/LPAC/etc): Block syscalls that would assist exploitation or make it noisier (e.g., reduce available IPC handles, limit mprotect usage to only validated flows). Chromium’s ongoing sandbox work and process hardening are designed to make a renderer compromise much less useful.
  • Practical constraint: Some OS/hardware combos don’t support the same features (pkeys, MTE, PAC); implement a capability matrix and enable features opportunistically per-platform.

Fuzzing JS Engines: Targeted Strategies and Metrics

  • Use a modern JS grammar-aware fuzzer (Fuzzilli) and scale it via ClusterFuzz/OSS‑Fuzz: Fuzzilli’s FuzzIL intermediate language and mutation strategies work well for JIT paths because they preserve semantic structure while generating diverse inputs; run it continuously against all engine tiers (baseline, optimizing JIT, wasm) and integrate crashes into triage.
  • Leverage sanitizers for root cause detail during triage: Use ASan/HWASan for test builds and GWP‑ASan for production sampling to gather actionable stack traces from real crashes without large production overhead. GWP‑ASan is intentionally sampled so it runs in production with negligible overhead while still uncovering real UAFs.
  • Sandbox fuzzing modes and bytecode verification: Enable engine test harness flags that perform full bytecode verification and sandbox fuzzing modes (V8 supports --verify_bytecode_full / sandbox testing flags) so the fuzzer explores invalid states that would otherwise be filtered.
  • Execution harness patterns: Use REPRL-style harnesses (read-eval-print-reset-loop) to get fast iteration and avoid process startup cost when fuzzing heavy engines; Fuzzilli, ClusterFuzz and V8 test harnesses support this model.
  • Metrics you must track: unique crash count (per day/week), time-to-triage, percentage of fuzz-derived fixes landed, reduction in production unique crashes post-mitigation, mean time between high-severity engine CVEs. Use these to prioritize mitigations by attacker ROI.

Sample fuzzing invocation (conceptual):

# build and run Fuzzilli against a D8 build (concept level)
swift run -c release FuzzilliCli --profile=v8 --storagePath=/var/fuzzilli-storage /path/to/d8

Practical Hardening Checklist and Rollout Plan

This is a pragmatic, low‑risk roadmap you can implement over 8–12 weeks with measurable checkpoints.

Week 0: Baseline and telemetry

  1. Baseline current crash surface: collect crash rates/unique crash hashes for JIT paths. Instrument telemetry to separate JIT-related crashes. (Metric: unique JIT crash/day) .
  2. Ensure your CI produces AddressSanitizer builds and has a simple fuzzing integration.

Weeks 1–4: Find and fix

  1. Run Fuzzilli + ClusterFuzz on the current engine build and dedicate triage rotation to prioritized crashes (start with engine components that have been historically exploitable). (Metric: unique crash reduction after triage roll.)
  2. Deploy GWP‑ASan sampling to a small percentage of production processes to catch long-tail UAFs that fuzzing misses. (Metric: new actionable reports/week.)

Weeks 4–8: Low-hanging hardening

  1. Add raw_ptr/MiraclePtr conversions for high‑risk pointer types (use the clang plugin and bots to track perf). Monitor perf dashboards carefully.
  2. Enable selective -fsanitize=cfi for high-value components compiled with LTO (start with dev/profiling builds, then canary). Measure overhead and false positives; add ignorelists where necessary.
  3. Turn on V8 bytecode verification (--verify_bytecode_full) on fuzzing and canary builds to catch generator bugs earlier.

Weeks 8–12+: Platform hardening

  1. Prototype pkey-based JIT sandboxing on Linux x64 (V8 experimental flag) for an internal canary build and measure performance/regressions.
  2. Plan for PAC-aware builds on ARM servers where available; account for PACMAN limitations by pairing PAC with MTE or other runtime checks. Use PTAuth/academic results to budget expected overhead.
  3. Instrument progressive rollout gates: canary → dev channel → beta → stable, gating on crash and perf SLIs.

Checklist (quick):

  • [ ] Corpus + Fuzzing (Fuzzilli + ClusterFuzz) in CI.
  • [ ] GWP‑ASan sampling in production.
  • [ ] -fsanitize=cfi rollout plan + LTO build validation.
  • [ ] raw_ptr/MiraclePtr conversion for key data structures.
  • [ ] pkey/MTE/PAC capability matrix by platform and test harnesses for each.
  • [ ] Bytecode verification enabled in fuzzing and testing builds.

Rollout considerations and risk controls

  • Use staged rollouts and automated perf regressions to catch surprises early.
  • Keep a rollback plan and debug flags for investigative builds (e.g., enable CFI diagnostics only for a short window).
  • Measure attacker cost improvements (time‑to‑exploit in a red‑team exercise, or variant-analysis difficulty) in addition to raw perf metrics; these security economics numbers motivate the larger changes.

Sources
Chrome Security Quarterly Updates – Quarterly summaries describing V8 sandbox work, CFI plans, Fuzzilli improvements, GWP‑ASan deployment and other Chrome security engineering priorities drawn from Chrome Security team updates.

V8 flag definitions (pkey / sandbox / bytecode verification) – V8 source flags showing strict_pkey_sandbox, verify_bytecode_full, and sandbox/fuzzing flags and their intent.

Clang Control Flow Integrity documentation – Implementation details for -fsanitize=cfi, LTO requirements, measured performance notes (Dromaeo <1% example) and available schemes.

Arm Memory Tagging Extension (MTE) — Android NDK guide – Explanation of MTE, operating modes (SYNC/ASYNC), and guidance for enabling/testing MTE on Android devices.

PACMAN: Attacking ARM Pointer Authentication (PACMAN) – MIT/DEF CON paper and PoC summary describing how speculative execution/microarchitectural side channels can bypass PAC on some hardware.

PTAuth: Temporal Memory Safety via Robust Points-to Authentication (arXiv / USENIX) – Research prototype leveraging PAC for temporal memory safety with measured overheads (software-emulated and expected hardware figures).

Fuzzilli — Google Project Zero (GitHub) – The JavaScript engine fuzzer (FuzzIL), architecture and usage notes for fuzzing V8/SpiderMonkey/JSC, used by engine security teams.

JS‑Fuzzer (ClusterFuzz / V8 tools README) – ClusterFuzz/JS fuzzer guide and practical commands for building and running JavaScript fuzzers against shells.

GWP‑ASan: Sampling heap memory error detection in‑the‑wild (Chromium) – Design, rationale and deployment notes for GWP‑ASan in Chrome production to detect heap bugs with negligible overhead.

Just‑In‑Time compilation and JIT memory regions on macOS (discussion / guide) – Practical description of MAP_JIT, com.apple.security.cs.allow-jit entitlement and dual-mapping/Bulletproof JIT-style approaches on Apple platforms.

Dangling Pointer Detector / raw_ptr usage (Dawn / Chromium docs) – Documentation and rollout notes describing raw_ptr, MiraclePtr/BackupRefPtr strategies and clang tooling used in Chromium’s pointer-hardening efforts.

Start by fixing what the fuzzers and GWP‑ASan report, then layer CFI + pointer protections + lightweight hardware checks where platform support exists; every layer you add multiplies the attacker’s cost and narrows the window an exploit needs to chain into a real compromise.

Recreating Apple’s Liquid Glass Effect on the Web with CSS, SVG, and Physics-Based Refraction Calculations

cover

cover

Introduction: The Liquid Glass Challenge

Apple’s liquid glass effect is a visual masterpiece—a seamless blend of transparency, refraction, and fluid motion that mimics the behavior of light passing through a curved glass surface. It’s not just aesthetically pleasing; it’s a testament to the marriage of art and physics. But replicating this effect on the web? That’s a different beast entirely. The challenge lies in translating real-world physics into browser-compatible code, where CSS, SVG, and computational refraction calculations must work in harmony to deceive the eye into believing it’s witnessing actual glass.

The core problem is twofold: refraction and deformation. In the physical world, light bends as it passes through glass due to changes in density—a phenomenon governed by Snell’s Law. On the web, this requires simulating light rays and their interaction with a virtual surface. Simultaneously, the liquid glass effect demands that this surface deforms dynamically, as if influenced by external forces like gravity or touch. This deformation isn’t just visual; it must alter the path of simulated light rays in real time, creating a convincing illusion of depth and movement.

The technical hurdles are steep. CSS and SVG, while powerful, weren’t originally designed for physics-based simulations. SVG displacement maps can warp images, but they lack the precision needed for accurate refraction. Physics calculations, meanwhile, are computationally expensive and risk slowing down the browser. Yet, as Chris Feijoo demonstrates in “Liquid Glass in the Browser”, these challenges aren’t insurmountable. By combining SVG filters for deformation, CSS for animation, and JavaScript for physics calculations, a workable solution emerges.

But not all approaches are created equal. Let’s compare three potential solutions:

  • Pure CSS Approach: Limited by CSS’s inability to handle complex physics calculations. While animations are smooth, refraction effects are static and lack realism.
  • SVG Displacement Maps + JavaScript: Offers dynamic deformation but struggles with real-time refraction. The computational load increases with complexity, risking performance degradation.
  • Hybrid Approach (CSS + SVG + Physics Calculations): Optimal for balancing performance and realism. CSS handles animations, SVG manages deformation, and JavaScript computes refraction. This distributes the workload efficiently, though it requires careful optimization to avoid bottlenecks.

The hybrid approach is the clear winner—but with a caveat. It breaks down when the number of light rays or deformation points exceeds the browser’s processing capacity. For large-scale implementations, offloading calculations to WebGL or WebAssembly becomes necessary. A rule of thumb: If the effect involves more than 100 deformation points or requires real-time interaction, use the hybrid approach with WebGL fallback.

The stakes are high. Without such innovations, web design risks becoming a static, two-dimensional medium in a world craving immersion. Mastering these techniques isn’t just about replicating Apple’s aesthetic—it’s about pushing the boundaries of what’s possible in the browser. As user expectations evolve, so must our tools and techniques. The liquid glass effect is more than a visual gimmick; it’s a glimpse into the future of web design.

Scenario Breakdown: Six Paths to Refraction

Recreating Apple’s liquid glass effect on the web isn’t a one-size-fits-all problem. Each approach to refraction simulation involves unique trade-offs between realism, performance, and complexity. Below, we dissect six distinct scenarios, analyzing their mechanisms, limitations, and optimal use cases.

1. Pure CSS Approach: The Illusion of Refraction

Mechanism: Uses CSS animations (e.g., transform: skew() and filter: blur()) to mimic light bending. No actual physics calculations—relies on visual tricks.

Trade-off: Smooth animations but static, unrealistic refraction. Light paths don’t adjust to surface deformation or viewer angle. Breaks down when dynamic interaction is required.

Rule: If static visuals with minimal interactivity are acceptable, use pure CSS. Otherwise, avoid.

2. SVG Displacement Maps: Warping Without Physics

Mechanism: SVG filters (<feDisplacementMap>) deform an image based on a height map. No refraction calculations—only surface distortion.

Limitation: Displacement maps lack precision for realistic refraction. Light bends uniformly, ignoring Snell’s Law. Fails under close inspection or dynamic lighting.

Rule: Use for subtle deformation effects where refraction realism isn’t critical. Pair with CSS for animation.

3. JavaScript Physics Simulation: Snell’s Law in Action

Mechanism: Calculates light paths using Snell’s Law (n₁ sin θ₁ = n₂ sin θ₂) for each pixel. Computationally expensive but accurate.

Risk: Browser slowdown with >100 deformation points. Garbage collection spikes as memory fills with intermediate calculations.

Rule: If real-time, accurate refraction is required, use JavaScript. Throttle calculations or offload to Web Workers for performance.

4. Hybrid Approach: CSS + SVG + JavaScript

Mechanism: Distributes workload:

  • CSS: Handles animations (e.g., @keyframes for fluid motion)
  • SVG: Manages surface deformation via <feDisplacementMap>
  • JavaScript: Computes refraction angles using Snell’s Law

Optimality: Balances realism and performance. Fails at >100 deformation points or with real-time interaction due to JavaScript bottlenecks.

Rule: Use for medium-complexity effects. Add WebGL fallback for scalability.

5. WebGL/WebAssembly Acceleration

Mechanism: Offloads physics calculations to GPU via WebGL shaders or WebAssembly. Parallel processing handles thousands of deformation points.

Trade-off: Steeper learning curve. Browser compatibility issues with older devices. Requires shader programming knowledge.

Rule: If large-scale, real-time effects are needed, use WebGL/WebAssembly. Pair with hybrid approach for fallback.

6. Pre-Rendered Video Fallback

Mechanism: Renders the liquid glass effect offline (e.g., with Blender) and embeds as video. No real-time calculations.

Limitation: Static content—no interactivity. File size increases with resolution and duration.

Rule: Use for marketing pages where interactivity isn’t required. Combine with CSS animations for pseudo-interactivity.

Comparative Analysis: Which Path to Choose?

Approach Realism Performance Interactivity Optimal Use Case
Pure CSS Low High None Static visuals
SVG Displacement Medium Medium Limited Subtle deformation
JavaScript Physics High Low Full Small-scale effects
Hybrid High Medium Medium Medium-complexity
WebGL/Wasm Highest High Full Large-scale effects
Pre-Rendered Video High High None Non-interactive content

Professional Judgment: The hybrid approach is optimal for most projects, balancing realism and performance. For large-scale implementations, WebGL/WebAssembly is non-negotiable. Avoid pure CSS or SVG-only methods unless realism is sacrificed intentionally.

Technical Deep Dive: CSS, SVG, and Physics in Harmony

Recreating Apple’s liquid glass effect on the web isn’t just about aesthetics—it’s a collision of art, physics, and code. At its core, the effect relies on three phenomena: transparency, refraction, and fluid motion. To replicate this, we harness CSS for animations, SVG for deformation, and physics-based calculations for realistic light bending. Here’s how these technologies intertwine to achieve the illusion of liquid glass.

1. Refraction: The Physics Behind Light Bending

The key to realism lies in Snell’s Law: n₁ sin θ₁ = n₂ sin θ₂. When light passes from one medium (air) to another (glass), it bends. This bending is governed by the refractive indices of the materials. In our case, we simulate this by calculating the angle of incidence and refraction for each pixel. The challenge? Snell’s Law requires per-pixel calculations, which are computationally expensive. JavaScript handles this, but it risks browser slowdown beyond 100 deformation points. Mechanism: Light rays interact with the virtual glass surface, and their paths are recalculated based on the surface’s curvature and refractive index. Impact: Without accurate refraction, the effect looks flat and unnatural.

2. Deformation: Warping the Surface in Real Time

To mimic fluid motion, the glass surface must deform dynamically. SVG displacement maps are used to warp the surface based on a height map. However, SVG’s lacks precision for realistic refraction, as it applies uniform bending without considering Snell’s Law. Mechanism: The height map defines the displacement of the surface, causing light rays to bend differently across the glass. Impact: Inaccurate deformation leads to unrealistic light paths, breaking the illusion of liquidity.

3. Hybrid Approach: Balancing Realism and Performance

The optimal solution combines CSS, SVG, and JavaScript. CSS handles smooth animations, SVG manages surface deformation, and JavaScript calculates refraction angles. This distribution of tasks minimizes performance bottlenecks. Mechanism: CSS animates the glass’s movement, SVG warps the surface, and JavaScript adjusts light paths in real time. Impact: The effect becomes immersive, but it breaks down with >100 deformation points or real-time interaction due to JavaScript’s computational limits.

Comparative Analysis of Approaches

  • Pure CSS: Uses transform: skew() and filter: blur() for static refraction. Trade-off: Unrealistic, no interactivity. Use Case: Static visuals.
  • SVG Displacement Maps: Uniform light bending, ignores Snell’s Law. Trade-off: Subtle effects only. Use Case: Non-critical realism.
  • JavaScript Physics Simulation: Accurate refraction but slows down with complexity. Trade-off: Performance risk. Use Case: Small-scale effects.
  • Hybrid Approach: Optimal balance for medium-complexity effects. Limitation: Fails at scale. Use Case: Most projects.
  • WebGL/WebAssembly: Offloads calculations to GPU. Trade-off: Steeper learning curve. Use Case: Large-scale effects.
  • Pre-Rendered Video: Static, no interactivity. Use Case: Non-interactive content.

Professional Judgment: When to Use What

Rule of Thumb: For most projects, the hybrid approach is optimal, balancing realism and performance. However, for large-scale implementations, WebGL/WebAssembly is essential. Avoid pure CSS or SVG-only methods unless realism is intentionally sacrificed. Mechanism: The hybrid approach distributes the workload efficiently, but it collapses under high complexity due to JavaScript’s single-threaded nature. WebGL/WebAssembly bypasses this by leveraging the GPU, but it requires more expertise.

Edge Cases and Risks

One common error is overloading JavaScript with real-time calculations, leading to browser slowdown. Mechanism: Excessive deformation points force JavaScript to recalculate light paths for each pixel, exceeding the browser’s processing capacity. Solution: Throttle calculations or use Web Workers. Another risk is ignoring Snell’s Law, resulting in unrealistic light bending. Mechanism: Without accurate physics, the effect loses its immersive quality. Solution: Always incorporate physics-based calculations, even if simplified.

In conclusion, recreating Apple’s liquid glass effect requires a deep understanding of the interplay between CSS, SVG, and physics. By combining these technologies thoughtfully, designers can push the boundaries of web design, ensuring the web remains a dynamic and engaging medium.

FileBrowser Alternatives for Mobile: A Self-Hoster’s Comparison Guide

The Problem

If you self-host FileBrowser, you know the desktop experience is solid. But open it on your phone and you’ll hit:

  • Tiny touch targets — buttons designed for mouse precision
  • Hover-dependent menus — nonexistent on touchscreens
  • Preview-second design — it’s a file manager, not a file viewer

For mobile, you want the opposite: preview-first, big tap areas, minimal navigation depth.

I tested the major alternatives. Here’s the comparison.

Quick Comparison

Tool Primary Use Mobile UX Self-Host Effort Customizable License
Filestash File browsing + preview ⭐⭐⭐⭐ Docker 1-liner Yes (Vue/JS) AGPL-3
AList Multi-storage aggregator ⭐⭐⭐⭐ Docker 1-liner Limited (Go) AGPL-3
Dufs Minimal HTTP file server ⭐⭐⭐ Single binary No MIT
FileBrowser File management ⭐⭐ Docker 1-liner Limited (Vue) Apache-2
Nextcloud Full cloud platform ⭐⭐ Complex stack Yes (PHP) AGPL-3
Cockpit Server admin panel ⭐ apt install No LGPL
code-server Remote VS Code ⭐ Docker Yes MIT

Tier 1: Filestash

Best for: Read-only browsing, markdown/code preview, mobile PWA

Filestash connects to your server via SFTP, WebDAV, S3, or Git, and renders a clean mobile-friendly UI. Files open in preview mode by default — markdown renders, code gets syntax highlighting, videos play inline.

Deploy

# docker-compose.yml
version: '3'
services:
  filestash:
    image: machines/filestash
    restart: always
    ports:
      - "8334:8334"
    volumes:
      - ./data:/app/data/state
docker compose up -d
# Open http://your-server:8334
# Configure SFTP backend pointing to your server

Mobile PWA Setup

  1. Open Filestash URL in Safari/Chrome on your phone
  2. Tap Share → “Add to Home Screen”
  3. Now it opens fullscreen — no browser chrome, feels like a native app

Why It Works

  • Preview-first: Click file → see content immediately
  • Touch-friendly: Large tap targets, no hover dependencies
  • Frontend is Vue/JS: If you want to customize mobile UX (card layout, feed view, larger buttons), fork and modify

Limitations

  • Not perfect on mobile — community notes the webapp can feel sluggish with large directories
  • No native iOS/Android app
  • AGPL license (important if you distribute modifications)

Tier 2: AList

Best for: Multi-storage browsing, video playback, aggregating cloud + local storage

AList isn’t a file browser — it’s a storage aggregator with a web frontend. Mount local dirs, Google Drive, S3, OneDrive, WebDAV all in one place.

Deploy

docker run -d --restart=unless-stopped 
  -v /etc/alist:/opt/alist/data 
  -p 5244:5244 
  -e PUID=0 -e PGID=0 
  --name="alist" 
  xhofe/alist:latest
# Get admin password
docker exec -it alist ./alist admin random
# Open http://your-server:5244

Strengths

  • Video playback is excellent — streams directly in browser
  • Big mobile-friendly buttons
  • Multi-backend: Local + cloud drives in one UI
  • Active community, regular updates

Limitations

  • Built on Go — UI customization requires modifying the embedded frontend
  • More suited as a “content aggregator” than a “file browser”
  • Overkill if you only need to browse one local directory

Tier 3: Dufs

Best for: Zero-config directory serving, temporary file sharing

Dufs is a single Rust binary. No config, no database, no Docker required (though Docker works too).

Deploy

# Direct binary
curl -fsSL https://github.com/sigoden/dufs/releases/latest/download/dufs-x86_64-unknown-linux-musl -o dufs
chmod +x dufs
./dufs /path/to/your/files -p 5000 --allow-search

# Docker
docker run -v /path/to/files:/data -p 5000:5000 sigoden/dufs /data

Strengths

  • Zero overhead — ~5MB binary, no dependencies
  • HTTP directory listing with basic file preview
  • Built-in upload, search, auth
  • Works surprisingly well on mobile (responsive design)

Limitations

  • Bare-bones UI — no rich markdown rendering, no fancy preview
  • No multi-backend support
  • Not designed for heavy daily use

What to Avoid (for Mobile)

❌ Nextcloud / Seafile

Heavy stack (DB + Redis + cron + WebDAV). Slow on mobile. Designed for team collaboration — massive overkill for personal file browsing. If you deploy it for “just viewing files”, you’ll spend more time maintaining it than using it.

❌ Cockpit

Server admin panel. Has a file section but it’s an afterthought. Don’t install a 200MB admin suite to browse markdown files.

❌ code-server

VS Code in the browser. Fantastic on iPad with a keyboard. Unusable on a phone screen — too many tiny UI elements, too much complexity.

❌ SFTP Apps (Free Tiers)

Termius and FE File Explorer both work, but free tiers lock key features (device sync, multiple connections). The freemium model is designed to frustrate you into paying.

The Optimal Setup

After testing everything, the best mobile experience comes from layering tools:

Phone (mobile browser)
  └── Filestash (browse + preview) ← primary
  └── AList (video playback) ← when needed

Desktop (regular browser)  
  └── FileBrowser (file management)
  └── SSH terminal (admin tasks)

Architecture Decision: If You Want to Customize

Both Filestash and AList are open source. Here’s where to fork:

Goal Fork This Why
Mobile UX improvements Filestash Vue/JS frontend, easy to modify
Add storage backends AList Clean Go backend, modular drivers
Custom preview engine Filestash Plugin-based viewer system
API-only file access AList Well-documented REST API

The “ultimate” architecture for power users:

  • AList as the storage aggregation layer (handles all backend connections)
  • Custom frontend (Next.js/Vue) consuming AList’s API
  • Feed-based UI (recent files, search-first, no path navigation)

Key Insight

The fundamental problem with phone file browsers isn’t the tools — it’s the mental model. Desktop file managers assume path-based navigation: /home/user/docs/project/file.md. On a 6-inch screen, this is hostile UX.

The best mobile tools minimize directory traversal:

  • Preview-first: Click = see content, not open folder
  • Search-first: Find by name, not by path
  • Recency-first: Show recent files, not root directory

Pick tools that match this model. Your phone will thank you.

Running a homelab? Filestash + Docker takes 2 minutes to deploy. Try it before building anything custom.

Beyond the Hype: Building Practical AI Agents with Memory and Reasoning

Your Agent Can Think. But Can It Remember?

If you’ve been following the AI space recently, you’ve likely seen the explosion of content around AI agents. The conversation often centers on a powerful dichotomy: reasoning versus memory. An agent that can reason can analyze a problem step-by-step. An agent with memory can learn from past interactions. But as many developers are discovering, creating an agent that effectively does both is where the real engineering challenge—and opportunity—lies.

The recent article highlighting that “your agent can think. it can’t remember.” struck a chord because it points to a fundamental gap in many current implementations. We get mesmerized by an LLM’s chain-of-thought reasoning, only to watch it fail on the second iteration of a task because it has the memory of a goldfish.

This guide is a practical, code-first dive into moving beyond that limitation. We’ll move from theory to implementation, building a simple yet powerful AI agent that integrates structured reasoning with persistent, context-aware memory. Let’s build an agent that doesn’t just solve a problem once, but gets better at solving it over time.

The Core Architecture: Reasoning, Memory, and Tools

A robust agent system rests on three pillars:

  1. The Reasoner (The “Brain”): Typically an LLM (like GPT-4, Claude, or an open-source model) that processes input, makes decisions, and formulates plans.
  2. The Memory (The “Experience”): A storage system that persists information across interactions. This is more than just chat history; it’s structured knowledge.
  3. The Tools (The “Hands”): Functions the agent can call to interact with the world—searching the web, running code, querying a database.

The breakdown happens when these components are siloed. The reasoner isn’t guided on what to remember or how to retrieve it efficiently.

Implementing Persistent Memory: A Vector Database Approach

The simplest form of memory is a conversation buffer. But for an agent to be truly useful, its memory should be semantic. It should remember concepts, not just text. This is where vector databases shine.

Let’s implement a VectorMemory class using langchain and ChromaDB (a lightweight, open-source vector store).

from langchain.embeddings import OpenAIEmbeddings
from langchain.vectorstores import Chroma
from langchain.schema import Document
from datetime import datetime
import uuid

class VectorMemory:
    def __init__(self, persist_directory="./agent_memory"):
        self.embeddings = OpenAIEmbeddings()
        self.vectorstore = Chroma(
            embedding_function=self.embeddings,
            persist_directory=persist_directory
        )
        self.session_id = str(uuid.uuid4())[:8]  # Track current session

    def remember(self, observation: str, metadata: dict = None):
        """Store an observation with context."""
        if metadata is None:
            metadata = {}
        metadata.update({
            'timestamp': datetime.utcnow().isoformat(),
            'session': self.session_id
        })
        doc = Document(page_content=observation, metadata=metadata)
        self.vectorstore.add_documents([doc])
        print(f"[Memory] Stored: {observation[:50]}...")

    def recall(self, query: str, k: int = 3, filter_session: bool = True):
        """Retrieve relevant past memories."""
        filter_dict = {'session': self.session_id} if filter_session else None
        results = self.vectorstore.similarity_search(
            query, k=k, filter=filter_dict
        )
        memories = [f"- {doc.page_content} (Context: {doc.metadata})" for doc in results]
        return "n".join(memories) if memories else "No relevant memories found."

# Initialize memory
agent_memory = VectorMemory()
agent_memory.remember(
    "User prefers API responses in JSON format.",
    {'preference_type': 'output_format', 'user_id': 'alice'}
)

This memory system stores each observation with metadata and allows for semantic search. The agent can now recall that “Alice likes JSON” when planning a response, even if we don’t use those exact words.

Integrating Memory into the Agent’s Reasoning Loop

Memory shouldn’t be an afterthought; it must be part of the agent’s cognitive cycle. We modify the agent’s prompt to include a “Relevant Memory” section and a directive to update memory with new learnings.

Here’s a simplified reasoning loop:

from langchain.llms import OpenAI
from langchain.prompts import PromptTemplate
from langchain.chains import LLMChain
import json

class PracticalAgent:
    def __init__(self, memory):
        self.llm = OpenAI(temperature=0)
        self.memory = memory
        self.prompt = PromptTemplate(
            input_variables=["input", "memories", "tools"],
            template="""
            You are a practical AI agent. Use your memory and tools to assist the user.

            RELEVANT PAST MEMORIES:
            {memories}

            USER'S REQUEST:
            {input}

            AVAILABLE TOOLS:
            {tools}

            INSTRUCTIONS:
            1. Analyze the request and relevant memories.
            2. Decide if you need to use a tool. If so, output a JSON blob with 'tool' and 'input' keys.
            3. If no tool is needed, provide a direct response.
            4. Conclude by specifying a NEW, USEFUL observation to store in memory. Format it as: `MEMORY: <observation>`

            Your response:
            """
        )
        self.chain = LLMChain(llm=self.llm, prompt=self.prompt)

    def run(self, user_input: str):
        # Step 1: Recall relevant memories
        memories = self.memory.recall(user_input)

        # Step 2: Generate reasoning and action
        tools_desc = "1. web_search(query): Search the web.n2. calculate(expression): Evaluate math."
        response = self.chain.run(input=user_input, memories=memories, tools=tools_desc)

        # Step 3: Parse response for tool use OR memory update
        if "MEMORY:" in response:
            direct_response, memory_observation = response.split("MEMORY:")
            memory_observation = memory_observation.strip()
            self.memory.remember(
                memory_observation,
                {'triggered_by_input': user_input[:30]}
            )
            return direct_response.strip()
        return response

# Let's see it in action
agent = PracticalAgent(agent_memory)
print("First interaction:")
result1 = agent.run("What's the weather like today?")
print(result1)

print("nSecond interaction:")
# The agent might recall a past preference about detail level
result2 = agent.run("Tell me a fun fact about Mars.")
print(result2)

In this loop, the agent is prompted to explicitly decide what to remember at the end of each turn, creating a continuous learning cycle.

Advanced Pattern: Reflection and Memory Pruning

A sophisticated agent doesn’t just accumulate memories; it reflects on them. Implementing a periodic “reflection” step can consolidate memories and prune irrelevant ones.

class ReflectiveAgent(PracticalAgent):
    def reflect(self):
        """Periodically review and summarize key memories."""
        print("n[Agent] Initiating reflection cycle...")
        # Get recent memories
        broad_memories = self.memory.recall("learning experience insights", k=10, filter_session=False)

        reflection_prompt = f"""
        Review these past interactions and learnings:
        {broad_memories}

        Identify the top 3 most important, persistent user preferences or factual lessons learned.
        Output them as concise, standalone statements for long-term storage.
        """
        reflection = self.llm(reflection_prompt)

        # Store the consolidated reflections as high-priority memory
        for statement in reflection.strip().split('n'):
            if statement:
                self.memory.remember(
                    f"Reflected Insight: {statement}",
                    {'type': 'reflection', 'priority': 'high'}
                )
        # Optional: Implement logic to clean up old, low-relevance memories here
        print("[Agent] Reflection complete. Key insights consolidated.")

Key Takeaways and Your Next Steps

Building a thinking and remembering agent requires a shift from viewing memory as a log to treating it as a structured, queryable knowledge graph. We’ve built the foundation:

  1. Semantic Memory: Use vector databases to store and retrieve memories by meaning, not just keywords.
  2. Integrated Loop: Bake memory recall and storage directly into the agent’s prompt and execution cycle.
  3. Proactive Learning: Instruct the agent to identify and store useful observations actively.
  4. Reflection: Add higher-order processes to consolidate learning and manage memory growth.

Your Call to Action: Start small. Take your existing agent prototype and integrate a simple vector memory system. The first experiment is straightforward: after each interaction, ask the LLM, “What is the single most important thing to remember from this exchange?” and store it. You’ll immediately see the qualitative jump in your agent’s coherence over long interactions.

The frontier of AI agents isn’t just about more complex reasoning; it’s about building agents with experiences, context, and the ability to learn from their own digital lives. Stop building goldfish. Start building elephants.

What’s the first task you’ll give an agent that can remember? Share your ideas in the comments below.