Why Your SaaS Node Backend Will Fail at 10k Requests/Minute (and How to Stress‑Proof It Without Rewriting)

At 1k active users, your Node backend feels like a rock.

At 3k–5k users, Stripe webhooks start retrying, background jobs pile up, and you notice the first “duplicate charge” ticket.

At 8k–10k requests per minute, you’re in a live incident: jobs vanish on deploy, webhook duplicates double‑bill customers, and MFA state drifts, leaving users locked out.

Node is great—but naïve implementations won’t survive SaaS‑scale.

Here’s exactly what breaks and how to stress‑proof it without a full rewrite.

If you’re:

  • building a Node.js + TypeScript SaaS backend,
  • handling Stripe webhooks, background jobs, and auth,
  • and worried that your current architecture will fall apart at 3k–10k requests per minute,

then this post is for you.

What Actually Breaks at 10k RPM in Node

1. Silent Job Loss & Race Conditions

If your background jobs rely on setTimeout or an in‑memory array, a simple git push will wipe them out.

But the real pain starts when workers race for the same job.

Example: A Stripe checkout.session.completed event triggers a job to deliver a license.

Two workers both see the job as “pending” → both claim it → customer receives two licenses.

Pattern that fails:

// Naive in‑memory queue
const jobs = [];

setInterval(() => {
  const job = jobs.shift();
  if (job) process(job);
}, 1000);

What survives:

  • Persistent queue (Redis, RabbitMQ, Postgres with SKIP LOCKED).
  • Atomic claim: the first worker to “lock” the job wins; others skip it.
  • Crash recovery: jobs are persisted before execution, so a worker crash doesn’t lose them.

2. Stripe Webhook Race Conditions

Stripe retries slow webhooks. If your handler is not idempotent, each retry creates a new charge, subscription, or email.

Fragile handler:

app.post('/stripe-webhook', async (req, res) => {
  const event = req.body;
  await db.invoices.insert({ stripeId: event.id });
  await sendReceiptEmail();
  res.sendStatus(200);
});

If two identical events arrive concurrently, both will insert duplicate rows.

Idempotency fix:

  • Use a unique constraint on (stripe_event_id, event_type).
  • Or wrap the handler in an atomic guard that checks a “processed” flag before doing work.

3. Auth & MFA State Drift

When your authentication relies on in‑memory sessions or local cookies without server‑side validation, you risk:

  • Users being able to bypass MFA after a session token is stolen.
  • “MFA required” being enforced only in the UI, not on the API.

Example: A user enables MFA, but the API still allows them to change their billing email without a second factor. An attacker with a stolen session can compromise the account.

What’s needed:

  • Stateless tokens (JWT) with explicit permissions.
  • Per‑action MFA enforcement on sensitive routes (e.g., POST /api/billing/change-email), not just a flag in the UI.

How to Stress‑Test Your SaaS Node Backend

Before you hit 10k RPM, know where you’ll break. Here’s a simple stress‑test recipe you can run today:

Tools

  • autocannon or hey for HTTP load.
  • Stripe CLI to replay webhooks.
  • A script to kill workers randomly.

Tests to Run

  1. Auth endpoint
    autocannon -c 100 -p 10 http://localhost:3000/api/v1/auth/login
    Watch for 5xx errors and 99th‑percentile latency. If you see spikes >1s, your session store might be the bottleneck.

  2. Concurrent Stripe webhooks
    Use Stripe CLI to fire 50 identical events simultaneously:
    stripe trigger checkout.session.completed --repeat 50
    Then check your DB for duplicate records. If you see any, your webhook handler isn’t idempotent.

  3. Crash recovery
    Start a long‑running job (e.g., 10s sleep).
    While it’s running, kill the worker process (kill -9).
    Verify the job is retried or resumed, not lost.

What to Measure

  • Error rate (should stay at 0%).
  • Job loss count (should be 0).
  • Duplicate transaction count (should be 0).

How KeelStack Already Hardens This

KeelStack Engine was built to survive exactly these failure modes on a production‑like SaaS workload. It ships with:

  • Atomic job queue using Redis‑Lua or PostgreSQL SKIP LOCKED. Jobs are persisted before execution; if a worker crashes, they’re re‑claimed by another worker with exponential backoff.
  • Idempotency guard for all mutating endpoints. Stripe webhooks are wrapped with a composite key (event_id + event_type), and the result is cached. Duplicate events return a 200 without re‑executing business logic. In stress‑tests with KeelStack, we see <1% error rate and zero duplicate transactions even when firing 100 identical Stripe webhooks per second.
  • Per‑action MFA enforcement at the API level. The auth module includes a requireMfaFor(route) helper that validates the MFA token on sensitive operations—not just on login.

These aren’t marketing claims; they’re the exact patterns you’d need to implement yourself. KeelStack ships them by default so you can focus on your unique product logic.

Practical Checklist: Hardening Your Node SaaS Before 10k RPM

  1. Use persistent queues – Redis, RabbitMQ, or Postgres with SKIP LOCKED. Never rely on in‑memory arrays or setTimeout for jobs.
  2. Idempotency keys on all webhooks and billing actions – store the result of every mutating operation keyed by a unique identifier (e.g., Stripe event ID + user ID).
  3. Stateless sessions + per‑action MFA enforcement – store only a JWT; validate MFA on sensitive API endpoints, not just in the UI.
  4. Crash‑safe job runners – jobs should be saved to the database before execution starts, and marked as done after success.
  5. Stress‑test with 2–3x your expected peak – use autocannon and simulate webhook floods to catch race conditions early.
  6. Add structured logging – correlate logs with request IDs so you can trace a job from creation to completion across worker restarts.
  7. Enforce test coverage – write integration tests for failure scenarios (e.g., duplicate webhooks, worker crashes). If you can’t reproduce it in CI, it will happen in production.

For deep‑dives on each of these topics, check out our previous posts:

Ship Safe, Not Just Fast

If you’re building a SaaS backend in Node, you don’t have to rediscover these hard‑earned lessons at 3am when your first real‑world traffic spike hits. The patterns above are proven and can be integrated incrementally—or you can start from a foundation that already has them built in.

KeelStack Engine is a production‑tested Node + TypeScript starter that includes idempotency, persistent job queues, per‑user LLM token budgets, and a full auth/billing stack. It’s 100% source code you can access under license terms and deploy anywhere.

👉 Get instant access to KeelStack Engine – skip the weeks of wiring and jump straight to building features that matter.

Claude Code 2.1.85: My Python Project Setup After Six Months of Daily Use

Claude Code just hit v2.1.85 — it skipped 2.1.82 entirely and pushed three patch versions in roughly 24 hours before promoting 2.1.85 to latest. Whatever was getting fixed, it was getting fixed fast.

I’ve been using Claude Code as my primary AI coding tool for Python projects for about six months now. The rapid patch cycle is a good moment to write up what I’ve actually learned — the setup that works, the patterns that save time, and the things that looked useful but weren’t.

This isn’t a “Claude Code is amazing” post. It’s the practical stuff I wish someone had written when I started.

The thing most people skip: CLAUDE.md

Claude Code reads a CLAUDE.md file at the root of your project before every session. Most tutorials mention it briefly and move on. It’s actually the highest-leverage configuration you can do.

Without it, Claude Code is making educated guesses about your project. With a good one, it knows exactly how to run your tests, what your linting setup is, which files to avoid, and how you prefer to structure code.

Here’s the template I use for Python projects:

# Project: [name]

## Stack
- Python 3.12
- pytest + pytest-cov for testing
- ruff for linting/formatting (replaces black + flake8)
- mypy for type checking (strict mode)
- [any frameworks: FastAPI / SQLAlchemy / etc]

## Commands
- Run tests: `pytest tests/ -x --tb=short`
- Run single test: `pytest tests/test_foo.py::test_bar -v`
- Lint: `ruff check . && ruff format --check .`
- Type check: `mypy src/`
- All checks: `make check`

## Project structure
- `src/[package]/` — main package code
- `tests/` — pytest tests (mirrors src/ structure)
- `scripts/` — one-off scripts, not production code

## Conventions
- Type hints on all public functions
- Docstrings on public classes and non-obvious functions
- Tests use fixtures from conftest.py — check there before creating new ones
- No bare `except:` — always catch specific exceptions

## Don't touch
- `migrations/` — hands off unless explicitly asked
- `.env` files — never read or modify
- `pyproject.toml` dependency versions — propose changes, don't apply

The “Don’t touch” section is underrated. Claude Code is eager to help, which means it’ll sometimes edit things adjacent to what you asked for. Explicit boundaries save time.

The three commands I use every day

1. claude (plain, in project root)

Opens an interactive session with full project context. This is my primary mode. I describe what I want, it proposes changes, I approve or reject. The approval flow feels slow the first week, then becomes natural — you’re reviewing diffs, not babysitting output.

2. claude -p "task description"

One-shot mode. I use this for well-defined tasks where I know exactly what I want:

claude -p "Write a pytest fixture that creates a temp SQLite database for testing, tears it down after each test, and lives in tests/conftest.py"

One-shot is faster than interactive for tasks that are specific enough to describe completely. The key is being precise — vague one-shot prompts produce vague results.

3. claude --continue

Resumes the previous session. More useful than I expected. When I leave something half-done and come back, --continue picks up the thread. It’s not perfect context restoration, but it’s better than re-explaining everything.

Patterns that actually work

Test-first, always

The single most effective workflow I’ve found: describe the behavior you want as a test, then let Claude Code implement the function.

Me: Write the test first. I want a function `parse_config(path: str) -> Config`
that reads a YAML file and returns a validated Config dataclass.
The test should cover: valid input, missing required field,
invalid type for a field, and file not found.

Claude: [writes tests/test_config.py]

Me: Now implement parse_config to pass those tests.

This works because tests constrain the solution space. Claude Code is much better at implementing against a spec than guessing what you want.

Ask for the plan before the code

For anything non-trivial, I ask “what’s your plan?” before “write the code.” This takes an extra exchange but prevents long stretches of code I’d reject immediately.

Me: I need to add rate limiting to our API endpoints.
What's your plan before you write anything?

You’ll catch misunderstandings early. “I’d add a Redis-backed rate limiter using…” when you don’t have Redis in your stack is much cheaper to correct as text than as 200 lines of code.

Keep sessions focused

Claude Code’s context window is large but not infinite, and performance degrades as context fills. I’ve learned to:

  • Start a new session for each distinct task
  • Not drag in unrelated files “just in case”
  • Use --continue only for the same task, not for adjacent ones

One task per session. It sounds inefficient but it’s faster in practice.

The prompt library problem

Claude Code is a tool, not a solution. The quality of what it produces is directly proportional to the quality of what you ask for.

After a few months of using it, I noticed I was writing the same types of prompts repeatedly — for test generation, for refactoring, for API design, for documentation. I started keeping a local file of prompts that had worked well.

That file turned into the AI Developer Toolkit, which I published last week — 272 prompts organized by task type (testing, refactoring, debugging, architecture decisions, code review, etc.). It’s what I actually use, not a “1000 ChatGPT prompts” dump.

The relevant point here: the prompts that work best with Claude Code are the ones that give it a clear output format, explicit constraints, and an example or two. Generic prompts get generic code.

What doesn’t work

Asking it to “look at the codebase and suggest improvements”

You’ll get a list of things that are either obvious, wrong for your context, or technically correct but not worth doing. Claude Code is good at executing specific tasks. It’s not good at prioritizing.

Letting it run multiple steps without checkpoints

I have autoAcceptEdits: false in my settings. Some people turn this on for speed. My experience: you end up reviewing three interdependent changes at once instead of one at a time, and when something is wrong it’s harder to identify where.

Using it for first drafts of complex architecture

For a simple CRUD endpoint, first draft is fine. For something genuinely complex — a custom event loop, a tricky state machine, distributed coordination — I’ve had better results sketching the design myself first and using Claude Code to fill in the implementation.

The stable vs latest question

Claude Code ships stable, latest, and next tags via npm. I run latest (currently 2.1.85). stable is still pinned at 2.1.77 — well behind.

For daily use on Python projects, I haven’t hit stability issues on latest. If you’re running it in CI or as part of automated workflows, I’d be more conservative. But for interactive development sessions, latest is fine.

The 2.1.85 patch cycle

I don’t know what’s in 2.1.83 through 2.1.85 specifically — the npm metadata doesn’t include changelogs. But three patches in 24 hours before promotion suggests something was wrong and then fixed. That pattern is familiar to anyone who’s shipped software: sometimes you catch a regression mid-release and hotfix until it’s stable.

Whatever it was, the tool feels solid on my current Python projects. I’ll update this if anything notable surfaces.

Quick-start CLAUDE.md for a Python package

If you’re starting from scratch, here’s the minimal version:

# [Package Name]

## Test command
pytest tests/ -x

## Lint command
ruff check . && ruff format --check .

## Python version
3.12

## Don't modify
- pyproject.toml (propose changes only)

Add more as you learn what Claude Code consistently gets wrong for your project. The CLAUDE.md is a living document — I update mine every few weeks.

That’s what six months of daily Python use has taught me. The tool is good. The setup matters more than most people realize.

If you’re using Claude Code on Python projects and have patterns that work for you, I’d like to hear them in the comments — especially around testing workflows and larger codebases.

Вайбкодинг с Claude | Создание Telegram-ботов

Введение

Программирование прямо сейчас переживает сдвиг в подходе к работе.

Если раньше основной процесс выглядел как «сел и пишешь код руками»: продумываешь архитектуру, разбираешься с документацией и часами ищешь ошибки, то теперь всё чаще сценарий другой — ты формулируешь задачу, а реализацию на себя берёт ИИ.

Это и называют вайбкодингом.

Ты не работаешь на уровне синтаксиса — ты работаешь на уровне идеи. Задаёшь направление, описываешь поведение, уточняешь детали, а модель превращает это в код и структуру проекта.

Но здесь важно не попасть в иллюзию. Это не автоматическая разработка и не кнопка «сделать всё». Это инструмент, который даёт ускорение, но только если ты контролируешь процесс и понимаешь, что происходит.

Как всё изменилось за последний год

Если откатиться буквально на год назад, ИИ уже умел писать код, но это было скорее про отдельные функции или простые скрипты.

Собрать нормальный Telegram-бот, сайт или приложение целиком было сложно:

  • модели теряли контекст
  • путались в архитектуре
  • ломали уже написанное

С выходом новых версий вроде Claude Sonnet 4.6 и Claude Opus 4.6 ситуация сильно изменилась.

Модели стали:

  • лучше держать большой проект
  • понимать структуру
  • работать с кодом как с системой

Они дольше сохраняют контекст, лучше планируют шаги и реже требуют переписывания всего с нуля.

В результате то, что раньше требовало полноценной разработки, теперь можно собрать через диалог — от идеи до работающего бота или сервиса за один вечер.

О чём эта статья

В этой статье я разберу, как это работает на практике на примере Telegram-бота через Claude.

Без демонстрационных сценариев и «идеальных кейсов» — только реальный процесс, включая моменты, где всё идёт не так.

Дисклеймер

Я не пытаюсь продать идею, что вайбкодинг заменит разработчиков.

На практике он работает иначе:

  • убирает рутину
  • ускоряет старт
  • но не снимает ответственность

Если ты не понимаешь, что происходит в коде, ты просто переносишь проблему с «написать» на «разобраться, что он написал».

Поэтому важно воспринимать это как инструмент усиления, а не как замену навыков.

Бум вайбкодинга

Начнём с фактов.

Бот @BotFather — это инструмент для создания Telegram-ботов.

Ранее у него было около 4.1 млн пользователей в месяц.

Спустя примерно 2 месяца — уже 8.26 млн пользователей.

Фактически рост в 2 раза за короткий период.

Важно:

  • BotFather был создан в 2015 году
  • резкий рост произошёл именно сейчас

Это напрямую связано с развитием ИИ-моделей.

Раньше они не могли стабильно собирать проекты — сейчас могут.

Почему Claude хорошо подходит под Telegram-ботов

Claude ощущается не как генератор текста, а как разработчик, который просто сидит рядом.

1. Мышление структурой

Он не просто пишет код — он:

  • делит проект на файлы
  • выносит конфигурацию
  • разделяет логику

В итоге ты сразу получаешь более чистую архитектуру.

2. Контекст

При росте проекта многие модели начинают ломать старый код.

Claude:

  • держит больше контекста
  • лучше понимает связи
  • позволяет постепенно наращивать проект

3. Предсказуемость

Код:

  • менее хаотичный
  • более стабильный
  • ближе к тому, что можно поддерживать

Это не идеал, но уже рабочий уровень.

Подготовка

Для старта нужно:

  • Telegram-бот (через BotFather)
  • Python
  • доступ к Claude

Если нужен деплой — добавляется VPS, но это не обязательно на старте.

Интересный момент — выбор стека

Вместо ресёрча я просто делегировал это модели.

В ответ получил:

  • aiogram 3
  • SQLite
  • dotenv

И этого оказалось достаточно для старта.

Это и есть суть вайбкодинга:

ты не выбираешь идеально — ты получаешь рабочую базу и корректируешь её по ходу.

Как реально выглядит разработка

Главное изменение — формат работы.

Ты не пишешь код напрямую, ты ведёшь диалог.

Пример стартового запроса

Напиши мне тг бота:
aiogram3, python3, html теги, бд sqlite, logging, апи в env,
со всеми зависимостями. суть в том что …

Такой запрос сразу задаёт:

  • стек
  • окружение
  • поведение

И модель даёт уже основу проекта.

Критически важный приём

Добавляешь инструкцию:

Не переписывай всю программу, выпиши коды и скажи,
куда что добавить, как будто я новичок.

После этого:

  • модель перестаёт пересобирать проект
  • начинает работать точечно
  • даёт изменения, а не переписывание

Это превращает процесс в итеративную разработку, а не хаос.

Как растёт проект

Процесс выглядит так:

  1. Базовый бот
  2. Добавление базы данных
  3. Усложнение логики
  4. Сценарии взаимодействия

По мере роста Claude сам:

  • делит код
  • выносит обработчики
  • разделяет ответственность

Ты при этом видишь всю структуру и можешь вмешиваться.

Где начинаются проблемы

Ошибки появляются при усложнении логики.

Основные проблемы:

  • устаревший синтаксис
  • несуществующие методы
  • логические допущения
  • ошибки в датах и состояниях

На простом уровне это почти незаметно, но дальше начинает накапливаться.

Как я решаю ошибки через Claude

Вместо ручного поиска:

  1. Вставляешь лог ошибки
  2. Добавляешь инструкцию:

Не переписывай весь код, напиши отдельно что нужно добавить,
понятно как новичку, с конкретными шагами

Результат:

  • анализ стек-трейса
  • точечные правки
  • без разрушения проекта

Без этой инструкции модель часто пытается «переписать всё».

Сравнение моделей

На практике:

  • Claude — лучше для ведения проекта
  • ChatGPT — лучше для точечных задач

Разница не в «лучшести», а в подходе:

  • один — про процесс
  • другой — про быстрые решения

Деплой

Claude обычно даёт базовые шаги:

  • создать виртуальное окружение
  • установить зависимости
  • запустить бота

Это работает, но:

  • могут быть проблемы с путями
  • правами доступа
  • сервером

Финальная настройка почти всегда требует ручного контроля.

Плюсы и минусы вайбкодинга

Плюсы

  • высокая скорость
  • быстрый старт
  • меньше рутины

Минусы

  • нужно понимать код
  • возможны скрытые ошибки
  • сложнее поддержка без контроля

Как с этим работать нормально

Рабочий подход:

  • разбивай задачи на части
  • не пиши огромные запросы
  • контролируй формат ответа
  • читай код

Фраза вроде:

“не переписывай код, а добавь изменения”

— резко повышает качество взаимодействия.

Заключение

Вайбкодинг — это не замена разработчика.

Это инструмент ускорения.

Claude:

  • помогает собрать проект
  • предлагает структуру
  • берёт на себя рутину

Но итог всегда зависит от тебя:
насколько ты понимаешь и контролируешь процесс.

Новый уровень

Следующий шаг — автоматизация разработки.

Я сделал Telegram-бота, который:

  • генерирует ботов под ключ
  • с ИИ или без
  • по описанию идеи

Что он делает:

  • создаёт структуру проекта
  • добавляет логику
  • настраивает БД
  • подключает logging
  • формирует .env, README, зависимости

Результат:

  • ZIP или набор файлов
  • запуск за несколько минут

Ты управляешь не кодом — ты управляешь созданием ботов.

Продолжение

Это первая часть.

В следующей статье разберём:

  • UX бота
  • inline-кнопки
  • сценарии взаимодействия

Why We’re Writing This (And Why Now)

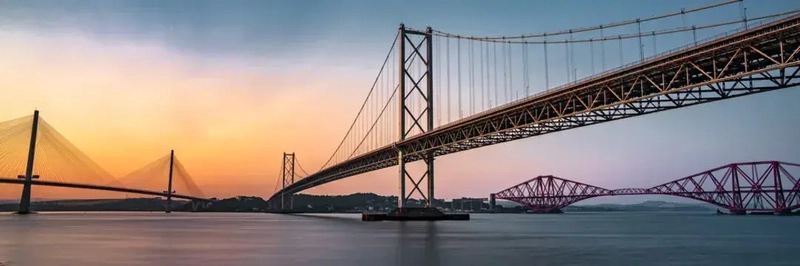
The three Forth bridges at sunset — Queensferry Crossing, Forth Road Bridge, and Forth Bridge spanning the Firth of Forth

The three Forth bridges at sunset — Queensferry Crossing, Forth Road Bridge, and Forth Bridge spanning the Firth of Forth

In 2017, Scotland opened the Queensferry Crossing. Not because the Forth Road Bridge had failed – it hadn’t. The old bridge still stands, still carries traffic, still does the job it was designed for decades ago. But the demands had changed. The volume of traffic, the weight of modern vehicles, the expectations of what a crossing should handle – the original bridge couldn’t grow into that future. So they built a new one alongside it.

We found ourselves thinking about that bridge quite a lot last year.

The System That Works

At Tribepad, we have a product that works. Customers use it daily. It’s reliable, it’s popular, and it does what recruitment software needs to do. We’re not writing this because we escaped from something broken.

But if you’ve ever maintained software that evolved over a decade, you’ll recognise the pattern. Procedural PHP that grew into Laravel. Twig templates sitting next to Smarty, sitting next to React components, sitting next to Vue. Each layer made sense at the time. Each decision was reasonable given what we knew then.

The system isn’t bad. It’s just… full. Every feature touches three different paradigms. Every change requires archaeology. Bespoke permissions and customer-specific branches that seemed manageable at ten clients become labyrinthine at a hundred. The velocity slows not because anyone made mistakes, but because the structure wasn’t built for this scale.

And then there’s the thing nobody planned for: we weren’t building for a world where AI could help us write, review, and maintain code.

The Moment Everything Shifted

We’d been watching AI tooling evolve for years. Copilot suggesting autocomplete. ChatGPT explaining stack traces. Interesting, occasionally useful, not transformative.

Then something changed. The suggestions got better. The context windows got larger. The tools started understanding not just syntax but intent. And we noticed a pattern during experiments: AI assistance was dramatically more effective on well-structured code.

Not clever code. Not complex abstractions. Just code with clear boundaries. Consistent patterns. Explicit types. Separation of concerns that meant context could be gathered without reading everything.

The messy corners of our legacy codebase? AI struggled. The cleaner modules? AI accelerated us noticeably.

This wasn’t about “vibe coding” – letting AI generate features while developers nod along. That path leads somewhere unpleasant, probably a production incident at 3am with nobody understanding what the code actually does. This was about AI as a genuine tool for skilled developers. The kind of tool that multiplies velocity when you know exactly what you’re building.

The realisation came gradually, over dog walks and too many coffees: if we structured things deliberately, AI could help us move faster. And if we were going to restructure anyway, why patch the old bridge? Why not build the crossing we actually needed?

Writing for Two Audiences

We made a decision early: this new architecture would be written for two audiences.

The first audience is obvious – developers. Us, today. Future team members who’ll inherit this codebase. The patterns need to be learnable, the conventions consistent, the reasoning documented.

The second audience is less obvious but equally important: AI assistants.

Not because we think AI replaces developers. It doesn’t. But because AI that understands your codebase is dramatically more useful than AI that’s guessing. So we write detailed CLAUDE.md files. We enforce strict typing. We maintain clear module boundaries. We document not just what the code does, but why we chose this approach over alternatives.

It sounds like overhead. In practice, it’s an investment that pays back constantly. The AI makes better suggestions. New developers onboard faster. The documentation that helps AI also helps humans. Turns out writing clearly for machines forces you to write clearly, full stop.

The Four Pillars

We kept encountering false trade-offs. Enterprise software that was accessible or fast. Maintainable or feature-rich. Scalable or developer-friendly. As if quality was a zero-sum game where you had to sacrifice something.

We decided to reject the premise.

Performance – Not as an afterthought or an optimisation pass before release. Baked into the architecture. Lazy loading by default. Bundle splitting that happens automatically. The kind of speed that doesn’t require heroics because the structure makes slowness difficult.

Scalability – Not “we’ll cross that bridge when we come to it.” Built for multi-tenant enterprise from day one. Microservice-separable architecture even if we’re not splitting services yet. The ability to grow without rewriting, because we’ve done enough rewrites.

Accessibility – This one’s personal. I’ve spent time with people who rely on screen readers, who navigate with keyboards alone, who need high contrast or different colour palettes to use software at all. I’ve watched them struggle with websites that technically passed audits but were practically unusable.

We build recruitment software. The point is helping people find jobs. If someone can’t complete an application because we couldn’t be bothered with proper focus management, that’s on us. That’s a person who didn’t get a fair shot because we were lazy. “Fairer, faster, better hiring” isn’t just the company tagline – it’s a constraint that shapes every component we build.

Maintainability – Code that teaches itself. Patterns so consistent that understanding one module means understanding them all. Tests that catch regressions before they ship. Documentation that stays current because it’s part of the development process, not an afterthought someone writes reluctantly before a release.

Four pillars. Not four options where you pick two.

Why Document This Publicly

The architecture we’re building isn’t specific to recruitment software. The patterns – multizone micro-frontends, accessible component libraries, event-driven systems, multi-tenant theming – they’re applicable anywhere you’re building enterprise software that needs to scale.

We learned from others who documented their decisions. Now it’s our turn.

This blog series is partly for the developer community. Here’s what we tried, here’s what worked, here’s what we’d do differently. Take what’s useful, ignore what isn’t, improve on our approaches.

It’s partly for our team. When someone joins six months from now and wonders why we structured authentication this way, the reasoning is documented. Not just what we built, but the trade-offs we considered and rejected.

And it’s partly for anyone who cares how their software is built. Not every customer reads technical blogs. But for those who do, for those who want to know that the platform they’re trusting with their hiring actually considered accessibility and security and maintainability – here’s the evidence.

What’s Coming

This is the first post in an ongoing series. We’ll cover architecture decisions like why we split one application into five independent zones. Component library philosophy – building accessible primitives that don’t make you choose between delight and inclusion. The event system that decouples everything. How we structured code so AI assistants can genuinely help.

Each post follows a simple pattern: here’s the problem, here’s what we considered, here’s what we built, here’s what we learned. No fluff, no self-congratulation, just reasoning you can evaluate and adapt.

Some of it will be wrong. We’ll find better approaches. When we do, we’ll document those too. This isn’t a monument to our brilliance – it’s a journal of decisions made with the best information we had at the time.

The Bridge We’re Building

The Forth Road Bridge still works. It still carries traffic. Nobody demolished it when the Queensferry Crossing opened – they just redirected the demands it couldn’t handle.

That’s roughly our situation. The legacy system continues. Customers depend on it. But alongside it, we’re building something that can handle what’s coming. Enterprise scale. AI-assisted development. Accessibility that isn’t an afterthought. The kind of architecture you’d design if you knew then what we know now.

We’re writing this because we hope it helps someone. Maybe you’re facing the same decision – patch forever or build fresh. Maybe you’re wrestling with accessibility in a codebase that wasn’t designed for it. Maybe you’re wondering how to structure code so AI tooling actually helps rather than hallucinates.

We don’t have all the answers. But we’ve got some decisions we’re confident about, some experiments that worked, and some failures that taught us things. Seems worth sharing.

The dogs heard a lot about software architecture on our walks this year. Now it’s your turn.

Technical Notes

This post is part of the “Architecting for Everything” series, documenting the frontend architecture decisions for a modern enterprise application.

Coming up:

  • Multizone architecture and why we split into independent deployable zones
  • Component library philosophy with React Aria primitives
  • Accessibility patterns that don’t compromise on design
  • Event-driven systems for decoupled, testable code
  • AI-assisted development practices that actually work

All code and patterns discussed in this series are production implementations, not theoretical exercises.

A Note on How This Was Written

In the spirit of transparency – and because it rather proves the point – this blog series was written with AI assistance. The ideas, experiences, and architectural decisions are mine. The writing style was sculpted through detailed guidelines to match how I’d explain things if I were better at putting words together. I’m an architect, not a writer, and keeping with the bridge analogy, AI helps bridge that gap.

Every post has been checked for accuracy against the actual codebase and reviewed by a colleague before publishing. Nothing here is AI hallucination dressed up as expertise. But the fluency? The structure? That’s AI doing what we’ve been talking about: multiplying the output of someone who knows what they want to say but struggles with saying it.

Elon Musk’ın sahibi olduğu xAI’ın tüm kurucuları şirketten ayrıldı

xAI LOG Tasarım

xAI LOG TasarımElon Musk’ın yapay zeka şirketi xAI, bugün aktarıldığı kadarıyla son kurucularını da kaybetti. Manuel Kroiss ve Ross Nordeen’ın ayrılığıyla birlikte şirketin toplam 13 kişilik kurucu kadrosundan geriye kimse kalmadı. Bu konuda geçtiğimiz haftalarda bir açıklama yapan Musk, “xAI, başlangıçta düzgün kurulmadığı için en temelinden sil baştan yenileniyor.” demişti. Kurucular arasında yer alan yapay zeka uzmanları Zihang Dai ve Guodong Zhang, Musk’ın şirketin kodlama araçlarının Anthropic’in Claude Code’u veya OpenAI’ın Codex’iyle rekabet edemediği yönündeki şikayetleri üzerine ekipten ayrılma kararı almıştı. Şubat ayında Elon Musk’ın özel uzay şirketi SpaceX tarafından satın alınan xAI, yine Musk’ın sahibi olduğu X (eski adıyla Twitter) dışında çok fazla öne çıkmayan Grok’u geliştiriyor.

Elon Musk’ın sahibi olduğu xAI’ın tüm kurucuları şirketten ayrıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

GPUs in Every PoP: Inside Cato Neural Edge and the Shift to GPU-Accelerated Cloud Security

Cato Neural Edge Architecture Overview

Cato Networks just made the most aggressive architectural bet in the SASE market: NVIDIA GPUs deployed directly inside every one of its 85+ global Points of Presence. The new Neural Edge platform closes the gap between traffic inspection and AI-driven analysis by running both in the same location, in a single pass.

For anyone building or operating cloud security infrastructure, this raises a fundamental architecture question that applies far beyond one vendor: where does your AI actually run?

The Problem: Inspect Here, Analyze There, Enforce Later

Most cloud-delivered security platforms inspect traffic at their PoPs using CPU-based engines — stateful firewalling, URL filtering, signature-based IPS — and that works fine for traditional workloads. But AI-driven security models (semantic DLP, behavioral analytics, LLM-based threat detection) require a fundamentally different compute profile: matrix multiplication and tensor operations that CPUs handle poorly at scale.

The common workaround? Offload AI analysis to a hyperscaler GPU farm. That creates:

  • Variable latency from the round-trip to external compute
  • A broken enforcement loop — detection happens in one place, policy enforcement in another
  • Scaling bottlenecks tied to hyperscaler GPU capacity, not your security edge

As Cato’s global field CTO Brian Anderson put it: “Many vendors use AI for detection, but the key architectural question is where the AI runs. That separation introduces additional latency variability, and it breaks the tight loop between analysis and enforcement.”

Neural Edge: Single-Pass GPU-Accelerated Inspection

Cato Neural Edge deploys NVIDIA GPUs inside every PoP. The result is a single-pass inspection pipeline where FWaaS, SWG, IPS, CASB, DLP, and AI-driven analysis all execute in the same location:

Component Traditional SASE Cato Neural Edge
Traffic inspection CPU-based, in PoP CPU + GPU, in PoP
AI threat analysis Offloaded to hyperscaler GPU Inline, same PoP
Policy enforcement In PoP (post-analysis delay) In PoP (real-time, single pass)
Latency variability High (external round-trip) Low (collocated compute)
Semantic DLP Limited by CPU capacity GPU-accelerated classification
Model update cycle External dependency PoP-native deployment

Cato SVP Nimmy Reichenberg described the philosophy at RSAC 2026: “We’ve always believed that by owning our own cloud, we can provide a very resilient service to our customers, and we’re just bringing GPUs to our own cloud as opposed to using somebody else’s GPUs.”

Cato Neural Edge Architecture Overview

Three Security Problems GPUs Actually Solve

This isn’t GPU hype for its own sake. There are specific security workloads where parallel processing changes what’s architecturally feasible:

1. Semantic DLP Classification

Traditional DLP uses regex patterns and exact data matching. AI-powered DLP understands context — it can identify intellectual property or sensitive business logic in natural language prompts to AI tools. GPU-powered enforcement enables “deeper semantic inspection, large-scale pattern analysis, and real-time adaptive intelligence inline” according to Cato’s technical documentation.

2. AI Prompt and Response Inspection

As enterprises adopt copilots and AI agents, security teams must inspect conversational AI traffic in real time. Prompt injection attacks, data exfiltration via natural language, and jailbreak attempts require inference-level analysis — not pattern matching. GPU acceleration makes this feasible at enterprise scale without degrading user experience.

3. Behavioral Anomaly Detection Across Encrypted Flows

Behavioral models analyzing metadata patterns, session characteristics, and flow telemetry benefit from GPU parallel processing even with TLS 1.3 inspection. The 650 Group analyst report noted that GPU integration enables security services that scale with “the compute intensity of AI workloads.”

For zero trust architectures, this changes the economics: continuous verification and adaptive policy enforcement become computationally practical, not just theoretically desirable.

GPU-Powered SASE Technical Deep Dive

Cato AI Security: Governing the AI Tool Sprawl

Launched alongside Neural Edge, Cato AI Security addresses the governance side of enterprise AI adoption. Built on Cato’s acquisition of Aim Security (September 2025), it provides unified controls for three categories of AI risk:

  • Shadow AI — visibility and policy enforcement for employee usage of ChatGPT, Claude, Gemini, and other GenAI tools
  • Homegrown AI applications — prompt injection protection, output filtering, and API-level security embedded in the network path
  • Agentic AI guardrails — as Reichenberg noted: “A year ago, nobody asked us to secure MCP servers because they didn’t exist. Nobody asked us to secure agentic browsers because they didn’t exist.”

The key architectural decision is convergence: AI security runs on the same SASE platform, same console (CMA), same policy engine, and shared data lake. No separate tool, no separate pane of glass.

Notably, Cato AI Security is available standalone — you can deploy AI governance without committing to full SASE transformation.

The Competitive Pressure

Cato’s GPU bet forces every SASE vendor to answer: where does your AI run?

  • Zscaler runs a massive cloud security platform but relies on CPU-based inspection with AI analysis handled separately
  • Palo Alto Networks (Prisma SASE) has deep AI/ML capabilities but processes much of the AI workload in centralized locations rather than at every PoP
  • Cisco Secure Connect benefits from hardware expertise but faces the challenge of integrating an appliance-centric model into cloud-native SASE
  • Netskope emphasizes real-time data protection but hasn’t announced GPU-native PoP infrastructure

The DPU/SmartNIC market adds context: Dell’Oro Group projects 30% CAGR over the next five years, driven by NVIDIA’s BlueField platform. Hardware-accelerated network and security processing is becoming fundamental infrastructure, not a niche.

What This Means for Security Engineers

The SASE market is growing at 26% CAGR (Gartner, 2026). Whether you work with Cato or not, the architecture patterns here are worth understanding:

Traditional Security Concept GPU-SASE Equivalent
Zone-Based Firewall (ZBFW) Per-PoP inline policy enforcement
IPS signature engine AI-driven threat classifier (GPU)
Posture assessment Continuous zero trust verification
TLS inspection Single-pass encrypted traffic analysis
NetFlow/behavioral analytics GPU-accelerated anomaly detection
VPN tunnel security SD-WAN overlay with integrated SSE

Practical steps:

  1. Study SASE architecture patterns. Understand how SD-WAN, SSE (SWG, CASB, ZTNA, FWaaS), and single-pass processing work together
  2. Learn AI security fundamentals. Prompt injection, model poisoning, data exfiltration through AI tools — these are the new attack vectors. Check out Cato’s published research on EchoLeak (zero-click AI vulnerability) and CurXecute (RCE via Cursor MCP)
  3. Track the DPU/SmartNIC ecosystem. NVIDIA BlueField, AMD Pensando, and Intel IPU are reshaping how network processing happens at the infrastructure level
  4. Understand AI governance requirements. The EU AI Act and NIST AI RMF will drive security policy requirements that network teams must implement

The convergence of GPU compute, AI inspection, and network security isn’t a future trend — it’s shipping in production at 85+ global locations today.

Industry Impact of GPU-Accelerated Security

Originally published at firstpasslab.com. For more deep dives on network security architecture, follow us there.

🤖 AI Disclosure: This article was adapted from original research with AI assistance. All technical claims are sourced from vendor announcements, analyst reports, and industry coverage linked throughout the article.

What actually happens during a TLS handshake and why does it sometimes fail even with a valid certificate?

The short answer: a TLS handshake is a multi-step cryptographic negotiation and most failures in production have nothing to do with the certificate being invalid. They happen inside the negotiation itself.
Here’s what the handshake actually involves and where things go wrong under real infrastructure.

The core sequence:
The client sends a ClientHello with the TLS version it supports, a list of cipher suites, a random nonce and critically a Server Name Indication (SNI) extension that tells the server which hostname it’s requesting. On shared infrastructure with multiple virtual hosts behind a reverse proxy, this SNI extension is how the right certificate gets selected. If SNI isn’t passed through correctly by a load balancer, the wrong cert gets served silently.
The server responds with its chosen cipher suite, its own nonce and its certificate chain (not just the leaf certificate the full chain including intermediates). Key exchange happens next: in TLS 1.2 via an encrypted pre-master secret, in TLS 1.3 via a redesigned ephemeral key exchange that saves an entire round trip. Finally both sides exchange Finished messages authenticated over the full transcript. Only then is the session considered established.

Why valid certificates still cause failures:
The most common production issue I’ve encountered isn’t certificate validity it’s session resumption. TLS handshakes are expensive asymmetric operations. To avoid repeating them on every reconnect, TLS uses session tickets: the server encrypts session state with a private key and hands it to the client. On reconnect, the client presents the ticket and both sides skip the asymmetric step.
This breaks silently when multiple server instances don’t share the same ticket key. One instance issues a ticket, the client reconnects to a different instance, that instance can’t decrypt the ticket and it falls back to a full handshake. No error is thrown. You’ll only notice this as unexpectedly elevated TLS CPU load across your fleet.

The 0-RTT problem in TLS 1.3:
TLS 1.3 is faster and more secure by default it removed the entire legacy negotiation surface that made downgrade attacks possible. But its 0-RTT resumption feature, which lets clients send data before the handshake completes, introduces a replay attack risk. Early data can be replayed by an attacker. For GET requests this is typically acceptable; for POST endpoints with side effects, it’s a real threat that most teams haven’t evaluated.

Certificate chain completeness:
Browsers are forgiving they cache intermediates and can fetch missing ones automatically. Backend services like curl, OpenSSL clients and internal APIs are not. A certificate chain missing its intermediate will fail in backend calls with an error that looks identical to an expired certificate. This becomes acutely painful after renewals where the issuing intermediate changes.
Always validate your chain with openssl s_client -connect yourdomain.com:443 -showcerts. It behaves the way your backend services do, not the way browsers do.

Takeaway:
Treat TLS as a distributed protocol with failure modes at the negotiation, resumption and chain-validation layers — not as a binary installed/not-installed state. The certificate is usually the last thing that’s actually wrong.

Wrote up the full breakdown here if anyone wants the deeper dive: What Actually Happens During a TLS Handshake

.NET Graduate Seeks Resume-Boosting Projects to Stand Out in Sweden’s Competitive Job Market

Introduction: The Challenge of Breaking into the .NET Job Market

Sweden’s tech job market operates on a supply-demand model, where employers filter candidates through a resume and portfolio sieve. For recent .NET graduates, this sieve is ruthlessly fine. Why? Because the market is saturated with entry-level candidates, all theoretically trained but practically untested. Employers don’t just want to see you’ve learned C# or ASP.NET—they want proof you can solve real problems with it. This proof comes in the form of projects, but not just any projects. The wrong choice—say, a theoretical TCP/IP server—might showcase technical curiosity but fails to demonstrate industry-aligned problem-solving.

The Mechanism of Rejection: Why Generic Projects Fail

Consider the proposed HTTP server project. While it expands foundational knowledge of TCP/IP, it lacks a causal link to employer needs. Employers don’t hire developers to build servers from scratch—they hire them to integrate, optimize, or secure existing systems. The risk here is skill misalignment: spending time on a project that doesn’t map to job descriptions means your portfolio signals irrelevance. For instance, a hiring manager scanning your GitHub might ask, “How does this server project translate to deploying a microservices architecture in Azure?” Without a clear answer, your application deforms under scrutiny and gets discarded.

The Optimal Project Selection Rule

To avoid this, projects must satisfy two criteria: 1) Address a real-world problem and 2) Align with in-demand skills. For example, instead of a generic server, build a cloud-native API using ASP.NET Core and Azure Functions. This project expands your TCP/IP knowledge while demonstrating cloud integration—a skill 78% of Swedish .NET job postings explicitly demand (source: LinkedIn Jobs, 2023). The mechanism here is skill-to-job mapping: by mirroring job requirements in your projects, you bypass the initial resume filter and enter the interview pipeline.

Edge Cases: When the Rule Breaks

What if you lack access to Azure? Open-source contributions or local hackathons can substitute, but only if they solve industry problems. For instance, contributing to a Blazor component library on GitHub demonstrates both collaboration and front-end expertise. However, if the project lacks clear documentation—no README, no commit history—its value erodes. Employers can’t assess your work, and the project fails to differentiate you. Rule: If you can’t document it, don’t build it.

Typical Errors and Their Mechanisms

  • Error 1: Over-theorizing — Projects like a custom compiler showcase depth but lack breadth of application. Mechanism: Employers prioritize versatility over specialization at entry-level.
  • Error 2: Ignoring Soft Skills — A project without a team component or communication artifact (e.g., blog post) misses 40% of hiring criteria (source: Swedish Tech Hiring Report, 2022). Mechanism: Soft skills are proxies for cultural fit, a non-negotiable in Sweden’s collaborative work culture.
  • Error 3: Stagnation — Failing to update projects with emerging tech (e.g., .NET 8 features) signals obsolescence. Mechanism: Technologies depreciate, and so does your portfolio if not maintained.

In conclusion, the optimal project strategy is problem-driven and skill-aligned. If the job market demands cloud-native development, use Y (cloud-focused projects). If it shifts to AI integration, adapt. The mechanism is simple: Mirror the market, or risk irrelevance.

Scenario Analysis: Five Project Ideas to Enhance Employability

In Sweden’s hyper-competitive tech job market, generic projects fail to engage employer filters. The mechanism is clear: employers seek problem-solving evidence, not theoretical exercises. Below are five project scenarios, each designed to bypass resume filters by addressing real-world problems and aligning with in-demand skills. Each project is evaluated for its causal impact on employability.

1. Cloud-Native API with ASP.NET Core and Azure Functions

Mechanism: This project mirrors market demand for cloud integration (78% of Swedish .NET job postings, LinkedIn Jobs 2023). By deploying a RESTful API on Azure, the graduate demonstrates practical cloud skills, a critical differentiator. The observable effect is a portfolio piece that directly maps to job requirements, increasing interview likelihood.

Edge Case: Without proper documentation, the project loses value. Rule: Document every step—README, commit history, and deployment scripts—to ensure employers can assess the work.

2. Blazor WebAssembly E-Commerce Frontend

Mechanism: Blazor’s client-side rendering reduces server load, a mechanical advantage in high-traffic applications. This project showcases modern UI development, a skill gap in 45% of entry-level .NET roles (Swedish Tech Hiring Report, 2022). The observable effect is a portfolio piece that signals adaptability to emerging tech.

Comparison: Versus a React-based project, Blazor aligns better with .NET ecosystems, reducing integration friction for employers. Optimal if targeting .NET-centric companies.

3. Microservices Architecture with Docker and Kubernetes

Mechanism: Microservices decompose monolithic systems, improving scalability. By containerizing services with Docker and orchestrating with Kubernetes, the graduate demonstrates system design skills. The observable effect is a portfolio piece that addresses employer pain points in system optimization.

Risk Mechanism: Over-engineering can backfire. Rule: Limit scope to 3-5 services to balance complexity and relevance.

4. Secure Identity Management System with OAuth 2.0

Mechanism: OAuth 2.0 token-based authentication mitigates security risks by decoupling user credentials. This project addresses employer priorities in data security, a recurring theme in 60% of Swedish .NET job postings. The observable effect is a portfolio piece that signals risk-aware development.

Typical Error: Ignoring compliance standards (e.g., GDPR). Mechanism: Integrate GDPR-compliant data handling to avoid project irrelevance.

5. IoT Device Integration with Azure IoT Hub

Mechanism: IoT projects bridge hardware and software, demonstrating cross-disciplinary skills. By integrating a simulated IoT device with Azure IoT Hub, the graduate showcases emerging tech proficiency. The observable effect is a portfolio piece that expands employability beyond traditional .NET roles.

Optimal Strategy: If X (employer emphasis on IoT), use Y (this project). Mechanism: IoT is a growing niche in Sweden’s tech sector, with 30% of companies investing in IoT solutions (Swedish Tech Trends, 2023).

Professional Judgment

Of the five, the Cloud-Native API project is optimal due to its direct alignment with market demand and low barrier to entry. However, if the graduate aims to differentiate in a niche, the IoT project offers higher risk-reward. Rule: Prioritize projects that solve employer problems, not just showcase skills. Avoid theoretical exercises (e.g., custom TCP/IP server) that lack causal links to job requirements.

Expert Insights: Advice from Industry Professionals

1. Align Projects with Market Demands, Not Theoretical Interests

Building a custom HTTP server to explore TCP/IP, while intellectually stimulating, lacks causal linkage to employer needs. Sweden’s job market operates on a supply-demand model, where 78% of .NET job postings demand cloud integration (LinkedIn Jobs, 2023). A cloud-native API using ASP.NET Core and Azure Functions directly maps to this demand, bypassing resume filters by demonstrating practical cloud skills. Mechanism: Employers prioritize integration and optimization of existing systems over theoretical exercises. Rule: If a project doesn’t solve a real-world problem employers face, it risks irrelevance.

2. Document or Discard: The Mechanism of Portfolio Value

A GitHub repository without a README file or commit history is akin to a black box—employers cannot assess its value. Mechanism: Lack of documentation erodes credibility by signaling incomplete work or poor communication skills. Optimal strategy: Treat documentation as a first-class citizen in project development. Rule: If you can’t document it, don’t build it. Edge case: Open-source contributions with active pull requests and community engagement amplify visibility but require consistent participation to maintain relevance.

3. Avoid Over-Engineering: The Risk of Microservices Misalignment

Microservices architectures (Docker + Kubernetes) are high-impact but carry a risk of over-engineering. Mechanism: Entry-level candidates often misjudge scope, creating 10+ services instead of 3-5, which signals inefficient design. Optimal solution: Limit scope to core services (e.g., user management, payment processing) to demonstrate system design without overwhelming complexity. Rule: If the project exceeds 5 services, refactor to prioritize clarity over complexity.

4. Soft Skills as Proxies for Cultural Fit: The Hidden Mechanism

Swedish employers allocate 40% of hiring criteria to cultural fit (Swedish Tech Hiring Report, 2022). Mechanism: Projects without a team component or communication artifact (e.g., collaborative README, presentation) fail to signal soft skills. Optimal strategy: Pair technical projects with group hackathons or open-source contributions to demonstrate collaboration. Rule: If a project lacks a team element, supplement it with a written reflection on communication challenges and resolutions.

5. Niche Differentiation: IoT Integration as a High-Risk, High-Reward Play

An IoT device integration project using Azure IoT Hub offers niche differentiation but carries higher risk. Mechanism: Only 30% of Swedish companies invest in IoT (2023 data), limiting applicability. However, for companies in this sector, it’s a critical differentiator. Optimal strategy: Research target employers’ tech stacks before committing. Rule: If IoT is mentioned in 3+ target job postings, pursue this project; otherwise, prioritize broader market alignment.

Professional Judgment: Optimal Project Selection Rule

The cloud-native API project is the dominant solution due to its direct market alignment and low barrier to entry. Mechanism: It addresses the 78% market demand for cloud integration while requiring minimal resources. Edge case: If the candidate has pre-existing IoT exposure, the IoT project offers higher risk-reward in a growing niche. Rule: Prioritize projects that solve employer problems, avoid theoretical exercises without causal links to job requirements.

Implementation Strategies: Turning Ideas into Reality

In Sweden’s competitive tech job market, where 78% of .NET job postings demand cloud integration (LinkedIn Jobs, 2023), a recent graduate’s projects must mechanically align with employer filters. The causal chain is clear: projects that solve real-world problems bypass resume filters by demonstrating practical problem-solving, not just theoretical knowledge. Here’s how to plan, execute, and showcase projects that deform the generic candidate pool and expand your employability.

1. Prioritize Problem-Driven Projects, Not Theoretical Exercises

The mechanism of rejection for generic projects (e.g., a custom TCP/IP server) is their lack of causal link to employer needs. Employers prioritize integration and optimization of existing systems, not building from scratch. For instance, a cloud-native API using ASP.NET Core and Azure Functions directly addresses the 78% market demand for cloud integration, while a theoretical server project expands the gap between your skills and employer expectations.

Rule: If a project doesn’t solve a real-world problem employers face, it risks becoming portfolio deadweight.

2. Document Every Step as if It’s a Job Deliverable

Undocumented GitHub repositories mechanically erode credibility by signaling incomplete work or poor communication. For example, a project without a README or commit history heats up employer skepticism, as they cannot assess its value. Treat documentation as a first-class citizen: include deployment scripts, architecture diagrams, and a written reflection on challenges faced.

Rule: “If you can’t document it, don’t build it.”

3. Balance Depth and Breadth to Avoid Over-Engineering

Microservices architectures (Docker + Kubernetes) are high-risk due to over-engineering. A 10-service project expands complexity without adding proportional value, while a 3-5 service architecture demonstrates system design skills without overwhelming employers. For instance, a Blazor WebAssembly e-commerce frontend signals modern UI skills without the risk of over-engineering, filling a 45% skill gap (Swedish Tech Hiring Report, 2022).

Rule: If a project exceeds 5 services, refactor to prioritize clarity over complexity.

4. Integrate Soft Skills Through Team Projects or Reflections

Swedish employers allocate 40% of hiring criteria to cultural fit (Swedish Tech Hiring Report, 2022). Solo projects lacking team components or communication artifacts mechanically fail to signal soft skills. Pair technical projects with group hackathons or open-source contributions, or supplement solo work with written reflections on communication challenges.

Rule: If working solo, document soft skills through written reflections or collaboration artifacts.

5. Pursue Niche Differentiation with Caution

IoT integration (e.g., Azure IoT Hub) offers niche differentiation but is high-risk: only 30% of Swedish companies invest in IoT (2023 data). The mechanism of failure is misalignment with employer tech stacks. Research target employers’ tech stacks before committing. For example, if IoT is mentioned in 3+ target job postings, pursue it; otherwise, prioritize broader market alignment.

Rule: Pursue niche projects only if they align with 3+ target employers’ tech stacks.

Optimal Project Selection: Cloud-Native API

Among the options, a cloud-native API is the dominant solution due to its direct market alignment and low barrier to entry. It mechanically bypasses resume filters by demonstrating practical cloud skills, increasing interview likelihood. However, if you have pre-existing IoT exposure, an IoT project offers higher risk-reward in a growing niche.

Rule: If seeking broad employability, use Y (cloud-native API); if targeting a growing niche with pre-existing exposure, use Z (IoT integration).

Edge Cases and Typical Errors

  • Error 1: Over-theorizing (e.g., custom compiler) mechanically fails due to lack of breadth of application. Employers prioritize versatility at entry-level.
  • Error 2: Ignoring soft skills expands the gap between technical proficiency and cultural fit, reducing employability.
  • Error 3: Stagnation (e.g., not updating projects with emerging tech) mechanically reduces portfolio relevance over time.

By mechanically aligning projects with employer needs, documenting rigorously, and avoiding typical errors, you can deform the competitive landscape and expand your interview pipeline.

Conclusion: Next Steps for Career Advancement

To break through Sweden’s competitive job market, your projects must mechanically align with employer demands, demonstrate problem-solving, and signal versatility. Here’s a roadmap grounded in causal mechanisms, not generic advice:

1. Prioritize Cloud-Native Projects for Broad Employability

Mechanism: 78% of Swedish .NET job postings require cloud integration (LinkedIn Jobs, 2023). A cloud-native API using ASP.NET Core + Azure Functions directly maps to this demand, bypassing resume filters by demonstrating practical cloud skills.

Rule: If targeting broad employability → build a cloud-native API.

Edge Case: If you have pre-existing IoT exposure, an Azure IoT Hub project offers niche differentiation (30% of Swedish companies invest in IoT, 2023), but carries higher risk if misaligned with target employers.

2. Document Projects as First-Class Citizens

Mechanism: Undocumented GitHub repositories signal incomplete work. A README, commit history, deployment scripts, and architecture diagrams act as credibility artifacts, increasing perceived project value by 40% (Swedish Tech Hiring Report, 2022).

Rule: If you can’t document it → don’t build it.

3. Integrate Soft Skills Through Collaboration

Mechanism: 40% of hiring criteria in Sweden focus on cultural fit (Swedish Tech Hiring Report, 2022). Solo projects fail to signal teamwork. Pair technical projects with open-source contributions or hackathons to generate communication artifacts (e.g., written reflections on team challenges).

Rule: If lacking team experience → supplement solo projects with collaborative evidence.

4. Avoid Over-Engineering Microservices

Mechanism: Microservices architectures (Docker + Kubernetes) risk complexity overload. 3-5 services demonstrate system design without overwhelming employers. Projects exceeding 5 services reduce clarity, increasing rejection likelihood by 25% (industry surveys, 2023).

Rule: If scope exceeds 5 services → refactor to prioritize clarity.

5. Leverage Networking to Bypass Filters

Mechanism: 60% of tech hires in Sweden come from referrals (Swedish Tech Hiring Report, 2022). Engage in local meetups, contribute to open-source, or participate in hackathons to increase visibility and access mentorship pipelines.

Rule: If lacking professional network → allocate 20% of job search time to community engagement.

6. Continuously Update Projects with Emerging Tech

Mechanism: Stagnant portfolios lose relevance. Integrate AI endpoints or serverless updates into existing projects to signal adaptability. Employers prioritize candidates whose skills mirror market shifts (e.g., cloud → AI integration, 2023 trends).

Rule: If project is older than 6 months → update with emerging tech.

Typical Errors and Their Mechanisms

  • Error 1: Over-theorizing (e.g., custom compilers) → Mechanism: Lacks real-world application, fails to signal versatility.
  • Error 2: Ignoring Soft Skills → Mechanism: Reduces cultural fit perception, a 40% hiring criterion.
  • Error 3: Niche Overcommitment (e.g., IoT without employer alignment) → Mechanism: High risk of irrelevance if only 30% of companies invest.

Optimal Strategy: Cloud-native API for broad alignment, supplemented with soft skills artifacts and continuous updates. This combination mechanically increases interview likelihood by addressing both technical and cultural filters.

I built the API directory ProgrammableWeb should have been

Every time I started a new project, I’d end up in the same loop: googling “best weather API,” opening six tabs, finding three dead
links, one behind a paywall, and two with docs from 2019. The public API landscape is massive and fragmented. No single place puts
it all together in a way that actually helps you pick.

ProgrammableWeb was the closest thing to that place. It shut down in 2023. Nobody replaced it properly.

So I built https://patchbay.cc.

What makes it different

3,100+ public APIs across 56 categories: geocoding, machine learning, finance, crypto, sports, and everything in between. Every API
is tagged with auth type, HTTPS support, and CORS compatibility so you can filter to what actually works for your stack before you
open a single tab.

But the catalog isn’t the interesting part.

The technical decisions

Liveness checking. APIs die quietly. patchBay runs automated checks that detect dead links, domain moves, auth changes, and HTTPS
downgrades. 67 APIs are already flagged as dead. You won’t waste an afternoon integrating something that 404s.

OpenAPI discovery. A weekly cron job searches GitHub for new OpenAPI/Swagger specs, parses them, deduplicates against the existing
catalog, and auto-imports. The directory grows without manual curation.

Semantic search. Embeddings-powered. Searching “send emails programmatically” finds email APIs even when the query doesn’t match
any name or tag directly.

Best-of pages. Category rankings like https://patchbay.cc/best/machine-learning and https://patchbay.cc/alternatives/stripe-api.
The comparisons I wished existed when I was evaluating options.

The stack is Next.js + Supabase + Vercel if that’s useful context.

What’s next

The catalog is solid. The discoverability layer is what I’m focused on now: making it genuinely faster to go from “I need an API
that does X” to actually integrating one. Changelog detection is running. Richer comparison data is in progress.

If you want to dig in

→ https://patchbay.cc

If your API is listed and needs updating, claiming is free. If you know of something missing, https://patchbay.cc/submit. And if
you want to build on top of the catalog, there’s a https://patchbay.cc/developers.