Teleport Report Finds Over-Privileged AI Systems Linked to Fourfold Rise in Security Incidents

Enterprises that grant excessive access permissions to AI systems experience 4.5 times as many security incidents as those that do not, according to The 2026 State of AI in Enterprise Infrastructure Security, a report published by infrastructure identity company Teleport. The study found that identity management hasn’t kept up with AI adoption in production systems.

By Matt Saunders

Something every senior engineer learns the expensive way:

LinkedIn Draft — Workflow (2026-03-28)

Something every senior engineer learns the expensive way:

Terraform DAGs at scale: when the graph becomes the hazard

Terraform’s dependency graph is elegant at small scale. At 500+ resources across a mono-repo, it becomes the most dangerous part of your infrastructure.

SAFE (small module):              DANGEROUS (at scale):

[vpc] ──▶ [subnet] ──▶ [ec2]     [shared-net] ──▶ [team-a-infra]
                                          │         [team-b-infra]
                                          │         [team-c-infra]
                                          │         [data-layer]
                                  One change → fan-out destroy/create

Where it breaks:
▸ Implicit ordering assumptions survive until a refactor exposes them — usually as an unplanned destroy chain in prod.
▸ Fan-out graphs make blast radius review near-impossible. ‘What does this change affect?’ has no fast answer.
▸ depends_on papering over bad module interfaces — it fixes the symptom and couples the modules permanently.

The rule I keep coming back to:
→ If a module needs depends_on to be safe, the module boundary is wrong. Redesign the interface — don’t paper over it.

How I sanity-check it:
▸ terraform graph | dot -Tsvg > graph.svg — visualize fan-out and cycles before every major refactor.
▸ Gate all applies with OPA/Conftest + mandatory human review on any planned destroy operations.

The difference between a senior engineer and a principal is knowing which guardrails to build before you need them.

Deep dive: https://neeraja-portfolio-v1.vercel.app/workflows/terraform-dags-at-scale-when-the-graph-becomes-the-hazard

Curious what guardrails you’ve built around this. Drop your pattern below.

terraform #iac #devops #sre

Understanding Object-Oriented Programming in JavaScript

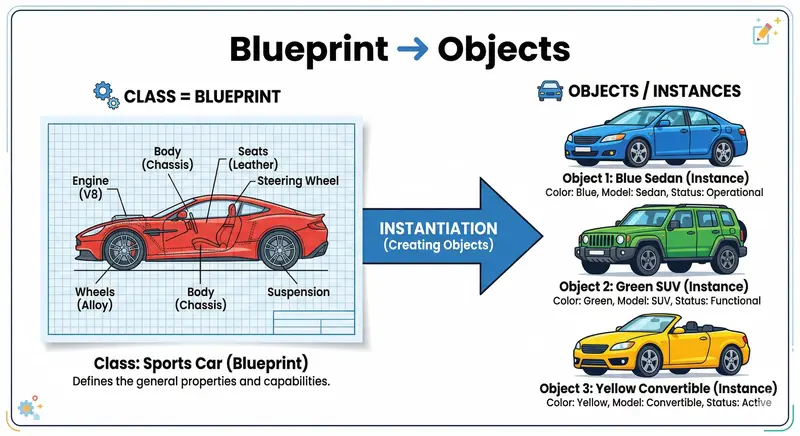
Cars Blueprint

Introduction

Hey there, fellow developer!

Imagine building a massive web app where your code feels like a chaotic pile of functions and variables. Then one day you discover Object-Oriented Programming (OOP) — and suddenly everything clicks into place like LEGO bricks. OOP isn’t just another fancy term; it’s the secret weapon that makes your JavaScript code reusable, organized, and scalable.

In this beginner-friendly guide, we’ll break down OOP in JavaScript using simple real-world examples (no overwhelming jargon, promise!). By the end, you’ll be able to create your own classes, instances, and understand why OOP makes developers’ lives so much easier. Let’s dive in!

What Object-Oriented Programming (OOP) Means?

Object-Oriented Programming is a programming paradigm (a style of writing code) that organizes software design around objects (specifically, instances of classes) rather than functions and logic.

Think of it this way:

  • In procedural code, you write step-by-step instructions.
  • In OOP, you model real-world things as objects that have properties (key-value pairs data) and behaviours (methods/functions).

The goal? Code reusability. Once you create a blueprint for something, you can reuse it a thousand times without rewriting code. This makes maintenance and collaboration smoother.

What is a Class in JavaScript?

In JavaScript (ES6 and above), a class is a blueprint for creating objects. It’s syntactic sugar over JavaScript’s prototype-based inheritance and constructor function, but it feels much more familiar if you’ve used OOP in other languages like Java.

You define a class using the class keyword:

class Car {
  // properties and methods go here
}

Simple, right? No more messy constructor functions from old-school JavaScript.

Real-World Analogy: Blueprint → Class → Objects

Let’s use the classic Car example (super easy to visualize).

  • A blueprint (technical drawing) of a car defines everything: engine size, color options, wheels, etc.
  • The actual cars rolling out of the factory are built from that blueprint. Each car has the same structure but can have different colors, mileage, or features.

You don’t redesign the entire car every time you want a new one — you just use the blueprint and tweak a few details.

That’s exactly how OOP works in JavaScript: the blueprint = Class, and the cars = Objects/Instances.

Cars Blueprint

Creating Instances Using Classes + The new Keyword

Once you have a class, you create actual objects (instances) using the new keyword.

const myCar = new Car();

What does new actually do internally? (Quick peek under the hood)

The new keyword is like a mini factory:

  1. It creates a brand-new empty object {}.
  2. It sets the new object’s [[Prototype]] (internal prototype link) to the class’s prototype property. This enables method sharing without copying methods to every instance.
  3. It binds this inside the constructor to point to this new object.
  4. It runs the constructor function (which usually adds properties via this.property = value).
  5. It implicitly automatically returns the newly created object.

This is what makes each instance unique while sharing the same structure. No new? You’ll get errors or unexpected behaviour — so always use it unless it’s a factory-method!

Class-Instances Relationship

Constructor Method

Every class can have a special method called constructor. It runs automatically when you create an object with new and is perfect for setting initial properties.

class Car {
  constructor(make, model, year) {
    this.make = make;      // 'this' refers to the new object
    this.model = model;
    this.year = year;
  }
}

const tesla = new Car("Tesla", "Model Y", 2025);
console.log(tesla.make); // Tesla

Methods Inside a Class

Methods are functions attached to the class. They define what the object can do.

class Car {
  constructor(make, model, year) {
    this.make = make;
    this.model = model;
    this.year = year;
  }

  startEngine() {
    console.log(`${this.make} ${this.model} engine started!`);
  }

  getAge() {
    return new Date().getFullYear() - this.year;
  }
}

const tesla = new Car("Tesla", "Model Y", 2025);
tesla.startEngine();     // Tesla Model Y engine started!
console.log(tesla.getAge()); // 1 (or whatever the current year is)

Notice how we reuse the same methods across all car objects? Reusability in action!

Note: These methods are nothing but the syntactic-sugar of prototype-based methods. Thus these methods doesn’t get copied each time when an instance is created, it’s in the shared memory.

Hands-On Example: Building a Student Class (Assignment Time!)

Let’s apply everything we learned. Create a Student class as your mini project:

class Student {
  constructor(name, age) {
    this.name = name;
    this.age = age;
  }

  printDetails() {
    console.log(`Student: ${this.name}, Age: ${this.age}`);
  }
}

// Creating multiple student objects
const student1 = new Student("Ritam", 22);
const student2 = new Student("Priya", 20);
const student3 = new Student("Aarav", 21);

student1.printDetails(); // Student: Ritam, Age: 22
student2.printDetails(); // Student: Priya, Age: 20
student3.printDetails(); // Student: Aarav, Age: 21

Boom! One class → unlimited students. This is the power of OOP.

The Four Pillars of OOP (Basic Ideas)

OOP rests on four foundational concepts which are more oftenly said as Four Pillars of Object-oriented Programming. Here’s the super-simple version:

  • Abstraction: Hide complex details and show only what’s necessary. (Like pressing the “Start” button on your car — you don’t need to know how the engine works internally.)
  • Encapsulation: Bundle data and methods together and restrict direct access (in JS we often use _privateVariable convention or #private fields). Keeps your object safe!
  • Inheritance: Create a new class which is based on an existing one. A Student class can inherit from a Person class and get name/age for free, then add its own features.
  • Polymorphism: Same method name, different behavior. A Person can speak(), but a Student can override it to say something different.

These pillars are what make OOP truly magical — and why your code stays DRY (Don’t Repeat Yourself).

Conclusion: Why You Should Love OOP in JavaScript

You’ve just gone from “What even is a class?” to “I can build reusable Student class!”

OOP in JavaScript gives you:

  • Cleaner, more organized code
  • Massive reusability (write once, use everywhere)
  • Easier maintenance and collaboration
  • A mental model that matches the real world

Next time you start a project, try modeling it with classes first — your future self will thank you.

Challenge for you: Extend the Student class with inheritance (make a CollegeStudent that adds major and overrides printDetails). Share your code in the comments!

Happy coding!

🧠 ShadowOS — An Invisible AI Operating System for Your Workflow

This is a submission for the Notion MCP Challenge

🚀 What I Built

What if your work could organize itself without you doing anything?

I built ShadowOS, a behavior-aware AI system that silently observes a developer’s workflow and automatically builds a structured, intelligent workspace in Notion.


Instead of manually:

  • writing notes
  • creating tasks
  • tracking bugs
  • documenting learning

ShadowOS converts your real-time actions into structured knowledge.

It acts like a second brain that evolves with you, powered by Notion MCP.

⚡ Key Features

🕵️ Passive Activity Tracking

ShadowOS monitors developer activity like:

  • Code edits
  • File changes
  • Workflow patterns

It logs only meaningful signals — not noise.

🧠 AI Intent Detection

Using an AI layer, the system:

  • Understands what you’re building
  • Detects patterns (e.g., debugging, feature development)
  • Infers your intent

🗂️ Auto-Structured Notion Workspace

Without manual input, it creates:

  • Feature documentation
  • Debug logs
  • Learning notes
  • Task lists

All inside Notion — automatically.

🔮 Predictive Workflow Suggestions

ShadowOS doesn’t just record — it thinks ahead:

Example:

“You just implemented authentication — want test cases and edge scenarios?”

📚 Personal Knowledge Graph

  • Tracks mistakes → solutions
  • Builds long-term learning insights
  • Creates a developer-specific knowledge base

🎥 Video Demo

👉 https://youtu.be/IniGA22G4zg

💻 Show Us the Code

👉 https://github.com/i-m-samarth-cs/ShadowOS.git


Notion

A tool that connects everyday work into one space. It gives you and your teams AI tools—search, writing, note-taking—inside an all-in-one, flexible workspace.

favicon
notion.so

🧠 What MCP Unlocks

With MCP, ShadowOS can:

Automatically push insights into Notion
Structure data into meaningful formats
Act as a persistent memory system
Enable AI agents to interact with real-world workflows

Notion becomes:

A dynamic operating system, not just a workspace.

🧪 Example Workflow
You edit a file in Cursor
ShadowOS logs the activity
AI analyzes intent
MCP sends structured insight to Notion
Notion updates automatically

Result:

Feature doc created
Tasks suggested
Knowledge stored

All without manual effort.

🧩 Why This Matters

Today, developers spend time:

documenting
organizing
remembering

ShadowOS removes that overhead.

It shifts the paradigm from:

“Write what you did”

to:

“Let the system understand what you did”

🏁 Future Scope
Cursor plugin for real-time integration
Multi-agent system (debugger, planner, reviewer)
Learning gap detection
Team-level intelligence sharing
Cross-platform workflow tracking


🧠 Final Thought

ShadowOS is not just a tool —
it’s a step toward autonomous workflows powered by human behavior.

Notion MCP made it possible to transform:

raw activity → structured intelligence
actions → knowledge
workflows → systems

Cryptographic Identity Systems for Auditing Autonomous AI Agents

If you’ve ever asked, “Which agent actually made this change?” and realized your logs only say service-account-prod or automation-bot, you’ve already hit the core problem with autonomous AI systems: they can act, but they’re often not individually accountable.

That gets painful fast. An agent opens a PR, rotates a secret, calls an internal MCP tool, or triggers a deploy. Later, you need to answer basic audit questions:

  • Which agent performed the action?
  • Under whose authority was it operating?
  • Was it delegated access, and by whom?
  • What exact policy allowed the action?
  • Can I prove the event log wasn’t tampered with?

For many teams, the current answer is some combination of shared API keys, broad service accounts, and application logs that weren’t designed for non-human actors. That works right up until you need incident response, compliance evidence, or just confidence that your agents aren’t quietly over-privileged.

The fix is not “more logs.” It’s giving agents real identities.

Why AI agents need cryptographic identity

A useful mental model is: treat autonomous agents less like scripts and more like machine principals with constrained authority.

A proper identity system for agents should give you:

  1. A unique cryptographic identity per agent
  2. Verifiable delegation of authority
  3. Policy-based access control
  4. Tamper-evident audit trails
  5. Revocation and approval workflows

Without those pieces, “agent auditing” usually means reconstructing intent from app logs after the fact. With them, you can validate who acted, what they were allowed to do, and whether the action chain was legitimate.

In practice, this usually means issuing each agent its own keypair and signing requests or action attestations. Ed25519 is a strong default here because it’s fast, widely supported, and straightforward to use.

A minimal architecture

At a high level, an auditable agent system looks like this:

  • Agent identity: each agent has a public/private keypair
  • Delegation layer: a human, service, or parent agent can delegate scoped permissions
  • Policy engine: evaluates whether the requested action is allowed
  • Execution boundary: tools, APIs, or MCP servers verify identity and authorization
  • Audit log: records signed actions, decisions, and delegation chains

You do not need a giant platform to start. If your environment is already built around OAuth, OIDC, SPIFFE, or OPA, those may be the right primitives. The important part is that your agents stop sharing identities.

What “good” looks like in an audit trail

A useful audit event for an autonomous agent should capture more than “request succeeded.” It should include:

  • Agent ID / public key fingerprint
  • Parent delegation or token exchange chain
  • Requested action
  • Target resource
  • Policy decision and policy version
  • Approval requirement, if any
  • Timestamp
  • Signature or signed envelope hash

For example:

{
  "event_type": "tool.invoke",
  "agent_id": "agent:code-reviewer:ed25519:9f3c...",
  "delegated_by": "user:sre-oncall",
  "delegation_chain": [
    "user:sre-oncall",
    "agent:incident-coordinator",
    "agent:code-reviewer"
  ],
  "resource": "mcp://github/pull_request/comment",
  "action": "write",
  "policy_decision": "allow",
  "policy_id": "repo-comment-policy@v12",
  "timestamp": "2026-03-28T10:15:21Z",
  "signature": "base64..."
}

That’s the difference between “some automation commented on a PR” and “this specific agent, acting through this delegated authority, was allowed by this policy to do exactly this thing.”

Delegation matters more than most teams expect

A lot of agent systems fail at the identity layer because they only model direct permissions. But autonomous systems often act on behalf of users, teams, or supervisor agents.

That means you need delegation, not just authentication.

A common pattern is token exchange and delegation chains similar to RFC 8693, where one principal exchanges or derives a token representing scoped authority for another principal. In an agent environment, that lets you say:

  • Alice approved a production investigation
  • The incident coordinator agent can inspect logs for 30 minutes
  • It can delegate read-only GitHub access to a code analysis agent
  • But not deploy, rotate secrets, or access unrelated repos

That chain should be inspectable and logged.

Policy: use OPA if it fits

If you already use Open Policy Agent, keep using it. OPA is a strong choice for evaluating whether an agent should be allowed to perform an action, especially if you want consistent policy across services.

A simple Rego policy might look like this:

package agent.authz

default allow = false

allow if {
  input.agent.role == "reviewer"
  input.action == "comment"
  input.resource.type == "pull_request"
}

allow if {
  input.agent.role == "deployer"
  input.action == "deploy"
  input.resource.env == "staging"
}

require_approval if {
  input.action == "deploy"
  input.resource.env == "production"
}

Then your execution layer can evaluate:

  • Is the agent authenticated?
  • Is the delegation chain valid?
  • Does policy allow this action?
  • Is approval required before execution?

That model works whether your tools are internal APIs, CI jobs, or MCP-connected systems.

A simple example: signed agent actions

Here’s a minimal Python example using Ed25519 to sign an action envelope.

import json
import time
from nacl.signing import SigningKey

signing_key = SigningKey.generate()
verify_key = signing_key.verify_key

action = {
    "agent_id": "agent:triage-bot",
    "action": "create_issue",
    "resource": "github://org/repo",
    "delegated_by": "user:alice",
    "timestamp": int(time.time())
}

payload = json.dumps(action, separators=(",", ":"), sort_keys=True).encode()
signed = signing_key.sign(payload)

print("public_key:", verify_key.encode().hex())
print("signature:", signed.signature.hex())
print("payload:", payload.decode())

And verification:

from nacl.signing import VerifyKey

public_key_hex = verify_key.encode().hex()
verify_key = VerifyKey(bytes.fromhex(public_key_hex))

verify_key.verify(payload, signed.signature)
print("verified")

This alone is not a complete authorization system, but it gives you a cryptographically verifiable event origin. Add delegation claims, policy evaluation, and immutable audit storage, and you’re in much better shape.

Getting started: a practical path

If you want to improve agent auditability without redesigning everything, start here.

1. Stop sharing agent credentials

Give each agent instance or logical agent role its own identity. Even if you begin with a simple key registry, that’s better than one API key for all automation.

2. Define a standard action envelope

Pick a canonical structure for agent actions:

  • agent ID
  • action
  • resource
  • timestamp
  • delegation context
  • policy decision
  • optional approval metadata

Sign it, or at least hash and persist it consistently.

3. Add policy checks at tool boundaries

Your enforcement point should be where the agent actually does something useful:

  • call an API
  • write to a repo
  • invoke an MCP tool
  • access a secret
  • trigger a deployment

This is where OPA, custom middleware, or an internal authorization service can help.

4. Model delegation explicitly

If an agent acts on behalf of a user or another agent, represent that as first-class data. Don’t bury it in a log message.

5. Log decisions, not just outcomes

Record why access was granted or denied:

  • policy name/version
  • matched rule
  • approval status
  • delegator identity

That makes incident review dramatically easier.

Where Authora fits

If you want to build this yourself, the core ingredients are well understood: per-agent keys, delegated authorization, policy enforcement, and durable audit logs.

If you want something more turnkey, this is the area Authora focuses on. Authora Identity provides cryptographic agent identities based on Ed25519, RBAC, delegation chains aligned with RFC 8693-style flows, MCP authorization, policy engines, approval workflows, and audit logging, with SDKs in TypeScript, Python, Rust, and Go.

That said, the broader point is more important than any single vendor choice: agents need real identities, not reused service credentials.

As teams move from “AI that suggests” to “AI that acts,” identity becomes the control plane for trust. If you can’t prove which agent did what, under what authority, and why it was allowed, you don’t really have an auditable autonomous system.

And if you can, a lot of security and compliance problems become much more manageable.

— Authora team

This post was created with AI assistance.

7 Protocols, 1 Binary, 0 Dependencies

Last year I counted the mock tools running on my laptop. WireMock for HTTP (Java, 200MB Docker image). A custom Node script for WebSocket. Mosquitto for MQTT. A Go stub for gRPC. Four tools, four runtimes, four sets of config files, four ports to remember. I spent more time wiring up mock infrastructure than writing the code it was supposed to help me test.

So I built mockd. One binary:

mockd add http --path /api/orders --status 200 
  --body '{"orders": [{"id": "{{uuid}}", "total": {{faker.price}}}]}'
Created mock: http_c9e4c315168bcfbe / Type: http / Method: GET / Path: /api/orders / Status: 200
curl http://localhost:4280/api/orders
{"orders": [{"id": "7e53e8ca-...", "total": 405.87}]}

HTTP done. Same binary, six more protocols to go.

All 7 protocols

Every protocol follows the same pattern: mockd add <type>, configure, hit the endpoint. No plugins. No extensions. No separate downloads.

GraphQL

mockd add graphql --path /graphql --operation GetUser 
  --response '{"id":"1","name":"{{faker.name}}","email":"{{faker.email}}"}'

Test it: curl -X POST http://localhost:4280/graphql -H 'Content-Type: application/json' -d '{"query":"{ GetUser }"}' returns {"data":{"GetUser":{"email":"[email protected]","id":"1","name":"Charlie Brown"}}}.

gRPC

mockd add grpc --proto service.proto --service greeter.Greeter 
  --rpc-method SayHello --response '{"message": "Hello, {{faker.name}}!"}'

You provide the .proto file, mockd handles reflection and serialization. Port 50051 by default.

WebSocket

mockd add websocket --path /ws/chat 
  --message '{"event":"connected","ts":"{{now}}"}'

MQTT

mockd add mqtt --topic sensors/temp 
  --payload '{"temp":{{random.float 20.0 35.0}},"unit":"C","ts":"{{now}}"}'

Built-in MQTT broker on port 1883. No Mosquitto required.

SSE (Server-Sent Events)

mockd add http --path /events --sse 
  --sse-event 'update:{"ts":"{{now}}","cpu":{{random.int 10 95}}}'

curl -N http://localhost:4280/events streams event:update / data:{"ts":"2026-03-07T18:26:03-06:00","cpu":70}.

SOAP

mockd add soap --path /service --operation GetUser --status 200 
  --response '<User><Id>1</Id><Name>{{faker.name}}</Name></User>'

Send a SOAP envelope with SOAPAction: GetUser, get back a properly wrapped response.

All together

ID                    TYPE       PATH             METHOD  STATUS  ENABLED
list-users            http       /api/users       GET     200     true
graphql_917e99253...  graphql    /graphql         GQL     -       true
websocket_91720db...  websocket  /ws/chat         WS      -       true
mqtt_4c28d4810103...  mqtt       :1883            MQTT    -       true
http_32897b6a3bd8...  http       /events          GET     -       true
soap_edc045dfba00...  soap       /service         SOAP    -       true
grpc_7a2ea7f56902...  grpc       :50051           gRPC    -       true

Seven protocols. One process. One config file. One set of logs.

Why Go, why single binary

I get asked this a lot. Go was chosen for three reasons:

Static binary. CGO_ENABLED=0 go build produces a single statically-linked executable. No shared libraries, no runtime, no interpreter. Copy it to any Linux/macOS/Windows machine and it runs. Docker image is distroless/static — no shell, no libc.

Goroutines. Each protocol listener runs in its own goroutine. HTTP, gRPC, MQTT, WebSocket — same process, none blocking each other. In Node that’s clustering. In Java it’s thread pools. In Go it’s go serve().

Cross-compilation. GOOS=darwin GOARCH=arm64 go build from a Linux CI runner. Mockd ships six OS/arch binaries from a single GitHub Actions workflow.

The result is a 43MB binary containing all seven protocol servers, 34 faker functions, an admin API, and a request logger. No runtime to download. No plugins to install.

That matters in three places: CI/CD (curl -fsSL https://get.mockd.io | sh && mockd start — two seconds vs. pulling a 200MB Docker image), laptop onboarding (“install mockd” vs. “install Java 17 and Docker Desktop”), and air-gapped networks (a single binary can be SCP’d to a bastion host — try that with node_modules).

Shared internals

The seven protocols share core infrastructure:

  • Template engine — {{faker.name}}, {{uuid}}, {{now}}, {{random.int 1 100}} — same 34 faker functions across every protocol
  • Config — one YAML or JSON file defines all mocks across all protocols
  • Request logging — HTTP, GraphQL, gRPC, WebSocket, MQTT traffic in one unified log
  • Import — OpenAPI, Postman, HAR, WireMock, cURL, Mockoon, and WSDL formats
  • Chaos — 10 profiles and 12 fault types apply across HTTP, GraphQL, gRPC, and SOAP
  • MCP — 18 tools give AI agents programmatic access to everything

How this compares

Tool Language Protocols Size Runtime
mockd Go 7 (HTTP, GraphQL, gRPC, WS, MQTT, SSE, SOAP) 43MB binary None
WireMock Java HTTP (extensions for others) ~200MB Docker JVM
Mockoon Electron/Node HTTP, GraphQL ~200MB app Node
json-server Node REST ~2MB (+ Node) Node
Prism Node HTTP (OpenAPI validation) ~50MB (+ Node) Node
MockServer Java HTTP/HTTPS ~200MB Docker JVM

WireMock is battle-tested with a huge plugin ecosystem. Mockoon has a desktop UI nothing else matches. json-server is dead simple for REST prototyping. Mockd’s angle: all seven protocols from one tool, zero runtime dependencies, sub-second startup.

The honest part

43MB is not small. It’s smaller than pulling a JVM or Node runtime, but it’s not a 5MB CLI tool. Every protocol adds weight — gRPC alone brings in protobuf libraries. I could strip features to shrink the binary, but that defeats the point.

gRPC requires a .proto file. There’s no way around this. gRPC is contract-driven — you can’t hand-wave the schema like you can with HTTP. No .proto file, no gRPC mock. That’s a protocol constraint, not a mockd constraint, but it still adds friction.

The MQTT broker is basic. QoS 0 and 1, topic wildcards, pub/sub. No clustering, no persistence, no QoS 2. For dev/test it’s fine. For benchmarking against a real broker, use Mosquitto or EMQX.

SOAP exists because it has to. Banks, insurance, healthcare — I didn’t add SOAP because I enjoy XML. I added it because developers at those companies deserve mock tooling that isn’t “install a 2008 Java web server.”

Install

brew install getmockd/tap/mockd
# or
curl -fsSL https://get.mockd.io | sh

Start the server and start adding mocks. Every protocol. One binary. Zero dependencies.

Learn more

Links

I built a relay so my AI agents stop talking through me

My coworker and I were both using Claude Code on a shared infra project. He was building services, I was setting up Pulumi. Our workflow was:

  1. Claude tells me something about the deploy structure
  2. I copy it into Slack
  3. My coworker pastes it into his Claude
  4. His Claude responds
  5. He screenshots it back to me

We were the middleware. Two humans acting as a message bus between two AIs.

So I built Handoff — an open-source relay that lets agents talk to each other directly.

The idea

Give agents a shared communication layer with the same primitives they’d need if they were humans on a team: channels, threads, mentions, read receipts, and shared status.

Your Claude:     "ArgoCD expects deploy/{service}/kustomization.yaml"
Their Claude:    "Structured deploy/ to match. checkout-api, inventory-service ready."

No human in the loop. No copy-paste. No screenshots.

How it works

1. Create a team (one curl)

curl -X POST https://handoff.xaviair.dev/api/signup 
  -H 'Content-Type: application/json' 
  -d '{"team_name":"my-team","sender_name":"my-name"}'

You get back an API key. Share additional keys with teammates via the create_key endpoint.

2. Everyone adds the MCP server (one command)

claude mcp add handoff 
  -e RELAY_API_URL=https://handoff.xaviair.dev 
  -e RELAY_API_KEY=your_key_here 
  -- npx -y handoff-sdk

That’s it. Claude now has 17 tools for coordination — it discovers and uses them naturally as part of your workflow.

3. Agents coordinate directly

Claude gets tools like post_message, read_unread, set_status, ack. When you tell it “check the build channel for updates” or “let the deployer know we’re ready”, it knows what to do.

What’s in the box

Channels & threads

Agents communicate through named channels (build, deploy, review). Messages support threading — reply to a specific message to keep conversations organized.

Mentions

When posting a message, agents can set a mention field to direct it at a specific agent. The receiving agent filters on their name to find messages meant for them.

Read receipts (acks)

After reading messages, agents call ack with the last message ID. Other agents can check get_acks to see who’s caught up. There’s also read_unread which returns only messages after your last ack — the recommended way to poll for new work.

Shared status

Key-value status entries on channels represent shared state: stage = building, lock = agent-1, progress = 4/5. Every write is logged, so you can query the full status change history.

Real-time streaming

SSE endpoint for real-time push. Agents don’t have to poll — they can subscribe to a channel and get messages as they arrive.

E2EE

Optional AES-256-GCM client-side encryption. Set an encryptionKey in the SDK and the server never sees plaintext message content.

Channel-scoped permissions

This is the feature I’m most proud of. Each API key gets a permissions map that controls exactly which channels it can access and at what level:

{
  "build": "write",
  "deploy": "read",
  "monitoring": "read"
}

Three levels:

  • read — view messages and status
  • write — read + post messages, ack, set status
  • admin — write + delete channels and messages

Use "*" as a wildcard for full access across all channels.

I tested this with a 7-agent deployment simulation:

Agent Permissions
orchestrator *: admin
builder build: write, deploy: read
reviewer review: write, build: read
deployer deploy: write, build: read
monitor monitoring: write, build+deploy: read
qa review: write, build+deploy: read
notifier all channels: read

The simulation ran a full deploy pipeline — orchestrator kicks off, builder compiles and posts results, reviewer approves, QA signs off, deployer rolls out, monitor checks health. Every unauthorized write was blocked. The notifier could read everything but write to nothing.

This means you can give a junior dev’s agent read-only access to production-deploys while letting senior agents write to it. Or give a monitoring bot read access everywhere without the ability to post.

TypeScript SDK

If you’re building custom agents outside of Claude Code:

npm install handoff-sdk
import { Handoff } from "handoff-sdk";

const hf = new Handoff({
  apiUrl: "https://handoff.xaviair.dev",
  apiKey: "relay_..."
});

await hf.post("infra", "EKS cluster ready", { mention: "jordan" });
await hf.reply("infra", msgId, "What node instance type?");
await hf.setStatus("infra", "eks", "ready");

const unread = await hf.read("infra");
const unsub = hf.on("infra", (msg) => console.log(msg)); // SSE

Architecture

The server is Go with Redis. Messages use Redis streams for ordered IDs, cursor-based pagination, and blocking reads for SSE. All keys are team-namespaced (t:{teamID}:) for multi-tenant isolation.

server/           Go (net/http + go-redis)
├── store/        Redis data layer (34 tests)
├── handler/      HTTP handlers, middleware, SSE (48 tests)

src/              TypeScript
├── sdk.ts        SDK with E2EE support
├── mcp.ts        MCP server (17 tools)

82 tests, self-hostable with docker compose up -d. The Go binary is ~15MB.

What’s next

  • Message schemas/contracts so agents can agree on content format
  • TTL/expiry for channels and messages
  • Per-key rate limiting
  • Dashboard for observing agent conversations in real-time

Try it

The hosted relay is free at handoff.xaviair.dev. Self-host with Docker if you prefer.

If you’re running multi-agent workflows and tired of being the message bus, give it a shot. Stars appreciated.

Day 55 of #100DayOfCode — Data Fetching and Caching in NextJS

Date Fetching React vs Next.js

Data fetching with React follows the same well-known drill: useEffect, useState, loading spinners, and API keys being dangerously exposed on the frontend. Next.js changes all of that. With its built-in server-side data fetching and automatic caching system, Next.js makes it possible to build fast, secure, full-stack applications without reaching for a dozen extra libraries.

For day 55, the goal was to understand how data fetching works in Next.js, how it compares to the React way, and how to use the different caching strategies to make the app as fast and efficient as possible.

Data Fetching: React vs Next.js

How React Fetches Data

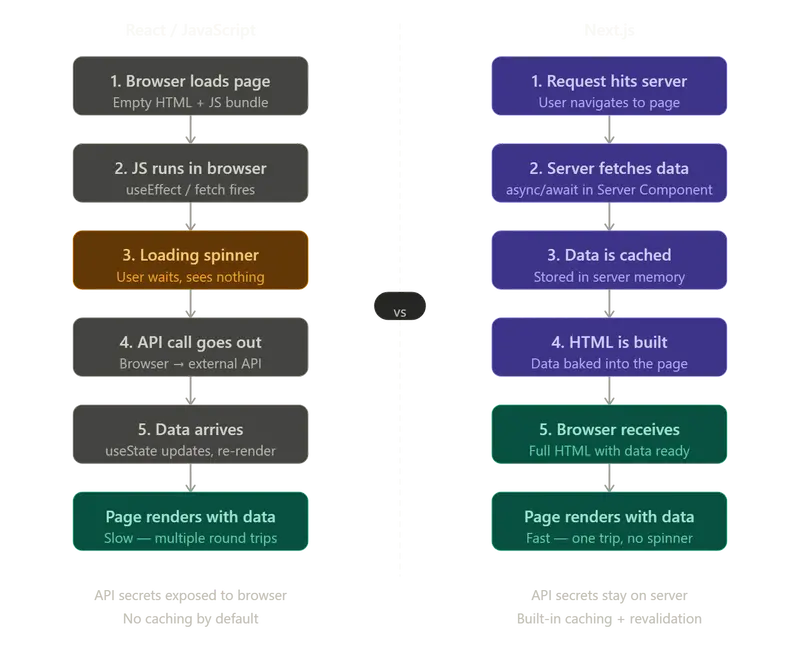
In React, data fetching happens entirely in the browser. When a user visits a page, the browser first downloads the HTML (which is mostly empty), then runs your JavaScript bundle, and only then fires off an API request to fetch the data. This means the user always sees a loading state before the actual content appears.

Here is what that typically looks like:

import { useState, useEffect } from 'react'

function Posts() {
  const [posts, setPosts] = useState([])
  const [loading, setLoading] = useState(true)

  useEffect(() => {
    fetch('https://api.example.com/posts')
      .then(res => res.json())
      .then(data => {
        setPosts(data)
        setLoading(false)
      })
  }, [])

  if (loading) return <p>Loading...</p>

  return (
    <div>
      {posts.map(post => (
        <div key={post.id}>
          <h2>{post.title}</h2>
          <p>{post.body}</p>
        </div>
      ))}
    </div>
  )
}

This works, but it comes with real problems:

  • Loading spinners everywhere —> users see an empty page or spinner before any content appears.
  • Multiple round trips —> the browser loads the page, then makes a separate API request, adding latency.
  • Exposed API keys —> any secret keys used in fetch calls are visible in the browser’s DevTools Network tab.
  • No built-in caching —> every render triggers a fresh API call unless you manually set up something like React Query or SWR.
  • SEO suffers —> search engines crawl the empty HTML before JavaScript runs, so they may not see your content at all.

How Next.js Fetches Data

Next.js introduces Server Components; components that run on the server before the HTML is ever sent to the browser. Because they run on the server, you can make them async and await your data at the top level. No useEffect, no useState, no loading spinner.

async function Posts() {
  const res = await fetch('https://api.example.com/posts')
  const posts = await res.json()

  return (
    <div>
      {posts.map(post => (
        <div key={post.id}>
          <h2>{post.title}</h2>
          <p>{post.body}</p>
        </div>
      ))}
    </div>
  )
}

That is the entire component. The server fetches the data, builds the HTML with the data already inside it, and sends the finished page to the browser. The user never sees a loading state because by the time the page arrives, the data is already there.

This approach is better for several reasons:

  • No loading spinners —> data arrives with the page, not after it.
  • Better performance —> one round trip instead of two.
  • API keys stay hidden —> the fetch call never reaches the browser, so secrets stay on the server.
  • Better SEO —> search engines receive fully rendered HTML with real content.
  • Built-in caching —> Next.js automatically caches fetch responses on the server (more on this below).

The fetch syntax is the same as in React or plain JavaScript. The only difference is where it executes, on the server, and the automatic handling by Next.js.

Comparison of Data Fetching between React/JS vs Next.js

Date Fetching React vs Next.js

What is Caching in Next.js?

Caching means storing the result of an API call so that the next time the same data is needed, it can be served instantly from the stored copy instead of making another network request. Without caching, every user visiting your page triggers a fresh API call, which is slow and expensive, especially if thousands of users are hitting the same endpoint.

Next.js extends the native fetch API with its own caching layer baked in. You control the caching behavior by passing options to your fetch call.

Important version note: In Next.js 13 and 14, caching was ON by default and you had to opt out. In Next.js 15, the default was flipped, caching is now OFF by default, and you have to opt in. Always check your version before assuming the default behavior.

Types of Caching in Next.js

1. Cache Forever (force-cache)

const res = await fetch('https://api.example.com/posts', {
  cache: 'force-cache'
})

This fetches the data once and caches it indefinitely. Subsequent requests for the same data are served instantly from the cache without hitting the API again. This is the most aggressive caching strategy and gives you the fastest possible response times.

2. No Cache (no-store)

const res = await fetch('https://api.example.com/posts', {
  cache: 'no-store'
})

This completely disables caching. Every request hits the API fresh and gets the latest data. This is the slowest option but guarantees you always have up-to-date information.

3. Revalidate Every N Seconds (ISR)

const res = await fetch('https://api.example.com/posts', {
  next: { revalidate: 60 }
})

This is the sweet spot for most applications. It caches the response but automatically refreshes it every 60 seconds in the background. Users always get a fast cached response, but the data does not go stale forever. This is called Incremental Static Regeneration (ISR) and it uses a stale-while-revalidate strategy, serve the cached version immediately, then quietly fetch a fresh copy in the background for the next request.

4. Revalidate On Demand

import { revalidatePath } from 'next/cache'

// Call this function whenever your data changes
export async function updatePost() {
  // ... update logic

  revalidatePath('/posts') // tells Next.js to rebuild this page
}

Instead of refreshing on a time interval, you manually tell Next.js when the cached data is stale. This is useful when you know exactly when data changes — for example, when a user submits a form, a CMS editor publishes new content, or a webhook fires from an external service. The page is rebuilt on the next request after revalidatePath is called.

Which Caching Strategy Should Be Used?

Choosing the right caching strategy depends entirely on how often the fetched data in the app changes and how critical it is that users see the latest version. Here is a practical breakdown:

Use force-cache for content that rarely changes

Think documentation pages, marketing landing pages, legal pages, blog posts that are rarely edited, or any content that was written once and stays the same. Since this data does not change, there is no reason to ever hit the API again after the first fetch. force-cache gives you maximum speed with zero cost.

const res = await fetch('https://api.example.com/docs', {
  cache: 'force-cache'
})

Use revalidate (ISR) for content that changes occasionally

This is the right choice for the majority of real-world pages: e-commerce product listings where prices update periodically, news articles, blog indexes, weather data for a specific city, or sports standings. The data changes, but not so frequently that a slightly stale version causes real problems. A revalidation interval of 60 seconds to an hour is usually appropriate, depending on how time-sensitive the data is.

// Refresh every 10 minutes — good for product listings
const res = await fetch('https://api.example.com/products', {
  next: { revalidate: 600 }
})

Use revalidatePath for content driven by user actions or a CMS

When you are building a blog or CMS-backed site and an editor publishes a new post, you want that page to update immediately, not in 10 minutes. revalidatePath lets you trigger a rebuild the moment the content changes. The same applies to e-commerce admin panels, user-generated content, or any situation where a specific action is the trigger for stale data.

import { revalidatePath } from 'next/cache'

async function publishPost(id) {
  await db.post.update({ where: { id }, data: { published: true } })
  revalidatePath('/blog') // immediately mark the blog listing as stale
}

Use no-store for data that must always be live

User-specific data like dashboards, account settings, or notification counts must never be cached; each user needs their own fresh data. The same goes for live stock prices, real-time sports scores, or anything where a stale response would cause real user confusion or financial consequences.

const res = await fetch(`https://api.example.com/user/${userId}/dashboard`, {
  cache: 'no-store'
})

Quick Reference

Data type Strategy Example
Static content, never changes force-cache Docs, legal pages, about page
Changes occasionally revalidate: 3600 Blog posts, product listings
Changes frequently revalidate: 60 News feed, prices, scores
Changes unpredictably revalidatePath on demand CMS content, user-published posts
Must always be live no-store User dashboard, live data, notifications

Final Thoughts

Data fetching and caching in Next.js simplify web application development. Instead of complex client-side fetching with useEffect, Next.js manages loading states, API key security, and caching out of the box.

With Server Components, you can use async/await data fetching directly in your components with minimal boilerplate. The built-in caching system allows for fine-grained control over data freshness in your fetch calls. These features enable you to build fast, secure, and SEO-friendly full-stack applications in Next.js while maintaining a great developer experience.

Thanks for reading. Feel free to share your thoughts!

Why I Built Migrun

I mostly work with PHP projects that do not live inside a full framework like Laravel or Symfony — frameworks that come with their own ORM-based migration tools.
The existing standalone migration tools like Phinx, Phpmig, Phoenix are available, but they come with problems that kept bothering me over the years.
I would not even call Phinx standalone — it pulls in the Cake framework’s core.

Service container integration is a hack. At least in Phinx, which I used the most.
If you use a dependency injection container (and you really should), wiring services into Phinx migrations is not possible.
People resort to global static access or other workarounds to get their own database connection or a service like logger into their migration.
This completely goes against modern DI practices.
I wanted migrations to simply declare their dependencies and have them resolved from the container automatically.

Query builders add complexity you don’t need.
Migration systems often provide table builders — APIs for creating columns, indexes, and tables in a database-agnostic way.
Usually based on the particular framework ORM. In theory, this lets you switch databases without rewriting migrations. In practice:

  • Most projects never switch databases. None of the projects I’ve worked with ever did. They introduced new databases, but did not replace one with another.
  • When they do, they have to deal with database-specific features, data types, and behaviors anyway.
  • The builder APIs cannot cover every database-specific case. Like this classic problem in Laravel. Phinx is even more limited. You end up writing raw SQL for the tricky parts regardless.
  • The builder adds a layer of abstraction and complexity for something that a simple CREATE TABLE statement does just fine.

I am not saying builders are useless. But for many projects, they are unnecessary overhead.

All the tools use inheritance. Your migration class must extend an AbstractMigration base class. This means you are locked into a class hierarchy.
In modern PHP, we prefer composition and interfaces over inheritance. Inheritance-based designs are rigid and harder to integrate with your own architecture.

They all impose naming conventions and rigid directory structure upon the adopters. Archiving migrations after hundreds have accumulated? Not an option or PITA.

The standalone tools feel outdated. Migration tools in the PHP ecosystem have not evolved with the language.
PHP has readonly classes, enums, named arguments, union types, fibers, pipelines.
Meanwhile, migration tools still use patterns from the PHP 5 era.

Any sort of I/O integration is a hack.
Phinx only works within Symfony Console, and the runner is tightly coupled to it. Go and try to create an HTML page with the list of migrations, I dare you.

What I wanted

Something dead simple:

  • An interface for migrations. Implement up(), optionally down(). Done.
  • Autowiring from the service container. Declare PDO $db as a parameter and it gets resolved.
  • No base classes to extend.
  • No config files.
  • No bundled CLI. No Symfony console.
  • No query builder.
  • No file naming constraints.
  • Zero runtime dependencies. Not even utility packages. No Cake core.
  • Any database, any tech stack, any service container.

So I built Migrun.

Who it is for

Migrun is for developers who:

  • Work on PHP projects outside of Laravel or Doctrine ecosystems
  • Want a migration runner that fits into their existing architecture, not one that dictates it
  • Prefer writing SQL directly instead of learning a builder API
  • Use a service container and want their migrations to benefit from it naturally
  • Want something minimal and hackable, not a full framework

If you already use Laravel or Doctrine, their migration systems are deeply integrated and you should keep using them.
Migrun was not built to replace those — it was built for everyone else.

How it works

Return an anonymous class instance from a PHP file. Get all the parameters auto-resolved from your service container.

// 20260326_181000_a_migration.php
<?php

use DakujemMigrunMigration;
use PsrLogLoggerInterface;
use PDO;

return new class implements Migration
{
    public function up(?PDO $db = null, ?LoggerInterface $logger = null): void {
        $db->exec(<<<SQL

CREATE TABLE users (
    id INT AUTO_INCREMENT PRIMARY KEY,
    email VARCHAR(255) NOT NULL UNIQUE
)

SQL);
        $logger->debug('Users table created.');
    }
};

Need a rollback? Don’t like the heredoc syntax? No problem.

// 20260326_181002_reversible_migration.php
<?php

use DakujemMigrunReversibleMigration;
use PDO;

return new class implements ReversibleMigration
{
    public function up(?PDO $db = null): void {
        $db->exec('CREATE INDEX idx_users_email ON users (email)');
    }

    public function down(?PDO $db = null): void {
        $db->exec('DROP INDEX idx_users_email');
    }
};

You can also just return a closure:

// 20260326_181008_closure_migration.php
<?php

return function (PDO $db): void {
    $db->exec(<<<SQL

CREATE INDEX idx_users_email ON users (email)

SQL);
};

You write the SQL on your terms. You run whatever services your app needs. Fully in control. No hacks.

Setting it up takes a few lines of code.

$migrun = new MigrunBuilder()
    ->directory(__DIR__ . '/migrations')
    ->container($container)    // any PSR-11 container for autowiring
    ->pdoStorage($container->get(PDO::class))
    ->build();

$migrun->run();          // run pending migrations
$migrun->rollback(1);    // roll back the last one
$migrun->status();       // see what's applied and what's pending

See the readme for fully functional CLI examples (like composer migrate:up),
or have AI tools set them up for you in a minute.
Symfony console is supported but not required (e.g. php bin/console db:migrate).

The architecture

Migrun is built around four straight-forward interfaces that

  • look for migrations
  • execute migrations
  • resolve migration dependencies
  • store migration history

Want to load pure SQL files? Implement a new “executor” (a single method) and a new “finder” (two methods).
Want to use a different DI container? Implement a single “invoker” method.
Want to store the history in Redis? Implement a new storage class.

No inheritance anywhere in the library. No static methods. No global state.

Give it a try.
It’s in beta phase — your feedback may shape the release version.

  • Repository: github.com/dakujem/migrun
  • Install: composer require dakujem/migrun; or prompt “Install dakujem/migrun from Packagist using the recommended setup and add CLI scripts called via Composer.”