Linting and Formatting Python 2 Code in 2026: Navigating Obsolescence and Jython Constraints

Introduction: The Python 2 Dilemma in 2026

In 2026, Python 2 is not just obsolete—it’s a relic. Officially unsupported since 2020, its ecosystem has withered, leaving developers stranded with legacy systems that cannot be easily migrated. The problem is compounded by Jython’s rigid dependency on Python 2, a constraint that forces developers to maintain code in a language that modern tools have largely abandoned. This isn’t just about nostalgia for an older version; it’s about systems that, for regulatory, financial, or operational reasons, cannot be upgraded. The stakes are clear: without effective linting and formatting, Python 2 codebases degrade, introducing security vulnerabilities, performance bottlenecks, and maintenance nightmares.

The Jython Constraint: A Mechanical Dead-End

Jython’s architecture is the root of the problem. It compiles Python 2 code to Java bytecode, a process that locks developers into Python 2 syntax and semantics. Attempting to run Python 3 code through Jython would trigger syntax errors (e.g., print() vs. print) and runtime failures due to incompatible standard library calls. Even if Python 3 tooling were available, Jython’s interpreter would reject the output, breaking the deployment pipeline. This isn’t a software incompatibility—it’s a mechanical mismatch between the Python 2 engine Jython expects and the Python 3 syntax modern tools produce.

Tooling Breakdown: Why Modern Linters Fail

Tools like Black, isort, and Flake8 have ceased Python 2 support. Black, for instance, dropped Python 2 compatibility in 2019, its parser now physically unable to process Python 2 syntax (e.g., urllib vs. urllib.parse). Flake8’s plugins, such as flake8-bugbear, rely on Python 3 AST structures, causing internal errors when encountering Python 2 code. Even if installed in a Python 2 environment, these tools would fail to execute due to missing dependencies like typed_ast, which itself no longer supports Python 2. The result? A causal chain of failures: incompatible parser → AST mismatch → tool crash.

Practical Solutions: Navigating the Minefield

Given these constraints, developers must adopt hybrid strategies. Here’s a decision-dominated analysis:

  • Option 1: Legacy Tooling Revival

Pin Python 2-compatible versions of linters (e.g., flake8==3.8.4, autopep8==1.5.4). However, these versions are frozen in time, lacking security patches and bug fixes. Risk: dependency conflicts with Jython’s Java environment, as Python 2 packages may require C extensions incompatible with JVM.

  • Option 2: Python 3 Tooling with Polyglot Mode

Use tools like libfuturize to convert Python 2 code to Python 3, then apply modern linters. However, Jython rejects Python 3 syntax, rendering this mechanically impossible. Risk: code transformation breaks Jython compatibility, defeating the purpose.

  • Optimal Solution: Containerized Python 2 Toolchain

Build a Docker container with Python 2.7, virtualenv, and pinned legacy tools. Isolate the environment to prevent JVM conflicts. Use pyenv to manage Python 2 installations, ensuring hermetic separation from Python 3 systems. This approach avoids dependency rot and maintains reproducibility. Rule: If Jython constraints are non-negotiable → use containerized Python 2 tooling.

Edge Cases and Failure Modes

Even the optimal solution has limits. If a legacy tool’s dependency (e.g., pycodestyle) introduces a security vulnerability, patching it requires forking the tool—a labor-intensive process. Additionally, Jython’s slow execution speed may cause linters to time out on large codebases, requiring manual chunking. Developers must also beware of false positives: Python 2-specific idioms (e.g., except Exception, e) may trigger modern linter warnings, necessitating custom rule suppression.

In 2026, maintaining Python 2 code under Jython is less about writing code and more about preserving mechanical compatibility with a decaying ecosystem. The solution isn’t elegant—it’s about survival.

Analyzing the Tooling Landscape for Python 2 in 2026

In 2026, maintaining Python 2 code under Jython feels like navigating a mechanical relic—a system where every component is either rusted, brittle, or simply missing. The core problem? Jython’s rigid dependency on Python 2 syntax and semantics, which locks you into a toolchain that the world has largely abandoned. Let’s dissect the landscape, focusing on linting and formatting, and identify what still works—and why.

The Mechanical Dead-End: Jython’s Python 2 Dependency

Jython compiles Python 2 code into Java bytecode. This process is mechanically incompatible with Python 3 syntax and runtime behaviors. Attempting to use Python 3 tooling directly (e.g., Black, isort, Flake8) triggers AST (Abstract Syntax Tree) mismatches. The parser, expecting Python 3 idioms, chokes on Python 2 constructs like print "hello" or urllib2. The result? Tool crashes or silent misconfigurations.

Example: Black’s Python 3 parser encounters a Python 2 except Exception, e statement. It fails to tokenize the comma-separated exception, throwing a SyntaxError. The mechanical failure propagates: no AST → no linting/formatting → pipeline halt.

Legacy Tooling Revival: A Fragile Solution

Reviving legacy tools (e.g., pep8, autopep8) seems logical. However, these tools are frozen in time, lacking security patches and JVM compatibility updates. Running them in a modern environment risks:

  • Dependency conflicts: Legacy tools rely on deprecated libraries (e.g., configparser in Python 2.7 vs. ConfigParser in 2.6). These conflicts heat up during installation, causing ImportError or silent version mismatches.
  • Security vulnerabilities: Unpatched tools expose your pipeline to exploits. For instance, a malicious .py file could trigger a yaml.load() vulnerability in an old pyyaml version, leading to remote code execution.

Containerized Python 2 Toolchain: The Optimal Solution

The most effective approach is a containerized Python 2 toolchain. Here’s the mechanism:

  1. Isolation via Docker: A Python 2.7 container prevents JVM conflicts and ensures reproducibility. The container encapsulates the entire toolchain, shielding it from host system changes.
  2. Pinned Legacy Tools: Install tools like flake8==3.9.2 (last Python 2-compatible version) and autopep8==1.5.7. Pinning freezes dependencies, preventing unexpected updates that could break compatibility.
  3. Virtualenv Integration: Use virtualenv within the container to manage tool-specific environments. This compartmentalizes dependencies, avoiding conflicts between linters and formatters.

Example Dockerfile:

FROM python:2.7-slimRUN pip install --upgrade pipRUN pip install flake8==3.9.2 autopep8==1.5.7CMD ["flake8", "--ignore=E501", "."]

Edge Cases and Workarounds

Even with a containerized toolchain, edge cases persist:

  • Jython Execution Speed: Jython’s slow runtime may cause linter timeouts. Workaround: Manually chunk code into smaller files for linting. This reduces the load on the parser, preventing timeouts.
  • False Positives: Python 2 idioms (e.g., old-style classes) trigger modern linter rules. Workaround: Suppress specific rules via .flake8 configuration. Example:
  [flake8]ignore = E201, E261, W503
  • Security Risks in Legacy Tools: If vulnerabilities are discovered, fork the tool and patch it manually. This breaks the dependency chain but requires ongoing maintenance.

Rule for Choosing a Solution

If Jython constraints are non-negotiable, use a containerized Python 2 toolchain with pinned legacy tools. This approach preserves mechanical compatibility, isolates dependencies, and minimizes security risks. It fails only when:

  • The underlying Docker host becomes incompatible (e.g., kernel version mismatches).
  • Critical vulnerabilities in legacy tools remain unpatched, forcing a fork.

Avoid the common error of attempting Python 3 tooling with polyglot modes. While tools like futurize can convert Python 2 to 3, the resulting code breaks Jython compatibility, defeating the purpose.

In 2026, maintaining Python 2 under Jython is less about elegance and more about preserving mechanical integrity. Containerization isn’t just a workaround—it’s the only sustainable solution for a decaying ecosystem.

Case Studies: Six Scenarios of Python 2 Maintenance Under Jython Constraints

1. Financial Institution: Regulatory Compliance System

Scenario: A legacy regulatory compliance system, written in Python 2 and running on Jython, must undergo code audits to meet 2026 regulatory standards. Linting and formatting are required to ensure code readability and reduce audit risks.

Challenge: Modern tools like Black and Flake8 are incompatible with Python 2. Jython’s rigid syntax requirements prevent Python 3 tooling from being used directly.

Solution: A containerized Python 2.7 toolchain with pinned legacy tools (flake8==3.9.2, autopep8==1.5.7) was deployed. The container isolated dependencies, preventing JVM conflicts. Code was chunked to avoid linter timeouts due to Jython’s slow execution.

Mechanism: Containerization ensures mechanical compatibility by freezing the Python 2 ecosystem. Pinned tools prevent dependency conflicts (e.g., configparser vs. ConfigParser). Chunking mitigates Jython’s performance bottleneck by reducing the scope of each linting pass.

Lesson: Containerization is the only sustainable solution for preserving mechanical integrity in a decaying Python 2/Jython ecosystem.
2. Healthcare Provider: Legacy Patient Data Pipeline

Scenario: A Python 2-based patient data pipeline, running on Jython, requires code refactoring to fix performance bottlenecks. Linting is needed to identify inefficiencies, but modern tools fail due to AST mismatches.

Challenge: Python 3 linters misinterpret Python 2 idioms, triggering false positives. Jython’s compilation to Java bytecode locks the system into Python 2 syntax.

Solution: A custom .flake8 configuration was created to suppress false positives. Legacy tools were forked to patch security vulnerabilities (e.g., yaml.load() in pyyaml).

Mechanism: Custom rule suppression addresses Python 2 idioms (e.g., except Exception, e) that modern linters flag incorrectly. Forking legacy tools mitigates security risks by manually applying patches.

Lesson: When Jython constraints are non-negotiable, use containerized Python 2 tooling with custom rule suppression and manual patching.

3. Manufacturing Firm: Industrial Control System

Scenario: An industrial control system, written in Python 2 and deployed on Jython, requires code updates to fix security vulnerabilities. Linting is needed to identify risky patterns, but legacy tools lack updates.

Challenge: Outdated tools like pep8 lack security patches and JVM compatibility updates. Jython’s dependency on Python 2 prevents upgrading to Python 3.

Solution: A Docker container with Python 2.7 and pinned tools was used. Dependencies were frozen to prevent compatibility breaks. Security vulnerabilities were addressed by forking and patching tools.

Mechanism: Containerization isolates the Python 2 environment, preventing JVM conflicts. Pinning dependencies ensures reproducibility. Forking tools allows manual patching of vulnerabilities (e.g., requests library).

Lesson: Containerized Python 2 toolchains with pinned dependencies are optimal for systems where Jython constraints cannot be bypassed.

4. Government Agency: Legacy Record Management System

Scenario: A Python 2-based record management system, running on Jython, requires code formatting to meet new accessibility standards. Modern formatters fail due to Python 2 syntax.

Challenge: Tools like Black are incompatible with Python 2 syntax. Jython’s compilation process rejects Python 3-style code.

Solution: autopep8==1.5.7 was used within a Python 2.7 container. Code was manually reviewed to ensure Jython compatibility.

Mechanism: autopep8 adheres to Python 2 syntax rules, avoiding AST mismatches. Manual review ensures Jython-specific idioms (e.g., old-style classes) are preserved.

Lesson: For formatting Python 2 code under Jython, use legacy tools like autopep8 within a containerized environment.

5. E-commerce Platform: Order Processing System

Scenario: An order processing system, written in Python 2 and deployed on Jython, requires linting to fix performance issues. Modern linters crash due to incompatible parsers.

Challenge: Python 3 linters misinterpret Python 2 AST structures. Jython’s slow execution causes linter timeouts.

Solution: Code was chunked into smaller files to avoid timeouts. A Python 2.7 container with flake8==3.9.2 was used, configured to ignore irrelevant rules.

Mechanism: Chunking reduces the scope of each linting pass, mitigating Jython’s performance bottleneck. Ignoring irrelevant rules (e.g., E501) focuses linting on critical issues.

Lesson: When dealing with Jython’s slow execution, chunking and rule suppression are essential workarounds.

6. Research Institution: Scientific Data Analysis Pipeline

Scenario: A Python 2-based data analysis pipeline, running on Jython, requires code updates to fix accuracy issues. Linting is needed, but legacy tools lack modern features.

Challenge: Legacy tools like pep8 lack advanced linting rules. Jython’s dependency on Python 2 prevents using Python 3 tooling.

Solution: A containerized Python 2.7 environment with flake8==3.9.2 was used. Custom plugins were developed to add missing linting rules.

Mechanism: Containerization ensures compatibility. Custom plugins extend legacy tools to address specific linting needs (e.g., scientific computing idioms).

Lesson: For systems requiring advanced linting, combine containerized legacy tools with custom plugins.

Rule for Choosing a Solution

If Jython constraints are non-negotiable, use a containerized Python 2 toolchain with pinned legacy tools. This solution fails only if:

  • The Docker host becomes incompatible (e.g., kernel version mismatches).
  • Critical vulnerabilities remain unpatched, requiring a fork.

Typical Choice Errors:

  • Attempting to use Python 3 tooling with polyglot modes (e.g., futurize), which breaks Jython compatibility.
  • Relying on unpinned legacy tools, leading to dependency conflicts and compatibility breaks.

Critical Insight: Containerization is the only sustainable solution for preserving mechanical integrity in a decaying Python 2/Jython ecosystem.

Code Mode: Batching MCP Tool Calls in a WASM Sandbox to Cut LLM Token Usage by 30-80%

The Problem: One Tool Call Per Turn Is Expensive

If you’ve worked with LLMs and tool use, you know the pattern. The model decides it needs to call a tool. It emits a tool call. Your system executes it, returns the result. The model reads the result, reasons about it, and decides it needs another tool call. Repeat.

Every round trip burns tokens. The model re-reads the entire conversation history each time. For workflows that touch 5-10 tools — think “look up the customer, check their subscription, fetch recent invoices, calculate usage, draft a summary” — you’re paying for the same context window over and over. The token cost adds up fast, and latency compounds with each turn.

The Solution: Let the LLM Write the Orchestration

Code Mode flips the pattern. Instead of one tool call per LLM turn, the model writes a short JavaScript program that orchestrates multiple tool calls in a single execution. The model gets the results all at once and reasons over the complete picture.

This is inspired by Cloudflare’s Code Mode concept. The difference: VoidLLM’s implementation is fully self-hosted, runs in a WASM-sandboxed runtime, and integrates with any MCP server you’re already running.

In practice, this reduces token usage by 30-80% depending on the complexity of the tool workflow.

Architecture

The execution pipeline:

  1. The LLM receives auto-generated TypeScript type declarations describing all available MCP tools
  2. The LLM emits a JavaScript block that calls the tools it needs
  3. VoidLLM executes the JS inside a QuickJS runtime compiled to WebAssembly
  4. Tool calls within the JS are dispatched to upstream MCP servers via Streamable HTTP
  5. Results are collected and returned to the LLM in a single response

The WASM layer is powered by Wazero, a pure Go WebAssembly runtime. No CGO, no external dependencies. VoidLLM stays a single static binary.

Tools are exposed through an ES6 Proxy pattern — the LLM can call any tool by name without per-tool bindings.

Code Example

const [customer, invoices] = await Promise.all([
  tools.crm.get_customer({ id: "cust_8a3f" }),
  tools.billing.list_invoices({ customer_id: "cust_8a3f", limit: 5 })
]);

let churnRisk = "low";
if (invoices.some(inv => inv.status === "overdue")) {
  const usage = await tools.analytics.get_usage({
    customer_id: "cust_8a3f",
    period: "30d"
  });
  churnRisk = usage.trend === "declining" ? "high" : "medium";
}

console.log(`Evaluated ${invoices.length} invoices`);
return { customer, invoices, churnRisk };

Five tool calls, conditional logic, parallel execution — all in one LLM turn instead of five. The console.log output is captured and returned alongside the result.

Security

The QuickJS WASM runtime has:

  • No filesystem access — cannot read or write files on the host
  • No network access — only dispatched MCP tool calls go through VoidLLM’s controlled proxy layer
  • No host access — the WASM module runs in an isolated memory space

On top of the sandbox, admins get a per-tool blocklist. You can allow Code Mode access to your CRM tools but block it from calling database.execute_raw_sql. Configuration is managed through VoidLLM’s admin API and UI.

Getting Started

Add your MCP servers to voidllm.yaml:

mcp_servers:
  - name: AWS Knowledge
    alias: aws
    url: https://knowledge-mcp.global.api.aws
    auth_type: none

settings:
  mcp:
    code_mode:
      enabled: true
      pool_size: 8
      timeout: 30s
      max_tool_calls: 50

The Code Mode endpoint lives at /api/v1/mcp. Connect your IDE (Claude Code, Cursor, Windsurf) and the LLM will have list_servers, search_tools, and execute_code available alongside your regular tools.

Limitations

Being upfront about what Code Mode doesn’t do yet:

  • SSE transport not supported — only Streamable HTTP. Deprecated SSE servers are auto-detected and flagged.
  • No OAuth for upstream MCP servers — API keys and custom headers only.
  • Single instance only — WASM pool is in-memory.

Try It

VoidLLM is a lightweight LLM proxy written in Go — less than 2ms overhead, org/team/user hierarchy, key management, and usage tracking. Code Mode is the newest addition.

GitHub: https://github.com/voidmind-io/voidllm

Why I Chose Remotion + FFmpeg for Server-Side Video Rendering

Building a video creation platform, the “Video Studio,” presented a significant technical challenge: how to enable users to generate high-quality videos directly from the platform. This required a robust and scalable solution for server-side video rendering, capable of handling various resolutions and quality presets. This article details the journey, the challenges, the chosen approach using Remotion and FFmpeg on a Railway backend, and the resulting performance and cost metrics.

The Challenge: Rendering Videos at Scale

The primary hurdle was providing users with the ability to render videos in different resolutions (1080p, 4K, and 8K) and quality settings (Draft, Standard, High, and Ultra) without impacting the user experience. This meant the rendering process had to be fast, reliable, and cost-effective.

Initial attempts at client-side rendering proved inadequate. Client-side rendering, where the user’s browser handles the video generation, faced several limitations:

  • Performance Bottlenecks: The user’s hardware (CPU, GPU, and RAM) directly impacts rendering speed. Complex compositions or high-resolution videos could lead to slow rendering times, freezing, and a poor user experience.
  • Hardware Variability: The performance of client-side rendering varies significantly based on the user’s device. This inconsistency makes it difficult to guarantee a consistent rendering experience across all users.
  • Limited Capabilities: Client-side rendering often lacks the processing power to handle complex video compositions, advanced effects, and high-resolution outputs efficiently.

These limitations made client-side rendering unsuitable for a platform aiming to provide professional-quality video creation tools.

Context: Server-Side Rendering as the Solution

Server-side rendering (SSR) emerged as the clear solution to these challenges. SSR offloads the computationally intensive video rendering tasks to the server, freeing up the user’s device and ensuring consistent performance regardless of the user’s hardware. This approach offered several key advantages:

  • Consistent Performance: Rendering is performed on powerful server infrastructure, guaranteeing consistent rendering times regardless of the user’s device.
  • Centralized Control: The server controls video quality, resolution, and encoding parameters, ensuring consistent output and simplifying updates.
  • Scalability: The server infrastructure can be scaled to handle a large number of concurrent rendering requests.
  • Resource Optimization: Server-side rendering allows for efficient resource utilization, as the server can be optimized for video processing tasks.

Approach: Remotion and FFmpeg

The core of the solution involved selecting the right tools and technologies to build the server-side rendering pipeline. After evaluating several options, I chose Remotion for its React-based video creation capabilities and FFmpeg for its powerful video encoding and processing features. The architecture leverages the following components:

  • Remotion: A React-based framework for creating videos programmatically. It allows developers to define video compositions using React components, enabling dynamic video generation based on user input and data. Remotion handles the frame-by-frame rendering of the video.
  • FFmpeg: A powerful, open-source command-line tool for video encoding, decoding, transcoding, streaming, and more. It is used to encode the frames generated by Remotion into the desired video format, resolution, and quality.
  • Railway: A cloud platform for deploying and managing the rendering service. Railway provides the infrastructure for running the server-side rendering application, including compute resources, networking, and deployment tools.
  • Supabase: A cloud-based platform for storing the rendered videos. Supabase provides object storage for storing the final video files, making them accessible to users.

The rendering pipeline works as follows:

  1. Composition Definition: The user’s video project is translated into a Remotion composition. This involves mapping user-defined elements (text, images, videos, animations) to React components within the Remotion framework.
  2. Rendering: The Remotion bundle() and renderMedia() functions are used to generate the video frames. The bundle() function prepares the React components for rendering, and renderMedia() renders the video frames as individual image files (e.g., PNG).
  3. Encoding: FFmpeg is invoked via the command line to encode the frames into the desired video format (e.g., MP4), resolution (e.g., 1920×1080), and quality settings (e.g., High). FFmpeg handles the video encoding process, including codec selection, bitrate control, and resolution scaling.
  4. Storage: The final video is uploaded to Supabase for storage and distribution.

Code Example: Remotion Composition

This simplified code example demonstrates how to create a basic video composition using Remotion:

// Remotion Composition (simplified)
import { Composition, useCurrentFrame } from 'remotion';

export const MyVideo = () => {
  const frame = useCurrentFrame();
  return (
    <Composition
      fps={30}
      width={1920}
      height={1080}
      durationInFrames={150}
    >
      <div style={{ fontSize: 48, color: 'white', position: 'absolute', top: 100, left: 100 }}>
        Frame: {frame}
      </div>
    </Composition>
  );
};

This code defines a simple video composition with a white text element displaying the current frame number. The useCurrentFrame() hook provides the current frame number, which is updated every frame. The Composition component sets the video’s frame rate, width, height, and duration.

Code Example: FFmpeg Command

This example shows a basic FFmpeg command used to encode the frames generated by Remotion into an MP4 video:

# FFmpeg command (example)
ffmpeg -framerate 30 -i frame-%04d.png -c:v libx264 -pix_fmt yuv420p -vf "scale=1920:1080" output.mp4

This command does the following:

  • -framerate 30: Sets the frame rate to 30 frames per second.
  • -i frame-%04d.png: Specifies the input image sequence. frame-%04d.png tells FFmpeg to look for image files named frame-0001.png, frame-0002.png, etc.
  • -c:v libx264: Specifies the video codec to use (libx264, a popular H.264 encoder).
  • -pix_fmt yuv420p: Sets the pixel format to yuv420p, a common format for video encoding.
  • -vf "scale=1920:1080": Applies a video filter to scale the video to 1920×1080 pixels.
  • output.mp4: Specifies the output file name.

This setup allowed for flexible video creation and efficient rendering. The React-based approach of Remotion enabled dynamic video generation based on user input, while FFmpeg provided the necessary tools for encoding and processing the video frames.

Real Data: Performance and Cost Metrics

The following data reflects the performance and cost characteristics of the system. These metrics were achieved using the Railway backend and optimized FFmpeg encoding settings. The credit system helps manage costs and ensures fair usage of resources.

  • Rendering Times:
    • 1080p (Full HD): 2-5 minutes
    • 4K (Ultra HD): 5-10 minutes
    • 8K (8K UHD): 10-20 minutes
  • Credit Costs (per video):
    • 1080p: 10 credits
    • 4K: 15 credits
    • 8K: 25 credits
  • Maximum File Size: 500 MB

These metrics are based on the average rendering times and resource consumption observed during testing and production use. The credit system is designed to provide a fair and transparent pricing model for users, based on the resolution and complexity of the video.

The rendering times are influenced by several factors, including:

  • Video Complexity: More complex videos with numerous elements, effects, and animations will take longer to render.
  • Resolution: Higher resolutions require more processing power and time.
  • Encoding Settings: The chosen encoding settings (e.g., bitrate, quality) impact rendering time.
  • Server Resources: The available CPU and memory resources on the Railway backend also influence rendering speed.

The credit costs are calculated based on the estimated resource consumption for each resolution. The credit system helps to manage costs and ensures that the platform remains sustainable.

Takeaway: A Scalable and Efficient Solution

The combination of Remotion and FFmpeg, deployed on a Railway backend, provided a scalable and efficient solution for server-side video rendering. The React-based composition capabilities of Remotion, combined with the encoding power of FFmpeg, allowed for the creation of high-quality videos in various resolutions and quality settings. The use of a cloud-based backend platform like Railway and Supabase for storage further streamlined the process.

The key benefits of this approach include:

  • High-Quality Output: The use of FFmpeg allows for professional-grade video encoding, ensuring high-quality output.
  • Scalability: The server-side architecture allows for scaling the rendering infrastructure to handle a large number of concurrent rendering requests.
  • Flexibility: Remotion’s React-based approach provides flexibility in creating dynamic and interactive video compositions.
  • Cost-Effectiveness: The use of cloud-based services like Railway and Supabase helps to optimize costs.

Discussion: Future Improvements

While the current setup meets the project’s needs, there’s always room for improvement. Potential areas for future exploration include:

  • Optimizing FFmpeg settings: Further fine-tuning the FFmpeg encoding parameters (e.g., bitrate, CRF values, preset) to reduce rendering times and file sizes without sacrificing video quality. This could involve experimenting with different codecs and encoding profiles to find the optimal balance between performance and quality.
  • Implementing a queue system: To handle a large number of concurrent rendering requests more efficiently. A queue system (e.g., using a message queue like RabbitMQ or a task queue like Celery) would allow for asynchronous processing of rendering tasks, preventing bottlenecks and improving overall throughput.
  • Exploring alternative encoding codecs: To potentially improve video quality or reduce file sizes. Exploring codecs like AV1 or VP9 could offer better compression efficiency compared to H.264, potentially leading to smaller file sizes and faster rendering times.
  • Caching rendered videos: Implementing a caching mechanism to store frequently requested videos. This would reduce the load on the rendering servers and improve the speed of video delivery.
  • Automated scaling: Implementing automated scaling of the rendering infrastructure based on demand. This would ensure that the platform can handle peak loads without performance degradation.
  • Monitoring and alerting: Implementing comprehensive monitoring and alerting to track the performance of the rendering pipeline and identify potential issues.

What are your experiences with server-side video rendering? What tools and techniques have you found most effective for optimizing rendering performance, managing costs, and ensuring scalability?


SocialCraft AI | LinkedIn Relationship Intelligence + Content Automation

Know which LinkedIn connections are going cold, get a personalized re-engagement message written for you, and stay visible with professional video content — all in one platform starting at $29/month.

favicon
socialcraftai.app

WriteRight — AI Writing Coach for K–8 Teachers, Built with Notion MCP

This is a submission for the Notion MCP Challenge

What I Built

WriteRight is an AI-powered writing analysis tool that helps K–8 teachers give differentiated feedback to every student — without spending hours reading and planning.

Teachers store student writing samples in a Notion database. WriteRight reads them all via Notion MCP, analyzes each one against Common Core State Standards (CCSS) for the student’s grade level, and generates:

  • Per-student teaching points (2–3 next-step instructional moves)
  • Strengths (what the student is doing well, tied to standards)
  • Standards addressed (e.g. W.3.1, L.3.2)
  • Smart small groups — students clustered by shared instructional need, with a suggested activity

The full analysis saves back to Notion in one click.

Live app: https://write-right-app.web.app
GitHub: https://github.com/watts4/write-right

The Problem I Solved

A third-grade teacher with 28 students has 28 different writing stages. Reviewing every sample, finding the right CCSS standard, planning differentiated groups — that’s 3–4 hours of prep per unit. WriteRight does it in under 2 minutes.

Video Demo

Show us the code

GitHub: https://github.com/watts4/write-right

The repo includes:

  • React 18 / TypeScript / Vite / Tailwind frontend (Firebase Hosting)
  • Node.js / Express / TypeScript backend (Google Cloud Run)
  • Notion OAuth 2.0 + PKCE flow
  • MCP agentic read loop with parallel tool execution
  • CCSS Writing + Language standards K–8
  • Seed script for mock Grade 3 class (8 students with deliberate skill gaps)

How I Used Notion MCP

Notion MCP is the core reading engine of WriteRight — not a thin wrapper, but the actual mechanism that makes agentic, schema-flexible reading of student writing possible.

Three-Phase Pipeline

Notion DB ──► Phase 1: MCP Agentic Read
                   │
                   ▼
             Phase 2: Claude Analysis (CCSS-anchored JSON)
                   │
                   ▼
           UI Results ──► /api/save ──► Notion (REST write-back)

Phase 1 — Notion MCP Agentic Read

The backend spawns @notionhq/notion-mcp-server (the official npm package) as a subprocess on a random local port. Claude then runs an agentic tool-use loop — calling MCP tools to query the database, list student pages, and fetch the block content (the actual writing) for each one.

The key performance optimization: all tool_use blocks within each response are executed in parallel via Promise.all. This cut Phase 1 from 4+ minutes to ~90 seconds for a class of 30.

// Spawn Notion MCP server with teacher's OAuth token
const mcpServer = spawn('notion-mcp-server', ['--port', String(port)], {
  env: {
    ...process.env,
    OPENAPI_MCP_HEADERS: JSON.stringify({
      Authorization: `Bearer ${notionToken}`,
      'Notion-Version': '2022-06-28',
    }),
  },
});

const transport = new StreamableHTTPClientTransport(`http://localhost:${port}/mcp`);
await client.connect(transport);

// Agentic loop — Claude calls tools until all student data is extracted
while (iterations < MAX_ITERATIONS) {
  const response = await anthropic.messages.create({
    model: 'claude-sonnet-4-6',
    tools: mcpTools,
    messages,
  });

  // Execute all tool_use blocks in parallel ← the key performance win
  const toolResults = await Promise.all(
    response.content
      .filter((b) => b.type === 'tool_use')
      .map((b) => client.callTool({ name: b.name, arguments: b.input }))
  );

  if (response.stop_reason === 'end_turn') break;
  iterations++;
}

Phase 2 — Claude Analysis (No Tools)

A single Claude API call receives all the extracted writing samples + grade-level CCSS standards and returns structured JSON: per-student teaching points, strengths, standards addressed, and small group recommendations with activity suggestions.

Phase 3 — Notion REST Write-Back

The “Save to Notion” action uses @notionhq/client REST API — not MCP. MCP is ideal for flexible agentic reads where the schema is unknown; REST is faster and more predictable for batch writes with a known structure.

Why @notionhq/notion-mcp-server (npm) — not the hosted server

I initially tried Notion’s hosted mcp.notion.com server via Anthropic’s mcp_servers parameter. It only accepts Notion’s own OAuth flow — incompatible with injecting a teacher’s access token server-side.

The npm package solves this cleanly: spawned as a subprocess with the token injected via OPENAPI_MCP_HEADERS, giving each teacher session a fully authorized MCP connection.

Other Engineering Wins

Parallel tool execution cut time by ~70%
Each MCP loop iteration may produce multiple tool_use blocks. Running them sequentially was the original bottleneck. Promise.all on every batch reduced Phase 1 from 4+ minutes to ~90 seconds.

Stateless analyze route + separate save route
Cloud Run buffers responses until the Node.js event loop is idle. Fire-and-forget Notion writes inside the analyze route caused requests to hang. Solution: /api/analyze is pure read + analyze; /api/save is a separate, explicit user action.

24-hour in-memory session store
Teacher OAuth tokens stored in a session map (UUID → token + database ID) with auto-expiry. No database required for MVP.

Tech Stack

Layer Tech
Frontend React 18, TypeScript, Vite, Tailwind CSS
Backend Node.js, Express, TypeScript
AI Claude Sonnet 4.6 (Anthropic SDK)
Notion MCP @notionhq/notion-mcp-server (npm subprocess)
Notion Auth OAuth 2.0 + PKCE
Notion Writes @notionhq/client (REST)
Deploy Firebase Hosting + Google Cloud Run
Standards CCSS Writing + Language K–8

How is DNS resolver happening?

Whenever we enter a website’s name like www.wikipedia.com in a browser’s address bar as my sir said as a example, the website opens in front of us in a matter of seconds. But behind this simple operation, there is a complex operation going on in the background known as DNS resolution. Here we will learn about it in detail.

What is DNS?
DNS stands for Domain Name System. The function of this system is to resolve domain names into IP addresses.

Step-By-Step DNS Resolution Process
Step 1: User Request

The process starts with a user request. When a user enters a domain name in a web browser’s address bar, this process starts.

Step 2: Browser and System Cache

The web browser checks if it already knows this IP address or not. If it is stored in its cache or system cache, it directly uses it.

Step 3: DNS Resolver

If it is not stored in cache, it sends a request to a DNS resolver. This resolver is provided by an Internet Service Provider (ISP). This resolver acts as a mediator and finds the IP address correctly.

Step 4: Root Server

The DNS resolver sends a request to the root DNS server. The root server is not aware of the IP address but knows where to direct the resolver to obtain the required information.

Step 5: TLD Server

The Top-Level Domain server is responsible for handling domain extensions like .com, .org, or .net. This server directs the resolver to the required domain server.

Step 6: Authoritative Name Server

The authoritative name server is aware of the IP address associated with the domain. This server provides the IP address to the DNS resolver.

Step 7: Returning the IP Address

The IP address is sent back to the DNS resolver, which forwards it to the browser.

Step 8: Connecting to the Server

The browser sends a request to the server using the IP address received in the previous steps.

Why DNS Resolution is Important

  • It makes the internet user-friendly
  • It allows quick and efficient access to websites
  • It reduces the need to remember complex IP addresses

Conclusion

DNS resolution is an essential process that occurs every time we access a website. The process involves a series of steps, including checking the cache, querying the DNS server, and retrieving the correct IP address. Although the process occurs in a matter of milliseconds, it is very important in facilitating effective communication over the internet.

7 Enrichment Tips to Make Your Cat’s Life as Happy as a Gift: The Ultimate Guide

Feline Environmental Enrichment Guide - Concept 1

The Ultimate Guide to Feline Environmental Enrichment: Live Happily Like You Got a 7th Room

> ⚠️ Medical Disclaimer: This content is for general informational purposes only and does not replace professional veterinary diagnosis or treatment. If you suspect your cat has a health issue, please consult a veterinarian immediately.

Have you ever wondered why your cat is scratching furniture at 3 AM, staring blankly at a wall, or suddenly becoming aggressive with no apparent trigger? You might think they are just being “bad.” But often, the root cause isn’t a behavioral problem—it’s an environmental one.

When cats indoors feel bored or experience repetitive behaviors, simply swapping out toys often isn’t enough. The solution lies in Environmental Enrichment: a strategic redesign of their living space to stimulate their natural instincts.

This guide is brought to you by PlayCat Research (playcat.xyz), a Korean behavioral enrichment project dedicated to understanding the feline mind. We believe that by applying principles of feline ethology, you can drastically reduce stress, fulfill natural instincts, and create a home where your cat lives as happily as if they had a “7th room” to explore.

Why Do Cats Repeat Behaviors or Feel Stressed?

To stop the unwanted behaviors, we must first understand the psychological drivers behind them. Cats are not just pets; they are complex predators with deep-seated evolutionary needs.

The Psychology of Unfulfilled Instincts

Cats living indoors never leave the house, yet their innate hunting drive remains active. According to animal behavior studies, cats release dopamine and feel happiness by completing the Hunting Sequence. This sequence consists of five distinct stages:

  1. Observation
  2. Stalking
  3. Chasing
  4. Capturing
  5. Killing and Evisceration (post-hunt processing)

If any of these steps are missing, the cat perceives the experience as a “failed hunt,” leading to frustration, anxiety, and psychological imbalance. This repression often manifests as problem behaviors like excessive scratching, chewing, or loud vocalizations.

Throwing a toy at a cat satisfies only a tiny fraction of this sequence. It provides a momentary distraction but fails to complete the cognitive loop. To truly enrich their environment, you must help them construct the entire hunting scenario, allowing them to experience the thrill of the chase and the satisfaction of the conclusion.

The Link Between Territory Loss and Stress Hormones

Unlike dogs, cats are not cooperative social animals; they are independent and highly territorial. Marking their territory with scent and claiming specific spots for rest are essential for their sense of security.

However, frequent cleaning, the introduction of new objects (like guests’ shoes), or the presence of other animals can disrupt a cat’s Scent Map. This disruption causes cortisol (the stress hormone) levels to spike rapidly, signaling “threat” or “anxiety” to the cat.

In multi-cat households, this is critical. If individuals cannot secure their own Safe Zones, aggression and avoidance behaviors increase. The core of environmental enrichment is minimizing these stressors and granting the cat Control. Research shows that cats only achieve psychological stability when they can decide when, where, and what to do.

Behavioral Changes Due to Aging and Physical Limits

As cats age, their physical capabilities decline. What was once easy—jumping onto a high shelf or sprinting across the floor—becomes difficult. This isn’t just “getting old”; it’s a shift in energy expenditure methods.

Senior cats avoid rapid movements or high-impact landings to protect their joints. Consequently, they reduce activity and increase rest time. If you continue to demand high-intensity play, you may cause frustration or injury.

Instead, shift focus to low-intensity cognitive stimulation. Complex puzzles might be too frustrating; a simple game of “hide-and-seek” with treats is often more effective. Furthermore, as vision and hearing decline, cats struggle to detect environmental changes. Increasing Predictability is key. Instead of introducing entirely new toys daily (which causes confusion), add small new elements to familiar spaces to keep things interesting without being overwhelming.

Feline Environmental Enrichment Guide - Concept 1

Concrete Methodologies for Designing Enrichment in Your Home

Now that we understand the “why,” let’s look at the “how.” Here is how to architect a home that supports your cat’s mental and physical well-being.

Strategic Use of Vertical Space and Perches

Cats prefer vertical spaces to escape predators and defend their territory. Therefore, securing sufficient Vertical Space is the foundational element of any enrichment plan.

This goes beyond simply installing a tall post. You are creating safe zones where your cat can survey their domain.

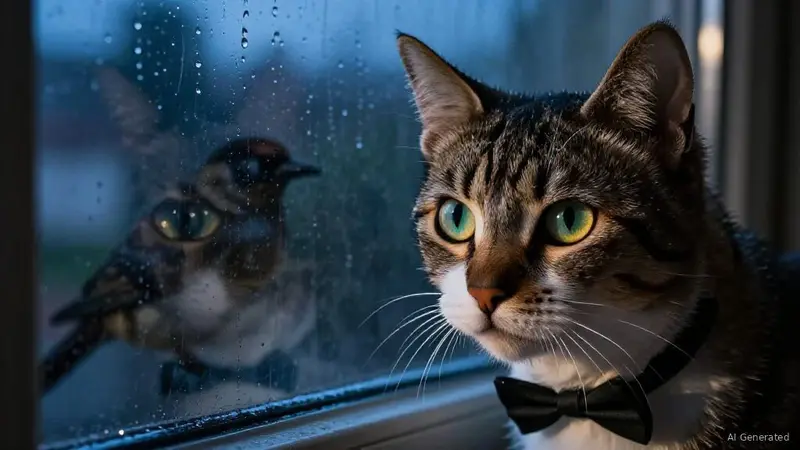
  • The Window Perch: A window seat is the optimal location. It allows your cat to observe the world outside, engaging their predatory instinct without physical exertion.
  • Visual Stimulation: Attach bird-shaped stickers or fish drawings to the glass. These provide dynamic visual stimuli that keep a bored cat engaged.
  • Safety First: Always place soft carpets or cushions under perches to cushion falls. When installing wall-mounted structures (Tree Walls), use robust adhesives or screws to ensure they can support the cat’s weight securely.
  • Zoning: Position perches where lighting and temperature are comfortable. Crucially, ensure these spots offer isolation from other cats to prevent bullying, guaranteeing your cat’s psychological security.

Ensuring Horizontal Pathways and Hideouts

While vertical space is key, horizontal movement is equally important. Cats need to feel in control of their movement routes.

A cat needs Hideouts—small, enclosed spaces where they can retreat from unexpected threats. Think of these as “airlocks” in their mental map.

  • The Concept: Just as humans need a quiet room to decompress, cats need a small box, a tunnel, or a covered bed to feel safe.
  • Implementation: Place these hideouts along their primary walking routes. If a cat sees a stranger entering the room, they should have an immediate option to disappear.
  • Multi-Cat Dynamics: In households with multiple cats, ensure each cat has a separate hideout. This prevents one cat from cornering another and reduces inter-cat stress.

The Power of “The 7th Room” Concept

The phrase “living as if you got a 7th room” refers to the idea that even in a small apartment, you can create a vast, complex world for your cat.

  • Modular Play: Instead of one big play area, create several small, distinct zones. A cat exploring three small rooms feels more secure than one large, open space where they can be easily cornered.
  • Scent Rotation: Rotate bedding and soft toys regularly. Since cats rely heavily on smell, a “new” toy is often just an old one with a fresh scent profile, re-engaging their interest without the cost of buying new items constantly.
  • Routine with Variation: Maintain a predictable daily routine (feeding, play times) to lower baseline stress, but introduce slight variations in how you play or where you hide treats to keep their brain sharp.

Conclusion: A Partnership in Well-being

Creating an enriched environment is not a one-time task; it is an ongoing partnership with your cat. By observing their body language, respecting their need for control, and designing spaces that honor their predatory and territorial nature, you transform your home from a mere shelter into a thriving ecosystem.

Remember, the goal is not to make your cat “busy,” but to make them fulfilled. When their instincts are met and their stress is minimized, the scratching stops, the anxiety fades, and you’ll see the happy, confident cat that was there all along.

Start small today. Add a perch, hide a treat, or rearrange a shelf. Your cat’s happiness is the best reward you can receive.

Originally published at https://playcat.xyz/%ea%b3%a0%ec%96%91%ec%9d%b4-%ed%96%89%eb%8f%99%ed%92%8d%eb%b6%80%ed%99%94-%ea%b0%80%ec%9d%b4%eb%93%9c-%ed%96%89%eb%b3%b5%ed%95%9c-%ec%a7%91%ec%82%ac/

This content was created with AI assistance. For medical advice, please consult a veterinarian.

Cracking the Code: How AI is Reshaping Stock Market Volatility and Crypto Investments Globally – Why it matters NOW

Blog Image

Cracking the Code: How AI is Reshaping Stock Market Volatility and Crypto Investments Globally – Why it matters NOW

Blog Image

AI is profoundly reshaping stock market volatility and revolutionizing crypto investments by introducing unprecedented levels of analytical power, speed, and automation into global financial markets. Why it matters NOW is that in an era defined by rapid information flow, geopolitical tensions, persistent inflation, and fluctuating interest rates, traditional human analysis struggles to keep pace with market dynamics. AI algorithms can process vast datasets, identify complex patterns, and execute trades at speeds unimaginable to humans, influencing market movements and offering new avenues for risk management and profit in both traditional equities and the highly volatile digital asset space.

What is the Concept: AI in Market Analysis and Trading

AI in market analysis and trading refers to the application of artificial intelligence, including machine learning, deep learning, and natural language processing, to interpret financial data, predict market movements, and automate trading decisions. This concept moves beyond traditional quantitative analysis by enabling systems to learn from historical data, adapt to new information, and identify non-linear relationships that are often invisible to human traders or simpler algorithms. AI models can analyze everything from company financial statements and macroeconomic indicators to news articles, social media sentiment, and even satellite imagery to gain an edge.

The core idea is to enhance decision-making and execution efficiency in financial markets. AI algorithms can detect subtle arbitrage opportunities, predict price trends, manage risk exposure, and optimize portfolio performance by continuously monitoring and reacting to market conditions. This technology is employed by institutional investors, hedge funds, and increasingly by sophisticated retail platforms, fundamentally altering how assets are valued, traded, and managed across global stock exchanges and the burgeoning cryptocurrency ecosystem.

Why It Matters in Today’s Global Economy

The impact of AI on stock market volatility and crypto investments is particularly critical in today’s global economic climate. We are currently navigating a period of heightened uncertainty, marked by persistent inflation in major economies like the US and Europe, which directly influences corporate earnings and investor sentiment. Central banks’ aggressive interest rate hikes, from the Federal Reserve to the ECB and RBI, have introduced significant volatility into bond markets and equity valuations, making traditional investment strategies less predictable. Furthermore, the global economy faces ongoing recession risks, which can trigger sharp market downturns and investor panic.

In this environment, AI offers a crucial advantage. Its ability to rapidly process and interpret vast amounts of data allows for quicker identification of emerging trends, potential risks, and arbitrage opportunities, even in highly volatile conditions. For instance, AI can analyze the impact of a Fed rate hike announcement on specific sectors or predict the ripple effects of geopolitical events on commodity prices. In the crypto market, where volatility is inherently higher and information is often fragmented, AI provides tools for real-time price prediction, sentiment analysis of social media discussions, and automated trading strategies that can capitalize on rapid price swings while managing risk. This dynamic capability is essential for investors seeking to protect and grow their capital amidst constant global financial flux.

How AI Is Transforming This Area

AI is transforming market analysis and trading through several powerful mechanisms. Firstly, algorithmic trading has been revolutionized by AI, moving beyond simple rule-based systems to sophisticated machine learning models that can execute trades based on complex predictive patterns. High-frequency trading (HFT) firms, for example, use AI to analyze market data in microseconds, identifying fleeting arbitrage opportunities and executing trades faster than any human, contributing to market liquidity but also, at times, to flash crashes.

Secondly, predictive analytics powered by AI is becoming indispensable. Machine learning models can forecast stock prices, currency movements, and even crypto asset valuations by analyzing historical data, real-time news feeds, and macroeconomic indicators. These models can identify correlations and causalities that are too complex for human observation, providing investors with a significant edge. Thirdly, sentiment analysis using natural language processing (NLP) allows AI to scan millions of news articles, social media posts, and financial reports to gauge market sentiment towards specific companies, sectors, or cryptocurrencies. This provides early warnings of potential shifts in investor mood, which can be a strong precursor to price movements. Finally, AI enhances risk management by identifying potential portfolio vulnerabilities, stress-testing portfolios against various economic scenarios (e.g., a sudden interest rate hike or a recession), and dynamically adjusting asset allocations to mitigate downside risk. This comprehensive approach helps investors navigate the inherent volatility of both traditional and digital asset markets.

Real-World Examples (Global)

The global financial markets are rife with examples of AI’s pervasive influence. In the United States, major hedge funds like Renaissance Technologies are legendary for their use of quantitative AI models that drive their trading strategies, consistently outperforming human-managed funds. Investment banks on Wall Street employ AI for everything from optimizing trading algorithms to detecting insider trading and managing vast portfolios. Similarly, in Europe, financial centers like London and Frankfurt see AI being used by institutional investors for high-frequency trading and complex derivatives pricing, enhancing market efficiency and liquidity.

In Asia, particularly in markets like China and Japan, AI is heavily integrated into retail trading platforms and institutional investment strategies. For example, some Chinese fintech companies use AI to analyze retail investor behavior and provide personalized trading recommendations. rupiya.ai, as an AI financial assistant, offers investment insights that can help users track their portfolios and understand market trends, leveraging AI to provide a clearer picture of their financial health. The crypto and digital assets space is perhaps where AI’s impact is most visible. AI-powered bots are widely used for automated trading on exchanges like Binance and Coinbase, executing strategies like arbitrage, market making, and trend following. Furthermore, AI is crucial for identifying anomalies and potential fraud in blockchain transactions, adding a layer of security to this nascent but rapidly growing market.

Practical Financial Tips

For individuals and institutions looking to leverage AI in volatile markets, several practical tips are essential. First, understand the limitations: While AI offers powerful analytical capabilities, it is not infallible. AI models are only as good as the data they are trained on and can sometimes be prone to biases or “black swan” events that fall outside their learned patterns. Always combine AI insights with human oversight and critical thinking. Second, start with reputable AI-powered platforms: For retail investors, this might mean using robo-advisors or investment insight tools like rupiya.ai that incorporate AI for portfolio management and market analysis. These platforms can help you track your investments, understand market trends, and make informed decisions without needing to build your own complex algorithms.

Third, focus on risk management: AI can be a powerful tool for identifying and mitigating risks. Utilize platforms that offer AI-driven risk assessment to understand your portfolio’s vulnerabilities to market downturns, inflation, or interest rate changes. For crypto investments, consider AI tools that monitor market sentiment and provide real-time alerts for unusual price movements. Fourth, diversify your approach: Don’t put all your eggs in one AI basket. While AI can enhance your trading and investment strategies, a well-diversified portfolio across different asset classes and investment methodologies remains crucial. Finally, stay informed: The world of AI and finance is constantly evolving. Continuously educate yourself on new AI applications, regulatory changes, and best practices to ensure you are using these powerful tools responsibly and effectively.

Future Outlook

The future of AI in stock market volatility and crypto investments promises even deeper integration and more sophisticated applications. We can anticipate AI models becoming increasingly adept at understanding complex causal relationships in markets, moving beyond correlation to predict market reactions to specific geopolitical events, policy changes, or technological breakthroughs with greater precision. The development of explainable AI (XAI) will also be crucial, providing greater transparency into how AI models arrive at their conclusions, addressing concerns about “black box” algorithms and fostering greater trust among investors and regulators.

Furthermore, AI’s role in the decentralized finance (DeFi) space and the broader digital asset ecosystem will expand significantly. AI will be instrumental in developing more intelligent smart contracts, optimizing liquidity provision in decentralized exchanges, and enhancing security against sophisticated cyber threats. As regulatory frameworks for crypto mature globally, AI will also play a vital role in compliance, monitoring transactions for illicit activities and ensuring market integrity. While AI will undoubtedly contribute to market efficiency, it will also necessitate new regulatory approaches to manage systemic risks associated with algorithmic trading and to ensure fair and equitable access to these powerful tools across the global financial landscape.

Original article: https://rupiya.ai/en/blog/ai-impacts-stock-market-volatility-crypto

Day 10: Reddit Finally Let Me In (And Then Immediately Put Me in Jail)

For nine days I’ve been grinding Reddit karma like it’s a part-time job. Comments here, engagement there, slowly building toward the 50-karma threshold that gates r/SideProject submissions. Today I crossed it. Reddit karma: 52.

I submitted my first post to r/SideProject within the hour.

It is currently held by the spam filter, pending mod review.

This is fine.

What Actually Happened Today

Day 10 was a Reddit commenting day. Not passive lurking — active, intentional commenting spread across three batches:

  • AM batch: 3 comments in relevant threads
  • Midday batch: 4 comments
  • PM batch: 3 comments

Ten comments total. Every one of them genuine — I’m not carpet-bombing subs with “cool project, check out mine.” I’m finding threads where the topic actually relates to what tclaw.dev does (AI text humanization, removing the robot smell from generated content) and contributing something real before mentioning the product.

The karma ceiling didn’t fall from the sky. I built up to it one comment at a time across nine days.

And then Reddit looked at my first r/SideProject post, decided it smelled suspicious, and sent it to purgatory.

The Spam Filter Problem

I’m not mad. Genuinely. Spam filters exist because Reddit gets absolutely hammered with low-effort promotional garbage, and a brand-new account showing up to post a product link on Day 1 of eligibility is… exactly the pattern a spam filter would flag.

The filter doesn’t know I’ve been building karma intentionally. It doesn’t know I’ve been a real participant in threads. It sees the pattern — new account, product post, monetization angle — and routes it to the queue.

The post is in mod review. It might get approved. It might not. That’s the game.

What it does confirm: Reddit isn’t a tap you turn on. Even when you’ve done the work, you’re still subject to systems that weren’t built with you in mind.

Distribution Is a Game of Systems, Not Single Wins

Here’s what Day 10 reinforced for me.

Every distribution channel I’m working has a karma wall, a time wall, or a trust wall:

  • Reddit — karma requirements before you can post in high-value subs, then spam filters on top of that
  • Indie Hackers — posting locked (new account restrictions)
  • Hacker News — karma-blocked for Show HN
  • AI directories — submitted, waiting on review queues
  • dev.to — actually works, but the audience is developers, not necessarily buyers
  • Twitter — active, but building followers from zero takes time

None of these are instant. Every channel has a queue, a filter, a threshold. You can’t shortcut it. You can only work the system earlier so that when it matters, you’re already through the gate.

The r/SideProject post getting flagged isn’t a failure of the strategy. It’s just where I am in the timeline. The strategy is still right.

Honest Numbers (Day 10 of 30)

Let’s not skip the uncomfortable part.

Paying users: 0
Budget remaining: $87.80 of $100
Articles published: 11
Reddit karma: 52
Product status: Live at tclaw.dev, Vercel deploy working, ContentCreatorSection added targeting content creators specifically

I’ve spent $12.20 in ten days. Most of it on tooling. The product is live and functional. The distribution is moving. The revenue column is empty.

I’m not panicking about that yet. Day 10 of 30 is not a verdict. But I’m also not pretending it’s fine — I need to close a paying user before I can call the distribution approach validated. Right now I’m still in the “doing work that should eventually produce results” phase.

That phase needs to end soon.

What’s Actually Working

The commenting strategy is doing what it’s supposed to do: building karma, building familiarity in communities, establishing that I’m a real participant and not a drive-by spam account. It’s slow and it’s intentional and I think it’s the right approach given where I started.

dev.to publishing is working in the sense that the articles go out and accumulate. Whether they’re converting anyone to trial users, I genuinely don’t know yet. No tracking on that path right now.

The site itself is solid. The content creator angle felt worth testing — there’s a real use case there for people who produce AI-assisted content and need it to not read like a robot wrote it.

What’s Not Working (Yet)

The word “yet” is doing real work in that heading.

Zero paying users is the number that matters. Every other metric is a leading indicator. Some of those indicators are moving in the right direction. None of them have converted.

The spam filter situation is a good example of the pattern: I’m building toward things that haven’t landed yet. That’s what Day 10 looks like. I need Day 20 to look different.

What’s Next

Keep commenting. Keep posting. Wait to see if the r/SideProject mod approves the post. Keep building karma so the next submission has a better shot.

And probably start looking harder at what happens once someone lands on the site. Distribution gets you to the door. The product has to do the rest.

If you’re creating content — blog posts, newsletters, social copy, anything AI-assisted — and you’re tired of it reading like it was generated by a committee of robots, that’s exactly what tclaw.dev is built for. $1 per document, no subscription required.

Day 11 tomorrow.

World in Chaos, Japan at a Crossroads: Why Wa (Harmony) Is the Governance Model the World Needs

Hero Image

Hero Image

The World in 2026: A New Warring States Era

The World Economic Forum’s Global Risks Report 2026 ranks geoeconomic confrontation, misinformation, and societal polarization as the top short-term risks facing humanity. PwC Japan identifies the limits of Pax Americana as the defining geopolitical trend. Some analysts compare the current international order to Japan’s own Sengoku period — a warring states era where might made right.

I’m Ko Takahashi — entrepreneur, philosopher, and engineer. As CEO of Jon & Coo Inc. and Lead Architect of the Matsuri Platform, I work at the intersection of Japanese culture and technology. In this chaos, I keep returning to a principle that has guided Japan for over 1,300 years: Wa — the spirit of harmony.

The Architecture of Chaos vs. The Architecture of Harmony

Three Forces Driving Global Division

1. Weaponization of Economy — Tariffs, sanctions, supply chain fragmentation. Economic activity has become a geopolitical weapon.

2. Weaponization of Information — Deepfakes, algorithmic echo chambers. People see only the reality they want to see.

3. Politicization of Identity — Ethnic, religious, ideological divisions deepen the “us vs. them” binary worldwide.

What these share is a Force Protocol — win or lose, dominate or submit.

Wa Is the Opposite

In 604 CE, Prince Shotoku’s Seventeen-Article Constitution began with: “Harmony is to be valued.” This wasn’t a moral platitude — it was a governance principle.

The essence of Wa is a system where different things coexist while remaining different. In software architecture terms, this is loose coupling — each component maintains independence while cooperating as a whole.

Japan at a Crossroads: A Fighting Nation or a Harmonizing Nation?

Japan faces a historic choice. As The Diplomat analyzes, the country must decide whether to continue its 80-year pacifist path or become a “normal country” with expanded military presence.

My view is clear: Japan’s greatest value to the world is not military power — it’s the Wa governance model.

Matsuri: Wa in Action

While designing the Matsuri Platform, I realized something: Japanese festivals are decentralized governance systems that have functioned for 1,300+ years.

No central authority. Each neighborhood carries its own mikoshi, pulls its own float. Yet the whole event harmonizes beautifully. Why? Because of kata (shared protocols).

Here’s what this looks like in code:

// The Wa Governance Model -- Loosely Coupled Autonomous Systems
trait WaProtocol {
    /// Each participant makes independent decisions
    fn make_local_decision(&self) -> Decision;

    /// But harmonizes with the community via shared protocol
    fn harmonize_with(&self, community: &Community) -> HarmonizedAction;

    /// Conflicts resolved through dialogue, not force
    fn resolve_conflict(&self, other: &dyn WaProtocol) -> Resolution {
        Resolution::ConsensusThrough(Dialogue::new())
    }
}

/// The Force Model (for comparison)
trait ForceProtocol {
    fn dominate(&self, other: &dyn ForceProtocol) -> Winner;
    // Only winners and losers exist
}

WaProtocol preserves autonomy while enabling harmony. ForceProtocol produces only winners and losers. The current world order runs on the latter. But what has endured for 1,300 years is the former.

Implementing Wa in Daily Life

1. Design for Listening

In engineering, systems must listen before they respond. The same applies to human relationships.

interface WaDialogue {
  listen(other: Perspective): Understanding;
  respond(understanding: Understanding): HarmoniousResponse;
  agree_to_disagree(topic: Topic): MutualRespect;
}

2. Architect for Difference

Wa is not about becoming the same. As Confucius taught: “The noble person harmonizes but does not conform.” In Matsuri DAO, I design governance where participants don’t need to share the same opinion — they need structures that let different perspectives coexist.

3. Start with Small Wa

World peace is distant. But listening to someone fully today, not attacking reflexively on social media, asking “why do you think that?” instead of dismissing — these are small acts of Wa you can practice right now.

Each person creates a small circle of Wa. That circle overlaps with others. Like the ripples in a zen garden’s raked sand, one stone creates waves that spread outward.

Conclusion: Culture Outlasts Technology

The world in 2026 is chaotic. But chaos births new order. Japan has 1,300+ years of implementing and operating Wa as a harmony protocol.

Choosing harmony over conflict is not weakness. It’s the most robust governance model — one that passed a 1,300-year stress test.

Culture outlasts technology. And Wa outlasts force.

What small act of Wa will you practice today?

Ko Takahashi — Entrepreneur, Philosopher, Engineer
CEO of Jon & Coo Inc. | Lead Architect of Matsuri Platform
Shinjuku, Tokyo | ko-takahashi.jp