Xbox’ta bu hafta sonu üç oyun ücretsiz: 3.000TL değerinde
 Xbox Game Pass kullanıcıları için ücretsiz oyun günleri başladı. Warhammer Space Marine dahil 3.000TL değerinde 5 oyun hafta sonu boyunca ücretsiz erişilebilir olacak…
 Xbox Game Pass kullanıcıları için ücretsiz oyun günleri başladı. Warhammer Space Marine dahil 3.000TL değerinde 5 oyun hafta sonu boyunca ücretsiz erişilebilir olacak…
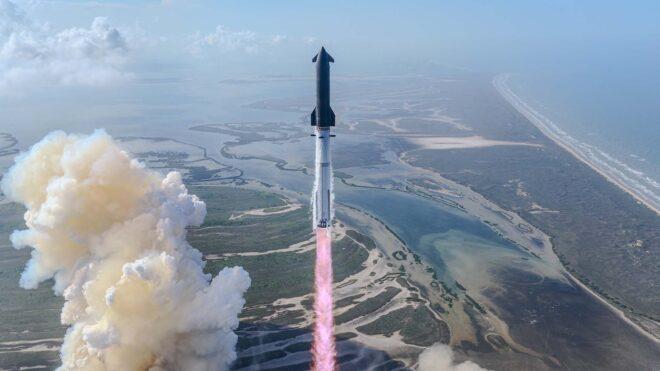
 Elon Musk’ın başarılı özel uzay şirketi SpaceX, bu sefer geçtiğimiz saatlerde gerçekleştirilen Starship V3 denemesiyle dikkat çekti. Dünyanın en güçlü roketinin son sürümü için yapılan ilk denemeyi, uzaydan internet sunan Starlink’ten güç alınan altyapıyla kayıt altına alan SpaceX, resmi X hesabından hem dışta hem de roketin üstünde çekilen nefes kesici videolar paylaştı. Deneme kapsamında yörüngeye test amaçlı Starlink uyduları bırakan şirket, Starship’i gerçek ticari görevlere hazırlamaya devam ediyor. Liftoff of Starship! pic.twitter.com/LQLdjK5V6K — SpaceX (@SpaceX) May 22, 2026 Starship’s Raptor engines ignite during hot-staging separation pic.twitter.com/oNdU0Z4FQI — SpaceX (@SpaceX) May 22, 2026 Live views brought to you by @Starlink pic.twitter.com/Rpn6XtHckU — SpaceX (@SpaceX) May 22, 2026 Starship is executing a banking maneuver that mimics the final approach it would take while returning to Starbase for a catch on a future mission pic.twitter.com/3YQr8LKAaj — SpaceX (@SpaceX) May 22, 2026 Splashdown confirmed! Congratulations to the entire SpaceX team on the twelfth flight […]
SpaceX, “Starship V3” denemesinden harika videolar paylaştı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.
Hey,
I’m a web developer – building UIs with React, TypeScript, Tailwind, and modern web tools. A few months ago, I decided to step into Machine Learning.
No prior ML background. Just curiosity and basic Python knowledge.I started Andrew Ng’s Machine Learning Specialization and created my own study plan. Here’s what the first 30 days looked like — the concepts that clicked, the mistakes I made, and what surprised me most.
Week 1: Building the Math Foundation
I started with prerequisites because they’re essential:
Concept: Why Gradients Matter
Gradient descent is the engine behind almost all modern ML.
Imagine you’re trying to reach the bottom of a valley in the dark. The gradient tells you the direction and steepness of the slope. You take a small step downhill.
(w = w - learning_rate * gradient)
Repeat until you reach the minimum.
This simple idea powers neural networks, linear regression, and more.
Weeks 2–3: Supervised Learning (The Real Fun Begins)
I dove into regression and classification:
I built small projects in Colab:
Concept: Regularization
Regularization is like putting guardrails on your model. Without it, the model can memorize noise in the training data (overfitting). With L2 regularization, we penalize large weights, helping the model generalize better.
Weeks 4–5: Neural Networks & Tree Ensembles
This is where things got exciting:
Concept: Backpropagation
Forward propagation makes a prediction.
Backpropagation figures out why the prediction was wrong and updates every weight accordingly using the chain rule. It’s like tracing a bug through a chain of React components — but for thousands of parameters.
What Surprised Me Most
What’s Next?
I’m continuing the plan:
I’ll be sharing regular updates here — code, lessons, and notebooks. If you’re also learning ML as a web developer, drop a comment. I’d love to hear your journey too!
The Problem
You are processing some data through background job. But before the processing is done, another request had been made to read the related data.
In this case you are either providing a historic data or serving wrong information.
Solution
Holding the request until the job is executed, could be the simplest solution.
I am not saying it is the only solution, but the simplest one.
Some Scenarios
Lets discuss about some possible scenarios.
Booking Job
When a user request to book a resource between two specifics dates. Let’s assume that it is done by a job. So it might take some time in production load.
In the meantime if another request is asking for that specific users booking data.
File Importing Job
User uploads a file like CSV or XML, you have accepted the file but it also needs processing, which should be done in by a job.
If the user ask for the status of the CSV resource in another request.
The Package
aihimel/laravel-waiting-request is a small Laravel package that solves exactly this — it lets one request park until another piece of work (a job, a sync, a long-running controller action) signals that the resource is ready to read.
Install
composer require aihimel/laravel-waiting-request
Optionally publish the config:
php artisan vendor:publish --tag="waiting-request-config"
How it works
The package exposes a tiny API around four ideas: block, wait, check, resolve. Under the hood it is backed by your Laravel cache — no extra infrastructure, no queue plumbing.
A blocker is identified by a class path and a resource id. That pair becomes a unique cache key, so blockers are per-resource (booking 42 does not interfere with booking 43).
use AihimelLaravelWaitingRequestFacadesLWRequest;

// 1. Block — call this where the background work *starts*
LWRequest::addBlocker(Booking::class, $booking->id);

// 2. Wait — call this in the request that wants to read the resource
$resolved = LWRequest::whenResolved(Booking::class, $booking->id);

if ($resolved) {
    return BookingResource::make($booking->fresh());
}

return response()->json(['message' => 'Still processing, try again'], 202);

// 3. Resolve — call this when the background work finishes
LWRequest::resolveBlocker(Booking::class, $booking->id);
You can also peek without waiting:
if (LWRequest::isBlocked(Booking::class, $booking->id)) {
    // resource is mid-flight
}
Applying it to the scenarios
Booking job. The controller that accepts the booking calls addBlocker(Booking::class, $id) and dispatches the job. The job calls resolveBlocker(...) in its handle() (or in a finally block). Any reader that hits GET /bookings/{id} in the meantime calls whenResolved(...) first and only reads the model once the writer is done.
File importing job. Same shape: addBlocker(Import::class, $import->id) when the upload is accepted, resolveBlocker(...) when the parser finishes (success or failure — both should release). The status endpoint calls whenResolved(...) so the client gets a settled answer instead of a half-imported snapshot.
Sensible defaults you can tune
Every knob lives in config/waiting-request.php and is overridable via env:
| Config | Env | Default | What it does |
|---|---|---|---|
cache_prefix |
LW_REQUEST_CACHE_PREFIX |
lw_request_ |
Namespace for cache keys |
timeout |
LW_REQUEST_MAX_WAITING_TIME |
5 |
How long whenResolved() waits before giving up (seconds) |
check_interval |
LW_REQUEST_CHECK_INTERVAL |
250 |
Poll interval inside whenResolved() (milliseconds) |
max_blocking_time |
LW_REQUEST_MAX_BLOCKING_TIME |
10 |
Max lifetime of a blocker before it auto-expires (seconds) |
addBlocker() takes an optional third argument so you can bump the TTL per call when you know a particular job runs longer:
LWRequest::addBlocker(Import::class, $import->id, 120); // 2 minutes
Why the blocker has a lifetime
If a job crashes before calling resolveBlocker(), you do not want readers to wait forever. From v2.x every blocker carries a Unix expiry timestamp. The next isBlocked() / whenResolved() call after that timestamp will:
Log::warning('Waiting-request blocker expired without being resolved', [...])
So even if your job dies, traffic recovers on its own and you get a log line telling you it happened.
Do’s and Don’ts
Do
finally. Wrap your job body so a thrown exception still hits resolveBlocker(). Auto-expiry is a backstop, not a happy path.max_blocking_time to comfortably exceed your worst-case job duration. If your import averages 8s and worst-cases at 25s, a 10s default will auto-release while the job is still running — defeating the lock.timeout to match your UX budget. If a client is willing to wait 2s for a synchronous response, set timeout=2; do not let whenResolved() hold an HTTP worker for 30s.true will be read as 1, treated as already-expired, and produce a one-time burst of warning logs.false return from whenResolved() as “still pending”. Respond with 202 Accepted (or similar) and let the client poll — do not pretend the data is ready. Don’t
isBlocked() on a hot, read-only path you expect to be side-effect-free. It evicts expired entries and writes a log line. That is intentional, but worth knowing.Cache::add() will reject the second addBlocker() (it returns false), but the package does not give you queueing, fairness, or strict mutual exclusion.Booking::class + $id), not by something coarse like the user id, or you will block requests that have nothing to do with each other.array or file drivers will not work across processes. In production, use redis / memcached so the worker that resolves the blocker and the web process that is waiting actually share the same cache.whenResolved() from a queue worker. Polling inside a worker burns a worker slot. Workers should resolve blockers, not wait on them.That’s the whole package — a couple of facade calls, a cache key per resource, and a sane expiry so nothing wedges. If you’ve ever shipped a ?retry=true hack or a sleep-and-pray in a controller, this is the cleaner version of that.
Source & issues: github.com/aihimel/laravel-waiting-request
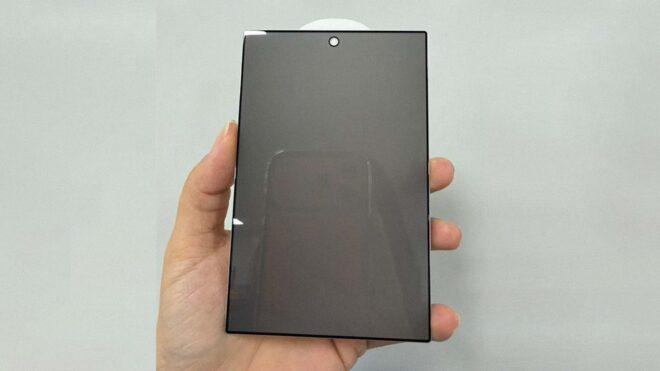
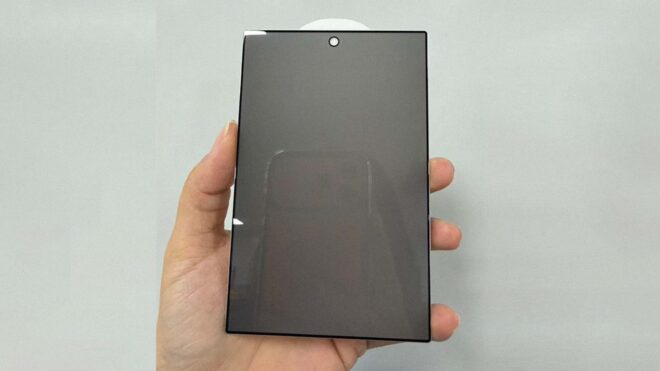 Geniş yapısıyla fark yaratacak katlanabilir telefon modeli Samsung Galaxy Z Fold8 Wide (ismi farklı olabilir) için yeni paylaşımlar yapıldı. Ice Universe’ten gelen bu paylaşımlarda cihazın ekranını koruyacak cam karşımıza çıkıyor. Telefonun kapalı formdaki boyutunu ve elde duruşunu gözler önüne seren cam, Huawei Pura X Max’te kullanılan camla da yan yana getiriliyor. TechManiacs tarafından aktarılan bilgilere göre Galaxy Z Fold8 Wide modeli 45W şarj destekli 4.800 mAh batarya, 7,6 inç boyutunda katlanabilir iç ekran, 5,4 inç boyutunda dış ekran, Snapdragon 8 Elite Gen 5 işlemci, 200 gram gövde ağırlığı, 50 megapiksel geniş açı + 50 megapiksel ultra geniş açı taşıyan arka kamera sistemi ve iki farklı 10 megapiksellik selfie kamerası gibi teknik detaylarla geliyor. If we add a screen to this tempered glass protector for the Samsung Galaxy Z Fold8 Wide, its cover screen would basically look like the image on the right. Of course, the real device will not have […]
Samsung Galaxy Z Fold8 Wide için yeni paylaşımlar geldi yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.
I wasted an entire afternoon wondering why Google Search Console kept showing zero rich results for my React app. The breadcrumbs looked perfect in the browser. Users could see them. But Google? Completely blind. The problem wasn’t my breadcrumb component it was that I’d never told Google what those breadcrumbs actually were. Structured data. Four lines of JSON-LD. That was it. Here’s everything I learned, so you don’t lose the same afternoon.
Why React Breadcrumbs Are Invisible to Google
React apps render in the browser. Google’s crawler is getting better at parsing JavaScript, but structured data embedded in client-rendered markup is still unreliable for rich results. The gold standard for breadcrumb rich results in Google Search is JSON-LD schema markup injected into <head> not your visible DOM breadcrumb trail.
The two things are completely separate:
Most tutorials show you how to build the UI. Almost none explain the schema side. That’s why your breadcrumbs look fine to you but don’t show up as rich results in Google.
Here’s what a valid BreadcrumbList schema looks like, per Schema.org:
{
  "@context": "https://schema.org",
  "@type": "BreadcrumbList",
  "itemListElement": [
    {
      "@type": "ListItem",
      "position": 1,
      "name": "Home",
      "item": "https://example.com"
    },
    {
      "@type": "ListItem",
      "position": 2,
      "name": "Blog",
      "item": "https://example.com/blog"
    },
    {
      "@type": "ListItem",
      "position": 3,
      "name": "My Article",
      "item": "https://example.com/blog/my-article"
    }
  ]
}
Your job is to get exactly this into a <script type="application/ld+json"> tag in <head> on every page that has breadcrumbs.
The Manual Approach: A Custom React Hook
If you’re not using any SEO library, here’s a clean, copy-paste hook that builds and injects breadcrumb schema based on your current route.
// hooks/useBreadcrumbSchema.js
import { useEffect } from "react";

export function useBreadcrumbSchema(crumbs) {
  useEffect(() => {
    const schema = {
      "@context": "https://schema.org",
      "@type": "BreadcrumbList",
      itemListElement: crumbs.map((crumb, index) => ({
        "@type": "ListItem",
        position: index + 1,
        name: crumb.label,
        item: crumb.url,
      })),
    };

    const script = document.createElement("script");
    script.type = "application/ld+json";
    script.id = "breadcrumb-schema";
    script.textContent = JSON.stringify(schema);

    // Remove any existing breadcrumb schema before inserting
    document.getElementById("breadcrumb-schema")?.remove();
    document.head.appendChild(script);

    return () => {
      document.getElementById("breadcrumb-schema")?.remove();
    };
  }, [crumbs]);
}
Then in your page component:
// pages/BlogPost.jsx
import { useBreadcrumbSchema } from "../hooks/useBreadcrumbSchema";

export default function BlogPost({ post }) {
  useBreadcrumbSchema([
    { label: "Home", url: "https://example.com" },
    { label: "Blog", url: "https://example.com/blog" },
    { label: post.title, url: `https://example.com/blog/${post.slug}` },
  ]);

  return <article>{/* your content */}</article>;
}
Result: Every time the component mounts, the correct JSON-LD block is injected into <head> and cleaned up on unmount. Paste it into Google’s Rich Results Test and you’ll see a green checkmark.
One caveat: if you’re using SSR (Next.js, Remix, etc.), this useEffect approach only runs client-side. For SSR, you need to render the script tag server-side which brings us to the next section.
The SSR Problem: Getting Schema Into <head> at Build Time
With Next.js, you can’t rely on useEffect for schema that needs to be in the initial HTML response. The fix is rendering a <script> tag directly in your component using next/head or the App Router’s <Head>:
// app/blog/[slug]/page.jsx (Next.js App Router)
import Head from "next/head";

function buildBreadcrumbSchema(crumbs) {
  return {
    "@context": "https://schema.org",
    "@type": "BreadcrumbList",
    itemListElement: crumbs.map((crumb, i) => ({
      "@type": "ListItem",
      position: i + 1,
      name: crumb.label,
      item: crumb.url,
    })),
  };
}

export default function BlogPost({ params }) {
  const crumbs = [
    { label: "Home", url: "https://example.com" },
    { label: "Blog", url: "https://example.com/blog" },
    { label: "My Post", url: `https://example.com/blog/${params.slug}` },
  ];

  const schema = buildBreadcrumbSchema(crumbs);

  return (
    <>
      <Head>
        <script
          type="application/ld+json"
          dangerouslySetInnerHTML={{ __html: JSON.stringify(schema) }}
        />
      </Head>
      <article>{/* your content */}</article>
    </>
  );
}
Now the schema is part of the server-rendered HTML Google sees it immediately, no JavaScript execution required.
Using a Library: When Manual Gets Tedious
The manual approach is fine for one or two page types. But if your app has ten different page templates (product pages, category pages, blog posts, docs), you’ll end up copy-pasting and slightly mangling that schema builder everywhere. That’s where a dedicated library helps.
I tried a few options and ended up using @power-seo because it handles breadcrumb schema, OpenGraph, and canonical tags from a single config object which matched how I was already thinking about per-page SEO.
npm install @power-seo
import { SEO } from "@power-seo";

export default function BlogPost({ post }) {
  return (
    <>
      <SEO
        breadcrumbs={[
          { label: "Home", url: "https://example.com" },
          { label: "Blog", url: "https://example.com/blog" },
          { label: post.title, url: `https://example.com/blog/${post.slug}` },
        ]}
        title={post.title}
        canonical={`https://example.com/blog/${post.slug}`}
      />
      <article>{/* your content */}</article>
    </>
  );
}
It generates the same JSON-LD output as the manual approach no magic, just less repetition. Whether that’s worth a dependency is your call. For small projects, the hook above is plenty.
What I Learned
useEffect-injected schema works for CSR apps, but for SSR/SSG (Next.js, Remix), render the <script> tag server-side inside <head> to guarantee it’s in the initial HTML.search.google.com/test/rich-results) before assuming it works. It’ll show you exactly what schema Google can parse.item values in your schema are a silent SEO killer Google will ignore the breadcrumb entirely if the URLs don’t resolve.If you want to see how the full implementation looks in a real Next.js blog (including dynamic route handling), here’s a detailed walkthrough: https://ccbd.dev/blog/how-to-implement-breadcrumb-schema-in-react-using-power-seo
What’s your setup?
Are you handling structured data manually, using a library, or just skipping it entirely and hoping for the best? I’m curious how other React devs are solving this especially on large apps with lots of page templates. Drop your approach in the comments. If you’ve found a cleaner pattern than what I’ve shown here, I genuinely want to know.
This is a submission for the Gemma 4 Challenge: Build with Gemma 4
What I Built
Planning a trip used to mean bouncing between five browser tabs — one for flights, one for hotels, one for itineraries, one for Reddit threads, and one you forgot you opened. I wanted to collapse that into a single conversation.
Gemma Travel Assistant is an AI-powered chat app that helps you plan trips from scratch. Tell it your budget, your vibe, your dates. Ask follow-up questions. Upload a photo of somewhere you saw on Instagram and ask “where is this, and what should I do there?” It remembers everything you said earlier in the conversation and uses it to give you better answers.
What makes it feel different from a plain chatbot:
It doesn’t just write paragraphs. When Gemma recommends hotels or destinations, the app parses those recommendations out of the response and renders them as visual cards — name, location, type badge (hotel / destination / restaurant), star rating, price range. You can scan five options in three seconds instead of reading five bullet points.
Responses stream token by token. You start reading the answer while Gemma is still writing it. For a full 5-day itinerary that can be 600+ words, this makes the experience feel instant instead of frozen.
It understands images natively. Drop in a photo — a landscape, a hotel lobby, a plate of food — and the model uses it as context. No extra vision pipeline, no OCR. Gemma 4 handles it directly.
Demo
Example conversation:
You: Plan a 5-day trip to Kyoto in October, budget around $1500, I love temples and local food
Gemma: Here’s a day-by-day itinerary for Kyoto in October — peak foliage season, so I’ve planned around the best viewing spots…
(streams in, then suggestion cards appear below for ryokans and restaurants)You: (uploads a photo of a bamboo forest)
Gemma: That’s Arashiyama Bamboo Grove in western Kyoto. It’s already on day 3 of your itinerary — here are the best times to visit to beat the crowds…
GitHub: https://github.com/mushahidmehdi/gemma-travel-assistant
Code
Stack:
| Layer | Choice |
|—|—|
| Framework | Next.js 16 (App Router) |
| Model | Gemma 4 31B Dense via OpenRouter |
| Styling | Tailwind CSS |
| Markdown | ReactMarkdown |
| Icons | Lucide React |
Project structure:
src/
├── app/
│   ├── api/chat/route.ts   # Streaming SSE proxy → OpenRouter
│   ├── layout.tsx
│   └── page.tsx            # Centered card layout
└── components/
    ├── ChatInterface.tsx   # Input, image upload, message list
    ├── ChatMessage.tsx     # Bubble renderer + suggestion parser
    └── SuggestionCard.tsx  # Hotel / destination / restaurant cards
How I Used Gemma 4
Choosing the model
I went with Gemma 4 31B Dense (google/gemma-4-31b-it). Here’s why that specific model, not the others:
The E2B / E4B models are designed for edge and mobile — brilliant for offline use, but I needed server-grade reasoning quality for multi-day itineraries with budget constraints, visa tips, and local context. A 2B model can hallucinate confidently about things it doesn’t know well.
The 26B MoE model is optimized for throughput. For a travel assistant where a single user sends a message and waits for the reply, throughput wasn’t the bottleneck. Quality and coherence over a long conversation were.
The 31B Dense hits the right balance: strong enough to produce well-structured, accurate travel advice, consistent enough to reliably follow formatting instructions (more on that below), and available on OpenRouter’s free tier so anyone can clone the repo and run it without a credit card.
The 128K context window was the other deciding factor. Planning a real trip is a long conversation. By the time you’ve discussed your budget, chosen a region, rejected two hotel options, added a day trip, and asked about visa requirements, you’ve accumulated thousands of tokens of context. Smaller context windows start dropping earlier constraints. With 128K, nothing gets forgotten.
Streaming the response
The API route doesn’t buffer — it pipes OpenRouter’s SSE stream directly to the browser:
// src/app/api/chat/route.ts
const stream = new ReadableStream({
  async start(controller) {
    const reader = response.body!.getReader();
    const decoder = new TextDecoder();

    while (true) {
      const { done, value } = await reader.read();
      if (done) break;

      const chunk = decoder.decode(value);
      const lines = chunk.split('n').filter(line => line.startsWith('data: '));

      for (const line of lines) {
        const data = line.slice(6);
        if (data === '[DONE]') { controller.close(); return; }
        try {
          const parsed = JSON.parse(data);
          const content = parsed.choices?.[0]?.delta?.content;
          if (content) controller.enqueue(new TextEncoder().encode(content));
        } catch { /* skip malformed chunks */ }
      }
    }
    controller.close();
  },
});

return new Response(stream, {
  headers: { 'Content-Type': 'text/plain; charset=utf-8' },
});
On the client, ChatInterface reads the stream chunk by chunk and appends to the last message in state, so React re-renders progressively as tokens arrive.
Structured output via prompting
I didn’t use a formal structured output API. Instead, the system prompt tells Gemma to append a fenced suggestions block at the end of any response that involves specific recommendations:
When suggesting places, format your hotel/destination/restaurant recommendations
as a JSON block at the end of your response:
suggestions
[{
“name”: “Nishiyama Onsen Keiunkan”,
“location”: “Yamanashi, Japan”,
“type”: “hotel”,
“rating”: 4.9,
“price”: “$$$”,
“description”: “The world’s oldest hotel, operating since 705 AD…”
}]
typescript
ChatMessage then does two things: strips that block from the visible text (so it doesn’t appear as raw JSON in the bubble), and passes the parsed array to SuggestionCard components:
function parseSuggestions(content: string) {
  const match = content.match(/```
{% endraw %}
suggestionsn([sS]*?)
{% raw %}
```/);
  if (!match) return { text: content, suggestions: [] };

  const text = content.replace(/```
{% endraw %}
suggestionsn[sS]*?
{% raw %}
```/, '').trim();
  try {
    return { text, suggestions: JSON.parse(match[1]) };
  } catch {
    return { text: content, suggestions: [] }; // graceful fallback
  }
}
If Gemma omits the block — for a conversational reply like “Great, let’s add a day trip!” — the component falls through cleanly and just shows the text bubble. No crashes, no empty card rows.
Multimodal input
Image uploads are encoded as base64 data URLs and injected into the last user message as an image_url content block — the format OpenRouter and Gemma 4 expect:
if (msg.role === 'user' && image && isLastMessage) {
  return {
    role: 'user',
    content: [
      { type: 'text', text: msg.content },
      { type: 'image_url', image_url: { url: image } }, // base64 data URL
    ],
  };
}
Gemma 4’s native vision understands the image without any preprocessing on my end — no external OCR, no separate vision model call. The model sees both the image and the conversation history and responds in context.
Building this made me appreciate how much the context window size and multimodal capability change what’s actually possible in a single conversation. A travel assistant that forgets what you said three messages ago, or that can’t look at a photo you found, is just a fancier search box. Gemma 4 31B makes it feel like talking to someone who’s actually paying attention.
Microsoft tried to kill the printer driver. 90% of US healthcare said no.
In late 2025, Microsoft put a line on the Windows Roadmap that should have read as routine. Starting January 2026, Windows Update would stop shipping legacy V3 and V4 printer drivers. Modern Print Platform only. Goodbye to a decade of brittle vendor blobs.
In February 2026 they quietly took it back. The line vanished from the roadmap. The official statement told users no action applies. Existing printers will keep working. The deprecation, for now, sits on hold.
Microsoft holds more market power than almost any company in history. They tried to retire a category of driver that Microsoft itself deprecated back in September 2023. They could not actually pull it off. The reason sits in every hospital in the United States, and it makes a noise like a 1990s modem.
TL;DR
| Thing | Status |
|---|---|
| V3 and V4 printer drivers | Deprecated since September 2023, still alive |
| January 2026 deprecation push | Announced, then retracted in February 2026 |
| US healthcare communication that still runs on fax | About 70 percent |
| Once you count EHR linked faxing | Closer to 90 percent |
| ATM transactions still running on COBOL | About 95 percent |
| Online banking transactions touching COBOL | More than 40 percent |
| Time horizon on this stuff actually dying | Decades, not quarters |
1. The headline that almost happened
The original Microsoft plan looked clean. V3 and V4 driver models carried known security and stability problems. Modern Print Platform, the IPP based replacement, outperforms them in almost every measurable way. Microsoft already deprecated the old drivers two and a half years ago. The January 2026 update would have completed the cleanup.
That plan sits in the archive now. Tom’s Hardware and Windows Central covered the original announcement. The retraction came after Microsoft “received feedback.” The polite version of “received feedback” reads as follows: some quite large customers told Microsoft, in writing, that breaking the printer pipeline would break the hospital pipeline, and that the hospital pipeline runs on fax.
2. The fax number you cannot believe
Here is the statistic that broke my brain when I first read it. Roughly 70 percent of healthcare communication in the United States still moves over fax. When you include EHR linked faxing, where an electronic health record system pretends to be a fax machine in order to talk to the rest of the industry, the number climbs to about 90 percent.
Ninety percent. Of the most regulated, most digitized, most money-flooded industry in the developed world. Running on a protocol that predates the personal computer.
   The 2026 healthcare comms diagram

  ┌──────────────┐         FAX           ┌──────────────┐
  │   Hospital A │  ─────────────────▶   │   Clinic B   │
  │   (modern    │                       │   (modern    │
  │    EHR)      │                       │    EHR)      │
  └──────────────┘                       └──────────────┘
        │                                       │
        ▼                                       ▼
   Pretends to be                          Pretends to be
   a fax machine                           a fax machine
        │                                       │
        ▼                                       ▼
  ╔═════════════════════════════════════════════════════╗
  ║   90% of the actual traffic goes over fax anyway    ║
  ╚═════════════════════════════════════════════════════╝
That diagram explains what Microsoft hit when they tried to ship the driver change. The driver path covers more than home offices. The driver path runs through compliance pipelines that no single engineering team owns. Break the driver layer in January, and somebody’s referral cannot reach somebody else’s prior authorization in February. That outcome does not fit a “we will respond to feedback” narrative. That outcome makes a 60 Minutes segment.
3. The other infrastructure that refuses to die
Fax counts as the most visible example. Not the only one. The pattern shows up everywhere stable infrastructure built up decades of edge cases. IBM has said for years, in slightly louder volumes each year, that COBOL still runs about 95 percent of ATM transactions and more than 40 percent of online banking. The COBOL workforce is aging out. The replacements never arrived. The systems keep running.
Same pattern with:
| System | Year designed | Still doing real work in 2026 |
|---|---|---|
| Fax | 1843 (concept), 1960s mainstream | Yes, in healthcare and government |
| COBOL | 1959 | Yes, in banks and insurance |
| FORTRAN | 1957 | Yes, in scientific computing |
| SQL | 1974 | Yes, almost everywhere |
| Email (SMTP) | 1982 | Yes, the protocol you read every day |
| HTTP | 1991 | Yes, you are reading this over it |
We tell each other we live in a world of rapid change. The world actually sits on one of the most stable substrates the species has ever built. The application layer churns. The substrate hardly moves at all.
4. The lesson for software you ship today
You will not build fax machines. You will, almost certainly, write code that outlives your current job, your current company, and possibly your current career. That outcome sits at the heart of the COBOL story that nobody puts on a slide. The COBOL devs in 1985 did not know their code would still run in 2026. They just shipped.
The code you wrote last week might still serve as a production database adapter in 2040. The defaults you picked stand a chance of becoming invariants for some future maintainer who has never met you. Five practical rules that pay back over the decade-scale arc of code:
Rule 1: Comment the boundary, not the line
Your future maintainer can read your code. They cannot read your decision tree. Write down why a particular flag exists, why a particular workaround sits where it does, why a particular value lives as a constant. Skip the obvious. Document the negotiations.
# bad
TIMEOUT = 47

# good
# Set to 47 seconds because the partner auth gateway has a hard 50s limit
# and we observed 1-2s of jitter from our load balancer in the May 2023
# postmortem. Do not raise without coordinating with the integrations team.
TIMEOUT = 47
The bad comment captures what the code already says. The good comment captures the negotiation that produced the number, which is the part that erases first.
Rule 2: Pick formats that read in plain text
JSON, CSV, plain SQL, basic English logs. The dependency on a binary format with proprietary tooling bites archaeologists hardest. If somebody can cat the file in 2046 and start guessing what it does, you have done them a favor that pays back forever.
The fax format is plain enough that a forensic analyst can read it with the right hardware. COBOL source is plain enough that a junior dev with a manual can read it. The systems that died fastest in the 1990s and 2000s were the ones that depended on a binary tool that the vendor stopped supporting. Choose against that future.
Rule 3: Write the migration script you wish someone had written for you
Every meaningful schema change should ship with the SQL or code that undoes it, or that walks the data from the old shape to the new one. Future you, or future someone, will thank you.
-- Forward migration
ALTER TABLE users ADD COLUMN preferred_locale VARCHAR(10) DEFAULT 'en-US';
UPDATE users SET preferred_locale = 'en-GB'
  WHERE country_code IN ('GB', 'IE', 'AU', 'NZ');

-- Down migration (commit this in the same file)
ALTER TABLE users DROP COLUMN preferred_locale;
Tools like Alembic, Flyway, Liquibase, and Sequelize migrations enforce this discipline. If your team is doing migrations as ad-hoc DBAs running scripts in pgAdmin, you are storing technical debt that compounds at the rate of every release.
Rule 4: Version your wire formats from day one
The number one source of unkillable legacy infrastructure is a public protocol that grew without a version field. The 1843 fax protocol gained version negotiation only when CCITT standardized it. The internet has 30 years of bolt-on versioning because TCP/IP shipped without it. Avoid being the contributor of the next one.
// good API response, version everywhere
{
  "version": "2026-05-01",
  "data": { "..." }
}
Use date-based versioning, header-based versioning, or URL-based versioning. Pick one. Use it consistently. When you need to make a breaking change in five years, the version field is the only thing that lets you do it without breaking every client at once.
Rule 5: Write a CHANGELOG that survives the company
CHANGELOG.md, in the root of every repo you own. One entry per release. Date, version, and a sentence per change. Not generated. Written by a human. The future maintainer reads this before they read your code.
## [2026-05-12] - 2.4.1
- Fixed billing rounding bug where orders with >100 line items
  rounded the tax down by 1 cent. See incident 2026-05-09.
- Raised the partner gateway timeout from 30s to 47s. Coordinated with
  the integrations team. Do not raise further.
The CHANGELOG is the only document that gets read in 2040. Make it count.
5. A short tour of the substrate you depend on right now
If you think your stack is modern, the following table is for you. The right column is the year the underlying protocol or format reached its current dominant form. Every one of these things runs in the path of the request that loaded this article.
| Layer | Protocol or format | Year |
|---|---|---|
| Network | TCP/IP | 1981 |
| Domain name | DNS | 1983 |
| Email transport | SMTP | 1982 |
| Email reading | IMAP | 1986 |
| Web transport | HTTP/1.1 | 1997 |
| Time format | Unix epoch | 1970 |
| Text encoding | UTF-8 | 1993 |
| Image format | JPEG | 1992 |
| Image format | PNG | 1996 |
| Video format | H.264 | 2003 |
| Database query language | SQL | 1974 |
| Source control | Git | 2005 |
| Container format | Tar | 1979 |
| Shell | POSIX shell | 1989 |
The newest thing on that list is H.264, and it is 23 years old. Everything else has been there longer than most of the people reading this article have been alive. The “modern stack” is a thin veneer of frameworks over a substrate that predates the personal computer in most cases.
This is not bad news. It is the most stable substrate any creative discipline has ever had to work on. Painters change pigments every century. Architects change materials every generation. Software engineers work on a foundation that has been mostly stable for 40 years. That foundation is what makes everything we build possible.
6. The honest take
A tempting story sits here that goes “legacy is bad and we should kill it.” That story misses the picture. The legacy systems stayed around because they work. A hundred million transactions a day stress-tested them, in front of regulators who would happily fine the carrier that broke them. The new systems will, eventually, earn the same proof. They have not yet.
The reasonable position lands at humility. We do not count as the first generation to write important software. We will not count as the last. The substrate predates us. The substrate will probably outlast us.
In a strange way, that picture reassures rather than worries. Microsoft cannot delete the printer driver. The fax machine still rings in your hospital. The work matters.
The bottom line
A driver deprecation that should have been routine got walked back because the substrate it sits on is older, weirder, and more important than the people deprecating it remembered. Healthcare runs on fax. Banking runs on COBOL. Your job, whatever you ship next, is going to land in someone’s legacy/ directory eventually. Write it like the next person matters.
Question for the comments: what is the oldest piece of infrastructure your job still depends on, and how surprised would your CTO be to learn it is in the critical path?
GDS K S · thegdsks.com · follow on X @thegdsks
The most modern thing in your stack is the part that is about to be legacy.

Lesson 2 of Build a Twitter Clone – A Practical Guide to Software Modelling
A diagram shows you what a system does; a data model tells you what it remembers. Before drawing a single flowchart, you need to know what information Bird must store – and how that information is shaped. In this lesson we read our three use cases for data clues, name the entities the system must track, define their fields and relationships, and translate all of it into a real MySQL schema split across two purposefully separated databases.
Introduction – Data Before Diagrams
Lesson 1 was closed with a promise: in Lesson 2, we draw the diagrams. Flowchart, functional diagram, sequence diagram – the works. At the moment we’re going to defer it for a while. The reason is quite simple – because of something that becomes obvious the moment you try to draw the flowchart for “Post a message” without it: a diagram that doesn’t know what data it’s moving is vague in exactly the wrong places.
You need to consider the following – the flowchart for posting a message will eventually have a step called something like “save the message.” Straightforward enough on paper. But the moment you try to build it, questions pile up fast:
 Figure 1. What is the Message?
A diagram that leaves those questions open isn’t a blueprint. It’s a sketch – useful for thinking, but not yet useful for building. The answers live in the data model: the formal description of what the system stores, and how the pieces of stored information relate to one another.
Think of the data model as the system’s long-term memory. The diagrams describe what the system does– its behaviour, its structure, its conversations. The data model describes what it remembers between those moments of action. Without memory, each request starts from nothing. With it, a message posted today is still there tomorrow, and the author who posted it can be found.
Getting the data model right before drawing the diagrams isn’t pedantry. It’s the thing that turns vague boxes into precise components. When you know that a message is a row with an id, a content field capped at 280 characters, and an author_id that points to a specific user – then the “save message” step in your flowchart stops being a placeholder and starts being an instruction. The functional block that does the saving has a clear contract. The sequence diagram can name what passes between components.
One System, Two Databases – and Why That’s the Right Call
Before we write a single table definition, there’s a structural question to answer: should all of Bird‘s data live in one database, or more than one?
The instinct is usually to start with one. It’s simpler, it requires less setup, and for a small project it feels like the obvious default. We’re going to make a different call – and the reasoning behind it is worth understanding clearly, because the same question will come up in every non-trivial system you ever build.
The problem with putting everything in one place
Start with the simpler option: one database called bird, with all tables inside it – users, messages, sessions, roles, everything. Will it work?
The answer is clear – it would work. In fact, it’s how most beginner projects start, and there’s nothing wrong with it as a starting point. But consider what happens as the system grows:
messages table to faster storage, or archive old records. But the table is in the same database as your user credentials, which have entirely different performance and retention requirements. You can’t move one without the other. Figure 2. All in one Database – Will it Work?
The deeper problem is this: a single database couples concerns that have no real reason to be coupled. They are in the same place not because they belong together, but because it was convenient to put them there. Convenience now, complexity later.
The principle: each domain owns its data
The solution is to give each distinct area of the problem its own data store – its own database that it, and only it, is responsible for. Nothing else writes directly to that data; anything that needs information from another domain has to go through the interface that domain exposes.
This is a well-established pattern in software design called Database per Service: each logical service or domain owns its storage, and the boundary between services is enforced at the data layer, not just at the code layer. The pattern makes the separation real and durable – you can’t accidentally reach across a boundary you’d have to explicitly cross.
![[Database per Service Design Pattern.jpg]]Figure 3. Database per Service Design Pattern
For Bird, two domains emerge clearly once you ask the question:
These two concerns have different owners, different change rates, and different security requirements. They will be given separate databases: ums (User Management System) for identity and access, and twitter for content and social graph.
| Database | Domain | What it owns |
|---|---|---|
ums |
Identity & access | Who people are, how they authenticate, what permissions they hold, which sessions are active |
twitter |
Content & social graph | The messages people post, and who follows whom |
Separating them means each can be optimized, scaled, or secured independently – a schema change in one won’t touch the other.
The idea behind the split: bounded contexts
The deeper principle at work here comes from Domain-Driven Design (DDD) – a way of thinking about how to organize software around the real-world problems it solves, rather than around technical convenience.
DDD would describe ums and twitter as separate bounded contexts: distinct areas of the problem, each with its own vocabulary, rules, and data. The word user in the identity context means something specific – an account with credentials, roles, and a session history. The word author in the messaging context means something different – a source of content, identified by an ID, whose full identity details live elsewhere. These concepts correspond to the same human being, but they are different models of that person, serving different purposes. Keeping them in separate databases makes that distinction visible and enforces it.
 Figure 4. How DDD Helps and Works
An analogy. Think of a hospital. The billing department and the medical records department both deal with the same patients – but they maintain completely separate files. The billing system doesn’t need to know a patient’s diagnosis; the medical records system doesn’t need to know their payment history. Each department owns its data. Information is shared only when explicitly requested, through defined channels. The separation isn’t bureaucracy – it’s what keeps sensitive data appropriately contained, and what lets each department evolve independently.
If you want to go deeper on Domain-Driven Design, this article covers the core ideas without requiring a computer science background.
Reading the Use Cases for Data Clues
A use case describes what a user accomplishes. But read carefully, and it also tells you what the system must remember in order to make that possible. Each of Bird‘s three use cases leaves a trail of data requirements – we just have to follow it.
Post a message
A user writes some text and publishes it. For this to work, the system must store the text itself, know who posted it, and record when it was posted so the timeline can be ordered. That’s three pieces of information: content, author, timestamp.
| Scope | Field | Type | Why it’s needed |
|---|---|---|---|
messages |
id |
UUID | A stable, unique identifier for this message |
messages |
author_id |
UUID | The id of the user who posted this message – links back to users.id
|
messages |
content |
String (max 280 chars) | The text of the message, capped at 280 characters |
messages |
created_at |
Timestamp | When the message was posted – used to order the timeline |
View the timeline
This use case produces no new fields. It reads existing messages rows, ordered by created_at descending, and joins to users on author_id to display the author’s name. Every field it depends on was already required by Post a message. Here we have to introduce what it is called – subscriptions and set a relation between author and and consumer of the message, i.e. – subscriber.
| Scope | Field | Type | Why it’s needed |
|---|---|---|---|
subscriptions |
subscriber_id |
UUID | The user doing the following – logical FK to users.id
|
subscriptions |
producer_id |
UUID | The user being followed – logical FK to users.id
|
subscriptions |
created_at |
Timestamp | When the follow relationship was created |
Register an account
A user creates an identity. The system must store a name to display, credentials to authenticate with (stored as a hashed password, never plain text), and again a timestamp. It also needs a way to distinguish one account from every other – a unique identifier that never changes even if the username does.
| Scope | Field | Type | Why it’s needed |
|---|---|---|---|
users |
id |
UUID | A stable, unique identifier for this user – never changes, even if name or email does |
users |
name |
String | The display name shown alongside every post |
users |
email |
String | Login credential; unique across all users – no two accounts can share an address |
users |
password_hash |
String | The user’s password after a one-way hashing function – never the plain-text password |
users |
created_at |
Timestamp | When the account was registered |
users |
updated_at |
Timestamp | When any field on this record last changed; refreshed automatically on every write |
| Scope | Field | Type | Why it’s needed |
|---|---|---|---|
roles |
id |
UUID | Unique identifier for this role |
roles |
name |
String | The role label (e.g. admin, member) – must be unique |
roles |
description |
String | Optional human-readable explanation of what this role permits |
| Scope | Field | Type | Why it’s needed |
|---|---|---|---|
sessions |
id |
UUID | Unique identifier for this login session |
sessions |
user_id |
UUID | References users.id – whose session this is |
sessions |
logged_in_at |
Timestamp | When the session started |
sessions |
logged_out_at |
Timestamp | When the session ended; NULL if the user is still logged in |
Across all three use cases, two distinct categories of information emerge: things the system needs to know about people, and things it needs to know about messages. That observation is the foundation of the data model.
Naming the Entities
An entity is a category of information the system tracks as a distinct thing – something that has its own identity, its own set of properties, and its own lifetime. Naming entities is the first act of data modelling: you’re deciding what the system considers a noun.
From the use cases, two entities name themselves:
User – a registered account. Every message is posted by a user; the timeline attributes each post to one. Users exist independently of any message they’ve posted, and they persist even if all their messages were deleted. They are a distinct thing in their own right.
Message – a piece of content posted by a user. Messages depend on users (a message with no author makes no sense), but they are not part of a user – they are their own thing, with their own timestamp and their own text.
Two entities. That matches the two databases we decided to create: ums owns User, and twitter owns Message. The database boundary and the entity boundary are the same line drawn twice.
You’ll notice there’s no
Timelineentity, noFeedentity, noNotification. The timeline is not a thing the system stores – it’s a query – give me all messages, ordered bycreated_at, descending. It exists at runtime, not at rest. This is a useful distinction to internalise: not everything the user sees needs to be stored.
In the next section we’ll define the fields each entity carries – and introduce the mechanism that connects a Messageback to the User who wrote it.
Defining the Fields
An entity is just a name until you give it fields – the individual pieces of data it holds. This is where the model gets concrete. For each field, we’ll state what it is, what type of value it holds, and why it exists, tracing every decision back to a use case or a design constraint.
A note on identifiers
Every entity needs a primary key – a field whose sole job is to uniquely identify one row among all others, forever. A common choice is an auto-incrementing integer (1, 2, 3…), but Bird uses something different: a UUID (Universally Unique Identifier), stored as 16 bytes (or 128 bits) of binary data.
A UUID looks like 550e8400-e29b-41d4-a716-446655440000 – a 128-bit value generated in a way that makes collisions statistically impossible, even across separate systems. The binary storage (BINARY(16)) keeps it compact and fast to index. The reason to prefer UUIDs over integers here is forward-looking: if Bird ever scales to multiple servers generating records simultaneously, each can produce its own IDs without coordinating with the others. Integers can’t do that safely.
Every table uses this same pattern for its primary key: a BINARY(16) column called id, defaulting to a freshly generated UUID.
users – the identity record
The users table lives in the ums database. It is the authoritative record of everyone who has registered an account.
| Field | Type | Purpose |
|---|---|---|
id |
BINARY(16) |
Primary key – uniquely identifies this user across the entire system |
name |
VARCHAR(100) |
The display name shown on posts |
email |
VARCHAR(255) |
Login credential and contact address; must be unique across all users |
password_hash |
VARCHAR(255) |
The result of running the user’s password through a one-way hashing function – never the password itself |
created_at |
DATETIME |
When the account was registered |
updated_at |
DATETIME |
When any field on this record was last changed; updated automatically |
Two fields deserve a word of explanation. password_hash stores a hashed password, not a plain-text one. A hash functionis a one-way transformation: you can turn a password into a hash, but you cannot reverse the process. When a user logs in, the system hashes what they typed and compares the result to the stored hash – the original password never needs to be stored or retrieved. This is standard practice; storing plain passwords is a serious security failure.
updated_at tracks the last modification time and refreshes itself automatically on every write. It’s low-cost to store and invaluable for debugging, auditing, and cache invalidation later.
Supporting the User: roles and sessions
The use cases named registration – but a real identity system has two more concerns lurking just beneath the surface: what is this user allowed to do, and is this user currently logged in? These concerns get their own tables.
roles is a lookup table – a simple list of named permission levels (for example, admin, moderator, member). Roles don’t come from the use cases directly; they come from the reality that not all users have the same permissions.
users_roles links users to roles. Because one user can hold multiple roles and one role can be held by many users, this is a many-to-many relationship – and the standard way to model that in a relational database is a join table: a table with two columns, each a reference to one side of the relationship.
sessions records active login sessions. When a user authenticates, a session row is created with a logged_in_at timestamp. When they log out, logged_out_at is filled in. This gives the system a full audit trail of who was logged in and when – and lets it invalidate specific sessions without forcing a global logout.
None of these tables store messages or content. They belong entirely to the ums database and the identity domain.
messages – the content record
The messages table lives in the twitter database. It is the record of everything posted.
| Field | Type | Purpose |
|---|---|---|
id |
BINARY(16) |
Primary key – uniquely identifies this message |
author_id |
BINARY(16) |
The id of the user who posted this message, from ums.users
|
content |
VARCHAR(280) |
The text of the message – capped at 280 characters |
created_at |
DATETIME |
When the message was posted |
content is capped at 280 characters – the same limit Twitter uses, and a deliberate product constraint, not a technical one. The database enforces it with VARCHAR(280).
author_id is the field that links a message to its author. It holds the id value of a row in ums.users. Because the two tables live in separate databases, MySQL cannot enforce this link with a formal foreign key constraint – but the relationship is real. The application layer is responsible for ensuring that no message is ever written with an author_id that doesn’t correspond to a real user.
subscriptions – the social graph
There is one more table in the twitter database: subscriptions. It didn’t appear in the original three use cases, but it’s present in the schema for a good reason – it’s the data that would power a personalised timeline.
A subscription is a directional relationship between two users: one subscriber who follows one producer. The table has just three fields:
| Field | Type | Purpose |
|---|---|---|
subscriber_id |
BINARY(16) |
The user doing the following |
producer_id |
BINARY(16) |
The user being followed |
created_at |
DATETIME |
When the follow happened |
The combination of subscriber_id and producer_id is the primary key – you can only follow someone once. Both columns are logical foreign keys to ums.users.id, subject to the same cross-database constraint limitation as author_id in messages.
subscriptions is infrastructure for a feature – “Follow a user” – that isn’t in scope for the current lesson’s use cases but is correct to model now, because adding it later would require a migration. Modelling it upfront costs nothing; omitting it and adding it later costs a schema change and a deployment. This is the kind of forward-thinking that separates a considered data model from a reactive one.
How the Entities Relate
Individual entities are only half the picture. A data model also defines how entities connect to one another – their relationships. For Bird, there are two:
A User has many Messages (one-to-many). One user can post any number of messages; each message belongs to exactly one user. This relationship is expressed through author_id in the messages table – a field that holds the id of the user who owns that row. Following the author_id from a message leads you to its author.
A User can follow many Users, and be followed by many Users (many-to-many). This is the social graph, modelled through the subscriptions table. To find everyone a user follows, query subscriptions where subscriber_id matches. To find everyone following a user, query where producer_id matches.
 Figure 5. Types of Relationships
The pattern to remember. A one-to-many relationship is expressed by putting the “one” side’s
idas a field on the “many” side – the foreign key lives in the child table. A many-to-many relationship requires its own table, with one column for each side. Both patterns appear inBird, and together they cover the vast majority of real-world data relationships you’ll encounter.
With the entities named, the fields defined, and the relationships mapped, the data model is complete. What remains is to choose a database engine and write the schema.
What the Diagrams Will Now Be Built On
Lesson 1 introduced three lenses for looking at a system: functional structure, behaviour, and component interaction. Lesson 1 also made a promise — that diagrams would follow.
They will. But notice what’s changed since then.
Before the data model existed, a flowchart for “Post a message” would have had a step labelled something like “save the message” — a placeholder that gestures at an action without defining it. Now that step has a precise meaning: create a row in twitter.messages with a content value, an author_id pointing to the authenticated user in ums.users, and a created_attimestamp set to now.
The data model doesn’t just inform the diagrams — it creates clear mechanics how they work. Every box that reads or writes data now has a contract: specific fields, specific tables, specific relationships. The sequence diagram will name what passes between components. The functional diagram will know what each block owns. The flowchart steps will correspond to real operations.
That’s where Lesson 3 picks up: with the data model as the foundation, we draw all three diagrams.
Conclusion
A data model is the contract the rest of the system is written against.
We started with three use cases and asked a simple question: what must the system remember for each of these to work? That question led us to two entities — User and Message — and from there to five tables across two purposefully separated databases.
The separation itself was a design decision, not a convenience. Identity and access belong to one domain; content and social graph belong to another. Keeping them apart makes each easier to change, scale, and reason about independently. The trade-off — enforcing cross-database relationships in application code rather than at the database level — is a known and manageable cost.
Every field in the schema exists for a reason traceable back to a use case. Every relationship reflects a real dependency between things the system tracks. Nothing was added for completeness or anticipation — except subscriptions, which earns its place by being cheaper to model now than to migrate in later.
The diagrams come next. They’ll have something real to say.
If you’ve spent any time around telecom billing systems, you know they’re not your typical CRUD app. You’ve got prepaid balances, real-time charging, usage events flying in every second, and downstream systems that need to know about things right now not in 30 seconds. So when you’re wiring up integrations, the question of “do we poll or do we listen?” comes up fast.
how REST APIs and webhooks actually play out in this context, and where each one earns its place.
The Core Difference (Without the Textbook Version)
REST APIs are pull-based. Your system asks: “Hey, what’s the current balance for subscriber X?” and the billing system replies. You’re in control of when data moves.
Webhooks flip that. The billing system says: “Subscriber X just crossed their data threshold here’s the event payload, do something with it.” You register a URL, and the billing system pushes to you when something happens.
Neither is universally better. They solve different problems, and in telecom billing, you often end up using both.
Where REST APIs Work Well
Account and balance queries. When a customer calls in or opens the self-care portal, you need their current balance, active plan, and usage summary on demand. That’s a perfect REST use case you fire a request, you get a response, you render it. Platforms like Optiva (formerly Sigma Systems) and Comarch expose rich REST APIs for exactly this their BSS layers are designed for synchronous, request-response interactions when an operator needs to read or update subscriber data.
Provisioning and plan changes. When a customer upgrades their plan, you need to write that change to the billing system, confirm it succeeded, and then maybe update a few other systems. REST is clean here because the flow is sequential and you need confirmation before you move on.
Reporting and reconciliation. Finance teams running end-of-day or end-of-month reconciliation are querying aggregated data at their own cadence. REST is the right tool no need to react to events, just pull what you need when you need it.
Alepo Technologies, which focuses heavily on prepaid and convergent charging, has built a lot of their integration surface around REST for these provisioning and management workflows. It makes sense operators need predictable, auditable writes into the billing system, not fire-and-forget events.
Where Webhooks Actually Earn Their Keep
Real-time telecom billing is where REST starts to show its limits.
Think about a prepaid subscriber whose balance hits zero mid-call. Or a data session that needs to be throttled when someone blows through their monthly cap. Or a fraud detection system that needs to act the moment a suspicious usage pattern appears. Polling for these events is expensive, laggy, and just architecturally wrong.
CSG(which handles billing for some of the largest carriers globally) and Qvantel (known for their cloud-native BSS stack) both lean into event-driven architectures for this reason. When your billing platform can push usage events, threshold crossings, or payment failures as webhooks, downstream systems can react in near real-time without hammering the billing system with constant polling.
A few concrete scenarios where webhooks shine in telecom:
TelcoEdge Inc. has made event-driven billing a core part of their pitch, particularly for operators moving toward real-time charging in 5G environments where latency in billing events can directly affect service delivery.
The Honest Trade-offs
Here’s where it gets real. Webhooks sound great until you have to operate them at scale.
Reliability is your problem now. With REST, if the call fails, you retry it. With webhooks, if your endpoint is down, you might miss events. You need dead letter queues, retry logic with exponential backoff, and idempotency on the receiving end. Billing events especially you cannot process a “payment received” webhook twice.
Ordering isn’t guaranteed. Events can arrive out of order. A “balance depleted” event and a “top-up received” event for the same subscriber might arrive in the wrong sequence depending on network conditions and load. Your consuming system has to handle that gracefully.
Security surface is different. With REST you control who calls you. With webhooks, someone’s pushing data to a URL you’ve exposed you need signature verification, TLS, and ideally IP allowlisting. Most mature billing platforms handle this well; Comarch’s telecom billing stack, for example, includes webhook signature mechanisms, but you still have to implement verification on your end.
Debugging is harder. A failed REST call gives you an immediate 4xx or 5xx and a stack trace. A missed webhook event might not surface until a customer complains their service wasn’t restored after topping up.
REST has its own pain points too polling overhead, rate limits, and the tendency for systems to build up nasty polling loops “just to be safe.” Plenty of telecom backends have been brought to their knees by clients polling every 5 seconds for account changes.
What Hybrid Actually Looks Like in Practice
Most real telecom billing integrations end up using both, and that’s not a cop-out answer it’s just how the problem decomposes.
A typical pattern: REST for writes (provisioning, plan changes, payment posts) and synchronous reads (account details, balance checks on demand), webhooks for async events (threshold alerts, session events, fraud signals, payment confirmations).
Qvantel’s cloud-native BSS architecture explicitly supports this their platform exposes REST for management operations and publishes events via webhooks or Kafka topics for real-time operational flows. That kind of separation makes the integration surface much cleaner.
The trend in 5G and cloud-native BSS is pushing more toward event-driven, but REST isn’t going anywhere. It’s still the right tool for structured, transactional interactions where you need a confirmation before proceeding.
Practical Advice If You’re Evaluating This
If you’re currently building or evaluating an integration with a telecom billing system:
The REST vs. webhooks question in telecom billing isn’t really a competition. It’s about understanding what each mechanism is good at and matching it to the problem. Synchronous, transactional, confirmed operations belong on REST. Asynchronous, time-sensitive, event-driven reactions belong on webhooks. Build both into your integration design and you’ll be in much better shape than teams that went all-in on one approach and spent months retrofitting the other.