Beyond the Hype: How Google I/O 2026 Secretly Democratized Production-Ready AI Agents with Managed Sandboxes.

While the tech world is hyping up consumer benchmarks from Google I/O, backend engineers are missing the real architectural leap. Google quietly solved the ultimate agentic nightmare—untrusted code execution—by baking native, ephemeral, and air-gapped Linux sandboxes straight into their SDK. Here is a look at the DevOps infrastructure you no longer have to build yourself.📝

The Core Problem: The Architectural Nightmare of Untrusted Code To appreciate Google’s update, we must look at the current state of building code-executing AI agents
[1].If you tell a model to “analyze this CSV and generate a chart,” it cannot just output text [1]. It needs to write Python code, install libraries, and run the script [1].For a backend engineer, letting an LLM execute arbitrary code on a server is the ultimate security nightmare. Building a secure, in-house environment to handle this introduces three massive architectural roadblocks.1. The Container Lifecycle Trap (Docker Management)Managing Docker containers programmatically at scale is a DevOps quagmire.The Reality: You must build a custom queue system to spin up containers on demand.The Friction: Containers must be provisioned instantly to avoid killing user experience.The Payload: Keeping a pool of warm containers active destroys your cloud budget.The Cleanup: You have to write complex garbage collection logic to ensure dead containers are completely wiped and destroyed after every session.

  1. The Sandbox Prison (Resource Throttling)An LLM can easily generate a broken loop or an overly aggressive script, either by accident or via prompt injection.The Risk: A infinite while loop will instantly peg your CPU at 100%.The Threat: A script could attempt to allocate gigabytes of memory, triggering Out-Of-Memory (OOM) killer events that take down adjacent services.The Nightmare: You are forced to configure complex cgroups, kernel-level resource limits, and aggressive execution timeouts just to keep a single rogue agent from crashing your entire cluster.
  2. Air-Gapping the Network (Networking Locks)An AI agent running code must be completely blind to your internal network.The Vulnerability: Without strict network isolation, a compromised agent can scan your internal ports.The Data Leak: It can reach out to your internal databases, call private microservices, or scrape cloud metadata endpoints (like AWS IAM or Google Cloud metadata).The Overhead: Securing this requires meticulous VPC configuration, strict network security policies, and total air-gapping. This leaves the agent completely blind, making it incredibly difficult to securely fetch the legitimate external dependencies (like npm or pip packages) it actually needs to do its job.

Beyond the I/O Sugar Rush: Why the Real Breakthrough is Infrastructure It is easy to get swept up in the immediate Google I/O sugar rush. The tech headlines are rightfully dominated by the flashy consumer milestones: the raw speed of Gemini 3.5 Flash, the uncanny multimodality of the Gemini Omni model, and the cinematic realism of Veo 3.But as backend engineers, we know that benchmark charts and text-to-video demos don’t build stable production systems. While the frontend community marvels at what these models can say, the real architectural leap lies in how Google is finally allowing them to execute. Away from the main stage, the truly revolutionary update isn’t a smarter model—it is the secure, isolated infrastructure built to run them.

No hyper-focusing on flashy consumer-facing releases like Gemini 3.5 Flash, the Gemini Omni multimodal model, and Veo 3, developers are missing the foundational shift happening in the backend. My entry is on isolated sandbox provisioning and runtime environments.

What most people are Overlooking/
The most underrated announcement is the native Sandbox Provisioning and Agent Harness Infrastructure built to run AI agents like “Jules” (Google’s new AI for coding).

Instagram
(Kyerimen).
Most developers look at coding agents and see text generation. A highly analytical submission should expose the actual engineering bottleneck Google solved: execution safety and orchestration.
A few can write an article reviewing Gemini 3.5 benchmarks. High-value entries analyze how software runs. Google is now firing up isolated Linux VMs with a fresh filesystem for agent execution on demand.
Zero-Configuration DevOps: Previously, if a developer wanted to build a secure coding agent that writes, tests, and executes code safely, they had to spend weeks configuring complex Docker files and gVisor isolation barriers. Google has quietly baked this heavy-lifting DevOps infrastructure directly into their developer console tools.
The Embedded “Critic” Layer: This underlying runtime environment includes a hidden, baked-in reasoning loop that uses a secondary verification layer to catch logic errors before returning agent outputs to a developer’s codebase

I say that the real architectural leap happened in a 90-second developer keynote demo regarding how agents actually execute code safely.
The Deep Dive—The Managed Agent Sandbox: Explain how Google’s system spins up automated Linux sandboxes, executes tasks, applies a built-in code reviewer loop, and safely tears down the state in under two minutes.
Why It Matters is ,,,”that this completely eliminates the need for developers to engineer complex backend infrastructure just to let an LLM interact with a terminal”.

The Architecture: Old vs. New Agent Execution To understand why Google’s managed infrastructure is a game-changer, we have to look at how backend engineers previously handled agentic code execution versus how Google handles it now.The Old Way (The DevOps Nightmare)Previously, letting an LLM execute code safely meant building and maintaining your own complex, high-latency containment layer:
[User Request]
│
▼
[Your Backend App] ──(API Call)──► [Stateless LLM]
│ │
(Receives Code) (Returns Code String)
│ │
▼ ◄┘
[Custom Docker Queue]
│
├─► [gVisor / Sandbox Isolation]
├─► [Resource Throttling Monitor]
└─► [State Serialization Middleware]

The New Way (Google’s Ephemeral Agent Sandbox)Google eliminates the middle tier. Your backend remains thin and secure, delegating the risky, stateful execution to a managed, isolated runtime:
[Your Backend App] ──(Single SDK Call)──► [Google Agentic Infrastructure]
│
┌──────────────────────────┴──────────────────────────┐
▼ ▼
[Gemini Orchestrator] [Ephemeral Linux Sandbox]
│ │
├─► (Generates Code Script) ─────────────────────────►├─► (Executes in Isolation)
│ ├─► (Maintains Local State)
◄─ (Intercepts Runtime Errors for Self-Correction) ───┤
│ ▼
└───────────────────(Returns Safe Output)────────► [Tears Down Sandbox]
The Architectural Data Flow The Hand-Off: Your backend triggers a task via the SDK. You do not provision servers, manage container lifecycles, or configure networking rules.The Ephemeral Spin-Up: Google instantly provisions an isolated, restricted Linux sandbox with a local file system dedicated to that specific session.The Local Feedback Loop: The agent writes code directly to this local environment. If a execution error occurs, a secondary verification layer (the “Critic”) catches the standard error (stderr) and pipes it back to the agent for autonomous debugging.The Safe Return & Burn: Once the task is successfully completed, the final validated output is sent to your backend, and the entire sandbox environment is immediately destroyed. –>

The Killer Assumption Test: How to Spot Doomed Product Decisions Before You Ship

Every product decision rests on at least one assumption that, if wrong, makes the entire effort pointless. I call this the “killer assumption.”

Most PMs don’t name it. They build, ship, and then explain why the metric didn’t move.

Here’s how to find the killer assumption before it finds you.

What Is a Killer Assumption?

A killer assumption is the single belief that has to be true for your product decision to be correct. Not all the assumptions — the one that matters most.

For example:

  • You’re building a notification feature to increase re-engagement. The killer assumption: “Users are disengaging because they forget about the product, not because they lost interest in it.”
  • You’re redesigning onboarding to improve activation. The killer assumption: “Users who drop off during onboarding are doing so because the flow is confusing, not because the product doesn’t match what they expected.”

Notice how in both cases, if the killer assumption is wrong, the entire effort is wasted — regardless of how well you execute.

Why PMs Don’t Surface It

There are a few reasons this happens:

1. Assumption naming feels like admitting uncertainty. Teams want to project confidence in their roadmap. Saying “here’s the one thing we’re betting on” feels like weakness. It’s actually the opposite — it’s intellectual honesty that enables faster learning.

2. The assumption is buried in the framing. When a PM writes “users need better search,” the killer assumption (“search is what’s blocking user success”) is hidden inside the solution statement. If you never separate problem from assumption from solution, you never see it clearly.

3. Everyone already agrees on it. The most dangerous assumptions are the ones that feel obviously true to the whole team. Consensus doesn’t validate assumptions. It just means nobody challenged them.

The 3-Question Test

Before committing to any significant product decision, answer these:

Q1: What would have to be true for this to work?
Write down everything. Then circle the one that, if false, would invalidate all the others.

Q2: How confident are we in that assumption, and why?
Not “pretty confident” — name the specific evidence. If you can’t, name what evidence you’d need.

Q3: What’s the cheapest way to test it before we build?
A customer interview, a landing page, a prototype, a manual experiment. The answer almost always exists. The question is whether the team is willing to slow down enough to run it.

The 4-Step Framework

This is one piece of a broader decision-making process I use with PM teams:

  1. Name the decision (not the feature, the actual decision being made)
  2. Define success criteria upfront (“We’ll know this worked if X moves from A to B by date”)
  3. Find the killer assumption (the one thing that has to be true)
  4. Set a review date (when will you revisit, and under what trigger conditions)

The killer assumption step is where most teams short-circuit. They move from step 1 directly to step 4, skipping the thing that would tell them whether step 1 was even the right question.

A Real Pattern I’ve Seen

At iQIYI, we had a team convinced that improving content discovery would increase weekly active usage. The killer assumption was: “Users who are inactive aren’t finding content they want.”

Running a 2-week test on a sample segment showed the actual pattern: users were finding content fine — they were just finishing their shows and not receiving a compelling “next series” recommendation at the right moment. Completely different problem. Completely different solution.

The original discovery feature would have taken a quarter to build. The recommendation timing fix took two weeks.

Naming the killer assumption before building saved about 10 weeks of engineering time.

The Discipline

The skill isn’t finding the assumption — it’s getting comfortable naming it out loud before you build, and being willing to run a cheap test before you commit.

Teams that do this ship less and learn more. That’s not a bad trade.

If you want the full framework with templates for running this process on your team, I put it in a short handbook: A 4-Step System for Analyzing Any Product Problem

Stop Describing Your Bugs — Just Screenshot Them

This is a submission for the Gemma 4 Challenge: Build with Gemma 4

What I Built
BugLens is an AI-powered screenshot debugger for developers. You upload a screenshot of any bug, error message, or broken UI, and Gemma 4 instantly analyzes it and returns a structured diagnosis — including the error type, severity, root cause, affected area, a step-by-step fix, and prevention tips.
No more copy-pasting stack traces or describing your screen to a chatbot. Just screenshot and drop it in.

Demo

Code

GitHub logo

Chris-code-tech
/
buglens

My Gemma 4 challenge project

BugLens 🔬

An AI-powered screenshot debugger built with Gemma 4. Upload a screenshot of any bug, error message, or broken UI — BugLens analyzes it and returns a structured diagnosis in seconds.

Built for the Gemma 4 Challenge.

What it does

Drop in any error screenshot and BugLens returns:

  • Error Type — what kind of bug it is
  • Severity — High / Medium / Low
  • Root Cause — why it’s happening
  • Affected Area — what part of the code is involved
  • How to Fix — step-by-step solution with code examples
  • Prevention — how to avoid it in the future

How it works

BugLens sends your screenshot directly to Gemma 4 31B Dense (gemma-4-31b-it) via the Google AI Studio API. The model reads the image, reasons about the error, and returns a structured analysis parsed into clean UI cards.

Getting started

  1. Clone the repo
  2. Open index.html in your…

How I Used Gemma 4
BugLens is powered by Gemma 4 31B Dense (gemma-4-31b-it) via the Google AI Studio API. I chose the 31B Dense model because visual debugging demands strong reasoning — the model needs to read error text in screenshots, understand code context, and produce actionable output all in one pass.
Gemma 4’s multimodal capability is the entire backbone of the app. Every analysis request sends the screenshot directly to the model as an inline image alongside a structured prompt, and the response is parsed into categorized cards in the UI. Without Gemma 4’s vision and reasoning power, the app simply doesn’t work — it’s not a wrapper, it’s the engine.

# I Built an AI Website Builder and Here’s What Actually Happened

I’ve been wanting to build something with AI for a while now. Not just a wrapper around ChatGPT, but something that actually feels useful. So I built CrafticWeb — you describe a website, and it generates real HTML/CSS/JS for you. You can tweak it with follow-up prompts, edit the code directly, preview it live, and deploy it with one click.

It’s live, it works, and I learned a ton building it. Here’s the honest story.

The Idea

The core concept is simple. You type something like “a landing page for a coffee shop with a dark theme” and the app sends that to an AI model (DeepSeek via OpenRouter), gets back a full HTML document, and renders it in the browser instantly. You can keep chatting to refine it, open it in a Monaco editor to manually tweak things, and when you’re happy — deploy it to a public URL.

I also added Google login, a credits system, and Stripe billing because I wanted to build something that felt like a real product, not just a weekend demo.

The Stack

For the frontend I went with React + Vite, Redux for state, Tailwind for styling, Framer Motion for animations, and Monaco Editor for the in-browser code editor. The backend is Node.js + Express, MongoDB for storage, JWT with httpOnly cookies for auth, and OpenRouter to talk to the AI. Stripe handles billing.

Nothing too exotic. The interesting stuff is in how it all fits together.

What Actually Broke (And How I Fixed It)

Getting the AI to return clean JSON

This was my first real headache. The backend sends a master prompt to DeepSeek via OpenRouter and expects back a clean JSON object like this:

{
  "message": "Your website is ready",
  "code": "<full HTML document>"
}

Simple enough in theory. In practice, the model kept wrapping its response in markdown code fences — you know, the triple backtick blocks — which meant JSON.parse() would just throw and the whole thing would fail. My fix was a small utility function that strips out those fences before parsing, and if the JSON is still broken, the backend retries the API call up to three times. Once I had that in place, generation became reliable.

Rendering the preview without CORS exploding

My first attempt at the live preview used srcdoc to inject HTML into an iframe. Vite did not like that. It kept injecting its own scripts into the content and everything would break with CORS errors.

The fix was switching to Blob URLs. Instead of passing the HTML as a string attribute, you create a Blob from it, generate a local object URL, and point the iframe’s src at that:

const blob = new Blob([html], { type: "text/html" });
const url = URL.createObjectURL(blob);
iframeRef.current.src = url;

The browser treats it like a local file, completely sandboxed, no CORS, no Vite interference. One small change, completely solved it.

Authentication Flow

Google Auth looks simple from the outside but there are a few moving pieces. Here’s the full flow:

  1. User clicks “Continue with Google”
  2. Firebase signInWithPopup returns the user’s info
  3. Frontend POSTs { name, email, avatar } to /api/v1/auth/register
  4. Backend creates or finds the user in MongoDB, generates a JWT, and sets it as an httpOnly cookie
  5. All subsequent requests send the cookie automatically via withCredentials: true

On the frontend every Axios call goes out with credentials attached:

axios.defaults.withCredentials = true;

And on the backend the cookie is set like this:

res.cookie("token", jwt, {
  httpOnly: true,
  secure: true,
  sameSite: "none",
});

The httpOnly flag means JavaScript on the client can never read the token directly — much safer than storing it in localStorage. And sameSite: 'none' + secure: true is what makes the cookie actually travel cross-origin between your deployed frontend and backend.

Cookies not working after deployment

This one burned me for an embarrassingly long time. I deployed to Render, everything looked fine locally, and then authenticated requests just stopped working in production. The cookie was being set, but the browser wasn’t sending it back with requests.

Turned out I needed two things together: sameSite: 'none' and secure: true on the cookie, and NODE_ENV=production set in Render’s environment variables. Without that last one, the backend was still behaving like it was in development mode and the production cookie settings never kicked in. Once both were set, it worked perfectly.

Google OAuth popup silently failing

Firebase’s signInWithPopup was failing with auth/popup-closed-by-user even when the user hadn’t closed anything. After digging around I found the culprit — a Cross-Origin-Opener-Policy header I’d added to the backend. It was preventing the OAuth popup from communicating back to the parent window. Removing that header fixed it completely.

The Thing I’m Most Proud Of

Honestly? The credits and billing system. It felt intimidating before I built it, but it’s pretty clean now. Stripe Checkout handles the payment UI, Stripe Webhooks confirm the payment server-side and add credits to the user’s account in MongoDB, and credits get deducted on each successful generation. The one thing I’d warn anyone about — use express.raw() as the body parser for your webhook route, not express.json(). The second one breaks Stripe’s signature verification and you’ll spend an hour wondering why webhooks aren’t firing.

What’s Next

I want to add streaming so the HTML appears progressively instead of all at once after a delay — that would make it feel way snappier. Version history is on the list too, so you can go back to an earlier generation if you over-prompted yourself into a mess.

If you want to check it out or dig into the code, it’s all open source.

👉 GitHub: github.com/KunalChakraborty445/Crafticweb

🌐 Live Demo: crafticwebai-beta.onrender.com

Built with too much console.log and not enough sleep — Kunal

webdev #javascript #react #nodejs #ai #buildinpublic #opensource #fullstack

Cooking an AI Campaign in 5 Minutes with Google Cloud AI APIs

About a month or so ago, during the Build with AI season, Google Developer Groups Johannesburg in South Africa hosted a build-a-thon with a concept I genuinely loved.

The whole concept was structured like a kitchen lab, with a key focus on local small businesses . Small to medium sized businesses dominate Southern Africa, so when I first read and saw the post i could instantly relate.

I loved the idea of turning code into usable business tools and a buildathon where we could be cooking up ideas together.

Different ingredients. Different flavours. Different tools. Immense impact!

I was excited to share the tutorial before the buildathon, but life and timing happened. So instead of letting the project sit in a notebook, I decided to turn it into an article anyone can follow, as they experiment with AI-powered marketing workflows.

But before we get technical, let me explain why I chose to build a multilingual marketing pipeline using Google Cloud AI tools.

There is a bigger vision here. This isn’t just about generating automated ads. It’s about creating systems where entrepreneurs can describe what they sell, define their audience, click a few buttons, and instantly receive dynamic, multilingual marketing assets they can actually use for one of the biggest advertising platforms, Radio, hence the audio content in local languages.

This project is simply the appetizer, a baseline and starting point for builders.

If AI can help market sneakers in multiple South African languages, what stops a small business from doing the same for lipstick, skincare, jewellery, furniture, or handmade products?

The Recipe: One Prompt, Multilingual Radio Copy

Colab Notebook Link: https://colab.research.google.com/gist/DeliaRudy/7e989ab921036166acdc43289022941a/business_story_telling.ipynb

The lab focuses on a simple workflow:

  1. A user describes their product or campaign idea.
  2. Gemini refines the marketing message.
  3. Google Text-to-Speech converts it into audio.
  4. Translation tools localise the campaign into multiple languages.
  5. Additional models extend multilingual support even further.

Instead of creating separate campaigns manually, the system helps generate a full multilingual experience from a single idea.

And honestly, this is where things became exciting for me.

Because many SMEs struggle with one major thing:

Creating consistent marketing content repeatedly.

Not because they lack creativity.

But because content creation takes time, resources, voiceovers, editing, localisation, and strategy.

AI changes that workflow dramatically without hurting their bottomline.

Step 1: The Prep Work (Gemini as the Brain)

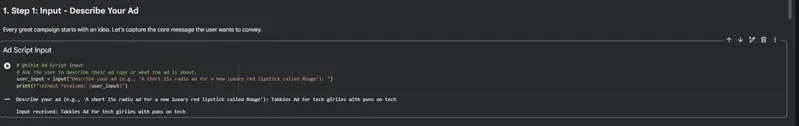
Every campaign starts with an idea. We start by taking a simple user input (e.g., “Takkies Ad for tech girlies with puns on tech”) and passing it to Gemini on Vertex AI to act as our creative partner.

We use gemini-2.5-flash to structure this raw idea into a professional 15-second radio script.

import vertexai
from vertexai.generative_models import GenerativeModel

# Initialize Vertex AI (assume PROJECT_ID and LOCATION are set)
vertexai.init(project=PROJECT_ID, location=LOCATION)

model = GenerativeModel("gemini-2.5-flash")

Step 2: The Flavor Profile (Translation with Context)

For radio advertisemnets, language matters deeply. People connect differently when they hear something in a language that feels familiar to them. For this lab, we focused on English, Afrikaans, isiZulu, and isiXhosa.

You can use the standard Cloud Translation API for bulk text or use an LLM like Gemini. The notebook highlights these as option A and B. In my opinion using Gemini allows for more context-aware, creative translations that preserve the “vibe and energy” of the ad.

# @title Translation using the Cloud Translation API - Option A

from google.cloud import translate_v2 as translate

translate_client = translate.Client()
languages = {
    'af': 'Afrikaans',
    'zu': 'Zulu',
    'xh': 'Xhosa'
}

llm_translations = {}

for lang_code, lang_name in languages.items():
    prompt = f"Translate the following marketing script into {lang_name}. Keep the tone professional yet catchy for a South African audience: {english_script}"

    response = model.generate_content(prompt)
    llm_translations[lang_code] = response.text

    print(f"--- {lang_name} (Gemini) ---")
    print(response.text)

   # @title Translation using Gemini (Vertex AI) - Option B

llm_translations = {}
for lang_code, lang_name in languages.items():
    prompt = f"Translate the following marketing script into {lang_name}. Keep the tone professional yet catchy for a South African audience: '{english_script}' output should be just plain text"
    response = model.generate_content(prompt)
    llm_translations[lang_code] = response.text
    print(f"--- {lang_name} (Gemini) ---")
    print(response.text)
    print()

Step 3: The Presentation (Text-to-Speech)

Now we need to plate the dish. We use the Google Cloud Text-to-Speech API to convert our generated scripts into high-quality, natural-sounding audio files.

Here is how you generate the Afrikaans version. You can wrap this in a function to loop through your translated scripts, swapping out the language_code and name (e.g., using af-ZA-Standard-A for Afrikaans).

from google.cloud import texttospeech

def synthesize_text(text, language_code, voice_name, output_filename):
    client = texttospeech.TextToSpeechClient()
    synthesis_input = texttospeech.SynthesisInput(text=text)

    # Select the voice parameters
    voice = texttospeech.VoiceSelectionParams(
        language_code=language_code,
        name=voice_name
    )

    audio_config = texttospeech.AudioConfig(
        audio_encoding=texttospeech.AudioEncoding.MP3
    )

    # Generate the audio
    response = client.synthesize_speech(
        input=synthesis_input, voice=voice, audio_config=audio_config
    )

    with open(output_filename, "wb") as out:
        out.write(response.audio_content)
    print(f"Audio content written to file '{output_filename}'")

# @title Synthesizing Afrikaans Audio
# Using the standard Cloud TTS API for Afrikaans
synthesize_text(llm_translations['af'], "af-ZA", "af-ZA-Standard-A", "ad_afrikaans.mp3")

Going Beyond the Basics: Vertex AI Model Garden

Whilst working on completing the lab, I ran into an interesting architectural challenge. While the standard TTS API is constantly expanding, it doesn’t currently offer a native voice for Xhosa (xh-ZA) and Zulu (zu-ZA). Think of a radio advert in South Africa excluding these two languages, would it fare well in Kwazulu Natal or part of the Eastern Cape?

This is where Vertex AI’s Model Garden shines, going beyond calling the gemini models and looking for open models that support text-to-speech.

Did you know: You can deploy specialized open-source models (like SeamlessM4T, which supports over 100 languages including Zulu and Xhosa) directly to an endpoint and route your specific language requests there.

What Comes Next?

Right now, this pipeline demonstrates the mechanics: prompting, refining scripts, translating content with context, and generating multilingual voiceovers.

The goal of sharing this isn’t to replace human creativity. It’s to show how easily developers can reduce the barriers that stop small businesses from showing up consistently online. Sometimes innovation doesn’t start with massive enterprise infrastructure—sometimes it starts with a build-a-thon, a simple Python script, and a community willing to experiment together in the kitchen.

Share your feedback in the comments/questions. I would love to hear what you think of this lab.

Your PM Retrospectives Are Lying to You

Every quarter, product teams hold retrospectives. Someone asks “what went well?” and “what didn’t?” The team lists bullet points. Someone writes “we should communicate better.” Everyone nods. Nothing changes.

The problem isn’t the retro format. It’s that you never defined what success looked like before the work started — so you can’t actually evaluate anything now.

I’ve run product teams at iQIYI, NIO, and Alibaba. The retrospectives that mattered had one thing in common: a pre-written success criterion that existed before any work began. Every other retro was theater.

The retrospective trap

When you define success after seeing the results, you unconsciously fit the definition to the outcome. If engagement went up 5%, that was the goal. If it went down 5%, you pivot to “we learned a lot.” The retro becomes a narrative exercise, not a learning exercise.

Real learning requires a pre-mortem question: “What would we need to see to know this worked?”

That question, answered before the sprint starts, is the only thing that makes a retrospective honest.

The four questions that fix retrospectives

Before any significant initiative, write answers to these four questions:

1. What is the decision we’re making?
Not “build feature X.” The actual decision: “Are we betting on engagement-led growth over acquisition-led growth this quarter?” Name it. A decision that can’t be stated in one sentence is a decision you haven’t made yet.

2. What does success look like — exactly, in advance?
One sentence. Measurable. Time-bound. Not “improve retention” but “increase D30 retention from 22% to 28% by July 15.” If you can’t write this before you start, you’re not ready to start.

3. What’s the killer assumption?
Every initiative rests on one belief that, if wrong, invalidates the whole effort. Find it. Name it. Write it down. “We’re assuming that power users are churning because of the onboarding flow, not the core product.” If that’s wrong, no amount of onboarding optimization saves you.

4. When is the assumption review date?
Not the ship date — the date you’ll check whether the assumption held. Six weeks post-launch, you open the document and ask: did the metric move? Did the assumption prove correct? This is the only retrospective question that matters.

What honest retrospectives look like

With pre-written criteria, your retro becomes a one-page debrief:

  • Did the metric hit the target? (Yes/No, with data)
  • Did the killer assumption hold? (Yes/No, with evidence)
  • What does this tell us about the next decision?

That’s it. No “communication” bullet points. No vague learnings. Just a clear verdict on whether the bet you made was right, and what you now know that you didn’t before.

The teams that compound the fastest aren’t the ones that ship fastest. They’re the ones that learn fastest — and learning requires knowing what you were trying to prove before you tried to prove it.

I built a complete 4-step decision framework around this: https://dcljoyful.gumroad.com/l/toPM

How I Built a Free, Self-Hosted Pipeline That Auto-Generates Faceless YouTube Shorts

Every “AI YouTube” tutorial ends the same way: sign up for ChatGPT Plus, then ElevenLabs, then Pictory, then n8n Cloud. Add it up and you’re paying $75–100/month before you’ve made a single video — let alone a single dollar.

I didn’t want a subscription stack. I wanted something that ran on my own machine, used free tiers and local models, and that I actually owned. So I built it, and I just open-sourced it under MIT.

It’s called FreeFaceless, and it takes one command to go from nothing to an uploaded Short:

script → voiceover → captions → b-roll → assembled video → YouTube upload

Repo: https://github.com/nils44344/FreeFaceless

Here’s how each stage works — and the one bug that cost me an evening.

The orchestration

The whole thing is a linear pipeline. Here’s the heart of it (trimmed):

def run_once(publish_at=None, upload_to_youtube=True):
    data = script.generate()                          # 1. Groq writes the script
    voice_mp3 = voice.synth(data["full_text"], ...)   # 2. edge-tts voiceover
    words = captions.transcribe_words(voice_mp3)      # 3. local Whisper timing
    scenes = visuals.fetch_for_scenes(data["scenes"]) # 4. Pexels b-roll
    ass = captions.write_ass(words, ...)              # 5. caption file
    final = assemble.build(scenes, voice_mp3, ass, …) # 6. ffmpeg
    if upload_to_youtube:
        upload.upload_video(final, data["title"], …)  # 7. YouTube Data API

Every stage is its own module, and everything is driven by a single config.yaml — so changing the niche, voice, or caption style is an edit, not a code change.

1. Script generation — Groq (free tier)

Groq’s free tier serves Llama 3.3 70B fast, and it’s OpenAI-compatible, so the official openai SDK works by just pointing the base URL at Groq:

from openai import OpenAI
client = OpenAI(api_key=GROQ_API_KEY, base_url="https://api.groq.com/openai/v1")

resp = client.chat.completions.create(
    model="llama-3.3-70b-versatile",
    response_format={"type": "json_object"},  # forces clean JSON
    messages=[{"role": "system", "content": SYSTEM_PROMPT}, ...],
)

The prompt asks for a hook + 4–6 facts + a CTA, returned as JSON with per-scene visual_query strings I can feed straight to stock search. JSON mode means no fragile regex parsing.

2. Voiceover — edge-tts (free, no key)

edge-tts exposes Microsoft’s neural voices for free, no API key:

import edge_tts
communicate = edge_tts.Communicate(text, "en-US-ChristopherNeural", rate="-12%")
await communicate.save("voice.mp3")

The quality is genuinely good enough for faceless content, and there are dozens of voices/accents to match the niche.

3. Word-level captions — faster-whisper (local)

This is the part most paid tools charge per-minute for. faster-whisper runs locally on CPU and gives word-level timestamps, which I turn into karaoke-style captions:

from faster_whisper import WhisperModel
model = WhisperModel("base", device="cpu", compute_type="int8")
segments, _ = model.transcribe("voice.mp3", word_timestamps=True)

Then I write an ASS subtitle file, 3 words at a time, in a big bold style — the look every Shorts channel uses. (FreeFaceless ships the open-licensed Anton font so it works out of the box.)

4. B-roll — Pexels (free API)

Each scene’s visual_query becomes a Pexels Videos search, pulling vertical clips. Free API, generous limits.

5. Assembly — ffmpeg

ffmpeg crops every clip to 1080×1920, concatenates them to match the voiceover length, overlays the audio, and burns in the captions:

"-vf", f"subtitles='{ass_path}':fontsdir='{fonts_dir}'"

6. Upload — YouTube Data API

OAuth desktop flow, token cached after the first browser login, then every future run refreshes silently. Supports immediate or scheduled publishing.

The bug that cost me an evening: SSL on Windows

On my machine, every HTTPS call died with CERTIFICATE_VERIFY_FAILED. The culprit: antivirus doing TLS interception with a custom root cert that Python’s bundled certifi doesn’t know about. The fix is one import, before any network client is built:

import truststore
truststore.inject_into_ssl()  # use the OS cert store instead of certifi

If you build anything network-heavy on Windows, keep this in your back pocket.

Honest limitations

  • Free tiers are rate-limited. This is built for one channel on a normal schedule, not bulk farms. Push it hard and you’ll hit limits.
  • Windows-first. The Python core runs anywhere; the helper scripts are PowerShell. Cross-platform PRs very welcome.
  • It’s a production tool, not a money machine. It automates making videos. Views and revenue depend on your content and the algorithm — no tool changes that.

Try it / contribute

The repo has a full setup guide (including the Google OAuth walkthrough, which is the only fiddly part):

https://github.com/nils44344/FreeFaceless

If it’s useful, a star helps other people find it — and I’d genuinely love feedback, especially on making the setup smoother for non-developers and getting it running on macOS/Linux.

TypeScript 54 to 58: The Features That Actually Matter in 2026

TypeScript 5.4 to 5.8: The Features That Actually Matter in 2026

I’ve been tracking TypeScript releases for 3 years. Most release notes are noise — “improved inference in corner cases” doesn’t change how you write code. Here’s what actually matters from the last 6 TypeScript versions: the features I’ve incorporated into my daily workflow, with practical examples.

Disclosure: This article contains affiliate links. If you sign up through the links above, I may earn a commission at no additional cost to you.

TypeScript 5.8: The Latest Features That Ship Today

1. infer in Template Literal Types (Finally Fixed)

Template literal types introduced infer for extracting parts of string types. But the original implementation was buggy — it would infer never in certain conditions.

// Before 5.8: problematic
type ExtractRoute<T> = T extends `${infer Method} ${infer Path}` 
  ? { method: Method; path: Path } 
  : never;

// In 5.8, this actually works reliably
type Route = ExtractRoute<'GET /api/users'>;
// { method: "GET"; path: "/api/users" }

// Practical example: type-safe API router
type Method = 'GET' | 'POST' | 'PUT' | 'DELETE';
type RouteConfig = `${Method} ${string}`;

function registerRoute<T extends RouteConfig>(route: T, handler: () => void) {
  const [method, path] = route.split(' ') as [Method, string];
  console.log(`Registering ${method} ${path}`);
}

registerRoute('GET /users', () => {});
registerRoute('POST /users', () => {});
// registerRoute('PATCH /users', () => {}); // Error: 'PATCH' not assignable to Method

2. Strict-Flag-by-Flag Configuration

You can now enable specific strict checks without enabling all of them:

{
  "compilerOptions": {
    "strictNullChecks": true,
    "noUncheckedIndexedAccess": true,
    "exactOptionalPropertyTypes": true
  }
}

The practical impact: you can incrementally adopt strictness. Start with strictNullChecks (the most valuable), then add others as you fix issues.

3. Default Type Parameters in Conditional Types

// Before: had to use distributive conditional types
type MaybeArray<T> = T extends any ? T[] : never;

// Now: cleaner with defaults
type MaybeArray<T, Fallback = T[]> = T extends any ? T[] : Fallback;

// Usage:
type A = MaybeArray<string>;      // string[]
type B = MaybeArray<string, null>; // string[] (no change here, but the mechanism works)

TypeScript 5.6: The Release That Flew Under the Radar

1. Iterator Helper Methods

TypeScript 5.6 introduced iterator helpers — methods on iterators that mirror Array methods:

// Before: had to convert to array to use .map(), .filter()
function* generateNumbers() {
  yield* [1, 2, 3, 4, 5, 6, 7, 8, 9, 10];
}

const result = Array.from(generateNumbers())
  .filter(n => n % 2 === 0)
  .map(n => n * 2);

// Now: use iterator methods directly (no intermediate array)
const result = generateNumbers()
  .filter(n => n % 2 === 0)
  .map(n => n * 2)
  .toArray();

// Works with generators too
async function* fetchPages(url: string) {
  let page = 0;
  while (page < 10) {
    const data = await fetch(`${url}?page=${page}`);
    yield data;
    page++;
  }
}

const allData = await fetchPages('/api/data')
  .filter(res => res.ok)
  .take(5)
  .map(res => res.json())
  .toArray();

2. Using Enums Are Now Strict

enum Status {
  Active = 'active',
  Inactive = 'inactive'
}

// TypeScript 5.6+: Using enum values is now strictly checked
function processStatus(status: Status) {
  // ...
}

processStatus(Status.Active); // ✅
processStatus('active'); // ❌ — now an error without explicit casting

This is a breaking change but a beneficial one. It catches a whole class of bugs where strings accidentally slip through.

TypeScript 5.5: Performance and Inference Improvements

1. Inferred Type Predicates

The most impactful quality-of-life improvement in recent releases:

// Before 5.5: TypeScript couldn't narrow array.filter() results
function isString(value: unknown): boolean {
  return typeof value === 'string';
}

const mixed: (string | number)[] = ['hello', 42, 'world', 100];

// TypeScript couldn't narrow this — result was (string | number)[]
const strings = mixed.filter(isString);

// With 5.5: TypeScript understands type predicates
// strings is correctly typed as string[]

This works when your type guard function returns a type predicate (value is Type). TypeScript now infers this from the implementation, not just the return type annotation.

2. Regular Expression Syntax Checking

// TypeScript 5.5+ validates regex literals
const emailRegex = /^[a-z]+@[a-z]+.[a-z]{2,}$/;
// Previously: no error if you wrote d+ (valid regex but probably a typo for d)
// Now: some common mistakes are caught at compile time

TypeScript 5.4: Narrowing Without Initial Assignment

1. Type Checking in Closures After Last Assignment

let value: string | number;

if (Math.random() > 0.5) {
  value = 'hello';
} else {
  value = 42;
}

// Before 5.4: TypeScript forgot the narrowing after assignment
// you'd need to use a function to capture the narrowed type
function getValue() {
  let v: string | number;
  if (Math.random() > 0.5) v = 'hello';
  else v = 42;
  return v;
}

// Now: TypeScript tracks narrowing through closures correctly
value.toString(); // ❌ Error in 5.4+: toString exists on both, ambiguous

function logValue(v: string | number) {
  // v is narrowed inside this function
  if (typeof v === 'string') {
    console.log(v.toUpperCase());
  } else {
    console.log(v.toFixed(2));
  }
}

2. NoInfer Utility Type

// TypeScript 5.4 introduces NoInfer
function createSignal<T>(value: T, defaultValue: T): T {
  return value ?? defaultValue;
}

// Before: this would infer T from defaultValue too
// createSignal('hello', 42) would error but inference was confusing
// Now: use NoInfer to control inference direction
function createSignal<T>(value: NoInfer<T>, defaultValue: T): T {
  return value ?? defaultValue;
}

The Features I Actually Use Daily

From all these releases, here are the 5 changes that most impact my code:

1. Inferred Type Predicates (5.5)

The .filter(isString) pattern alone saves hours of typing explicit casts.

2. Iterator Helpers (5.6)

Eliminated dozens of Array.from() conversions. Generator pipelines are finally readable.

3. noUncheckedIndexedAccess (strict flag)

Every time I access arr[0] without checking length, TypeScript reminds me it could be undefined. This flag has caught real bugs.

// With "noUncheckedIndexedAccess": true
const items = ['a', 'b', 'c'];
const first = items[0]; // type: string | undefined
if (first !== undefined) {
  console.log(first.toUpperCase()); // ✅ TypeScript knows it's string here
}

4. Template Literal Types

The GET ${string} pattern for route typing is production-ready in 5.8.

type HttpMethod = 'GET' | 'POST' | 'PUT' | 'DELETE';
type Route = `${HttpMethod} /${string}`;

const routes: Route[] = [
  'GET /users',      // ✅
  'POST /users',     // ✅
  'DELETE /users/1',  // ✅
  'PATCH /users',    // ❌
];

5. Variadic Tuple Types with Inference

Building type-safe API clients:

type ApiRoute = {
  method: HttpMethod;
  path: string;
  response: unknown;
};

function createApiClient(routes: ApiRoute[]) {
  return {
    async request<M extends HttpMethod, P extends string>(
      method: M,
      path: P,
      ...args: ExtractRoute<P> extends { params: infer Params } ? [Params] : []
    ) {
      // type-safe request
    }
  };
}

The Migration Guide

Step 1: Upgrade TypeScript

npm install typescript@latest

Step 2: Enable Strict Flags Incrementally

{
  "compilerOptions": {
    "strictNullChecks": true
  }
}

Fix all errors. Then:

{
  "compilerOptions": {
    "noUncheckedIndexedAccess": true
  }
}

Step 3: Update Type Guard Functions

// Before
function isString(value: unknown): boolean {
  return typeof value === 'string';
}

// After (same code, but now TypeScript infers the predicate)
function isString(value: unknown): value is string {
  return typeof value === 'string';
}

Step 4: Replace Array.from() with Iterator Methods

// Before
const doubled = Array.from(generator()).map(x => x * 2);

// After
const doubled = generator().map(x => x * 2).toArray();

Should You Upgrade?

Yes. TypeScript 5.4-5.8 have accumulated enough quality-of-life improvements that upgrading from 5.0 is worth it. The inference improvements alone will reduce the amount of explicit type annotations you need to write.

Start with npm install typescript@latest, run your build, and fix errors. The strict flags are the highest-value changes — enable them even if it takes time to fix all the errors.

For developers who want to stay current with TypeScript best practices and similar tooling, check out Systeme.io for building and launching complete products with AI tools.

This article contains affiliate links. If you sign up through the links above, I may earn a commission at no additional cost to you.