Tarihi Ay görevi için geri sayım başladı: 54 yıl sonra ilk olacak
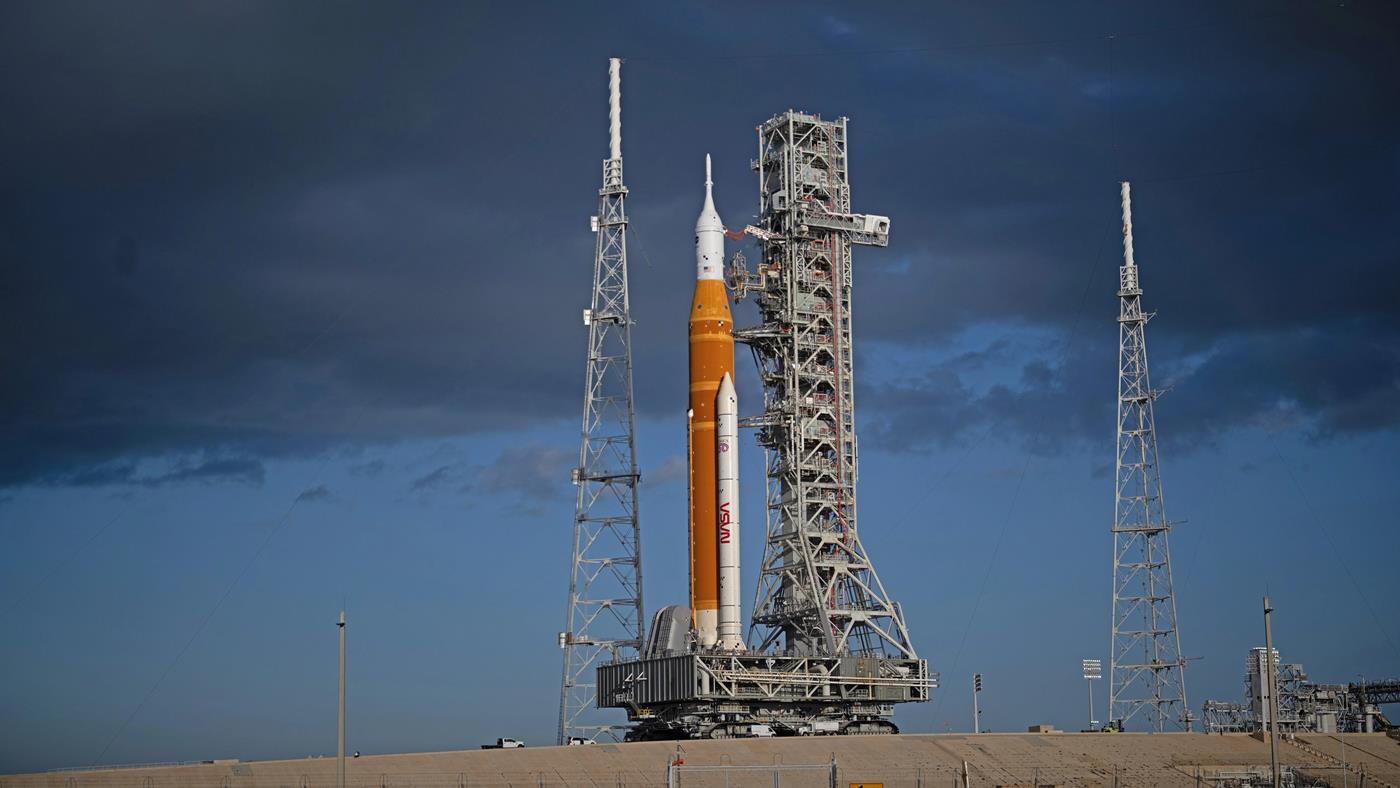
NASA, Artemis 2 görevi için yeniden geri sayıma başladı. 54 yıl sonra insanları yeniden Ay’a göndermeyi hedefleyen Artemis II görevinin 1 Nisan’da fırlatılması hedefleniyor.
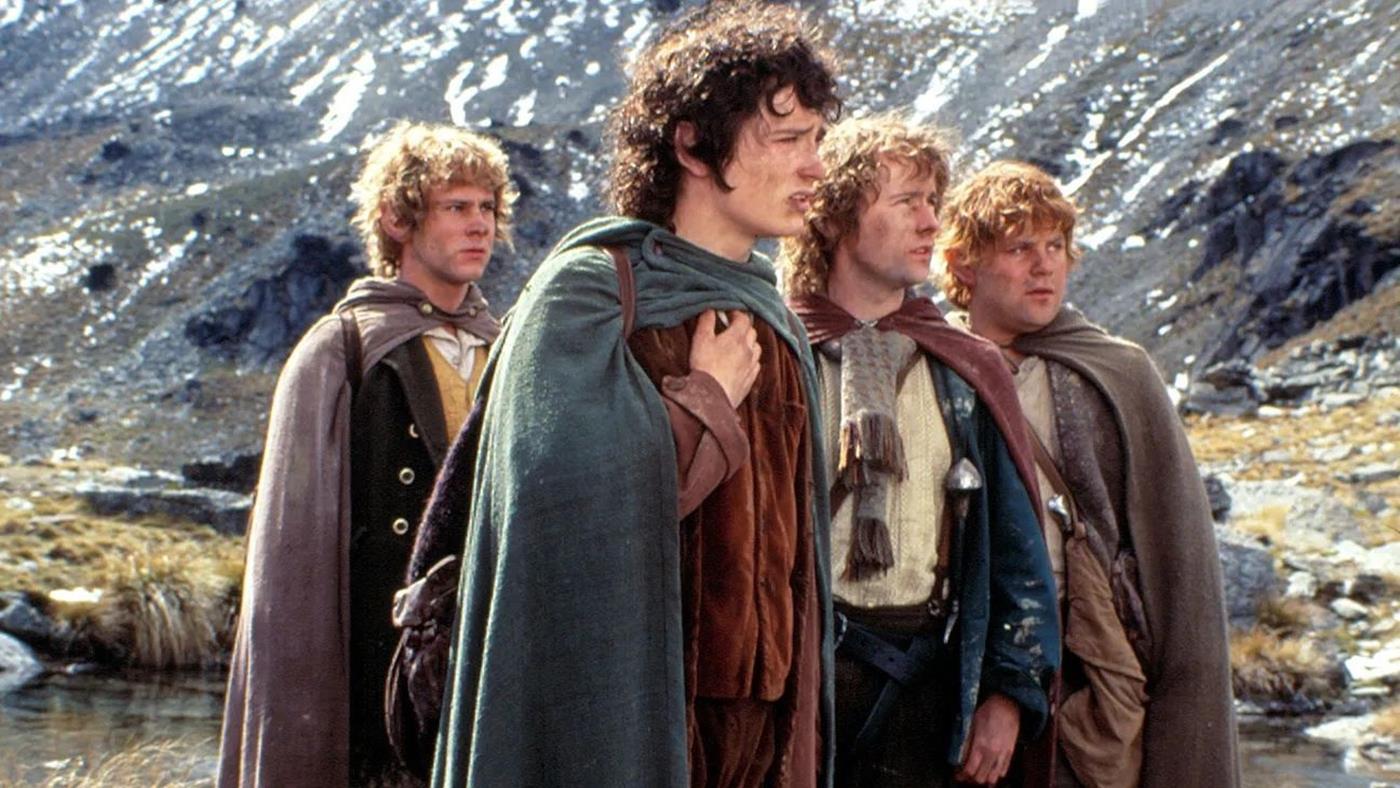
Daha önce duyurulan The Hunt for Gollum’un yanı sıra yeni bir Yüzüklerin Efendisi filmi daha hazırlanıyor. Üstelik bu yeni proje, orijinal üçlemenin devamı niteliğinde olacak.
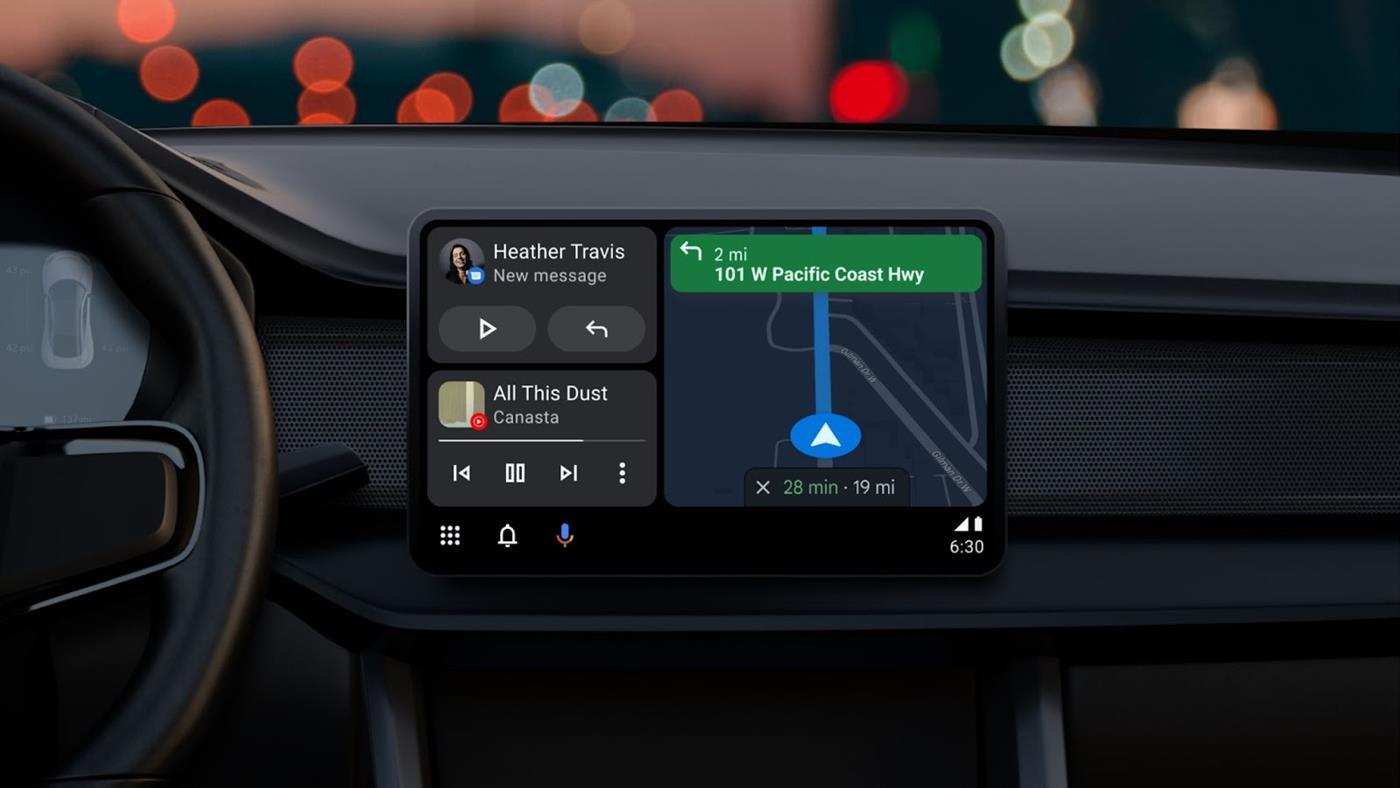
Google, araçlara yönelik Android işletim sistemini, yalnızca bilgi-eğlence sistemlerini çalıştıran bir yazılım olmaktan çıkarıp, geleceğin otomobillerinin merkezi beyni haline getirmeyi hedefliyor.
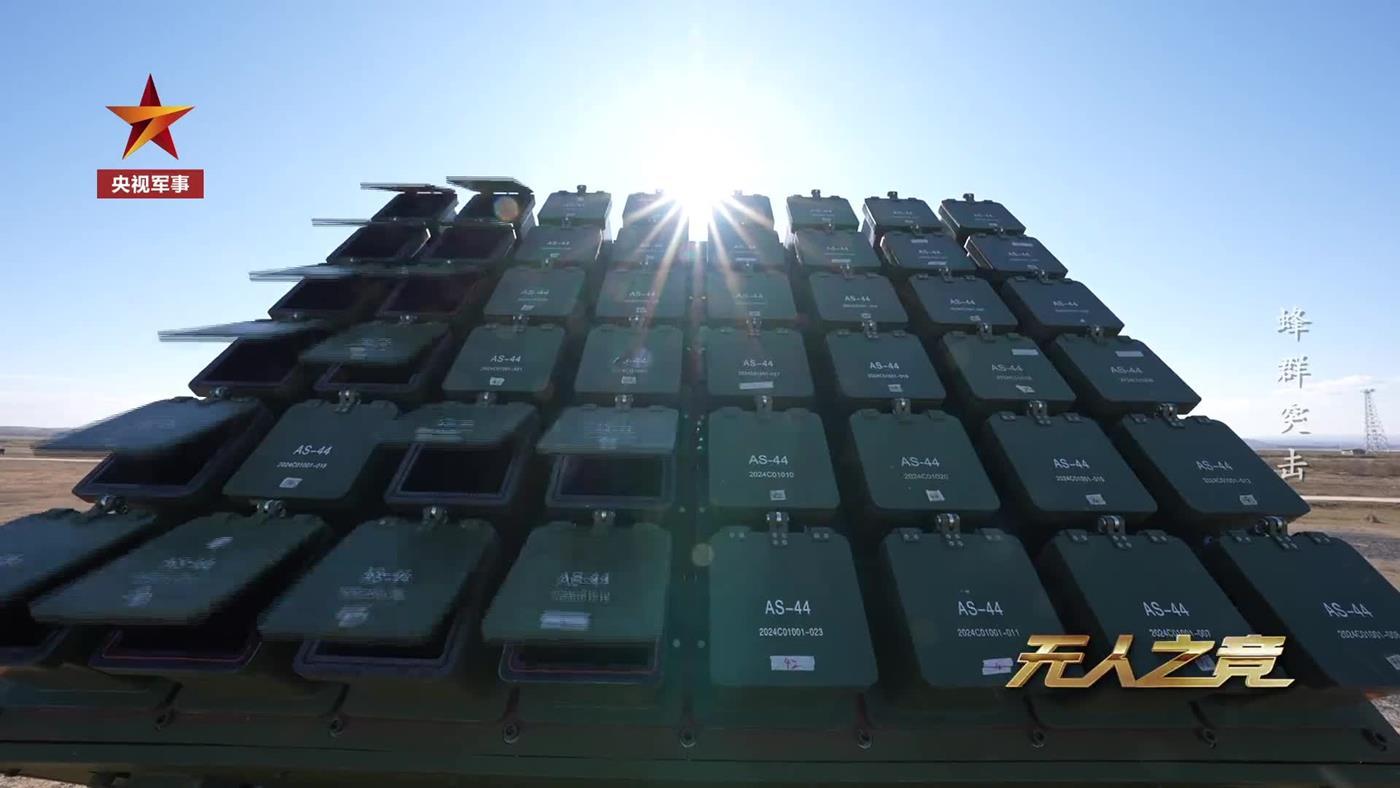
Çin, Atlas dron sürü sistemini tanıttı. Tek operatörle 96 dronu kontrol eden sistem, hassas taarruz, keşif ve elektronik harp yetenekleriyle modern savaşlarda kuvvet çarpanı oluyor.After releasing a tile calculator app (500+ downloads), I applied the same formula to paint calculation.
Tech stack:
Flutter + Riverpod (state management)
Hive (calculation history)
SharedPreferences (settings persistence)
Material 3, green #4CAF50
flutter_localizations for i18n
Key challenges:
Units system — storing metric/imperial per saved calculation was tricky. Each history record saves its own unitSystem so when you load it back, units don’t reset to current settings.
Opening deductions — supporting both standard sizes (door 2.0×0.9m, window 1.2×1.0m) and custom sizes with separate counters for each type.
Paint brand database — auto-filling coverage when a brand is selected while still allowing manual override.
The app:
Paint Calculator: Room & Wall
https://play.google.com/store/apps/details?id=com.paintcalculator.squarefeet.wallroom
Happy to answer questions about the Flutter implementation.
I spent several weeks reading the wagtail/news-template codebase for my Google Summer of Code application. This post shares what I found – what works, what is broken, and what could be better.
The wagtail/news-template homepage – dark mode enabled by default
What the starter kit is
The news-template is a Wagtail starter kit for news and media websites. It gives you article pages, topic filtering, pagination, search, and dark mode. Everything works out of the box. The design uses Tailwind CSS and is responsive.
What it does well
The content model is solid. ArticlePage supports authors, topics, publication dates, and hero images. The body is built from StreamField blocks. Editors can add sections, quotes, stats, and cards – no code needed.
The block system is flexible. FeaturedArticleBlock lets editors override an article’s image, description, and CTA text. Topic filtering works via query parameters. It is a small but thoughtful detail.
What is broken or missing
Reading the code revealed several bugs.
Newsletter signup never submitted. The email input had no name attribute. The button was an <a> tag with no connection to the input. Every visitor who tried to sign up got no result. I fixed this in PR #107.
Mobile navigation links were broken. A regression left mobile nav links with empty href="" attributes. Users were redirected back to the current page. Fixed in PR #101.
FeaturedArticleBlock had an empty template. The block defined five fields but its template was a stub. It rendered raw block data instead of HTML. Fixed in PR #103.
Missing imports caused runtime errors. slugify was not imported in utils/models.py. Pagination exceptions were missing in news/models.py. Both caused NameError crashes.
Form fields lacked label elements. Inputs had no <label> elements. This is a WCAG 2.1 AA accessibility violation. Fixed in PR #99.
Test coverage was minimal. The project had three tests before my contribution. Core models, template tags, and views had no coverage at all.
What could be added
Author profile pages with bio and social links
RSS feed for articles
Open Graph meta tags for social sharing
Multilingual support
Final thoughts
The starter kit is a strong foundation. The content model and block system are well thought out. But several core features were broken. Contributing fixes taught me more about Wagtail than any tutorial could.
If you care about statistics, machine learning, or what everyone now calls “AI” — learning linear regression well is the single most important investment you can make. Not transformers. Not diffusion models. Linear regression.
You can go as shallow as calling model.fit(X, y) and declaring you know regression. Or you can go deep — the linear algebra behind the closed-form solution, the calculus behind gradient descent, the numerical analysis behind SVD, the Gauss-Markov assumptions that tell you when least squares is optimal, Cook’s distance that reveals when one rogue data point is hijacking your entire model, and the Bayesian interpretation that turns regularisation into prior beliefs. People still write PhD theses on this subject. It runs that deep.
This post takes you through five fundamentally different algorithms for solving the same regression problem — each from a different branch of mathematics — and they all produce the exact same answer. Five roads, one destination. Along the way, you’ll build intuitions that transfer directly to neural networks, Gaussian processes, and Bayesian inference.
By the end, you’ll implement all five from scratch and understand why they agree.
Let’s Build It
Click the badge to open the interactive notebook:
Watch gradient descent iteratively converge on the least-squares solution:
Here’s the setup — a synthetic dataset with a clear linear trend plus Gaussian noise:
import numpy as np
import matplotlib.pyplot as plt
np.random.seed(42)
n = 50
X_raw = np.random.uniform(0, 10, n)
y = 2.5 * X_raw + 7 + np.random.normal(0, 2.5, n)
# Design matrix: add a column of ones for the intercept
X = np.column_stack([np.ones(n), X_raw]) # shape (50, 2)
Our goal: find $boldsymbol{beta} = [beta_0, beta_1]$ that minimises the sum of squared residuals:
The true values are $beta_0 = 7$ (intercept) and $beta_1 = 2.5$ (slope). Let’s recover them five ways.
Method 1: Normal Equation
The closed-form solution from linear algebra:
beta_normal = np.linalg.inv(X.T @ X) @ X.T @ y
print(f'Normal equation: y = {beta_normal[0]:.2f} + {beta_normal[1]:.2f}x')
Method 2: Gradient Descent
Iteratively update $boldsymbol{beta}$ in the direction that reduces the error:
def gradient_descent(X, y, lr=0.001, n_iter=500):
beta = np.zeros(X.shape[1])
history = [beta.copy()]
for _ in range(n_iter):
residuals = X @ beta - y
gradient = (2 / len(y)) * X.T @ residuals
beta -= lr * gradient
history.append(beta.copy())
return beta, history
beta_gd, gd_history = gradient_descent(X, y, lr=0.02, n_iter=1000)
print(f'Gradient descent: y = {beta_gd[0]:.2f} + {beta_gd[1]:.2f}x')
Method 3: SVD (Pseudo-Inverse)
The numerically stable route via singular value decomposition:
U, s, Vt = np.linalg.svd(X, full_matrices=False)
beta_svd = Vt.T @ np.diag(1 / s) @ U.T @ y
print(f'SVD: y = {beta_svd[0]:.2f} + {beta_svd[1]:.2f}x')
Method 4: scipy.optimize.minimize
Treat regression as a generic optimisation problem:
from scipy.optimize import minimize
def mse_loss(beta, X, y):
return np.mean((y - X @ beta) ** 2)
result = minimize(mse_loss, x0=[0, 0], args=(X, y), method='Nelder-Mead')
beta_scipy = result.x
print(f'scipy.optimize: y = {beta_scipy[0]:.2f} + {beta_scipy[1]:.2f}x')
Method 5: sklearn
The one-liner you’ll use in practice:
from sklearn.linear_model import LinearRegression
model = LinearRegression()
model.fit(X_raw.reshape(-1, 1), y)
beta_sklearn = np.array([model.intercept_, model.coef_[0]])
print(f'sklearn: y = {beta_sklearn[0]:.2f} + {beta_sklearn[1]:.2f}x')
All five produce the same answer:
The lines overlap perfectly. Every method converges to the same $boldsymbol{beta}$ because they’re all minimising the same objective — the sum of squared residuals.
What Just Happened?
Five algorithms, one answer. Let’s understand why, and where they differ.
The Normal Equation: Where the Gradient Is Zero
The mean squared error is:
Setting the gradient to zero:
Solving for $boldsymbol{beta}$:
This is exact — no iteration, no approximation. But it requires $X^top X$ to be invertible. If your features are collinear (or nearly so), the determinant is close to zero and the solution explodes numerically.
Gradient Descent: Follow the Slope Downhill
Instead of solving the equation analytically, gradient descent takes small steps in the direction of steepest descent:
where $eta$ is the learning rate. The gradient $nabla L = -frac{2}{n}X^top(mathbf{y} - Xboldsymbol{beta})$ points uphill, so we subtract it.
This is the same algorithm that trains neural networks — just applied to a simpler problem. If you understand gradient descent here, you understand SGD everywhere.
The learning rate matters. Too large and the iterations overshoot and diverge. Too small and convergence is painfully slow. For linear regression, the optimal learning rate relates to the eigenvalues of $X^top X$.
SVD: The Numerically Stable Path
The SVD decomposes $X = U Sigma V^top$. Substituting into the normal equation:
This avoids computing $X^top X$ entirely. When $X^top X$ is ill-conditioned (near-singular), the normal equation gives garbage, but SVD handles it gracefully by working with the singular values directly. This is what numpy’s lstsq and sklearn use internally.
scipy.optimize: The Black-Box Approach
The minimize function treats regression as a generic optimisation problem. We pass the loss function, initial guess, and algorithm — it handles the rest. Nelder-Mead (a derivative-free simplex method, like in our GP hyperparameter optimisation) doesn’t even compute gradients. This approach generalises to any loss function — L1, Huber, custom losses — where closed-form solutions don’t exist.
sklearn: What Happens Inside
sklearn’s LinearRegression uses the SVD internally via numpy.linalg.lstsq. It handles the design matrix construction (adding the intercept column), feature scaling, and edge cases. For production code, always use sklearn — it’s tested, optimised, and handles corner cases you’d forget.
Going Deeper
OLS Is Maximum Likelihood Under Gaussian Noise
If we assume the noise is Gaussian — $y_i = mathbf{x}_i^topboldsymbol{beta} + epsilon_i$ where $epsilon_i sim mathcal{N}(0, sigma^2)$ — then the likelihood is:
Taking the log and maximising gives exactly the least-squares objective. So OLS is maximum likelihood estimation under Gaussian noise — the same MLE framework that appears throughout our tutorial series.
Ridge Regression: When the Normal Equation Breaks
If $X^top X$ is singular or nearly so, the normal equation is unstable. Ridge regression adds a penalty $lambda|boldsymbol{beta}|^2$ to the objective:
The $lambda I$ term makes the matrix invertible regardless of collinearity. Larger $lambda$ shrinks coefficients toward zero — a bias-variance tradeoff you can explore hands-on in the Overfitting Explorer.
def ridge_regression(X, y, lam):
"""Ridge regression: closed-form solution."""
n_features = X.shape[1]
return np.linalg.inv(X.T @ X + lam * np.eye(n_features)) @ X.T @ y
lambdas = [0, 1, 10, 100]
for lam in lambdas:
beta_r = ridge_regression(X, y, lam)
print(f'lambda={lam:>3d}: y = {beta_r[0]:.2f} + {beta_r[1]:.2f}x')
The Bayesian interpretation: Ridge regression is equivalent to placing a Gaussian prior $boldsymbol{beta} sim mathcal{N}(mathbf{0}, sigma^2/lambda cdot I)$ on the weights and computing the MAP estimate. The connection to Bayesian inference runs deep — Ridge is OLS with a prior, and GP regression generalises this to infinite-dimensional feature spaces.
Influential Observations: When One Point Rules the Model
OLS minimises squared errors, which means a single outlier far from the data cloud can drag the entire regression line toward itself. This isn’t a bug — it’s a mathematical consequence of the $L^2$ loss.
Cook’s distance (Cook, 1977) quantifies this: it measures how much all fitted values change when observation $i$ is removed. The formula combines the residual size with the observation’s leverage — how extreme its $x$ value is:
A common rule of thumb flags points with $D_i > 4/n$ as potentially influential. The danger is subtle: a high-leverage point (extreme $x$) doesn’t always distort the fit — it might sit right on the true line. But when a high-leverage point is also an outlier in $y$, it can single-handedly determine the slope.
This is why residual analysis is not optional. Plotting residuals against fitted values, checking for heteroscedasticity (fan-shaped patterns), and inspecting Q-Q plots for normality are how you verify that your model’s assumptions actually hold on your data. A clean-looking $R^2$ can mask serious problems that only residual plots reveal.
When influential points are genuine (not data errors), consider robust alternatives: Huber loss, L1 regression (which minimises absolute errors instead of squared), or RANSAC.
When NOT to Use Linear Regression
Computational Complexity Comparison
| Method | Time Complexity | When to Use |
|---|---|---|
| Normal Equation | $O(p^2 n + p^3)$ |
Small $p$ (< ~10k features) |
| Gradient Descent | $O(npT)$ |
Large datasets, online learning |
| SVD | $O(np^2)$ |
Medium datasets, ill-conditioned $X$
|
| scipy.optimize | Varies | Custom loss functions |
| sklearn |
$O(np^2)$ (SVD internally) |
Production code |
Where $n$ = samples, $p$ = features, $T$ = iterations. For most tabular ML, sklearn’s SVD-based approach is the right choice.
Where This Comes From
Legendre (1805) and Gauss (1809)
The method of least squares has one of the most famous priority disputes in science. Adrien-Marie Legendre published it first in 1805, in Nouvelles méthodes pour la détermination des orbites des comètes. But Carl Friedrich Gauss claimed he had been using it since 1795 — and in his 1809 Theoria motus corporum coelestium, he provided the theoretical justification by connecting least squares to maximum likelihood under Gaussian errors.
The original application was astronomy: predicting the orbit of the asteroid Ceres from a handful of noisy observations. The same problem structure — fitting a model to noisy data — appears in every regression task today.
The Normal Equation
Gauss showed that the least-squares estimator satisfies the normal equations:
The name “normal” comes from the geometric interpretation: the residual vector $mathbf{y} - Xboldsymbol{beta}$ is normal (perpendicular) to the column space of $X$. The OLS solution is the orthogonal projection of $mathbf{y}$ onto the space spanned by the features.
The Gauss-Markov Theorem
OLS is optimal — but only under specific assumptions. The classical linear model requires:
$y = Xboldsymbol{beta} + boldsymbol{epsilon}$ — the true relationship is linear in the parameters$mathbb{E}[epsilon_i mid X] = 0$ — errors are unrelated to the features$text{Var}(epsilon_i) = sigma^2$ — constant error variance across all observations$text{Cov}(epsilon_i, epsilon_j) = 0$ for $i neq j$ — errors are independent$X$ has full column rank — no feature is a perfect linear combination of othersWhen these hold, the Gauss-Markov theorem guarantees that OLS is the Best Linear Unbiased Estimator (BLUE):
Among all linear unbiased estimators, OLS has the smallest variance.
The key word is unbiased. The theorem doesn’t say OLS is the best estimator period — biased estimators like Ridge can achieve lower mean squared error by trading a small bias for a large reduction in variance.
When the assumptions fail, OLS can mislead. Heteroscedastic errors inflate standard errors. Autocorrelated residuals (common in time series) make confidence intervals too narrow. And multicollinearity makes the normal equation numerically unstable — exactly the scenario Ridge regression was designed for.
Further Reading
Try It Yourself
The interactive notebook includes exercises:
scipy.optimize with the min_abs_dev_error loss from the original code). Which is more robust?$y = x^2 + epsilon$ and fit linear regression with features $[1, x, x^2]$. How does the design matrix change?$x_2 = x_1 + epsilon$). Compare the normal equation vs SVD solutions. What happens to np.linalg.cond(X.T @ X)? Interactive Tools
Related Posts
Frequently Asked Questions
What are the different ways to solve linear regression?
Linear regression can be solved with the normal equation (closed-form matrix algebra), gradient descent (iterative optimisation), QR decomposition (numerically stable matrix factorisation), singular value decomposition (SVD), and regularised variants like Ridge and Lasso. Each method has different trade-offs in speed, stability, and applicability.
When should I use gradient descent instead of the normal equation?
Use gradient descent when the number of features is very large (more than about 10,000), because the normal equation requires inverting a matrix that is quadratic in the number of features. Gradient descent scales linearly with the number of features and can also handle datasets too large to fit in memory via mini-batch processing.
What is the difference between Ridge and Lasso regression?
Both add a penalty to prevent overfitting, but Ridge (L2) shrinks coefficients towards zero without eliminating them, while Lasso (L1) can set coefficients exactly to zero, effectively performing feature selection. Use Lasso when you expect many features to be irrelevant; use Ridge when most features contribute to the prediction.
Why does the normal equation sometimes fail?
The normal equation requires inverting the matrix X^T X, which fails when features are perfectly collinear (the matrix is singular). Even near-collinearity causes numerical instability, amplifying rounding errors. QR or SVD-based methods handle these cases more gracefully. Ridge regression also solves this by regularising the matrix.
Is linear regression still useful in the age of deep learning?
Absolutely. Linear regression is interpretable, fast, requires no hyperparameter tuning (for the basic form), and works surprisingly well when the relationship is approximately linear. It serves as a strong baseline, and understanding it deeply is essential for understanding more complex models that build on the same principles.
Series note: This post is Part 1 of my Security Engineering Interview Prep series. I am working through Saed Farah’s “If I Were Starting Over as a Security Engineer in 2026” question bank — 94 questions mapped to a structured curriculum — and archiving my personal answers here as I lock each one in.
These are the answers I would give in a real phone screen. I am targeting mid-level Security Engineering roles at companies like Anthropic, GitLab, Stripe, Coinbase, Trail of Bits, and NCC Group.
Why Phone Screen Answers Belong in a Blog
The following ten questions appear in Security Engineering phone interviews. They come from Section A: Encryption, Authentication & Access of Saed Farah’s question bank, and nine of the ten are flagged ★ INDISPENSABLE — meaning they appear frequently enough across mid-level Security Engineering screens that a weak answer on any of them is a disqualifying signal.
Interview prep that stays in a notebook rots. Writing answers in public forces you to be precise. Vague mental models collapse under the pressure of an interviewer’s follow-up. Clear writing is the test.
Let’s get into it.
Q1 — What is a Three-Way Handshake?
This is the technique used in TCP/IP connections to verify
sender and recipient of messages can communicate with each other.
Below is a quick summary of the handshake:
Sender sends an SYN packet to recipient
Recipient replies back with a SYN-ACK packet to sender
Sender replies back with an ACK packet
It is possible an attacker can trick either party into believing
they are the authentic recpient of said party’s messages: an
attack known as a TCP Session Hijacking Attack.
To prevent this the TCP 3-way handshake enforces Initial Sequence
Number Randomization. Now that said party is sending a random number
it is hard for the attacker to predict what the future ISN will
be in said party’s future packets–mitigating the attack.
Without doing the TCP 3-way handshake an attacker
can next attempt a Denial of Service by sending excessive SYN packets
–depleting the other party of system resources.
Curriculum anchor: Week 1–2 TCP/IP fundamentals. ★ Indispensable.
Q2 — How Do Cookies Work?
Let me first start with the rationale behind cookies.
In the modern world the user must make an effort to prove their
identity to a service. This can be done by entering a (sufficiently
complex) password, or a passkey, or biometric credentials. Users
frequently close sessions to work on something else only to come back
to the service after a brief period of time. It would annoy the user
to have to exert manual effort to prove their identity to a web
service! Had that been the case critical business models such as
Software as a Service may not have been as profitable as they are
today.
To make the user’s life easier web security developers introduced
the Cookie system. After the user proves their identity through
manual effort the first time (such as by using one of the techniques
discussed previously) — the web service passes on a Cookie which
contains secret information unique to said user. Whenever the user
revisits the web service the user’s browser automatically sends the
cookie to the web service for authentication. If the secret information
is verified to be correct the user’s identity is verified.
Throughout history web developers faced issues with attackers stealing
Cookies or even tricking users to submitting cookies to the web
service without their knowledge. Several security defenses to protect
cookies from theft or unwitting submission have been invented such
as the HttpOnly flag (forbids Javascript from accessing the Cookie),
the Secure flag (which only allows the cookie to be submitted upon
the browser being able to establish a valid HTTPS connection to the
target website), and the SameSite flag (which restricts the ability
of a cookie to be sent in cross-site requests), Expires flag (which
sets expiration date of cookie)–a good habit to set expiration
to minimize risk of cookie theft, Domain, and Path flags (to
restrict to which webistes and endpoints the browser is allowed
to send cookies too).
Web developers must take care to verify the secret information
received from cookies matches what is expected. They must also
be sure to set the proper security flags to avoid mismanagement
of the cookie. Finally Web Developers must be careful not to
allow the attacker to steal any secrets stored within the Cookie.
For instance if a Cookie stores a CSPRNG-generated string the
web server should NOT also store the string–only a cryptographically
secure message digest. This–and using a constant-time comparision
string function to compare message digest–are appropriate precautions
to prevent an attacker from stealing the Cookie secret.
Curriculum anchor: Week 6 — session management and secure cookie flags. ★ Indispensable.
Q3 — How Do Sessions Work?
HTTP requests are not persistent–they do not keep track of the
state of previous HTTP requests/replies. This is a downside for
users using a web-service: a person that has logged into a web service
would ideally want the web service to remember they are the true
identity as the user and that they are authorized to access/interact
with certain resources on the web service. Web developers had
to figure out a way to allow this beyond sending simple HTTP requests.
This gave birth to two important techniques for establishing and
verifying user sessions: User session cookie management and
verifying Anti-CSRF tokens. Both of these techniques require the
user to receive and store credentials that the web service verifies
upon the user revisiting the web service within the expiration
time window. This allows the web service to automatically verify
the identity of the user to access certain resources from the web
service. Precautions have been made to prevent attackers from
corrupting user sessions (see previous explanations above). Anti-CSRF
tokens prevent an attacker from tricking users into performing actions
on a cross-site that said user has a valid cookie for.
Upon logout session credentials are marked as invalid. Upon expiration
session credentials must be rejected by the web server.
Curriculum anchor: Week 6 — session management. See also: Full Stack Python Security, Chapter 3.
Q4 — Explain How OAuth2 Works
OAuth is a framework that allows a third-party service (called a
client in OAuth2) to access a protected resource on behalf of a
resource owner (the human user).
Here are the steps on the most important version of OAuth2, the
authorization grant, works. My information is taken from
“OAuth2 in Action” — page 23. 1
It is ideal if the client
generates a code_verifier for Proof-Key for Code Exchange. This
is a CSPRNG-generated secret. The client then can either send
the code_verifier to the Authorization Server or ideally
send the cryptographic message digest of the code_verifier
to the Authorization Server. In either case what the Authorization
Server receives is called the code_challenge. Proof-Key for Code
Exchange prevents a MITM attacker that has stolen the
authorization code from receiving an access token from the
Authorization server’s token endpoint. Although ideal not
required in OAuth2. The code_challenge can be the code_verifier
itself but ideally the cryptographic message digest of the
code_verifier. Having the Authorization Server’s token endpoint
store the hash, instead of the actual code_verifier protects the
code_verifier from theft if an attacker compromises the
Authorization Server’s token endpoint.
The third-party service, called the client, redirects the resource
owner, or user, to the authorization endpoint. There, the user must
prove their identity using traditional authentication.
The resource owner is given the option to authorize the client.
The user manually approves.
The authorization server now redirects resource owner back
to client with authorization code.
Client authenticates by sending client credentials, authorization
code, and ideally also the Proof-Key for Code Exchange code_verifier
to the Authorization Server’s token endpoint.
Authorization server sends access token to client. Ideally
the authorization server also sends a refresh token the client
can use to get a new access token should the current access token
expire.
Client accesses the protected resource after sending the access token.
Source: OAuth 2 in Action (Justin Richer & Antonio Sanso), p. 23. 1
Curriculum anchor: Week 12 — SSO + OAuth2 + JWT. ★ Indispensable.
Q5 — Explain How JWTs Work
The following answer is straight from:
https://www.jwt.io/introduction#what-is-json-web-token 2
JWT Tokens are a compact and self-contained technique to transmit
secret information between client and server. The recipient of the
token can verify the authenticity of the message since the JWT Token
is signed.
There are two uses of JWTs:
Authorization: After the user manually authenticates themselves and
proves their identity the user is assigned a JWT Token. From that point
on for every endpoint the user accesses the server verifies the user’s
identity by verifying the user’s JWT Token. Developers must be
careful the JWT Token is not stolen–such as from an XSS exploit.
Secure Information Exchange: JWT Tokens are also used in the
private transfer of information. The secrecy of the JWT Token content
is protected under TLS. The authenticity of the JWT Token is protected
by HMAC or digital signature (using a private-public key pair).
There are three components to a JWT Token:
Header: Usually explains the type of token and the digital
signature algorithm being used.
Payload: This is the main content of the JWT Token–compromised
of claims.
Signature: This is either the HMAC or digital signature that
recipients can verify upon recieving the message. A valid verification
implies the message was not tampered and was sent by the claimed
sender.
Source: jwt.io — Introduction to JSON Web Tokens. 2
Curriculum anchor: Week 6 — API auth patterns. ★ Indispensable.
Q6 — What Is a PKI Flow? How Would You Diagram It?
PKI flow maps the chain-of-trust from Root Certificate Authority
to the TLS Certificate owned by a web service. The idea is all
the digital signatures of the certificates belonging to each of
these services must be verified by clients as valid before the
client (or user’s browser) accepts the TLS certificate of the
web service as valid. This is a prerequisite that must be done
before the client establishes a secure HTTPS connection with
a web server.
The diagram of the flow of verification–showing the order at
which TLS Certificates are verified–are shown below:
Root Certificate validated–>Intermediate Certificates validated
–>Web Server TLS Certificate validated
There is a point to the existence of the Root Certificate.
Every browser comes with it a set of publicly known Root TLS
Certificates–so a self-signed Root TLS Certificate is sufficient
to verify that a Root TLS Certificate is valid. The Root Certificate
can be thought of as a Root of Trust for this reason. If Root
TLS Certificates are publicly acknowledged why do we have Intermediate
TLS Certificates. In case a Root Certificate is compromised it would
be costly to replace the original Root Certificate with a brand new
one. An Intermediate Certificate Authority will be much more quickly
be able to replace an invalid/stolen TLS Certificate than a Root
Certificate. The Intermediate Certificate Authority signs the TLS
Certificate of the web service the client is interested in visiting.
A self-signed TLS certificate for a web service means nothing–anyone
can make one–but only the real web service should be able to convince
an Intermediate TLS Certificate to sign the web service’s TLS
Certificate. This is not to say it is impossible for Intermediate
Certificate Authorities to mis-issue TLS Certificates. To this day
it is a problem. The best mitigation of that is DNSSEC and DANE.
Although those two techniques are best practice the industry
has decided to settle with Certificate Transparency. These are
unmodifiable–append only logs of issued TLS Certificates that
site owners can check to see if a TLS Certificate has been mis-issued
for their site. Although Certificate Transparency is an industry
standard–it does NOT prevent mississuance of TLS Certificates.
To prevent mis-issuance the Certificate Authority Authorization
field in DNS records has been introduced whitelisting which
Certificate Authorities are authorized to issue TLS Certificates.
Still even this does not prevent the mis-issuance of TLS Certificates.
The best defenses to prevent mis-issuance are still DNSSEC and
DANE–despite low adoption.
To avoid the risk of theft of TLS Certificate–web services are
encouraged to replace their TLS Certificates periodically–from as
little as 3 months to no more than a year of time.
Curriculum anchor: Week 5 — cryptography basics + asymmetric key infrastructure.
Q7 — Describe the Difference Between Symmetric and Asymmetric Encryption
Symmetric-Key Cryptography uses the same key to encrypt/decrypt
information. This is the encrypion featured in password authentication,
encrypting of documents, generating HMACs, and more. Symmetric-Key
Cryptography–when using a sufficiently long and CSPRNG-generated
key–is thought to be resistant to attack by a quantum supercomputer.
Asymmmetric Encryption: In this encryption one key is used to encrypt
data and a separate key is used to decrypt data. This field begain
with the invention of Diffie-Hellman Key Exchange by cryptographers
Diffie Whitfield, Martin Hellman, and Ralph Merkle. Asymmetric
Encryption is featured in digital signatures and public-key encryption.
Unfortunately asymmetric key encryption is harder to use than
symmetric-key encryption–and this is arguably the biggest hurdle
to its adoption. Even as late as 2022 CE NIST admits it should take
two whole decades for organizations to adopt the new post-quantum
safe public-key algorithms NIST standardized. Classical Asymmetric
-Key Encryption is vulnerable to Shor’s Algorithm–an algorithm
that a quantum supercomputer can execute to crack the private key
featured in classical asymmetric-key encryption.
Some examples of algorithms that fall under symmetric-key cryptography:
AES, HMAC-SHA-256, Argon2ID
Some examples of asymmetric-key encryption algorithms:
Diffie-Hellman Key Exchange, RSA, Kyber-1024, Dilithium
Curriculum anchor: Week 5 — cryptography basics. ★ Indispensable. Pre-loaded from Intel ChaCha20 (symmetric) + XMSS (asymmetric post-quantum signatures).
Q8 — Describe the TLS Handshake
The following gives the steps for the Handshake:
Client sends ClientHello Message:
a. Details which algorithms the client wants to use.
b. Client sends it public key for key exchange in this message
Server responds with ServerHello:
a. Tells client which algorithm(s) the server chose.
b. Client recives server’s public key for key exchange
2.5. Both Client and Server independenty derive premaster secret
from ECDHE shared secret. The ECDHE shared secret is derived during
ECDHE key exchange. Used later in MAC verification to verify
no MITM attack took place during TLS Handshake.
Server sends TLS Certificate to client
a. Has server’s public key and identity information
b. Includes certificate chain.
Server sends CertificateVerify message.
a. Contains signature over ClientHello + ServerHello +
Certificate Transcript.
b. This proves server owns the private key corresponding to
the public key in the TLS certificate.
Server sends “Finished” Message with MAC
a. Contains a MAC over the entire handshake transcript.
i. Client must first verify public key in TLS
Certificate is valid before verifying MAC. This avoids the
Diffie-Hellman MITM where the attacker sends ECDHE public keys
to victim whose private keys the attacker has knowledge of.
Client verifies TLS Certificate Chain
a. Starting from TLS Certificate of the website, past
Intermediate Certificates, up to the Root TLS Certificate of the
website. All signatures must be valid. If at any point a signature is
found to be invalid the client must reject the TLS certificate and
refuse to establish a TLS connection with the website. At that point it
is possible the website is a fake.
Client Derives Session Keys to Verify MAC
a. Client derives session keys using HKDF from premaster
secret to verify MAC Server sent over TLS Handshake Transcript (
ClientHello + ServerHello + TLS Certificate). This proves no MITM
attack took place.
Client sends “Finished” Message
a. Client reports it finished verifying server’s identity by
sending “Finished” message
b. Client sends a MAC to server over entire handshake
transcript. Server verifies MAC is correct. This proves there
was not MITM in the handshake process.
Encrypted Communication Between Client and Server Begins
a. Encrypted Communication in TLS takes place in TLS 1.3
with AEAD ciphers.
Curriculum anchor: Week 2 — TLS/HTTPS networking. ★ Indispensable.
Q9 — How Does HMAC Work?
A Hash-based Message Authentication Code is built on a cryptographic
message digest. To use an HMAC a user must supply a secret key
and a document as two arguments. The HMAC will generate an ID
number unique to the secret key and document pair. The recipient
of a message can then verify that a message was truly sent
by the alleged sender by recalculating the HMAC and verifying the
HMAC sent by the sender matches the one the recipient recalculated.
Security Engineering Interviews care less on the math behind
how algorithms work and more on how to make use of them.
Curriculum anchor: Week 5 — cryptography basics. Pre-loaded from Intel crypto implementations.
Q10 — Why Is HMAC Designed the Way It Is?
Resource: Understanding Cryptography Second Edition 3
HMACs are designed the way they are to avoid common attacks against
MACs: including the suffix and prefix attacks–and HMACs are designed
the way they are since they make use of cryptographic message digest
functions–which are widely available in software cryptographic
libraries to implement and are much easier to program securely
than block ciphers–the alternative building block used to make
a MAC. HMACs are widely used instead of MACs built on block ciphers
since HMACS are easier to prove to be secure even if the hash
featured in HMAC is found to be weak against collision resistance or
weak in second preimage resistance–under certain assumptions.
Source: Understanding Cryptography, 2nd Edition (Christof Paar & Jan Pelzl). 3
Curriculum anchor: Week 5 — cryptography basics. ★ Indispensable.
Where These Questions Sit in the Curriculum
| Question | ★ Indispensable? | Curriculum Week | Status |
|---|---|---|---|
| Q1 — TCP Three-Way Handshake | ★ Yes | Week 1 | ✅ Pre-loaded |
| Q2 — How Cookies Work | ★ Yes | Week 6 | 🔵 Near-term |
| Q3 — How Sessions Work | No | Week 6 | 🔵 Near-term |
| Q4 — OAuth2 | ★ Yes | Week 12 | 🟣 Build toward |
| Q5 — JWT | ★ Yes | Week 6 | 🔵 Near-term |
| Q6 — PKI Flow | No | Week 5 | ✅ Pre-loaded |
| Q7 — Symmetric vs. Asymmetric | ★ Yes | Week 5 | ✅ Pre-loaded |
| Q8 — TLS Handshake | ★ Yes | Week 2 | ✅ Pre-loaded |
| Q9 — HMAC | No | Week 5 | ✅ Pre-loaded |
| Q10 — Why HMAC Is Designed That Way | No | Week 5 | ✅ Pre-loaded |
What’s Next
Part 2 will cover Q11–Q17 — the remainder of Section A — including Perfect Forward Secrecy, data-at-rest encryption strategy, authentication vs. authorization, and Kerberos/Diffie-Hellman/RSA distinctions.
Part 3 will move into Section B: Network Security, Protocols & Logging — the largest section at 36 questions.
References
This post is part of my public Security Engineering interview prep series. I am building toward a full-time Security Engineering role and maintaining an open-source project — SecEng-Exercises on GitHub — that curates high-quality, secure code datasets to train AI to write more secure code. Follow along on Dev.to.
Justin Richer & Antonio Sanso. OAuth 2 in Action. Manning Publications, 2017. p. 23 — Authorization Code grant flow and PKCE extension. ↩
JSON Web Tokens — Introduction. jwt.io/introduction. ↩
Christof Paar & Jan Pelzl. Understanding Cryptography, 2nd Edition. Springer, 2010. HMAC construction and attack analysis. ↩
Hi, this post was initially written for Caché. In June 2023, I finally updated it for IRIS. If you are revisiting the post since then, the only real change is substituting Caché for IRIS! I also updated the links for IRIS documentation and fixed a few typos and grammatical errors. Enjoy 🙂
In this post, I show strategies for backing up InterSystems IRIS using External Backup with examples of integrating with snapshot-based solutions. Most solutions I see today are deployed on Linux on VMware, so a lot of the post shows how solutions integrate VMware snapshot technology as examples.
IRIS backup – batteries included?
IRIS online backup is included with an IRIS install for uninterrupted backup of IRIS databases. But there are more efficient backup solutions you should consider as systems scale up. External Backup integrated with snapshot technologies is the recommended solution for backing up systems, including IRIS databases.
Are there any special considerations for external backup?
Online documentation for External Backup has all the details. A key consideration is:
“To ensure the integrity of the snapshot, IRIS provides methods to freeze writes to databases while the snapshot is created. Only physical writes to the database files are frozen during the snapshot creation, allowing user processes to continue performing updates in memory uninterrupted.”
It is also important to note that part of the snapshot process on virtualised systems causes a short pause on a VM being backed up, often called stun time. Usually less than a second, so not noticed by users or impacting system operation; however, in some circumstances, the stun can last longer. If the stun is longer than the quality of service (QoS) timeout for IRIS database mirroring, then the backup node will think there has been a failure on the primary and will failover. Later in this post, I explain how you can review stun times in case you need to change the mirroring QoS timeout.
A list of other InterSystems Data Platforms and performance series posts is here.
You should also review IRIS online documentation Backup and Restore Guide for this post.
Backup choices
Minimal Backup Solution – IRIS Online Backup
If you have nothing else, this comes in the box with the InterSystems data platform for zero downtime backups. Remember, IRIS online backup only backs up IRIS database files, capturing all blocks in the databases that are allocated for data with the output written to a sequential file. IRIS Online Backup supports cumulative and incremental backups.
In the context of VMware, an IRIS Online Backup is an in-guest backup solution. Like other in-guest solutions, IRIS Online Backup operations are essentially the same whether the application is virtualised or runs directly on a host. IRIS Online Backup must be coordinated with a system backup to copy the IRIS online backup output file to backup media and all other file systems used by your application. At a minimum, system backup must include the installation directory, journal and alternate journal directories, application files, and any directory containing external files the application uses.
IRIS Online Backup should be considered as an entry-level approach for smaller sites wishing to implement a low-cost solution to back up only IRIS databases or ad-hoc backups; for example, it is helpful in the set-up of mirroring. However, as databases increase in size and as IRIS is typically only part of a customer’s data landscape, External Backups combined with snapshot technology and third-party utilities are recommended as best practice with advantages such as including the backup of non-database files, faster restore times, enterprise-wide view of data and better catalogue and management tools.
Recommended Backup Solution – External backup
Using VMware as an example, Virtualising on VMware adds functionality and choices for protecting entire VMs. Once you have virtualised a solution, you have effectively encapsulated your system — including the operating system, the application and the data — all within .vmdk (and some other) files. When required, these files can be straightforward to manage and used to recover a whole system, which is very different from the same situation on a physical system where you must recover and configure the components separately — operating system, drivers, third-party applications, database and database files, etc.
VMware snapshot
VMware’s vSphere Data Protection (VDP) and other third-party backup solutions for VM backup, such as Veeam or Commvault, take advantage of the functionality of VMware virtual machine snapshots to create backups. A high-level explanation of VMware snapshots follows; see the VMware documentation for more details.
It is important to remember that snapshots are applied to the whole VM and that the operating system and any applications or the database engine are unaware that the snapshot is happening. Also, remember:
By themselves, VMware snapshots are not backups!
Snapshots enable backup software to make backups, but they are not backups by themselves.
VDP and third-party backup solutions use the VMware snapshot process in conjunction with the backup application to manage the creation and, very importantly, deletion of snapshots. At a high level, the process and sequence of events for an external backup using VMware snapshots are as follows:
Backup solutions also use other features such as Change Block Tracking (CBT) to allow incremental or cumulative backups for speed and efficiency (especially important for space saving), and typically also add other important functions such as data deduplication and compression, scheduling, mounting VMs with changed IP addresses for integrity checks etc., full VM and file level restores, and catalogue management.
VMware snapshots that are not appropriately managed or left to run for a long time can use excessive storage (as more and more data is changed, delta files continue to grow) and also slow down your VMs.
You should think carefully before running a manual snapshot on a production instance. Why are you doing this? What will happen if you revert back in time to when the snapshot was created? What happens to all the application transactions between creation and rollback?
It is OK if your backup software creates and deletes a snapshot. The snapshot should only be around for a short time. And a crucial part of your backup strategy will be to choose a time when the system has low usage to minimise any further impact on users and performance.
IRIS database considerations for snapshots
Before the snapshot is taken, the database must be quiesced so that all pending writes are committed, and the database is in a consistent state. IRIS provides methods and an API to commit and then freeze (stop) writes to databases for a short period while the snapshot is created. This way, only physical writes to the database files are frozen during the creation of the snapshot, allowing user processes to continue performing updates in memory uninterrupted. Once the snapshot has been triggered, database writes are thawed, and the backup continues copying data to backup media. The time between freeze and thaw should be quick (a few seconds).
In addition to pausing writes, the IRIS freeze also handles switching journal files and writing a backup marker to the journal. The journal file continues to be written normally while physical database writes are frozen. If the system were to crash while the physical database writes are frozen, data would be recovered from the journal as usual during start-up.
The following diagram shows freeze and thaw with VMware snapshot steps to create a backup with a consistent database image.
VMware snapshot + IRIS freeze/thaw timeline (not to scale)
Note the short time between Freeze and Thaw — only the time to create the snapshot, not the time to copy the read-only parent to the backup target.
Summary – Why do I need to freeze and thaw the IRIS database when VMware is taking a snapshot?
The process of freezing and thawing the database is crucial to ensure data consistency and integrity. This is because:
Data Consistency: IRIS can be writing journals, or the WIJ or doing random writes to the database at any time. A snapshot captures the state of the VM at a specific point in time. If the database is actively being written during the snapshot, it can lead to a snapshot that contains partial or inconsistent data. Freezing the database ensures that all transactions are completed and no new transactions start during the snapshot, leading to a consistent disk state.
Quiescing the File System: VMware’s snapshot technology can quiesce the file system to ensure file system consistency. However, this does not account for the application or database level consistency. Freezing the database ensures that the database is in a consistent state at the application level, complementing VMware’s quiescing.
Reducing Recovery Time: Restoring from a snapshot that was taken without freezing the database might require additional steps like database repair or consistency checks, which can significantly increase recovery time. Freezing and thawing ensure the database is immediately usable upon restoration, reducing downtime.
Integrating IRIS Freeze and Thaw
vSphere allows a script to be automatically called on either side of snapshot creation; this is when IRIS Freeze and Thaw are called. Note: For this functionality to work correctly, the ESXi host requests the guest operating system to quiesce the disks via VMware Tools.
VMware tools must be installed in the guest operating system.
The scripts must adhere to strict name and location rules. File permissions must also be set. For VMware on Linux, the script names are:
# /usr/sbin/pre-freeze-script
# /usr/sbin/post-thaw-script
Below are examples of freeze and thaw scripts our team use with Veeam backup for our internal test lab instances, but these scripts should also work with other solutions. These examples have been tested and used on vSphere 6 and Red Hat 7.
While these scripts can be used as examples and illustrate the method, you must validate them for your environments!
Example pre-freeze-script:
#!/bin/sh
#
# Script called by VMWare immediately prior to snapshot for backup.
# Tested on Red Hat 7.2
#
LOGDIR=/var/log
SNAPLOG=$LOGDIR/snapshot.log
echo >> $SNAPLOG
echo "`date`: Pre freeze script started" >> $SNAPLOG
exit_code=0
# Only for running instances
for INST in `iris qall 2>/dev/null | tail -n +3 | grep '^up' | cut -c5- | awk '{print $1}'`; do
echo "`date`: Attempting to freeze $INST" >> $SNAPLOG
# Detailed instances specific log
LOGFILE=$LOGDIR/$INST-pre_post.log
# Freeze
irissession $INST -U '%SYS' "##Class(Backup.General).ExternalFreeze("$LOGFILE",,,,,,1800)" >> $SNAPLOG $
status=$?
case $status in
5) echo "`date`: $INST IS FROZEN" >> $SNAPLOG
;;
3) echo "`date`: $INST FREEZE FAILED" >> $SNAPLOG
logger -p user.err "freeze of $INST failed"
exit_code=1
;;
*) echo "`date`: ERROR: Unknown status code: $status" >> $SNAPLOG
logger -p user.err "ERROR when freezing $INST"
exit_code=1
;;
esac
echo "`date`: Completed freeze of $INST" >> $SNAPLOG
done
echo "`date`: Pre freeze script finished" >> $SNAPLOG
exit $exit_code
Example thaw script:
#!/bin/sh
#
# Script called by VMWare immediately after backup snapshot has been created
# Tested on Red Hat 7.2
#
LOGDIR=/var/log
SNAPLOG=$LOGDIR/snapshot.log
echo >> $SNAPLOG
echo "`date`: Post thaw script started" >> $SNAPLOG
exit_code=0
if [ -d "$LOGDIR" ]; then
# Only for running instances
for INST in `iris qall 2>/dev/null | tail -n +3 | grep '^up' | cut -c5- | awk '{print $1}'`; do
echo "`date`: Attempting to thaw $INST" >> $SNAPLOG
# Detailed instances specific log
LOGFILE=$LOGDIR/$INST-pre_post.log
# Thaw
irissession $INST -U%SYS "##Class(Backup.General).ExternalThaw("$LOGFILE")" >> $SNAPLOG 2>&1
status=$?
case $status in
5) echo "`date`: $INST IS THAWED" >> $SNAPLOG
irissession $INST -U%SYS "##Class(Backup.General).ExternalSetHistory("$LOGFILE")" >> $SNAPLOG$
;;
3) echo "`date`: $INST THAW FAILED" >> $SNAPLOG
logger -p user.err "thaw of $INST failed"
exit_code=1
;;
*) echo "`date`: ERROR: Unknown status code: $status" >> $SNAPLOG
logger -p user.err "ERROR when thawing $INST"
exit_code=1
;;
esac
echo "`date`: Completed thaw of $INST" >> $SNAPLOG
done
fi
echo "`date`: Post thaw script finished" >> $SNAPLOG
exit $exit_code
Remember to set permissions:
# sudo chown root.root /usr/sbin/pre-freeze-script /usr/sbin/post-thaw-script
# sudo chmod 0700 /usr/sbin/pre-freeze-script /usr/sbin/post-thaw-script
Testing Freeze and Thaw
To test the scripts are running correctly, you can manually run a snapshot on a VM and check the script output. The following screenshot shows the “Take VM Snapshot” dialogue and options.
Deselect– “Snapshot the virtual machine’s memory”.
Select – the “Quiesce guest file system (Needs VMware Tools installed)” check box to pause running processes on the guest operating system so that file system contents are in a known consistent state when you take the snapshot.
Important! After your test, remember to delete the snapshot!!!!
If the quiesce flag is true, and the virtual machine is powered on when the snapshot is taken, VMware Tools is used to quiesce the file system in the virtual machine. Quiescing a file system is a process of bringing the on-disk data into a state suitable for backups. This process might include such operations as flushing dirty buffers from the operating system’s in-memory cache to disk.
The following output shows the contents of the $SNAPSHOT log file set in the example freeze/thaw scripts above after running a backup that includes a snapshot as part of its operation.
Wed Jan 4 16:30:35 EST 2017: Pre freeze script started
Wed Jan 4 16:30:35 EST 2017: Attempting to freeze H20152
Wed Jan 4 16:30:36 EST 2017: H20152 IS FROZEN
Wed Jan 4 16:30:36 EST 2017: Completed freeze of H20152
Wed Jan 4 16:30:36 EST 2017: Pre freeze script finished
Wed Jan 4 16:30:41 EST 2017: Post thaw script started
Wed Jan 4 16:30:41 EST 2017: Attempting to thaw H20152
Wed Jan 4 16:30:42 EST 2017: H20152 IS THAWED
Wed Jan 4 16:30:42 EST 2017: Completed thaw of H20152
Wed Jan 4 16:30:42 EST 2017: Post thaw script finished
This example shows 6 seconds of elapsed time between freeze and thaw (16:30:36-16:30:42). User operations are NOT interrupted during this period. You will have to gather metrics from your own systems, but for some context, this example is from a system running an application benchmark on a VM with no IO bottlenecks and an average of more than 2 million Glorefs/sec, 170,000 Gloupds/sec, and an average 1,100 physical reads/sec and 3,000 writes per write daemon cycle.
Remember that memory is not part of the snapshot, so on restarting, the VM will reboot and recover. Database files will be consistent. You don’t want to “resume” a backup; you want the files at a known point in time. You can then roll forward journals and whatever other recovery steps are needed for the application and transactional consistency once the files are recovered.
For additional data protection, a journal switch can be done by itself, and journals can be backed up or replicated to another location, for example, hourly.
Below is the output of the $LOGFILE in the example freeze/thaw scripts above, showing journal details for the snapshot.
01/04/2017 16:30:35: Backup.General.ExternalFreeze: Suspending system
Journal file switched to:
/trak/jnl/jrnpri/h20152/H20152_20170104.011
01/04/2017 16:30:35: Backup.General.ExternalFreeze: Start a journal restore for this backup with journal file: /trak/jnl/jrnpri/h20152/H20152_20170104.011
Journal marker set at
offset 197192 of /trak/jnl/jrnpri/h20152/H20152_20170104.011
01/04/2017 16:30:36: Backup.General.ExternalFreeze: System suspended
01/04/2017 16:30:41: Backup.General.ExternalThaw: Resuming system
01/04/2017 16:30:42: Backup.General.ExternalThaw: System resumed
VM Stun Times
At the creation point of a VM snapshot and after the backup is complete and the snapshot is committed, the VM needs to be frozen for a short period. This short freeze is often referred to as stunning the VM. A good blog post on stun times is here. I summarise the details below and put them in the context of IRIS database considerations.
From the post on stun times: “To create a VM snapshot, the VM is “stunned” in order to (i) serialize device state to disk, and (ii) close the current running disk and create a snapshot point.…When consolidating, the VM is “stunned” in order to close the disks and put them in a state that is appropriate for consolidation.”
Stun time is typically a few 100 milliseconds; however, if there is a very high disk write activity during the commit phase, stun time could be several seconds.
If the VM is a Primary or Backup member participating in IRIS Database Mirroring and the stun time is longer than the mirror Quality of Service (QoS) timeout, the mirror will report the Primary VM as failed and initiate a mirror takeover.
Update March 2018:
My colleague, Peter Greskoff, pointed out that a backup mirror member could initiate failover in as short a time as just over half QoS timeout during a VM stun or any other time the primary mirror member is unavailable.
For a detailed description of QoS considerations and failover scenarios, see this great post: Quality of Service Timeout Guide for Mirroring, however the short story regarding VM stun times and QoS is:
If the backup mirror does not receive any messages from the primary mirror within half of the QoS timeout, it will send a message to ensure the primary is still alive. The backup then waits an additional half QoS time for a response from the primary machine. If there is no response from the primary, it is assumed to be down, and the backup will take over.
On a busy system, journals are continuously sent from the primary to the backup mirror, and the backup would not need to check if the primary is still alive. However, during a quiet time — when backups are more likely to happen — if the application is idle, there may be no messages between the primary and backup mirror for more than half the QoS time.
Here is Peter’s example; Think about this time frame for an idle system with a QoS timeout of:08 seconds and a VM stun time of:07 seconds:
Please also read the section, Pitfalls and Concerns when Configuring your Quality of Service Timeout, in the linked post above to understand the balance to have QoS only as long as necessary. Having QoS too long, especially more than 30 seconds, can also cause problems.
End update March 2018:
For more information on Mirroring QoS, also see the documentation.
Strategies to keep stun time to a minimum include running backups when database activity is low and having well-set-up storage.
As noted above, when creating a snapshot, there are several options you can specify; one of the options is to include the memory state in the snapshot – Remember, memory state is NOT needed for IRIS database backups. If the memory flag is set, a dump of the internal state of the virtual machine is included in the snapshot. Memory snapshots take much longer to create. Memory snapshots are used to allow reversion to a running virtual machine state as it was when the snapshot was taken. This is NOT required for a database file backup.
When taking a memory snapshot, the entire state of the virtual machine will be stunned, stun time is variable.
As noted previously, for backups, the quiesce flag must be set to true for manual snapshots or by the backup software to guarantee a consistent and usable backup.
Reviewing VMware logs for stun times
Starting from ESXi 5.0, snapshot stun times are logged in each virtual machine’s log file (vmware.log) with messages similar to:
2017-01-04T22:15:58.846Z| vcpu-0| I125: Checkpoint_Unstun: vm stopped for 38123 us
Stun times are in microseconds, so in the above example, 38123 us is 38123/1,000,000 seconds or 0.038 seconds.
To be sure that stun times are within acceptable limits or to troubleshoot if you suspect long stun times are causing problems, you can download and review the vmware.log files from the folder of the VM that you are interested in. Once downloaded, you can extract and sort the log using the example Linux commands below.
Example downloading vmware.log files
There are several ways to download support logs, including creating a VMware support bundle through the vSphere management console or from the ESXi host command line. Consult the VMware documentation for all the details, but below is a simple method to create and gather a much smaller support bundle that includes the vmware.log file so you can review stun times.
You will need the long name of the directory where the VM files are located. Log on to the ESXi host where the database VM is running using ssh and use the command: vim-cmd vmsvc/getallvms to list vmx files and the long names unique associated with them.
For example, the long name for the example database VM used in this post is output as:
26 vsan-tc2016-db1 [vsanDatastore] e2fe4e58-dbd1-5e79-e3e2-246e9613a6f0/vsan-tc2016-db1.vmx rhel7_64Guest vmx-11
Next, run the command to gather and bundle only log files:
vm-support -a VirtualMachines:logs.
The command will echo the location of the support bundle, for example:
To see the files collected, check '/vmfs/volumes/datastore1 (3)/esx-esxvsan4.iscinternal.com-2016-12-30--07.19-9235879.tgz'.
You can now use sftp to transfer the file off the host for further processing and review.
In this example, after uncompressing the support bundle navigate to the path corresponding to the database VMs long name. For example, in this case:
<bundle name>/vmfs/volumes/<host long name>/e2fe4e58-dbd1-5e79-e3e2-246e9613a6f0.
You will see several numbered log files; the most recent log file has no number, i.e. vmware.log. The log may be only a few 100 KB, but there is a lot of information; however, we care about the stun/unstun times, which are easy enough to find with grep. For example:
$ grep Unstun vmware.log
2017-01-04T21:30:19.662Z| vcpu-0| I125: Checkpoint_Unstun: vm stopped for 1091706 us
---
2017-01-04T22:15:58.846Z| vcpu-0| I125: Checkpoint_Unstun: vm stopped for 38123 us
2017-01-04T22:15:59.573Z| vcpu-0| I125: Checkpoint_Unstun: vm stopped for 298346 us
2017-01-04T22:16:03.672Z| vcpu-0| I125: Checkpoint_Unstun: vm stopped for 301099 us
2017-01-04T22:16:06.471Z| vcpu-0| I125: Checkpoint_Unstun: vm stopped for 341616 us
2017-01-04T22:16:24.813Z| vcpu-0| I125: Checkpoint_Unstun: vm stopped for 264392 us
2017-01-04T22:16:30.921Z| vcpu-0| I125: Checkpoint_Unstun: vm stopped for 221633 us
We can see two groups of stun times in the example, one from snapshot creation and a second set 45 minutes later for each disk when the snapshot is deleted/consolidated (e.g. after the backup software has completed copying the read-only vmx file). The above example shows that most stun times are sub-second, although the initial stun time is just over one second.
Short stun times are not noticeable to an end user. However, system processes such as IRIS Database Mirroring continuously monitor whether an instance is ‘alive’. If the stun time exceeds the mirroring QoS timeout, the node may be considered uncontactable and ‘dead’, and a failover will be triggered.
Tip: To review all the logs or for trouble-shooting, a handy command is to grep all the vmware*.log files and look for any outliers or instances where stun time is approaching QoS timeout. The following command pipes the output to awk for formatting:
grep Unstun vmware* | awk '{ printf ("%'"'"'d", $8)} {print " ---" $0}' | sort -nr
Summary
You should monitor your system regularly during normal operations to understand stun times and how they may impact QoS timeout for HA, such as mirroring. As noted, strategies to keep stun/unstun time to a minimum include running backups when database and storage activity is low and having well-set-up storage. For constant monitoring, logs may be processed by using VMware Log Insight or other tools.
In future posts, I will revisit backup and restore operations for InterSystems Data Platforms. But for now, if you have any comments or suggestions based on the workflows of your systems, please share them via the comments sections below.