
I Built 77 Web Scrapers — Here Are the 10 Patterns That Actually Work
After building 77 scrapers, every problem is a variation of the same 10 patterns
I’ve published 77 web scrapers on Apify Store. Reddit, Hacker News, Google News, Trustpilot, YouTube, Bluesky — you name it.
Here are the 10 patterns I use in every single one.
Pattern 1: Always use sessions
# Bad: new connection every request
for url in urls:
    requests.get(url)  # TCP handshake every time

# Good: reuse connection
session = requests.Session()
for url in urls:
    session.get(url)  # Reuses TCP connection
Impact: 2-5x faster for multiple requests to the same domain.
Pattern 2: Exponential backoff on errors
import time

def fetch(url, max_retries=3):
    for i in range(max_retries):
        try:
            resp = session.get(url, timeout=10)
            if resp.status_code == 429:
                time.sleep(2 ** i)
                continue
            resp.raise_for_status()
            return resp
        except Exception:
            if i == max_retries - 1:
                raise
            time.sleep(2 ** i)
Pattern 3: Extract data with CSS selectors, not XPath
from bs4 import BeautifulSoup

soup = BeautifulSoup(html, 'html.parser')
titles = [el.text.strip() for el in soup.select('h2.post-title a')]
CSS selectors are more readable and closer to how you think in the browser devtools.
Pattern 4: Handle pagination with generators
def paginate(base_url):
    page = 1
    while True:
        resp = session.get(f'{base_url}?page={page}')
        data = resp.json()
        if not data['results']:
            break
        yield from data['results']
        page += 1

for item in paginate('https://api.example.com/items'):
    process(item)
Pattern 5: Normalize data immediately
def normalize(raw):
    return {
        'title': raw.get('title', '').strip(),
        'price': float(raw.get('price', '0').replace('$', '').replace(',', '')),
        'url': raw.get('url', '').split('?')[0],  # Remove query params
        'scraped_at': datetime.utcnow().isoformat(),
    }
Clean data at extraction time, not later.
Pattern 6: Deduplicate by content hash
import hashlib
seen = set()

def is_new(item):
    key = hashlib.md5(json.dumps(item, sort_keys=True).encode()).hexdigest()
    if key in seen:
        return False
    seen.add(key)
    return True
Pattern 7: Log progress, not just errors
import logging
log = logging.getLogger(__name__)

for i, url in enumerate(urls):
    log.info(f'Processing {i+1}/{len(urls)}: {url}')
    data = scrape(url)
    log.info(f'Got {len(data)} items from {url}')
When a scraper runs for 2 hours, you NEED to know where it is.
Pattern 8: Save incrementally, not at the end
with open('results.jsonl', 'a') as f:
    for item in scrape_all():
        f.write(json.dumps(item) + 'n')
        f.flush()  # Write to disk immediately
If the scraper crashes at item 999 out of 1000, you still have 999 results.
Pattern 9: Respect robots.txt
from urllib.robotparser import RobotFileParser

rp = RobotFileParser()
rp.set_url('https://example.com/robots.txt')
rp.read()

if rp.can_fetch('*', url):
    scrape(url)
else:
    log.warning(f'Blocked by robots.txt: {url}')
Pattern 10: Make it configurable
import argparse

parser = argparse.ArgumentParser()
parser.add_argument('--urls', nargs='+', required=True)
parser.add_argument('--output', default='results.jsonl')
parser.add_argument('--max-pages', type=int, default=10)
parser.add_argument('--delay', type=float, default=1.0)
args = parser.parse_args()
Hardcoded values = one-time scripts. Configurable = reusable tools.
The meta-pattern
Every scraper I build follows the same structure:
1. Parse config → 2. Fetch pages → 3. Extract data → 4. Normalize → 5. Deduplicate → 6. Save
The specifics change. The pattern doesn’t.
All 77 scrapers are on Apify Store. Source patterns are on GitHub.
What scraping pattern took you the longest to learn?
I help companies build data extraction pipelines. Contact me if you need custom scrapers.
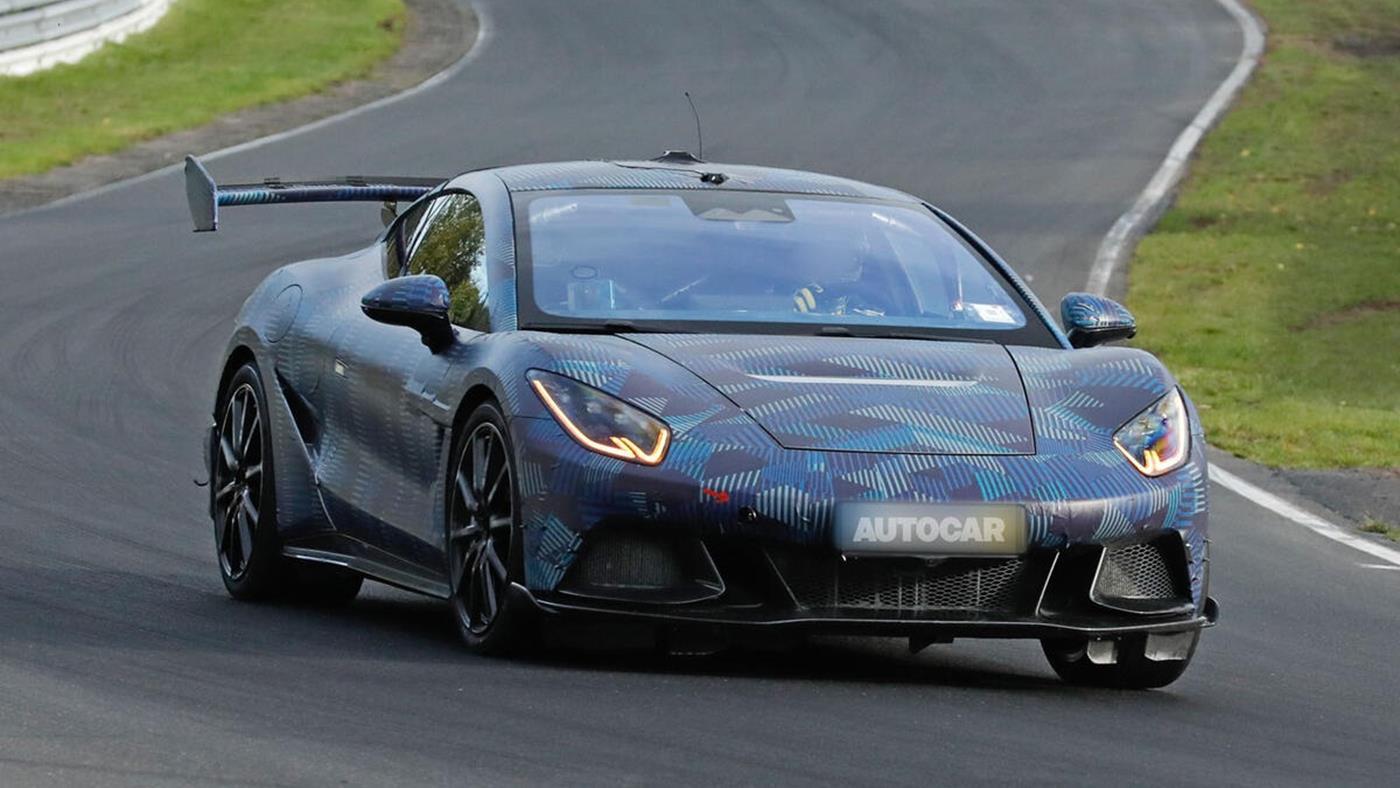
 Denza, Z konseptinin üretim versiyonunu ilk kez gösterdi. Çinli marka, süper coupe’yi Avrupa’da Goodwood’da sergileyecek ve performansla lüksü birleştiren modelle iddialı geliyor.
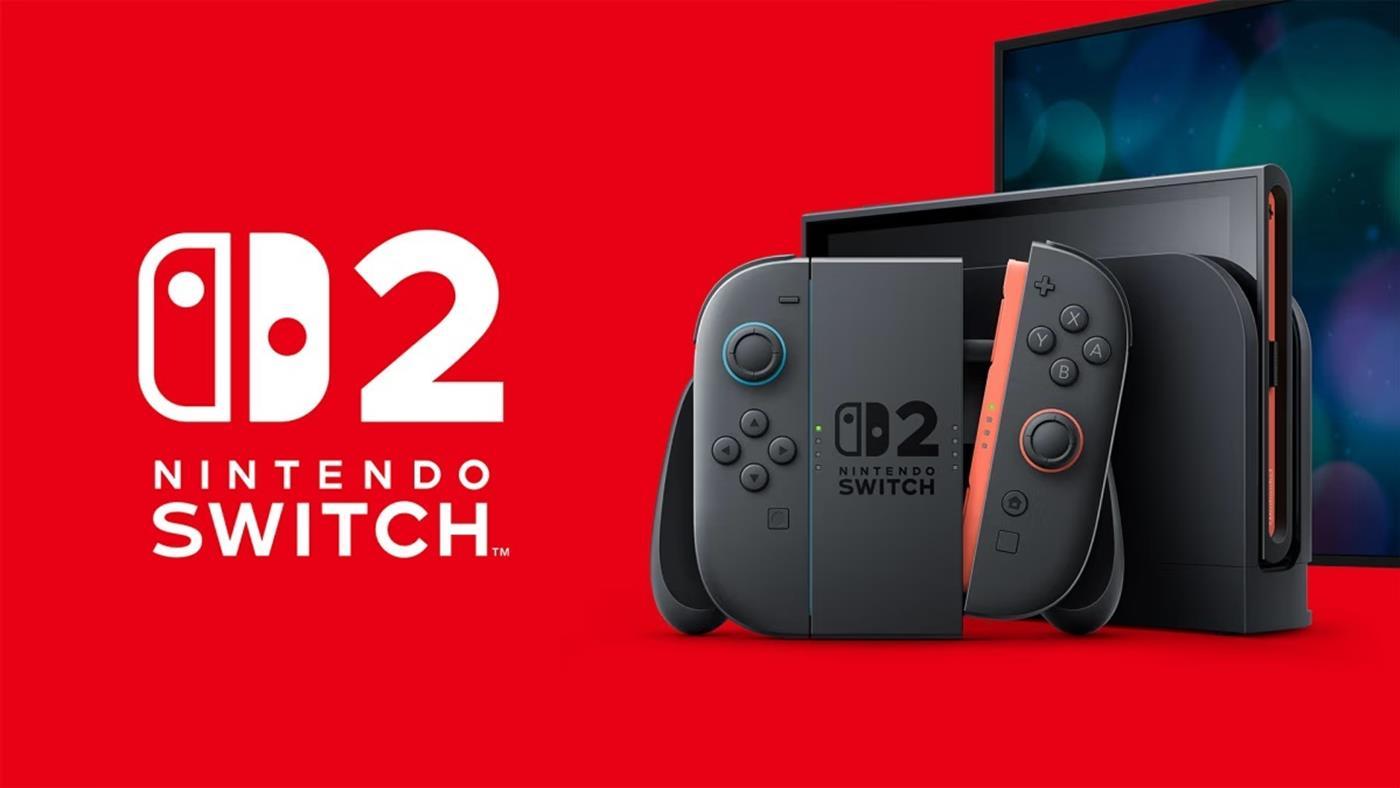
 Nintendo Switch 2 için üretimi milyonlarca adet azaltılabilir. Ancak mevcut satış verileri, konsolun beklentilerin üzerinde performans gösterdiğini söylüyor. İşte detaylar..
 Nvidia, GeForce Game Ready 595.97 WHQL sürücüsünü yayınladı. Yeni sürüm, Enshrouded ve Arknights: Endfield hatalarını çözerken sistem problemlerini de gideriyor.
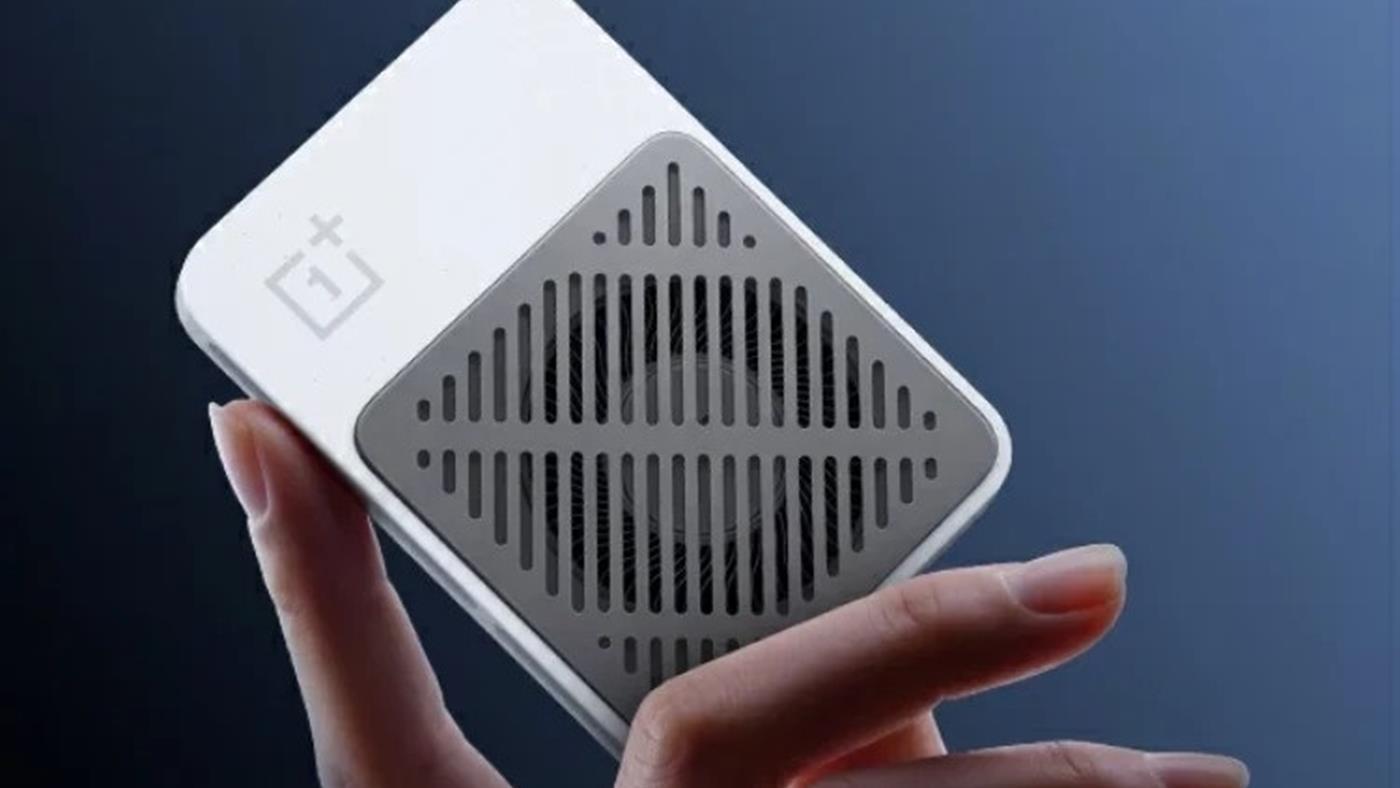
 OnePlus, “dünyanın en ince manyetik telefon soğutucusu” olarak tanıttığı Magnetic Ice Cooling Clip adlı yeni aksesuarını duyurdu.
 Londra, artan SUV sayısı ve güvenlik riskleri nedeniyle yeni bir ücretlendirme planını değerlendiriyor. Karar, hem trafik güvenliğini hem de elektrikli araç dönüşümünü etkileyebilir.