Mert
AI Workflow Automation Needs More Than Another Script
Most teams do not start with a workflow automation strategy.
They start with a small problem.
A lead needs to be added to a CRM.
A support message needs to be routed to the right person.
A form submission needs to trigger an email.
A spreadsheet needs to be updated after a payment.
A Slack message needs to be sent when something important happens.
At first, the solution is simple.
Someone writes a script.
Someone connects a few tools.
Someone creates a small automation.
Someone schedules a cron job.
And for a while, that works.
But as the team grows, the number of small automations grows too. Eventually, those little scripts and one-off workflows become part of how the business actually operates.
That is where the real challenge begins.
The future of automation is not just about connecting tools. It is about building reliable systems that can understand context, move data, trigger actions, and support real business operations.
That is why AI workflow automation is becoming so important.
The problem is not lack of tools
Most companies already use plenty of software.
There may be a CRM for sales, a helpdesk for support, a project management system for tasks, a billing platform for payments, spreadsheets for reporting, email for communication, and Slack or Discord for internal updates.
Each tool solves a specific problem.
The issue is what happens between those tools.
Data has to move.
People have to follow up.
Messages have to be summarized.
Records have to be updated.
Tickets have to be categorized.
Reports have to be created.
Customers have to be routed to the right team.
This in-between work is usually repetitive, but still important.
It is also where teams lose a lot of time.
A workflow automation platform helps reduce this friction by connecting systems and making processes repeatable.
But traditional automation has limits.
Traditional automation is good at rules
Most workflow automation starts with simple logic.
If this happens, then do that.
If a form is submitted, create a lead.
If a payment succeeds, send a receipt.
If a ticket is opened, notify support.
If a meeting ends, create a follow-up task.
This is useful because the input and output are predictable.
The problem is that many real workflows are not perfectly structured.
A customer email may contain multiple requests.
A lead may describe their needs in messy language.
A support ticket may need to be classified by urgency.
A sales conversation may need to be summarized before it is useful.
A document may need to be analyzed before a workflow can continue.
This is where AI changes the role of automation.
AI workflow automation allows workflows to do more than move data. It allows them to interpret information, summarize context, classify inputs, extract details, generate responses, and prepare decisions.
That makes automation useful in areas that previously required constant human review.
Why n8n is useful for AI workflow automation
n8n has become popular because it gives teams flexibility.
It is visual enough for building workflows quickly, but technical enough for developers and operations teams that need more control.
With n8n workflow automation, teams can connect APIs, databases, internal tools, SaaS products, webhooks, and AI models inside the same workflow.
That flexibility matters.
Many teams do not want a rigid automation tool that only supports basic use cases. They want a system that can handle custom logic, branching, data transformation, API calls, and AI-powered steps.
For example, a team might use n8n to receive a webhook, enrich a lead, summarize the lead’s message with AI, score the intent, update the CRM, create a task, and notify the sales team.
That is no longer just app-to-app automation.
That is an operational workflow.
AI workflows are different from normal workflows
Adding AI to a workflow changes what the workflow can do.
A normal workflow might check whether a field equals a specific value.
An AI-powered workflow can read a message and infer what the person is asking for.
A normal workflow might send the same email template to everyone.
An AI-powered workflow can generate a personalized draft based on context.
A normal workflow might route tickets based on selected categories.
An AI-powered workflow can classify the ticket even if the customer wrote it in natural language.
This is the real value of AI workflow automation.
It helps teams automate work that is repetitive but not always cleanly structured.
That does not mean AI should make every decision by itself. In many cases, the best workflows still keep humans involved at key points.
The difference is that AI can prepare the work before a person gets involved.
It can summarize, classify, extract, draft, and organize information so the human only handles the part that actually requires judgment.
The hidden problem: reliability
Building a workflow is only one part of the problem.
Running it reliably is another.
This becomes more important when workflows start supporting real business processes.
If an automation sends a casual internal notification and fails once, it may not matter much.
But if an automation handles lead routing, customer onboarding, ticket classification, billing updates, or operational reporting, failure becomes serious.
A broken workflow can mean missed leads, delayed support, inaccurate reports, or manual cleanup later.
That is why automation infrastructure matters.
A workflow automation platform should not only make workflows easy to build. It should also make them reliable enough to run in production.
For tools like n8n, this means thinking about deployment, uptime, backups, monitoring, updates, logs, environment variables, API keys, queues, and recovery.
Those things are not exciting, but they are what make automation dependable.
Self-hosting gives control, but also responsibility
One reason teams like n8n is that it can be self-hosted.
That is a big advantage for teams that want more control over data, configuration, and infrastructure.
But self-hosting also means someone has to manage the system.
Someone has to set up the server.
Someone has to configure SSL.
Someone has to handle updates.
Someone has to monitor failed executions.
Someone has to manage backups.
Someone has to troubleshoot the deployment when something breaks.
For developers and DevOps teams, that may be acceptable.
For founders, agencies, lean teams, and operations teams, it can quickly become a distraction.
The goal of automation is to reduce manual work. But if the team spends too much time maintaining the automation infrastructure, the platform starts creating another operational burden.
That is the tradeoff many teams run into.
Where Agntable fits in
Agntable is built for teams that want to run powerful open-source automation and AI tools without managing all of the infrastructure manually.
Instead of spending time setting up servers, configuring deployments, managing SSL, handling backups, and troubleshooting infrastructure, teams can focus on building useful workflows.
For teams using n8n workflow automation, this means they can get the flexibility of n8n while reducing the operational work needed to keep it running.
For teams building AI workflow automation, this matters even more.
AI workflows often depend on multiple services: model providers, webhooks, databases, APIs, queues, files, and internal tools. If the hosting layer is unreliable, the workflow becomes unreliable too.
Agntable helps teams move faster by making the deployment and management layer simpler.
You can learn more about Agntable here:
A workflow automation platform should help teams focus on workflows
The best automation platform is not just the one with the most integrations.
It is the one that helps teams build reliable workflows without slowing them down.
For developers, flexibility matters.
For operations teams, reliability matters.
For founders, speed matters.
For agencies, repeatability matters.
For businesses, the final outcome matters: fewer manual tasks, fewer mistakes, faster execution, and better use of team time.
That is why AI workflow automation is becoming a serious part of modern operations.
It is not just about saving a few minutes.
It is about building systems that help the business run more smoothly.
The future of automation is smarter and more connected
The next generation of automation will not only connect tools.
It will understand context.
It will combine workflow automation, AI models, APIs, databases, human approvals, and business logic into systems that can handle more complex work.
n8n is one of the tools making this possible because it gives teams a flexible way to design workflows.
AI makes those workflows more capable.
Managed infrastructure makes them easier to run.
Together, these pieces are becoming the foundation for modern workflow automation.
Final thoughts
Most teams do not need more disconnected tools.
They need better systems between the tools they already use.
That is where AI workflow automation becomes valuable.
With n8n, teams can design flexible workflows that connect apps, APIs, and internal systems. With AI, those workflows can understand and process unstructured information. With Agntable, teams can run automation tools without taking on the full burden of infrastructure management.
The goal is simple.
Spend less time moving data manually.
Spend less time maintaining servers.
Spend less time fixing broken processes.
And spend more time building the work that actually moves the business forward.

Reviving Cineverse: From Local Storage to Firebase 🚀
This is a submission for the GitHub Finish-Up-A-Thon Challenge
What I Built
I built Cineverse, a cinematic movie discovery app powered by the TMDB API. It allows users to:
- 🎬 Browse trending and popular movies
- 🔍 Search for any movie by title
- 📖 View detailed movie info (ratings, overview, release date)
- ❤️ Save favorites and manage a personal watchlist
- 👤 Create an account and sync data across devices
- 🛡️ Admin dashboard with role-based access control
The app is built with Flutter, backed by Firebase Authentication and Cloud Firestore, and designed with a premium dark cinematic theme.
Demo
🔗 GitHub Repository: github.com/Ali23102001/cineverse_app
Key Features in Action
| Feature | Description |
|---|---|
| 🔐 Login & Register | Email/Password + Google Sign-In via Firebase Auth |
| 📧 Email Verification | New users must verify their email before accessing the app |
| 🏠 Home Screen | Trending movies fetched live from the TMDB API |
| 🔍 Search | Real-time movie search with beautiful result cards |
| 🎬 Movie Details | Full movie info with backdrop images, ratings, and overview |
| ❤️ Favorites & Watchlist | Cloud-synced via Firestore — accessible from any device |
| 👤 Profile | User profile with sign-out and account management |
| 🛡️ Admin Dashboard | Restricted to admin email only, with automatic redirect for unauthorized users |
The Comeback Story
❌ Before: The Abandoned Prototype
Cineverse started as a basic Flutter project — a simple movie browsing app with:
- Local storage for everything (no cloud, no sync)
- No real authentication system
- No user accounts, favorites, or watchlists
- Constant crashes on Android due to misconfigured build files
- Just a skeleton that looked okay but didn’t work as a real app
I abandoned it because the jump from “local prototype” to “production-ready app” felt overwhelming. Firebase configuration, platform-specific issues, authentication flows… it was too much to tackle at the time.
✅ After: The Finished Product
When the GitHub Finish-Up-A-Thon Challenge dropped, I knew this was the one. Here’s everything I changed:
-
🔥 Firebase Authentication — Completely replaced local storage auth with Firebase. Users can now sign up with Email/Password or Google Sign-In, with full email verification flow.
-
☁️ Cloud Firestore Integration — User profiles, favorites, and watchlists are stored in Firestore and sync across all devices in real-time.
-
🛡️ Admin Dashboard — Built a secure admin panel restricted by email-based role checking. Unauthorized users get automatically redirected to the home screen.
-
🔧 Platform Fixes — Resolved deep Android build crashes (
build.gradle.kts,AndroidManifest.xml) and Web configuration issues that were preventing Firebase from initializing properly. -
🎨 Polished UI — Refined the splash screen, navigation shell, and overall theme to feel premium and cinematic.
-
📧 Email Verification Screen — Added a dedicated verification flow so users can’t access the app without confirming their email first.
The app went from a broken prototype to a fully functional, cloud-synced movie discovery platform.
My Experience with GitHub Copilot
GitHub Copilot was instrumental in finishing this project. Here’s specifically how it helped:
🚀 Firebase Boilerplate
Setting up firebase_auth, google_sign_in, and cloud_firestore involves a LOT of repetitive setup code. Copilot auto-completed entire authentication service methods — sign in, sign up, sign out, email verification — saving me hours of typing and documentation-checking.
🔧 Platform Configuration Hell
The hardest part of reviving Cineverse was fixing Android and Web platform configs. Copilot helped me:
- Fix the
build.gradle.ktsKotlin DSL syntax for Firebase plugins - Configure the correct
AndroidManifest.xmlintent filters for Google Sign-In - Set up
firebase_options.dartwith the right project configuration
🛡️ Access Control Logic
When I needed to restrict the Admin Dashboard to a specific admin email, Copilot immediately suggested the pattern: check FirebaseAuth.instance.currentUser?.email on screen load, and redirect unauthorized users using Navigator.pushReplacement. Clean and effective.
🧭 Navigation & State Management
Copilot helped me refactor the app’s navigation from simple push/pop to a proper shell-based layout with a bottom navigation bar, ensuring smooth transitions between Home, Search, Favorites, Watchlist, and Profile screens.
Bottom line: Copilot turned what would have been a multi-week slog through Firebase docs into a focused, productive revival. It felt like pair-programming with someone who already knew the entire Firebase + Flutter ecosystem by heart.
Built with ❤️ using Flutter, Firebase, and GitHub Copilot
Approaches to Streaming Data into Apache Iceberg Tables
This is Part 13 of a 15-part Apache Iceberg Masterclass. Part 12 covered Python and MPP engines. This article covers the three primary approaches to streaming data into Iceberg tables and the operational trade-offs each creates.
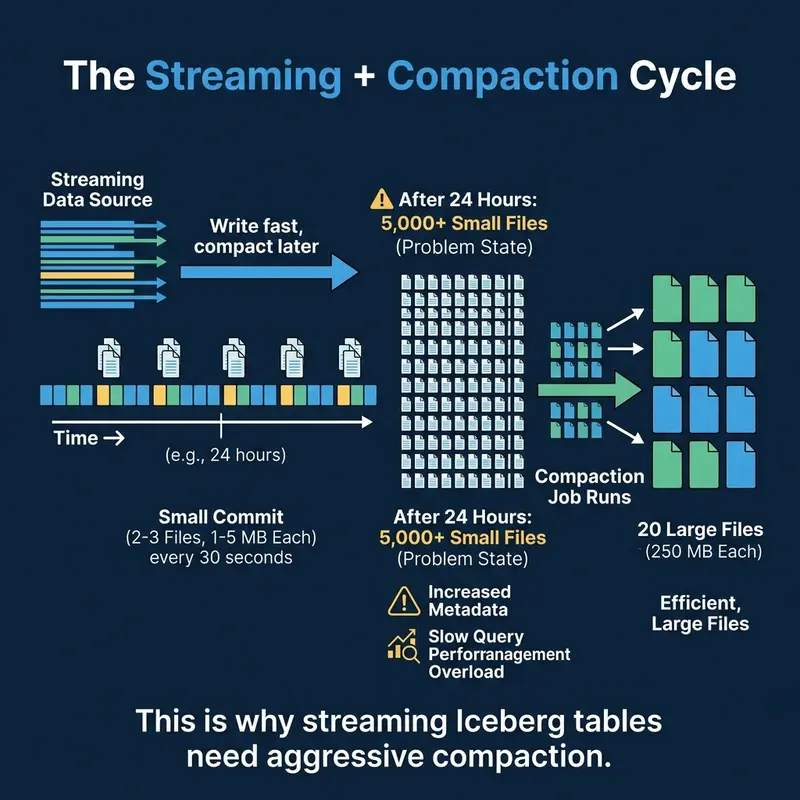
Iceberg was designed for batch analytics, but most production data arrives continuously. Streaming ingestion bridges this gap by committing data to Iceberg tables at regular intervals. The challenge is that frequent commits create the small file problem, and managing that trade-off between data freshness and table health is the central concern of streaming to Iceberg.
Table of Contents
- What Are Table Formats and Why Were They Needed?
- The Metadata Structure of Current Table Formats
- Performance and Apache Iceberg’s Metadata
- Technical Deep Dive on Partition Evolution
- Technical Deep Dive on Hidden Partitioning
- Writing to an Apache Iceberg Table
- What Are Lakehouse Catalogs?
- Embedded Catalogs: S3 Tables and MinIO AI Stor
- How Iceberg Table Storage Degrades Over Time
- Maintaining Apache Iceberg Tables
- Apache Iceberg Metadata Tables
- Using Iceberg with Python and MPP Engines
- Streaming Data into Apache Iceberg Tables
- Hands-On with Iceberg Using Dremio Cloud
- Migrating to Apache Iceberg
Three Streaming Architectures
Spark Structured Streaming
Spark Structured Streaming processes data in micro-batches and commits to Iceberg at configurable intervals:
df = spark.readStream.format("kafka")
.option("subscribe", "events")
.load()
df.writeStream.format("iceberg")
.outputMode("append")
.option("checkpointLocation", "s3://checkpoint/events")
.trigger(processingTime="60 seconds")
.toTable("analytics.events")
Each trigger creates a new Iceberg commit with the accumulated data. A 60-second trigger produces 1,440 commits per day, each adding a small number of files.
Latency: Seconds to minutes (configurable via trigger interval).
Small file impact: Moderate. Longer trigger intervals produce fewer, larger files.
Best for: Teams already using Spark for batch processing who want to add near-real-time ingestion.
Apache Flink Iceberg Sink
Flink processes events continuously and commits to Iceberg at checkpoint intervals:
-- Flink SQL
INSERT INTO iceberg_catalog.analytics.events
SELECT event_id, event_time, payload
FROM kafka_source
Flink’s checkpointing mechanism determines commit frequency. A 30-second checkpoint interval produces commits every 30 seconds with whatever data has accumulated.
Exactly-once semantics: Flink’s checkpoint mechanism provides exactly-once delivery guarantees to Iceberg. If a Flink job crashes, it recovers from its last checkpoint and replays any data that was not yet committed to Iceberg. This means no duplicate records and no data loss, which is critical for financial and transactional data pipelines.
Partitioned writes: Flink can route events to partitions dynamically based on partition transforms. Combined with Iceberg’s hidden partitioning, this means streaming data lands in the correct partition directory automatically without any special logic in the streaming application.
Upserts and CDC: Flink supports changelog streams (insert, update, delete operations) and can write them to Iceberg as equality deletes and data files. This enables CDC (change data capture) patterns where a database’s transaction log is streamed directly into an Iceberg table, maintaining a near-real-time copy.
Latency: Seconds (tied to checkpoint interval).
Small file impact: High. Frequent checkpoints produce many small files.
Best for: Teams needing the lowest-latency streaming with exactly-once semantics and CDC support.
Kafka Connect Iceberg Sink
The Iceberg Sink Connector reads directly from Kafka topics and writes to Iceberg tables:
{
"name": "iceberg-sink",
"config": {
"connector.class": "org.apache.iceberg.connect.IcebergSinkConnector",
"topics": "events",
"iceberg.catalog.type": "rest",
"iceberg.catalog.uri": "https://catalog.example.com",
"iceberg.tables": "analytics.events"
}
}
Latency: Minutes (Kafka Connect batches records before committing).
Small file impact: Lower than Spark/Flink because commits are less frequent.
Best for: Organizations with existing Kafka infrastructure that want a managed connector approach.
Apache Iceberg Sink Connector: The community-maintained Iceberg Sink Connector for Kafka Connect supports schema evolution from Kafka’s Schema Registry, automatic table creation, and partition routing. It reads records from Kafka topics, buffers them in memory, and commits to Iceberg in configurable batch intervals.
Operational simplicity: Kafka Connect is a managed framework. You deploy the connector configuration, and Kafka Connect handles scaling, offset management, and fault recovery. There is no custom application code to write or maintain. For organizations that already run Kafka Connect for other sinks (databases, search indexes), adding an Iceberg sink is straightforward.
The Streaming + Compaction Cycle
Every streaming approach shares the same fundamental problem: frequent commits produce small files. The solution is to pair streaming ingestion with aggressive compaction.
A typical production pattern:
- Stream data in via Flink or Spark with 60-second commit intervals
- Run compaction every hour to merge small files from the last hour into optimally-sized files
- Expire snapshots daily to clean up the accumulated snapshot metadata
Dremio’s automatic table optimization handles this compaction automatically for tables managed by Open Catalog. AWS S3 Tables also provides built-in compaction for streaming workloads.
The Latency vs. Maintenance Trade-off
The key insight: you do not always need sub-second latency. Most dashboards refresh every 5-15 minutes. If your consumers can tolerate 5-minute data freshness, using a 5-minute trigger interval produces 90% fewer small files and dramatically reduces compaction overhead.
Production Streaming Architecture
A production streaming-to-Iceberg pipeline typically includes four components:
- Message queue (Kafka, Kinesis, Pulsar): Buffers events from source systems
- Stream processor (Flink, Spark Streaming): Transforms and writes to Iceberg
- Compaction service (Dremio auto-optimization, Spark scheduled jobs): Merges small files on a recurring schedule
- Monitoring (metadata tables): Tracks file counts, sizes, and commit frequency
The most common mistake in streaming Iceberg architectures is deploying the stream processor without the compaction service. Without compaction, query performance degrades within days. Always deploy both together.
Choosing the Right Approach
Monitoring Streaming Health
After deploying a streaming pipeline, monitor these metrics daily using metadata tables:
- Commit frequency: How many snapshots are being created per hour?
- Average file size: Is the small file problem growing?
- Compaction lag: Are compaction jobs keeping up with the write rate?
- End-to-end latency: How long between an event occurring and it being queryable in Iceberg?
A well-tuned streaming pipeline commits every 1-5 minutes, produces files of 32-128 MB per commit, and has compaction running every 30-60 minutes to consolidate the small files into 256 MB targets.
Part 14 provides a hands-on walkthrough of Iceberg on Dremio Cloud.
Books to Go Deeper
- Architecting the Apache Iceberg Lakehouse by Alex Merced (Manning)
- Lakehouses with Apache Iceberg: Agentic Hands-on by Alex Merced
- Constructing Context: Semantics, Agents, and Embeddings by Alex Merced
- Apache Iceberg & Agentic AI: Connecting Structured Data by Alex Merced
- Open Source Lakehouse: Architecting Analytical Systems by Alex Merced
Free Resources
How to Add Rounded Corners to an Image Online
Rounded corners can make a screenshot, avatar, product image, or blog graphic feel more polished. The effect is small, but it often makes an image fit better inside a modern website, presentation, or social post.
The easiest way to add rounded corners depends on what you need next.
If the image is only going on a website, CSS might be enough:
img {
border-radius: 24px;
}
But CSS does not create a new image file. If you need to download and use the edited image somewhere else, you need a tool that exports the result.
That is where a browser-based image tool is useful.
Quick method
- Open https://image-corners.utilforge.xyz
- Drop your image into the tool.
- Adjust the corner radius slider.
- Add a border if the image needs separation from the background.
- Choose transparent or solid background.
- Export as PNG, JPG, or WebP.
PNG is usually the best choice when you want transparent corners. JPG is fine for photos when transparency does not matter. WebP is a good modern option for web use.
When rounded corners help
Rounded corners are especially useful for:
- app screenshots
- landing page images
- product documentation
- blog graphics
- avatars
- social media posts
- thumbnail images
They are not always needed. If the image already sits inside a designed frame, extra rounding can look redundant. But for raw screenshots, a little radius and padding can make the image feel more intentional.
Border or no border?
Use a border when the edge of the image blends into the page. This often happens with screenshots that have a white or very light background.
A thin gray or muted color border is usually enough. Thick borders can work for social graphics, but they often look heavy in documentation or product pages.
Transparent vs solid background
Use transparent background when you want the image to sit naturally on different page colors.
Use a solid background when you want a consistent card-like image, especially for social media, slide decks, or thumbnails.
Final tip
The most natural-looking rounded corners are usually subtle. Try a radius between 16px and 48px for normal screenshots, then adjust based on image size.
The subtle impact of AI (& IT) on jobs
If you are very fortunate you might find a career that excites you. That has certainly been the case for my career in software development but I am not sure it will be for much longer, and in a way “It’s payback time”.
Even if you have managed to snag your dream job, in the majority of cases there will still be tasks you don’t like doing. You also probably spend more than half of your working life doing tasks you don’t mind doing but don’t “push your buttons”. Well, it could be about to get worse due to AI.
As long as the amount of time you get to do the tasks you enjoy exceeds the time you spend on the tasks you hate, most people can cope. A little advice if your job falls short in tasks you enjoy:
-
If (and it’s a big if) you have a good manager, you should discuss the situation. There might not be opportunities to change things but if there are, a good manager realises a happy employee is more productive than a reluctant one.
-
Alternatively, you might have to take more drastic action and find a new role, maybe in another company. I realise this is far easier to type than done but life is too short to be doing what you don’t like if there is the slightest chance there could be something better.
-
Finally, you might want to consider that there might be a different career path that offers you more opportunities to engage in the tasks you enjoy but that is the biggest leap of all, and very few have the option for one reason or another.
These days we have to consider that AI might take your job, if the hyperbole from our tech overlords is to be believed. What is almost certain is AI will impact our jobs and take tasks off us “so we can be more productive”!
If the tasks being taken away are ones we rather not do anyway, that’s a good thing and means we will hopefully have more time to do the tasks we actually enjoy. However, it is just as likely that AI will take the tasks we relish, replacing them with more tasks we loath. This will drastically impact the quality of our working life.
It is with this realisation that I fear my career might have been built doing this even before AI entered the picture. Truth be told, this realisation dawned on me some time ago but I cowardly chose to bury it in the back of my mind. I suspect this fact is now coming back to haunt me.
As a developer of bespoke business applications my primary focus has been on simplifying the business process, delivering business efficiencies and producing “business value” (whatever that means) with scant regard for the potential impact such changes might have on the end-user’s enjoyment of their job, that was none of my concern.
Well, I could regard the way AI is likely to negatively impact my job as payback, guilty or not, and I would hazard I am not alone.
Made a Rust based AI agent
I built and published a Rust AI agent from scratch in my journey to learn Rust.
GitHub: https://github.com/Tejas1Koli/rust-ai-agent
crates.io: https: https://crates.io/crates/rust-ai-agent
What it currently supports:
• Local LLM execution with Ollama
• DuckDuckGo web search
• Async execution with Tokio
• Structured logging
• Typed configuration + validation
• Cross-platform binaries (Linux/macOS/Windows)
• Single-binary CLI distribution
One thing I found interesting while building this:
The entire source code is currently around ~25 KB.
An equivalent LangChain-style AI agent would usually end up much larger because of:
framework layers → wrappers → middleware → orchestration abstractions
Rust forced me to think more directly about:
• Runtime flow
• Async execution
• Tool orchestration
• Error handling
• Deployment
• System design decisions
Compared to many Python-based AI agents, Rust gives:
• Lower runtime overhead
• Better concurrency handling
• Stronger type safety
• Easier deployment through compiled binaries
• Less dependency/runtime bloat
Building this made me realize that AI tooling is increasingly becoming a systems engineering problem, not just a prompting problem.
Still improving:
• Provider abstractions
• Streaming
• Memory/runtime systems
• Better orchestration flow
You can try it with:
cargo install rust-ai-agent
P.S. I used tutorials/documentation while building parts of this, but implementing and shipping it taught me much more than just watching content.
Rust #AI #SystemsProgramming #OpenSource #DeveloperTools #LocalAI #Tokio #Ollama
Fiat’tan Duster’a yeni rakip geldi: Karşınızda Grizzly
Fiat’ın küresel pazarlar için tasarladığı yeni Grizzly modelinin ilk gösterimi yapıldı. İki farklı gövde tipiyle sunulacak araç piyasada Renault Duster gibi modellerle rekabet edecek.Sinemada bu hafta: Mandalorian ve Grogu, Yolcu, Önce Kadınlar (22 Mayıs 2026)
Bu hafta sinema salonlarında dokuz yeni film gösterime girerken, dijital platformlara da yeni filmler geliyor. İşte bu hafta sinemaseverleri bekleyen yeni filmler:Apple dolandırıcılara geçit vermedi: App Store’da 2.2 milyar dolarlık işlem engellendi!
Apple, 2025’te 2 milyondan fazla sorunlu uygulama başvurusunu reddetti ve dolandırıcılık amaçlı 1.1 milyardan fazla hesabın oluşturulmasını engelledi. İşte raporun ayrıntıları: