
Chunking in RAG: why your splitter matters more than your embedding model

Most RAG retrieval problems I’ve debugged came down to the same thing: someone swapped the embedding model three times, added a reranker, then gave up — and never once changed the chunker.

This is backwards. The chunker decides what your embedding model is allowed to see. A great embedding on a bad chunk is still a bad retrieval. And the published research from the last 18 months keeps pointing at the same conclusion: the “smart” chunking strategies don’t beat a tuned dumb one. What does beat them is augmenting each chunk with context.

This post walks through the four chunking strategies you’ll actually run into, why semantic chunking disappoints on benchmarks, and a working contextual retrieval implementation with the numbers from Anthropic’s report. By the end you should have a default chunking recipe you can defend with data, not vibes.

The four chunking strategies

Almost every chunker in the wild is a variation of one of these.

1. Fixed-size

Split every N tokens (or characters) with some overlap.

def fixed_chunks(text: str, size: int = 512, overlap: int = 50):
    tokens = text.split()
    step = size - overlap
    return [" ".join(tokens[i:i + size]) for i in range(0, len(tokens), step)]

Fast and reproducible. Cuts mid-sentence. Useful as a baseline so you have something to beat.

2. Recursive character splitting

The LangChain default. Tries paragraph breaks first, then sentences, then words — recursing until each chunk fits.

from langchain_text_splitters import RecursiveCharacterTextSplitter

splitter = RecursiveCharacterTextSplitter(
    chunk_size=800,
    chunk_overlap=100,
    separators=["nn", "n", ". ", " ", ""],
)
chunks = splitter.split_text(document)

This is the pragmatic default for prose. It respects natural breaks when it can, falls back to character splits when it can’t.

3. Document-structure-aware

Uses the document’s own structure as the split signal — Markdown headers, HTML tags, code AST nodes. The chunks carry the section path as metadata, which is gold for filtering at retrieval time.

from langchain_text_splitters import MarkdownHeaderTextSplitter

splitter = MarkdownHeaderTextSplitter(
    headers_to_split_on=[("#", "h1"), ("##", "h2"), ("###", "h3")],
)
chunks = splitter.split_text(markdown_doc)
# each chunk's metadata: {"h1": "...", "h2": "...", "h3": "..."}

Use this whenever your source has structure. Throwing it away to run recursive character splitting is a self-inflicted wound.

4. Semantic chunking

Embed each sentence, walk through the document, and start a new chunk every time the cosine distance between adjacent sentences exceeds a percentile threshold.

from llama_index.core.node_parser import SemanticSplitterNodeParser
from llama_index.embeddings.openai import OpenAIEmbedding

splitter = SemanticSplitterNodeParser(
    buffer_size=1,
    breakpoint_percentile_threshold=95,
    embed_model=OpenAIEmbedding(),
)
nodes = splitter.get_nodes_from_documents(documents)

Intuitively appealing. Topically coherent chunks should retrieve better. And it costs you an embedding call per sentence at index time.

The intuition is wrong often enough to matter.

Why semantic chunking often disappoints

Chroma Research ran a careful evaluation last year (Brandon Smith and Anton Troynikov, the latter a Chroma co-founder). They tested embedding-similarity splitters and LLM cluster chunkers against plain recursive and fixed-size chunking across multiple corpora, scoring with Intersection-over-Union and Recall.

The headline result: semantic methods produced inconsistent, often negligible gains. Sometimes they lost. Meanwhile they cost orders of magnitude more in embedding and LLM calls at index time.

The dominant variables across every experiment were chunk size and overlap, not the splitting strategy. A RecursiveCharacterTextSplitter at the right size was a hard-to-beat baseline.

If you’re going to spend engineering hours, spend them on a chunk-size sweep, not on a smarter splitter.

import numpy as np

def recall_at_k(retrieved_ids, relevant_ids, k=5):
    return len(set(retrieved_ids[:k]) & set(relevant_ids)) / len(relevant_ids)

# Sweep chunk_size with everything else held constant
for size in [256, 400, 600, 800, 1000, 1200]:
    chunks = chunk_corpus(documents, size=size, overlap=size // 8)
    index = embed_and_index(chunks)
    scores = [recall_at_k(index.search(q), gold) for q, gold in eval_set]
    print(f"size={size}  recall@5={np.mean(scores):.3f}")

You will see a clear curve, not a flat line. Pick the peak. Don’t ship a default you never measured.

What actually moves the needle: contextual retrieval

The interesting move isn’t a smarter splitter. It’s keeping the splitter dumb and giving each chunk back the context it lost when you split it.

This is Anthropic’s contextual retrieval recipe. For every chunk, prompt a cheap model with the full document and the chunk, and ask for 50-100 tokens of situating context. Prepend that context to the chunk before embedding.

import anthropic

client = anthropic.Anthropic()

CTX_PROMPT = """<document>
{doc}
</document>

Here is a chunk we want to situate within the whole document:
<chunk>
{chunk}
</chunk>

Give a short (50-100 token) context that situates this chunk
within the overall document for retrieval. Answer only with the
succinct context."""

def contextualize(doc: str, chunk: str) -> str:
    msg = client.messages.create(
        model="claude-haiku-4-5-20251001",
        max_tokens=200,
        messages=[{
            "role": "user",
            "content": [
                {"type": "text", "text": CTX_PROMPT.format(doc=doc, chunk=chunk),
                 "cache_control": {"type": "ephemeral"}},
            ],
        }],
    )
    return msg.content[0].text

augmented_chunks = [
    f"{contextualize(doc, c)}nn{c}" for c in chunks
]

The cache_control block matters. Without prompt caching you pay the full document token cost per chunk. With it, the document is cached once and reused across every chunk call — Anthropic reports roughly a 90% cost reduction on the context-generation step.

The reported numbers on their evaluation corpus (codebases, papers, fiction; top-20 retrieval failure rate):

  • Contextual Embeddings alone: 35% fewer failed retrievals (5.7% → 3.7%)
  • + Contextual BM25 (the same context augmentation applied to a BM25 index): 49% fewer (5.7% → 2.9%)
  • + a reranker on top of both: 67% fewer (5.7% → 1.9%)
  • One-time indexing cost: ~$1.02 per million document tokens with Haiku + prompt caching
  • Optimal chunk size in their tests: 800 tokens with 100-token overlap, beating both 400 and 1600

The 800/100 number is worth pausing on. It’s not “256 because that’s what the tutorial said.” It’s not “1024 because the context window is big.” It’s a measured optimum on a real corpus. Yours will land somewhere similar but not identical — run the sweep.

When contextual retrieval pays for itself

Indexing cost goes up. Query-time cost is unchanged. So the math is:

  • How often do you re-index? If you re-index weekly on a 100M-token corpus, that’s ~$100/week. Trivial for most production systems.
  • What’s a retrieval miss worth? In support automation a single wrong answer can be measured in minutes of human time. The math is usually obvious.

Where it doesn’t pay: tiny corpora (< 1M tokens) where you can fit everything in context anyway, or extremely high-churn corpora where you re-embed many times a day. Everything else, run it.

Note: Contextual retrieval is additive with everything else. Recursive splitter, document-structure-aware metadata, BM25 hybrid, reranker — they all stack. The 67% number assumes the full stack. Don’t read that line as “the reranker is doing nothing.”

A default recipe to start from

If you’re staring at a blank file, this is a reasonable first pass:

  1. Recursive character splitter at 800 tokens, 100 overlap.
  2. Preserve any structural metadata (Markdown headers, file paths) as chunk metadata.
  3. Add 50-100 tokens of LLM-generated context per chunk with Haiku + prompt caching.
  4. Hybrid: vector index + BM25 over the same augmented chunks.
  5. Rerank top-20 down to top-5 with a cross-encoder.
  6. Build a 100-query eval set from real user logs and run a chunk-size sweep against your corpus before treating any of this as settled.

Step 6 is the one most teams skip. Don’t.

Wrapping up

Chunking is one of the highest-leverage things in a RAG pipeline and one of the least-measured. The cheap experiments — sweeping chunk size, adding contextual augmentation — usually beat the expensive ones (a fancier embedding model, a third reranker).

Two links worth your time next:

What chunk size do you run in production — and have you actually benchmarked it against alternatives, or is it still the framework default? I’m curious how often teams have a measured answer here.
Meet tsParticles v4: richer colors, modular plugins, and a brand new paint system

tsParticles v4: HDR Colors, Paint Variants, and a Fully Modular Ecosystem

tsParticles v4.0 is finally here.

This release introduces long-requested features, major rendering improvements, and a completely modernized plugin architecture.

Compared to v3.9.1, nearly every subsystem has evolved.

Let’s take a look at what’s new.

✨ HDR & Display P3 Support

tsParticles v4 introduces HDR-ready rendering with automatic Display P3 color support.

Modern devices like recent Macbooks, iPhones, iPads, and high-end monitors can display a much wider color gamut than classic sRGB. v4 detects support automatically and switches the canvas to display-p3 when available.

{
  "hdr": true
}

(enabled by default)

The difference is immediately visible on compatible displays: reds, purples, neon tones, and gradients appear noticeably richer and more vibrant.

If Display P3 isn’t supported, tsParticles gracefully falls back to standard sRGB.

Additionally, canvas contexts now use:

desynchronized: true

to reduce rendering latency and improve animation smoothness.

🎨 The New Paint System

One of the biggest configuration improvements in v4 is the new unified paint system.

In v3, fills and strokes were configured separately:

  • particles.color
  • particles.stroke

In v4, both are merged into a single paint model:

{
  "particles": {
    "paint": {
      "color": { "value": "#ff0000" },
      "fill": {
        "enable": true,
        "opacity": { "min": 0.3, "max": 0.8 }
      },
      "stroke": {
        "color": { "value": "#000000" },
        "width": { "min": 1, "max": 3 },
        "opacity": 1
      }
    }
  }
}

The real power comes from paint variants.

paint can now be an array that combines both options. this allows to have hollow particles or no-stroke particles, or filled particles with a border, and you are in full control without going crazy with configurations:

{
  "particles": {
    "paint": [
      {
        "fill": {
          "enable": true,
          "color": { "value": "#ff0000" }
        },
        "stroke": {
          "color": { "value": "#00ff00" },
          "width": 2
        }
      },
      {
        "fill": {
          "enable": true,
          "color": { "value": "#0000ff" }
        },
        "stroke": {
          "color": { "value": "#ffff00" },
          "width": 1
        }
      }
    ]
  }
}

Each particle randomly selects a variant at creation time.

In v3, this usually required duplicated configs and particle groups. In v4, it’s built directly into the engine.

Migration

- particles.color
+ particles.paint.fill

- particles.stroke
+ particles.paint.stroke

🌈 Palette System

v4 introduces a completely new concept: Palettes.

Palettes provide curated combinations of:

  • background colors
  • blend modes
  • fill colors
  • stroke colors

with a single configuration entry.

import { loadFireworksGoldPalette } from "@tsparticles/palette-fireworks-gold";

await loadFireworksGoldPalette(engine);
{
  "palette": "fireworks-gold"
}

This automatically configures:

  • background.color
  • particles.paint
  • blend modes like "screen" or "lighter"

More than 100 palettes are already available across categories like:

Category Examples
🎆 Fireworks gold, neon, rainbow, silver
🌌 Space nebula, pulsar, supernova
🌿 Nature autumnLeaves, cherryBlossom
🌊 Water deepOcean, splash
🔥 Fire embersAndAsh, moltenMetal
🎮 Gaming minecraft, pacman, tetris
🖥️ Tech matrixRain, hologram, vaporwave
🎨 Spectrum rainbow, rgbPrimaries
🎯 Vibrant neon, retro, tropical

Each palette is distributed as its own npm package for optimal tree-shaking and lazy loading.

🧩 Fully Modular Plugin Architecture

The largest architectural change in v4 is the move toward a truly modular ecosystem.

Many features previously embedded in the core have been extracted into standalone plugins managed through the new PluginManager.

Benefits include:

  • smaller bundles
  • improved tree-shaking
  • easier maintenance
  • independent feature releases
  • lazy-loaded functionality

New Plugins

Plugin Description
@tsparticles/plugin-blend Blend modes (screen, lighter, multiply)
@tsparticles/plugin-manual-particles Precise particle positioning
@tsparticles/plugin-zoom Particle zoom effects
@tsparticles/plugin-move Unified movement system
@tsparticles/plugin-background-mask Background masking
@tsparticles/plugin-trail Particle trails
@tsparticles/plugin-interactivity Mouse/touch interactions
@tsparticles/plugin-themes Theme support
@tsparticles/plugin-responsive Responsive configurations

🔷 New Shapes

Two new built-in shapes are now available:

Shape Package
Matrix @tsparticles/shape-matrix
Squircle @tsparticles/shape-squircle

The Matrix shape supports animated katakana, ASCII, and kanji characters with randomized updates for classic cyberpunk effects.

🖥️ OffscreenCanvas Support

Rendering internals have been modernized using OffscreenCanvas.

When possible, tsParticles automatically transfers rendering using:

transferControlToOffscreen()

Benefits include:

  • reduced main-thread overhead
  • zero-copy rendering
  • lower rendering latency
  • a unified rendering pipeline

ILoadParams.element now accepts both:

  • HTMLCanvasElement
  • OffscreenCanvas

⚡ SpatialHashGrid Replaces QuadTree

The old QuadTree implementation has been replaced with a SpatialHashGrid.

This improves:

  • collision performance
  • particle link queries
  • memory efficiency
  • scalability in high-particle scenes

🔄 New Easing Functions

v4 adds three new easing families:

Easing Family Package
Gaussian @tsparticles/easing-gaussian
Sigmoid @tsparticles/easing-sigmoid
Smoothstep @tsparticles/easing-smoothstep

Example:

{
  "particles": {
    "move": {
      "speed": {
        "min": 1,
        "max": 5,
        "easing": "ease-in-out-sigmoid"
      }
    }
  }
}

📦 Migration Summary

New Root Options

+ hdr: boolean
+ palette?: string
+ resize: ResizeEvent

New Particle Options

+ paint: Paint | Paint[]
+ palette?: string

Moved to Plugins

- backgroundMask
- interactivity
- manualParticles
- responsive
- themes

Removed / Replaced

- color
+ paint.fill

- stroke
+ paint.stroke

📋 Quick Migration Guide

- "@tsparticles/engine": "^3.9.1"
+ "@tsparticles/engine": "^4.0.0"
- particles.color.value
+ particles.paint.fill.color.value
- particles.stroke.width
+ particles.paint.stroke.width
- interactivity.resize.enable
+ resize.enable

Package Renames

- @tsparticles/move-base
+ @tsparticles/plugin-move

- @tsparticles/updater-color
+ @tsparticles/updater-paint

- @tsparticles/updater-stroke-color
+ @tsparticles/updater-paint

Complete migration guide:

https://particles.js.org/migrations/from-v3

🔜 What’s Next

v4 establishes the foundation for the future of tsParticles.

The new architecture enables faster experimentation and community-driven extensions without bloating the core engine.

Planned areas of expansion include:

  • community-created palettes
  • additional standalone effects
  • new shapes

Useful Links

Happy coding 🚀

Note: This post was generated with the help of AI, then reviewed and refined manually.

Otomotiv Sanayii Derneği, 2026’nın ilk 4 aylık verilerini açıkladı

Otomotiv Sanayii Derneği, 2026’nın ilk 4 aylık verilerini açıkladı

Otomotiv Sanayii Derneği, 2026’nın ilk 4 aylık verilerini açıkladıOtomotiv Sanayii Derneği (OSD) 2026 yılının ilk 4 aylık dönemine ilişkin verileri açıkladı. Geçen yılın aynı dönemine göre toplam üretim yüzde 3 gerileyerek 448 bin 428 adet olarak gerçekleşti. Geçen yılın ilk 4 aylık dönemine göre yüzde 15 düşüş yaşanan otomobil üretimi ise 250 bin 276 adet oldu. Traktör üretimiyle birlikte toplam üretim ise 455 bin 526 adet olarak gerçekleşti. Ticari araç grubunda, yılın ilk 4 ayında üretim yüzde 17, ağır ticari araç grubunda yüzde 20 ve hafif ticari araç grubunda ise yüzde 17 artış gösterdi. 2025 yılının ilk 4 aylık dönemine göre ticari araç pazarı yüzde 6, hafif ticari araç pazarı ise yüzde 9 artarken ağır ticari araç pazarında yüzde 7’lik düşüş yaşandı. Yılın ilk 4 ayında bir önceki yılın aynı dönemine göre toplam otomotiv ihracatı adet bazında yüzde 9, otomobil ihracatı ise yüzde 27 geriledi. Bu dönemde, toplam ihracat 300 bin 718 adet, otomobil ihracatı ise 142 bin […]
Otomotiv Sanayii Derneği, 2026’nın ilk 4 aylık verilerini açıkladı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

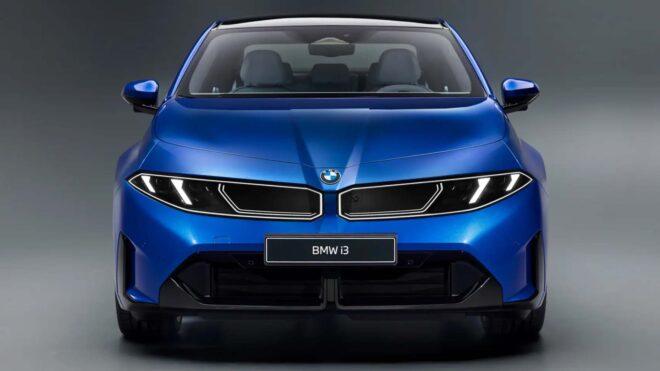
Yeni jenerasyon BMW 1 Serisi, hem elektrikli hem içten yanmalı olarak 2028’de gelecek

BMW 1 Serisi

BMW 1 SerisiAutocar tarafından aktarıldığı kadarıyla yeni jenerasyon BMW 1 Serisi, hem elektrikli hem de içten yanmalı motor seçenekleriyle 2028’de gelecek. Neue Klasse döneminin yeni tasarım dilini benimseyecek aracın, içten yanmalı tarafta 1.5 ile 2.0 litrelik dört silindirli benzinli motorlarla sunulacağı ve aynı zamanda plug-in hibrit seçeneğinin de listede olacağı söyleniyor. Burada 2.0 litrelik benzinli motor, elektrik motoru ve 100 km civarında tamamen elektrikli sürüş getirecek km 19,5 kWh kapasiteli bataryanın bir araya getirilmesi bekleniyor. Elektrikli tarafta tek bir elektrik motoru aracılığıyla 322 beygir güç sunması beklenen yeni araç için daha güçlü bir “M” versiyonunun hazırlanabileceği de aktarılıyor. Bu versiyonda gücün tam 463 beygire kadar taşınabileceği düşünülüyor. Tamamen elektrikli versiyonunda BMW i3’ten daha ufak batarya taşınacağı için 900 km menzil sunamayacak yeni 1 Serisi, kompakt bir seçenek olarak Avrupa başta olmak üzere birçok pazarda çok talep görebilir ve özellikle gençlerin ilgisini çekebilir.
Yeni jenerasyon BMW 1 Serisi, hem elektrikli hem içten yanmalı olarak 2028’de gelecek yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

“I Got Tired of Rewriting 4 AI CLI Config Files. So I Put Setup Behind One Button”

I like trying new AI coding tools.

I do not like reconfiguring them.

That was the part that kept getting old: every new CLI came with a different config file, different base URL setting, and a different way to point it at my local gateway.

After doing this a few too many times, I added a small feature to CliGate: a dashboard page that can install and configure the tools for me.

The annoying part

The tools are similar, but the setup is not:

  • Claude Code wants env vars
  • Codex wants ~/.codex/config.toml
  • Gemini CLI has its own proxy setup path
  • OpenClaw wants a JSON provider config

That means one simple goal:

“Point all of them at localhost:8081“

turns into four different setup chores.

What I changed

CliGate now has a Tools page that does two jobs:

  1. detect whether Node.js and the CLI tools are installed
  2. write the proxy config for each tool from the same UI

The code behind it is pretty direct.

The installer knows the official npm package for each tool:

codex: {
  name: 'Codex CLI',
  command: 'codex',
  npmPackage: '@openai/codex'
}

and the dashboard exposes actions like:

await this.api('/codex/config/proxy', { method: 'POST' });
await this.api('/api/tools/install/codex', { method: 'POST' });

So instead of editing files manually, I can open the panel, click install if a tool is missing, then click configure.

The part I wanted most

I did not want a generic “tool manager.”

I wanted a very specific workflow:

  • install Claude Code, Codex, Gemini CLI, or OpenClaw
  • point each one at the same local gateway
  • launch the tool without leaving the dashboard

That is what the page does now.

For example, the Codex side boils down to these settings:

chatgpt_base_url = "http://localhost:8081/backend-api/"
openai_base_url = "http://localhost:8081"

Claude Code gets its localhost base URL, Gemini CLI gets patched for proxy mode, and OpenClaw gets its provider block written with the same target.

Why this is better than another README section

I already had setup docs.

The problem was not missing information. The problem was repetition.

Every time I switched machines, reset a config, or wanted to try another CLI, I was doing the same boring setup work again.

Once I moved that into the product, the project became easier to try and easier to keep using.

Who this is actually for

If you use one tool with one API key, this is probably unnecessary.

If you keep bouncing between Claude Code, Codex, Gemini CLI, or OpenClaw, the friction adds up fast. That is the use case this page fixes.

If you’ve built a similar setup layer for AI tooling, I’m curious what you automated first: install, auth, config, or routing.

Your Inventory Counter Just Went Negative. Here’s Why — and How to Fix It.

Black Friday. 9:02am. Your e-commerce platform has been live for two minutes.

A limited-edition sneaker drops - 500 pairs in stock. Within seconds, the inventory counter is spinning. Add to cart. Checkout. Payment confirmed. Your servers in the US, EU, and Asia are all taking orders simultaneously to keep latency low for every customer on the planet.

By 9:04am, you’ve sold 620 pairs.

You have 500.

Your ops channel lights up. Support tickets flood in. You’re now emailing 120 paying customers to tell them their confirmed order doesn’t exist. The refunds go out. The trust doesn’t come back.

What went wrong wasn’t a bug in your payment code. It wasn’t a race condition in the traditional sense. It was something more fundamental: your distributed counter had no floor. And when multiple servers decremented it concurrently, each one saw a local view that looked safe - and the global invariant silently broke.

This is the problem Bounded Counters were designed to solve. And the solution is one of the most elegant ideas in the CRDT literature.

What an Inventory Counter Actually Is

Before the distributed systems, let’s ground this in something simple.

An inventory counter is just a number. It represents how many units of something you have available. When a customer buys one, the number goes down. When a shipment arrives, the number goes up. The rule is straightforward:

The counter must never go below zero.

In SQL, this is trivial:

CREATE TABLE inventory (
    product_id  BIGINT PRIMARY KEY,
    stock       INT DEFAULT 0 CHECK (stock >= 0)
);

The CHECK constraint enforces the floor. If a transaction tries to bring stock below zero, the database rejects it. One server. One source of truth. The constraint holds perfectly.

The same logic applies to a wallet: balance must never go below zero. To an ad budget: spend must never exceed the limit. To a rate limiter: requests must never exceed the ceiling.

These are bounded counters - counters with a numeric invariant that must never be violated.

Simple when you have one server. Deeply interesting when you have many.

The Moment Simplicity Breaks

Your platform grows. One server can’t handle Black Friday traffic. You distribute.

You deploy database replicas in the US, EU, and Asia. Each region accepts writes locally to keep latency low. The system is eventually consistent - replicas sync in the background, but any given server might be working from a slightly stale view of the world.

Here’s what happens to your inventory counter.

500 pairs in stock. Three servers, each seeing the same initial state: stock = 500. In the first two minutes, customers are hammering all three regions simultaneously.

The US server processes 200 orders. Locally: 500 - 200 = 300. Looks fine.

The EU server, working from the same initial state it loaded before the US orders propagated, processes 180 orders. Locally: 500 - 180 = 320. Also looks fine.

The Asia server processes 170 orders. Locally: 500 - 170 = 330. Still fine locally.

When the three servers finally sync: 500 - 200 - 180 - 170 = -50.
You’ve oversold by 50 pairs. Every check passed locally. The global invariant shattered silently.

Why the Solutions You’re Thinking Of Don’t Work Here

At this point, two approaches come to mind. Both fail at scale in ways worth understanding.

Distributed locks: Before decrementing, acquire a global lock on the inventory key across all replicas. Only one server writes at a time.

This works - and kills your latency. A lock that spans data centres separated by hundreds of milliseconds of network round-trip adds that latency to every single purchase. On Black Friday, when the whole point of distributing was to make checkout fast, a global lock turns your purchase flow into a queue. Users abandon cart. Revenue drops.

Strong consistency everywhere: Route all inventory writes through a single primary node or quorum. Every decrement gets serialised.

Also works. Also slow. Same problem as distributed locks, different mechanism. The CAP theorem is not negotiable: if you want strong consistency across geographically distributed nodes, you pay in latency and availability.

In Episode 2, PN-Counter gave us increment and decrement without coordination. But I ended that piece with a warning: PN-Counter has no floor. Nothing in its design prevents the score from going to -50,000. For Reddit karma, nobody cares. For inventory, that’s a P0 incident.

We need something new.

The Insight: Stop Distributing the Counter. Distribute the Permission.

Here’s the shift in thinking that makes Bounded Counters work.

With PN-Counter, we stopped trying to coordinate on every write. We accepted that replicas might temporarily disagree on the exact value. That was fine because eventual consistency was acceptable.

Bounded Counters need something stronger: a hard floor that can never be violated, even under concurrent writes, even during network partitions, even when replicas have stale views.

The key insight: you don’t need every replica to know the exact current value to enforce the floor. You just need every replica to know it has permission to decrement.

Think of it like tickets.

You have 100 items in stock. The floor is 0. That means you have 100 units of “decrement permission” - 100 tickets. You distribute those tickets across your three servers before the sale starts:

  • US server: 50 tickets
  • EU server: 30 tickets
  • Asia server: 20 tickets

Now the rule is simple: a server can only decrement if it has at least one ticket to spend. When it decrements by N, it spends N tickets.

The US server takes 50 orders: spends 50 tickets, now has 0. Stops accepting orders locally. The EU server takes 30 orders: spends 30 tickets, now has 0. Stops accepting orders locally. The Asia server takes 20 orders: spends 20 tickets, now has 0. Stops.

Total orders: 100. Exactly the stock. Global invariant: never violated.

Nobody coordinated on a single order. Every check was purely local. The constraint held globally because the math is airtight: if total tickets = total available decrements, and each replica can only spend what it owns, the sum of decrements can never exceed the total tickets.

This is the escrow idea, applied to distributed systems. You’re not distributing the counter. You’re distributing the permission to decrement.

The Wallet Walk-Through

Let’s trace this concretely with a wallet that must never go below zero.

Initial state: Wallet value = 100. Floor = 0. Available decrement rights = 100 − 0 = 100.

Rights distributed:

DC_A: 50 rights
DC_B: 30 rights
DC_C: 20 rights

Payment at DC_A: User pays 15 units.

DC_A checks local rights: 50 ≥ 15 ✓. Executes locally. No coordination needed.

DC_A: 35 rights remaining
DC_B: 30 rights remaining
DC_C: 20 rights remaining
Global value: 85

Concurrent payment at DC_B: User pays 25 units.

DC_B checks local rights: 30 ≥ 25 ✓. Executes locally. DC_A and DC_B never talked during either payment.

DC_A: 35 rights remaining
DC_B: 5 rights remaining
DC_C: 20 rights remaining
Global value: 60

Both payments went through. Both were validated purely locally. The global floor - wallet ≥ 0 - was never at risk, because the sum of all rights (35 + 5 + 20 = 60) exactly equals the remaining balance.

Failed payment at DC_C: User tries to pay 25 units.

DC_C checks local rights: 20 < 25 ✗. Cannot guarantee the floor locally.

Two options: fail immediately, or coordinate to borrow rights from another replica.

Rights transfer: DC_C asks DC_A for 10 rights. DC_A has 35 and can spare them.

DC_A: 25 rights  (gave 10 to DC_C)
DC_B: 5 rights
DC_C: 30 rights  (received 10 from DC_A)

DC_C re-attempts: 30 ≥ 25 ✓. Payment goes through.

DC_A: 25 rights
DC_B: 5 rights
DC_C: 5 rights
Global value: 35

At no point did the wallet go below zero. At no point did all three servers need to agree on the exact current value before processing a payment. The invariant held through local checks alone - with one brief coordination event only when a replica ran out of its allocated rights.

The Data Structure

The Bounded Counter state at each replica tracks three things:

type BoundedCounter struct {
    Min int64     // lower bound (e.g. 0)
    N   int       // number of replicas
    ID  int       // this replica's index

    R [][]int64   // R[i][j]: rights replica i transferred to j
                  // R[i][i]: rights replica i created for itself (via increments)
    U []int64     // U[i]: decrements executed at replica i
}

The rights matrix R is the core. Each replica owns the diagonal - R[i][i] is the rights it created. Off-diagonal entries R[i][j] track rights transferred from replica i to replica j. Every entry only ever increases. This is the grow-only constraint, applied to a matrix instead of a single value.

Reading the current value:

func (c *BoundedCounter) Value() int64 {
    var inc, dec int64
    for i := 0; i < c.N; i++ {
        inc += c.R[i][i]
        dec += c.U[i]
    }
    return c.Min + inc - dec
}

Sum the diagonal (total increments), subtract total decrements, add the floor.

Checking local rights:

func (c *BoundedCounter) LocalRights() int64 {
    id := c.ID
    var created, received, sent, spent int64
    created = c.R[id][id]
    for i := 0; i < c.N; i++ {
        if i == id { continue }
        received += c.R[i][id]
        sent += c.R[id][i]
    }
    spent = c.U[id]
    return created + received - sent - spent
}

Rights I created, plus rights I received, minus rights I gave away, minus rights I already spent.

Decrementing:

func (c *BoundedCounter) Dec(n int64) error {
    if c.LocalRights() < n {
        return fmt.Errorf("not enough rights")
    }
    c.U[c.ID] += n
    return nil
}

Only decrement if you have the tickets. Otherwise, reject or trigger a rights transfer.

Transferring rights:

func (c *BoundedCounter) Transfer(to int, n int64) error {
    if c.LocalRights() < n {
        return fmt.Errorf("not enough rights to transfer")
    }
    c.R[c.ID][to] += n
    return nil
}

The merge - identical pattern to every CRDT we’ve built:

func (c *BoundedCounter) Merge(other *BoundedCounter) error {
    for i := 0; i < c.N; i++ {
        for j := 0; j < c.N; j++ {
            if other.R[i][j] > c.R[i][j] {
                c.R[i][j] = other.R[i][j]
            }
        }
        if other.U[i] > c.U[i] {
            c.U[i] = other.U[i]
        }
    }
    return nil
}

Element-wise maximum. Every entry in R and U only ever grows. Merge is commutative, associative, idempotent. Replicas always converge.

Why the Invariant Can Never Break

Here’s the mathematical guarantee, stated plainly.

Total decrement rights across all replicas = current value − floor.

Each replica can only decrement by spending rights it owns. A replica cannot own negative rights. Therefore, the total decrements across all replicas can never exceed the total rights in the system. Therefore, the global value can never drop below the floor.

This holds even when replicas have stale views of each other’s state. Each replica’s local check - ”do I have enough rights?” - is conservative by design. If you have 20 rights and the operation needs 25, you say no. You might technically have been able to borrow rights from another replica - but you don’t know that yet, and the safe answer is always no.

Coordination is infrequent and amortised. For operations that fit within local rights, zero coordination. For operations that exceed local rights, one round-trip to request a transfer. Compared to coordinating on every write, this is a dramatic improvement in practice.

The Trade-Off You Should Know

Bounded Counter is the most complex CRDT in this series so far - and it comes with trade-offs worth naming.

Rights starvation: if a replica runs out of rights and the replica it needs to borrow from is unreachable (network partition, server failure), the operation fails. The invariant is safe - you’d rather fail an operation than violate the floor - but the user experience is a rejection, not a delay. For inventory, that means “out of stock” even when stock technically exists elsewhere. Acceptable for correctness. Worth designing around.

State size scales with replica count: the R matrix is N×N. With 3 replicas, 9 cells. With 100 replicas, 10,000. For most geo-distributed systems (2-7 data centres), this is negligible. For edge computing with thousands of nodes, you’d want a different approach.

Rights rebalancing is a background concern: a replica that consistently gets more traffic than its rights allocation will hit starvation more often. Operational tooling to monitor and rebalance rights distribution is not optional - it’s part of running this in production.

The Bigger Pattern

Three episodes in, the shape of CRDT design is clear.

Every CRDT we’ve built solves a hard distributed problem by identifying a constraint that eliminates ambiguity.

G-Counter said: make it grow-only. The maximum is always correct.

PN-Counter said: never decrement - use two grow-only counters and subtract at read time.

Bounded Counter says: never coordinate on every operation - distribute the permission to operate instead.

The constraint is always the solution. The art is finding the right one.

What’s Next

The next piece steps back from counters entirely.

What if instead of tracking numbers, you need to track membership - items in a set, users in a group, tags on a document? The same concurrent update problems apply. And a surprisingly simple grow-only constraint solves the basic case cleanly.

Episode 4: G-Set - grow-only sets, where the items go in but never come out, and why that constraint enables a clean distributed implementation.

The full series:

Subscribe to the newsletter to get each episode as it drops.
If you’re building distributed systems and want to think through invariant enforcement, CRDT design, or distributed architecture with someone who has been deep in this space - I do 1:1 sessions on Topmate.

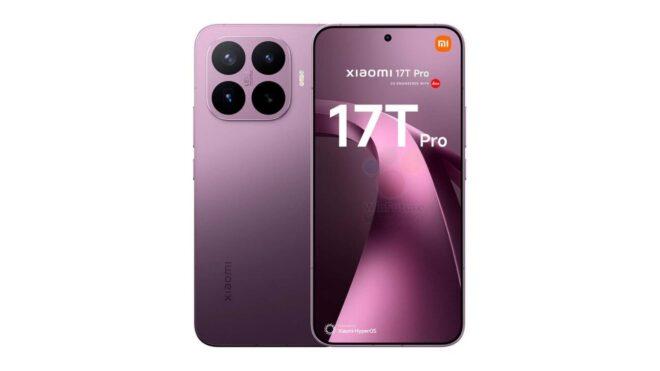
Türkiye satışı olası Xiaomi 17T serisi resmi olarak 28 Mayıs’ta tanıtılacak

Xiaomi 17T

Xiaomi 17TBugün Xiaomi’nin X hesabından yapılan paylaşıma göre “Xiaomi 17T” serisi resmi olarak 28 Mayıs’ta tanıtılacak. Kısa süre önce Roland Quandt tarafından detaylandırılan Xiaomi 17T, 6,59 inç boyutunda 120 Hz AMOLED ekran, MediaTek Dimensity 8500 Ultra işlemci, 12 GB LPDDR5X RAM, 256/512 GB UFS 4.1 depolama, 67W şarj destekli 6.500 mAh batarya ve 32 megapiksel selfie kamerasıyla geliyor. Cihazın arkasında ise 50 megapiksellik Light Fusion 800 sensörlü geniş açı, 5x optik zoom sunan 50 megapiksel telefoto ve 12 megapiksel ultra geniş açı kameralar bir araya getiriliyor. Üst model Xiaomi 17T Pro ise sızıntıya göre 6,83 inç boyutunda 144 Hz AMOLED ekran, MediaTek Dimensity 9500 işlemci, 12 GB LPDDR5X RAM, 512 GB UFS 4.1 depolama, 100W şarj destekli 7.000 mAh batarya ve 32 megapiksel selfie kamerasıyla geliyor. Cihazın arkasında 50 megapiksellik Light Fusion 950 sensörlü geniş açı, 5x optik zoom sunan 50 megapiksel telefoto ve 12 megapiksel ultra geniş açı kameralar bir […]
Türkiye satışı olası Xiaomi 17T serisi resmi olarak 28 Mayıs’ta tanıtılacak yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Gemini’dan güç alacak “Siri” için yeni detaylar paylaşıldı

Apple ChatGPT Siri LOG Tasarım

Apple ChatGPT Siri LOG TasarımBloomberg’den Mark Gurman tarafından aktarılan son bilgilere göre Apple, Gemini’den güç alacak yeni nesil Siri için ayrı bir uygulama sunacak. Bu uygulama aracılığıyla kullanıcılar Siri’yle, Gemini ya da ChatGPT ile olduğu gibi yazılı şekilde iletişim kurabilecek. Gurman’a göre bu uygulamada yapılan görüşmelerin bir süre sonra otomatik olarak silinmesine imkan tanıyan bir özellik de yer alıyor. İki yıldır beklenen yeni Siri’yi “beta” takısıyla kullanıma sunacağı aktarılan Apple, iddiaya göre sisteme güç verecek Gemini modellerini doğrudan kendi “Private Cloud Compute” sunucularında çalıştıracak. Bu sayede Apple kullanıcılarının yaptığı görüşmelere Google’ın erişim sağlayamayacağı söyleniyor. Resmi olarak önümüzdeki ay düzenlenecek WWDC26 etkinliğinde tanıtılacak yeni nesil Siri, genel kullanıma iOS 27 ve diğer yeni işletim sistemlerinin çıkacağı eylül ayında açılacak.

Gemini’dan güç alacak “Siri” için yeni detaylar paylaşıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

My Brother Doesn’t Code. Now He Ships Features.

My brother runs a large crew of pipelayers. The math they do in the field is genuinely hard. Rolling offsets, fitting angles, engineer tape measurements in decimal feet. I don’t understand any of it. But I know how to build apps, so I built him a calculator PWA.

The problem came after launch. Every time he needed something changed, he’d send me a message. “Can you make the font bigger?” “The offset calculator is wrong for 22.5 degree fittings.” I’d context-switch out of whatever I was doing, try to understand what he meant, get it wrong the first time, and eventually push a fix days later. I was the bottleneck, and I didn’t even understand the domain. He knows what the app needs. I know how to code. But the translation layer between us is lossy.

So I built an agent that cuts me out of the loop. He sends a message describing what he wants, the agent makes the changes, deploys a preview, and waits for his approval before pushing to production. No code. No git. No terminal. Just plain English and a preview link.

This isn’t a polished product. It’s a starting point. But the decisions behind it are intentional, and I think they’re worth walking through.

Why Telegram?

I needed a chat interface that was dead simple to use from a phone in the field. Telegram’s Bot API made this straightforward. You create a bot through @botfather, get a token, register a webhook URL, and you’re receiving messages as JSON payloads. No app to build, no OAuth flow, no UI framework. The user just opens a chat and starts typing.

The bot becomes the entire interface. My brother doesn’t need to know what’s behind it.

The Architecture

Here’s the full flow:

  1. User sends a message to the Telegram bot
  2. Telegram POSTs the message to an API Gateway endpoint
  3. A Lambda function receives it and invokes an AgentCore Runtime
  4. The AgentCore container runs Claude with access to the codebase
  5. Claude edits code, validates, builds, and deploys a preview to S3/CloudFront
  6. The agent sends status updates and the preview URL back through Telegram
  7. User reviews the preview and says “ship it” (or asks for changes)
  8. The agent merges to main and cleans up

Everything is defined in a single CDK stack. One cdk deploy creates all the infrastructure.

Claude as a Headless Developer

I chose Claude for the agent because of the Claude Agent SDK. It gives you a headless coding experience out of the box. Claude already knows how to read files, write code, run shell commands, and iterate on errors. I didn’t need to build any of that tooling. I just needed to point it at a codebase and give it constraints.

The query function from the SDK is the core of it:

from claude_agent_sdk import query, ClaudeAgentOptions

async for message in query(
    prompt=message_text,
    options=ClaudeAgentOptions(
        system_prompt=system_prompt,
        allowed_tools=["Read", "Write", "Edit", "Bash", "Glob", "Grep"],
        cwd=workspace,
        max_turns=30,
    ),
):
    if hasattr(message, "result"):
        result_text = str(message.result)

That’s the whole invocation. Claude gets the user’s message, a system prompt with context about the project, and a set of tools it can use. It figures out the rest.

Guardrails Make It Safe

Handing an AI agent the keys to a production codebase sounds risky. It is, if you don’t constrain it. The system prompt is where you define what the agent can and can’t do:

GUARDRAILS:
1. ONLY modify files in src/ and tests/ directories.
2. ALWAYS run validation before deploying.
3. If validation fails, fix the issues and re-run until it passes.
4. NEVER deploy code that fails validation.
5. Keep changes focused — don't refactor unrelated code.
6. Preserve the engineer tape (decimal feet) convention.
7. Fitting angles are 11.25 / 22.5 / 45 / 90 degrees — don't change these.

Rules 6 and 7 are domain-specific. I don’t know pipelaying math, but I know those values are sacred.

The workflow section tells Claude exactly how to validate, build, deploy a preview, and wait for approval:

WORKFLOW:
1. Understand the user's request. If unclear, ask for clarification.
2. Make the changes.
3. Run validation: npm run validate
4. If validation fails, fix and retry (up to 3 attempts).
5. Build and deploy to preview.
6. Share the preview URL.
7. Wait for user approval before merging.

The agent never pushes to main on its own. It always deploys to a preview URL first and waits.

Who Gets Access

Every incoming message goes through an authorization check:

if not is_authorized(message.user_id):
    return {"status": "ignored", "reason": "unauthorized"}

The allowlist is a comma-separated list of Telegram user IDs passed as a CloudFormation parameter at deploy time. Simple, intentional, hard to get wrong.

AgentCore: Ephemeral Compute with Long Runtimes

AI coding agents are slow. They need time to read code, think, write changes, run validation, fix errors, build, and deploy. That can take minutes.

Amazon Bedrock AgentCore gave me exactly what I needed. It spins up a container when a request comes in, keeps it warm for subsequent messages from the same user, and shuts it down after an idle timeout. Session affinity routes subsequent requests from the same session to the same container:

user_id = str(payload.get("message", {}).get("from", {}).get("id", "unknown"))
session_id = f"telegram-user-session-id-{user_id}"

The workspace persists. The conversation history persists. It feels stateful even though the compute is ephemeral.

The Async Trick

Telegram expects a 200 response within seconds. But the agent takes minutes. The solution is an async entrypoint:

@app.entrypoint
def handle_request(payload, context=None):
    message = parse_telegram_message(payload)

    task_id = app.add_async_task(
        f"agent-{message.user_id}",
        {"chat_id": message.chat_id, "user_id": message.user_id},
    )

    threading.Thread(
        target=_run_agent_background,
        args=(message.chat_id, message.user_id, message.text, task_id),
        daemon=True,
    ).start()

    return {"status": "accepted", "task_id": task_id}

The add_async_task call tells AgentCore “I’m not done yet, don’t shut down this container.” While the agent works, it sends status updates directly to Telegram through the Bot API.

One CDK Deploy

The CDK stack creates: API Gateway endpoint, Lambda relay function, AgentCore Runtime (container built from source), S3 + CloudFront for previews, and a Secrets Manager secret for the GitHub deploy key.

agent_runtime = agentcore.Runtime(
    self, "PipelayerRuntime",
    runtime_name="pipelayer_agent",
    agent_runtime_artifact=agentcore.AgentRuntimeArtifact.from_asset(AGENT_DIR),
    environment_variables={
        "TELEGRAM_BOT_TOKEN": telegram_bot_token.value_as_string,
        "DEV_BUCKET": dev_bucket_name.value_as_string,
        "DEV_CDN_DOMAIN": dev_distribution.distribution_domain_name,
        "GITHUB_DEPLOY_KEY_SECRET": deploy_key_secret.secret_arn,
    },
)

The Real Takeaway

AI agents work best when you constrain them. The guardrails in the system prompt are what make this safe enough to hand to someone who doesn’t code. The agent can’t touch files outside src/ and tests/. It can’t deploy without passing validation. It can’t push to production without explicit approval.

My brother doesn’t need to understand React, or git, or AWS. He just needs to describe what he wants. The agent handles the rest, within boundaries I set.

If you want to dig into the full implementation, the repo is at github.com/singledigit/pipelayer-agent. It’s not perfect, but it works. And my brother ships features now.

I built 400+ web tools, but the data forced a pivot. Here is what I learned.

Hey everyone,

A while back, I set out to build 100Plus Tools. The initial goal was completely broad: create a massive, fast library of general utilities. I was building simple calculators, text converters, basic formatting tools, and SEO helpers, trying to cover as much ground as possible.

But after tracking the usage data, something interesting happened.

The generic audience didn’t really care about another text converter. Instead, it was developers, DevOps engineers, and QA techs who were actually showing interest and returning to the site. The traffic wasn’t coming from random web surfers; it was coming from people looking for fast, privacy-first JSON parsers, encoding helpers, and debugging utilities.

Instead of fighting that signal, I leaned directly into it.

Today, the platform has grew to over 420+ browser-based tools, and the vast majority are now focused entirely on developer workflows: handling APIs, data transformation, JSON formatting, security, JWT decoding, and webhook debugging.

Expanding beyond the web: The extensions

As the platform grew, I realized that some debugging workflows shouldn’t require opening a new browser tab. To bridge that gap, I started building side-utilities directly into the browser. A few recent launches include:

API Detective: A Chrome extension built to spy on the hidden background plumbing of websites. It sniffs out underlying REST, GraphQL, JSON, and WebSocket calls so you can reverse-engineer or debug frontend behaviors instantly.

API Error Decoder: Failed API calls can be incredibly vague. This extension captures 4xx/5xx responses, CORS failures, and auth issues, then translates the technical jargon into plain-English explanations of what actually went wrong.

DevTab: A clean, distraction-free “New Tab” replacement that replaces the default layout with quick-access bookmarks, dev utility shortcuts, and tool search to cut down on daily friction.

The Realization: Developers still just need simple utilities

With everything moving toward heavy “AI-everything” right now, I realized something vital: developers still just need fast, lightweight, focused tools that remove daily friction. They need visibility into data, fast encoding helpers, and solid debugging workflows that load instantly and don’t track their inputs.

That is the direction I’m pushing. The goal isn’t to chase trends anymore; it’s to build a genuinely useful, comprehensive ecosystem for developers over time.

It’s still early, and I’m updating the codebase daily.

Since the platform is now shifting to serve this exact community, I’d love to get your brutally honest feedback:

What is the one utility tool you use daily that you wish were faster or ad-free?

Are there specific formatting, network, or API debugging pain points you face that are missing a dedicated tool?

Check it out at 100Plus Tools and let me know your thoughts or feature requests in the comments! 🛠️