Ujorm3: New Lightweight ORM for JavaBeans and Records, Final Version

Do the simplest thing that could possibly work. — Kent Beck, creator of Extreme Programming and pioneer of test-driven development.

Today, I would like to introduce the final version of the Ujorm3 library with a newly written ORM module for working with JavaBean and Record objects in the context of relational databases. The goal of this module was a transparent solution without additional dependencies, supporting type-safe construction of SQL statements.

For fast manipulation of domain object data, the library compiles its own bytecode at runtime, achieving performance comparable to handwritten code. The core of the library intensively utilizes the Typed Key Pattern design pattern. Two interfaces in particular were carried over from the original version of the Ujorm library — Ujo and Key. Both interfaces applied this pattern back in 2007, even before the pattern received its name.

The Typed Key Pattern design pattern represents a technique for reading and writing domain object values through its key API, replacing traditional getters and setters with an internal property map. Keys are type-parameterized descriptors carrying information about the data type (or a default value) and, thanks to generics, ensure type safety without casting; they also allow mass operations on attributes without reflection. In terms of internal representation, this approach corresponds to the Typesafe Heterogeneous Container concept, which was first systematically published by Joshua Bloch in May 2008 in the second edition of the book Effective Java following the introduction of generics to the Java language.

Let me remind you of some basic information from the previous blog post: the default mapping of entity attributes to database columns is described using JPA annotations from the Jakarta package. The @Column annotation is used for mapping attributes to columns, and @Enumerated is used for mapping enum types. The table name is declared with the @Table annotation.

Since the library does not use any binary-modified classes, partial column updates in an UPDATE statement require providing a list of modified attribute names (for example, as a String[] array) or the original object, from which the library creates this list itself. A single database table can be serviced by several classes — typically representing a subset of the entity.

One of the goals of the new library was to find the optimal balance between utility value and minimalist source code. The author believes that such an approach has a positive impact on minimizing errors and significantly extends the lifespan of the library. However, certain limitations arise from this approach. For example: The library does not support lazy-loading and supports only M:1 relationships when mapping relations.

The ORM module of the Ujorm3 library offers a set of tools with different levels of abstraction for database commands. Choose the solution that best suits your specific requirement:

  1. EntityManager — the fastest way to handle CRUD (Create, Read, Update, Delete) operations with a single table using a primary key. For such elementary cases, the class generates the SQL command itself.
  2. SelectQuery — a tool primarily designed for fetching data, including relations. It supports filtering data using type-safe Criterion objects, which can be arranged into a binary tree (using AND and OR operators). An alternative is using the bind() method. For specific cases, the beginning and end of the generated SQL command can be manually appended.
  3. SqlQuery — a low-level universal class for general requirements. It allows writing native SQL while maintaining safety using the bind(), label(), and column() methods. Using a generic mapper, the library can automatically populate relational objects as well. The last two classes share a common ancestor, which can serve as a base for any future implementations.

Let’s look at simple usage examples, starting with the low-level approach. The following method inserts a city into the database table (using a fluent API) and returns the identifier of the inserted row.

public Long insertCity(String name, String country) {
    return SqlQuery.run(connection(), query -> query
        .sql("""
             INSERT INTO city
             ( name,  country_code) VALUES
             (:name, :countryCode )
             """)
        .bind("name", name)
        .bind("countryCode", country)
        .executeInsert(rs -> rs.getLong(1))
        .findFirst().orElseThrow());
}

The next example searches for employees and fetches their data, including the city name. The ResultSetMapper class supports multithreaded access.

static final ResultSetMapper EMPLOYEE_MAPPER =
             ResultSetMapper.of(Employee.class);

public List<Employee> findEmployees(Connection connection, Long minId) {
    return SqlQuery.run(connection, query -> query
        .sql("""
             SELECT e.id  AS ${e.id}
             , e.name     AS ${e.name}
             , c.name     AS ${c.name}
             FROM employee e
             JOIN city c ON c.id = e.city_id
             WHERE e.id >= :id
             """)
        .label("e.id"  , MetaEmployee.id)
        .label("e.name", MetaEmployee.name)
        .label("c.name", MetaEmployee.city, MetaCity.name) // Key Path mapping
        .bind("id", minId)
        .toStream(EMPLOYEE_MAPPER.mapper()) // Generic mapping including relations
        .toList());
}

The MetaEmployee class is an automatically generated metamodel created using the optional ujorm-meta-processor APT plugin. However, mapping can also be written directly in the SQL SELECT statement at the column alias position in the format of dot-separated property names (properties, for example, boss.name). However, it needs to be enclosed in quotes (or other characters depending on the database type). If the DB column name matches the attribute, explicit mapping is unnecessary. For example:

SELECT e.id, e.name, c.name AS "boss.name" FROM ...

The last example performs a similar SELECT using the SelectQuery class. Here, the columns(true) method loads all columns of the table, including foreign keys. The column(...) method adds another column to the mapping and can also handle multiple relations.

The relation type is determined by the nullable property from the JPA annotation: a mandatory object attribute (marked as nullable=false) generates an INNER JOIN relation type, otherwise it generates a LEFT JOIN. The beginning of the SQL statement can (optionally) be changed using the sql() method, and the end can (optionally) be appended using the tail() method.

final EntityContext CTX = EntityContext.ofDefault();
final EntityManager<Employee, Long> EMPLOYEE_EM = CTX.entityManager(Employee.class);

List<Employee> select(Connection connection) {
    return SelectQuery.run(connection, EMPLOYEE_EM, query -> query
            .sql("SELECT")  // Optional
            .columns(true)
            .column(MetaEmployee.city, MetaCity.name)     // INNER JOIN
            .column(MetaEmployee.boss, MetaEmployee.name) // LEFT JOIN
            .where(MetaEmployee.id.whereGe(1L).and(MetaCity.id.whereGe(1L)))
            .tail("ORDER BY", MetaEmployee.id)
            .toList()
    );
}

The code of the Ujorm3 project is thoroughly covered by JUnit tests. Integration tests are run via a Bash script (in the bin directory) against dockerized databases: PostgreSQL, MySQL, MariaDB, OracleFree, and MSSQL Server. More detailed information about the Ujorm3 library can be found on the homepage of the project — including additional examples.

A reference usage of Ujorm3 can be found in the PetStore project, which (aside from the Ujorm library) has no other Maven dependencies. The PetStore project then gave rise to a prototype web application called TopMovies for movie viewers — this application recommends movies to users based on how their ratings match a virtual group with similar preferences.

Apart from the Ujorm library, this project also has no other dependencies. Data is stored in an H2 database, or optionally in PostgreSQL. Although the project is not publicly available, you can freely try the prototype at the provided link (the number of fictitious users is limited).

Web Links

  • Homepage — is part of the Ujorm3 project hosted on GitHub.
  • PetStore — a sample open-source application demonstrating the Ujorm3 library. It uses the ORM module for database queries and the Element class to build the UI.
  • TopMovies — a prototype application for recommending movies based on the alignment of user ratings with a virtual movie group.
  • JavaDoc — class description.
  • An ORM performance comparison — comparing performance and other metrics with Hibernate, Jdbi, MyBatis, and other libraries. Tests run on PostgreSQL (in Docker) and H2 (in-memory) databases using Java 25.

From 99 Traders to One Signal: Implementing a Distilled KOL Consensus Strategy on FMZ

The word “distillation” has been showing up everywhere lately. In AI it usually means compressing complex capabilities into a more compact, reusable form. The same idea carries over to strategy research — and when you make it concrete, what you’re really doing is taking knowledge that was previously scattered, fuzzy, and dependent on subjective experience, and turning it into something you can compute, verify, and continue to refine.

The crypto-kol-quant project has been getting a lot of attention recently. What’s actually interesting about it isn’t the number of KOLs it scrapes, or the fact that it uses LLMs. It’s that the project tries to do something quantitative research rarely attempts: distill traders’ experience into a set of computable capability factors, and then aggregate those factors into a consensus signal. That’s a question worth taking seriously. Because if a group of long-active, stylistically consistent traders really have built up their own cognitive frameworks for the market, those frameworks shouldn’t only live in tweets, charts, and offhand remarks — they ought to be extractable, organized, and made part of a runnable strategy pipeline.


Working from that premise, we built an early implementation inside the FMZ environment. The goal wasn’t to “port” the project — it was to wire up its core logic from end to end: pull market data, translate the market into structured state, decide which trading capabilities are being triggered by that state, map those capabilities back to trader profiles, and finally aggregate every trader’s individual judgment into a weighted consensus signal. It’s clearly not a finished trading system, but it does demonstrate one important thing: trader experience really can be compressed, structured, and inserted into a strategy’s decision flow.

What Gets Distilled Is Capability, Not Opinion

When people first encounter a project like this, they tend to read it as “a KOL sentiment strategy.” That’s not quite right. The original project isn’t trying to count who’s bullish today or who’s calling tops and bottoms. It’s pushing further: how does this trader actually understand the market? Under what kind of structure does he lean long? Does he focus on trend, position, pattern, volatility, or macro context? And can the way he makes those calls be organized into a stable set of capability tags?

Once you frame the problem that way, the strategy’s center of gravity shifts. The system stops caring about any single statement and starts caring about the methodology behind it. Put differently: what gets distilled here isn’t text — it’s trading knowledge itself. The system tries to translate subjective experience, which used to require a human to interpret, into rules a program can recognize and call. That’s the biggest difference between this and the usual sentiment models. It’s not measuring how hot the market mood is. It’s reconstructing how different trading frameworks would react to the current market.

Step 1: Translate the Market Into State Variables

For distillation to actually land, the first step can’t be prediction — it has to be feature engineering. The reason is simple: a trader’s language is written for humans, not programs. Take a sentence like “price pulled back to a key moving average, decent spot to add on the second tap.” A trader gets it instantly, but a program has to break it down: which moving average — the 50-day or the 200-day? Is price actually near that line? Is the trend still intact? Did a confirming candle appear?

So the system’s first job isn’t to produce a long/short call. It’s to convert raw market data into a set of structured states. The most basic layer here uses price to build trend and momentum features. Moving averages, exponential moving averages, RSI, MACD — these aren’t there to pile up indicators, they’re there to answer a simple question: roughly what state is the market in right now?


The key code:

# Use moving averages of different periods to describe price's position within trends
f['ma20']  = _sma(c, 20)
f['ma50']  = _sma(c, 50)
f['ma100'] = _sma(c, 100)
f['ma200'] = _sma(c, 200)

# Exponential moving averages weight recent price changes more heavily
f['ema20'] = _ema(c, 20)
f['ema50'] = _ema(c, 50)

# RSI captures whether the market is overbought/oversold or losing momentum
f['rsi14'] = _rsi(c, 14)

# MACD line, signal line, and histogram together track trend and momentum shifts
ml, ms, mh = _macd(c)
f['macd']      = ml
f['macd_sig']  = ms
f['macd_hist'] = mh

The code isn’t doing anything complicated. Moving averages help the system locate current price relative to longer-term trend; RSI and MACD describe whether momentum is building or fading. None of this is a trading decision yet — it’s purely a “market state” layer.

The system also adds volatility and positional features, because a lot of trading judgments don’t rely on trend alone — they also depend on whether we’re in a volatility-compression phase, or whether price is sitting near a range high or low.

The corresponding code:

# Log returns are the basis for volatility computation
logr = np.log(c / c.shift(1))

# 30-day annualized realized volatility, gauging current volatility level
# Note: sqrt(365) — crypto trades around the clock, so we annualize on
# calendar days rather than the 252 trading days used for equities
f['rv30'] = logr.rolling(30, min_periods=10).std() * np.sqrt(365)

# Recent 20-day and 50-day highs/lows, used to locate price within recent structure
f['high_20d'] = h.rolling(20, min_periods=1).max()
f['low_20d']  = l.rolling(20, min_periods=1).min()
f['high_50d'] = h.rolling(50, min_periods=1).max()
f['low_50d']  = l.rolling(50, min_periods=1).min()

rv30 captures the recent annualized volatility level. The range highs/lows tell the system where current price sits inside the recent price structure. On top of that, macro context gets folded into the state space too — there’s a kind of trader who doesn’t only look at the coin price; they’re simultaneously watching the dollar index, equity risk appetite, and the rate environment. The code aligns these to the daily frame and then turns them into readable state:

# DXY as a backdrop for dollar strength
if 'DXY' in macro:
    dxy = _align(macro['DXY'])
    f['dxy_ret_20d']    = dxy.pct_change(20)
    f['dxy_trend_down'] = (dxy.pct_change(20) < -0.01).astype(int)

# SPX as a proxy for risk appetite
if 'SPX' in macro:
    spx = _align(macro['SPX'])
    f['spx_ret_20d']  = spx.pct_change(20)
    f['spx_trend_up'] = (spx.pct_change(20) > 0).astype(int)

The point of this whole step compresses to one sentence: take “what the market looks like right now” and turn it into structured state the machine can keep reading. Without this layer, there’s nothing left to distill.

Step 2: Encode Subjective Experience as Capability Factors

Features alone aren’t enough — features only describe the market, they don’t say what that state means. The next step is to write traders’ experience into rules: given the current state variables, decide which trading capabilities are being triggered.

This is where the strategy’s distillation flavor is strongest. We’re no longer talking abstractly about “frameworks that matter”; we’re committing them to actual program conditions. The current implementation’s capability factors span pattern, structure, indicator, cycle, and macro layers. Some come from pattern recognition — bull flags, bear flags, double tops/bottoms, head-and-shoulders, triangles. Some come from structural analysis — Wyckoff, SMC, ICT-style frameworks. Some come from indicators themselves — RSI divergences, golden/death crosses, Bollinger band squeeze breakouts. And some come from cycle and macro context — halving cycles, trending vs. ranging market regime shifts, DXY drawdowns, risk-on rebounds.

A textbook example is “trend pullback continuation.” Plenty of traders share this pattern: if the larger trend is still up, price pulls back to a key moving average, and the current candle shows a confirming bid, that often means the trend continues. The program states it directly:

# Check whether current price is close to the 50-day moving average
near_ma50 = abs(close - ma50_v) / close < 0.02 if close > 0 else False

# If the 50-day MA is still above the 200-day MA, and a green candle shows up
# right at the pullback, score this as a trend-continuation capability signal
# (In production you'd want extra confirmation — volume, candle body, lower wick)
s['cap_014_trend_pullback_continuation'] = 0.6 if (ma50_gt and near_ma50 and is_green) else 0.0

There’s nothing mysterious here — it’s just breaking a sentence of human language into a few conditions a machine can evaluate one by one. Another example is “Bollinger squeeze breakout.” For many traders, a long stretch of compressed volatility followed by a sudden expansion (up or down) usually signals a fresh directional choice. The rule looks like:

# bb_w20_p1 is the 20-period mean of Bollinger bandwidth (the squeeze baseline).
# If the previous candle's bandwidth sits below that baseline, treat it
# as a volatility-contraction state.
squeezed = bb_w_p1 < bb_w20_p1 if bb_w20_p1 > 0 else False

# Squeeze followed by a breakout above the upper band -> positive signal
# Squeeze followed by a break below the lower band  -> negative signal
s['cap_021_bollinger_squeeze_breakout'] = (
    0.6  if (squeezed and close > bb_u) else
   -0.6  if (squeezed and close < bb_l) else 0.0
)

Macro factors get the same treatment. For traders who lean macro, BTC isn’t an isolated price series — it’s affected by the dollar, equities, and the rate environment, so those views are also written into capability checks:

# Falling DXY is generally read as a positive backdrop for BTC
s['cap_027_dxy_inverse_btc']  = 0.4 if (not _nm(dxy_r20) and dxy_r20 < -0.01) else 0.0

# Rising S&P implies improving risk appetite
s['cap_028_spx_risk_on_off']  = 0.4 if (not _nm(spx_r20) and spx_r20 >  0.02) else 0.0

# Falling short-end yields imply a marginal liquidity tailwind
s['cap_029_yields_liquidity'] = 0.4 if (not _nm(y_r20)   and y_r20   < -0.02) else 0.0

What matters at this layer isn’t how many rules we wrote — it’s that we completed the most critical move in the entire distillation: compressing judgments that previously required subjective interpretation into computable conditions. Worth noting in passing: most capability factors in the current version are condition-triggered rather than continuously scored. That means the system is closer to detecting whether a particular structure holds than to repricing every micro-fluctuation. It’s why this implementation fits daily or mid-to-low frequency reasoning better than high-frequency trading.

Step 3: Don’t Sum Factors — Map Them Back to Trader Profiles


If the strategy stopped at the factor layer, it would still just be a regular rule system. What makes the original project distinctive is that it doesn’t stop there — it pushes one step further: factors don’t directly determine direction; they get mapped back to trader profiles first.

This part matters. Real traders don’t “use all capabilities equally.” Some lean into trend, some into structure, some into cycle, some into macro. Faced with the same market state, different traders care about completely different things. So instead of averaging all factors at once, the system reads each trader’s capability preferences first, then computes that trader’s individual signal given the current factor state.

The profile-loading logic:

# For each trader, load the capability factors they actually use, with weights
caps = {c['id']: float(c.get('weight', 0.5))
        for c in p.get('capabilities_used', [])}

profiles.append({
    'handle': p.get('handle', item['name'][:-5]),
    'caps':   caps
})

Each profile is essentially answering one question: which capability factors does this trader actually rely on, and how heavily does each one weigh in his framework? Once profiles are in hand, the system computes each trader’s “personal signal” for the current market:

for p in profiles:
    sig = 0.0
    wt  = 0.0

    # Iterate over every capability this trader cares about
    for cap_id, w in p['caps'].items():
        score = factor_scores.get(cap_id, 0.0)

        # Current factor score scaled by this trader's preference weight
        sig += w * score
        wt  += abs(w)

    # Normalize to get this trader's personal signal in the current market
    trader_raw = sig / wt if wt > 0 else 0.0

By this point the system feels different. It’s no longer just looking at “which factors lit up.” It’s approximating something else: if you handed today’s market to these 99 traders, how would each of them judge it?

Step 4: From Personal Signals to Weighted Consensus


Once each trader’s personal signal is computed, the system finally enters the consensus layer. “Consensus” here isn’t a vote, and it’s definitely not whoever-shouts-loudest-wins — it factors in historical effectiveness as well.

A quick note for readers new to the term: IC stands for Information Coefficient — the historical correlation between a signal and forward returns. Higher absolute IC means the signal carries more information.

The two most important outputs in the current code are ic_weighted and trust_adjusted. The core logic:

# First: weight only traders with positive IC, producing ic_weighted
pos_w  = sum(max(t['ic'], 0) for t in trader_signals)
ic_wt  = (
    sum(t['signal'] * max(t['ic'], 0) for t in trader_signals) / pos_w
    if pos_w > 0 else 0.0
)

# trust_adjusted goes a step further:
# positive-IC traders are used directly; negative-IC traders are flipped
# and then everything is weighted by absolute IC magnitude
abs_w = sum(abs(t['ic']) for t in trader_signals)
trust = (
    sum((t['signal'] if t['ic'] >= 0 else -t['signal']) * abs(t['ic'])
        for t in trader_signals) / abs_w
    if abs_w > 0 else 0.0
)

Two simple but important principles are embedded here. First: traders who’ve been more effective historically carry more weight today. Second: traders whose historical IC is negative aren’t thrown out — they may be used as inverse indicators instead. So trust_adjusted isn’t just “what does the crowd think” — it’s “who thinks what, and whose view do we actually trust.”

One caveat worth flagging: flipping a negative-IC trader assumes that negative IC reflects stable contrarian information, not statistical noise. In practice you’d want a significance test or a sample-size gate before using the inverse — otherwise you’re amplifying randomness instead of correcting it.

This is also why the system reads differently from a normal sentiment model. It isn’t tallying voices — it’s running a round of cognitive aggregation that’s been checked against history. Compress the whole method into one sentence: turn the market into state variables, map state variables into capability factors, map capability factors into per-trader personal signals, and finally aggregate those personal signals by historical effectiveness into a consensus call.

What the FMZ Implementation Actually Achieves

If the project stayed in research mode, the system would feel more like a “consensus analyzer.” On FMZ, the priority is wiring the entire pipeline so it can keep running. The most important code is just three lines:

# Step 1: turn raw price data and macro variables into structured state
feat_df = build_features(records, macro if macro else None)

# Step 2: evaluate which capability factors are triggered given the state
factor_scores = evaluate_factors(feat_df)

# Step 3: map factors back to trader profiles, then aggregate to consensus
consensus = compute_consensus(factor_scores)

These three lines are the strategy’s three most important abstractions. Layer one handles market state; layer two handles capability evaluation; layer three handles trader consensus. Execution, risk control, and state display sit downstream of these, but from a research-logic perspective the critical part is already complete. The point of this implementation isn’t how many runtime details it adds — it’s that the original project’s capability profiles are no longer static files, the factors are no longer just research outputs, and the consensus is no longer just a number in a report. They’ve been wired into a continuously running judgment loop.

Why It’s Still Just a Prototype

This implementation isn’t the endgame. The current code uses BTC daily bars, so it’s better suited to mid-to-low frequency consensus calls than to high-frequency trading. Its core still revolves around daily structure, cycle position, macro backdrop, and trader capability preferences. Trader profiles and IC values are still static inputs — the system hasn’t yet entered an online-evolution phase. In other words, “knowledge distillation” step one is done, but “the distilled knowledge keeps self-correcting” hasn’t fully landed.

That doesn’t take away from what the project does demonstrate, which is itself important: trader experience really can be compressed, structured, and inserted into a strategy pipeline. The value isn’t that it produces stable returns yet — it’s that it advances a research path that previously sat at the concept level into something runnable. How those capability factors should evolve, how trader weights should update, and how consensus should keep recalibrating against live markets — those are questions only more runtime data can answer.

Closing

What’s genuinely instructive about crypto-kol-quant isn’t the volume of trendy concepts it strings together. It’s that it pushes a hard-to-systematize problem one step forward: take traders’ experience, turn it from expression into capabilities, from capabilities into factors, from factors into consensus. The FMZ implementation’s job is to actually run that distillation pipeline end-to-end. It doesn’t oversell itself as the final answer, and it doesn’t try to hide the fact that it’s still an early prototype. But it does prove one thing: trading experience doesn’t have to live only in charts and language — it can be distilled, structured, executed, and even placed inside a system that continuously judges the market.

If traditional quant is good at finding patterns inside price series, then a strategy of this kind points to a direction worth pushing: extract patterns from human cognition, then let those patterns participate in the market in turn. And that, more than anything else, may be why “distillation” deserves attention in strategy research.

Original project: Tower of Locked Demons Skill — Refining 99 Crypto Traders (suo yao ta Skill)

Special thanks to user GiantBin for the underlying ideas. If you have your own thoughts on this direction, we’d welcome the conversation.

Gnoke-Database v3 is live — here’s what actually shipped

Gnoke-database

Some days ago I wrote about Gnoke-Database — a self-hosted Firebase alternative that runs on any PHP host with SQLite. The response was more than I expected, so I wanted to follow up with what actually exists now, not just the idea.

What shipped

v3 is a street-beta. That means the core engine is frozen and deployed on a real server. Not a demo. Not a prototype. A working backend that a courier company is currently running on.

The file layout settled into something clean:

/api        ← PHP + SQLite backend (frozen)
/scripts    ← Frontend engine modules (frozen)
/app        ← Your app lives here
/tools      ← Configurator + setup helpers

Two files to edit per deployment. Everything else is frozen.

The thing I’m most proud of

The data layer genuinely works offline-first. You write a record — it lands in localStorage instantly. No waiting for a network response. When the connection returns, the sync engine pushes the queue silently. When a teammate saves something on their device, the pull leg brings it down and your UI re-renders. Nobody coordinated that. The engine did.

The developer contract is simple enough to write on a napkin:

GnokeStore.define('ledger', { scope: 'user' });
GnokeStore.onChange('ledger', render);
GnokeStore.save('ledger', { title: 'Rice', amount: 5000 });

That’s it. Local write, automatic sync, reactive UI.

What I intentionally left out

No OAuth. No file uploads. No real-time WebSockets. No admin dashboard for business users.

Those aren’t gaps — they’re the point. Gnoke is not trying to be Supabase. It’s trying to be the thing that works on a ₦7,000/month shared host when your team is 50 people and you need data to sync reliably between field devices.

The auth is PIN-based. Staff register with a phone number or email, set a PIN, and the engine handles the rest. If someone loses their device or forgets their PIN, an admin generates a one-time recovery code. Simple. No SMS API required.

What’s still in progress

  • gnoke-secure.js and gnoke-restore.js — the built-in login UI helpers — are being simplified. The current version has some rough edges around how the client builds the device identity hash. I’m ironing that out.
  • The admin panel is intentionally minimal right now — staff list and OTP generator only. It’s a developer tool, not a business dashboard.
  • Documentation is thin. The README is honest about this: the code is the truth for now.

To the person who asked about WordPress

You can run Gnoke-Database on the same server as WordPress. They share the same PHP host, same file system. Your WordPress site and your Gnoke-powered app are just two separate folders. No conflict. They plug into the same wall outlet — they don’t have to merge.

The repo

Still early.. The README has the full context..

github.com/edmundsparrow/gnoke-database

If you’re building something where Firebase feels like overkill — or where the bill is becoming a problem — give it a look.

MIT License. Your own Firebase, on your own server.

Gnoke-database
If I can think, I can breathe. If I can breathe, I can win.

GitHub Already Has More Engagement Than LinkedIn. It Should Do Something About It.

I published a CVE detection tool recently. Nothing unusual there.

https://github.com/liamromanis101/CVE-2026-31431-Copy-Fail—Vulnerability-Detection-Script

On LinkedIn, the post got 385 impressions. A handful of likes, two comments, one of which was a recruiter, and one person clicked the link which might have been me testing it.

The GitHub repo, in the last 14 days alone: 6,230 views, 3,254 unique visitors, 923 clones from 585 unique cloners. 22 stars, 22 watchers, 2 forks. People actually ran the code.

Nobody clones a repo to be polite.

That is not an edge case. That is the pattern, every time.

LinkedIn Shows You What People Claim. GitHub Shows You What People Do.

LinkedIn is a performance platform. You write a headline, list your credentials, and hope the algorithm rewards you. The engagement is performative by design. Reactions, reposts, congratulations on your work anniversary from people you met once in 2019.

GitHub is a proof-of-work platform. You push code. People clone it, break it, improve it, or ignore it. Nobody pretends to engage. The stars and forks are real signal because there is no social pressure to give them.

This matters enormously if you are trying to build a company or find people worth building one with.

The Problem GitHub Has Not Solved Yet

Here is the thing: GitHub already has everything it needs to become the place where startups are formed.

It has developers at the earliest stage of their best ideas. A commit is often the first tangible artifact of a company that will eventually be worth something. GitHub sees that before any investor does, before any accelerator does, before the founders themselves have put a name to what they are building.

It has genuine engagement data. Not vanity metrics. Actual signals about who is working on what, who is collaborating with whom, and whose code other people trust enough to build on.

It has a culture that LinkedIn cannot replicate. GitHub is not a strictly professional environment. It is not NSFW either. It sits in the space between the two, which means people are actually themselves on it. That is rare, and it is valuable.

What it does not have is a product layer that uses any of this deliberately.

What I Think GitHub Should Build

I wrote a full strategic proposal on this. The short version is: a founder matching and angel investor platform built on top of GitHub’s existing engagement data.

Call it GitHub Launchpad.

The idea is not complicated. If you look at what somebody has built, what others have contributed to, who has consistently shown up across meaningful repositories, you have a far more reliable picture of a potential co-founder than any LinkedIn profile gives you. You are not reading a CV. You are reading a commit history.

Add a structured layer for founders to signal that they are looking for collaborators or early investment, connect that to angels who want to back people before the pitch deck exists, and you have something no other platform can replicate. Because the proof-of-work layer is already there. It is just not being used for this.

Why This Is a Disruption Opportunity, Not an Incremental Feature

LinkedIn is not the natural home for early-stage startup formation. It is where companies post jobs once they already have fifty people. The seed-stage problem, finding the right co-founder, getting in front of the right angel before you have traction, has never been solved well.

GitHub is already embedded in the moment before that. It is at the first commit. It sees the proof of capability that no other platform has access to.

The opportunity to own startup formation from a position of genuine structural advantage is available now. That window will not stay open indefinitely as purpose-built competitors continue to develop.

The Full Proposal

I have written this up properly, with the product detail, the revenue model, and the competitive picture.

If this is an idea worth discussing, I would rather discuss it somewhere people are actually building things.

The full proposal is in the repo below. Thoughts welcome, especially from anyone who has tried to solve the co-founder matching problem and found the existing options wanting.

github.com/liamromanis101/github-launchpad

Tags: #startup #github #productivity #discuss

Hello World: Embracing the Chaos of the Shifting Tech Landscape 👋

The tech landscape is shifting faster than ever, and adaptation is no longer optional—it’s the default. 🚀

In a world driven by constant technological evolution, staying in one place means falling behind. That is why I am incredibly thrilled to officially join this platform today.

Throughout my software development journey, I have realized that the best way to solidify your own understanding is by sharing it with others. Every bug fixed, every framework mastered, and every architecture designed comes with a story and a lesson.

Moving forward, I will be using this space to share:
• Real-world learnings from my day-to-day development journey.
• Deep dives and viewpoints on emerging tech trends and tools.
• Practical breakdowns of complex engineering challenges.

I am excited to connect, learn from this brilliant community, and build in public. Let’s connect and grow together! 📈

AI Agents Work While You Sleep — Now They Can Wake You Up

Let me describe a Tuesday evening.

I fire off /start "refactor billing module", the pipeline kicks in, six AI agents start doing their thing, and I think: great, I’ve got an hour. I’ll cook pasta.

I cook pasta. I eat pasta. I do the dishes. I put on an episode of something. I come back.

The pipeline has been waiting for my approval for 54 minutes. The senior-dev agent is sitting there, doing absolutely nothing, blocked on a gate:plan that needed one click from me. Fifty-four minutes of human absence. Zero pasta to show for it.

This is the core tension of running an AI pipeline: the whole point is that it works while you’re not watching. But the moment it needs you, it needs you immediately — and it has no way to tell you that.

Until now.

What we added

Two things, both live in the board’s Notifications settings:

Email alerts — you enter your email, click a verification link, done. From that point on, five specific events send you an email:

  • A P0 incident opens (the pipeline found a production fire)
  • A gate has been waiting for your approval for more than 30 minutes
  • A gate is actively blocking the pipeline right now
  • Your monthly AI spend crosses the limit you set
  • Monday morning weekly digest — what got done, what it cost, how many gates passed

Browser push notifications — desktop notifications, the same kind you get from Slack or email. You enable them once in the board settings, the browser asks for permission, and that’s it. No app to install. No Firebase. No account anywhere.

Why exactly these five triggers

The first version of this feature had fifteen triggers. It was immediately annoying. Every time an agent sneezed, my phone buzzed.

The honest answer to “what do I actually need to know about right now” is surprisingly short:

Something broke. Not “an agent is running” or “a review started” — the actual situation where production is on fire and the pipeline found it before I did.

I’m blocking progress. The pipeline stopped and is waiting for me. The longer I wait, the more time I’ve wasted running all those agents. If it’s been 30 minutes, I definitely didn’t see the gate notification in the terminal.

I’m about to overspend. LLM costs are real. A runaway pipeline on a big refactor can quietly rack up $20–30 if nobody’s watching. A cost alert at $15 is much better than discovering $40 on the invoice.

Weekly summary. Not urgent, but useful. Monday morning coffee + what your AI team accomplished this week = a surprisingly good way to start the day.

That’s the whole list. No alerts for “agent started”, “agent completed”, “reviewer disagreed with another reviewer”, or any of the other events that feel important but mostly produce noise.

The email setup

Open the board → Settings → Notifications. Enter your email. You get one verification email — click the link, and you’re verified forever. No repeated sign-ins, no token rotation, no dashboard at some third-party service.

Under the hood the board sends emails through a relay we run at greatcto.systems. We’re using Resend on the free tier (100 emails/day), which is more than enough for a solo developer who isn’t actively burning the place down.

Why a relay and not direct SMTP? Because storing an SMTP password inside a local tool that lives on your laptop is a disaster waiting to happen. The relay holds the credentials; your board just sends an HTTPS request. If the relay is down, you miss a notification. That’s fine. You’re not building a hospital.

The push notifications

This one was more fun to build.

Browser push notifications sound simple — they’re everywhere, every website pesters you with them — but implementing them correctly from scratch is genuinely involved. There’s a spec called VAPID that requires signing cryptographic tokens with elliptic curve keys, and basically every tutorial says “just use the web-push npm package.”

We couldn’t. The board server is intentionally zero-dependency — no npm packages, no node_modules, nothing. It’s a single file that you can read start to finish in an afternoon. Adding a library for notifications would mean adding a library for notifications and everything that library depends on, which is how you end up with 47 packages installed to send one HTTP request.

So we implemented it ourselves using only what Node.js ships with.

The fun gotcha: somewhere deep in the VAPID spec, the signature format that Node produces natively is not the format that browsers expect. One is DER-encoded (an old ASN.1 format from the 90s), the other is just raw bytes. Our first test push hit the browser’s push service and got a 401 back. Fifteen minutes of reading specs later, we found the conversion, fixed it, and every subsequent push worked perfectly.

The end result: you toggle the switch in the board, your browser asks “Allow notifications?”, you click Allow, and from that point on your desktop shows a native notification whenever any of the five triggers fire. Same notification you’d get from a Slack message. No third-party service involved.

The notification drawer

Push and email are for when you’re away from the keyboard. The in-app drawer is for when you’re at the keyboard but not watching the terminal.

Click the bell icon in the top nav. A panel slides out with the last 20 notifications — what fired, when, and whether you’ve seen it. Unread count shows as a badge on the bell. “Mark all read” lives right there.

The history persists across restarts. Close the board, reopen it tomorrow morning, your Monday digest is still there.

How to try it

npx great-cto init
npx great-cto board

Go to Settings → Notifications. Add an email or enable push (or both). Then just work normally. If a gate waits too long, you’ll hear about it.

The whole thing is open source: github.com/avelikiy/great_cto (MIT, free, you pay your own LLM provider).

The pasta incident has not repeated since.

VS Code Setup & Extension Configuration for Web Development

VS Code Setup & Extension Configuration for Web Development – Coding Papa’s Dev Log

Welcome to everyone starting their self-taught journey in web development. This video provides a detailed guide on how to install VS Code, the most widely used code editor by developers. From installation to basic settings and leveraging extensions to boost development productivity, we cover everything so even beginners can easily follow along. Let’s take the first step together in building the development environment needed to learn various web development languages like HTML, CSS, JavaScript, and PHP.

What you’ll learn in this tutorial

How to install VS CodeHow to configure basic VS Code settingsHow to install and utilize extensionsBasics of PHP development environment setupSettings to improve code readability (automatic word wrap)Target Audience: Beginners who want to learn web development independently, those who want to learn VS Code installation and basic settings*Difficulty:* Introductory

Key Contents

Installing VS CodeSearch for ‘VS Code’ on Google and access the official website. Download the installer for your operating system (Windows, macOS) and proceed with the installation. You can generally go with the default options during installation. We’ll also guide you on how to launch VS Code after installation is complete. We explain step-by-step so anyone can easily follow without complex procedures.

Extensions to Boost Development ProductivityOne of VS Code’s powerful features is its extensions. Installing extensions tailored to the language you’re developing in can significantly improve development efficiency, including code writing and debugging. In this video, we’ll show you how to install essential extensions for web development, such as HTML and PHP, with examples. We’ll explore useful extensions like color highlighting and PHP IntelliSense, helping you learn how to choose the right plugins for your needs.

Basic VS Code Settings and Useful TipsAfter installing VS Code, it’s important to adjust settings to match your development style. We’ll learn how to configure basic environment settings like changing font size and setting themes. Additionally, we’ll provide useful tips, such as how to enable the ‘automatic word wrap’ feature (Alt + Z) to make long code easier to read at a glance, helping you create a more comfortable coding environment.

Conclusion

You’ve successfully completed the first step towards web development by installing and configuring VS Code. Now you’re ready to start coding. We hope you effectively utilize VS Code as you learn various web development technologies like HTML, CSS, JavaScript, and PHP. Coding Papa’s Dev Log channel will continue to provide useful information and tutorials related to web development, so please stay tuned.

Watch the Tutorial Video

Türkiye’de üretilen katlanabilir telefon modeli Reeder S71 Flip satışa sunuldu

Türkiye

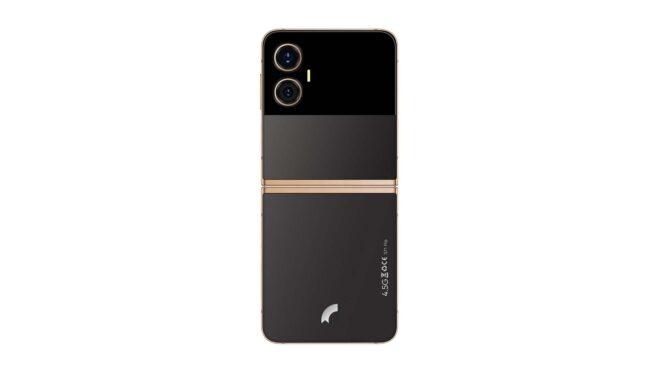
Türkiye'de üretilen katlanabilir telefon modeli Reeder S71 Flip satışa sunulduYerli üreticinin doğrudan Türkiye’de ürettiği katlanabilir telefon modeli Reeder S71 Flip, 28 bin TL’den satışa sunuldu. Cihaz için KAP’a yaptığı bildirimde, “Şirketimizin yerli teknoloji ürün gamını genişletme stratejisi kapsamında, Türkiye’de yerli üretim olarak geliştirilen ilk flip phone modellerinden biri olan Reeder S71 Flip satışa sunulmuştur. S71 Flip; katlanabilir telefon segmentinde konumlandırılmış olup, bu form faktörüne özel katlanabilir ekran yapısı, özel menteşe ve kasa tasarımı ile geliştirilmiştir. Ürünün ekran, kasa ve mekanik yapı uyumuna ilişkin geliştirme süreçleri, Şirketimizin iki yılı aşkın Ar-Ge çalışmaları kapsamında yürütülmüştür.” ifadelerini kullanan şirket, dikey formlu cihazda 6.85 inç AMOLED ekran, MediaTek MT6789 işlemci, 6 GB RAM, 128 GB depolama alanı, 64 megapiksellik ana kamera ve 3.750mAh bataryaya yer veriyor. İki farklı renk seçeneği bulunan telefon, birçok rakibinden farklı olarak dışında herhangi bir ekran taşımıyor.

Türkiye’de üretilen katlanabilir telefon modeli Reeder S71 Flip satışa sunuldu yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

OPAQUE: Password Authentication That Never Sends the Password

The standard way to log in — type a password, send it to the server, hope the server hashes it well — has a structural flaw nobody has been able to fix without changing the protocol. OPAQUE changes the protocol. The server never sees the password, can’t be tricked into revealing it, and can’t even pre-compute attacks against your future logins.

Type your password into a login form and it travels — encrypted in transit, but as plaintext to the server. The server hashes it (hopefully with Argon2 or scrypt), compares to a stored hash, and either accepts or rejects. This is the model essentially every web application uses, and it has three persistent problems.

  • The server sees the plaintext password at the moment of login. A compromised server, a malicious operator, or a logging misconfiguration captures it.
  • The TLS connection has to be terminated somewhere. If termination happens at a CDN, load balancer, or WAF you don’t control, the plaintext briefly exists in that operator’s memory.
  • If the password database is stolen, attackers can mount an offline brute-force attack against every account in parallel. Hash strength helps, but not infinitely.

An augmented password-authenticated key exchange (aPAKE) fixes all three by making the password the only thing the client ever knows, and the verifier the only thing the server ever knows — with a protocol that proves the client knows the right password without revealing it.

The PAKE Family

PAKEs have existed since the early 1990s. The first widely studied scheme, EKE (Encrypted Key Exchange) by Bellovin and Merritt in 1992, was patented and never saw broad deployment. SRP (Secure Remote Password) followed in 1998 and shipped in a few places, notably Apple’s iCloud key vault and 1Password’s earlier sync architecture. SRP works but had no formal security proof for years and isn’t ideal for modern key exchange constructions.

OPAQUE, designed by Stanislaw Jarecki, Hugo Krawczyk, and Jiayu Xu in 2018 and currently in IRTF draft finalization, is the modern answer. It’s an augmented PAKE — meaning the server doesn’t store anything that would let it impersonate the client back to the client — built on well-understood primitives (OPRF, Diffie-Hellman, AEAD) with a proof in the universal composability framework.

How the Protocol Actually Works

OPAQUE has two phases: registration (which happens once when the user signs up) and login (every authentication afterward).

Registration

  1. The client picks a random secret blind, blinds the password with it, and sends the blinded password to the server.
  2. The server applies an oblivious pseudorandom function (OPRF) using its own per-user secret key, then returns the result to the client.
  3. The client unblinds the response. It now has a high-entropy value derived from the password but only computable with the server’s cooperation — this is the “rwd” (randomized password).
  4. The client derives an encryption key from rwd, generates a long-term private key, encrypts an “envelope” containing that private key plus authentication material, and sends the envelope back to the server.
  5. The server stores the envelope, the OPRF key, and a public key — never seeing the password or rwd.

Login

  1. The client blinds the password again with a fresh blind, sends it.
  2. The server applies the OPRF with the user’s stored key, returns the blinded result and the envelope.
  3. The client unblinds, recovers rwd, decrypts the envelope, recovers the long-term private key.
  4. Both sides perform an authenticated Diffie-Hellman key exchange using the recovered keys, establishing a fresh session key.

The crucial property: the server’s OPRF response depends on its secret key, so the client cannot brute-force the password offline by guessing and recomputing — it has to interact with the server for each guess, where rate limits and lockouts apply. And the server, never having seen the password, has nothing useful to leak if it’s compromised.

The OPRF, in plain terms
An oblivious pseudorandom function lets the server compute f(secret, input) for a client without learning the input. The client gets the output. The server learns nothing about what was input. This is the building block that makes OPAQUE’s “server never sees the password” property work.

What This Stops

Attack Password + bcrypt OPAQUE
Malicious server logs plaintext password Vulnerable Server never sees it
TLS termination at CDN exposes plaintext Vulnerable Nothing useful exposed
Stolen database, offline cracking Hash slows it Requires server interaction
Pre-computation (rainbow tables) Defeated by salt OPRF key is per-server
Phishing site captures password Vulnerable Still vulnerable
Compromised client keylogger Vulnerable Still vulnerable

OPAQUE is not magic. It moves the trust boundary from “server promises not to peek” to “server cannot peek.” It does nothing about endpoint compromise — if your browser or device is owned, the password is exposed regardless of protocol. Phishing, where the user types the password into the wrong site entirely, is also unaffected because OPAQUE assumes the client knows where it’s connecting.

Where It’s Deployed

OPAQUE adoption is still early, but real. WhatsApp uses it for the password protecting end-to-end encrypted iCloud and Google Drive backups, deployed in 2021. Tutanota added OPAQUE-based password verification for its mailbox login flow. Internal experiments at Cloudflare and Meta have published reference implementations. The CFRG draft is on track for final RFC status in 2026.

Why isn’t it everywhere yet? Three reasons:

  • Browser support is library-only. No native WebCrypto primitive for OPAQUE exists yet. Implementations rely on WebAssembly modules or JavaScript libraries, which is fine but adds deployment friction.
  • Round trips. OPAQUE adds one or two extra round trips compared to a classic POST-the-password login. On mobile networks with high latency, the user-visible difference can be ~100-300ms.
  • Migration is hard. An existing service with millions of bcrypt-hashed passwords can’t switch to OPAQUE without each user logging in once with their current password (so the server can run the OPAQUE registration and discard the old hash). Coordinating that flow is operationally annoying.

The Underlying Lesson

Most security improvements in the password-authentication world have been about tuning the existing model: better hashing, mandatory TLS, breach-database checks, second factors. Those are valuable. But the underlying architecture — “type a secret, transmit it, hope” — is fundamentally constrained. OPAQUE is the first widely studied scheme that genuinely changes the architecture.

Whether your favorite service ever ships it is a function of how much they care about the difference between “I trust my server not to log” and “my server can’t log even if it tries.” If you build authentication systems, the OPAQUE drafts and the reference implementations are worth reading carefully.

*Originally published at [havenmessenger.com](

Designing an Account Context Manifest for AI Browser Agents

Your AI browser agent can open a page.

It can click buttons.

It can fill forms.

It can even complete a workflow that looks correct from the outside.

But here is the more important question:

Can you prove it used the right account, the right browser profile, the right proxy, the right session history, and the right workflow boundary?

For many browser automation projects, the answer is no.

Not because the automation framework is bad. Playwright, Puppeteer, browser MCP servers, and AI agents are all powerful.

The problem is more basic:

Most systems treat browser control as the whole workflow.

In real account-based automation, browser control is only one layer.

The missing layer is account context.

This post introduces a simple pattern I call an Account Context Manifest: a structured file that tells an AI browser agent which account environment it is allowed to use, what assumptions must stay stable, and what evidence should be recorded.

It is not a silver bullet.

It is not a replacement for security, platform compliance, or human review.

But it is a practical way to stop AI browser automation from becoming a pile of disconnected scripts, state files, proxy flags, and screenshots.

Browser control is not account-aware execution

Most browser automation examples start like this:

const browser = await chromium.launch();
const page = await browser.newPage();

await page.goto("https://example.com");
await page.click("text=Login");

That is fine for tests, demos, and simple one-off tasks.

But real account workflows are different.

A real workflow usually depends on more than a URL and a selector.

It depends on questions like:

  • Which account is being used?
  • Which browser profile belongs to that account?
  • Which proxy or network route should be used?
  • Does the timezone match the proxy region?
  • Does the locale match the account environment?
  • Is the session expected to be fresh or persistent?
  • Are browser extensions required?
  • Is this task safe for headless execution?
  • When should the agent stop for human review?
  • What evidence should be saved if the workflow fails?

If these details live in different places, the agent may still run.

But the result becomes hard to audit.

That is where many browser agents fail in practice.

Not because they cannot click.

But because they do not know enough about the account environment they are clicking inside.

What is an Account Context Manifest?

An Account Context Manifest is a structured definition of the browser environment an automation run is allowed to use.

It connects these fields into one object:

  • account identity
  • browser profile
  • proxy configuration
  • timezone and locale
  • session state
  • browser mode
  • workflow permissions
  • human review rules
  • debugging evidence

Here is a minimal example:

{
  "account_id": "acct_us_042",
  "profile_id": "profile_us_042",
  "profile_path": "./profiles/acct_us_042",

  "proxy": {
    "id": "proxy_us_res_07",
    "country": "US",
    "timezone": "America/New_York",
    "locale": "en-US"
  },

  "browser": {
    "mode": "headed",
    "persistent_context": true,
    "extensions_required": ["wallet", "password-manager"]
  },

  "state": {
    "storage_state_path": "./states/acct_us_042.json",
    "last_verified_at": "2026-05-18T10:00:00Z"
  },

  "workflow": {
    "allowed_tasks": [
      "login-check",
      "page-inspection",
      "report-export"
    ],
    "requires_human_review": [
      "verification",
      "payment",
      "profile-reset"
    ]
  },

  "evidence": {
    "save_screenshot": true,
    "save_dom_snapshot": true,
    "log_proxy_check": true
  }
}

The manifest does not make the agent smarter by itself.

Instead, it makes the execution environment explicit.

Before the agent acts, it should know:

I am operating account acct_us_042, inside profile profile_us_042, using a US proxy, with New York timezone, in headed mode, and I must stop before verification or payment actions.

That is very different from:

Open Chromium and do the task.

Key fields in the manifest

A useful Account Context Manifest does not need to be complex.

But a few fields should be treated as first-class execution inputs.

Field Meaning Why it matters
account_id The business or platform account being used Prevents account confusion
profile_id The browser profile assigned to the account Keeps browser identity consistent
profile_path Local path for persistent browser context Allows repeatable, long-lived sessions
proxy.id The selected proxy route Makes network identity auditable
proxy.timezone Expected timezone for the proxy region Reduces environment mismatch
proxy.locale Expected language and locale Keeps browser behavior consistent
browser.mode headed or headless Helps reproduce failures
persistent_context Whether a long-lived profile is used Keeps session continuity
allowed_tasks Tasks this account can run Prevents accidental misuse
requires_human_review Actions where the agent must stop Adds safety boundaries
evidence Logs, screenshots, snapshots Makes debugging possible

These fields turn hidden assumptions into explicit constraints.

That is the main value of the manifest.

Why storageState alone is not enough

Playwright’s storageState is useful.

It can save cookies and local storage. It can help skip repeated login steps. For many testing workflows, that is exactly what you need.

But storageState is only a snapshot of part of the browser state.

It does not describe the full account environment.

For example, storageState does not tell you:

  • which long-lived browser profile the account belongs to
  • whether the workflow was run in headed or headless mode
  • which proxy was used
  • whether the proxy region matched the timezone and locale
  • whether required extensions were available
  • whether the run required a human review point
  • whether the run produced useful debugging evidence

So storageState is helpful, but it should not be the only source of truth for account-based automation.

The manifest gives the state file context.

Instead of treating a state file as a magic login shortcut, the agent treats it as one part of a larger account environment.

A minimal Playwright implementation

Here is a simple TypeScript example using Playwright.

The point is not to build a full production system.

The point is to show that a browser run should begin by loading account context, not by launching a random browser.

import { chromium } from "playwright";
import fs from "fs";

type AccountManifest = {
  account_id: string;
  profile_id: string;
  profile_path: string;

  proxy: {
    id: string;
    country: string;
    timezone: string;
    locale: string;
  };

  browser: {
    mode: "headed" | "headless";
    persistent_context: boolean;
    extensions_required?: string[];
  };

  workflow: {
    allowed_tasks: string[];
    requires_human_review: string[];
  };

  evidence: {
    save_screenshot: boolean;
    save_dom_snapshot: boolean;
    log_proxy_check: boolean;
  };
};

const manifest: AccountManifest = JSON.parse(
  fs.readFileSync("./manifests/acct_us_042.json", "utf-8")
);

function assertTaskAllowed(taskName: string, manifest: AccountManifest) {
  if (!manifest.workflow.allowed_tasks.includes(taskName)) {
    throw new Error(
      `Task "${taskName}" is not allowed for account ${manifest.account_id}`
    );
  }
}

const taskName = "page-inspection";

assertTaskAllowed(taskName, manifest);

const context = await chromium.launchPersistentContext(
  manifest.profile_path,
  {
    headless: manifest.browser.mode === "headless",
    timezoneId: manifest.proxy.timezone,
    locale: manifest.proxy.locale
  }
);

const page = await context.newPage();

console.log({
  event: "browser_context_started",
  account_id: manifest.account_id,
  profile_id: manifest.profile_id,
  profile_path: manifest.profile_path,
  proxy_id: manifest.proxy.id,
  mode: manifest.browser.mode,
  task: taskName
});

await page.goto("https://example.com");

if (manifest.evidence.save_screenshot) {
  await page.screenshot({
    path: `./evidence/${manifest.account_id}-${taskName}.png`,
    fullPage: true
  });
}

await context.close();

A production version should do more:

  • validate the manifest with a schema
  • check proxy availability before starting
  • confirm account identity after login
  • save structured logs
  • encrypt sensitive fields
  • separate read-only tasks from account-changing tasks
  • stop before risky actions
  • require review for sensitive workflows

But even this minimal version creates a better habit:

The agent reads the account context before it touches the browser.

Add schema validation before execution

If an AI agent can trigger browser workflows, the manifest should be validated before execution.

A lightweight schema can prevent avoidable mistakes.

For example:

import { z } from "zod";
import fs from "fs";

const ManifestSchema = z.object({
  account_id: z.string().min(1),
  profile_id: z.string().min(1),
  profile_path: z.string().min(1),

  proxy: z.object({
    id: z.string().min(1),
    country: z.string().min(2),
    timezone: z.string().min(1),
    locale: z.string().min(2)
  }),

  browser: z.object({
    mode: z.enum(["headed", "headless"]),
    persistent_context: z.boolean(),
    extensions_required: z.array(z.string()).optional()
  }),

  workflow: z.object({
    allowed_tasks: z.array(z.string()),
    requires_human_review: z.array(z.string())
  }),

  evidence: z.object({
    save_screenshot: z.boolean(),
    save_dom_snapshot: z.boolean(),
    log_proxy_check: z.boolean()
  })
});

const manifest = ManifestSchema.parse(
  JSON.parse(fs.readFileSync("./manifests/acct_us_042.json", "utf-8"))
);

This is especially useful when manifests are generated by another system, edited by operators, or selected by an AI agent.

Do not let the agent guess the environment.

Make the environment explicit.

Validate it first.

Pre-run checks before the agent acts

Before an AI browser agent starts a workflow, it should pass a few basic checks.

Check Why it matters
Is the selected profile the expected one? Prevents the agent from using a clean or wrong browser profile
Does the proxy region match timezone and locale? Reduces inconsistent execution environments
Is the run headed or headless? Makes failures easier to reproduce
Is this task allowed for this account? Prevents unsafe or unintended actions
Are cookies and local storage from the expected profile? Avoids state confusion between accounts
Does the workflow require human review? Stops the agent before sensitive steps
Will evidence be saved? Makes debugging possible after failure

These checks are not glamorous.

But they prevent a common failure mode in AI automation:

The agent completes a task, but nobody can explain the environment in which it happened.

Common failure modes the manifest prevents

A manifest is useful because it turns hidden assumptions into visible inputs.

Failure mode Without manifest With manifest
Wrong proxy A script runs with a random proxy flag Proxy is bound to account context
Wrong browser profile The agent opens a clean browser The agent launches the expected persistent profile
Headed/headless mismatch Failure is hard to reproduce Execution mode is logged
Cookie confusion State files are reused blindly State file is tied to account and profile
Unsafe retry Agent repeats account-changing actions Workflow rules define review boundaries
Weak debugging “It worked yesterday” Logs show account, profile, proxy, task, and evidence

The manifest does not remove the need for testing.

It gives your tests, agents, and human reviewers a shared language.

Where MCP and browser agents fit

Browser MCP servers and AI agents are useful because they make browser actions easier to expose as tools.

An agent can navigate, click, read the page, summarize content, and decide the next step.

But MCP does not automatically solve account context.

The agent still needs to know:

  • which browser target it is allowed to use
  • which profile belongs to the account
  • which workflow it is allowed to run
  • which actions require human review
  • which logs or screenshots should be saved
  • which environment assumptions should not change

Without that boundary, the agent is improvising.

With a manifest, the agent is still flexible, but it operates inside a defined environment.

That is the difference between browser access and account-aware execution.

Keep sensitive data out of the manifest

One important rule:

Do not put secrets directly into the manifest.

Avoid storing raw passwords, private keys, seed phrases, API keys, or payment credentials in a plain JSON file.

Instead, the manifest should reference secure storage:

{
  "account_id": "acct_us_042",
  "secrets": {
    "password_ref": "vault://accounts/acct_us_042/password",
    "api_key_ref": "vault://accounts/acct_us_042/api-key"
  }
}

The manifest should describe the account environment.

It should not become a secret dump.

For teams, this distinction matters a lot.

The more agents, profiles, and workflows you add, the more important it becomes to separate:

  • identity metadata
  • browser state
  • secrets
  • permissions
  • audit logs

A manifest can connect these pieces without exposing all of them in one file.

When a manifest becomes a workspace

A manifest works well when you have a few accounts and a disciplined team.

But as the system grows, you may start to manage:

  • many browser profiles
  • many proxy routes
  • persistent sessions
  • headed and headless workflows
  • AI agent tasks
  • browser MCP tools
  • human review points
  • recurring logs and screenshots
  • team permissions

At that point, the manifest often becomes part of a larger operating layer.

Some teams build this internally. Others use a browser automation workspace for account context so that profiles, proxies, automation tasks, and review evidence stay connected instead of being scattered across scripts and folders.

The important idea is not the tool name.

The important idea is this:

Account identity, browser state, proxy mapping, automation logic, and evidence should not be separated after the workflow starts.

They should be connected before the agent acts.

A practical starting template

If you are building your own system, start small.

Create one manifest per account:

{
  "account_id": "acct_example_001",
  "profile_id": "profile_example_001",
  "profile_path": "./profiles/acct_example_001",

  "proxy": {
    "id": "proxy_001",
    "country": "US",
    "timezone": "America/New_York",
    "locale": "en-US"
  },

  "browser": {
    "mode": "headed",
    "persistent_context": true
  },

  "workflow": {
    "allowed_tasks": [
      "login-check",
      "read-only-inspection"
    ],
    "requires_human_review": [
      "verification",
      "payment",
      "settings-change"
    ]
  },

  "evidence": {
    "save_screenshot": true,
    "save_dom_snapshot": false,
    "log_proxy_check": true
  }
}

Then add three rules:

  1. Every browser run must load a manifest.
  2. Every manifest must be validated before execution.
  3. Every run must log the account ID, profile ID, proxy ID, task name, and execution mode.

That alone will make many automation failures easier to understand.

Final takeaway

AI browser agents do not only need browser access.

They need account context.

Before scaling browser automation, define the account identity, browser profile, proxy mapping, workflow boundary, and evidence trail as first-class execution inputs.

A simple manifest is a good start.

When the manifest becomes too hard to maintain manually, move the same logic into a shared workspace.

The goal is not just to make agents click faster.

The goal is to make browser automation reproducible, reviewable, and safe enough for real account workflows.

Related reading:

If you are deciding how to manage login state in Playwright, this breakdown of storageState vs persistent context may be useful.