SpaceX’in beklenen halka arzı Haziran’da gerçekleşebilir
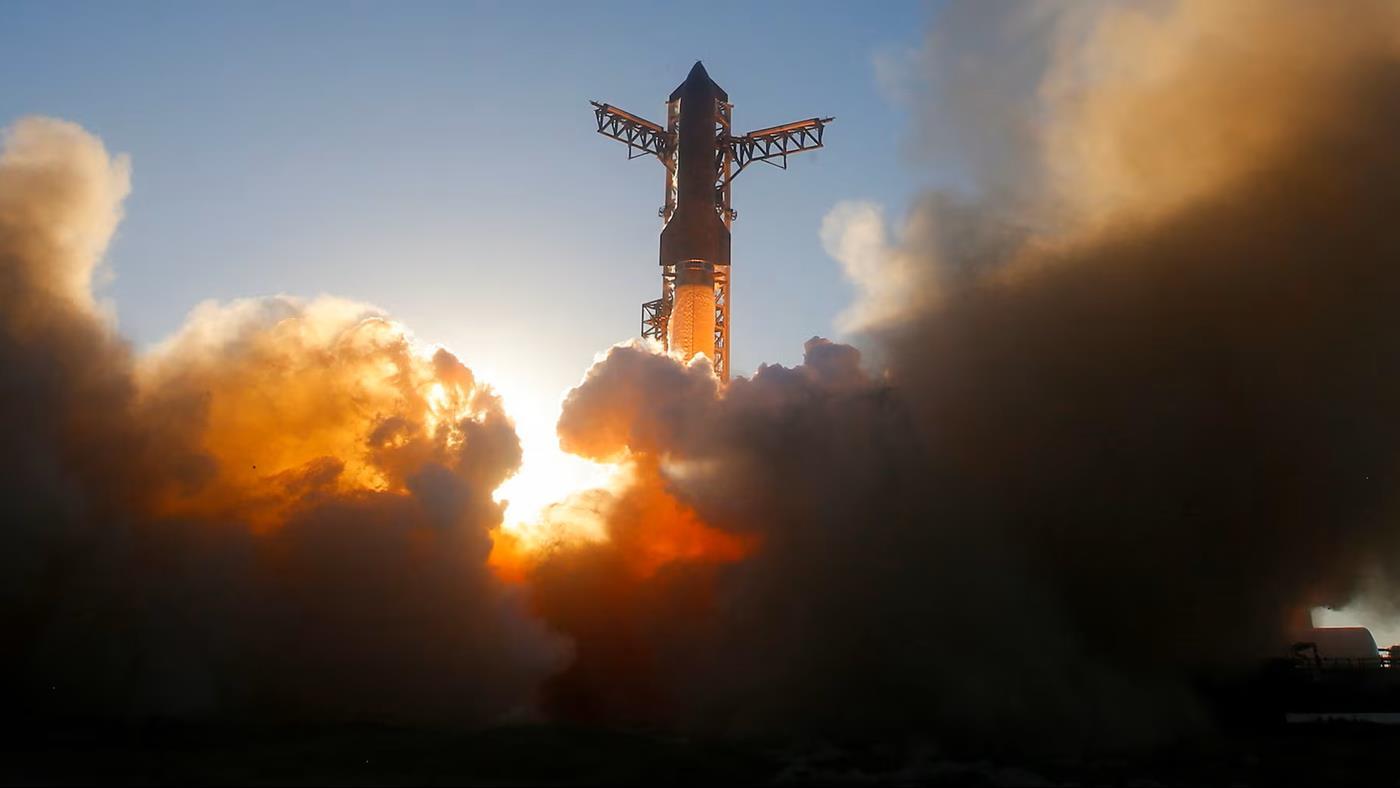
 SpaceX’in haziran ayında halka arz sürecine resmen başlayacağı bildirildi. Şirketin 75 milyar dolarlık IPO ve 1,75 trilyon dolarlık değerleme hedeflediği belirtiliyor.

 Mert
SpaceX’in haziran ayında halka arz sürecine resmen başlayacağı bildirildi. Şirketin 75 milyar dolarlık IPO ve 1,75 trilyon dolarlık değerleme hedeflediği belirtiliyor.
 İstanbul Medeniyet Üniversitesi Teknokent’te geliştirilen Gözcü Mobil, SIM kartsız çalışan yerli akıllı takip cihazlarıyla 20 bin satışa ve 10 binden fazla aktif kullanıcıya ulaştı.
 Antarktika buzullarında bulunan radyoaktif demir izleri, Dünya’nın milyonlarca yıl önce patlayan bir yıldızın kalıntılarıyla dolu kozmik bir bulutun içinden geçtiğini gösteriyor.
 Take-Two Interactive CEO’su Strauss Zelnick, katıldığı bir programda GTA 6 için de konuştu ve oyunun açıklanan son çıkış tarihine uyulacağını, yani merakla beklenen yapımın 19 Kasım’da çıkacağını dile getirdi. Projenin ilk iç hedefin yaklaşık 18 ay gerisinde kaldığını aktaran Zelnick, geçtiğimiz hafta yaptığı başka bir açıklamada, GTA 6’ya yönelik beklentilerin korkutucu seviyede olduğunu söylemişti. Bugün ön siparişe açılacağı söylenen yeni GTA’da “Bonnie and Clyde” tarzında aksiyonu oldukça bol bir işleyiş karşımıza çıkacak. Resmi açıklamasında, “Grand Theft Auto VI, Grand Theft Auto serisinin şimdiye kadarki en büyük ve en sürükleyici evriminde, Vice City’nin neon ışıklı sokaklarına ve ötesine ev sahipliği yapan Leonida eyaletine gidiyor.” ifadesine yer verilen oyun, milyonlarca PlayStation 5 ve Xbox Series X/S sahibi tarafından merakla bekleniyor. Yapımın PC çıkış tarihi ise halen bilinmiyor.
Take-Two CEO’su tarihi yineledi: “GTA 6, 19 Kasım’da çıkacak” yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.
dev.to — Gemma 4 Challenge submission (Write track)
Drafted: 2026-05-18
Track: Write about Gemma 4 ($100 × 5 winners)
Source material:gemma4-e4b-cognitive-stages-eval.md— internal fair-witness report (PR #307)
Companion submission: Build track piece on E4B model choice
Submission deadline: 2026-05-24 23:59 PDT
Winners announced: 2026-06-04
Tags:devchallenge,gemmachallenge,gemma,ollama
Why a Write-track submission in addition to the Build-track one
The Build-track submission (Building a Mini Palantir on gemma4:e4b — 128K Context Lets the Graph Actually Be Graph-RAG) made an intentional model choice argument: 128K context window > parameter count, so E4B was right for the Graph-RAG retrieval-conditioning stage.
That argument held — and it is still the strongest single thing E4B does in this project.
But once the v0.3 Cognitive Middleware Layer started shipping Phase 2 stages (verification, planner, tool router, query rewriter, fact-check), a second pattern showed up that the Build-track piece could not honestly absorb: E4B silently returns empty responses on five of the nine cognitive stages, while the same prompts on Gemma 3 12B succeed end-to-end.
This is the Write-track piece that documents that pattern honestly, without retreating from the Build-track claim. Same author, two articles, two facets of the same model.
The challenge judging rubric for the Write track is:
A fair-witness field report meets all four at once: it shares reproducible numbers, an explicit “I don’t know yet” stance on root cause, and a set of open questions that other operators can act on.
Suggested title (pick one)
| # | Title | Why |
|---|---|---|
| A |
5 empty responses from gemma4:e4b. 4 hypotheses. 0 root cause. A fair-witness field report from a Graph-RAG production. |
⭐ Strongest hook — number-led, names a tension (no resolution), promises honesty. |
| B | Where Gemma 4 e4b runs out of room: empty responses on meta-reasoning stages | Clearer technical framing, slightly less click-worthy |
| C | Gemma 4 e4b: brilliant at synthesis, silent on meta-reasoning. A field report. | Bridges the strengths and weaknesses in the title itself |
Recommended: A. Numbers-led titles outperform on the dev.to feed; the “0 root cause” half signals the writing is honest rather than gloating.
Cover image
Use reports/promo-assets/screenshots/03-chat-graph-paths.jpg — the chat-UI screenshot with “그래프 경로 47개 보기” surfaced. It primes the reader for “this writer ships a real Graph-RAG pipeline” before the article gets into the failure mode.
Download URL: https://github.com/Hashevolution/James-RAG-Evol/blob/main/reports/promo-assets/screenshots/03-chat-graph-paths.jpg?raw=true
Tags
devchallenge, gemmachallenge, gemma, ollama
ollama is the 4th tag (instead of rag) — the failure mode plausibly involves the Ollama chat template or stop-token handling, so the Ollama tag’s audience is more likely to recognize the pattern.
Submission body (copy-paste into dev.to editor)
*This is a submission for the [Gemma 4 Challenge: Write about Gemma 4](https://dev.to/challenges/google-gemma-2026-05-06)*

## TL;DR

`gemma4:e4b` (4 B parameters, the "efficient" Gemma 4 build) **excels at long-form natural-language synthesis from a 5 KB retrieved context** in my Graph-RAG project. It also **silently returns empty responses on five short meta-reasoning stages** — query rewrite, plan decomposition, web summary, self-critique, fact-check. Same model, same backend, same `task` parameter. Swapping to `gemma3:12b` made all five succeed without touching a single prompt.

I have data. I do not yet have a root cause. Posting this as a fair-witness field report in case other local-LLM operators have seen the same pattern (or have a prompt-side fix that doesn't require jumping to a 12 B model).

This is a companion to my earlier [Build-track submission](https://dev.to/hashevolution/building-a-mini-palantir-on-gemma4e4b-128k-context-lets-the-graph-actually-be-graph-rag-33fk), which argued for E4B on the basis of its 128 K context window. That argument is still right — for the synthesis stage. The five meta stages are where the 4 B variant runs out of room.

## Setup (reproducible)

### Project

[**PROJECT JAMES v0.3.x**](https://github.com/Hashevolution/James-RAG-Evol) — a local-first Graph-RAG reasoning engine. MIT-licensed, Ollama-only, no cloud LLM dependency. v0.3.0 shipped the Cognitive Middleware Layer architecture; v0.3.x is landing its phases incrementally — verification engine, planner, tool router, query rewriter, fact-check.

Relevant stages of the cognitive layer:

| Stage | Purpose | Prompt shape |
|---|---|---|
| `query_rewrite` | Rewrite the user question for retrieval | Korean/English instruction → JSON `{"rewritten": "..."}` |
| `plan.decompose` | Break a multi-aspect question into ≤ 5 subtasks | Instruction → JSON `{"subtasks": [...]}` |
| `synth.rag` | The actual long-form answer | System prompt + retrieved context (~5 KB) + Korean question → Korean prose answer |
| `synth.web_summary` | Summarize fetched web results | Instruction + web snippets → short Korean summary |
| `reflect.critique` | Critique the draft answer | Draft + instruction → Korean critique text |
| `verify.fact_check` | Audit claims against source docs | Answer + sources + instruction → JSON `{"grounded": bool, "unsupported": [...]}` |

All stages route through one Ollama backend adapter and use the same `JAMES_LLM_MODEL` env var. Whatever model is named, every stage talks to it the same way.

### Environment

- OS: Windows 11, PowerShell
- Ollama: latest mid-May 2026 build
- Models installed locally: `gemma4:e4b` (9.6 GB, ~4 B params), `gemma3:12b` (8.1 GB, ~12 B), plus a few others irrelevant to this report
- All `JAMES_ENABLE_*` cognitive flags set to `1` in the same shell before launching the server

### Test query

```


BlackRock 과 Vanguard 의 ETF 전략 차이를 비교해줘


```

A real Korean retrieval question. Intent classifier picked `retrieval` correctly. Document corpus contains ~10 finance documents matching the topic.

## What I observed with `gemma4:e4b`

Direct quote of the server console (one query, all stages enabled):

| Stage | LLM call type | Latency | Response size | Result |
|---|---|---|---|---|
| INTENT classify | `task=classify` | 9.1 s | **9 chars** ("retrieval") | ✅ OK |
| `query_rewrite` | `task=general` | 2.1 s | **0 chars** | ❌ empty |
| entity extract | `task=extract` | 9.5 s | **452 chars** (JSON of 9 entities) | ✅ OK |
| `synth.web_summary` | `task=general` | 4.0 s | **0 chars** | ❌ empty |
| `synth.rag` | `task=general` | 13.7 s | **2 690 chars** (Korean prose) | ✅ OK |
| `reflect.critique` | `task=general` | 4.2 s | **0 chars** | ❌ empty |
| `verify.fact_check` | `task=general` | 4.3 s | **0 chars** (prompt 4 319 → truncated to 4 000) | ❌ empty |

The empty-response path is taken when Ollama returns HTTP 200 but `response: ""` — the server replied successfully, the model just produced zero tokens. JAMES logs it as `gemma.empty_response`.

### What's striking

- **The 5 empty responses cluster at ~2–4 seconds.** Not a timeout. The per-stage budget is 10–30 s; the model decided it was done.
- **The two successful `task=general` calls** (entity extract: JSON; synth.rag: long Korean prose) **took 9.5 s and 13.7 s.** Same backend, same model, same `task` parameter — only the prompt shape differs.
- **The pattern is consistent across multiple trials.** Run the same query three times back-to-back and the same five stages are empty each time.

## Control — same prompts on `gemma3:12b`

Same query, same flags, no other changes. Single env-var swap, restart server:

| Stage | Latency | Response | Result |
|---|---|---|---|
| `query_rewrite` | 0.91 s | "BlackRock 및 Vanguard의 ETF 투자 전략과 포트폴리오 구성 방식의 차이점을 비교 분석해줘" — meaning-preserved keyword expansion | ✅ |
| `plan.decompose` | 1.33 s | 3 subtasks (BlackRock 조사 / Vanguard 조사 / 비교 분석) | ✅ |
| `synth.rag` | 9.6 s | 2 690-char Korean answer | ✅ |
| `reflect.critique` | 7.98 s | "## 답변 초안 비판적 검토 — 모순 / 사실 오류 …" — coherent meta-critique | ✅ |
| `reflect.revised` | 9.19 s | revised answer based on critique | ✅ |
| `verify.fact_check` | 1.17 s | `{"grounded": true, "unsupported": []}` — valid JSON | ✅ |

Full 9-step trace renders end-to-end. Wall-clock ~39 s. Same prompts. Same wiring. Same backend.

**This is the punchline: nothing changed except the model name.**

## Where Gemma 4 e4b still wins

Staying fair to the model:

- Long-form synthesis from a 5 KB retrieved context — the project's most-frequent stage — handled well at 13.7 s for 2 690 chars of genuinely useful Korean prose.
- JSON entity extraction with a 9-entity schema returned 452 chars of clean JSON at 9.5 s.
- Single-token classification — emit exactly one of seven mode strings — was fine.

The model is not "broken." It ships real Graph-RAG answers. The narrow failure mode is a second class of prompts: **short, structured, meta-instructional**.

## The failure pattern

```


✅ succeeds    long context + free-form Korean prose
✅ succeeds    short instruction + emit 1 token from a finite vocab
✅ succeeds    rich context + emit one JSON object describing the input
❌ empty       short context + emit JSON that critiques / restructures / audits the input


```

The five empty responses share three traits:

1. **The model is asked to act on a model output** — rewrite the user query, critique a draft, audit claims.
2. **The expected output is short and structured** — a few sentences, or a tight JSON object.
3. **The prompt mixes Korean instructions with English JSON schema keys** — e.g. `{"rewritten": "..."}` or `{"grounded": true, "unsupported": []}`.

A natural-language paraphrase (synth.rag) avoids all three. A JSON entity extraction has trait 3 only, and that one passes. The cluster of all three is what seems to silence the model.

## Four working hypotheses

I have data but not a root cause. Four candidate explanations, listed by my own subjective likelihood:

### A. Meta-reasoning capacity at 4 B is the floor

Critique / verify / decomposition prompts ask the model to reason *about* another reasoning artifact. The empirical literature on small open-weights models (Qwen 2.5-3B, Phi-3-mini, Gemma-2-2B, …) consistently shows the meta-reasoning gap is the first capability to drop below ~7 B params, while paraphrase-from-context survives much smaller. If this is right, no prompt-side fix exists for E4B on these stages.

### B. Early stop-token emission on short structured prompts

Ollama returning `response: ""` on a 2–4 s call (well below the timeout) is consistent with the model emitting EOS / `<end_of_turn>` immediately. Possibly the chat template wrapping resembles a completed conversation when the user prompt itself looks like an instruction-only frame with no input data attached.

### C. Korean instruction + English JSON schema confusion

The five failing prompts all mix Korean directive language with English-key JSON output. The two succeeding `task=general` calls don't (entity extract uses Korean prompt → Korean-content JSON; synth.rag is all Korean). Worth testing whether an all-Korean schema (e.g. `{"재작성된_질의": "..."}`) would change anything.

### D. JAMES-side prompt-truncation artifact

The `verify.fact_check` log shows `prompt 4 319자 → 4 000자 축약` — JAMES capped the prompt at 4 000 chars, which likely chopped the closing brace of an embedded JSON example in the system prompt. If true, this is a JAMES bug, not a Gemma 4 bug — but it would only explain `verify.fact_check`, not the other four empty responses.

The report explicitly **does not** advocate for a single hypothesis — that is the work this feedback round is asking the community to fund.

## What I'd love feedback on

If you've used `gemma4:e4b` (or `gemma4:e2b`) and have data points either way, I'd like to know:

1. Have you seen the same "empty response on short structured prompts" pattern? Especially critique-of-a-draft, JSON schema audit, query rewrite.
2. Did a prompt-engineering change rescue it on your setup? Different chat template, different `num_predict`, different temperature, all-one-language prompts, anything else.
3. Does `gemma4:e2b` show the same pattern, or is it specific to E4B?
4. Does the same prompt set behave on `gemma4:31b-dense` / `gemma4:26b-moe` if you have one of those provisioned?
5. Is there a known issue with Ollama + Gemma 4 + JSON-output prompts in your experience?

Project's stance on next steps:

- Default model swap to `gemma3:12b` is already done locally. `gemma4:e4b` stays available — its long-context synthesis is the project's bread-and-butter stage.
- A follow-up PR (option A2) will let operators wire individual cognitive stages to different backends, so E4B can keep `synth.rag` while a heavier model takes the meta stages.
- We will **not** patch JAMES's prompt shapes specifically to coax E4B into responding on these stages until we understand whether the empty response is the model declining, the chat template misfiring, or a JAMES-side truncation bug.

## Reproduction

If you want to reproduce — or, more usefully, to falsify — the report on your own corpus:

```

powershell
# 1. Install JAMES (one-liner, MIT, no cloud)
git clone https://github.com/Hashevolution/James-RAG-Evol
cd James-RAG-Evol
python -m pip install -r requirements.txt

# 2. Make sure the two models are local
ollama pull gemma4:e4b
ollama pull gemma3:12b

# 3. Enable the five cognitive stages
$env:JAMES_ENABLE_QUERY_REWRITE = "1"
$env:JAMES_ENABLE_PLANNER       = "1"
$env:JAMES_ENABLE_REFLECT       = "1"
$env:JAMES_ENABLE_VERIFY        = "1"
$env:JAMES_ENABLE_FACT_CHECK    = "1"

# 4. Test with Gemma 4
$env:JAMES_LLM_MODEL = "gemma4:e4b"
python server_llmwiki.py
# In another shell, send a retrieval query, e.g. the same BlackRock vs Vanguard line above.
python scripts/replay_trace.py --recent

# 5. Control: Gemma 3
$env:JAMES_LLM_MODEL = "gemma3:12b"
python server_llmwiki.py
# Same query, same trace command — all 9 stages succeed


```

If you publish your own numbers — X / GitHub issue / Reddit / dev.to comment — please tag `#JAMES` or open an issue on the [repo](https://github.com/Hashevolution/James-RAG-Evol). I'll link it back to this report.

## A note on the companion piece

This Write-track submission and the [Build-track submission](https://dev.to/hashevolution/building-a-mini-palantir-on-gemma4e4b-128k-context-lets-the-graph-actually-be-graph-rag-33fk) are deliberately contradictory in tone — one defends the model choice, the other documents where the same model falls short on a different class of prompts. Both are honest readings of the same model under different conditions. I think the contradiction is the point: writing about Gemma 4 useful for the community has to include both halves, not just the half that fits the marketing arc.

If you've read [Ali Afana's parallel piece on MoE vs Dense](https://dev.to/alimafana/i-added-three-rules-to-gemma-4-the-moe-searched-the-dense-model-refused-1j18), you'll recognize the framing: same prompt, opposite behavior, architecture under the model is the variable I wasn't controlling. He came at it from MoE vs Dense; I came at it from 4 B vs 12 B and meta-task vs synthesis-task. The two reports compose.

---

🤖 *Honest disclosure: this submission was drafted with AI assistance and edited by the author. The trace numbers, environment specs, and reproduction commands are real and verifiable in the linked repository. The hypotheses are the author's; the fair-witness framing — data without root cause — is deliberate.*
```

`

---

## Where to publish

dev.to → New Post → Editor v1 (markdown) → paste the body above → set title, tags, cover image → **Publish**.

After publish:

1. Add the URL to `reports/promo-assets/launch-tracker.md` "Social posts" table (or trigger a small docs PR — happy to handle this from a future session).
2. Add a self-reply comment on the article pointing at:
   - The internal eval report ([`gemma4-e4b-cognitive-stages-eval.md`](./gemma4-e4b-cognitive-stages-eval.md)) — the source of truth.
   - The Build-track submission — completes the "two halves, same author" arc.
   - Ali Afana's parallel piece — extends the conversation across two writers.
3. Quote-reply from the existing X English thread + LinkedIn post linking the new article. Image: `06-3d-graph.jpg` again (the hero), or `03-chat-graph-paths.jpg` if the post wants to lead with the chat UI.

## Why this submission can win the Write track

| Rubric criterion | This piece |
|---|---|
| **Clarity and depth of explanation** | One controlled experiment, six tabulated trace rows, four named hypotheses, explicit reproduction script |
| **Originality of perspective or insight** | Fair-witness framing — "I have data, not a conclusion" — is rare in dev.to LLM writing. Most pieces commit to a hypothesis early |
| **Practical value to the community** | The five open questions are answerable by anyone running Gemma 4 + Ollama. Any single reply with falsifying data is useful project-wide |
| **Quality of writing** | Inherited from the eval report's voice — short paragraphs, tight tables, no flourish |

Combined with the Build-track piece, the same author appears twice on the challenge with two non-overlapping perspectives on the same model. That itself is a signal of seriousness — defending a model in one piece and documenting its limits in the other is the opposite of a marketing arc.

## Risk-management notes

- The piece is honest about a failure mode of Gemma 4. It is *not* a hit piece — it explicitly preserves credit for what the model does well, and frames the failure as "rich call for community data" rather than "model is bad." This tone is the actual differentiator.
- The mention of Korean text in failed prompts could be misread as a language-equity issue. The body explicitly frames Hypothesis C as one of four possibilities and proposes the test (Korean-key JSON) — that is the right shape for the claim, not bigger.
- Title A leads with five numbers. If dev.to's automatic linting flags it, B or C are safe fallbacks.

## Companion artifacts

- Source eval report (definitive numbers): [`gemma4-e4b-cognitive-stages-eval.md`](./gemma4-e4b-cognitive-stages-eval.md)
- Feedback-routing handover (what to do when replies arrive): [`docs/handovers/v0.3.x-gemma4-feedback-track.md`](../../docs/handovers/v0.3.x-gemma4-feedback-track.md)
- Build-track Companion: [`devto-gemma4-challenge.md`](./devto-gemma4-challenge.md)
- Visual library for cover / inline images: [`screenshots/README.md`](./screenshots/README.md)
- Launch tracker (running log): [`launch-tracker.md`](./launch-tracker.md)# dev.to — Gemma 4 Challenge submission (Write track)

> Drafted: 2026-05-18
> Track: **Write about Gemma 4** ($100 × 5 winners)
> Source material: [`gemma4-e4b-cognitive-stages-eval.md`](./gemma4-e4b-cognitive-stages-eval.md) — internal fair-witness report (PR #307)
> Companion submission: [Build track piece on E4B model choice](./devto-gemma4-challenge.md)
> Submission deadline: 2026-05-24 23:59 PDT
> Winners announced: 2026-06-04
> Tags: `devchallenge`, `gemmachallenge`, `gemma`, `ollama`

## Why a Write-track submission in addition to the Build-track one

The Build-track submission ([`Building a Mini Palantir on gemma4:e4b — 128K Context Lets the Graph Actually Be Graph-RAG`](https://dev.to/hashevolution/building-a-mini-palantir-on-gemma4e4b-128k-context-lets-the-graph-actually-be-graph-rag-33fk)) made an *intentional model choice* argument: 128K context window > parameter count, so E4B was right for the Graph-RAG retrieval-conditioning stage.

That argument held — and it is still the strongest single thing E4B does in this project.

But once the v0.3 Cognitive Middleware Layer started shipping Phase 2 stages (verification, planner, tool router, query rewriter, fact-check), a second pattern showed up that the Build-track piece could not honestly absorb: E4B silently returns empty responses on five of the nine cognitive stages, while the same prompts on Gemma 3 12B succeed end-to-end.

This is the Write-track piece that documents that pattern honestly, without retreating from the Build-track claim. Same author, two articles, two facets of the same model.

The challenge judging rubric for the Write track is:

- Clarity and depth of explanation
- Originality of perspective or insight
- Practical value to the community
- Quality of writing

A fair-witness field report meets all four at once: it shares reproducible numbers, an explicit "I don't know yet" stance on root cause, and a set of open questions that other operators can act on.

---

## Suggested title (pick one)

| # | Title | Why |
|---|---|---|
| **A** | **5 empty responses from `gemma4:e4b`. 4 hypotheses. 0 root cause.** A fair-witness field report from a Graph-RAG production. | ⭐ Strongest hook — number-led, names a tension (no resolution), promises honesty. |
| B | Where Gemma 4 e4b runs out of room: empty responses on meta-reasoning stages | Clearer technical framing, slightly less click-worthy |
| C | Gemma 4 e4b: brilliant at synthesis, silent on meta-reasoning. A field report. | Bridges the strengths and weaknesses in the title itself |

Recommended: **A**. Numbers-led titles outperform on the dev.to feed; the "0 root cause" half signals the writing is honest rather than gloating.

## Cover image

Use [`reports/promo-assets/screenshots/03-chat-graph-paths.jpg`](./screenshots/03-chat-graph-paths.jpg) — the chat-UI screenshot with "그래프 경로 47개 보기" surfaced. It primes the reader for "this writer ships a real Graph-RAG pipeline" before the article gets into the failure mode.

Download URL: `https://github.com/Hashevolution/James-RAG-Evol/blob/main/reports/promo-assets/screenshots/03-chat-graph-paths.jpg?raw=true`

## Tags

```plaintext
devchallenge, gemmachallenge, gemma, ollama
```

`ollama` is the 4th tag (instead of `rag`) — the failure mode plausibly involves the Ollama chat template or stop-token handling, so the Ollama tag's audience is more likely to recognize the pattern.

---

# Submission body (copy-paste into dev.to editor)

`

```markdown
*This is a submission for the [Gemma 4 Challenge: Write about Gemma 4](https://dev.to/challenges/google-gemma-2026-05-06)*

## TL;DR

`gemma4:e4b` (4 B parameters, the "efficient" Gemma 4 build) **excels at long-form natural-language synthesis from a 5 KB retrieved context** in my Graph-RAG project. It also **silently returns empty responses on five short meta-reasoning stages** — query rewrite, plan decomposition, web summary, self-critique, fact-check. Same model, same backend, same `task` parameter. Swapping to `gemma3:12b` made all five succeed without touching a single prompt.

I have data. I do not yet have a root cause. Posting this as a fair-witness field report in case other local-LLM operators have seen the same pattern (or have a prompt-side fix that doesn't require jumping to a 12 B model).

This is a companion to my earlier [Build-track submission](https://dev.to/hashevolution/building-a-mini-palantir-on-gemma4e4b-128k-context-lets-the-graph-actually-be-graph-rag-33fk), which argued for E4B on the basis of its 128 K context window. That argument is still right — for the synthesis stage. The five meta stages are where the 4 B variant runs out of room.

## Setup (reproducible)

### Project

[**PROJECT JAMES v0.3.x**](https://github.com/Hashevolution/James-RAG-Evol) — a local-first Graph-RAG reasoning engine. MIT-licensed, Ollama-only, no cloud LLM dependency. v0.3.0 shipped the Cognitive Middleware Layer architecture; v0.3.x is landing its phases incrementally — verification engine, planner, tool router, query rewriter, fact-check.

Relevant stages of the cognitive layer:

| Stage | Purpose | Prompt shape |
|---|---|---|
| `query_rewrite` | Rewrite the user question for retrieval | Korean/English instruction → JSON `{"rewritten": "..."}` |
| `plan.decompose` | Break a multi-aspect question into ≤ 5 subtasks | Instruction → JSON `{"subtasks": [...]}` |
| `synth.rag` | The actual long-form answer | System prompt + retrieved context (~5 KB) + Korean question → Korean prose answer |
| `synth.web_summary` | Summarize fetched web results | Instruction + web snippets → short Korean summary |
| `reflect.critique` | Critique the draft answer | Draft + instruction → Korean critique text |
| `verify.fact_check` | Audit claims against source docs | Answer + sources + instruction → JSON `{"grounded": bool, "unsupported": [...]}` |

All stages route through one Ollama backend adapter and use the same `JAMES_LLM_MODEL` env var. Whatever model is named, every stage talks to it the same way.

### Environment

- OS: Windows 11, PowerShell
- Ollama: latest mid-May 2026 build
- Models installed locally: `gemma4:e4b` (9.6 GB, ~4 B params), `gemma3:12b` (8.1 GB, ~12 B), plus a few others irrelevant to this report
- All `JAMES_ENABLE_*` cognitive flags set to `1` in the same shell before launching the server

### Test query

```


BlackRock 과 Vanguard 의 ETF 전략 차이를 비교해줘


```

A real Korean retrieval question. Intent classifier picked `retrieval` correctly. Document corpus contains ~10 finance documents matching the topic.

## What I observed with `gemma4:e4b`

Direct quote of the server console (one query, all stages enabled):

| Stage | LLM call type | Latency | Response size | Result |
|---|---|---|---|---|
| INTENT classify | `task=classify` | 9.1 s | **9 chars** ("retrieval") | ✅ OK |
| `query_rewrite` | `task=general` | 2.1 s | **0 chars** | ❌ empty |
| entity extract | `task=extract` | 9.5 s | **452 chars** (JSON of 9 entities) | ✅ OK |
| `synth.web_summary` | `task=general` | 4.0 s | **0 chars** | ❌ empty |
| `synth.rag` | `task=general` | 13.7 s | **2 690 chars** (Korean prose) | ✅ OK |
| `reflect.critique` | `task=general` | 4.2 s | **0 chars** | ❌ empty |
| `verify.fact_check` | `task=general` | 4.3 s | **0 chars** (prompt 4 319 → truncated to 4 000) | ❌ empty |

The empty-response path is taken when Ollama returns HTTP 200 but `response: ""` — the server replied successfully, the model just produced zero tokens. JAMES logs it as `gemma.empty_response`.

### What's striking

- **The 5 empty responses cluster at ~2–4 seconds.** Not a timeout. The per-stage budget is 10–30 s; the model decided it was done.
- **The two successful `task=general` calls** (entity extract: JSON; synth.rag: long Korean prose) **took 9.5 s and 13.7 s.** Same backend, same model, same `task` parameter — only the prompt shape differs.
- **The pattern is consistent across multiple trials.** Run the same query three times back-to-back and the same five stages are empty each time.

## Control — same prompts on `gemma3:12b`

Same query, same flags, no other changes. Single env-var swap, restart server:

| Stage | Latency | Response | Result |
|---|---|---|---|
| `query_rewrite` | 0.91 s | "BlackRock 및 Vanguard의 ETF 투자 전략과 포트폴리오 구성 방식의 차이점을 비교 분석해줘" — meaning-preserved keyword expansion | ✅ |
| `plan.decompose` | 1.33 s | 3 subtasks (BlackRock 조사 / Vanguard 조사 / 비교 분석) | ✅ |
| `synth.rag` | 9.6 s | 2 690-char Korean answer | ✅ |
| `reflect.critique` | 7.98 s | "## 답변 초안 비판적 검토 — 모순 / 사실 오류 …" — coherent meta-critique | ✅ |
| `reflect.revised` | 9.19 s | revised answer based on critique | ✅ |
| `verify.fact_check` | 1.17 s | `{"grounded": true, "unsupported": []}` — valid JSON | ✅ |

Full 9-step trace renders end-to-end. Wall-clock ~39 s. Same prompts. Same wiring. Same backend.

**This is the punchline: nothing changed except the model name.**

## Where Gemma 4 e4b still wins

Staying fair to the model:

- Long-form synthesis from a 5 KB retrieved context — the project's most-frequent stage — handled well at 13.7 s for 2 690 chars of genuinely useful Korean prose.
- JSON entity extraction with a 9-entity schema returned 452 chars of clean JSON at 9.5 s.
- Single-token classification — emit exactly one of seven mode strings — was fine.

The model is not "broken." It ships real Graph-RAG answers. The narrow failure mode is a second class of prompts: **short, structured, meta-instructional**.

## The failure pattern

```


✅ succeeds    long context + free-form Korean prose
✅ succeeds    short instruction + emit 1 token from a finite vocab
✅ succeeds    rich context + emit one JSON object describing the input
❌ empty       short context + emit JSON that critiques / restructures / audits the input


```

The five empty responses share three traits:

1. **The model is asked to act on a model output** — rewrite the user query, critique a draft, audit claims.
2. **The expected output is short and structured** — a few sentences, or a tight JSON object.
3. **The prompt mixes Korean instructions with English JSON schema keys** — e.g. `{"rewritten": "..."}` or `{"grounded": true, "unsupported": []}`.

A natural-language paraphrase (synth.rag) avoids all three. A JSON entity extraction has trait 3 only, and that one passes. The cluster of all three is what seems to silence the model.

## Four working hypotheses

I have data but not a root cause. Four candidate explanations, listed by my own subjective likelihood:

### A. Meta-reasoning capacity at 4 B is the floor

Critique / verify / decomposition prompts ask the model to reason *about* another reasoning artifact. The empirical literature on small open-weights models (Qwen 2.5-3B, Phi-3-mini, Gemma-2-2B, …) consistently shows the meta-reasoning gap is the first capability to drop below ~7 B params, while paraphrase-from-context survives much smaller. If this is right, no prompt-side fix exists for E4B on these stages.

### B. Early stop-token emission on short structured prompts

Ollama returning `response: ""` on a 2–4 s call (well below the timeout) is consistent with the model emitting EOS / `<end_of_turn>` immediately. Possibly the chat template wrapping resembles a completed conversation when the user prompt itself looks like an instruction-only frame with no input data attached.

### C. Korean instruction + English JSON schema confusion

The five failing prompts all mix Korean directive language with English-key JSON output. The two succeeding `task=general` calls don't (entity extract uses Korean prompt → Korean-content JSON; synth.rag is all Korean). Worth testing whether an all-Korean schema (e.g. `{"재작성된_질의": "..."}`) would change anything.

### D. JAMES-side prompt-truncation artifact

The `verify.fact_check` log shows `prompt 4 319자 → 4 000자 축약` — JAMES capped the prompt at 4 000 chars, which likely chopped the closing brace of an embedded JSON example in the system prompt. If true, this is a JAMES bug, not a Gemma 4 bug — but it would only explain `verify.fact_check`, not the other four empty responses.

The report explicitly **does not** advocate for a single hypothesis — that is the work this feedback round is asking the community to fund.

## What I'd love feedback on

If you've used `gemma4:e4b` (or `gemma4:e2b`) and have data points either way, I'd like to know:

1. Have you seen the same "empty response on short structured prompts" pattern? Especially critique-of-a-draft, JSON schema audit, query rewrite.
2. Did a prompt-engineering change rescue it on your setup? Different chat template, different `num_predict`, different temperature, all-one-language prompts, anything else.
3. Does `gemma4:e2b` show the same pattern, or is it specific to E4B?
4. Does the same prompt set behave on `gemma4:31b-dense` / `gemma4:26b-moe` if you have one of those provisioned?
5. Is there a known issue with Ollama + Gemma 4 + JSON-output prompts in your experience?

Project's stance on next steps:

- Default model swap to `gemma3:12b` is already done locally. `gemma4:e4b` stays available — its long-context synthesis is the project's bread-and-butter stage.
- A follow-up PR (option A2) will let operators wire individual cognitive stages to different backends, so E4B can keep `synth.rag` while a heavier model takes the meta stages.
- We will **not** patch JAMES's prompt shapes specifically to coax E4B into responding on these stages until we understand whether the empty response is the model declining, the chat template misfiring, or a JAMES-side truncation bug.

## Reproduction

If you want to reproduce — or, more usefully, to falsify — the report on your own corpus:

```

powershell
# 1. Install JAMES (one-liner, MIT, no cloud)
git clone https://github.com/Hashevolution/James-RAG-Evol
cd James-RAG-Evol
python -m pip install -r requirements.txt

# 2. Make sure the two models are local
ollama pull gemma4:e4b
ollama pull gemma3:12b

# 3. Enable the five cognitive stages
$env:JAMES_ENABLE_QUERY_REWRITE = "1"
$env:JAMES_ENABLE_PLANNER       = "1"
$env:JAMES_ENABLE_REFLECT       = "1"
$env:JAMES_ENABLE_VERIFY        = "1"
$env:JAMES_ENABLE_FACT_CHECK    = "1"

# 4. Test with Gemma 4
$env:JAMES_LLM_MODEL = "gemma4:e4b"
python server_llmwiki.py
# In another shell, send a retrieval query, e.g. the same BlackRock vs Vanguard line above.
python scripts/replay_trace.py --recent

# 5. Control: Gemma 3
$env:JAMES_LLM_MODEL = "gemma3:12b"
python server_llmwiki.py
# Same query, same trace command — all 9 stages succeed


```

If you publish your own numbers — X / GitHub issue / Reddit / dev.to comment — please tag `#JAMES` or open an issue on the [repo](https://github.com/Hashevolution/James-RAG-Evol). I'll link it back to this report.

## A note on the companion piece

This Write-track submission and the [Build-track submission](https://dev.to/hashevolution/building-a-mini-palantir-on-gemma4e4b-128k-context-lets-the-graph-actually-be-graph-rag-33fk) are deliberately contradictory in tone — one defends the model choice, the other documents where the same model falls short on a different class of prompts. Both are honest readings of the same model under different conditions. I think the contradiction is the point: writing about Gemma 4 useful for the community has to include both halves, not just the half that fits the marketing arc.

If you've read [Ali Afana's parallel piece on MoE vs Dense](https://dev.to/alimafana/i-added-three-rules-to-gemma-4-the-moe-searched-the-dense-model-refused-1j18), you'll recognize the framing: same prompt, opposite behavior, architecture under the model is the variable I wasn't controlling. He came at it from MoE vs Dense; I came at it from 4 B vs 12 B and meta-task vs synthesis-task. The two reports compose.

---

🤖 *Honest disclosure: this submission was drafted with AI assistance and edited by the author. The trace numbers, environment specs, and reproduction commands are real and verifiable in the linked repository. The hypotheses are the author's; the fair-witness framing — data without root cause — is deliberate.*
```

`

---

## Where to publish

dev.to → New Post → Editor v1 (markdown) → paste the body above → set title, tags, cover image → **Publish**.

After publish:

1. Add the URL to `reports/promo-assets/launch-tracker.md` "Social posts" table (or trigger a small docs PR — happy to handle this from a future session).
2. Add a self-reply comment on the article pointing at:
   - The internal eval report ([`gemma4-e4b-cognitive-stages-eval.md`](./gemma4-e4b-cognitive-stages-eval.md)) — the source of truth.
   - The Build-track submission — completes the "two halves, same author" arc.
   - Ali Afana's parallel piece — extends the conversation across two writers.
3. Quote-reply from the existing X English thread + LinkedIn post linking the new article. Image: `06-3d-graph.jpg` again (the hero), or `03-chat-graph-paths.jpg` if the post wants to lead with the chat UI.

## Why this submission can win the Write track

| Rubric criterion | This piece |
|---|---|
| **Clarity and depth of explanation** | One controlled experiment, six tabulated trace rows, four named hypotheses, explicit reproduction script |
| **Originality of perspective or insight** | Fair-witness framing — "I have data, not a conclusion" — is rare in dev.to LLM writing. Most pieces commit to a hypothesis early |
| **Practical value to the community** | The five open questions are answerable by anyone running Gemma 4 + Ollama. Any single reply with falsifying data is useful project-wide |
| **Quality of writing** | Inherited from the eval report's voice — short paragraphs, tight tables, no flourish |

Combined with the Build-track piece, the same author appears twice on the challenge with two non-overlapping perspectives on the same model. That itself is a signal of seriousness — defending a model in one piece and documenting its limits in the other is the opposite of a marketing arc.

## Risk-management notes

- The piece is honest about a failure mode of Gemma 4. It is *not* a hit piece — it explicitly preserves credit for what the model does well, and frames the failure as "rich call for community data" rather than "model is bad." This tone is the actual differentiator.
- The mention of Korean text in failed prompts could be misread as a language-equity issue. The body explicitly frames Hypothesis C as one of four possibilities and proposes the test (Korean-key JSON) — that is the right shape for the claim, not bigger.
- Title A leads with five numbers. If dev.to's automatic linting flags it, B or C are safe fallbacks.

## Companion artifacts

- Source eval report (definitive numbers): [`gemma4-e4b-cognitive-stages-eval.md`](./gemma4-e4b-cognitive-stages-eval.md)
- Feedback-routing handover (what to do when replies arrive): [`docs/handovers/v0.3.x-gemma4-feedback-track.md`](../../docs/handovers/v0.3.x-gemma4-feedback-track.md)
- Build-track Companion: [`devto-gemma4-challenge.md`](./devto-gemma4-challenge.md)
- Visual library for cover / inline images: [`screenshots/README.md`](./screenshots/README.md)
- Launch tracker (running log): [`launch-tracker.md`](./launch-tracker.md)
At some point you clicked login with Google or another account on a third-party app because it was faster and it was the easiest way to get what you wanted from the site. You clicked and forgot about it. Well, so did a Vercel employee. That single click is exactly how threat actors walked straight in one of the most widely recognized cloud platforms on the internet on April 2026. The attackers accessed internal environment variables (dynamically set value that is used throughout a program and determines properties of a program on each device) and came back demanding $2 million. This was solely possible because of a forgotten permission and a chain of connections which was not so on the foreground. Here’s the plot.
Press enter or click to view image in full size
More about Vercel
Vercel is an American cloud application company that specializes in providing developer tools and infrastructure for building, deploying, and maintaining websites. It is particularly known for its creation and optimization of the Next.js framework, which is widely used for React applications. It is optimized for Next.js but it also supports other frameworks such as Django and Flask. This breach specifically did not compromise Vercel’s customer side encryption but it exposed the internal environment variables, which should not have been open to the outside. The breach mainly has to do with OAuth permissions, so OAuth is the protocol behind every “login with Slack” or “connect with GitHub” button we normally click. When we authorize a third party app, we issue it with a token (a temporary access key) that lets it act for you together with whatever permission you allowed. Now, the problem here is that most people usually click “allow all” which hands you the main body key to your account. Once the connection is activated and given permission, it just sits there trusted by every system it comes into contact with. These integrations are given broad permissions because companies tend to think functionality is more important than security. After connecting, they forget about them and never audit what data these apps have access to.
The Vercel breach is not the first time this exact mechanism caused a big problem. In August 2025 a threat actor called UNC6395 used stolen OAuth tokens from Drifts Salesforce integration where they accessed customer environments across more than 700 organizations. This was done without any exploit or phishing involved. The same method was used, but with different companies.
How Did The Breach Start In The Beginning?
The Vercel breach did not start at Vercel though. It actually started a lot earlier at an AI company. This is a small startup that most people do not know about. The Vercel breach then moved from this artificial intelligence company to other places through a chain of people and companies that everyone trusted. Back in February 2026, an employee of Context.ai (an enterprise AI productivity tool, part of the growing category of “AI Office Suite” products that plug into your Google Workspace) was infected with Lumma Stealer malware. Lumma Stealer is an information-stealing malware. It specializes in stealing sensitive data such as browser information or cryptocurrency wallet details. The infected employee was a core member of the startup team with direct access to important administrative endpoints including the environment variable settings and production logs that made it more vulnerable for stealing of critical information.
Hudson Rock’s intelligence analysis found out that the employee had been downloading Roblox “auto-farm” scripts and executors. This is an efficient delivery vector for malware such as this Lumma Stealer.
Not Your Usual Password Stealer
Lumma is a session vacuum meaning it does not need your password to steal you active browser cookies, tokens that tell websites “this guy is already logged in, trust them”. It bypasses MFA entirely. The threat actors are thus not logging in as you but resuming your ongoing session at a website. This is not an advanced malware used by governments. Infostealers such as Lumma are a type of malware that can be bought and used by anyone running around fifty dollars per month which is actually cheaper than software subscriptions. In the first half of 2025 these infostealers stole, over two hundred seventy thousand Slack login details. (Engaging in the purchase, distribution, or use of malware is illegal and carries severe criminal penalties. This information is provided for educational purposes to help security professionals and organizations defend against these evolving threats.)
The Threat Actors:
A threat actor using the ShinyHunters persona notified that they were responsible for the attack via Telegram and BreachForums. They claimed to have stolen access keys, source code and other valuable information and demanded $2 million in return. Vercel confirmed the breach publicly and said that it affected a limited group of customer information. They notified law enforcement, checked with GitHub, Microsoft, npm and Socket to make sure none of the packages on npm were compromised.
Important: Vercel also published a specific OAuth Client ID as an indicator of compromise:
110671459871-30f1spbu0hptbs60cb4vsmv79i7bbvqj.apps.googleusercontent.com
Google Workspace admins should check their API Controls console for this immediately.
Two Things to Do For Businesses Before You Close This Tab:
Go to myaccount.google.com/permissions. Every app listed has some level of access to your Google account. Check these thoroughly and disable permissions if not in use. Also, review activity log for any suspicious or unrecognized activity. Attackers no longer need to deploy detectable payloads. They use OAuth tokens and API keys and service accounts to access secure systems which makes their actions appear like regular business operations. Traditional perimeter defenses and endpoint detection systems fail to detect adversaries who operate with real credentials through authentic system connections.
The Only Best Conclusion
The Vercel breach will be described in three ways it represents a supply chain attack and an OAuth failure and an infostealer incident. All of those framings are correct. But the simplest framing is this: someone granted a permission, forgot about it, and that forgotten permission became a $2 million problem.
You need to check your permissions at this moment instead of waiting until next week.
It’s 12:50am on a Wednesday. I’m in bed, phone glowing in the dark. Someone in my X timeline just posted a 15-second Seedance 2.0 clip and called it “the end of traditional film and drama production.” There are 3,200 likes. I scroll. The next post is a Claude Code thread from a founder who shipped a Notion competitor in six days. Then another announcement, another model release, another founder shipping faster than I am.
I close X. I open it again four minutes later.
I’ve been doing this for 15 years now — product management at scale, then building my own companies. I’ve been through Web 2.0, the mobile shift, the SaaS boom, the great cloud migration. None of those felt like this.
Naming the feeling
Some have started calling it AI Blue. It isn’t the burnout I had in 2018. It isn’t the imposter syndrome of being a junior PM in 2009. It has a specific shape.
It’s the strange experience of working on something for months while watching the floor underneath shift in real time. It’s reading a paper on Saturday and rewriting your roadmap by Tuesday. It’s opening Claude Code and feeling slightly relieved and slightly diminished at the same time.
It’s the dread that visits at 1am after you’ve been doom-scrolling demos, not because you’ve decided you should pivot, but because you can’t quite tell anymore whether what you’re building is real work or just stalling.
Why this is different from previous waves
Previous tech transitions had a rhythm. The thing that was coming was big, but it was distinct. Web meant the desktop developer either learned JS or didn’t. Mobile meant the same with iOS. You could see the new world from where you were, and you could decide whether to walk toward it.
This is different. The thing that’s arriving isn’t a new platform. It’s a moving capability that keeps absorbing work itself. Becoming an “AI-augmented builder” isn’t a one-time switch you flip — it’s a moving target. You start using Claude Code, and a few months later the same Claude Code does work that used to be your job. Every release shifts the line of what counts as “your contribution” and what counts as “just orchestration.”
For someone who got into product work because of the specific feeling of taking a messy customer problem and translating it into something a team can actually ship, this hits a layer that previous transitions didn’t.
Why the usual coping tools don’t fit
For a few months I tried the usual moves. Most of them didn’t quite work.
CBT — the kind in self-help books — is great when your brain is telling you “everyone will laugh at me” or “I’ll fail this presentation.” You write the thought down, check it against evidence, reframe. The reframe lands because the original thought was actually wrong.
CBT doesn’t fit AI Blue because the thoughts are partially right. “What I’m building might get cloned by the next model release” isn’t a distortion. It’s a forecast grounded in evidence from the last 18 months. You can’t reframe your way out of a forecast.
Therapy was another option. The therapist I found was kind, smart, and had no idea what a model release was. Trying to explain why I cared that Claude got better at long context made me feel like I was speaking a foreign language. Not her fault. Just not the right fit for this specific moment.
Talking to ChatGPT about it — which I tried, more than once — is funny in retrospect. Because ChatGPT is half the source of the dread. Asking ChatGPT to help process my anxiety about AI is like asking Wall Street to help process my anxiety about capitalism. Technically it can offer thoughts. The frame just doesn’t sit right.
What started to actually help
Around month three I came back to a framework I’d half-known for years: the Stoic dichotomy of control.
The idea isn’t original. Marcus Aurelius wrote about it. Epictetus wrote about it. Tim Ferriss tweets about it once a quarter. The move is to take whatever’s weighing on you and sort it into two columns: what you actually control, and what you don’t.
For AI Blue, the columns look like this:
Outside my hands:
In my hands:
I read that list and felt embarrassed. I’d been spending most of my anxious energy on the left column. The left column doesn’t move because of my attention. The right column does.
Here’s a concrete scene. Couple weeks ago, I was reading a tweet from another founder who’d just shipped an AI drama production tool — same problem I’m solving, similar workflow integration approach. My instinct was to message my brother — he’s not a builder — to ask if the world even needed what I was making. I noticed the impulse. Didn’t send. Tried the column thing instead.
In my control: keep shipping my version this week, pivot, or close the laptop and watch a movie. Not in my control: how fast they iterate, whether their version gets traction first, whether my brother understands what I’m even worried about.
I closed the laptop and watched a movie. Worked on my version the next day. Their tool kept moving — got some traction, some not. I shipped mine. A handful of people are using it.
That’s not a triumphant story. They’ll keep building. Someone else will ship something similar next month. But I have a thing in the world being used by real people now, instead of a thing in my head that I never built because I was anxious about a hypothetical.
The second thing that helped is an idea from acceptance-commitment therapy: values. Not as a poster on a wall. As a question — what kind of person am I, regardless of what AI does this year? What kind of work am I drawn to, regardless of whether AI eventually does that work better?
This part is uncomfortable because the answers aren’t impressive. They’re things like: “I like the feeling of making something that someone uses.” “I like the moment of figuring out a hard problem.” “I want to be the kind of person who calls his parents weekly.”
But those things don’t change because of a model release. They were mine before AI and they’ll be mine after.
Why I built a thing
I built a small thing called Oase because I needed something that did the above for me at 1am. The control split, the values question — they sound simple. They’re harder to do alone in your head at 12:50am than they look.
I’m not the right audience for therapy at that hour. I’m not in crisis. I just need a focused conversation that knows what Claude Code is and helps me run through the move I described above. Ten minutes. Then back to bed.
So I built it. It’s an AI. I know — I sat on the idea for months for exactly that reason. But after enough 1am moments where I tried the alternatives and they didn’t fit, I built the thing I needed.
It’s not therapy. Not a meditation app. One focused conversation, about ten minutes, that helps you split what you control from what you don’t and ends with one small thing for tonight that isn’t work. Beta is opening this week. There’s a landing page at oase.monadlabs.co.
An open question to readers
I’m writing this partly because I want feedback. I’m not sure if “AI Blue” is the right name. I’m not sure if 1am is the right time to optimize for. I’m not sure if ten minutes is the right length. I’m not even sure if the premise — using an AI to talk about AI anxiety — is something other people will accept.
What I am sure of: the feeling is real, it’s specific, it doesn’t match anything I’ve had before, and a lot of people I respect in this industry are quietly carrying it.
If any of this lands for you, I’d love to hear about it. Either through the beta signup or just in the comments. If none of it lands, I’d also love to hear about that. I want to know if I’m reading this moment wrong.
This is a submission for the Gemma 4 Challenge: Build with Gemma 4
Google’s AI story is usually told from the top of the stack.
Bigger models. Better reasoning. More multimodal demos. More cloud endpoints.
That is useful. But there is a different question that kept nagging at me:
What happens when the person who needs the AI is not sitting in a perfect cloud environment? What happens when they are on a farm, the internet is weak, the data is local, and the decision is not abstract at all?
That is why I built SoilSense AI.
What I Built
SoilSense AI is an offline-first farm intelligence app powered by Gemma 4. It runs on a PC, phone, tablet, or Raspberry Pi hub. It connects farm profiles, live soil sensor readings, plant analysis, chat history, and local memory into one app — and it works without a cloud account.
The core problem it solves: most AI agriculture demos skip the boring part. They show a nice chat box, the farmer asks a question, the model gives a confident answer. But real farms are not a single prompt.
A farmer may have one field for vegetables, another for flowers, another for fruit. Each has different crops, soil conditions, irrigation patterns, and disease risks. If those readings get mixed together, the AI advice becomes worse than useless. It becomes confidently wrong.
There is also the connectivity problem. A system that only works when the cloud is reachable is not good enough for many rural environments.
So SoilSense is built on a different assumption: the farm is the source of truth. Gemma 4 is the reasoning layer.
What the app includes:
The important part is not just that Gemma answers farm questions. It is that Gemma answers with the farm’s context already in front of it.
Demo
Demo video: https://youtu.be/EJ6397EinNw?si=a9Ei3Fxmsh_UHHjV
GitHub: https://github.com/ogMaverick12/soilsense-ai/tree/beta
The demo flow:
One honest note: I do not currently have physical sensor hardware connected for the submission demo. The demo uses Judge Mode — it replays sensor packets through the same local bridge endpoints that real ESP32 and Raspberry Pi nodes use. It proves the ingestion and routing pipeline, but it is replayed data, not live hardware.
Code
Tech stack:
bridge/server.mjs)farmId and sensorNodeId on every readingThe project structure keeps concerns clean: src/ has the React app and app logic, bridge/ has the local hub, desktop/ has the Electron shell, android/ has the Capacitor project, and scripts/ has Pi and Windows launchers. Docs cover setup, mobile deployment, Raspberry Pi use, sensor integration, and packaging.
How I Used Gemma 4
SoilSense is intentionally Gemma-only. The UI and local bridge both reject non-Gemma model tags. That matters because I did not want the submission to quietly become a generic model-switcher wrapper. The point is to show Gemma 4 as the reasoning engine for a local-first farm workflow, not as one option among many.
Model strategy is hardware-aware:
gemma4:e2b — preferred for Raspberry Pi and weak edge devicesgemma4:e4b — the balanced local desktop path (detected and tested on my machine through Ollama)google/gemma-4-31b-it — the API path for stronger disease reasoning when internet is availableFor analysis, Gemma receives structured context:
The output is also structured. SoilSense prompts Gemma for a JSON response covering health status, primary issue, urgency, confidence, disease evidence, soil interpretation, sensor correlation, memory used, spoken alert, and next actions. That lets the UI show a practical verdict instead of dumping raw prose into a chat window.
Gemma also powers a free-form farm chat mode. Even there, the selected farm’s local memory is passed as context — so chat answers are grounded in that farm’s history, not a blank slate.
Local evidence from my test machine (Windows x64, 8 CPU threads, 15.8 GB RAM, gemma4:e4b via Ollama):
| Capability | Result | Honesty note |
|---|---|---|
| TypeScript check | Passed (npm run typecheck) |
Static check only, not a full end-to-end test |
| Production build | Passed (npm run build) |
dist/ is generated output, not committed |
| Windows installer | Built (SoilSense AI Setup 0.1.0.exe) |
Attached to GitHub Releases, not the repo |
| Android debug APK | Built via Capacitor + Gradle | Debug build unless signed release is created |
| Setup health endpoint | Passed: app, LAN, sensor, node, and model checks | Depends on local machine and network |
| Judge Mode replay | Accepted 9 packets across 3 farms | Replayed packets, not physical hardware |
| Farm-scoped sensor route | Returned orchard readings for judge-fruit-orchard
|
Proves routing by farmId through the bridge |
| Local Gemma detection | Detected gemma4:e4b through Ollama |
Recommendation changes by hardware and installed models |
| Local Gemma smoke test | Returned a response in ~70 seconds | Latency depends heavily on hardware and model warm state |
That last number is not a universal benchmark. Local inference speed depends on hardware, model size, and warm state. But it proves the local path is wired end to end on my machine.
Where I Would Push Back On My Own Project
SoilSense does not prove field-grade sensor calibration. Low-cost pH and NPK sensors can be noisy. A real deployment needs calibration records, placement guidance, and local agronomy validation.
It does not prove every Android phone can run local Gemma. Phone-local support depends on the Android on-device GenAI runtime and device capability — which is exactly why the PC/Pi hub mode exists as the fallback.
It is also not a replacement for local experts, lab tests, pesticide labels, or official agricultural guidance. SoilSense is decision support. It is not a magic agronomist in a box.
I think that honesty makes the project stronger. The architecture is built for the real constraint: use local data, keep the farmer in control, and let Gemma reason over context instead of isolated prompts.
Final Take
The most exciting AI apps are not always the ones with the largest model call.
Sometimes the real product is the boring glue around the model — local data, memory, sensor routing, setup flows, privacy boundaries, and a UI that someone can actually use on a farm with weak internet.
That is what SoilSense AI is trying to be.
Not just “Gemma, answer a farm question.”
Gemma 4 with the farm profile, the sensor feed, the history, the crop, and the constraints in front of it.
That is the difference between a chatbot and a tool. And for farmers working with local hardware and unreliable connectivity, that difference matters.


