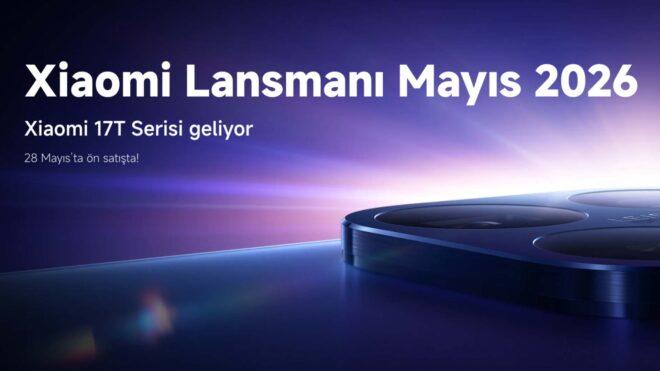
Xiaomi 17T serisi resmi olarak Türkiye’de de satışa sunulacak

Xiaomi 17T

Xiaomi 17TBugün Xiaomi tarafından yapılan açıklamaya göre Xiaomi 17T serisi resmi olarak Türkiye’de de satışa sunulacak. 28 Mayıs’ta tanıtılacak ve aynı gün Türkiye’de ön satışa çıkarılacak seride, tam olarak iki farklı model yer alıyor. Kısa süre önce Roland Quandt tarafından detaylandırılan Xiaomi 17T, 6,59 inç boyutunda 120 Hz AMOLED ekran, MediaTek Dimensity 8500 Ultra işlemci, 12 GB LPDDR5X RAM, 256/512 GB UFS 4.1 depolama, 67W şarj destekli 6.500 mAh batarya ve 32 megapiksel selfie kamerasıyla geliyor. Cihazın arkasında ise 50 megapiksellik Light Fusion 800 sensörlü geniş açı, 5x optik zoom sunan 50 megapiksel telefoto ve 12 megapiksel ultra geniş açı kameralar bir araya getiriliyor. Üst model Xiaomi 17T Pro ise sızıntıya göre 6,83 inç boyutunda 144 Hz AMOLED ekran, MediaTek Dimensity 9500 işlemci, 12 GB LPDDR5X RAM, 512 GB UFS 4.1 depolama, 100W şarj destekli 7.000 mAh batarya ve 32 megapiksel selfie kamerasıyla geliyor. Cihazın arkasında 50 megapiksellik Light Fusion 950 […]

Xiaomi 17T serisi resmi olarak Türkiye’de de satışa sunulacak yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

AI Landing Page Builders in 2026: A Developer’s Honest Take

So your non-technical co-founder just asked you to “quickly build a landing page” for the new product launch. Again.

You could spin up a Next.js project, configure Tailwind, set up a CMS, write the copy yourself, and deploy to Vercel. Or you could hand them an AI landing page builder and get back to the actual codebase.

In 2026 the second option is genuinely viable. Here is what actually works — and what to watch out for as someone who knows enough to be opinionated about this stuff.

The part that matters to developers

Most landing page builder comparisons focus on the demo output. As a developer you probably care about different things.

  • Does the generated code not make your eyes bleed?
  • Can a non-technical teammate maintain it without pinging you every time?
  • Is the publish path clean enough that you do not have to get involved?
  • Does it not lock everything into a proprietary format with no exit?
  • Will it load fast without you having to optimize it manually?

That last point is worth emphasizing. A beautiful AI-generated page that scores 43 on PageSpeed is not a landing page. It is a problem you will eventually get tagged in to fix.

What is actually worth recommending to your team

⚡ Unicorn Platform
The one you can recommend without reservations to a non-technical co-founder or marketer. Fast generation, clean no-code editor, direct publish path. The page stays editable after launch without anyone needing to touch code. Good fit for SaaS launches, waitlists, and product pages — which is probably what your team needs anyway.

The output is not going to win any awards for code elegance but it is clean enough, loads reasonably fast, and most importantly your teammates can update it themselves at 11pm before a launch without creating a GitHub issue for you.

🆓 Wix AI
Free entry point. If someone on the team wants to test a landing page workflow before committing budget, this is the least painful starting point. Broad feature set, easy onboarding, no technical setup required. You will probably never touch it directly which is exactly the point.

🎯 Landing-page.io
Describe the product, generate the page, publish. That is the entire workflow. No configuration, no setup, no opinions about your stack. Best for fast campaign pages where the only requirement is “live by end of day.”

🎨** Figma Make**
If your team already uses Figma for design handoff, this fits naturally into the existing workflow. Prompt to layout, visual iteration, responsive prototyping. The publish path is not as direct as other tools but for design-heavy teams it makes sense. Bonus: designers can own the whole process without pulling you in.

📈 Webflow AI
The one with actual structure underneath. If the landing page is the start of a bigger content site — blog, multiple product pages, SEO content — Webflow gives you reusable components, a proper CMS, and enough control that you will not hate what it produces. More setup overhead but the output is more defensible long-term.

🌍 Rollout
Fast generation with multilingual support and export flexibility. Good for teams that want to deploy outside the builder’s native environment. The export workflow means you can actually look at what you are getting before it goes anywhere.

🔧 Dorik AI
Practical middle ground for no-code operators. Direct publish, CMS options, expandable into a full site later. Less opinionated than Webflow, more structured than pure speed tools.

The technical watch-outs

Things to check before recommending any AI landing page builder to your team:

  • Page speed score on mobile (aim for 80+)
  • Custom domain support (non-negotiable)
  • HTTPS by default (also non-negotiable)
  • Export options if you ever need to migrate
  • Whether the embed/script situation is a mess
  • Meta tag and OG tag control
  • How the page handles images (lazy loading, WebP support)

Most tools pass the basics in 2026. The ones that do not are usually obvious within five minutes of generating a test page.

The real reason developers should care about this
Here is the honest case for caring which AI landing page builder your team uses.
Every time a non-technical teammate cannot update the landing page themselves, they create a ticket. That ticket lands in your queue. You spend twenty minutes on something that should have taken them two minutes.
Multiply that by every pricing update, every new testimonial, every CTA test, every seasonal promotion. That is a meaningful chunk of developer time going to page maintenance instead of product work.
The right AI landing page builder is the one that eliminates that category of ticket entirely. Not because the page is perfect. Because your teammates can fix it themselves.

Bottom line

For most teams the recommendation is straightforward:

  • Non-technical co-founder needs a page live this week → Unicorn Platform
  • Want to test before spending anything → Wix AI
  • Campaign page needed by end of day → Landing-page.io
  • Design team already in Figma → Figma Make
  • Building a full content site → Webflow AI

Full comparison with more detail on each tool: unicornplatform.com/blog/ai-landing-page-builders-in-2026

Local Models are getting so good these days. Imagine having an AI agent on your local machine. No API keys. No Subscription. No Rate Limits. I installed Gemma 4 E2B on a 10-year-old laptop. Read to find out my experience.

tech_girlll profile

I Built a Single-File AI Agent in Go — Zero Dependencies, Double-Click to Run

Hey DEV community! 👋

I’m an undergrad developer who spent the last few months hacking on something I’m excited to share: OpenAgent — a local AI Agent that ships as a single binary. No Docker. No Node.js. No Python environments. Just download the .exe and double-click.

GitHub: github.com/the-open-agent/openagent ⭐

The Problem I Was Trying to Solve

Like many of you, I’ve been experimenting with AI Agents for everything from code generation to automating tedious tasks. But I kept hitting the same friction:

# Typical "getting started" experience
npm install -g some-agent
# 847 packages installed...
# Oh, you need Python 3.9+ too
pip install ...
# Also Docker for the vector DB
docker-compose up
# 12 minutes later...
# Wait, why is this 400MB?

Sound familiar? I wanted something that felt more like:

# Download openagent.exe (23MB)
# Double-click
# Done ✅

So I built it.

What Makes OpenAgent Different

Single Binary, Zero Runtime Dependencies

I wrote OpenAgent in Go with a specific constraint: everything must compile into one executable. The React frontend gets embedded at build time. The backend is pure Go. One process, one port (14000), one file.

The result:

  • 23 MB executable (vs 400MB+ for typical setups)
  • ~2.7s cold start (vs 30s for alternatives)
  • ~110 MB idle memory

It’s Not Just “Hello World”

Despite being a single file, OpenAgent packs real capabilities:

Feature Details
🤖 Models 30+ providers: OpenAI, Claude, DeepSeek, Gemini, Mistral, Grok…
🌐 Browser Real browser automation (navigation, clicks, forms, screenshots)
🖥️ Shell Local command execution with PTY support
📄 Office Read/write Word, Excel, PowerPoint
🔗 MCP Plug-and-play with any MCP-compatible server
📚 RAG PDF/Word/Excel → automatic chunking, embedding, indexing
⚡ Workflows BPMN-style visual orchestration
📊 Dashboard Token usage, activity logs, tool management

Why Go Instead of Python?

“But isn’t AI/ML Python’s domain?”

Here’s the thing: Agent performance is bottlenecked by LLM API calls, not language execution speed. The magic happens in the architecture — how you orchestrate tools, manage state, handle concurrency.

Go gives me:

  • Static compilation → single distributable binary
  • Goroutines → efficient concurrency without the memory bloat
  • Cross-platform → Windows/Mac/Linux from one codebase
  • No runtime → users don’t install anything

For a “personal local Agent,” these trade-offs beat Python’s dynamic flexibility.

Quick Start

Windows (easiest):

  1. Download openagent_Windows_x86_64.exe from Releases
  2. Double-click
  3. Open http://localhost:14000

macOS/Linux:

curl -fsSL https://raw.githubusercontent.com/the-open-agent/openagent/master/scripts/install.sh | bash

Configure your model:
The UI has a one-click setup for OpenAI, Claude, DeepSeek, or any OpenRouter-compatible provider.

The Engineering Decisions I’m Proud Of

1. Shell with Guardrails

Shell access is powerful but dangerous. In tool/shell.go, I built in:

  • Default 30s timeout (max 300s)
  • Session-based poll/write/submit flow
  • Optional PTY for interactive programs
  • Audit logging for every command

It’s designed as a production tool, not a foot-gun.

2. Memory-Conscious Concurrency

I ran an 80-concurrent health check stress test. Memory grew by 10 MB. Go’s goroutine + channel model makes this trivial compared to the memory curves I’ve seen in Node.js-based agents.

3. Frontend Embedded, Not Served

The React build gets embedded into the binary with Go’s embed package. No separate static files to manage, no path resolution issues, no “where did my assets go” bugs.

Real Talk: What’s Not Perfect

I want to be transparent about where we stand:

Metric OpenAgent OpenClaw
Lighthouse Score 45 87
Health Check P50 ~33ms ~20ms

Our frontend loading needs work. The Lighthouse gap is real — we’re optimizing it. The health check difference is milliseconds, but still.

If you find cases where we’re slower or more expensive, file an issue. I genuinely want to know.

Who This Is For

  • Developers who want a Claude Code alternative that runs locally with their own API keys
  • Privacy-conscious users who don’t want data leaving their machine
  • Resource-limited setups where running multiple agents used to be impossible
  • Security folks who need audit trails and controlled shell access

Get Involved

OpenAgent is Apache 2.0 licensed. The code is on GitHub, and I review issues/PRs within 12 hours.

If the project helps you, a ⭐ means a lot. If you want to contribute, there are plenty of good first issue labels waiting.

GitHub: github.com/the-open-agent/openagent

Discord: discord.gg/5rPsrAzK7S

The Bigger Picture

I believe personal AI Agents should be lighter, not heavier. One file. Double-click. Done.

No 400MB installs. No dependency hell. No “it works on my machine.”

Just an Agent that does the job and gets out of your way.

That’s OpenAgent.

Built with Go, caffeine, and the stubborn belief that software should just work. ☕

Multilingualism in startups

When launching a startup, don’t make it multilingual until you have stable revenue and a team to support it. You can’t know whether the startup will become profitable, so early on, your time is better spent finding PMF and acquiring users. AI can write scripts to manage translation files and help with text translation, but the quality will still be poor. Users might as well use the browser’s built-in translator.

If you build the service in 10 languages right away, you’ll struggle to maintain it. Every interface change means updating translation files across all languages, even though most of your users will likely understand an English interface anyway. But if you’re building for a specific country, build it in that country’s language and don’t add English. Even two languages at the start are worse than one. With a single language, you can keep text directly in the code instead of splitting it into separate translation files.

You’re Already Using Git Worktrees. You Should Understand Them.

Diagram

If you’ve ever run git clone and then started editing files in the resulting folder, you’ve been using a Git worktree all along. Git just doesn’t call it that in day-to-day conversation.

git worktree is the feature that lets you add more checkouts (more folders with files on disk) that all share the same underlying repository history. Done well, it replaces the “stash/switch/stash-back” dance with something simpler: keep your in-progress work open in one directory, and do the urgent/clean/experimental thing in another.

This is a mental-model article: what a worktree is, why Git enforces “one branch per worktree,” and the few lifecycle commands that keep worktrees from turning into confusing “already checked out” / stale-metadata problems.

The Mental Model: Shared History, Separate Working State

Git’s own git worktree docs describe the feature as managing “multiple working trees attached to the same repository.” The twist is that you always start with one: the directory you land in after a normal (non-bare) clone is the main worktree.

Linked worktrees are additional working directories attached to the same repo. They share the object database (commits/trees/blobs), but each worktree has its own working state: checked-out files, its own HEAD, and its own index (staging area).

That’s the whole trick:

  • Shared: history and objects (you don’t redownload Git data like a second clone).
  • Per worktree: files-on-disk + HEAD + index (you don’t stomp on your other checkout).

One nuance that matters: a worktree isn’t its own independent “repo.” Most refs and remote configuration are shared. When you git fetch, you’re updating the shared repository data that all worktrees see. That’s what makes worktrees lighter than multiple clones—but it’s also why Git has to be careful about how a branch name maps to a checkout.

If you want a deeper explanation of why “objects live once” makes this efficient, the Git book’s “Git Objects” chapter is a good reference: Git Internals: Git Objects.

Diagram

What Actually Changes on Disk when You Add a Worktree

Git keeps the shared repository database in one place, then tracks per-worktree state separately. That’s why it can add a second checkout without cloning.

If you’ve ever noticed that .git sometimes looks like a file (not a folder), that’s often Git pointing your working tree at the real “gitdir.” Worktrees lean on this idea heavily: each worktree has its own admin area, but the objects are shared.

The Rule that Surprises People: One Branch per Worktree

If you try to attach the same branch to two worktrees, Git will usually refuse with “branch is already checked out.” That refusal is protection.

The core reason is that a branch name is just a movable pointer. If two working directories could both “be” feature, the branch pointer could move in one directory while the other directory still has older files on disk. Now you have a branch name that no longer uniquely identifies a single working state.

Said differently: Git is fine with multiple worktrees having different HEADs (each checkout is independent), but a branch ref like refs/heads/feature is shared at the repository level. Letting two worktrees both “own” the same branch would create a footgun where “what commit is feature?” depends on which folder last advanced it.

Git worktree visualized

When you want “two directories, same starting point,” Git’s safer options are:

  • Create a new branch name for the second worktree:
git worktree add ../wt-fix -b fix-branch
  • Use a detached HEAD when you don’t intend to keep the work long-term:
git worktree add -d ../wt-scratch

Detached HEAD is the “I want another directory at this commit, but I’m not claiming a branch name” mode. That’s why it’s safe: you can still make commits, but you’re not advancing a shared branch ref unless you later create one.

--force exists for edge cases, but it’s opting out of a guardrail. If you don’t already know why you need it, you probably don’t.

Where Worktrees Shine (in Practice)

Worktrees are a productivity primitive whenever parallelism beats context switching. Three common patterns:

1) Hotfix without Touching Your In-Progress Directory

When a production issue lands mid-feature, create a new worktree on a hotfix branch:

git worktree add ../wt-hotfix -b hotfix

You get a clean checkout in a new folder, and your original directory stays exactly as it was. When you’re done, remove it cleanly:

git worktree remove ../wt-hotfix

Tower’s Git worktree FAQ describes this as one of the “default” worktree use cases, and it’s the one most people feel immediately.

2) PR Reviews and Repros in a Clean Sandbox

You can attach a worktree directly to a remote-tracking branch and keep it around for as long as the review takes:

git worktree add ../wt-review origin/some-pr-branch

3) Scratch Experiments You Don’t Want to Keep

Detached worktrees are great for “let me try something” work without committing to a branch name yet:

git worktree add -d ../wt-scratch

If you end up making commits you want to keep, create a branch before you delete the folder so you don’t lose track of them.

A Quick Note on “Why Not Just Clone Twice?”

Separate clones can absolutely solve the same “two directories” problem. The difference is mainly cost and coupling:

  • Clones duplicate setup (another fetch/clone, another .git object store).
  • Worktrees share Git objects, but still behave like separate checkouts.

If you need complete isolation (different remotes, radically different Git config, or you want to move one copy around freely), a second clone can still be the simplest answer.

Keeping Your Directories Sane

The simplest convention (and the one that avoids the “oops, I edited the wrong checkout” mistake) is: keep linked worktrees outside the main project folder.

repo/            # main worktree
repo-hotfix/     # linked worktree
repo-review/     # linked worktree

If you do this often, encode intent in the directory name so it’s searchable later (wt-hotfix-1234, wt-pr-998, wt-bisect-crash) instead of generic tmp/.

If you want all worktrees contained under one parent folder, a popular layout is “bare repo + many worktrees” (see Nick Nisi and Ahmed El Gabri). For background on bare repositories themselves, the Git book chapter is a good reference: Git Basics: Getting a Git Repository.

a conceptual folder layout illustration comparing “sibling worktrees” vs “bare repo + worktrees inside one folder.”

If you try the “bare repo + worktrees” approach, keep the tradeoff in mind: you’re saving Git object duplication, not environment duplication. Two worktrees can still mean two node_modules/ folders, two build outputs, and two IDE indexes. If setup dominates your workflow, keep only the worktrees you’re actively using.

The Lifecycle Gotchas (and the 5 Commands that Prevent Them)

Removing vs Deleting (Stale Metadata)

Deleting a worktree folder in Finder isn’t the same as telling Git it’s gone. Prefer:

git worktree remove ../wt-review

If you already deleted the folder, clean up the leftover admin state:

git worktree prune

Git can also garbage-collect stale worktree metadata automatically over time (controlled by gc.worktreePruneExpire). That’s helpful, but it’s not a substitute for removing worktrees intentionally when you’re done.

Diagram

“This Branch Is Already Checked Out”

This is Git enforcing “one branch per worktree.” Your usual fixes are:

  • make a new branch name (-b)
  • use detached HEAD (-d)

If you’re debugging “why won’t Git let me…”, list the current attachments:

git worktree list

Moving Worktrees (and Repairing when Paths Change)

If you need to reorganize, prefer Git’s commands over dragging folders around in your file manager.

  • git worktree move <worktree> <new-path> relocates a linked worktree (you can’t move the main worktree).
  • If you moved things manually and links broke, git worktree repair can reestablish the connection in supported cases.

Intermittent Drives: Lock Before Git Prunes

If a worktree lives on an external drive or network mount, Git may treat it as “missing” when the volume isn’t mounted. Use git worktree lock to prevent surprises:

git worktree lock --reason "On external drive" /Volumes/SSD/wt-release

Cheat Sheet

git worktree add ../wt-name -b my-branch   # new worktree + new branch
git worktree add ../wt-name origin/branch  # worktree from remote-tracking branch
git worktree add -d ../wt-scratch          # detached-HEAD scratch worktree
git worktree list                          # see what's attached
git worktree remove ../wt-name             # remove cleanly
git worktree prune                         # cleanup after manual deletion

The Takeaway

Worktrees aren’t a niche add-on. They’re the name for the checkout you already use, plus a way to add more checkouts without cloning again. Keep the mental model in your head—shared history, separate working state—and Git’s guardrails (like one branch per worktree) stop feeling arbitrary and start feeling helpful.

If you learned something from this post, give me a follow and checkout the AI powered markdown editor that i am building on the side.

Swiss Jass: Commandos Edition is Now on the Google Play Store

Swiss Jass: Commandos Edition is now available on the Google Play Store! This mobile card game app brings the classic Swiss card game Jass to your phone, featuring a unique Black Forest Commandos theme.


Swiss Jass: Commandos Edition – Apps on Google Play

Play a mobile-friendly version of Jass with Black Forest Commandos characters.

favicon
play.google.com

The book Docker and Kubernetes Security started with a battle scene between Gord, Rothütle, Jack, and a CVE monster. Those three characters we met again in Black Forest Shadow, with Evie joining them. The events of Black Forest Shadow are set in late 1865, happening over 3 days in the Black Forest. The Commandos are on a mission to stop CVE monsters from spreading chaos across the region.


Black Forest Shadow — A Dark Fantasy Guide to Docker and Kubernetes Security – Docker and Kubernetes Security – Docker and Kubernetes Security

A dark fantasy novel set in the Black Forest of 1865 that teaches Docker and Kubernetes security through narrative — covering CVE hunting, SBOM generation, runtime hardening, and container security.

favicon
dockersecurity.io

Between those events and the Asgard Mission, the characters recruit new members: Mina (aka Wilhelmina), Agent Null, The Valkyrie, and Captain Ahab. The Commandos are now a team of 8, and they are summoned by Thor to go to Asgard and stop the CVE monsters from invading the realm of the gods. During this mission, two new Commandos join them: Artemisia and RuinTan.
Those events are depicted in the workshop series Docker Commandos as well as the upcoming comic book Black Forest Commandos: Asgard Mission.

Characters

Black Forest Commandos

The Black Forest Commandos are a team of 10 characters:

  • Gord: The leader of the Commandos, a skilled strategist and fighter. She wears plate armor and wields a sword glowing blue with the power of the Okterakt, a time-manipulation device.
  • Rothütle: The second-in-command, a master of strategy and tactics. He wears a red fedora and an orange T-shirt, showing that he’s a member of the Red Team.
  • Jack: The wildcard of the group, he started off helping the CVE monsters but later switched sides to join the Commandos. He was a miner in the Black Forest Shadow book, but in the Asgard Mission he’s a cyborg soldier with advanced scouting abilities.
  • Evie: The cowgirl and infiltrator of the Commandos. She wears a brown cowboy hat and a leather jacket, is a skilled sniper and scout.
  • Mina: The pale undead assassin of the Commandos. She had a dispute with Hades, the god of the underworld, and was cursed to be alive. She can’t eat, but gets energy from photosynthesis. She wears black tactical gear and has dark hair.
  • Agent Null: The masked tactical soldier of the Commandos. No one knows anything about him, not even his name. He likes an MP5SD and wears a skull balaclava.
  • The Valkyrie: The blonde guardian of the Commandos. She wears modern tactical armor and has tattooed arms. She’s a fierce fighter and protector of the team.
  • Captain Ahab: The bearded veteran of the Commandos. He’s a naval captain and mostly chauffeurs the team around.
  • Artemisia: An Amazonian warrior who joins the Commandos during the Asgard Mission. She has fought in the Battle of Salamis and was sent to Asgard after she was angered by Zeus for not siding with the Olympians during the battle.
  • RuinTan: The hulking champion of the Commandos. He was honored with immortality by the prophet Zarathustra in 1500 BC, and bears the name RuinTan, literally meaning “bronze-bodied”. He wears heavy golden armor and wields a massive sword.

Gameplay

Swiss Jass: Commandos Edition trump select

Swiss Jass, also known as Schieber Jass, is a popular trick-taking card game in Switzerland. The game is played with a 36-card deck, which is a standard deck with the 2s, 3s, 4s, and 5s removed. The Swiss suits are:

  • Bells (Schellen)
  • Acorns (Eicheln)
  • Roses (Rosen)
  • Shields (Schilten)

In the Commandos Edition, you can use the Commandos suits:

  • Shields
  • Attestations
  • Hardened
  • Signatures

Each suit has 9 cards, ranked from highest to lowest as follows:

Rank (French) Rank (Swiss) Commandos name Points Points in Trump
A = Ace D = Deuce Artemisia 11 11
K = King K = König Gord 4 4
Q = Queen O = Ober Rothütle 3 3
J = Jack U = Under Jack 2 20
10 10 / Banner Agent Null 10 10
9 9 Mina 0 14
8 8 The Valkyrie 0 0
7 7 Captain Ahab 0 0
6 6 RuinTan 0 0

The game is played with four players in two fixed partnerships. The objective is to be the first team to reach 1000 points across multiple rounds. Each round consists of 9 tricks, and players must follow suit if they can. Players can always play a trump card.

Swiss Jass: Commandos Edition table

At the beginning of each round, players can choose a trump suit or play Schieben to pass the decision to their partner. In the trump suit, Jack the Buur (the Jack) is the highest card, followed by Mina the Nell (the 9).

Conclusion

You can download Swiss Jass: Commandos Edition on the Google Play Store here. The app is free to play and has no ads or in-app purchases.

On the website, there is also the Asgard Arcade, a collection of mini-games inspired by the Commandos and the Asgard Mission. You can play an online version of Jass there as well, together with 3 other mini-games:

  • Asgard Siege: Match the right commando to the right CVE monster to defend Asgard.
  • Blackjack: A classic card game where you try to get as close to 21 points as possible without going over.
  • Reference Deck: Simple card-comparison game to learn about each commando’s abilities.


Black Forest Commandos — Narrative-Driven Container Security Workshop – Docker and Kubernetes Security – Docker and Kubernetes Security

A hands-on container security workshop told through the story of 10 commandos fighting CVE monsters in Asgard. Covering SBOMs, attestations, hardened images, VEX, Docker Bake, Cosign, and zero-day defense. (Previously known as Docker Commandos).

favicon
dockersecurity.io

Epoch 2: From Reading to Creating

Abstract teal and green illustration showing simple token-like discs flowing into a larger network of connected digital panels, representing basic assets becoming programmable assets with metadata, permissions, and rules.

Epoch 1 was about learning how Solana works: wallets, accounts, transactions, balances, and on-chain state.

Epoch 2 turns that foundation into something you can build with. You’ll create tokens, add metadata, experiment with fees and transfer rules, mint NFTs, and see how assets can carry behavior of their own.

What “programmable asset” actually means

We first met SOL pretty early in Epoch 1. It is the currency used on Solana to pay fees, fund accounts, and it gave you a clean first lap around transactions and Explorer.

So it would be easy to think of Solana mainly as a network for moving SOL around.

But Solana also lets you create assets whose rules are part of the asset itself: who can create more, who can hold them, whether they can move, whether transfers take a fee, and what metadata other apps can read.

Abstract teal and green illustration showing simple token-like discs flowing into a larger network of connected digital panels, representing basic assets becoming programmable assets with metadata, permissions, and rules.

That might sound like a lot, but the next four weeks of 100 Days of Solana break it down step by step.

If you’ve built Web2 products, you’ve probably worked with things users can earn, hold, spend, unlock, or display: loyalty points, in-app credits, course badges, gaming currencies, access passes, reputation scores.

In a traditional app, those things live in your database. Your backend decides how they are created, who they belong to, whether they can move between users, and what they can be used for.

On Solana, some of those rules can move into the asset itself.

To make that work, Solana splits those ideas across a few building blocks. A mint describes the asset. Token accounts record who holds it. Authorities decide who can create more, freeze accounts, update metadata, or collect fees.

A basic token can answer the first question: who holds how much?

But product ideas usually need more than that. What is this asset called? Can another app recognize it? Can it be transferred? Should transfers take a fee? Should a new holder be approved before they can use it?

Token-2022 is Solana’s token program for that next layer. It adds optional extensions, which are predefined features for metadata, fees, frozen accounts, non-transferability, interest-bearing display amounts, and other asset behaviors.

Some of those rules are configured on the mint. Some are tracked on token accounts. But the important shift is this: the rules are enforced by the token program, not only by your application.

Arc 5: A token and then a name for it

The first arc of Epoch 2 starts with the simplest asset you can create: a token on devnet.

You create the mint. You issue some supply to your own wallet. You open Explorer and there it is: an asset you created, controlled by your wallet, sitting on a public network anyone can inspect.

At first, though, it is still pretty bare.

Abstract teal and green illustration showing a simple token becoming a recognizable asset with metadata, then being blocked from transfer by a lock, representing non-transferable token rules.

A mint address is useful to a program but it does not mean much to a person. It is just a long base58 string. So the next step is metadata: a name, a symbol, and a URI that can point to richer details such as an image and traits.

That is when the token starts to feel less like a raw account and more like something you can work with.

This first arc of Epoch 2 also introduces a more important design choice: should this asset be transferable?

Not every asset should move freely. A certificate of completion, a verified badge, or a reputation score should belong to the person who earned it. In this arc, you will create a non-transferable token and try to send it to another wallet. And you’ll see that the token program refuses the transfer because the rule is part of the asset.

Arc 6: Rules the network enforces for you

Arc 6 is where Token-2022 starts to matter.

You will create an interest-bearing token: a mint with an interest rate in its configuration. The raw balance does not change, but compatible wallets and clients can calculate a display amount that grows over time.

In a Web2 app, that kind of behavior might need timestamps, background jobs, database updates, and careful UI logic. With Token-2022, the rate is part of the token configuration, and compatible clients use it to calculate the displayed balance.

Token-2022 calls these optional features extensions. An extension is a built-in capability you add to a token: metadata, transfer fees, interest-bearing display amounts, frozen accounts, non-transferability, and so on.

In Arc 6, you start combining them.

Abstract teal and green illustration showing a central token connected to modular panels for metadata, fees, interest, frozen accounts, transfer restrictions, and credentials, representing Token-2022 extensions as built-in asset rules.

A token might have metadata, a transfer fee, an interest rate, or other built-in rules. Some extensions can work together; others cannot. That means token design starts to feel a little like schema design: you need to decide what the asset should be able to do before you create it, because some choices are permanent and others are hard to change later.

The arc also introduces default frozen accounts. This means new token accounts start frozen and cannot be used until a freeze authority thaws them.

That gives you a simple version of a gated asset flow. Not every holder is automatically eligible. Someone has to approve the account before it can transact.

Finally, you will combine non-transferable tokens with permanent delegates to model a revocable credential. The holder cannot transfer it to someone else, but a designated authority can still burn it.

That gives you something close to: this credential can be issued and revoked, but it cannot be passed on.

You could model that in a database, but the rule would live inside your application. Here, the rule is part of how the asset works.

Arc 7: NFTs use the same building blocks

Arc 7 moves from fungible tokens into NFTs.

The useful surprise is that NFTs are not a completely separate technical world. At their simplest, they use the same basic ingredients you will have already covered up to that point: a mint, token accounts, metadata, and authority.

The difference is uniqueness.

A normal token is designed so many people can hold units of the same asset. An NFT is designed so there is only one of that asset. One token. One current owner. One piece of metadata that explains what it represents.

You will build the simplest version first: a unique asset on devnet that only your wallet owns. Then you will add the things people expect from an NFT: a name, an image URI, traits, and membership in a collection.

That is where metadata matters again. The NFT stops being just a unique on-chain asset and starts becoming something wallets, explorers, and other apps can present in a recognizable way.

The most satisfying moment in this arc comes when you update it.

You change the metadata on your live devnet NFT, then refresh a compatible wallet or explorer. The image changes. The name changes. The transaction has a signature anyone can audit, and the updated state is visible to compatible tools that read the standard.

You are not just editing a file or changing a row in your own database. You are changing asset state on a public network.

Arc 8: Assets that carry their own behavior

Arc 8 brings the whole epoch together.

You will create a fee-bearing token with a 1% transfer fee. Send 100 tokens to another wallet, and the recipient receives 99. The remaining 1 is withheld automatically according to the rules configured on the token.

That is the important part: your application did not calculate the fee, intercept the transfer, or run a background job. The token program enforced the rule.

Then you will run the rest of the lifecycle. You will inspect the withheld fees, harvest them from token accounts up to the mint, and withdraw them using the withdraw authority.

That gives you the full pattern: transfer, withhold, harvest, withdraw.

From there, the arc pulls together the ideas from the previous weeks. You will stack interest behavior on top of transfer fees. You will audit token mints to understand which rules are configured. You will revisit non-transferable tokens now that you have seen how fees, metadata, frozen accounts, and authorities all fit together.

By this point, Token-2022 should feel less like a list of features and more like a design toolkit.

The point is not that every token should use every extension. Most should not. The point is that you now have a vocabulary for asset behavior: fees, identity, display logic, access control, transfer restrictions, and revocation.

You can design those behaviors without writing a custom Solana program from scratch.

What you’ll walk away with

By the end of Epoch 2, you’ll have a small portfolio of real Solana experiments on devnet.

Custom tokens with metadata. Transfer fees configured and inspected. Interest-bearing display amounts. Frozen accounts thawed by an authority. Non-transferable assets that refuse to move. A 1-of-1 NFT minted, added to a collection, updated, and verified on-chain. A fee-bearing token whose withheld fees you harvested and withdrew yourself.

You’ll also have written about what you built.

And that’s because explaining a concept in your own words is one of the best ways to find out whether you actually understand it.

So, let’s get into it!

Join us on the 100 Days of Solana journey.

Building Hypervisor Infrastructure with Proxmox and Ceph

Author: Rajendra Acharya

Why Proxmox and Ceph?

Proxmox VE is a powerful open-source platform for managing virtual machines and containers. When combined with Ceph, it enables a highly available, scalable, and cost-effective infrastructure.

Key Benefits

  • High Availability (HA): Minimized downtime through automatic failover.
  • Scalability: Seamlessly expand compute and storage resources as needed.
  • Cost-Effectiveness: Open-source, community-driven technologies with enterprise-grade capabilities.

This combination is ideal for enterprises, startups, and home lab enthusiasts looking to build a production-grade hypervisor infrastructure.

Setting Up Proxmox Infrastructure

Step 1: Install Proxmox VE

Download the ISO

Download the latest Proxmox VE ISO from the official website:

Proxmox VE Official Website

Install Proxmox VE

  • Create a bootable USB drive or use PXE boot.
  • Install Proxmox VE on your server hardware.

Initial Configuration

During installation:

  • Configure the hostname.
  • Assign a static IP address.
  • Set the root password.

* Verify management network connectivity.

Step 2: Configure Networking

For production environments, proper network segmentation is highly recommended.

Recommended Network Setup

  • Use bonded interfaces for redundancy and improved reliability.
  • Create separate VLANs for:

    • Management traffic
    • Ceph storage traffic
    • Virtual machine traffic

This separation improves both performance and security.

Setting Up Ceph for Distributed Storage

Step 1: Prepare Proxmox Nodes

Before deploying Ceph:

  1. Ensure you have at least three Proxmox nodes for cluster reliability.
  2. Install additional disks on each node for Ceph OSDs (Object Storage Daemons).

Step 2: Install and Configure Ceph

Enable Ceph

  1. Navigate to:
Datacenter → Ceph
  1. Initialize the Ceph cluster.

Deploy OSDs

Add dedicated disks as OSDs from:

Ceph → OSD

These disks will provide distributed storage capacity for the cluster.

Configure MONs (Monitors)

  • Deploy at least three monitor nodes to maintain quorum and ensure cluster reliability.

Create Ceph Pools

Create storage pools and define redundancy policies such as:

  • Replication
  • Erasure Coding

Pool configuration depends on your performance and redundancy requirements.

Integrating Ceph with Proxmox

Step 1: Add Ceph Storage to Proxmox

  1. Navigate to:
Datacenter → Storage
  1. Add Ceph RBD as a storage backend.
  2. Verify connectivity and pool access.

Step 2: Migrate VM Storage

Move VM disks to the Ceph RBD pool to achieve:

  • Centralized storage
  • Live migration capabilities
  • High availability support

High Availability and Maintenance

Configure HA in Proxmox

To enable high availability:

  • Create HA Groups and define failover priorities.
  • Configure quorum and fencing properly to avoid split-brain scenarios.

Regular Maintenance

Monitor Ceph Cluster Health

Use the following command regularly:

ceph status

Monitor Infrastructure Performance

Use the Proxmox dashboard to:

  • Monitor VM performance
  • Track storage utilization
  • Review cluster health

The Takeaway

Building a hypervisor infrastructure using Proxmox and Ceph provides an excellent balance of flexibility, reliability, and scalability. While the initial setup requires careful planning, the end result is a resilient and enterprise-grade infrastructure powered entirely by open-source technologies.

Whether you’re building a data center platform, private cloud, or advanced home lab, Proxmox and Ceph offer a powerful foundation capable of competing with many commercial solutions.

Related Reading

By understanding and implementing these technologies, you gain hands-on experience with modern infrastructure design while building a platform that delivers enterprise-grade performance and reliability.

Como Precificar Opções em Nível Institucional Usando IA (PINNs) e Python

Se você trabalha ou estuda o mercado de derivativos, sabe que a velocidade e a precisão no cálculo do preço de opções não são apenas metas técnicas — são diferenciais competitivos.

Tradicionalmente, dependemos do modelo de Black-Scholes ou de simulações de Monte Carlo estruturadas em código legado para aproximar o preço justo de um contrato. No entanto, quando precisamos escalar esses cálculos para milhares de requisições simultâneas ou tratar condições de contorno complexas, os gargalos de processamento aparecem.

É aqui que entra a fusão entre Inteligência Artificial e Física Financeira: as PINNs (Physics-Informed Neural Networks).

Neste artigo, vou te mostrar como consumir uma infraestrutura de nível institucional baseada em redes neurais informadas por física para precificar opções em milissegundos usando Python.

O que são PINNs e por que elas importam nas finanças?Diferente das redes neurais tradicionais que precisam de bilhões de dados históricos para “aprender” uma tendência (e que frequentemente falham ao tentar extrapolar), as PINNs integram leis matemáticas diretamente em sua função de perda (loss function).No nosso contexto, a rede é treinada respeitando a famosa Equação Diferencial Parcial (EDP) de Black-Scholes:

forçar o modelo de IA a obedecer às restrições da física financeira, eliminamos alucinações matemáticas e conseguimos um poder de inferência absurdamente veloz, ideal para sistemas de alta frequência (HFT) e gerenciamento de risco em tempo real.

Mão na Massa: Consumindo o PINN Master em Python
Para evitar que você tenha que montar, treinar e hospedar um cluster de GPUs para rodar essa rede do zero, vamos utilizar o PINN Master – Institutional Option Pricing, uma API robusta hospedada na AZURE que expõe esse modelo pronto para produção.

O melhor de tudo? Ela possui uma camada 100% gratuita para testes.

Passo 1: Obter suas credenciais
Antes de rodar o script, você só precisa acessar a página oficial do PINN Master no RapidAPI e assinar o plano gratuito para liberar seu token de acesso. Se tiver qualquer dúvida sobre os primeiros passos, há um Tutorial de Inicialização Oficial do PINN Master muito simples de seguir.

Passo 2: O Código
Com a sua chave em mãos, utilize o código abaixo para fazer uma chamada de precificação de uma opção de compra (Call):

import requests

# Endpoint de alta performance da API
url = "https://pinn-master-institutional-option-pricing.p.rapidapi.com/v1/price"

# Parâmetros de precificação do contrato
querystring = {
    "spot": "100.0",        # Preço atual do ativo subjacente
    "strike": "100.0",      # Preço de exercício da opção
    "volatility": "0.20",   # Volatilidade implícita (20%)
    "rate": "0.05",         # Taxa de juros livre de risco (5%)
    "maturity": "1.0",      # Tempo até o vencimento (1 ano)
    "type": "call"          # Tipo do contrato: call ou put
}

headers = {
    "X-RapidAPI-Key": "SUA_CHAVE_GRATUITA_AQUI",
    "X-RapidAPI-Host": "pinn-master-institutional-option-pricing.p.rapidapi.com"
}

try:
    response = requests.get(url, headers=headers, params=querystring)
    response.raise_for_status()

    dados_precificacao = response.json()
    print("--- Resultado da Invocação PINN Master ---")
    print(dados_precificacao)

except requests.exceptions.RequestException as e:
    print(f"Erro ao conectar com a infraestrutura quant: {e}")

Por que essa abordagem muda o jogo?
Latência Previsível: Ao transferir a complexidade do cálculo matemático para uma inferência de rede neural otimizada na nuvem, você ganha tempo de resposta homogêneo.

Abstração de Infraestrutura: Toda a arquitetura de escalabilidade na AZURE fica oculta atrás de um método GET limpo.

Fácil Integração: Você pode plugar esse retorno diretamente em dashboards de trading, planilhas dinâmicas ou bots de execução de ordens.