
PostgreSQL centric – Planetary Architecture

Product Requirements Document

PostgreSQL is not the persistence layer. It is the application. Everything else is orbit.

1. Vision

Modern web stacks treat the database as a dumb filing cabinet at the end of a long chain — request → router → controller → service → ORM → DB. Business logic is smeared across every layer. Security is enforced in the app. Permissions live in middleware. Mutations go through serializers. The database just executes INSERT and stays quiet.

Planetary Architecture inverts this.

PostgreSQL is the sun. Every other component — the admin dashboard, the HTTP adapter, the frontend, the external services — orbits it. Business logic, authorization, validation, transformation, and auditing all live inside Postgres. Downstream layers are deliberately dumb: they render, they route, they receive webhooks. They do not own logic.

The platform — django-pg-planetary — is the control plane that makes this architecture operable without writing a single line of SQL. It extends Django admin into a full database operations dashboard, serving every persona involved in building and running a Planetary stack.

2. The Stack

┌─────────────────────────────────────────────────────────────┐
│                      CONTROL PLANE                          │
│         django-pg-planetary (Django Admin Extension)        │
│         Karen · Bob · Senior Dev — one unified dashboard    │
└──────────────────────────┬──────────────────────────────────┘
                           │  DDL only · metadata only
                           │  never raw table data
┌──────────────────────────▼──────────────────────────────────┐
│                   ☀️  POSTGRESQL (the app)                   │
│                                                             │
│  raw tables      — superadmin only, REVOKE ALL on everyone  │
│  views           — DTOs, redacted, role-scoped              │
│  INSTEAD OF      — the only way CUD ever happens            │
│  functions       — business logic, overloaded by signature  │
│  RLS policies    — authorization at the row level           │
│  triggers        — mutations, audits, notifications         │
│  types/domains   — validated, reusable data shapes          │
│  FDW             — forensic audit to separate DB            │
│  pg_notify       — async event emission                     │
└────────┬────────────────────────────────────────────────────┘
         │                              │
         │ pg_notify / pg_net           │ SQL over HTTP
         │                  ┌───────────▼──────────┐
         │                  │       PostgREST       │
         │                  │   dumb HTTP adapter   │
         │                  │   exposes views +     │
         │                  │   functions as REST   │
         │                  └───────────┬──────────┘
         │                              │ REST + JWT
         │                  ┌───────────▼──────────┐
         │                  │     Next.js BFF       │
         │                  │  renders · consumes   │
         │                  │  zero business logic  │
         │                  └───────────┬──────────┘
         │                              │
┌────────▼──────────────────────────────▼──────────────────────┐
│                   SERVICES (dumb, isolated)                   │
│     pdf-export · email · payment · sms · storage · etc.      │
│     receive payload · do one thing · return result           │
│     know nothing about the DB schema                         │
└──────────────────────────────────────────────────────────────┘
         │
┌────────▼──────────────────────────────────────────────────────┐
│                    AUDIT DB (FDW shadow)                       │
│     separate server · append-only · forensic isolation        │
│     full before/after JSON trail per row per operation        │
└────────────────────────────────────────────────────────────────┘

3. Personas

Karen — Business Operations

Uses Django admin to browse and manage data rows. Her experience is unchanged from standard Django admin. She interacts with views only — never raw tables. RLS ensures she sees exactly what her role allows, automatically.

Bob — DevOps / DB Administrator

Uses the planetary extension to manage the full Postgres security and infrastructure layer. Zero SQL written. He manages roles, grants, policies, table health, scheduled jobs, replication, and configuration through GUI forms that generate and execute SQL behind the scenes.

Senior Developer

Uses the extension to design and apply the Postgres application layer. Writes function bodies, designs view schemas, declares protected tables, manages types, configures FTS, and controls the audit setup. The platform scaffolds everything; Senior fills in the business logic.

PostgREST (system actor)

Watches Postgres. Exposes whatever views and functions exist as REST endpoints, scoped by JWT role claims. Picks up every change Senior makes automatically. No configuration required per new view or function.

Next.js BFF (system actor)

Consumes PostgREST endpoints. Renders data. Calls service endpoints for non-DB operations. Has no knowledge of the underlying schema, RLS rules, or function signatures.

4. Core Principles

4.1 The Protected Table Contract

Every raw table in a Planetary stack follows this contract:

  1. REVOKE ALL ON raw_table FROM PUBLIC — no one touches data directly
  2. REVOKE ALL ON raw_table FROM app_role — includes the Django DB user
  3. One or more views declared as the only access points
  4. INSTEAD OF triggers on each view — the only mutation path
  5. Overloaded functions per operation type — validation and transformation
  6. RLS on views — row-level authorization per role/claim

The platform scaffolds steps 1–6 from a single “Protect this table” action. Senior fills in function bodies. Everything else is generated.

4.2 Views as DTOs

A view is not a convenience — it is an explicit API contract. One raw table can have many views:

invoice_raw          ← locked, superadmin only
  invoice_v          ← standard ops view, status + amounts
  invoice_v_finance  ← finance role, full breakdown
  invoice_v_redacted ← public-facing, PII masked
  invoice_v_audit    ← compliance, all fields + metadata

PostgREST exposes each view as a separate endpoint. RLS on each view enforces who can query what. No app-layer serializers needed.

4.3 Metadata ≠ Data Privileges

Revoking data access from the Django DB user does NOT revoke metadata access. The platform can fully introspect any table’s columns, types, constraints, indexes, policies, and triggers via pg_catalog and information_schema — without ever reading a row of actual data. This is the foundation of the view builder, policy editor, and trigger scaffolder.

4.4 Functions as the Business Logic Layer

Postgres functions are:

  • Overloadable by signature — process_invoice(a) and process_invoice(a, b) coexist
  • Transactional — they run inside the trigger’s transaction
  • Testable — callable directly via PostgREST or SELECT
  • Replaceable — CREATE OR REPLACE with no downtime

All validation, transformation, computed fields, and side-effect orchestration live in functions. The app layer calls views. It never implements business logic.

4.5 FDW Forensic Audit

Audit triggers write to a foreign table backed by a separate database server via postgres_fdw. The audit DB is:

  • On a different host (optionally different provider)
  • Append-only by policy — no UPDATE, no DELETE
  • Invisible to application roles
  • Full row_to_json(OLD) / row_to_json(NEW) per operation

If the main DB is compromised, wiped, or ransomwared — the audit trail is untouched on a completely separate server. The platform wires this up per table with a toggle.

5. Platform Features

5.1 Introspection Engine

The foundation. Pure pg_catalog + information_schema queries. Returns structured metadata the UI builds on. No data access required.

  • Tables, columns, data types, nullability, defaults
  • Constraints — PK, FK, unique, check, exclusion
  • Indexes — type, columns, partial condition, expression
  • Views + materialized views — definition, dependencies
  • Stored functions + procedures — signature, language, body, security
  • Triggers — timing, event, level, condition, function
  • Policies — command, roles, USING, WITH CHECK expressions
  • Roles + grants — membership, table/column/schema privileges
  • Extensions — installed, available, version
  • FDW servers + foreign tables
  • Publications + subscriptions
  • Table health — live tuples, dead tuples, bloat, last vacuum/analyze

5.2 Protected Table Manager (Senior + Bob)

The core workflow of the platform.

Declare a table as protected:

  • Select table from introspected list
  • Platform generates REVOKE statements for all non-superadmin roles
  • Column picker: drag-drop columns into one or more named views
  • Per-column: include / exclude / apply redaction function
  • Platform generates CREATE VIEW for each declared view
  • INSTEAD OF trigger skeleton auto-generated per view
  • Senior writes function body in inline editor
  • One-click apply — REVOKE + views + triggers executed in single transaction

View builder:

  • Visual column selector from introspected schema
  • Redaction function picker (mask_pan, mask_email, hash, nullify, etc.)
  • Live SQL preview
  • Role assignment — which PostgREST role sees this view
  • RLS policy generator — column picker for USING expression

5.3 Policy Manager — RLS / RBAC / ABAC / PBAC (Bob + Senior)

RLS Policies:

  • Enable/disable RLS per table/view — toggle
  • Create policy: name, table, command (ALL/SELECT/INSERT/UPDATE/DELETE)
  • USING expression builder — column picker + operator + value/function
  • WITH CHECK expression builder
  • PERMISSIVE vs RESTRICTIVE toggle
  • Role assignment
  • Live SQL preview
  • Active policies list with enable/disable per policy

Role Management (RBAC):

  • Create / rename / drop roles
  • Role membership — assign roles to roles (hierarchy)
  • Grant / revoke table privileges per role
  • Grant / revoke column-level privileges
  • Grant / revoke schema privileges
  • Grant / revoke function execute privileges
  • Role matrix view — roles × tables × privileges grid

Session Claims (ABAC):

  • Define current_setting('app.x') claim variables used in policies
  • JWT claim → set_config mapping documentation per role
  • Policy expression helpers using claim variables

Policy Templates (PBAC):

  • User-owns-row: user_id = current_setting('app.user_id')::uuid
  • Tenant isolation: tenant_id = (auth.jwt() ->> 'tenant_id')::uuid
  • Soft-delete filter: deleted_at IS NULL
  • Time-bounded: valid_from <= now() AND valid_to >= now()
  • Save custom templates — reusable across tables

5.4 Function & Trigger Manager (Senior)

Functions:

  • List all stored functions with signature, language, security mode
  • Create / edit function — inline code editor with syntax highlighting
  • Language picker — plpgsql, sql, python (plpython3u)
  • SECURITY INVOKER vs SECURITY DEFINER toggle
  • Parameter builder — name, type, default, mode (IN/OUT/INOUT)
  • Return type picker — scalar, setof, table, trigger, void
  • Function overload group view — all signatures for same name
  • Test runner — call function with sample args, see output

Triggers:

  • List all triggers per table with status
  • Create trigger: timing (BEFORE/AFTER/INSTEAD OF), event (INSERT/UPDATE/DELETE/TRUNCATE)
  • Column-specific UPDATE trigger (OF col1, col2)
  • FOR EACH ROW vs FOR EACH STATEMENT toggle
  • WHEN condition builder
  • Function picker from existing trigger functions
  • Enable / disable per trigger
  • Deferrable + deferred toggle

Event Triggers (DDL-level):

  • Fire on CREATE TABLE, ALTER TABLE, DROP, etc.
  • Auto-attach audit triggers to any new table — set-and-forget for Bob
  • Enforce naming conventions on DDL operations

5.5 Schema Object Manager (Senior + Bob)

Views:

  • List all views with definition preview
  • Create / edit view — column picker + SQL editor
  • Dependency graph — which tables/functions a view uses
  • Drop cascade safety — shows what breaks before executing

Materialized Views:

  • Create materialized view from view or raw SQL
  • Refresh strategy — manual / pg_cron scheduled
  • Refresh schedule builder (cron expression)
  • Index management on materialized view columns
  • Concurrent refresh toggle

Custom Types:

  • ENUM types — create, add values, rename, drop
  • Composite types — field builder with name + type
  • Domain types — base type + CHECK constraint
  • Range types — subtype + canonical function

Extensions:

  • Available extensions list with description
  • Install / drop per extension
  • Version display
  • Commonly useful: uuid-ossp, pgcrypto, pg_stat_statements, pg_cron, pg_net, postgres_fdw, postgis, unaccent, btree_gin

Sequences:

  • List, create, alter (start, increment, min, max, cycle)
  • Current value display
  • Owned-by column display

Schemas:

  • Create / drop schemas
  • search_path configuration per role
  • Move tables between schemas

5.6 Index Manager (Bob + Senior)

  • List all indexes — type, columns, size, usage stats
  • Detect unused indexes via pg_stat_user_indexes (idx_scan = 0)
  • Create index — type picker (B-tree, GIN, GiST, BRIN, Hash)
  • Partial index — WHERE clause builder
  • Expression index — expression input with column picker
  • Concurrent build toggle (non-blocking)
  • Index size vs query benefit display

5.7 Full Text Search (Senior)

  • Text search configuration manager
  • Dictionary management
  • tsvector column setup — which columns, which config
  • to_tsvector expression builder
  • GIN index auto-suggestion on tsvector columns
  • Test query — enter search terms, preview ranked results

5.8 Audit Layer (Bob)

  • Enable audit per table — toggle
  • FDW server configuration — host, dbname, credentials
  • Foreign table auto-creation on audit DB
  • Audit trigger auto-generated and attached
  • Audit log viewer (reads from foreign table — read-only)
  • Audit DB health status
  • Retention policy — pg_cron job to prune old audit records (on audit DB side)

5.9 Replication & CDC (Bob)

  • Publications — create, add/remove tables, manage row filters
  • Subscriptions — create, monitor lag, enable/disable
  • Logical replication slot monitoring
  • FDW connections — list, test, drop

5.10 Scheduled Jobs — pg_cron (Bob)

  • List all cron jobs with schedule, last run, status
  • Create job — SQL input + cron expression builder
  • Enable / disable per job
  • Run now (immediate one-off execution)
  • Job run history + error log

5.11 Notifications — pg_notify / pg_net (Senior)

  • NOTIFY channels in use — list active LISTEN connections
  • pg_net webhook trigger builder — target URL, payload template
  • Outbound webhook log (via net._http_response)

5.12 Performance & Health (Bob)

  • Table stats — live tuples, dead tuples, bloat %, last vacuum/analyze
  • pg_stat_statements — top queries by total time, calls, mean time
  • Cache hit ratio — buffer hits vs disk reads
  • Connection stats — active, idle, idle-in-transaction, by role
  • Lock monitor — active locks, blocking queries, wait graph
  • VACUUM / ANALYZE — trigger manually per table or ALL
  • Autovacuum settings — per-table overrides (fillfactor, thresholds)
  • Table size breakdown — table + indexes + toast

5.13 Configuration (Bob)

  • ALTER SYSTEM GUI — categorized parameter list
  • Search params by name or description
  • Current vs pending (requires reload) indicator
  • pg_reload_conf() trigger button
  • Per-database and per-role parameter overrides via ALTER DATABASE SET / ALTER ROLE SET

5.14 PostgREST Integration

  • View → PostgREST endpoint mapping display
  • Function → RPC endpoint display (/rpc/function_name)
  • JWT role claim → Postgres role mapping documentation
  • Schema cache reload trigger (NOTIFY pgrst, 'reload schema')
  • Endpoint health check per view

6. Non-Goals

  • Not a data browser. Django admin owns rows and data management. This platform does not display table contents except for the audit log viewer.
  • Not a query editor. Not a replacement for psql, DBeaver, or TablePlus. Senior who needs raw SQL uses those tools.
  • Not an ORM. No model abstraction. Everything is native Postgres SQL, generated and executed directly.
  • Not a migration framework. No Alembic/django-migrate style versioned migrations. DDL changes are applied directly. Event triggers handle DDL auditing.
  • Not a connection pooler. PgBouncer / Supavisor are separate infrastructure concerns.

7. Privilege Architecture

superadmin         → everything. raw tables, DDL, pg_catalog, config
senior_dev role    → DDL via platform, metadata, no raw table data
bob_devops role    → platform UI operations, metadata, health stats
django_app role    → metadata on raw tables, data on views only
postgrest role     → data on views, scoped by JWT sub-role
karen role         → rows in views, filtered by RLS
audit_writer role  → INSERT only on foreign audit tables

The platform authenticates as django_app for introspection. DDL operations are executed via a separate platform_ddl role with elevated privileges, scoped to specific operations, never exposed to the HTTP layer.

8. Package Design

django-pg-planetary/
├── planetary/
│   ├── apps.py                  ← PlanetaryConfig, auto-registers admin
│   ├── introspect/
│   │   ├── tables.py            ← columns, types, constraints
│   │   ├── policies.py          ← pg_policies queries
│   │   ├── roles.py             ← pg_roles, memberships, grants
│   │   ├── routines.py          ← functions, triggers, event triggers
│   │   ├── objects.py           ← views, matviews, types, sequences
│   │   ├── indexes.py           ← index stats, usage
│   │   ├── health.py            ← pg_stat_*, vacuum, bloat
│   │   └── replication.py       ← publications, subscriptions, slots
│   ├── builders/
│   │   ├── policy_builder.py    ← CREATE/ALTER/DROP POLICY → SQL
│   │   ├── role_builder.py      ← GRANT/REVOKE/CREATE ROLE → SQL
│   │   ├── trigger_builder.py   ← CREATE/DROP TRIGGER → SQL
│   │   ├── view_builder.py      ← CREATE VIEW / INSTEAD OF → SQL
│   │   ├── function_builder.py  ← CREATE OR REPLACE FUNCTION → SQL
│   │   └── audit_builder.py     ← FDW setup, audit trigger → SQL
│   ├── executor.py              ← safe DDL execution, transaction wrapper
│   ├── admin/
│   │   ├── policy_admin.py
│   │   ├── role_admin.py
│   │   ├── schema_admin.py
│   │   ├── trigger_admin.py
│   │   ├── function_admin.py
│   │   ├── health_admin.py
│   │   ├── audit_admin.py
│   │   └── cron_admin.py
│   ├── templates/
│   │   └── admin/planetary/     ← per-view HTML templates
│   └── static/
│       └── planetary/           ← JS for live SQL preview, editors
└── setup.py

Installation:

# settings.py
INSTALLED_APPS = [
    'django.contrib.admin',
    'planetary',               # adds Planetary section to admin
    ...
]

PLANETARY = {
    'DDL_ROLE': 'platform_ddl',          # elevated role for DDL ops
    'AUDIT_SERVER': 'audit_db_server',   # FDW server name for audit
    'POSTGREST_URL': 'http://localhost:3000',
}

9. The Paradigm in One Sentence

Karen checks the data. Bob secures the database. Senior encodes the rules. Postgres enforces everything. PostgREST exposes it. Next.js renders it. Services handle the side effects. Nobody writes middleware.
Microsoft, Copilot tuşunun özelleştirilmesine imkan tanıyacak

Copilot

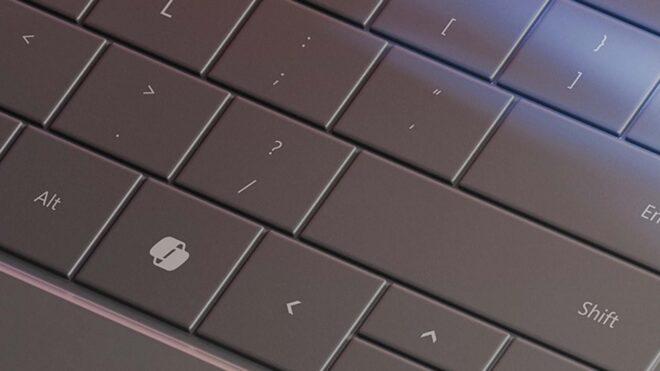
CopilotMicrosoft, bugün yapılan resmi paylaşıma göre çok sayıda yeni nesil dizüstü bilgisayar modeline konulan Copilot tuşunun özelleştirilmesine imkan tanıyacak. Yıl sonunda Windows 11 işletim sistemi için gönderilecek güncelleme sayesinde kullanıcılar, şu anda yapay zeka sistemini devreye sokan Copilot tuşunu “sağ ctrl tuşu” ya da “bağlam menüsü tuşu” olarak atayabilecek. Çoğu kullanmadığı ve geldiğin ilk günden bu yana eleştirdiği buton, yıl sonunda gerçekten işlevsel hale getirilecek.
Microsoft, Copilot tuşunun özelleştirilmesine imkan tanıyacak yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Ford, Avrupa pazarı için önemli duyurular gerçekleştirdi

Ford

FordFord bugün büyük önem verdiği Avrupa pazarı için önemli duyurular gerçekleştirdi. “Ford Avrupa’da Atağa Kalkıyor” diyen şirket, 2029 sonuna kadar Avrupa’da, Avrupa için üretilen tamamen yeni beş binek araç lanse edeceğini aktardı: “Global Bronco ailesinin yeni üyesi Avrupa’ya geliyor: Global Bronco ailesinin bu yeni “multi energy” üyesi, güçlü karaktere sahip kompakt bir SUV olacak. Model 2028’den itibaren Ford’un İspanya Valencia’daki fabrikasında üretilecek. · Elektrikli Hatchback: Bu yeni küçük elektrikli araç, özgün tasarımı Ford’un imza niteliğindeki sürüş dinamikleriyle birleştirerek “yarıştan yola” uzanan kabiliyetleri B segmentine taşıyacak. · Küçük Elektrikli SUV: Ralli mirasından gelen tasarım dilini ve sürüş dinamiklerini şehir kullanımına uygun bir paket içinde sunan dinamik, tamamen elektrikli küçük SUV. · İki Multi Energy Enerji Crossover: Ralli ruhu taşıyan iki yeni crossover modeli, 2029 sonuna kadar yeni ürün gamına katılacak.” Şirket ayrıca şunlara değindi: “Ford’un özellikle Avrupa’nın kendi yarış formatı olan ralli dünyasında bir asrı aşan yarış mirası bulunuyor. Ford, bu […]
Ford, Avrupa pazarı için önemli duyurular gerçekleştirdi yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

ABB ve Yüce Auto-Škoda, Mobil Hızlı Şarj Çözümü alanında iş birliğine imza attı

ABB ve Yüce Auto-Škoda, Mobil Hızlı Şarj Çözümü alanında önemli bir iş birliğine imza attı

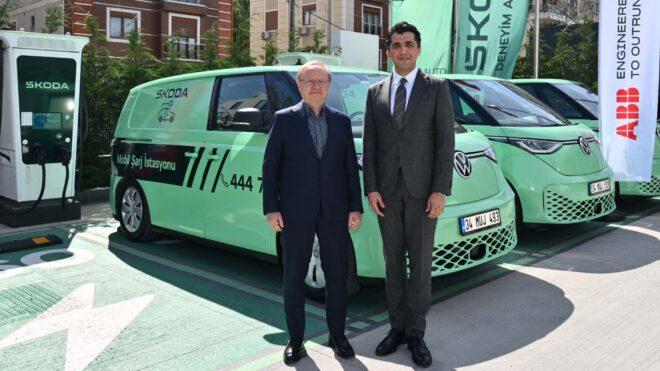
ABB ve Yüce Auto-Škoda, Mobil Hızlı Şarj Çözümü alanında önemli bir iş birliğine imza attıABB ve Yüce Auto-Škoda, bugün ortak açıklamalarıyla Mobil Hızlı Şarj Çözümü alanında önemli bir iş birliğine imza attıklarını duyurdu. Bu konuda yapılan resmi paylaşımda, “Türkiye’de elektrikli araç perakende sektörünün öncü firmalarından Yüce Auto-Škoda, yolda kalan Elektrikli araç sahiplerine hizmet vermek amacıyla İsviçre merkezli otomasyon ve elektrifikasyon teknolojileri lideri ABB ile bir iş birliği gerçekleştirdi. Şarj istasyonlarındaki hizmeti kullanıcıların olduğu yere kadar götürerek zamandan tasarruf etmelerini sağlamak ve elektrikli araçların menzil kaygılarını tüketicilerin satın alma kararını engelleyen bir faktör olmaktan çıkartmak amacı ile ABB ortaklığında mobil DC hızlı şarj çözümleri üretilmeye başlandı. ABB ürünleri ile gerçekleşen bu projede kullanılan invertörlerin kompakt boyutu, darbelere ve titreşimlere dayanıklılığı önem kazanıyor. Yüce Auto-Škoda’nın mobil şarj çözümleri kapsamında van gövdeli ticari araçlar, her marka ve model elektrikli araçlar için hızlı şarj istasyonlarına dönüştürülüyor. Potansiyel elektrikli araç alıcıları ve mevcut elektrikli araç kullanıcıları için en önemli beklenti haline gelen menzil kaygısı ve hizmet kesintisini ortadan kaldırmak […]

ABB ve Yüce Auto-Škoda, Mobil Hızlı Şarj Çözümü alanında iş birliğine imza attı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Prisma Server Actions in Next.js 16: the patterns that work and the N+1 that sneaks up on you

Prisma Server Actions in Next.js 16: the patterns that work and the N+1 that sneaks up on you

Next.js 16 shipped recently with App Router improvements and Server Actions stabilized as a first-class primitive. The community is adopting Server Actions as the natural replacement for API routes on mutations. The migration looks obvious — less boilerplate, co-location with the component, shared types between client and server. I started moving in that direction too. And somewhere along the way I ran into an N+1 that didn’t come from Prisma: it came from how I was composing the Actions.

My thesis is this: Prisma ORM 5 doesn’t introduce N+1 in Server Actions. Action composition does — the pattern of calling multiple independent Actions from the same component, or chaining them without collapsing the queries. It’s an architecture problem, not an ORM problem. And it has a solution, but you have to know where to look.

Classic N+1 vs. composition N+1 in Server Actions

The classic N+1 with Prisma is well-known: you iterate over a list and fire a separate query for each item because you forgot the include. The official Prisma docs on query optimization cover it precisely — use include or select with nested relations, or for more complex cases, findMany with relational filters instead of queries in a loop.

The composition N+1 in Server Actions is different. It doesn’t show up inside the body of a single Action — it shows up when the component calls multiple Actions in sequence or in parallel, and each Action opens its own connection with its own Prisma cursor. Under SSR load, that becomes connection pool pressure that never appears in local tests.

Look at this problematic pattern:

// app/dashboard/page.tsx
// ⚠️ Problematic pattern: three independent Actions
// each one opens its own connection to the pool

import { getUserProfile } from "@/actions/user"
import { getRecentOrders } from "@/actions/orders"
import { getNotifications } from "@/actions/notifications"

export default async function DashboardPage() {
  // Three separate round-trips, three pool connections
  const profile = await getUserProfile()
  const orders = await getRecentOrders()
  const notifications = await getNotifications()

  return <Dashboard profile={profile} orders={orders} notifications={notifications} />
}

Each of those Actions has its own prisma.user.findUnique, its own prisma.order.findMany, its own prisma.notification.findMany. Three queries that could be resolved with a single well-designed call — or at minimum with Promise.all to parallelize them.

The connection pool under SSR load

Prisma uses an internal connection pool. In Next.js App Router with SSR, each request can fire multiple Server Actions in the same render. If every component on the page calls its own Action, the pool receives a short but intense burst of connections per user visit.

The most common pattern that generates this problem is using prisma as a global singleton alongside PrismaClient instantiated in each separate module. Prisma’s documentation explicitly recommends using a singleton instance in serverless and SSR environments:

// lib/prisma.ts
// Singleton pattern recommended by Prisma for Next.js
// Source: https://www.prisma.io/docs/orm/prisma-client/queries/query-optimization-performance

import { PrismaClient } from "@prisma/client"

const globalForPrisma = globalThis as unknown as {
  prisma: PrismaClient | undefined
}

export const prisma =
  globalForPrisma.prisma ??
  new PrismaClient({
    log: process.env.NODE_ENV === "development" ? ["query", "warn", "error"] : ["error"],
  })

if (process.env.NODE_ENV !== "production") globalForPrisma.prisma = prisma

If you skip this pattern, every hot reload in development — and potentially every cold start in production with some providers — can instantiate a fresh PrismaClient with its own pool. The result: exhausted connections with no obvious warning in the logs.

The patterns that work: collapsing queries into a single Action

The antidote to the composition N+1 is simple to state but requires discipline: one Action per use case, not one Action per entity. Instead of three independent Actions for the dashboard, one single Action that groups the three queries with Promise.all:

// actions/dashboard.ts
// ✅ Correct pattern: one Action that collapses the queries
// Promise.all for real parallelism within the same connection

"use server"

import { prisma } from "@/lib/prisma"
import { auth } from "@/lib/auth"

export async function getDashboardData() {
  const session = await auth()
  if (!session?.user?.id) throw new Error("Not authenticated")

  const userId = session.user.id

  // Single pool invocation — three queries in parallel
  const [profile, orders, notifications] = await Promise.all([
    prisma.user.findUnique({
      where: { id: userId },
      select: { name: true, email: true, avatarUrl: true },
    }),
    prisma.order.findMany({
      where: { userId, createdAt: { gte: new Date(Date.now() - 30 * 24 * 60 * 60 * 1000) } },
      orderBy: { createdAt: "desc" },
      take: 10,
    }),
    prisma.notification.findMany({
      where: { userId, read: false },
      orderBy: { createdAt: "desc" },
      take: 5,
    }),
  ])

  return { profile, orders, notifications }
}

The difference isn’t just about queries — it’s about design. An Action that groups data for a specific use case is easier to cache, easier to test, and more honest about what problem it’s actually solving.

The forgotten include and the query that multiplied

The classic N+1 still lives inside Actions. If you iterate over results and fire a nested query per item, Prisma isn’t going to save you — that’s on you. The most frequent pattern I see in codebases just starting with Server Actions:

// ⚠️ Classic N+1 inside an Action
// One query per order to fetch the product

"use server"

import { prisma } from "@/lib/prisma"

export async function getOrdersWithProducts(userId: string) {
  const orders = await prisma.order.findMany({ where: { userId } })

  // ❌ N+1: one query per order
  const ordersWithProduct = await Promise.all(
    orders.map(async (order) => {
      const product = await prisma.product.findUnique({
        where: { id: order.productId },
      })
      return { ...order, product }
    })
  )

  return ordersWithProduct
}

The correct fix is to collapse with include:

// ✅ Correct include: a single query with implicit JOIN
// Prisma collapses everything into a single round-trip

"use server"

import { prisma } from "@/lib/prisma"

export async function getOrdersWithProducts(userId: string) {
  return prisma.order.findMany({
    where: { userId },
    include: {
      product: {
        select: { name: true, price: true, imageUrl: true },
      },
    },
    orderBy: { createdAt: "desc" },
    take: 20,
  })
}

The select inside the include matters: you’re not pulling the full product object, you’re pulling exactly the fields the component needs. That reduces the serialized payload Next.js has to transfer between server and client.

Real gotchas: what the 15-minute tutorial doesn’t cover

"use server" doesn’t guarantee automatic serialization of Prisma errors. If an Action throws a PrismaClientKnownRequestError (say, a constraint violation), that error doesn’t reach the client the way you’d expect in all cases. You need to wrap with try/catch and serialize the error explicitly:

// actions/user.ts
// Explicit Prisma error handling in Server Actions

"use server"

import { prisma } from "@/lib/prisma"
import { Prisma } from "@prisma/client"

export async function createUser(data: { email: string; name: string }) {
  try {
    return await prisma.user.create({ data })
  } catch (error) {
    // Unique constraint violation (P2002 in Prisma)
    if (error instanceof Prisma.PrismaClientKnownRequestError) {
      if (error.code === "P2002") {
        return { error: "That email is already registered" }
      }
    }
    // Unexpected error: log it, don't expose it
    console.error("[createUser]", error)
    return { error: "Internal error. Please try again." }
  }
}

Query logging in development is your best diagnostic tool. The singleton above already includes log: ["query"] in development — that lets you see exactly how many queries each render fires. If you see the same SELECT repeated N times in the terminal, you have an N+1 and you can attack it before it hits production.

Server Actions and React 19 useOptimistic can mask the problem. If you use useOptimistic to update the UI before the Action resolves, perceived latency drops — but the queries are still there. Don’t confuse improved UX with optimized queries.

This connects to something I already documented when looking at how OpenTelemetry in Spring Boot reveals the real problem when the log says OK: observability surface matters. In Next.js 16, if you don’t have query traces, the Action log can look healthy while queries multiply underneath.

FAQ: Prisma Server Actions Next.js 16 N+1

Why does N+1 appear in Server Actions when it didn’t in my API routes?
In API routes, the natural pattern was one route = one handler = one query. In Server Actions, co-location with the component invites you to create one Action per entity, and components end up calling several Actions in the same render. That composition generates multiple round-trips that never existed in an API route because the query was centralized.

Does Prisma ORM 5 have any mechanism to automatically detect N+1?
Not automatically at runtime, but you can enable query logging (log: ["query"]) to see them in development. There are community proposals for a native N+1 detector, but as of this post it’s not a stable feature. The official optimization docs document the patterns to avoid, but detection is still manual or via external tooling.

How many PrismaClient instances should I have in a Next.js 16 project?
One. Using the singleton pattern with globalThis. More than one instance means more than one connection pool, which under SSR load can exhaust available database connections. This is especially critical on serverless providers where each function can have its own process.

Is Promise.all inside an Action enough to fix the pool problem?
For multiple independent queries inside a single Action, yes: Promise.all parallelizes them within the same invocation and the pool handles a single connection (or the minimum needed). What Promise.all does not fix is when you have multiple independent Actions fired from different components in the same render — that needs consolidation at the architecture level.

How does this affect Next.js 16 caching?
Next.js 16 has Data Cache and Full Route Cache. If you use fetch or unstable_cache, you can cache the result of a Server Action. But the N+1 happens before the cache — if the Action isn’t cached (mutations, data with no-store), every request executes the queries. The right pattern is to cache the entire Action with unstable_cache when the data allows it, not to cache individual queries inside it.

Does this pattern also apply to Prisma with pure Server Components (no Actions)?
Yes, but with a difference: in Server Components without Actions, queries live directly in the component and Next.js can do component-level caching more easily. The composition problem is more acute with Server Actions because the mental model of “one Action = one button or form” leads to excessive granularity that multiplies round-trips.

What I’m keeping and what I’m not buying

I’m keeping this pattern: one Action per use case, not one Action per entity. That’s the most important mindset shift when migrating from API routes to Server Actions with Prisma.

What I’m not buying is the narrative that Server Actions automatically simplify the data model. They simplify the boilerplate — shared types, no explicit endpoint — but the responsibility to not multiply queries is still yours. If you were coming from API routes where one route = one well-considered query, jumping to Actions can lead to query sprawl that’s actually worse.

The honest trade-off: Server Actions win on DX and co-location. They lose on visibility into which queries fire per render if you don’t have logging active. Before deploying any page with multiple Actions, pull up the dev terminal with log: ["query"] running and count how many SELECTs appear per render. If the number surprises you, you have work to do.

This connects directly to what I documented in Prisma vs JDBC: the benchmark that almost made me blame the wrong ORM — the ORM is rarely the problem. Query shape is. And in Next.js 16 with Server Actions, shape is defined by the Action architecture, not by Prisma.

For those coming from the Spring Boot world, there’s an interesting parallel with retry budget and amplification: every abstraction that looks like a simplification introduces its own amplification vector. In Server Actions, that vector is granular query composition.

Sources:

This article was originally published on juanchi.dev

Prisma Server Actions en Next.js 16: los patrones que funcionan y el N+1 que aparece cuando no lo esperás

Prisma Server Actions en Next.js 16: los patrones que funcionan y el N+1 que aparece cuando no lo esperás

Next.js 16 salió hace poco con mejoras en el App Router y estabilización de Server Actions como primitiva de primera clase. La comunidad está adoptando Server Actions como el reemplazo natural de las API routes para mutaciones. La migración parece obvia — menos boilerplate, co-location con el componente, tipo compartido entre cliente y servidor. Yo también empecé a moverme en esa dirección. Y en algún punto del camino encontré un N+1 que no venía de Prisma: venía de cómo estaba componiendo las Actions.

Mi tesis es esta: Prisma ORM 5 no introduce N+1 en Server Actions. Lo introduce la composición de Server Actions — el patrón de llamar múltiples acciones independientes desde el mismo componente o encadenarlas sin colapsar las queries. Es un problema de arquitectura, no de ORM. Y tiene solución, pero hay que saber dónde mirar.

El N+1 clásico vs el N+1 de composición en Server Actions

En el N+1 clásico con Prisma, el problema es conocido: iterás sobre una lista y por cada ítem hacés una query separada porque olvidaste el include. La documentación oficial de Prisma sobre optimización lo documenta con precisión: la solución es usar include o select con relaciones nested, o en casos más complejos, findMany con filtros relacionales en lugar de queries en loop.

El N+1 de composición en Server Actions es diferente. No aparece en el cuerpo de una sola Action — aparece cuando el componente llama a varias Actions en secuencia o en paralelo, y cada Action abre su propia conexión con su propio cursor de Prisma. Bajo carga de SSR, eso se convierte en una presión sobre el connection pool que no aparece en tests locales.

Mirá este patrón problemático:

// app/dashboard/page.tsx
// ⚠️ Patrón problemático: tres Actions independientes
// cada una abre su propia conexión al pool

import { getUserProfile } from "@/actions/usuario"
import { getRecentOrders } from "@/actions/pedidos"
import { getNotifications } from "@/actions/notificaciones"

export default async function DashboardPage() {
  // Tres round-trips separados, tres conexiones del pool
  const perfil = await getUserProfile()
  const pedidos = await getRecentOrders()
  const notificaciones = await getNotifications()

  return <Dashboard perfil={perfil} pedidos={pedidos} notificaciones={notificaciones} />
}

Cada una de esas Actions tiene su propio prisma.user.findUnique, su propio prisma.order.findMany, su propio prisma.notification.findMany. Tres queries que podrían resolverse con una sola llamada bien diseñada — o al menos con Promise.all para paralelizarlas.

El connection pool bajo carga de SSR

Prisma usa un connection pool interno. En Next.js App Router con SSR, cada request puede disparar múltiples Server Actions en el mismo render. Si cada componente de la página llama su propia Action, el pool recibe una ráfaga corta pero intensa de conexiones por cada visita de usuario.

El patrón más común que genera este problema es el uso de prisma como singleton global junto con el PrismaClient instanciado en cada módulo separado. La documentación de Prisma recomienda explícitamente usar una instancia singleton en entornos serverless y SSR:

// lib/prisma.ts
// Patrón singleton recomendado por Prisma para Next.js
// Fuente: https://www.prisma.io/docs/orm/prisma-client/queries/query-optimization-performance

import { PrismaClient } from "@prisma/client"

const globalForPrisma = globalThis as unknown as {
  prisma: PrismaClient | undefined
}

export const prisma =
  globalForPrisma.prisma ??
  new PrismaClient({
    log: process.env.NODE_ENV === "development" ? ["query", "warn", "error"] : ["error"],
  })

if (process.env.NODE_ENV !== "production") globalForPrisma.prisma = prisma

Si no usás este patrón, cada hot reload en desarrollo — y potencialmente cada cold start en producción con algunos providers — puede instanciar un PrismaClient nuevo con su propio pool. El resultado: conexiones agotadas sin advertencia obvia en los logs.

Los patrones que funcionan: colapsar queries en una sola Action

El antídoto al N+1 de composición es simple de enunciar pero requiere disciplina: una Action por caso de uso, no una Action por entidad. En lugar de tres Actions independientes para el dashboard, una sola Action que agrupa las tres queries con Promise.all:

// actions/dashboard.ts
// ✅ Patrón correcto: una Action que colapsa las queries
// Promise.all para paralelismo real dentro de la misma conexión

"use server"

import { prisma } from "@/lib/prisma"
import { auth } from "@/lib/auth"

export async function getDashboardData() {
  const session = await auth()
  if (!session?.user?.id) throw new Error("No autenticado")

  const userId = session.user.id

  // Una sola invocación al pool — tres queries en paralelo
  const [perfil, pedidos, notificaciones] = await Promise.all([
    prisma.user.findUnique({
      where: { id: userId },
      select: { nombre: true, email: true, avatarUrl: true },
    }),
    prisma.order.findMany({
      where: { userId, creadoEn: { gte: new Date(Date.now() - 30 * 24 * 60 * 60 * 1000) } },
      orderBy: { creadoEn: "desc" },
      take: 10,
    }),
    prisma.notification.findMany({
      where: { userId, leida: false },
      orderBy: { creadoEn: "desc" },
      take: 5,
    }),
  ])

  return { perfil, pedidos, notificaciones }
}

La diferencia no es solo de queries — es de diseño. Una Action que agrupa los datos de un caso de uso específico es más fácil de cachear, más fácil de testear y más honesta sobre qué problema está resolviendo.

El include que se olvidó y la query que se multiplicó

El N+1 clásico todavía existe dentro de las Actions. Si iterás resultados y hacés una query anidada por cada ítem, Prisma no lo va a prevenir solo — eso es tuyo. El patrón más frecuente que veo en codebases que empiezan con Server Actions:

// ⚠️ N+1 clásico dentro de una Action
// Una query por cada pedido para traer el producto

"use server"

import { prisma } from "@/lib/prisma"

export async function getPedidosConProductos(userId: string) {
  const pedidos = await prisma.order.findMany({ where: { userId } })

  // ❌ N+1: una query por cada pedido
  const pedidosConProducto = await Promise.all(
    pedidos.map(async (pedido) => {
      const producto = await prisma.product.findUnique({
        where: { id: pedido.productId },
      })
      return { ...pedido, producto }
    })
  )

  return pedidosConProducto
}

La solución correcta es colapsar con include:

// ✅ Include correcto: una sola query con JOIN implícito
// Prisma colapsa todo en un único round-trip

"use server"

import { prisma } from "@/lib/prisma"

export async function getPedidosConProductos(userId: string) {
  return prisma.order.findMany({
    where: { userId },
    include: {
      producto: {
        select: { nombre: true, precio: true, imagenUrl: true },
      },
    },
    orderBy: { creadoEn: "desc" },
    take: 20,
  })
}

El select dentro del include es importante: no traés el objeto completo de producto, traés exactamente los campos que el componente necesita. Eso reduce el payload serializado que Next.js tiene que transferir entre server y cliente.

Gotchas reales: lo que no aparece en el tutorial de 15 minutos

El "use server" no garantiza serialización automática de errores de Prisma. Si una Action lanza un PrismaClientKnownRequestError (por ejemplo, un constraint violation), ese error no llega al cliente de la forma que esperás en todos los casos. Necesitás wrapear con try/catch y serializar el error explícitamente:

// actions/usuario.ts
// Manejo explícito de errores de Prisma en Server Actions

"use server"

import { prisma } from "@/lib/prisma"
import { Prisma } from "@prisma/client"

export async function crearUsuario(data: { email: string; nombre: string }) {
  try {
    return await prisma.user.create({ data })
  } catch (error) {
    // Constraint unique violation (P2002 en Prisma)
    if (error instanceof Prisma.PrismaClientKnownRequestError) {
      if (error.code === "P2002") {
        return { error: "El email ya está registrado" }
      }
    }
    // Error no esperado: loguear, no exponer
    console.error("[crearUsuario]", error)
    return { error: "Error interno. Intentá de nuevo." }
  }
}

El logging de queries en desarrollo es tu mejor herramienta de diagnóstico. El singleton de arriba ya incluye log: ["query"] en desarrollo — eso te permite ver exactamente cuántas queries dispara cada render. Si ves el mismo SELECT repetido N veces en el terminal, tenés un N+1 y podés atacarlo antes de que llegue a producción.

Server Actions y React 19 useOptimistic pueden ocultar el problema. Si usás useOptimistic para actualizar la UI antes de que la Action resuelva, la percepción de latencia baja — pero las queries siguen estando. No confundas UX mejorada con queries optimizadas.

Esto conecta con algo que ya documenté al analizar cómo OpenTelemetry en Spring Boot muestra el problema real cuando el log dice OK: la superficie de observabilidad importa. En Next.js 16, si no tenés trazas de queries, el log de la Action puede parecer saludable mientras las queries se multiplican por debajo.

FAQ: Prisma Server Actions Next.js 16 N+1

¿Por qué aparece N+1 en Server Actions si no aparecía en mis API routes?
En API routes, el patrón natural era una ruta = un handler = una query. En Server Actions, la co-location con el componente invita a crear una Action por entidad, y los componentes terminan llamando varias Actions en el mismo render. Esa composición genera múltiples round-trips que en una API route no existían porque la query estaba centralizada.

¿Prisma ORM 5 tiene algún mecanismo para detectar N+1 automáticamente?
No automáticamente en runtime, pero sí podés habilitar el log de queries (log: ["query"]) para verlas en desarrollo. Hay propuestas en la comunidad para un detector de N+1 nativo, pero a la fecha de este post no es una feature estable. La documentación oficial de optimización documenta los patrones a evitar, pero la detección sigue siendo manual o via herramientas externas.

¿Cuántas instancias de PrismaClient debería tener en un proyecto Next.js 16?
Una sola, usando el patrón singleton con globalThis. Más de una instancia significa más de un connection pool, lo que bajo carga de SSR puede agotar las conexiones disponibles en la base de datos. Esto es especialmente crítico en providers serverless donde cada función puede tener su propio proceso.

¿Promise.all dentro de una Action es suficiente para resolver el problema de pool?
Para el caso de múltiples queries independientes dentro de una Action, sí: Promise.all las paraleliza dentro de la misma invocación y el pool maneja una sola conexión (o las mínimas necesarias). El problema que Promise.all no resuelve es cuando tenés múltiples Actions independientes disparadas desde distintos componentes del mismo render — ahí necesitás consolidar a nivel de arquitectura.

¿Cómo afecta esto al caching de Next.js 16?
Next.js 16 tiene caching de Data Cache y Full Route Cache. Si usás fetch o unstable_cache, podés cachear el resultado de una Server Action. Pero el N+1 ocurre antes del cache — si la Action no está cacheada (por ejemplo, en mutaciones o en datos con no-store), cada request ejecuta las queries. El patrón correcto es cachear la Action completa con unstable_cache cuando los datos lo permiten, no cachear queries individuales dentro de ella.

¿Este patrón aplica también a Prisma con Server Components puros (sin Actions)?
Sí, pero con una diferencia: en Server Components sin Actions, las queries viven en el componente directamente y Next.js puede hacer caching a nivel de componente más fácilmente. El problema de composición se acentúa con Server Actions porque el modelo mental de “una Action = un botón o formulario” lleva a granularidad excesiva que multiplica los round-trips.

Lo que me quedo y lo que no compro

Me quedo con este patrón: una Action por caso de uso, no una Action por entidad. Es el cambio de mentalidad más importante al migrar de API routes a Server Actions con Prisma.

Lo que no compro es la narrativa de que Server Actions simplifican el modelo de datos automáticamente. Simplifican el boilerplate — el tipo compartido, el endpoint explícito — pero la responsabilidad de no multiplicar queries sigue siendo tuya. Si venías de API routes donde una ruta = una query bien pensada, el salto a Actions puede llevar a una dispersión de queries que es peor.

El trade-off honesto: Server Actions ganan en DX y co-location. Pierden en visibilidad de qué queries se disparan por render si no tenés el logging activo. Antes de deployar cualquier página con múltiples Actions, revisá el terminal de desarrollo con log: ["query"] activo y contá cuántos SELECT aparecen por render. Si el número te sorprende, tenés trabajo por hacer.

Esto se conecta directamente con lo que documenté en Prisma vs JDBC: el benchmark que casi me hace culpar al ORM equivocado — el ORM rara vez es el problema. La forma de las queries sí lo es. Y en Next.js 16 con Server Actions, la forma la define la arquitectura de las Actions, no Prisma.

Para los que vienen del mundo Spring Boot, hay un paralelo interesante con el presupuesto de retry y amplificación: cada abstracción que parece simplificar introduce su propio vector de amplificación. En Server Actions, ese vector es la composición granular de queries.

Fuentes:

Este artículo fue publicado originalmente en juanchi.dev

How Apache Kafka Powers Real-Time Data Pipelines

Batch vs Streaming

Most standard data pipelines run on a schedule. You use tools like Airflow and dbt to extract and transform large batches of API data once a day. However, what would happen if the data wasn’t collected but rather is being collected in the moment. Scheduled batch scripts are unable to keep up when you go from analyzing yesterday’s data to needing real-time metrics now.

This is where streaming comes in. You would require a system designed for continuous event streaming like Apache Kafka, an open-source distributed event streaming platform.
It acts as a massive central nervous system, allowing data to flow continuously from source to destination.

To understand how Kafka works, I’ll break down its core concepts using a live streaming project:
a pipeline that extracts real-time weather data from the OpenWeatherMap API and streams it directly into a Cassandra database.

Batch vs Streaming

Let’s look at Kafka’s architecture.

Broker

Kafka does not run on a single machine, it is a distributed system.

A Broker is a single Kafka server responsible for receiving, storing and serving messages.

A Cluster is a group of brokers working together. If one broker fails, the cluster ensures the data is replicated and safe elsewhere.

In the project’s code, you can see the connection to the broker defined via the bootstrap_servers parameter pointing to localhost:9092.

Events

In Kafka, an event (also record or message) records the fact that ‘something happened.’ They consist of a key, value, timestamp and headers and cannot be updated or changed. In the streaming pipeline, this is the json response extracted from the weather api.

Topic

Whereas in a database you insert data into a table, in Kafka, you push data to a topic. In the weather pipeline, the topic is simply defined as:

topic = 'weather_info'

Every API response pulled will be published to this specific topic.

producer.send(topic, {api_response})

To ensure the system can scale horizontally and process millions of messages simultaneously, topics are split into Partitions. They allow multiple consumers to read from the same topic in parallel.

Within each partition, messages are assigned a unique sequential ID known as an Offset. This allows consumers to track exactly where they left off in reading the stream, ensuring no data is skipped or read twice.

Producer

A producer is any application that publishes data to a Kafka topic. Their only job is to gather data and push it to the broker. For this project, producer.py acts as the producer. It requests data from the weather api, receives a json payload, and sends it to the topic every 5 seconds.

producer = KafkaProducer(
    bootstrap_servers='localhost:9092',
    value_serializer=lambda v: json.dumps(v).encode('utf-8')
    )

while True:
    results = extract()
    producer.send(topic, results)
    time.sleep(5)

Serialization

Kafka is designed for maximum throughput, meaning it doesn’t process the internal structure of your data. To Kafka, a complex JSON payload or DataFrame is nothing more than an array of raw bytes hence the value_serializer argument in the code block above.

Conversely, when the data reaches its destination, it must be deserialized back into a readable format. This is why the consumer script includes a matching deserializer value_deserializer.

Consumer

A consumer subscribes to one or more topics, reads the stream of incoming records and processes them. In consumer.py, the script acts as a continuous listener on the weather-info topic. As soon as a new weather event arrives, the consumer receives the event, flattens the nested JSON, converts Unix timestamps into standard datetime formats and executes an INSERT statement to load the clean data into a Cassandra database table.

for message in consumer:
    raw_data = message.value

    # ... data flattening and timestamp conversion ...

    session.execute(insert_query, (
        raw_data.get('id'),
        unix_to_dt(sys_data.get('sunrise')),
        # ... other fields ...
        sys_data.get('country')
    ))

Unlike a standard Python for loop that ends when it reaches the bottom of a list, a Kafka for message in consumer loop is infinite.

Architeture

Why use Kafka?
Because, if the OpenWeatherMap API suddenly surges, sending thousands of records per second, and you have a Python script writing directly to Cassandra, the database might become overwhelmed, lock up and crash, taking your entire pipeline down with it.

Kafka on the other hand, acts as an indestructible shock absorber. The Producer can dump millions of records into the Kafka topic at lightning speed and Kafka will just take them. The Consumer will then read from the topic at its own pace, processing and inserting records into Cassandra as fast as it can without overwhelming the database.
And even if the consumer crashes, Kafka remembers exactly where it left off, ensuring zero data loss when it restarts.

I Built a 3D Weather App with Live Wind and Temperature Maps (React + Three.js)

🌍 3D Weather App

Hey everyone,

I’ve been working on a weather app inspired by MSN Weather and Apple Weather and finally built a working version.

🔥 Features

  • 🌬️ Animated wind flow across the map
  • 🌡️ Temperature visualization (hot & cold regions)
  • 🗺️ Interactive map (click anywhere to get weather)
  • ⚡ Real-time weather data
  • 🎨 Modern UI with glassmorphism

🚀 Live Demo

👉 https://project-1l4qo.vercel.app

💡 What I’m Improving

  • More accurate weather data
  • Better wind simulation
  • Enhanced map visuals

Would love to get feedback from you guys 🙌
What should I improve next?

2,775 Downloads in 3 Days With Zero Marketing Budget

2,775 Downloads in 3 Days With Zero Marketing Budget — Here’s What Happened

I need to be honest up front: I don’t fully know why this happened.

Three days ago, we published adaptive-memory-multi-model-router v2.0.0 to npm. No Product Hunt launch. No Twitter thread. No influencer shoutout. No paid ads. Nothing.

Here’s what the download numbers look like:

Day Downloads Notes
Day 1 552 Steady trickle after publish
Day 2 320 Actually dropped — I was worried
Day 3 1,903 What?
Total 2,775 In 72 hours

That’s not a typo. Day 3 had more downloads than Days 1 and 2 combined. Six times more.

This is the story of what we did, what actually worked, what completely failed, and what I think happened. I’m writing this because I wish someone had written this when I was trying to figure out how to get open-source projects noticed.

What We Built

First, context. We built an open-source LLM router called adaptive-memory-multi-model-router (the name is terrible, I know — we’re working on it). It does three things:

  1. Routes requests across 39 LLM providers — OpenAI, Anthropic, Gemini, Groq, Cerebras, Mistral, DeepSeek, Ollama, and 30+ more
  2. Adaptive memory — tracks which models work best for your use case and routes accordingly
  3. OpenAI-compatible proxy server — drop-in replacement for api.openai.com

The proxy server was the v2.0.0 addition. You run:

npx a3m-router serve

And suddenly every OpenAI SDK in your stack can talk to any of 39 providers. No code changes. No new SDKs. Just swap the base URL.

That’s it. That’s the product.

The Strategy (What We Thought Would Work)

Before publishing, we had a plan. It was a bad plan, but it was a plan:

1. Dev.to Articles

We wrote 4 articles. Technical, detailed, with code examples. We thought the developer community would pick them up.

Result: 0 views. Literally zero. New Dev.to account, no followers, no history. The algorithm didn’t surface them, and we had no audience to seed them with.

Lesson learned: publishing to a platform where you have zero reputation is like shouting into the void. Content doesn’t go viral on its own — community does.

2. Hacker News

We submitted to Hacker News. Show HN, carefully written, technical angle.

Result: Flagged and buried. New account, first post, no karma. The HN algorithm (and community) correctly identified this as someone they’d never heard of. Gone within minutes.

Lesson learned: HN requires community cred. You can’t show up day one and expect traction, no matter how good the project is.

3. GitHub Stars

We expected developers to star the repo after discovering it.

Result: 0 stars. As I write this, the GitHub repo has zero stars. Two thousand seven hundred seventy-five people downloaded the npm package. Zero starred the repo. That’s a conversion rate of 0%.

This stings, but it makes sense. People don’t star repos they find through npm. They install, they try, they move on. GitHub stars come from community, not package managers.

4. SEO and Keywords

This is where things get interesting.

What Actually Worked (The 156 Keywords)

Here’s the part I didn’t expect to matter. When we published to npm, we stuffed the package.json with 156 keywords. Not spammy SEO garbage — actual, descriptive keywords that developers and AI agents might search for:

{
  "keywords": [
    "openai",
    "anthropic",
    "llm",
    "router",
    "gateway",
    "proxy",
    "multi-model",
    "ai",
    "gpt",
    "claude",
    "gemini",
    "groq",
    "ollama",
    "langchain",
    "agent",
    "inference",
    "fallback",
    "load-balancing",
    "streaming",
    "adaptive",
    // ... 136 more
  ]
}

The intent was simple: make the package findable when someone searches npm for “openai proxy” or “llm router” or “multi-model gateway.”

But I think what actually happened is more interesting.

The AI Agent Discoverability Hypothesis

Here’s my theory on the Day 3 spike: AI coding agents are discovering packages through npm search.

When a developer asks Cursor, Copilot, Windsurf, or any AI agent to “set up an LLM routing solution” or “add multi-model support to my app,” the agent searches npm. It finds our package because we have 156 keywords covering every conceivable search term.

The Day 3 spike wasn’t organic human discovery. It was AI agents installing packages on behalf of developers who asked their tools to set up LLM infrastructure.

I can’t prove this. But the pattern fits:

  • Day 1: Initial publish, some human curiosity
  • Day 2: Drop-off, the curiosity faded
  • Day 3: Spike — something systemic kicked in

If I’m right, this has massive implications for open-source discoverability. The next SEO isn’t Google — it’s npm keywords optimized for AI agent search.

The Proxy Server Effect

The other factor: npx a3m-router serve.

This one command gives you a working OpenAI-compatible API gateway. No configuration, no API keys to start, no setup wizard. Just run it and point your existing OpenAI SDK at http://localhost:8080/v1.

Developers (and AI agents) can test it in 30 seconds:

# Install and start
npm install adaptive-memory-multi-model-router
npx a3m-router serve

# In another terminal — your existing OpenAI code, unchanged
curl http://localhost:8000/v1/chat/completions 
  -H "Content-Type: application/json" 
  -d '{"model":"claude-3-haiku-20240307","messages":[{"role":"user","content":"hello"}]}'

Zero friction. Zero code changes. That’s the kind of utility that spreads when an AI agent finds it and thinks “this solves the problem.”

The Download Hockey Stick

Here’s the numbers again, visualized:

2,000 |                              ***
      |                              * *
1,500 |                              *  *
      |                              *   *
1,000 |                              *    *
      |                              *     *
  500 | ***                          *      *
      | *  *                         *       *
    0 |*    *   *  *                 *        *
      +------   ------   --------------------
        Day 1    Day 2         Day 3
         552      320          1,903

Day 3 is a hockey stick. Downloads went from hundreds to nearly two thousand overnight. The weekly npm badge went from 872 to 2,775 in a single day.

What We Did Wrong (Complete Transparency)

I want to be honest about the failures because growth stories that only highlight successes are worthless.

We built features instead of community. We spent weeks adding providers, building the proxy server, writing tests. We spent zero time building an audience, engaging on Twitter, contributing to other projects, or writing before the launch.

We ignored the landing page. The GitHub README is good, but there’s no website, no landing page, no documentation site. 2,775 people downloaded something with 0 GitHub stars. That means people aren’t even looking at the repo — they’re installing blindly.

We picked a terrible name. adaptive-memory-multi-model-router is descriptive but impossible to remember or type. We should have branded it something short and memorable from day one.

We launched on platforms where we had no presence. Dev.to with 0 followers. HN with 0 karma. It’s like opening a restaurant in a city where nobody knows you and expecting a line out the door.

The v2.0 Pivot That Changed Everything

The original v1.0 was a library. You imported it, configured it, wrote code against it. Useful, but not the kind of thing that spreads.

v2.0 added the proxy server, and that changed the entire value proposition:

Before v2.0 After v2.0
Library you import Service you run
Requires code changes Drop-in replacement
Framework-specific Works with everything
Need to learn the API OpenAI-compatible

The proxy server means you don’t need to learn our API. You don’t need to change your code. You don’t need to rewrite your LangChain chains or your HTTP calls. You just swap api.openai.com for localhost:8000 and everything works.

That’s the kind of product that spreads. Not because it’s better — but because it requires zero effort to try.

The Dashboard Effect

v2.0 also added a web dashboard. You run the proxy and open http://localhost:8081 to see:

  • All 39 providers and their status
  • Real-time request routing
  • Cost tracking across providers
  • Latency comparisons
  • Memory scores (which models perform best)

The dashboard isn’t just useful — it’s proof. When someone tries the proxy for the first time, the dashboard shows them it’s actually working. That builds trust instantly.

Try It (30 Seconds to a Working AI Gateway)

If you’ve read this far, you might as well try it:

# Install
npm install -g adaptive-memory-multi-model-router

# Start the proxy server
npx a3m-router serve

# Test it (OpenAI-compatible!)
curl http://localhost:8000/v1/chat/completions 
  -H "Content-Type: application/json" 
  -d '{
    "model": "gpt-4o-mini",
    "messages": [{"role": "user", "content": "Hello!"}]
  }'

Or with the OpenAI SDK:

import OpenAI from 'openai';

const client = new OpenAI({
  baseURL: 'http://localhost:8000/v1',
  apiKey: 'any-key-works' // proxy handles routing
});

const response = await client.chat.completions.create({
  model: 'gpt-4o-mini',
  messages: [{ role: 'user', content: 'Hello!' }]
});

Same SDK. Same API. Different backend. That’s the point.

GitHub: github.com/Das-rebel/adaptive-memory-multi-model-router

NPM: npmjs.com/package/adaptive-memory-multi-model-router

What’s Next (And We Need Your Help)

The downloads are great, but downloads without community is just a number on a badge. Here’s what we need:

  1. GitHub stars help. The repo has 0 stars. If you tried it and it worked, a star costs nothing and helps with discoverability more than you’d think.

  2. What providers do you need? We have 39. But if your provider isn’t listed, tell us. We’ll add it.

  3. What features are missing? The proxy is new. The memory system is new. We know there are gaps. Open an issue, even if it’s just a one-liner.

  4. War stories. If you tried it and something broke, tell us. If it worked in a way we didn’t expect, tell us that too. Building in public means nothing if nobody talks back.

The Honest Takeaway

I don’t have a growth hack for you. We didn’t crack a secret algorithm. We didn’t game any system.

What happened is: we built something genuinely useful (an OpenAI-compatible proxy that talks to 39 providers), we made it trivially easy to try (npx a3m-router serve), and we made it findable (156 npm keywords).

Then we got lucky with timing. AI agents are becoming the primary way developers discover tools. Our keywords made us findable by those agents. The proxy made us useful once found.

That’s the whole story. No secrets. No tricks. Just build useful things, make them easy to try, and make them findable.

The 2,775 downloads are a nice number. But I’d trade them all for 10 GitHub stars from developers who actually use the thing.

If this story was useful, follow along at github.com/Das-rebel/adaptive-memory-multi-model-router. Stars appreciated. Issues celebrated. PRs worshipped.