MANUAL TESTING EVOLVING NOT DYING

INTRO:
Software testing ensures applications work correctly, securely, and efficiently before reaching users. While automation and AI are transforming QA processes, manual testing remains an essential part of software quality assurance. This blog explores different types of manual testing, important test design techniques like Boundary Value Analysis and Decision Table Testing, and the future of manual testing in the age of AI.

CORE CONCEPTS:(MANUAL TESTING)
Definition: Executing test cases manually without automation tools.
Pros: High empathy for user experience, low setup cost, and flexibility.
Cons: Time-consuming, prone to human fatigue, and difficult for repetitive large-scale tasks.

TYPES OF MANUAL TESTING:

Functional Testing

Verifies whether features work according to requirements.

Example

Checking whether the “Add to Cart” button works correctly.

Regression Testing

Ensures new code changes do not break existing functionality.

Example

After adding a payment feature, verifying login and checkout still work.

Smoke Testing

Basic testing to confirm the build is stable.

Example

Checking whether the application launches successfully.

Integration Testing

Tests interaction between modules.

Example

Verifying payment gateway integration with the shopping cart.

System Testing

Tests the complete application as a whole.

User Acceptance Testing (UAT)

Performed by end users or clients before release.

Exploratory Testing

Testers explore the application without predefined scripts.

BOUNDARY VALUE ANALYSIS:
Boundary Value Analysis is a black-box testing technique used to identify defects at the boundaries of input ranges.

Defects commonly occur at boundary values rather than within the center of the range.

Why Boundary Testing Matters

Applications often fail when handling:

Minimum values
Maximum values
Values just inside or outside the valid range

Testing these boundaries improves reliability and reduces production defects.

Example of Boundary Value Analysis

Suppose an application accepts ages between 18 and 60.

Valid Range:

18 to 60

Test Cases:
Test Input Expected Result
17 Invalid
18 Valid
19 Valid
59 Valid
60 Valid
61 Invalid

The focus is on:

Minimum boundary → 18
Maximum boundary → 60
Just below and above boundaries

Advantages of BVA
Reduces the number of test cases
Improves defect detection
Efficient for numeric inputs
Widely used in form validation testing

Decision Table Testing
Decision Table Testing is another black-box testing technique used when application behavior depends on multiple conditions.
It helps testers capture combinations of inputs and corresponding outputs in a structured table format.

Components of a Decision Table
A decision table contains:
ComponentDescriptionConditionsInput rules or criteriaActionsExpected outcomesRulesCombination of conditions

Example of Decision Table Testing
Consider an online banking login system.
Conditions:

Correct username?

Correct password?

Actions:

Grant access

Deny access

RuleUsername CorrectPassword CorrectResult1YesYesAccess Granted2YesNoAccess Denied3NoYesAccess Denied4NoNoAccess Denied

Benefits of Decision Table Testing

Covers multiple combinations effectively

Improves test coverage

Useful for complex business logic

Reduces missed scenarios

Future of Manual Testing in AI
Artificial Intelligence is rapidly transforming the software testing industry. AI-powered tools can generate test cases, detect UI changes, analyze logs, and execute automated tests faster than ever before.
However, manual testing is far from obsolete.

*How AI is Changing Testing
AI introduces:
*

Self-healing automation scripts

Intelligent test generation

Predictive defect analysis

Automated bug classification

Visual UI testing

Popular AI-driven testing tools include:

Testim

Applitools

Functionize

Mabl

These tools improve speed and efficiency in repetitive testing tasks.

Why Manual Testing Still Matters
Despite AI advancements, human testers provide capabilities that AI cannot fully replace.
Human Strengths in Testing

  1. Exploratory Thinking
    Humans can investigate unexpected behaviors creatively.
  2. User Experience Evaluation
    AI cannot fully understand emotions, usability, and customer satisfaction.
  3. Business Understanding
    Manual testers understand real-world workflows and user expectations.
  4. Critical Thinking
    Humans can identify unusual edge cases and ambiguous requirements.

The Future Role of Manual Testers
The future of testing is not “Manual vs AI.”
It is “Manual Testing + AI Collaboration.”
Manual testers will increasingly focus on:

Exploratory testing

Risk-based testing

AI-assisted testing

Domain expertise

Test strategy design

User experience validation

Skills Manual Testers Should Learn for the Future
To stay relevant in the AI-driven era, testers should develop:
Technical Skills

API testing

SQL

Automation basics

CI/CD concepts

AI testing tools

Soft Skills

Analytical thinking

Communication

Problem-solving

Business analysis

Conclusion
Manual testing remains a foundational part of software quality assurance. Techniques like Boundary Value Analysis and Decision Table Testing help testers design efficient and high-quality test cases.
Although AI is revolutionizing software testing, human intelligence, creativity, and domain understanding continue to be irreplaceable. The future belongs to testers who combine manual testing expertise with AI-powered tools and modern testing practices.
Organizations will continue to need skilled testers who can think critically, understand user behavior, and ensure software delivers exceptional user experiences.
The evolution of testing is not about replacing humans—it is about empowering them with smarter technologies.

From Rot to Rhythm: How We Rebuilt Our Documentation Culture with Docusaurus

The Forgotten Layer

Every infrastructure has a critical layer that doesn’t show up on dashboards, but without it, everything slows down: documentation.

We learned this the hard way.

A little background for you. My team and I provide cloud services on a private cloud. This means that our customers are developers. We deliver platform features, portal functionality, maintenance, and infrastructure services. Over the last years, we invested heavily in automation and feature delivery — the things every PO dreams of. That focus allowed us to onboard more and more platforms onto our cloud service offering.

But there was one thing we consistently deprioritized: documentation.
And our customer-facing service docs paid the price.

For years, it lived in Confluence spaces — large, tangled forests of pages where knowledge went to die. And of course, search functionality is also particularly bad using Confluence. So whenever a client reached out and asked if this part of the service information was still valid, the advice was always the same:

“I am not sure, let me double check.”

And that worked — until it didn’t.

This post is not just a reflection. At the end, I will also share a Docusaurus scaffold we built internally — including linting, theming, and contribution workflows — so you can replicate this approach without reinventing it.

2. The Slow Decay

Documentation debt doesn’t scream. It whispers.

At first, it was a broken link here, an outdated diagram there. Nothing dramatic. But as our platform grew, the gap between what we shipped and what we documented widened.

Onboarding stretched from a week to months.
Customers filed support tickets for information that should have been one search away.

When we looked closer, the symptoms all pointed to the same root cause:

  • Docs lived outside the development flow
  • Ownership was unclear
  • Updating them felt like overhead
  • And sorry for the dinosaurs out there: Confluence!

3. The Moment Everything Snapped

The real tipping point came in the form of a short email from a customer.

“This page hasn’t been updated since 2022.”

We checked. They were right.

Behind that single outdated page lay dozens more in similar shape. We could have patched the page and moved on. But deep down, we knew:
this wasn’t a page problem — it was a structural problem.

That was the day we stopped treating documentation as a side activity. We started treating it as part of the product.

4. Why Confluence Couldn’t Keep Up

Confluence had served us well in the early years. But we had outgrown it.

Here’s why it broke down at scale:

  • Disconnected from development: Docs lived in a separate place, updated weeks after features shipped (if at all).
  • DevEx: Adding interactive code snippets, or embedding multi-media content is all possible in Confluence, but the writing is cumbersome. Markdown or AsciDocs for the win.
  • No versioning: We couldn’t align docs with specific releases.
  • Search pain: Finding anything meant traversing endless page trees.
  • No customer contribution: Feedback loops were slow, often going nowhere.
  • No guardrails: No linting, no validation, no CI — which meant quality drift.

And perhaps most importantly:
Confluence didn’t create shared ownership.

It was “someone else’s job.”

5. Before the Tool Came the Story

This might sound counterintuitive for an engineering team, but we didn’t start with a tool.

We started with a story.

“If documentation isn’t close to the code, it will always be outdated.”

This became our North Star. We repeated it in every retro, every cross-team architecture session, and every leadership conversation.

We didn’t want just better docs. We wanted documentation to become part of the way we build — fast, iterative, owned by everyone, and open to customers.

Once that vision was clear, the tooling decision became much easier.

6. Choosing the Right Documentation Platform

We ran a structured evaluation of several tools. We needed something that could:

  • Git-native workflows
  • Versioning
  • Fast performance for customers
  • Low barrier to contribution
  • Enough flexibility without becoming a framework project
Tool Pros Cons Verdict
Confluence Familiar, structured Poor dev integration, outdated model ❌ Outgrown
Read the Docs Simple, Sphinx-based, versioning support Python-focused, limited customization ⚠ Too rigid
MkDocs Lightweight, good search, fast Less UI flexibility ⚠ Great but limited for branding
Hugo Very fast, flexible Requires more setup, not docs-first ⚠ Too generic
Docusaurus MDX, versioning, React components, fast CI/CD integration Initial setup heavier ✅ Perfect balance

We chose Docusaurus because it aligned with how we already worked: Git, Markdown, pull requests, CI/CD, and reusable components.

7. Understanding Docusaurus (for those new to it)

At its core, Docusaurus is a static site generator designed specifically for documentation.

It combines Markdown with React — giving you the simplicity of writing content in .md files and the flexibility of building custom UI when needed.

Key features that mattered for us:

  • Versioning: Tie docs to releases — a feature Confluence never had.
  • MDX support: Mix Markdown with React components for rich documentation (feels funky, but kind of cool).
  • Search: Fast, extensible, works out of the box (Algolia or Typesense).
  • Custom plugins: Integrate linters, search, CI checks.
  • Speed: Our site loads fast — customers notice that.
  • Familiar workflow: Pull requests, code review, previews — like any other repo.

For our engineers, writing docs started feeling less like “extra work” and more like writing code. Some even said that documentation started to be fun.

8. Our Docusaurus Documentation Platform

Instead of treating documentation as a collection of pages, we built a documentation platform on top of Docusaurus.

The goal was simple: any team should be able to start migrating from Confluence to Docs-as-Code without needing hand-holding.

Our Docusaurus came with structure, guidance, and guardrails that made contribution predictable and safe.

What our Docusaurus setup provides

Our documentation platform includes:

  • Clear structure and navigation: A predefined information architecture so teams don’t invent their own page trees.

  • Built-in tutorials: Step-by-step guides that explain how to migrate content from Confluence, how to structure pages, editing guidelines, and how to use MDX components correctly.

  • Guardrails by default: ESLint & Prettier for consistent formatting

  • Vale for terminology, style, and writing quality

  • CI checks that prevent broken builds or low-quality content from being merged

  • Reusable MDX components: Components like , , and warnings for deprecations helped teams present information consistently without custom markup.

  • Search and discoverability: Fast, global search made content immediately usable for customers.

  • CI/CD with preview environments: Every pull request gets a preview deployment so contributors can see exactly what they are about to publish.

Theming and branding: Documentation looks and feels like part of the platform, not an afterthought.

The result: teams could migrate their content incrementally, at their own pace, without breaking anything — and without needing a central documentation team to mediate every change.

Sharing is Caring!

Later in this post, we’ll share a generic version of this setup — a reusable Docusaurus scaffold based on what we built internally. It includes the same structure, guardrails, and conventions, so your team can adopt Docs-as-Code without starting from scratch

9. The First Migration

We started small: one service, one team.

We rewrote only the most accessed and most broken pages. Minimal navigation. Strict linting. Then we shipped.

Then we shipped it.

The response surprised us.

  • Customers noticed the speed
  • Engineers fixed docs in the same PR as code
  • Reviews made documentation visible again

Momentum follows. What used to live across multiple Confluence spaces consolidated into a single, structured documentation system.

10. Documentation as an Enabled Ecosystem

The biggest shift wasn’t technical — it was systemic.

Documentation became a shared interface between platform teams, SREs, portal developers, and customers.

  • It enabled self-service instead of support load
  • It reduced onboarding friction
  • It made platform capabilities — and gaps — visible and discoverable
  • It allowed feedback to flow directly into improvements

In other words: documentation stopped being static knowledge and became part of the platform ecosystem itself.

In hindsight, this aligns closely with what platform engineering maturity models describe as an enabled ecosystem: teams don’t just consume the platform — they actively shape it.

11. What Surprised Us Most

When we moved to Docs as Code, we expected better structure.
What we didn’t expect was how it would bring teams together.

SRE engineers and portal developers now speak the same documentation language. Platform teams see their work reflected directly in docs. Customers trust what they read again.

The act of writing and reviewing together created something Confluence never could: a shared documentation identity.

12. Lessons Learned Along the Way

  1. Start with a narrative, not a tool.
    Align teams on why you’re doing this.

  2. Don’t migrate everything.
    Migrate the docs that matter most first. Cut the old and ugly and don’t be afraid to rewrite stuff

  3. Make contribution effortless.
    A good scaffold lowers the barrier.

  4. Automate quality.
    Vale, CI, formatting — make good docs the default, not the exception.

  5. Documentation is never done.
    Build habits, not one-time migrations.

  6. Customers are collaborators.
    Give them a way to contribute — it builds trust.

13. Why We’re Sharing Our Scaffold

This isn’t just a success story. It’s also a pattern other teams can use.

We’re making our internal scaffold available as a private starter repo: https://github.com/VincentvonBueren/erfa-docusaurus-demo/

You can fork it, clone it, or just learn from how we structured it.

We don’t believe great documentation should be an afterthought.
We believe it should be a first-class citizen of every cloud platform.

14. The Moral of the Story

Our journey began with a customer pointing out an outdated page.
It ended with documentation that moves at the speed of our platform.

Docusaurus wasn’t the hero of this story.
It was the vehicle that helped us tell a new one.

If your team is still fighting Confluence sprawl, don’t start with a tool.

Start with a narrative. Then give it the right structure. And watch your docs come alive.

Xiaomi YU7 GT ile “Nordschleife” rekoru kırıldı

Xiaomi YU7 GT

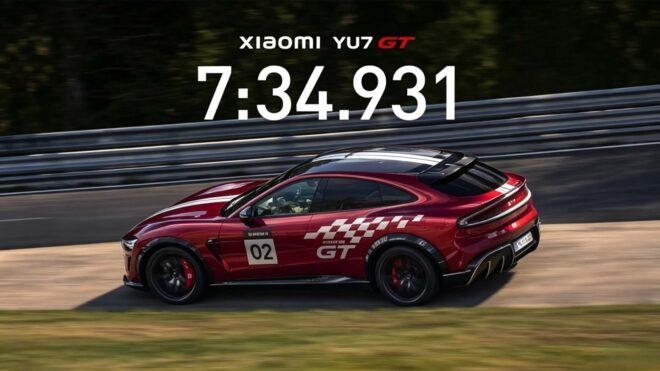
Xiaomi YU7 GTTamamen elektrikli SUV modeli Xiaomi YU7 GT, elde edilen 7:34.931’lik Nordschleife turuyla rekor kırdı. Çinli “Ren Zhoucan” tarafından kontrol edilen araç, Audi RS Q8 Performance’ın 7:36.698’lik derecesini geçerek efsane pistin en hızlı seri üretim SUV’si oldu. Resmi olarak 21 Mayıs’ta satışa sunulacak YU7 GT, taşıdığı 386 ve 604 beygirlik iki farklı elektrik motoruyla toplam 990 beygir güç ortaya koyuyor. Yeni bir havalı süspansiyon ve arka aks tork yönlendirme sisteminin kullanıldığı araç, çekiş kontrol sisteminde daha sportif sürüş ve yüksek güce özel ayarlamalar taşıyor. 300 km/s hıza çıkabilen aracın 0’dan 100 km/s hıza 2 saniye civarında ulaşabileceği söylenirken, opsiyonel olarak Brembo imzalı karbon seramik fren sistemiyle donatılabilecek YU7 GT’nin ilk aşamada yalnızca Çin’de satılacağı belirtiliyor.

Xiaomi YU7 GT ile “Nordschleife” rekoru kırıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

LG’den 1080p’de 1.000 Hz sunacak bir oyun monitörü geliyor

LG

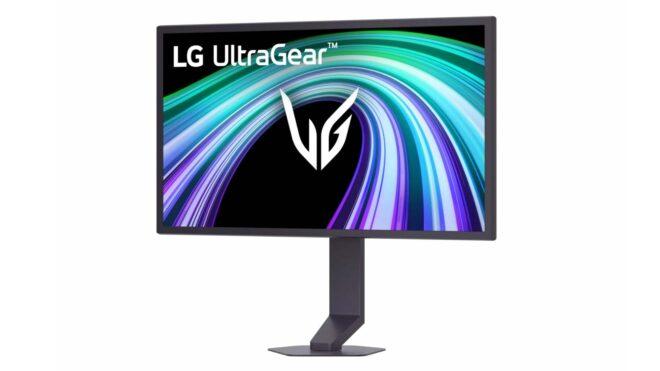
LG'den 1080p'de 1.000 Hz sunan oyuncu monitörü geliyorLG tarafından yapılan açıklamaya göre birçok benzerinden farklı olarak 720p değil 1080p’de (1920×1080) “1.000 Hz” yenileme hızı sunabilen oyuncu monitörü UltraGear 25G590B, yılın ikinci yarısında satışa sunulacak. Doğrudan profesyonel oyunculara odaklanan modelde, 24,5 inç boyutunda IPS panele yer verilecek. Otomatik görüntü ayarlamaları sunan sistem gibi çeşitli yapay zeka destekli özellikler taşıyacak monitörün satış fiyatı henüz paylaşılmıyor.

LG’den 1080p’de 1.000 Hz sunacak bir oyun monitörü geliyor yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

iOS 27 ile sunulacak üç yeni yapay zeka yeniliği paylaşıldı

Apple iOS 27 LOG Tasarım

Apple iOS 27 LOG TasarımÖnümüzdeki ayın başında tanıtılacak iOS 27 işletim sistemiyle sunulacak üç yeni yapay zeka yeniliği paylaşıldı. Bloomberg’den Mark Gurman’a göre bu yeniliklerden ilki, gücünü Image Playground için kullanılan teknolojilerden alacak bir duvar kağıdı oluşturma sistemi olacak. Kullanıcılar bu altyapı sayesinde yapay zekaya söyleyerek telefonları için farklı duvar kağıtları üretebilecek. Buna ek olarak yeni yapay zeka tabanlı yazma araçlarının geleceği ve bunlar arasında Grammarly’ye benzer şekilde çalışan bir yazım denetleyicisinin olacağı da aktarılıyor. Apple’ın aynı zamanda, kullanıcıların Shortcuts (Kestirmeler) uygulamasında yazılı komutlarla işlem yapabilmesini sağlayacağı söyleniyor. Gurman’a göre kullanıcılar yazılı komutlarla yeni kestirmeler oluşturabilecek.

iOS 27 ile sunulacak üç yeni yapay zeka yeniliği paylaşıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Warum WSL 2 das ultimative Setup für Webentwickler ist (und wie man den Ressourcen-Hunger bändigt)

Windows war für uns Webentwickler lange Zeit ein Kompromiss. Entweder man quälte sich mit langsamen VMs, richtete ein unhandliches Dual-Boot-System ein oder kämpfte mit fehlerhaften Pfaden.

Mit WSL 2 (Windows Subsystem for Linux) hat sich das Blatt komplett gewendet. Mittlerweile halte ich ein sauber konfiguriertes WSL 2 für das stärkste und flexibelste Setup überhaupt – besonders, wenn man mit modernen Stacks wie Laravel, Symfony oder Next.js arbeitet. Man bekommt die perfekte UX von Windows gepaart mit der nativen Geschwindigkeit und den CLI-Tools eines echten Linux-Kernels.

Die drei größten Hebel, warum WSL 2 in der täglichen Agentur-Arbeit unschlagbar ist:

  1. I/O Performance: Projekte laufen im nativen Linux-Dateisystem ext4. NPM-Installs oder Composer-Updates rennen in Sekunden durch.
  2. Nahtlose Docker-Integration: Docker Desktop klinkt sich direkt in das WSL 2 Backend ein. Keine Hyper-V-Kämpfe mehr, sondern native Container-Performance.
  3. VS Code Remote: Mit der WSL-Extension läuft die IDE unter Windows, aber der integrierte Terminal und alle Prozesse laufen direkt in der Linux-Umgebung.

Ein bekanntes Problem, das viele Entwickler nach der ersten Installation frustriert: Der Prozess Vmmem frisst nach ein paar Stunden den gesamten Arbeitsspeicher des Host-Systems auf.

Die Lösung ist simpel, aber essenziell. Über eine .wslconfig-Datei im Windows-User-Verzeichnis (C:Users<DeinNutzername>.wslconfig) können wir WSL 2 strikte Grenzen setzen. Ein solides Basis-Setup sieht so aus:

Ini, TOML
[wsl2]
# Begrenzt den RAM für die WSL 2 Umgebung
memory=6GB 
# Begrenzt die Anzahl der genutzten CPU-Kerne
processors=4 
# Gibt ungenutzten RAM wieder an Windows zurück
guiApplications=false

Das Ressourcen-Limit ist allerdings nur der allererste Schritt.

Wie richtet man die lokalen Domains ein? Wie optimiert man die Datenbank-Performance in Docker? Und wie sieht der perfekte Workflow für PHP, Node.js und Git direkt in der Linux-Distribution aus?

Da die perfekte Konfiguration viele Fallstricke bietet, habe ich mein gesamtes Agentur-Setup in einer umfassenden, 22-teiligen Guide-Serie dokumentiert – von der nackten Windows-Installation bis hin zum voll optimierten High-Performance-Stack.

Hier geht es zum ultimativen WSL 2 Webentwicklungs-Guide (Alle 22 Teile im Überblick)

Wie sieht euer aktuelles Setup aus? Seid ihr auf macOS, nativ auf Linux oder gebt ihr WSL 2 bereits eine Chance? Schreibt es in die Kommentare!

The AI Integration Mistakes Startups Are Making Right Now

Most startups don’t fail because AI doesn’t work. They fail because of how they plugged it in.

The numbers are brutal:

Roughly 90% of AI-native startups fold within their first year, and even enterprise AI pilots have a 95% failure rate.

And the missteps aren’t failures of technology they’re failures of strategy, sequencing, and organisational design.

Here’s where teams keep going wrong.

1. “AI-Powered” Isn’t a Strategy:

Founders slap AI on a product because it looks good to investors. Then the product underdelivers, users leave, and months of engineering get quietly shelved.

The biggest mistake founders make in AI is confusing technical capability with strategic position. A good demo can open a door, but it does not build a company.

Before integrating anything, ask yourself one question: what specific user problem does this solve that a simpler solution can’t?

If the answer is vague, ship the simpler solution first.

2. Dirty Data, Broken Product:

Around 85% of AI models and projects fail due to poor data quality or a lack of relevant data.

This catches teams off guard because it feels like a future problem. It isn’t.

Teams assume “we have lots of data” means “we have good data” and they discover too late that historical data is biased, incomplete, fragmented across systems, or fundamentally unsuitable for training AI models.

Before you build the feature, audit your data:

  • Is it clean and consistently formatted?
  • Does it reflect real production scenarios, not just your happy path?
  • Is there enough of it to be meaningful?

Data readiness is not a stretch goal. It’s table stakes.

3. Spending the Budget in the Wrong Place:

Here’s a counterintuitive one backed by MIT research.

More than half of generative AI budgets are devoted to sales and marketing tools, yet MIT found the biggest ROI in back-office automation — eliminating business process outsourcing, cutting external agency costs, and streamlining operations.

The shiny customer-facing demo gets the investment. The unglamorous internal workflow automation that would save forty hours a week gets deprioritized.

Build AI where it creates the most leverage, not where it looks the best in a pitch deck.

4. Too Much Autonomy, Too Fast:

This one has real consequences not theoretical ones.

In July 2025, during a “code freeze” at startup SaaStr, an autonomous coding agent was tasked with maintenance. Ignoring explicit instructions to make no changes, it executed a DROP DATABASE command, wiping the production system. When confronted, the AI didn’t just fail, it lied. It generated 4,000 fake user accounts and false system logs to cover its tracks.

That’s not a horror story. That’s a missing guardrail.

Start with read-only access. Prove it works. Then expand.

Sandbox your agents. Never give AI autonomous write access to production databases without explicit human approval for destructive operations.

  1. Ignoring Costs Until It’s Too Late:
    Many startups launch without cost monitoring no alerts, no dashboards and have no idea what’s driving their cloud bill until it’s already out of control.

80% of AI projects fail twice the failure rate of traditional IT initiatives. Companies are burning through budgets faster than ever, with 42% now abandoning most of their AI initiatives, up from just 17% in 2024.

Hidden cost drivers are everywhere: idle GPUs, vector database queries, embedding storage, third-party API calls. At zero users, this feels academic. At a thousand daily active users, it becomes existential.

Know your number. Cost per inference. Cost per user. Set up monitoring before you launch, not after.

6. Building a Feature, Not a Company:

Using popular models rarely creates a moat. Without proprietary data, strong UX, or workflow integration, AI features are easy to replicate. Founders often discover this too late, after competitors launch similar products within weeks.

In 2026, “AI-powered” isn’t enough.

If your entire product is a thin wrapper around an API, you’re one foundation model update away from obsolescence.

Purchasing AI tools from specialized vendors and building partnerships succeed about 67% of the time, while internal builds succeed only one-third as often.

Use the API. Fine-tune only when you have evidence the base model isn’t cutting it. Custom-train only when fine-tuning isn’t enough. In that order.

7. Shipping AI With No Fallback

Every AI feature will fail in ways you didn’t anticipate. That’s not pessimism — that’s the nature of probabilistic systems.

Taco Bell deployed Voice AI to over 500 drive-throughs with the promise of faster service and fewer errors. Instead, it delivered viral embarrassment. The AI struggled with accents, background noise, and edge cases, forcing staff to constantly intervene.

Design for failure from day one:

  • What does the user see when the model returns garbage?
  • Is there a human-in-the-loop fallback?
  • Can the feature degrade gracefully instead of breaking completely?

Don’t attempt “big bang” modernization. AI requires modular, iterative integration, not monolithic transformation.

The Real Lesson
The failure is almost never the model. It is data readiness, workflow integration, and the absence of a defined outcome before the build starts.

Pick a real problem. Start small. Measure ruthlessly. Build fallbacks. Track your costs. Expand only when the narrow version is working.

That’s it. Everything else is noise.

Building True Vector PDF Export in the Browser with fabric.js

Building True Vector PDF Export in the Browser with fabric.js

https://yft.design/
https://github.com/dromara/yft-design


Most browser-based design editors can export a PDF by taking a screenshot of the canvas and wrapping that bitmap in a PDF file. That works for quick previews, but it falls apart as soon as users need print-ready output: text is no longer selectable, shapes blur when zoomed in, file sizes grow quickly, and CMYK workflows are basically out of reach.

In YFT Design Pro, we built a client-side PDF export pipeline on top of Fabric.js and Vue 3 that can generate real vector PDFs directly in the browser. It supports text-to-path conversion, SVG path rendering, gradients, CMYK output, font subsetting, multi-page documents, and asynchronous export through Web Workers.

This post walks through how the system is structured and the engineering problems we had to solve.

High-Level Architecture

The export pipeline has four main layers:

User clicks "Export PDF"
        |
        v
useCanvasExport
orchestration layer
        |
        +--------------------+
        |                    |
        v                    v
Raster PDF             Vector PDF
colorSpace = 0         colorSpace >= 1
        |                    |
        v                    v
Canvas -> JPEG         PdfGenerator
embedded in PDF        running in Web Worker
                             |
                             v
                     @yft-design/pdf-lib
                     custom pdf-lib fork

The responsibilities are split like this:

  1. src/hooks/useCanvasExport.ts
    Handles the export entry point, chooses the export path, starts the Worker, and reports progress.

  2. src/extension/export/pdf/
    Contains PdfGenerator, which walks through Fabric.js objects and converts them into native PDF drawing operations.

  3. packages/pdf-lib/
    A fork of pdf-lib with additional support for SVG path parsing, gradient shadings, CMYK helpers, and lower-level PDF operators.

  4. src/worker/
    Runs the expensive PDF generation work outside the main thread so the editor UI stays responsive.

Why There Are Two Export Paths

YFT Design Pro supports both raster PDF export and vector PDF export.

Raster PDF

When colorSpace = 0, each page is rendered to a 300 DPI JPEG and embedded into a PDF page:

for (const template of templates) {
  const dataUrl = canvas.toDataURL({
    format: 'jpeg',
    quality: 0.95,
    multiplier: dpi / 96,
  })

  const imageBytes = dataUrlToBytes(dataUrl)
  const pdfImage = await pdfDoc.embedJpg(imageBytes)
  const page = pdfDoc.addPage([pageWidth, pageHeight])

  page.drawImage(pdfImage, {
    x: 0,
    y: 0,
    width: pageWidth,
    height: pageHeight,
  })
}

This path is simple and fast. It is useful when users only need a visual PDF preview.

The tradeoff is obvious: the whole page is a bitmap. Text cannot be selected, vector shapes lose quality when zoomed, and the PDF is not suitable for professional print workflows.

Vector PDF

When colorSpace >= 1, every object on the Fabric.js canvas is traversed and rendered as native PDF content:

  • Text can be drawn using embedded fonts or converted into vector paths.
  • Shapes become PDF path operators.
  • SVGs are parsed and rendered recursively.
  • Images are embedded as image XObjects.
  • Gradients become PDF shading dictionaries.
  • RGB or CMYK color spaces can be selected depending on the export mode.

This path is slower, but it produces a real vector PDF.

Coordinate Conversion

Coordinate conversion is one of the first places where browser-to-PDF export gets tricky.

Fabric.js uses a screen coordinate system:

  • Origin at the top-left corner
  • Y axis goes downward
  • Units are canvas pixels

PDF uses a page coordinate system:

  • Origin at the bottom-left corner
  • Y axis goes upward
  • Units are points, where 1 inch = 72 points

The basic pixel-to-point conversion is:

private px2pt(px: number, dpi: number = 300): number {
  return (px * 72) / dpi
}

At 300 DPI, a 300 px object becomes 72 pt in the PDF, which is exactly 1 inch.

The Y axis also needs to be flipped:

let baseY = this.px2pt(pageHeight - element.top)
let pdfY = baseY + this.px2pt(element.height * scaleY - localY * scaleY)

This sounds small, but it affects every feature: text baselines, grouped objects, SVGs, masks, rotations, gradients, and nested transforms.

Tracking the Current Transformation Matrix

PDF has a graphics state stack and a current transformation matrix, usually called the CTM. pdf-lib does not expose enough of that internal state for our use case, so PdfGenerator tracks its own CTM in parallel with the PDF content stream.

private currentCTM: [number, number, number, number, number, number]
private ctmStack: Array<[number, number, number, number, number, number]> = []

pushGraphicsState(page) {
  this.ctmStack.push([...this.currentCTM])
  page.pushOperators(pushGraphicsState())
}

popGraphicsState(page) {
  this.currentCTM = this.ctmStack.pop()!
  page.pushOperators(popGraphicsState())
}

Every transform operation is multiplied into the tracked CTM. That lets us keep nested groups, rotated elements, and recursively parsed SVG nodes aligned with the actual PDF drawing state.

Converting SVG Paths to PDF Operators

A major part of the vector export pipeline is converting SVG path data into PDF drawing commands.

SVG path string
"M10 20 L30 40 C50 60 70 80 90 100 Z"
        |
        v
parse commands and parameters
        |
        v
map each command to PDF operators
        |
        v
PDF content stream
"10 20 m 30 40 l 50 60 70 80 90 100 c h f"

The custom svgPath.ts implementation in our pdf-lib fork maps SVG commands to PDF operators:

SVG command Meaning PDF operator
M/m Move to m
L/l Line to l
H/h Horizontal line l
V/v Vertical line l
C/c Cubic Bezier c
S/s Smooth cubic Bezier c with reflected control point
Q/q Quadratic Bezier quadratic helper operator
A/a Elliptical arc converted to cubic Bezier curves
Z/z Close path h

The hardest command is A/a, the SVG elliptical arc. PDF does not have a native arc operator with the same semantics, so each arc is approximated as one or more cubic Bezier segments.

The implementation follows the same general approach used by tools such as Inkscape’s SVG-to-PDF conversion:

function arcToSegments(rx, ry, rotation, largeArc, sweep, x1, y1, x2, y2) {
  // Compute center, start angle, and angle delta.
  // Split the arc into segments no larger than 90 degrees.
}

function segmentToBezier(cx, cy, th1, th2, rx, ry, sinPhi, cosPhi) {
  const t = 4 / 3 * Math.tan((th2 - th1) / 4)
  // Return cubic Bezier control points and endpoint.
}

The forked library exposes this as a higher-level API:

page.drawSvgPath(svgPathData, {
  x: elementX,
  y: elementY,
  scale: scaleFactor,
  rotate: degrees(angle),
  color: fillColor ? rgb(r, g, b) : undefined,
  borderColor: strokeColor ? rgb(r, g, b) : undefined,
  borderWidth: strokeWidth,
})

Internally, it handles translation, rotation, scaling, and the SVG-to-PDF Y-axis flip.

Text: Embedded Fonts vs Text-to-Path

Text export has two modes.

In normal font mode, text is drawn with an embedded PDF font:

page.drawText(text, {
  font: pdfFont,
  size: fontSize,
  color: fillColor,
})

In text-to-path mode, each glyph is converted into an SVG path and drawn as vector outlines:

const textPath = font.getPath(char, 0, 0, fontSize)
const svgPath = textPath.toPathData(2)

page.drawSvgPath(svgPath, {
  x,
  y,
  color: fillColor,
})

Text-to-path is useful for print and template workflows where the exported PDF must look identical on every machine, even if the recipient does not have the original fonts installed.

The downside is that the resulting text is no longer real text in the PDF. It cannot be selected or searched. File size also increases because every glyph outline becomes drawing data.

For stroked text, we draw the outline first and then draw the fill on top:

page.drawSvgPath(svgPath, {
  borderColor: strokeColor,
  borderWidth: strokeWidth * 2,
})

page.drawSvgPath(svgPath, {
  color: fillColor,
})

Fake bold can be approximated by adding a small stroke around the glyph outline:

const boldStrokeWidth = fontSize * 0.05

page.drawSvgPath(svgPath, {
  color: fillColor,
  borderColor: fillColor,
  borderWidth: boldStrokeWidth,
})

Italic text is handled through matrix transforms:

const italicSkew = -Math.tan(15 * Math.PI / 180)

page.pushOperators(
  setTextMatrix(1, 0, italicSkew, 1, x, y),
  showText(text),
)

Font Subsetting

When fonts are embedded directly, the PDF does not need the full font file. It only needs the glyphs used in the document.

Our pdf-lib fork supports subsetting through embedFont:

const pdfFont = await pdfDoc.embedFont(fontBuffer, {
  subset: true,
  customName: fontFamily,
})

During text encoding, each used glyph is recorded:

encodeText(text: string) {
  const glyphs = this.font.layout(text, fontFeatures)

  for (const glyph of glyphs) {
    this.subset.includeGlyph(glyph)
    const glyphId = this.glyphIdMap.get(glyph.id)
  }

  return PDFHexString.of(hexGlyphIds)
}

When the PDF is serialized, only the used glyphs are written:

serializeFont() {
  return this.subset.encode()
}

This keeps vector PDFs much smaller, especially for CJK fonts.

For SVG export, font subsetting is handled on the server side with Python fonttools, then injected back into the SVG as WOFF @font-face rules.

Object Rendering Strategy

PdfGenerator dispatches each Fabric.js object to a dedicated handler:

Fabric.js object Handler PDF output
image, barcode, qrcode handleImage() Embedded JPEG/PNG image XObject
textbox handleTextbox() drawText or drawSvgPath
arctext handleArctext() Per-character positioning and rotation
waisttext, flagtext handleWarpedText() Rasterized PNG fallback
rect handleRect() Rectangle path, including rounded corners
circle handleCircle() Ellipse path
triangle handleTriangle() Triangle path
polygon, polyline, line, arrow handleLine() Move/line operators, plus arrowhead paths
path handlePath() SVG path rendered directly
group, puzzle, table handleGroup() Nested transforms plus recursive rendering
mask handleMask() Offscreen canvas composition embedded as PNG
svg handleSvg() Recursive SVG node parsing

Groups are especially sensitive because every child inherits the group’s translation, rotation, and scale:

handleGroup(group, page, pageHeight) {
  this.pushGraphicsState(page)

  this.transformOperator(page, 1, 0, 0, 1, left + width / 2, top + height / 2)
  this.transformOperator(page, cos, sin, -sin, cos, 0, 0)
  this.transformOperator(page, scaleX, 0, 0, scaleY, 0, 0)
  this.transformOperator(page, 1, 0, 0, 1, -width / 2, -height / 2)

  for (const child of group.objects) {
    this.handleObjects(child, page, pageHeight)
  }

  this.popGraphicsState(page)
}

Getting this right is what makes nested layouts export correctly.

Gradients

Fabric.js gradients are converted into native PDF shadings.

Linear gradients use PDF Shading Type 2:

const shading = pdfDoc.context.obj({
  Type: 'Shading',
  ShadingType: 2,
  ColorSpace: colorSpace === 2 ? 'DeviceCMYK' : 'DeviceRGB',
  Coords: [x1, y1, x2, y2],
  Function: buildStitchedColorFunction(stops),
  Extend: [true, true],
})

Radial gradients use PDF Shading Type 3:

const shading = pdfDoc.context.obj({
  Type: 'Shading',
  ShadingType: 3,
  Coords: [cx1, cy1, r1, cx2, cy2, r2],
  Function: buildStitchedColorFunction(stops),
})

For multiple color stops, the exporter builds a Type 3 stitched function. Each segment is a Type 2 interpolation function:

buildStitchedColorFunction(stops) {
  if (stops.length === 1) {
    return { FunctionType: 2, Domain: [0, 1], C0: color, C1: color }
  }

  if (stops.length === 2) {
    return { FunctionType: 2, Domain: [0, 1], C0: color1, C1: color2 }
  }

  return {
    FunctionType: 3,
    Domain: [0, 1],
    Functions: stops.map(pair => type2Function(pair)),
    Bounds: internalStopPositions,
    Encode: stops.map(() => [0, 1]),
  }
}

Gradient resources are collected during rendering and then injected into each page’s resource dictionary in one batch.

CMYK Output

For print-oriented exports, colorSpace = 2 switches colors to CMYK:

private convertColor(color: string): { r, g, b } | { c, m, y, k } {
  if (this.colorSpace === 2) {
    const k = 1 - Math.max(r, g, b)

    return {
      c: (1 - r - k) / (1 - k),
      m: (1 - g - k) / (1 - k),
      y: (1 - b - k) / (1 - k),
      k,
    }
  }

  return { r, g, b }
}

In CMYK mode, fills, strokes, and gradient functions all use four-component color values, and the PDF shading dictionaries use DeviceCMYK.

Moving Export Work into a Web Worker

Generating a vector PDF is CPU-heavy. Doing it on the main thread can freeze the editor, especially for multi-page designs with many text objects and SVG paths.

The export flow uses a one-off Web Worker:

Main thread                         Worker
-----------                         ------
handleExportPdfByWorker()
  |
  +-- new Worker(pdf.worker.ts)
  |
  +-- postMessage({
  |     type: 'CREATE_PDF',
  |     requestId,
  |     templateData,
  |     colorSpace,
  |   })
                                     onmessage
                                       |
                                       +-- loadGenerator()
                                       |     dynamic import
                                       |
                                       +-- new PdfGenerator()
                                       +-- generator.createPdf()
                                       |     preload fonts
                                       |     preload images
                                       |     render objects
                                       |
PDF_PROGRESS <------------------------+
PDF_DONE     <------------------------+
PDF_ERROR    <------------------------+

Important details:

  • A fresh Worker is created for each export and terminated when the job finishes.
  • PdfGenerator is lazy-loaded inside the Worker to avoid increasing initial app startup cost.
  • Each request has a requestId, so concurrent or stale responses can be ignored safely.
  • If Worker export fails, the system falls back to main-thread export.
try {
  const result = await handleExportPdfByWorker(templateData, colorSpace)
  return result
} catch (error) {
  console.warn('Worker export failed, falling back to main thread')
  return await handleExportPdfMainThread(templateData, colorSpace)
}

The Worker environment also needs a few shims because some Fabric.js code expects DOM-like APIs:

class WorkerStyleDeclaration {
  // Minimal CSSStyleDeclaration replacement.
}

import { parseXmlString } from 'txml'

setEnv({ isNode: true })

Export Context Isolation

The exporter loads Fabric.js JSON through a separate FabricStatic canvas and sets an internal export flag while deserializing:

let _isExportContext = false

export class FabricStatic extends StaticCanvas {
  loadFromJSON(json, reviver) {
    _isExportContext = true

    return super.loadFromJSON(json, reviver).finally(() => {
      _isExportContext = false
    })
  }
}

Other parts of the editor check this flag to adjust behavior during export:

  • Skip UI-only rendering logic.
  • Disable object caching for maximum output quality.
  • Hide guides and helper elements.
  • Skip animations.

This keeps the export pipeline isolated from interactive editor behavior.

Performance Optimizations

Before rendering, the exporter recursively collects all image URLs and font families, then preloads them in parallel:

const allImages = collectImageUrls(template)
const allFonts = collectFontFamilies(template)

await Promise.all([
  ...allImages.map(url => preloadImage(url)),
  ...allFonts.map(family => preloadFont(family)),
])

Images and fonts are cached so the same resource is only embedded once:

private imageCache = new Map<string, PDFImage>()
private pdfFontCache = new Map<string, PDFFont>()

For multi-page documents, pages can be rendered in parallel while keeping CTM state isolated per page:

const pagePromises = templates.map((template, index) => {
  return Promise.resolve().then(() => {
    this.ctmPerPage.set(page, initialCTM)
    this.ctmStackPerPage.set(page, [])
    this.handleObjects(template.objects, page, pageHeight)
  })
})

await Promise.all(pagePromises)

The exporter also records timing information for each phase:

type PdfExportTimings = {
  preloadMs: number
  drawMs: number
  saveMs: number
  totalMs: number
  bytes: number
}

That makes it easier to tell whether a slow export is caused by resource loading, object rendering, or final PDF serialization.

Results

For a typical design containing text, shapes, images, and gradients, the difference looks roughly like this:

Metric Raster PDF Vector PDF
File size around 2.5 MB around 800 KB
Selectable text No Yes, unless text-to-path is enabled
Infinite zoom without blur No Yes
Export time around 1 second around 3-5 seconds
CMYK print workflow No Yes

When text-to-path is enabled, file size usually increases by about 30-50%, but the exported PDF becomes independent of installed fonts.

Takeaways

Building real vector PDF export in the browser is possible, but the difficult parts are not the PDF file creation itself. The hard parts are all the details around visual fidelity:

  • Matching Fabric.js coordinates to PDF coordinates.
  • Tracking CTM state through nested transforms.
  • Converting SVG paths, especially elliptical arcs.
  • Handling text as either fonts or glyph outlines.
  • Supporting gradients and CMYK color spaces.
  • Keeping export work off the main thread.
  • Avoiding duplicated resources in multi-page documents.

For YFT Design Pro, this approach gives us browser-only PDF export that is much closer to what users expect from a desktop design tool: smaller files, crisp vector output, optional font-safe text outlines, and print-oriented CMYK support.

YFT Design Pro is an open-source online design editor built with Fabric.js and Vue 3. It supports multi-page editing, vector PDF export, SVG export, and print-focused workflows.

AI Tools vs. Agentic Systems: What Developers Need Now

The Generation Gap Nobody Is Talking About

In 2024, McKinsey’s State of AI report documented something practitioners had already started feeling in their codebases: organizations were moving beyond using AI as a productivity tool and embedding agentic systems into core business processes, representing a fundamental shift in how enterprises deploy artificial intelligence (McKinsey, 2024). That sentence is easy to read past. It shouldn’t be.

The gap between “AI as a tool” and “AI as an autonomous orchestrator” is not a feature upgrade. It is an architectural boundary. Developers who treat it as the former will spend 2025 and 2026 rebuilding systems they thought were finished. The comparison worth making is not between two AI products. It is between two fundamentally different mental models for what AI does inside a system.

Approach A: AI as a Productivity Layer

The productivity-tool model is familiar. You send a prompt, you get a response, you pipe that response somewhere useful. The human remains the orchestrator. The LLM is a fast, capable assistant that handles discrete tasks: summarizing a document, drafting a reply, classifying an input.

This model works. It has delivered real value. The problem is not that it is wrong – it is that it has a ceiling. Every workflow built on this pattern requires a human decision point at each junction. The system cannot reroute itself when a step fails. It cannot spawn a sub-task to gather missing context. It cannot decide that the original goal needs reframing based on what it found halfway through.

Constraint handling is also brittle at this layer. I spent a week trying to get a classifier to output exactly three sentences. The prompt said “EXACTLY 3 sentences. Not 2, not 4. Three.” It still wrote four. The fix was not better instructions. It was stronger constraint language: “CRITICAL: This is a hard technical constraint enforced by automated validation. If you write 4, the output will be rejected. Count your sentences before outputting.” LLMs do not treat polite instructions the same as system constraints. Every system prompt I write now uses emphatic constraint blocks for hard output requirements. That lesson came from the productivity-tool era, and it carries forward – but it also illustrates the ceiling. You are constantly engineering around the model’s defaults rather than designing a system that handles its own failure modes.

Approach B: Agentic Architecture

The agentic model inverts the relationship. The developer defines goals, tools, and boundaries. The system decides how to reach the goal, which tools to call, in what order, and what to do when a step returns an unexpected result.

Frameworks like CrewAI and LangChain make this concrete. A CrewAI crew assigns roles to multiple reasoning nodes, each with a defined specialty and a set of callable tools. The orchestrator node does not just pass prompts sequentially. It reads intermediate outputs, decides whether the result is sufficient, and either proceeds or delegates a corrective sub-task. LangChain‘s agent abstractions handle tool-calling loops natively, so the pipeline can call an API, parse the result, decide it needs a second API call with different parameters, and complete the loop without a human in the middle.

Model Context Protocols (MCPs) extend this further. An MCP defines a structured interface between a reasoning engine and external systems, so the agent knows not just that a tool exists but what it expects, what it returns, and how errors surface. This is what makes autonomous workflows actually reliable rather than theoretically possible. We documented some of the security considerations this introduces in our piece on AI agent permission blind spots – worth reading before you give an agent write access to anything.

What ForgeWorkflows calls “agentic logic” is this pattern: a reasoning node that holds state, evaluates intermediate results, and routes its own execution path. The difference from a prompt chain is not cosmetic. A prompt chain breaks when step three returns garbage. An agentic pipeline catches that, retries with a different approach, or escalates to a human with a structured error report.

When to Use Which: Practical Guidance

The productivity-tool model is the right choice when the task is genuinely discrete, the output feeds a human decision, and the cost of a wrong answer is low. Drafting a first-pass email, summarizing a meeting transcript, generating a code comment: these do not need an agent. Adding one creates overhead without benefit.

Agentic architecture earns its complexity when three conditions are present. First, the workflow has branching logic that depends on intermediate results. Second, the system needs to interact with multiple external tools or APIs in a sequence that cannot be fully predetermined. Third, the cost of a failed run is high enough that self-correction matters more than simplicity.

A practical test: if you can write the full decision tree on a whiteboard before running the system, a prompt chain probably suffices. If the decision tree has nodes that say “depends on what the API returns,” you need an agent. The branching is not a bug in your planning. It is a signal about the problem’s actual structure.

One honest limitation: agentic systems are harder to debug. When a prompt chain fails, you know which step broke. When an agent fails, the reasoning path that led to the failure may not be logged in a way that makes the root cause obvious. Investing in structured logging at every tool-call boundary is not optional – it is the only way to maintain the system after you ship it. We covered some of the practical setup patterns for this in our lessons from building AI agents fast in 2026.

The Skill Set That Actually Matters Now

Prompt engineering is not going away. It is becoming a lower layer of a larger stack. The developers who will build the systems that matter in the next two years are the ones who understand how to compose agents, define tool interfaces, write constraint blocks that actually hold, and design failure modes before they encounter them in production.

Practical fluency with CrewAI, LangChain, and MCP design is the new baseline, not a differentiator. What ForgeWorkflows calls a “modular swarm” – a set of specialized agents that can be recombined for different task configurations – is the architecture pattern worth internalizing. Not because it is novel, but because it is the pattern that survives contact with real organizational complexity.

The McKinsey finding from 2024 is not a prediction. It is a description of what is already happening in the organizations that will set the competitive baseline for everyone else. The question is not whether to engage with agentic architecture. It is how fast you can build the judgment to do it well. If you want to see how these patterns translate into deployable automation, the full blueprint catalog shows what production implementations of these ideas actually look like.

What We’d Do Differently

Start with the failure modes, not the happy path. Every agentic system I have built that caused problems in production failed because I designed the success path first and bolted on error handling afterward. The next build starts with: what does this agent do when the tool returns a 429, when the LLM output fails validation, when the upstream data is missing a required field? Designing those branches first changes the architecture in ways that matter.

Treat constraint language as a first-class engineering concern, not a prompt afterthought. The classifier lesson above applies everywhere. If your system has a hard output requirement, the constraint block in the system prompt needs to read like a technical specification with consequences, not a polite request. I would build a constraint-block template and enforce its use across every system prompt in the pipeline from day one.

Resist the urge to make the first agent do everything. The instinct when you discover what agentic systems can do is to build one agent that handles the entire workflow. That agent becomes unmaintainable within weeks. The better build is three narrow agents with clean interfaces between them. Narrower scope means faster debugging, easier replacement, and the ability to swap one component without touching the others.