6G yolunda büyük adım: Japon araştırmacılar 560 GHz’de 112 Gbps hıza ulaştı
 Japon araştırmacılar, “mikrocomb” tabanlı yeni bir kablosuz iletişim sistemi geliştirerek 560 GHz bandında saniyede 112 gigabit veri aktarım hızına ulaştı.

 Mert
Japon araştırmacılar, “mikrocomb” tabanlı yeni bir kablosuz iletişim sistemi geliştirerek 560 GHz bandında saniyede 112 gigabit veri aktarım hızına ulaştı.
 Sosyal medya platformu X, kullanıcıları ücretli doğrulama sistemine yönlendirecek yeni bir adım attı. Artık mavi tik sahibi olmayan kullanıcılar günde sadece 50 gönderi ve 200 yanıt paylaşabilecek.
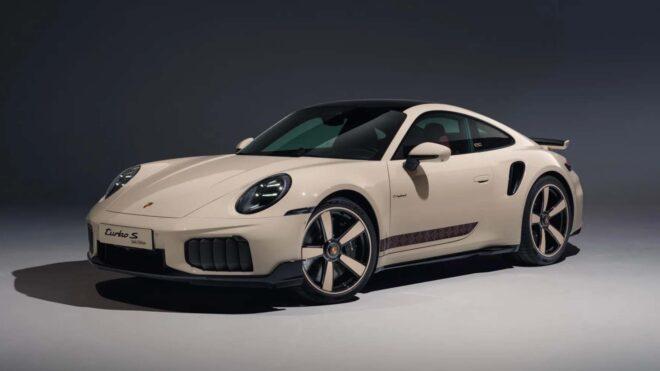
 Porsche, Kuveyt’teki 70. yılını “Porsche 911 Turbo S Sadu Edition” adını verdiği özel bir modelle kutluyor. “Porsche Exclusive Manufaktur” imzalı araç, “Cremewhite” olarak isimlendirilen krem renkte geliyor. Hem içinde hem de dışında Arap dokuma sanatı Al Sadu’dan ilham alınarak hazırlanan detayların yer aldığı 710 beygirlik modelin sınırlı sayıda üretileceği açıklanıyor. Henüz fiyatı paylaşılmayan Sadu Edition, Kuveyt’teki zenginlerin satın almak için sıraya gireceği bir model olabilir.
Özel model “Porsche 911 Turbo S Sadu Edition” görücüye çıkarıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

submission for the Hermes Agent Challenge
A few months ago I drew a maturity ladder for CLAUDE.md files — does the file exist, are constraints explicit, do skills load on demand. Useful for self-locating, and the ladder generalizes past Claude — CLAUDE.md, AGENTS.md, .cursorrules, Copilot instructions all live on the same rungs.
After a lot (lot lot lot) more time spent with these setups, the ladder is built on a different, broader axis than I first drew it on: the channel each rung runs on.
The new ladder
| Level | Name | What’s added | Channel |
|---|---|---|---|
| L0 | System | System prompt only | attention |
| L1 | Primer | One instruction file (CLAUDE.md, AGENTS.md, .cursorrules) |
attention |
| L2 | Composite | Multiple files — user defaults, project overrides | attention |
| L3 | Scoped | Path-scoped rules (.claude/rules/*.md) |
attention |
| L4 | Delegated | Skills — procedures invoked on demand | attention |
| L5 | Abstracted | Sub-agents — child contexts called by the parent | attention (interface) |
| L6 | Governed | Hooks, MCP gates, deny-permissions | enforcement |
| L7 | Adaptive | Self-improving skills written by the agent | self-writing |
Two cuts split the ladder: one between L5 and L6 (soft to hard), one between L6 and L7 (read to write). I’ll use attention and soft channel interchangeably from here, and the same for enforcement / hard channel.
A quick tour
L0 (System) is the cold start: the model with whatever the vendor injected, nothing else.
L1 (Primer) is your single root file — the entry every model sees first.
L2 (Composite) is the moment you split user-level config from project-level: ~/.claude/CLAUDE.md vs ./CLAUDE.md, or your global Cursor settings vs a project .cursorrules.
L3 (Scoped) introduces path scoping — the rule about Python tests only loads when the agent touches tests/*.py.
L4 (Delegated) is skills, which let you ship procedures the agent can pull on demand instead of dumping every workflow into the root file.
L5 (Abstracted) is sub-agents — child processes with their own context, called by the parent for a focused subtask. The child’s reasoning runs in its own context window, separate from the parent’s. What flows back is the result, which re-enters the parent as a new source. The parent–child interface is on the soft channel; the child’s internal work runs on its own soft channel, not the parent’s.
L0 through L4 share one context — they all compete for the same finite slot against the user’s prompt and the recent diff. L5 spawns a second context but couples to the parent on attention. Together that’s the soft channel — attention dynamics, by another name.
L6 (Governed) is where it profoundly changes. Hooks are not in the model’s context window. A PreToolUse hook that blocks git push on a non-zero pytest exit doesn’t get downweighted by a long task. An MCP server that requires authentication before reading a file doesn’t depend on the model remembering your auth rule. Deny-permissions in .claude/settings.json for .env and .pem files don’t compete with the rest of the spec. L6 is enforcement — outside the context dynamics, deterministic, not subject to load or context rot.
L7 (Adaptive) is different again. The agent writes its own instructions — not because the user said “remember this,” but because the agent finished a task and decided some part of the trajectory was worth saving for next time. At read time the artifact lands in the attention channel like anything else. What’s different is the writer: the model wrote the file, the trigger was task completion, and the user never saw the prompt that produced it. L7 is self-writing.
That’s the ladder.

Two cuts under the ladder: attention channel covers L0–L5, enforcement is L6 alone, self-writing is L7 alone. Cut 1 at L5/L6 marked soft to hard. Cut 2 at L6/L7 marked read to write.
The first cut: L5 / L6
The load-bearing observation in this reframe is the cut between L5 and L6.
L0 through L5 all run on the soft channel — either directly on the parent’s field (L0–L4) or on a child’s that couples back to the parent through prompts and results (L5). They compete. They decay with load. The model can downweight any of them, lose track of any of them, prioritize the user’s prompt over any of them. You can tell a sub-agent “always check tests before reporting done” and it’ll do it 80% of the time, or 95%, or 60% — you don’t know without measurement. The same instruction in a CLAUDE.md and the same instruction passed to a sub-agent are running on the same physics, just on different fields.
L6 is outside that physics entirely.
Generic example. Suppose your CLAUDE.md says “never push without running tests.” That’s L1. The model reads it, integrates it into context, weights it against everything else loaded — your other rules, the recent diff, the user’s prompt. If you have four thousand tokens of instructions and the model is mid-task, that line is competing with everything else for attention. Sometimes it follows. Sometimes it doesn’t.
Now suppose you have a PreToolUse hook on Bash that exits non-zero if pytest fails. That’s L6. The model can decide to push or not push. It doesn’t matter. The push fails before the model’s intent reaches the network.
Same constraint, two channels, two failure modes. Soft channel fails probabilistically. Hard channel fails deterministically. They take different fixes — soft constraints want better content and ordering (the Pink Elephant piece is about that fight), hard constraints want a better hook script, a tighter PreToolUse matcher, or a stricter permission rule.
Calling these the same thing because they’re both “in your .claude/ directory” hides the architectural difference.
The second cut: L7 writes itself
L7 – Adaptive isn’t a third channel exactly — at read time, what L7 wrote lands in the same context with everything else. The cut is at write time. The agent writes its own instructions.
Most “memory” features in shipping agents aren’t L7 by this cut. Claude Code’s saved memory writes when the user signals remember this or accepts a prompt to save. Cursor’s notepads, Copilot’s pinned context, Gemini’s saved facts — same pattern. The agent keeps the artifact, but the user authored it. That’s persistent context, not self-writing. Call it L6.5 if you want a name for it.
The clearest L7 in print today is Hermes Agent, released by Nous Research. The mechanism is documented: when the agent identifies a saveable trajectory — after a successful task with five or more tool calls, after recovering from errors and finding a working path, after the user corrects its approach, or after discovering a non-trivial workflow — it invokes its skill_manage tool to extract a SKILL.md (markdown with YAML frontmatter) into ~/.hermes/skills/. Future sessions load the skill automatically and it becomes available as a slash command. The user didn’t ask for it. The agent decided the trajectory was worth saving.
Three of the four triggers are what make this clearly L7 and not L6.5. Error recovery, user correction, novel-workflow discovery — these are cases where only the agent knows the saveable moment happened. A user-driven memory feature can capture “this task was useful enough to want it remembered” by asking the user after the fact. It can’t capture “I tried three approaches and the third worked” unless the agent volunteers it. The artifact format matters too: an auto-extracted SKILL.md lands in ~/.hermes/skills/ in the same format human-written skills use. Next session, the agent loads it and can’t tell who the author was. That symmetry is what makes the loop close — every successful trajectory can shape the next one.
Concretely, here’s what an auto-extracted skill might look like — illustrative, in the shape Hermes’s documented SKILL.md schema specifies, fitting the second trigger (the agent worked through a pytest debugging session, found the working path, and saved the lesson):
---
name: debug-pytest-import-errors
description: When pytest reports ModuleNotFoundError despite a successful editable install, check src-layout configuration before chasing PYTHONPATH.
version: 1.0.0
platforms: [macos, linux]
metadata:
  hermes:
    tags: [python, testing]
    category: dev-workflow
---
# Debug pytest ImportError on src-layout projects

## When to Use
pytest fails with `ModuleNotFoundError` after a fresh clone, even though `pip install -e .` ran and the import works in a Python REPL.

## Procedure
1. Check `pyproject.toml` for `where = ["src"]` under the build-system packages section.
2. Confirm `pythonpath = ["src"]` is set in `[tool.pytest.ini_options]`.
3. Re-run `pip install -e .`; confirm `.egg-info` lands at the package root, not inside `src/`.

## Pitfalls
- `PYTHONPATH=src` as an env var works locally but doesn't survive CI.

## Verification
`uv run pytest` runs without `ModuleNotFoundError`.
The frontmatter is functional — tags and category route the skill in Hermes’s index; platforms gates it by OS. The body’s When to Use / Procedure / Pitfalls / Verification is the schema’s recommended shape. Notice what the agent saved: not the original failing command, not the dead-ends, just the working path plus the trap that would have lured a next session into chasing PYTHONPATH. That’s curation, not transcription.
This is why L7 is safe to leave unsupervised in Hermes and risky most places else. The SKILL.md schema enforces moves a well-coupled instruction needs — imperative voice, directive ordering, named constructs, the warning placed after the working path rather than before it. A free-form memory feature has no such structural prior; the agent writes whatever feels worth saving, and the writes degrade as the agent’s writing discipline does.
Schema is the cheap version of supervision.
The new failure mode is the self-writing layer running unsupervised. An auto-extracted skill that overfits to one project. A trajectory summary written under a stale assumption that surfaces six weeks later as a phantom instruction. There’s no rule file the user authored to grep for the source — the rule is in a markdown file the agent wrote and the user never read, sitting in ~/.hermes/skills/ or its equivalent.
L7 doesn’t replace L0–L6. It runs alongside, with its own writes and its own decay. Most agent setups don’t have it because most agents don’t expose it. The ones that ship a memory feature mostly do L6.5 and call it L7.
When to climb
The dominant pattern I see in real repos is L1 with a thin L6: a CLAUDE.md, maybe a few rule files at L3, deny-permissions for .env. L4 (skills) is rare — most authors haven’t built any. L5 (sub-agents) is rarer — most use cases haven’t surfaced. L7 is mostly absent — most agents don’t expose a self-writing surface, and the few setups that do have one running treat it as opt-in defaults nobody reviewed.
Across 28,721 public repositories with AI configs, 89.9% don’t name specific constructs in their instructions — no backticks, no file paths, no function names. That’s most of the soft channel running at low coupling: easily downweighted, easily lost. The hard channel is thinner. The adaptive channel is mostly absent.
Large spec, small contract, no adaptive layer. That’s the asymmetry — but it’s not always a bug. Each rung exists because the rung below it fails in a specific way. The trigger is the failure, not a feature wishlist.
| From | To | Symptom that triggers the climb |
|---|---|---|
| L0 | L1 | Re-explaining the same project context every session |
| L1 | L2 | One file got long enough that important rules get ignored |
| L2 | L3 | Path-irrelevant rules pollute every task |
| L3 | L4 | The same procedure gets described inline across multiple rules |
| L4 | L5 | A procedure pollutes the parent’s context with reasoning chains the parent doesn’t need |
| L5 | L6 | A constraint must hold 100% of the time, not 95% |
| L6 | L7 | You keep correcting the same preference across sessions |
| L6 | L7 | You keep watching the agent re-derive the same workaround |
The mistake is climbing without the symptom. A repo with three rules in one file doesn’t need L3. A solo developer’s CLAUDE.md doesn’t need a sub-agent. Premature climbs cost context budget for no return; you’ve added structure the model has to navigate without solving a problem you actually had.
The opposite mistake is more common: under-building the higher rungs because the symptoms feel like model failures rather than rung failures. “The agent didn’t run tests before pushing” reads like a prompt-engineering problem; it’s a missing L6. “The agent forgot we use Cloudflare Workers” reads like context drift; it’s a missing L7. “The agent keeps describing the deploy process every time I ask” reads like verbosity; it’s a missing L4.
Climb when the rung below stops working.
Three questions for your repo
Not a recipe. A diagnostic. For any rule in your setup, ask:
Most rules answer silently / sees / yes. That tells you which channel you’re in. The interesting question is whether anything in your setup is on the other channels at all.
A note on related taxonomies
There are other progressive ladders for AI agent setups in print. Vellum’s L0–L5 is an autonomy axis — how much the agent decides on its own. Blake Crosley’s 4-tier is a concurrent-decomposition axis — how many agents run in parallel. Anthropic’s 5-layer ADK frame for Claude Code is a content-boundary axis — what kind of content goes where. Zylon’s 5-architectural and GitHub’s 3-tier carve different cuts again, mostly around how the agent is wired into a product surface.
The ladder above is on a different axis from any of those. It sorts by the channel each mechanism runs on — soft attention, hard enforcement, self-writing memory — and progresses through the named constructs an agent exposes (CLAUDE.md, scoped rule files, skills, sub-agents, hooks, auto-memory). The two cuts (L5/L6 and L6/L7) are the load-bearing claim; the autonomy and concurrency taxonomies don’t draw those cuts because they’re sorting on different things.
Different axis, different cuts, different diagnostic. Use whichever maps onto the question you’re actually asking.

Terminal output: ails check on a .claude directory. LADDER reads 8 rungs across 3 channels. SETUP reads L1 + L3 + L6 (Primer, Scoped, Governed). Channel/Levels/Count table shows attention L0–L5 count 5, enforcement L6 count 1, self-writing L7 count 1. Cuts named at L5/L6 soft→hard and L6/L7 read→write.
*Previously: CLAUDE.md Best Practices: From Basic to Adaptive — where I drew the ladder the first way. The State of AI Instruction Quality for additional data.
I’m building Reporails, measurement for the attention channel. npx @reporails/cli check runs locally, no account needed.*
Armorer v0.1.19
We have been building Armorer as an experimental local control plane for AI agents.
Getting one agent demo working is usually not the hard part. The harder part is everything right after that: provider configuration drift, Docker or Colima state, partial installs, failed runs, and figuring out what actually changed between attempts.
So Armorer is not another agent framework. It is our attempt at a local ops layer for agents: install them, configure them, run them, supervise jobs, and recover when setup or runtime goes sideways.
What changed in v0.1.19
Repo: https://github.com/ArmorerLabs/Armorer
It is still experimental, so we care a lot more about honest feedback from people already running local or self-hosted agent workflows than about pretending the product is finished.
Drafted for the GitHub Copilot Challenge (opens May 21). Will add the official
devchallengetag once the challenge announcement is live.
For the last 18 months I have been running a small one-person open-source program: meaningful PRs across Anthropic, OpenAI, Google, Microsoft, NVIDIA, AWS repos, plus 20-something smaller projects in the MCP and LLM tooling space. The math gets bad fast. You cannot keep 40 repos warm in your head; the cost of context-switching is what kills throughput, not the typing.
GitHub Copilot CLI is the one tool that has actually moved that number for me. Not for writing code: I write most of the code by hand. For navigating code I have never seen before in repos I have just cloned. Below is the workflow that survived two iterations and the prompts I keep coming back to.
The triage loop
When a triage candidate comes in (an issue I tagged earlier, a thread I bookmarked, a TODO I left in a fork), I run roughly this sequence:
# 1. Fast skim: what is this repo, where is the meat?
gh copilot suggest "explain the architecture of this repo from the top-level dirs"

# 2. Locate the file the issue is about, without grepping for an hour
gh copilot suggest "where is the streaming response handler in this repo?"

# 3. Once the file is in front of me, ask copilot to make sense of the
# function I am staring at, not in general but specifically
gh copilot explain "this function" -- src/streaming/handler.py:412-510

# 4. Stage a small, surgical patch and have copilot sanity-check it
gh copilot suggest "review this diff for correctness and side effects"
Three prompts and a diff review is what 80% of my PRs look like in practice. The remaining 20% are the ones where Copilot is wrong (or I am) and I have to slow down. Those are the PRs that ship the most value.
What Copilot CLI is genuinely good at
Mapping a repo I have never read. I ask “what does this repo do” and get a 6-line summary that is correct often enough to be load-bearing. Saves the 20 minutes of skimming I used to do.
Pointing at the right file by description. “Where is the rate limiter implemented?” gets me a path in seconds. The path is right 9 times out of 10. The one time it is wrong, the wrong path is at least adjacent, and that adjacency is itself a clue.
Translating between languages I do not have in working memory. I ship to Python, TypeScript, and Rust regularly. I can write all three fluently but I context-switch slowly. gh copilot suggest "what is the TypeScript equivalent of this Rust pattern" lets me carry an idea between languages without re-reading the syntax for ? operator semantics for the seventh time.
Generating the boring 80% of a CI workflow. GitHub Actions YAML is one of the worst per-keystroke languages I know. Copilot CLI gives me a YAML that is right enough to commit and tweak. The first version is rarely the final version, but it is closer than mine would have been from a blank file.
What it is not good at
Anything that needs to reason about cross-file state. Copilot CLI sees one snippet at a time. If your refactor touches three files and the question is “what breaks downstream,” ask a human or a tool with broader context.
Telling you which of two patches is better. I asked Copilot to evaluate two patches I had written against the same issue. It picked the worse one, because the worse one looked tidier in the diff. Aesthetic correctness, not behavioral correctness. Copilot is great for shape, bad for taste.
Replacing your understanding of the codebase. This is the trap. The first month I used Copilot CLI for triage, I shipped a PR that touched a part of the codebase I had not actually read. The review caught it. I have not made that mistake since, and I will not get away with it again. Use Copilot to find the code; do not use Copilot to avoid reading the code.
Concrete win: a 47-second triage
The fastest triage I have had was an open issue on a popular Python MCP SDK. Repo new to me. Issue: a streaming handler dropped final tokens occasionally.
gh repo clone foo/bar && cd bar
gh copilot suggest "where is the streaming response chunked"
# -> src/forem/streaming.py
gh copilot explain "the early-return condition in chunk_iter()" -- src/forem/streaming.py:204-244
# -> "Returns when chunk size is 0, but the producer also emits empty
#     keepalive chunks; the early return ends the stream prematurely."
# Fix:
sed -i 's/if not chunk:/if chunk is None:/' src/forem/streaming.py
gh copilot suggest "write a regression test for keepalive empty-chunk handling"
# -> generates a test that I keep and edit
git checkout -b fix/keepalive-chunks
git commit -am "Don't end stream on empty keepalive chunks"
gh pr create
The PR took 47 seconds to draft. The review took two days. The fix was right.
This is the workflow that the CLI unlocks. Not “write my code for me.” It is “tell me where to look so I can spend my brain on the thing only I can do.”
Three habits that took me three months to learn
Always confirm the path before reading. gh copilot suggest "where is X" is fast and confident, but it can be wrong. Type the path it suggests into your editor and check the file actually contains what you expect. Two-second sanity check.
Quote real code into the prompt. “Explain this function” is mediocre. “Explain the early-return at line 204” is targeted. The narrower the prompt, the more useful the answer. Copy-paste the line of code into the prompt; do not summarize it.
Treat the first answer as a hypothesis. Copilot will hand you something confident-sounding. The right move is to verify, not to trust. The fastest verifier is the test that should fail before your fix and pass after.
What I still want
A “show me the three places this function is called” command. I know I can gh copilot suggest for it, but a first-class command for cross-file context is the gap between “useful triage tool” and “real refactor partner.” If GitHub ships that, I will retire grep -R for half my workflow.
If you are doing OSS contributions across many repos and have not tried gh copilot suggest for repo-mapping, install it once and run it once. It is one apt-install away on Ubuntu, one brew-install on Mac.
gh extension install github/gh-copilot
gh copilot suggest "what is this repo about"
If it sticks, the rest of this post is the playbook.
Happy triaging.
Submission for the Gemma 4 DEV Challenge, Build track. Companion to my Write-track post on the five libs behind it.
What it is
A tool-using research agent that runs locally on Gemma 4 e2b via Ollama, in around 200 lines of Node.
You give it a question. It picks between two tools, reads a Wikipedia page, then returns a structured JSON answer with sources. No API key. No rate limit. Two GB of RAM and an Ollama instance is the whole stack.
ollama pull gemma4:e2b
git clone https://github.com/MukundaKatta/gemma4-safe-agent
cd gemma4-safe-agent && npm install
npm run demo -- "What is RLHF?"
{
  "final": "RLHF is a technique that uses human preferences as a reward signal to fine-tune language models.",
  "sources": ["https://en.wikipedia.org/wiki/Reinforcement_learning_from_human_feedback"],
  "steps": 2
}
Repo: github.com/MukundaKatta/gemma4-safe-agent
Why Gemma 4 e2b specifically
Gemma 4 ships in four sizes: e2b and e4b for edge and mobile, a 26B Mixture-of-Experts model, and a 31B dense model for servers. I picked e2b on purpose.
Reasons:
GEMMA_MODEL=gemma4:e4b.The same agent runs against any of the four Gemma 4 variants with one env var change.
How it works
The whole agent is a small loop:
for (let step = 0; step < MAX_STEPS; step++) {
  const fitted = fit(messages, { maxTokens: 4096, preserveSystem: true, preserveLastN: 2 });
  const raw = await ollamaChat(fitted.messages);
  const action = parseAction(raw);

  if (action.kind === 'tool') {
    const result = await TOOLS[action.tool].fn(action.args);
    messages.push({ role: 'assistant', content: raw });
    messages.push({ role: 'user', content: `tool_result: ${result}` });
    continue;
  }

  return cast({ llm, validate, prompt: 'Restate as JSON: ...' });
}
The whole run is wrapped in an agentguard.firewall block. Each tool is wrapped with agentvet.vet and agentsnap.traceTool. That gives me:
fetch_url({ url: 12345 }) never runsI wrote about the scaffolding in detail in the Write-track companion post. Here the focus is the agent and the demo.
What you can run
The repo ships three entry points:
npm run demo -- "...": real run against your local Gemma 4 e2bnpm run demo:mock: same agent, with fetch_url returning canned pages (no internet needed)AGENT_MOCK=1 node examples/run-stub.js: deterministic stub LLM in place of Gemma 4, so the whole pipeline runs in CI without any model at allThe third one is the one I use for snapshot regression tests. It proves the agent’s tool-use behavior is stable even with an LLM swapped out.
What surprised me
Two things.
Gemma 4 e2b picks the right tool more often than I expected. The model is small but the tool-selection task is well-bounded (“you have these two tools, here’s the schema, return one JSON”). When the surrounding scaffolding catches arg mistakes and JSON glitches, the model’s reasoning is the part that doesn’t need help.
The final-answer step is where the model really needs the cast loop. Asking for “JSON only, no prose” still produced Sure here you go: {...} enough of the time that I would not trust the agent without agentcast wrapping that step. With it, the post-condition becomes a guarantee.
Try it
Repo: github.com/MukundaKatta/gemma4-safe-agent (MIT)
Issues and PRs welcome. The five scaffolding libs are all on npm under @mukundakatta/* and are zero-dep, so you can pull them into your own Gemma 4 projects one at a time.
If you build something on top of this, drop me a link.
Have fun with Gemma 4.
Drafted in anticipation of the Google I/O 2026 Writing Challenge. Will add the
devchallengeand challenge-specific tags once the announcement is live on May 19.
I/O week is the one week of the year where my GitHub feed and my coffee maker are equally caffeinated. This year the announcement I cared about most was Gemma 4, the new family of open models from Google. By Friday I had gemma4:2b and gemma4:4b running on a laptop via Ollama, a small research agent loop, and a handful of tiny libraries I had been meaning to ship anyway.
Here is what I shipped, why I shipped each piece, and what I learned about running a 2B-parameter open model as the brain of a real agent.
The headline: 2B is enough if the scaffolding is right
Pointing a 2B-parameter model at “answer this question, use tools when you need to, return JSON” goes badly without scaffolding. The model wraps JSON in markdown fences. It hallucinates tool args. It drops a required field. Each of those is a separate failure mode, and each one has a clean, small fix.
The agent I built is around 200 lines of code. The five libraries it depends on are around 200 lines each. Total surface area is small enough that I can hold the whole thing in my head and stick a debugger into any of it.
Concretely, on the question “What is RLHF?”, the agent:
gemma4:2b returns a structured plan).fetch_url to read the Wikipedia page).Steps 4, 5, and 6 are the load-bearing ones. Without them the 2B model is a toy. With them it is a useful tool that runs on a laptop with no API key and no rate limit.
The five small problems and the five small fixes
Problem 1: Output drifts
Gemma 4 will return JSON wrapped in json ..., sometimes with a trailing comma, sometimes prefixed with “Sure, here you go:”. I built a three-pass repair: strip fences, extract the largest balanced JSON object, remove trailing commas. Then validate against a schema. If validation still fails, hand the model a short hint and retry once.
The hint is the trick. Small models self-correct beautifully when you tell them precisely what was wrong. They do not self-correct on “invalid JSON, please try again.” Give them the field name and the constraint.
Problem 2: Tool args go wrong
When the 2B model picks a tool, it sometimes picks args that violate the schema you sent it. The fix is to validate every tool call before running it. If validation fails, do not run the tool. Feed the validation issues back to the model as the tool’s response. The model gets exactly the structural complaint it needs to correct on the next turn.
This catches three classes of bugs: wrong types (string where number was wanted), missing required fields, and extra fields the schema does not permit. All of them happen with smaller models. None of them happen if you validate first.
Problem 3: The agent can wander to the wrong domains
Once the model can pick URLs to fetch, you have handed it URL-picking power. That is not always what you want. A naive prompt-injection attack can convince a small model to fetch from an attacker-controlled domain.
The fix is the smallest piece in the stack: a declarative domain allowlist. Set it to the three or four hosts the agent legitimately needs. Block everything else with an actionable error. The model never gets to wander.
Problem 4: Context budget gets tight
Gemma 4 advertises 128k tokens but the practical throughput window is much smaller. Bounded chat histories matter. The fix is anchored truncation: always preserve the system message at the top and the trailing user turn at the bottom. Drop the middle when the total goes over budget.
DropOldest is the right default. DropMiddle is a reasonable alternative if you want to keep both early grounding context and recent turns. Both keep the load-bearing pieces of the prompt.
Problem 5: You will regress, and not notice
You tweak a system prompt. The agent picks a different tool order. Sometimes that is fine. Sometimes it is a regression that breaks the deployed app. By Friday afternoon.
The fix is a snapshot test. Record one agent run end-to-end as a JSON trace. First test run writes the snapshot. Every subsequent run compares against the snapshot and fails with a unified diff if anything diverges. Refresh the snapshot when the change is intentional. Five lines per test.
Why “small open model + scaffolding” matters
The pitch for big closed models is that they hide all of these problems for you. The pitch for small open models is everything else: latency, cost, privacy, offline-ness, the ability to fine-tune. The five problems above are the price of admission for the latter.
The good news is that each problem is small and each fix is small. The combined scaffolding is around 1000 lines of code, MIT-licensed, distributed as separate libraries you can adopt one at a time. You can swap any one of them for your own implementation without the rest noticing.
The whole loop in 20 lines
let messages = build_messages(question);
let fitted = Fitter::new(8_000).fit(messages, Strategy::DropOldest);

let raw = call_gemma4_via_ollama(&fitted, &tap).await?;
let action = action_caster.parse(&raw)?;

if action.kind == "tool" {
    let v = tool_validator(&action.tool)?;
    v.validate(&action.args)
        .map_err(|e| anyhow::anyhow!(e.for_llm()))?;

    // Egress allowlist before any fetch
    if let Some(url) = action.args.get("url") {
        allow.check(url.as_str().unwrap())?;
    }
    run_tool(&action).await
} else {
    Ok(action.text)
}
That is the whole thing. The 2B model on the other end. Five small libraries doing the boring work. The result is reliable enough for me to dogfood on local tasks without worrying about the model going off the rails.
What I’m taking away from I/O 2026
Two things, mostly.
Open is having a moment, but only with scaffolding. Gemma 4 (2B) running locally is a real productivity tool once the safety net is in place. Without the safety net it is a demo that breaks the first time a user asks something weird. The community has been quietly building the safety net for a year; pick it up off the shelf.
Local-first lowers the threshold for trying things. I built and tested the loop above without a single API call to a paid endpoint. The whole iteration cycle was free. The thing that would have been three weeks of work on a paid model was three nights of work on Ollama.
If you build something on Gemma 4 this week, the meta-lesson is: do not be afraid to scaffold around it. The model is the easy part. The scaffolding is the part that ships.
Happy I/O week.
For two days, my company laptop kept showing this error:
Your organization has deleted this device.
To fix this, contact your system administrator and provide error code 700003.
At first, it looked like the only option was to disconnect and reconnect my work account from Windows.
I really did not want to do that.
Removing and adding the account again can work, but it is annoying. You may need to re-authenticate apps, reconnect services, and deal with device registration again.
Luckily, there is a better option.
The command that fixed it
Open a terminal and run:
dsregcmd /forcerecovery
After running the command, Windows asks you to sign in again with your work account.
That is it.
In my case, after logging in again, everything started working without disconnecting all accounts manually.
It saved me a lot of wasted time.
When this helps
This can help when:
700003
A small warning
This is not magic.
If your device was intentionally removed by IT, or your company uses Intune, Autopilot, Conditional Access, or Hybrid Join, talk to your administrator first.
🔖 Stay ahead of the dev curve
I created a Curated RSS Feed Bundle for Web Developers — a hand-picked OPML file of the best dev blogs and websites on the internet.
💡 Just download, import into your favorite RSS reader (like Feedly or NetNewsWire), and enjoy fresh insights every day.
👉 Grab it on Gumroad — stay sharp without the noise.
The PCI Security Standards Council ended the 4.0 transition window on March 31, 2025, and 2026 is the first full enforcement year under PCI DSS v4.0.1. That changes how fintech teams should be interviewing angular developers for fintech roles. The old “build a CRUD app with auth” coding round won’t surface whether a candidate has shipped Angular code in a regulated environment.
Most engineering leads still interview the way they did pre-update. They probe RxJS knowledge, ask about signals versus zone.js, and maybe a question on lazy loading. Then they hand the new hire a transaction-dispute screen that touches PII and PAN data, and hope for the best. The interview rubric for angular developers for fintech roles needs to change.
That gap shows up later. It shows up during a SOC 2 readiness review, or when the breach forensics team finds an access token sitting in localStorage. According to IBM’s Cost of a Data Breach Report, the financial sector averages $5.9 million per incident, with detection windows still hovering near 200 days.
If you’re planning to Hire Angular Developer talent for a regulated codebase, the five questions below pull the technical interview onto ground where compliance gaps actually surface. Each one tests whether the candidate has shipped real fintech work, not whether they can recite the Angular docs.
Question 1: How Do Angular Developers for Fintech Handle Session Tokens and OAuth 2.0?
The wrong answer here is some version of “we put the JWT in localStorage and add it as a Bearer header in an HTTP interceptor.” That’s textbook, and it’s also the pattern that turns a single XSS bug into a session-takeover incident.
A candidate who’s shipped Angular code in a regulated stack will walk you through HttpOnly, Secure, SameSite=Strict cookies for the refresh token, with short-lived access tokens held in memory and rotated on every refresh call. They’ll mention PKCE for public clients, the OAuth 2.0 authorization code flow over implicit, and silent renewal patterns. They’ll know that storing anything sensitive in sessionStorage is functionally identical to localStorage from an XSS perspective.
Push them further. Ask how they’d revoke a token mid-session if a SOC analyst flags suspicious activity. Strong angular developers for fintech will sketch out a backend revocation list, a forced re-auth route guard, and a BehaviorSubject-driven auth state that propagates the logout across all open tabs within seconds.
This question maps to PCI DSS v4.0.1 Requirement 8 (access control) and the GLBA Safeguards Rule.
Question 2: Setting Up CSP and Trusted Types in an Angular Fintech App
Most candidates have heard of Content Security Policy. Far fewer have actually configured it in a real Angular build pipeline used by angular developers for fintech work.
Walk them through your current index.html. Ask what they’d remove. The answer should include a hard “no” on unsafe-inline and unsafe-eval for script-src, and a nonce-based approach where the nonce gets injected per-request from the server, then bound to Angular via the ngCspNonce attribute or the autoCsp workspace option.
The follow-up matters more. Ask about Trusted Types. A senior candidate will explain that Trusted Types enforce safer coding patterns at the DOM API level, blocking innerHTML and similar sinks unless the value passes through a policy. They should mention that Angular’s DomSanitizer plays well with Trusted Types, and that bypassSecurityTrustHtml calls in a fintech codebase should be treated like a git blame lookup waiting to happen.
If they mention CSP violation reporting endpoints and tuning the policy from real production traffic, hire them. Angular developers for fintech work who know this pipeline end-to-end are scarce, and they’re the difference between a PCI DSS Requirement 6 sign-off and a remediation cycle.
Question 3: What Does a Frontend Audit Trail Look Like in Regulated Code?
This one separates candidates who’ve worked in regulated codebases from those who haven’t.
A frontend audit trail isn’t console.log(“user clicked transfer”). It’s a structured event stream that fires on specific user actions, carries a correlation ID, ties the event to a session, and never logs PII or PAN. Senior angular developers for fintech roles know to pipe these events to a dedicated logging endpoint over HTTPS, not the same telemetry pipeline used for performance metrics or marketing analytics.
Ask what they’d log when a user initiates a wire transfer. The strong answer covers: timestamp, user ID (not PII), session ID, correlation ID, action type, the route they came from, and the device fingerprint. Never the recipient account number. Never the amount in cleartext if your scope avoids it. Backend systems get the sensitive payload through a separate authenticated channel.
Push on retention. PCI DSS Requirement 10 asks for one year of log retention with 90 days immediately accessible. SOC 2 expects monitoring evidence at the same depth. The SEC pushes this further: the Cybersecurity Disclosure Rule requires material incidents to be disclosed within four business days. Angular developers for fintech work who treat frontend logging as an architectural concern, not an afterthought, are the ones who make that timeline survivable.
Question 4: Keeping Angular Components Out of PCI DSS Scope
The cheapest PCI DSS audit is the one that touches the fewest Angular components.
The right candidate knows scope reduction is an architectural decision, not a code-review fix. Raw PAN should never enter the Angular state tree. Not in a FormControl. Not in a BehaviorSubject. Not in a Redux or NgRx store. Not even briefly.
What replaces it: a hosted-iframe approach using Stripe Elements, Adyen Drop-in, Braintree Hosted Fields, or a similar tokenization-first provider. The Angular app embeds the iframe, listens for a token event, and only ever touches the resulting opaque token. The card data lives in the processor’s PCI-compliant frame; your fintech app gets a string that means nothing to an attacker.
Test the candidate on edge cases. What about a payment-update flow where the user needs to see the last four digits of their stored card? The processor returns those four digits as a separate field; you never reconstruct them. What about a chargeback dispute screen? The processor returns a masked reference; the Angular component renders it but never persists it.
Angular developers for fintech work who understand scope reduction save their employer significant audit fees, because the QSA scoping document gets dramatically shorter. This is the kind of architectural discipline Bacancy’s senior Angular engineers ship by default on fintech engagements, and it’s the difference between a Level 1 assessment that takes weeks and one that drags into the next quarter.
Question 5: Architecting KYC/AML Capture and Consent in the Angular Layer
KYC and AML data flows are where well-meaning Angular code creates expensive compliance debt.
When you’re interviewing angular developers for fintech roles, the candidate should walk you through PII minimization on the frontend. Collect only what the regulator requires, never persist it in localStorage, never pass it as a URL query parameter (it ends up in server logs and Referer headers), and never send it to analytics tools. Mixpanel, Segment, and Google Analytics scripts should be blocked on KYC routes through a per-route CSP override or a separate, leaner SPA bundle.
Consent capture is the second half. Strong angular developers for fintech treat consent as a discrete, server-acknowledged event with its own audit-trail entry. They use granular checkboxes instead of bundled “I agree to everything” toggles, they version the consent text, and they expose a settings page where the user can revoke consent and trigger the GDPR or CCPA data-deletion workflow.
The interview probe: ask what happens when a California user submits a CCPA deletion request mid-KYC. The right answer involves halting the verification flow, surfacing a confirmation modal, hitting a backend endpoint that flags the user record for deletion, and logging the request with a correlation ID. Anything less, and the regulator notice arrives before the next product release.
Conclusion
Compliance failures rarely look like compliance failures during a code review. They look like a stray localStorage.setItem(‘token’, …), an [innerHTML] binding on a dispute-resolution screen, or a PII field accidentally serialized into a debug log. The five questions above pull those gaps into the interview before they become breach forensics.
The hiring bar shifted in 2026. PCI DSS v4.0.1 continuous validation, the SEC four-day disclosure window, and rising SOC 2 expectations mean a single bad Angular hire compounds risk faster than ever. Sourcing angular developers for fintech engagements through a partner with regulated-codebase experience changes the failure mode entirely. If you’re scaling a fintech engineering team this year, partner with an Angular development company that’s already shipped production code under a QSA review. Bacancy’s vetted angular developers for fintech projects know the difference between code that compiles and code that survives an audit.