
DreamZero vs Motus

I. Autoregressive & Bidirectional Unified Generation

DreamZero and Motus are the two most representative works in the field of World Action Models (WAMs). Both conduct joint video + action generation, adopt flow matching, and use chunk-based generation. However, they differ completely in generation paradigms, training mechanisms, alignment methods, and inference logic.

DreamZero adopts autoregressive causal generation (only looks at the past, not the future).

It generates chunk by chunk in chronological order.
It strictly follows causal attention masking.
At each time step, it can only see historical observations, not the future.
It naturally conforms to robots’ physical timing logic.
It is suitable for closed-loop control and real-time inference.

Motus adopts a flexible unified framework (capable of looking at the future, non-causal).

Essentially built on the UniDiffuser-based unified multimodal framework with a bidirectional non-causal underlying architecture, Motus supports switching among 5 task modes.
These include: VLA (action-only generation), WM (video-only generation), IDM (inverse dynamics), VGM (video-guided action), and Video-Action Joint generation.
In video-action joint generation mode, Motus adopts a bidirectional non-causal architecture to generate the entire future video chunk and action chunk in one go, achieving temporal alignment via video sparsification and action densification.
In VLA mode, Motus only outputs actions without generating videos; the video side remains in a pure noise state with no video generation performed.
At this time, there is no bidirectional global modeling, as the video side contains no content for bidirectional interaction.
Its inference relies on the interaction between the action expert and the understanding expert, rather than complete tri-modal joint attention.

TIPS:Architecturally, Motus is bidirectional and non-causal.
Functionally, Motus is a flexible unified framework.
Motus does not adhere to non-causality in all cases. Its default architecture is bidirectional, built on the bidirectional, non-causal UniDiffuser, but causality can be restricted via masking.

II. Chunk-Based Generation Mechanism**

Both use chunks, but their logics are entirely different.

DreamZero: Autoregressive Chunk Generation

Each chunk depends on the output of the previous chunk.
Training uses chunk-wise teacher forcing.
Inference uses KV caching, computing only the current chunk.
Each chunk corresponds to a fixed duration of action.

Motus: Global Bidirectional Chunk Modeling, Multi-Step Denoising Generation

During training: Temporal relationships of all chunks are modeled at once with Tri-model Joint Attention. All frames and action tokens are mutually visible (bidirectional and non-causal), conditioned on real historical observations, and independent of autoregressive generation results.
During inference: Multi-step iterative denoising is performed based on Rectified Flow (as shown in Algorithm 6, where τ gradually decreases from Tτ to 1). The entire future sequence is generated in one pass, not a single forward step.
No autoregressive KV caching: Due to the non-causal architecture, there is no need to maintain historical KV caching as DreamZero does. However, the diffusion denoising process requires multi-step computation, with inference overhead concentrated on global attention calculation within a single step.
Video downsampling alignment is required: Long sequences are generated in one pass, so the video frame rate must match the action frequency (e.g., 1:6 sparsification) to avoid token imbalance.
Suitable for unified modeling, not long-horizon closed-loop tasks.

How Motus Achieves Global Temporal Dependencies

Motus’s global temporal dependencies are not generated step-by-step in chronological order like DreamZero, which only looks at the past. Instead:
The entire temporal sequence of “past, present, future” is fed into the model at once.
It adopts Tri-model Joint Attention, concatenating the QKV of three experts in the attention layer to achieve cross-modal information fusion.
Each expert retains independent feedforward networks and normalization layers. All frames and action tokens are mutually visible and influential, enabling unified modeling of the entire temporal sequence.
It adopts UniDiffuser-style global bidirectional temporal modeling. During training and inference, it processes:
[Initial frames, all future frames to be generated, all future actions to be generated] into a long token sequence, which is fed into the Transformer.
For example:[Historical Frames], [Future Frame 1], [Future Frame 2], [Future Frame 3], [Action 1], [Action 2], [Action 3], [Action 4]
It is not generated frame-by-frame or chunk-by-chunk; instead, the entire temporal sequence is input and modeled at once.
Motus uses Tri-model Joint Attention with a simple rule: all temporal positions are mutually visible, with no causal restrictions.

  • Historical Frames → Can see future frames
  • Future Frames → Can see historical frames
  • Actions → Can see all video frames (past + future)
  • Video Frames → Can see all actions

It does not use lower triangular causal masking, which is completely opposite to GPT and DreamZero.
Motus adopts a deliberately designed Video-Sparse, Action-Dense strategy, setting the video frame rate to 1/6 of the action frequency. This balances the imbalance in token counts between video and actions, preventing the model from overfitting video generation and weakening action prediction capabilities.

Regarding Downsampling

Whether video downsampling is required is not a manually chosen strategy but a natural consequence of the model’s generation paradigm.
Bidirectional and autoregressive models differ fundamentally in this characteristic, which directly affects the authenticity of video timing and the accuracy of action alignment.
Bidirectional generation models (such as Motus, UniDiffuser, and mainstream video generation architectures) adopt a global synchronous generation mechanism. The model processes the complete video sequence in one pass, with all frames mutually visible and influencing each other.
Past frames can attend to future frames, and future frames can act backward on past frames, forming a globally unified temporal representation.
To achieve full-sequence joint modeling, the model must use fixed-length video chunks during both training and inference. Because the global attention mechanism requires a predefined sequence length to construct an attention matrix of fixed size.
If the sequence length is not fixed, the size of the attention map changes dynamically, making training unstable.
Meanwhile, the bidirectional diffusion denoising process requires synchronous noise addition and denoising for the entire video. Temporal positional encoding, noise scheduling, and sampling steps all depend on a unified sequence length.
Thus, bidirectional models can only generate fixed lengths set during training when starting generation at any time point. When task duration does not match the model’s supported length, video downsampling or stretching is required, which inevitably distorts the native frame rate and temporal structure.
In contrast, autoregressive models follow strict causal generation. The model generates future content chunk-by-chunk based solely on historical observations and continuously records historical information via KV caching.
It does not need to see the complete sequence in advance or construct a global attention map in one pass. Thus, it naturally supports video generation of arbitrary lengths without downsampling or distorting the original frame rate.
This characteristic enables autoregressive architectures to maintain the true temporal relationship of videos, ensuring precise natural alignment between video frames and actions, and providing a more reliable temporal foundation for robot closed-loop control.
Bidirectional models must use fixed lengths and rely on downsampling, with inference extendable via sliding windows. Autoregressive models support longer contexts via KV caching but are also limited by cache capacity.
DreamZero’s advantage lies in preserving the native frame rate (no downsampling alignment), not in supporting arbitrary lengths.

III. Video + Action Joint Generation

DreamZero: Single Model, Single DiT, Joint Denoising

Video and action share the same DiT backbone.
Same layers, same attention, same temporal sequence.
Video and action share denoising time steps.
Jointly optimized with the same flow matching loss.
Video guides action, action aligns with video, deeply coupled.
Minimal architecture, no expert separation.
The mechanism for video-guided action adopts implicit inverse dynamics.
Its action prediction relies entirely on the shared attention mechanism, learning actions end-to-end from generated videos with higher physical alignment.

Motus: Mixture-of-Experts (MoT), Tri-Modal Joint Attention

Three independent experts: video expert (Wan2.2), understanding expert (Qwen-VL), action expert (trained separately).
Tri-modal cross-attention per layer.
Separate temporal order and noise scheduling for video and action.
Unified under the UniDiffuser framework.
Supports 5 mode switches, with looser modal coupling.
The mechanism for video-guided action uses explicit inverse dynamics mode.
The model first generates complete future videos, then infers actions accordingly. This step-by-step logic may be more stable and interpretable for certain tasks.

IV. Differences in Flow Matching

DreamZero: Joint Flow Matching + Teacher Forcing

Video and action share time steps.
Inputs real historical frames during training to avoid error accumulation.
Centered on video prediction; actions derived from visual futures.
Chunk-wise teacher forcing (inputs real history chunk-by-chunk to predict the next chunk).

Motus: Rectified Flow + Decoupled Time Steps

Separate time steps for video and action.
Aims for unified modeling.
Supports multiple task mode switches.
Global one-shot teacher forcing (inputs real initial frames + history, predicts the entire future in one pass).

V. How Video Guides Action Generation

DreamZero: Vision-First → Implicit Inverse Dynamics

First predicts future video (visual planning).
Infers actions from video via shared attention, end-to-end learning.
Actions strictly follow video planning; video quality directly determines action quality.

Motus: Dual-Path Collaboration → Explicit Inverse Dynamics + Joint Generation

Path 1 (IDM Mode): First generates complete future video, then explicitly infers actions.
Path 2 (Video-Action Joint Mode): Video and action generated simultaneously, mutually constrained.
Video and action are collaborative, with no mandatory video priority → more flexible, but weaker physical alignment than DreamZero.

VI. Inference Mechanism

DreamZero: Closed-Loop Real-Time Inference

After each execution step, replace predicted frames in KV cache with real observations.
Completely eliminates error accumulation.
Explicitly optimized for 7Hz asynchronous closed-loop, with detailed error accumulation elimination mechanism.
Fast inference, deployable.
Designed for closed-loop control; preventing error accumulation is one of its core design goals, naturally suitable for long-horizon tasks.

Motus: Open-Loop Generation

Generates all video + action in one pass.
No ground truth injection, no closed loop.
Errors accumulate.
Motus’s flexible unified framework may incur additional inference overhead, such as slow speed, but no specific latency data is reported in the paper.
Architecturally, it focuses more on a unified generative framework. Its inference method is closer to one-shot open-loop planning.
While short-term tasks can be handled via short-term prediction with open-loop execution, long-horizon tasks requiring long-term visual feedback are theoretically more prone to error accumulation.

VII. Training & Deployment Difficulty

DreamZero

Simple architecture, single DiT, easy to reproduce.
Strict requirements for timing and alignment.
Stable training, runs on real robots.
Requires high compute power, with mature optimizations.
DreamZero has mature system-level optimizations (asynchronous execution, quantization, DiT caching), achieving real-time control with 150ms latency.

Motus

Complex architecture, three experts, difficult integration.
Multi-stage training pipeline, data pyramid.
Deployment optimization details are sparsely documented in the paper.

VIII. Pre-Training Data Source & Scale

In terms of video backbone pre-training, both models leverage internet-scale video data to acquire basic spatiotemporal priors. DreamZero uses Wan2.1 as the backbone, while Motus initializes based on the newer Wan2.2 5B model.
Despite sharing the same origin, their data strategies during robot fine-tuning follow completely different technical paths.
DreamZero adopts a highly focused real robot data strategy, using approximately 500 hours of real-world teleoperation data, all from the AgiBot G1 dual-arm robot, collected across 22 different environments with a strict “task diversity over repetition” principle.
Its data strategy explicitly limits the number of demonstrations per task, actively discarding a task after 50 collections to force a broader task distribution and enhance zero-shot generalization.
For cross-embodiment transfer, DreamZero uses very little video-only data, including 20 minutes of unlabeled video from the YAM robot and 12 minutes of human-view video, which significantly improves performance on unseen tasks.
In contrast, Motus adopts a larger six-layer data pyramid structure, forming a full-level, large-scale heterogeneous training system spanning web videos, human videos, simulation data, task-agnostic data, multi-robot mixed data, and target robot data.
Its cross-embodiment and generalization capabilities rely on large-scale heterogeneous data from diverse sources such as Egodex, AgiBot, RDT, RoboMind, and RoboTwin.
Motus specifically sets Level 4: Task-Agnostic Data in its six-layer data pyramid.
This data is generated by random sampling in the target robot’s action space, independent of specific tasks, to align latent action space with real robot control signals.
This design is critical for the stability of latent action learning, while DreamZero’s data strategy does not emphasize such alignment data.
Overall, DreamZero follows a small, refined, real-data-first, diversity-focused data path, better aligned with the low-data-cost requirements of real robot deployment.
Motus follows a large-scale, multi-source, pyramid-style data path, relying on massive heterogeneous data for capability coverage. The two have fundamentally different data philosophies and deployment approaches.

IX. Action Representation

DreamZero uses the robot’s native joint space as action representation, directly outputting relative joint positions corresponding one-to-one with the robot body, typically around 14 dimensions.
This representation requires no additional spatial mapping, with the action space fully aligned with the real robot control space.
The model learns via inverse dynamics, directly mapping video predictions to executable joint control signals. Action decoding is simple and direct, highly aligned with real robot physical execution logic.
A minor detail: DreamZero’s joint space refers to relative joint positions, not raw joint angles.
This indicates that under the goal of aligning physical execution, it also applies normalization to adapt to different robot bodies.
In contrast, Motus uses latent action as a unified representation.
It first extracts pixel-level motion information via optical flow, then compresses it into a fixed-dimensional latent action representation via DC-AE.
This optical-flow-based action space is independent of specific robot morphology, naturally enabling cross-embodiment unified expression.
During execution, Motus decodes latent actions into corresponding robot control signals.
In short, DreamZero learns inverse dynamics for specific robots, focusing on precise execution.
Motus learns general motion priors, focusing on cross-domain generalization.
The two represent two distinct technical paths: physical execution alignment versus general motion abstraction.
My Browser Test Passed. The User Was Never Logged In.

That single moment changed how I think about browser automation entirely.

When I started building browser automation tooling around Playwright, I expected the hardest problems to be technical. I thought most of the work would be around selectors, Docker containers, traces, retries, and CI stability.

Instead, I kept running into something much more uncomfortable: tests that looked successful while proving almost nothing.

One moment in particular completely changed my perspective. I was debugging a recorded login flow that passed consistently in CI. The browser opened the page, filled the credentials, clicked the login button, and completed every recorded step without errors.

The user was never logged in.

The application had shown a validation error after the click, but the test never checked whether the dashboard appeared, whether the URL changed, or whether an authenticated session actually existed.

The browser moved through the flow successfully. The test still failed at its real purpose.

await page.locator('#email').fill('[email protected]')
await page.locator('#password').fill('secret')
await page.locator('#login-button').click()

// Test passed
// User was never authenticated

That was the moment I realized browser movement creates a dangerous illusion of correctness.

The more I worked with AI-assisted browser automation, the more often I saw variations of the same problem. Generated flows without assertions. Self-healing selectors silently switching to different elements. Retry logic hiding flaky behavior instead of exposing it. Agents confidently summarizing successful runs while the actual business outcome was wrong.

The problem was not AI itself. AI is genuinely useful for browser automation. It can help generate steps, explain failures, suggest selectors, summarize traces, and speed up debugging.

The real problem starts when important logic becomes invisible.

If a test changes selectors without review, retries failed actions silently, or decides on its own what “success” means, the team slowly loses control over what is actually being tested. That may be acceptable for exploratory sessions, but it becomes dangerous for regression testing.

I think this is where many discussions about AI testing miss the point. The issue is not whether automation should exist. The issue is whether the automation remains understandable.

A reliable browser test should still have visible steps, explicit assertions, inspectable selectors, clear traces, and reviewable retries. Someone should be able to open the test six months later and immediately understand why it passed.

That idea eventually shaped how I approached WrightTest. I did not want a system where an autonomous agent disappears into the browser and returns with “everything looks good.” I wanted recorded flows, editable steps, visible assertions, Playwright traces, and debugging that stays understandable to the person running the test.

Ironically, building more browser automation made me trust fully autonomous testing less, not more.

Not because automation is bad.

Because invisible automation is very easy to trust too early.

And in testing, false confidence is usually more dangerous than a visible failure.

A Practical Model Selection Matrix for Multi-Model AI Apps

When a product starts using more than one AI model, the question changes from “which model is best?” to “which model is best for this feature?”

For teams building with GPT, Claude, Gemini, DeepSeek, Qwen, and other models, a simple model selection matrix can make API decisions much easier.

I added a new GitHub guide for this here:

https://github.com/yeallen441-del/vectorengine-quickstart/blob/main/MODEL_SELECTION_MATRIX.md

Why a model selection matrix helps

Many AI apps begin with one default model. That is fine for a prototype, but production systems usually need more nuance:

  • premium reasoning for complex answers
  • balanced models for daily user traffic
  • low-cost models for internal utility tasks
  • Chinese or regional models for bilingual workflows
  • fallback models when a provider is slow or unavailable

Without a matrix, teams often choose models by habit instead of data.

Evaluation dimensions

I like to compare models across these dimensions:

  • reasoning quality
  • Chinese-language quality
  • latency
  • cost
  • context length
  • JSON reliability
  • provider availability

The important part is to test the same prompt set across all candidates. Otherwise, the comparison becomes subjective.

A simple grouping strategy

Instead of testing every model against every feature, start with four groups.

1. Premium reasoning

Use this group for agent planning, coding help, complex analysis, and final customer-facing answers.

2. Balanced daily usage

Use this group for common support replies, summaries, product copy, and normal chat experiences.

3. Low-cost utility tasks

Use this group for classification, language detection, keyword extraction, routing decisions, and short rewriting.

4. Chinese and regional LLMs

Use this group for Chinese customer support, Chinese RAG, bilingual SaaS workflows, Qwen testing, and regional model comparison.

Do not assume English performance predicts Chinese performance. Test both.

Why an OpenAI-compatible gateway helps

If your app already uses the OpenAI SDK, an OpenAI-compatible API gateway lets you compare multiple models while keeping the same request shape.

That means your team can test GPT, Claude, Gemini, DeepSeek, Qwen, and other models without rewriting every integration.

VectorNode AI focuses on that pattern: one OpenAI-compatible gateway for multiple AI models.

Website: https://www.vectronode.com/

GitHub guide: https://github.com/yeallen441-del/vectorengine-quickstart/blob/main/MODEL_SELECTION_MATRIX.md

How We Halved Our Playwright E2E Suite

Five patterns that took a slow, flaky Playwright suite down to fast and stable.

We had a Playwright E2E suite that had grown into a painful, flaky part of CI.

Dozens of login/logout cycles per file. Fixed waitForTimeout calls everywhere. Hundreds of UI clicks just to set up state before each assertion.

Every other run, something would fail. We’d retry, hope for green, and move on.

Eventually we paid the tax.

The Before / After

Metric Before After
Tests in the heaviest spec 14 11
Lines of test code ~1,800 ~1,500
Runtime (clean) ~8 min ~4 min
CI reliability ~50% flaky runs Stable with normal retries

Across the broader suite, a similar pass:

  • dropped about a dozen low-value tests,
  • replaced one E2E test with a focused unit suite that runs in 1.2 seconds instead of 30,
  • and stripped fixed waits from the most-trafficked files.

Five patterns did most of the work.

Pattern 1: Programmatic Auth

Login through a form fill takes 2–3 seconds on a good day.

With 40+ login/logout cycles in a file, that’s two minutes of click ceremony before you’ve asserted anything useful.

Most modern auth setups support a programmatic path:

  1. Sign in via the auth provider’s REST endpoint.
  2. Write the resulting token to localStorage (or wherever your client SDK reads from).
  3. Skip the form entirely.

Mirror it for logout — clear the session storage and cookies, then navigate to /login.

That last navigation is the part I’d skip on first attempt and regret.

Without it, after clearing storage the page is still on /dashboard/something and the SPA detects “no session” and starts its own redirect to /login.

The next loginAs then races that redirect, and you get sporadic "navbar not visible" errors that look like flakes but are actually deterministic timing bugs.

Pattern 2: API-Driven Setup

This was the single biggest win for us.

Most of what tests do to set up state is already callable via REST — those endpoints exist because the app uses them.

There’s no reason to drive the UI to:

  • add a user to a group,
  • configure a setting,
  • assign a role,
  • or seed fixtures

when you could just POST directly.

Before: six UI steps for setup:

await page.goto('/admin/groups');
await page.getByRole('row', { name: /Test Group/ }).click();
await page.getByRole('button', { name: 'Add Member' }).click();
await page.getByPlaceholder('Search users').fill(TEST_USER_EMAIL);
await page.getByRole('option', { name: TEST_USER_EMAIL }).click();
await page.getByRole('button', { name: 'Add' }).click();
// ... wait for it to persist, navigate back, etc.

After: one API call:

async function ensureUserInGroup(page: Page) {
  const headers = await getAuthHeaders(page);

  await page.request.post(
    `/api/groups/${GROUP_ID}/members/add`,
    {
      headers: {
        ...headers,
        'Content-Type': 'application/json',
      },
      data: {
        user_ids: [TEST_USER_ID],
      },
    }
  );
}

Test setup went from ~25–30 seconds to ~3 seconds.

The Tradeoff

API-based setup means a test can pass even if the UI setup flow itself is broken.

We accepted that tradeoff.

We kept dedicated tests for the setup flows themselves, and the rest of the suite became free to focus on the behavior it actually existed to verify.

The principle:

Exercise the UI for what you’re actually testing.

A test asserting:

“The frontend hides button X for a viewer”

does not need to configure viewer permissions through the UI too.

Pattern 3: State Assertions, Not Fixed Waits

Hardcoded page.waitForTimeout(1500) calls were everywhere — usually under comments like:

// wait for it to commit

On a fast CI day, harmless.

On a slow CI day, flaky.

Instead of:

await page.waitForTimeout(1500);

assert on the actual signal:

await page.waitForSelector('[role="alert"][aria-label="Saved"]');

The result is:

  • faster on the happy path,
  • more reliable under load,
  • and easier to reason about.

Reach for expect.toPass() with a polled async block when the signal comes from another page or from eventual backend consistency.

Pattern 4: For “Was This Persisted?” — Ask the API, Not the DOM

This was the subtlest bug in the suite, and the one we learned the hard way after a CI regression we couldn’t reproduce locally.

If your frontend uses an optimistic-update library like:

  • RTK Query
  • React Query
  • SWR

then the DOM can temporarily lie about persistence.

A row hidden by an optimistic delete looks identical to a row that was actually deleted — until the cache refetches in the background and the row pops back into existence.

A toHaveCount(0) assertion succeeds against the optimistic state, then the next assertion in the test finds the row again.

When you’re asserting that persisted state changed, poll the backend until the change is actually committed:

await expect(async () => {
  const resp = await page.request.get(
    '/api/.../items',
    { headers }
  );

  const items = await resp.json();

  expect(
    items.some((i) => i.name === itemName)
  ).toBe(false);
}).toPass({
  timeout: 30000,
  intervals: [1000, 2000, 3000],
});

Same idea for permission revocation:

await expect(async () => {
  const resp = await page.request.get(
    '/api/.../resource',
    { headers }
  );

  expect(resp.status()).toBeGreaterThanOrEqual(400);
}).toPass({
  timeout: 90000,
});

The distinction matters:

  • The DOM answers:

“What is rendered right now?”

  • The API answers:

“Did this actually commit?”

Those are not always the same question.

Pattern 5: Audit for Redundancy

After the speedups, the suite was still larger than it needed to be.

On honest review, three categories of redundancy stood out.

Symmetric Mirror Tests

Examples:

  • “User has elevated role + base permission”
  • “User has base role + elevated permission”

What we see here:

  • Different setup states.
  • Identical observable assertions.
  • Same backend path.

One test covered the public contract sufficiently.

Cleanup Tests Duplicating Hooks

We had tests whose sole purpose was deleting leftover fixtures.

But the suite already had afterAll cleanup hooks with retry safety.

The cleanup “tests” added runtime, not coverage.

Generic Component Smoke Tests

Several tests asserted things like:

  • the list loads,
  • pagination works,
  • columns render.

But those shared components were already exercised by nearly every feature test in the suite.

The smoke tests weren’t paying for themselves.

The audit removed roughly a third of tests with no meaningful coverage loss.

A useful question turned out to be:

“Is this test distinct?”

not merely:

“Does this test pass?”

What We Didn’t Do

Some dead ends are worth documenting too.

Parallelizing Tests That Shared Accounts

Concurrent logins for the same backend user triggered session revocation cascades across contexts.

We reverted it.

Reusing Auth Sessions Across Browser Contexts

Several client SDKs rejected rehydrated sessions across multiple contexts.

Each loginAs() now performs a fresh REST sign-in.

The overhead (~200ms) was small enough that determinism mattered more.

Using Short Retry Budgets for Permission Assertions

Eventually consistent systems can take longer than expected, especially during deploys.

A 15-second retry window was not enough.

We replaced short retries with explicit API polling patterns.

Takeaways

  1. If you’re using the UI as a setup harness, you’re paying twice.
    Use APIs to create state and reserve the UI for the behavior you actually care about.

  2. Replace waitForTimeout() with state assertions wherever possible.
    Fixed waits are bets against your worst CI day.

  3. For “was this persisted?” — ask the API, not the DOM.
    The DOM can be optimistic, cached, or mid-render.

  4. Programmatic auth compounds across every test.
    The savings stack up quickly, and you eliminate subtle redirect races.

  5. Audit your suite for true redundancy.
    “All passing” is not the same as “all paying for themselves.”

There’s no silver bullet here — just a stack of small, principled changes that compound.

Fast E2E suites usually aren’t the result of one big optimization.

They’re the result of removing dozens of tiny sources of unnecessary work.

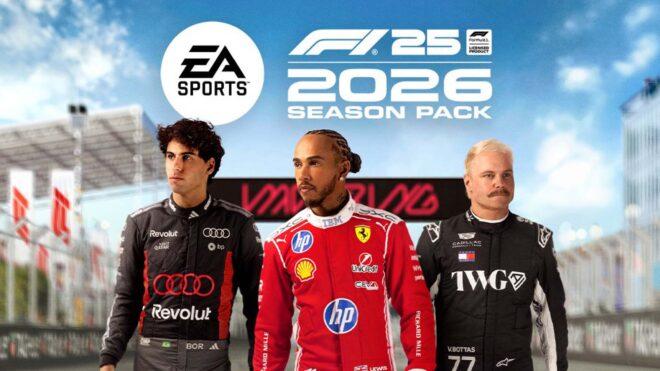
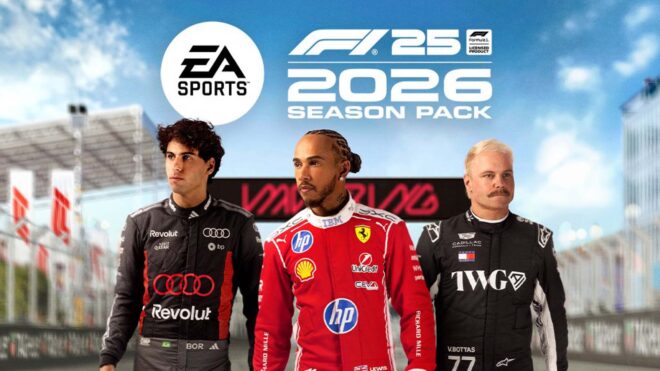
F1 25’in “2026” DLC’si 20 Mayıs’ta tanıtılacak

F1 25’in "2026" DLC’si 20 Mayıs

F1 25’in "2026" DLC’si 20 Mayıs'ta tanıtılacakEA Games, aynı oyunu yeniden sunmak yerine F1 25 için ücretli bir 2026 DLC’si çıkaracak ve bu DLC resmi olarak 20 Mayıs’ta tanıtılacak. Şirket, 2027 yılında ise baştan sona yeniden tasarlanmış bir Formula 1 oyunu piyasaya sürecek. A New Era.@easportsf1 reveal: May 20. 🏎️#F125SeasonPack pic.twitter.com/TXvIxTLNXg — Formula 1 (@F1) May 18, 2026

F1 25’in “2026” DLC’si 20 Mayıs’ta tanıtılacak yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

How I built a no-account leaderboard for my typing game — and why I’ll never ask for signup

When I started building Clackpit, I knew I wanted a daily leaderboard. Competitive pressure is the single biggest reason people return to a typing game — seeing your name one slot below someone else is a visceral motivation loop that no feature list can replicate.

But I also knew from playing TypeRacer that account friction kills the moment. You’re in the zone, you finish a race at a personal best, and then… “Create an account to save your score.” The spell breaks. Half the people close the tab.

So I built Clackpit’s leaderboard to work with zero accounts. Here’s how.

The core insight: localStorage is your persistent identity layer

Every time someone visits Clackpit for the first time, they’re assigned a random handle — something like “QuickFalcon” or “SwiftPine.” It gets stored in localStorage. That’s it. That’s the account.

function getOrCreateHandle(): string {
  const stored = localStorage.getItem('clackpit_handle');
  if (stored) return stored;

  const adjectives = ['Quick', 'Swift', 'Sharp', 'Rapid', 'Keen'];
  const nouns = ['Falcon', 'Pine', 'River', 'Stone', 'Arrow'];

  const handle = 
    adjectives[Math.floor(Math.random() * adjectives.length)] +
    nouns[Math.floor(Math.random() * nouns.length)] +
    Math.floor(Math.random() * 99);

  localStorage.setItem('clackpit_handle', handle);
  return handle;
}

The handle persists across sessions. Players can change it once — this is important, because the ability to choose your name is part of the identity investment. But they can’t change it to something that’s already on the leaderboard (we check server-side), and once changed, it’s locked for 24 hours.

The server side: Cloudflare KV as a daily leaderboard store

The leaderboard resets daily. Each entry is a score object keyed by date:

interface LeaderboardEntry {
  handle: string;
  wpm: number;
  accuracy: number;
  mode: 'sprint' | 'marathon' | 'endurance';
  timestamp: number;
}

When a race finishes, the client POSTs to /api/leaderboard with the handle, score, and mode. The worker looks up the current day’s leaderboard from KV, upserts the entry (keeping only the player’s best score for the day), and writes it back with a 24-hour TTL.

async function submitScore(env: Env, entry: LeaderboardEntry): Promise<void> {
  const key = `leaderboard:${todayKey()}`;
  const raw = await env.LEADERBOARD.get(key);
  const board: LeaderboardEntry[] = raw ? JSON.parse(raw) : [];

  // Upsert: replace existing entry for this handle, or append
  const idx = board.findIndex(e => e.handle === entry.handle);
  if (idx >= 0) {
    // Only keep the better score
    if (entry.wpm > board[idx].wpm) board[idx] = entry;
  } else {
    board.push(entry);
  }

  // Sort and cap at top 50
  board.sort((a, b) => b.wpm - a.wpm);
  board.splice(50);

  await env.LEADERBOARD.put(key, JSON.stringify(board), {
    expirationTtl: 86400 * 2 // 2-day TTL so yesterday's leaderboard stays readable
  });
}

The daily reset is implicit: a new key (leaderboard:2026-05-17) just starts empty. No cron job needed.

The anti-cheat problem

Without accounts, someone can just refresh localStorage, generate a new handle, and post another score. I don’t pretend this is unsolvable — it’s not, but it’s also not worth solving at this stage. The leaderboard is entertainment, not a tournament with prizes.

What I did add: server-side rate limiting per IP using KV (one submission per 5 minutes), and a WPM cap above which scores are silently rejected (currently 220 WPM — humanly achievable but rare enough to filter obvious bots). Both are soft filters. The goal is making casual cheating annoying, not building a fraud detection system.

Why this works better than I expected

The no-account leaderboard has some emergent properties I didn’t anticipate:

The handle creates identity without commitment. “QuickFalcon42 is on the leaderboard” is surprisingly motivating even though QuickFalcon42 is a random string someone got three minutes ago. People name themselves. They check back to see if their name is still in the top 10. The absence of a real account doesn’t reduce this effect much.

Daily resets reduce intimidation. On a permanent leaderboard, a 180 WPM typist who’s been there for two years makes every new visitor feel hopeless. A daily leaderboard lets a 95 WPM typist realistically place in the top 10 on a quiet morning. It stays competitive.

Zero friction means more completions. This is the real one. In early testing (before I shipped the leaderboard), about 60% of visitors who started a race finished it. After shipping the leaderboard, that number went up — people who were going to quit mid-race sometimes pushed through to post a score.

If you’re building anything with a competitive element and you’re considering whether to require accounts first: ship the no-account version. You can always add accounts later. You cannot un-kill the momentum you lost from the friction.

Try the leaderboard at clackpit.launchyard.app — the daily reset is at midnight UTC if you want to plant a flag.

From DeepSeek to Quack: When the Dream of Distributed DuckDB Started to Feel Real

At the beginning of 2025, DeepSeek changed the conversation around AI infrastructure.

Most people focused on the model quality, the training cost, and the geopolitical story around a new Chinese AI lab suddenly competing with the biggest names in the industry. That part was interesting, of course. But as an engineer, the part that caught my attention was not only the model.

It was the data pipeline behind it.

DeepSeek released Smallpond, a lightweight data processing framework built on DuckDB and 3FS. The idea was surprisingly simple: instead of building everything around a traditional big-data engine like Spark, run many independent DuckDB-based processing jobs close to the data, partition the workload carefully, and let each local engine do what it does best.

That sounds almost too simple.

But that is exactly why it is interesting.

The uncomfortable question: do we always need Spark?

As a senior engineer, I have worked on systems where Spark was the default answer before the problem was even fully understood.

Need to process files? Use Spark.

Need to aggregate logs? Use Spark.

Need to transform Parquet? Use Spark.

Need to join medium-sized datasets? Still Spark.

Spark is powerful, and I am not arguing against it. But in many real projects, the operational cost becomes the hidden tax: cluster configuration, memory tuning, shuffle behavior, executor sizing, dependency packaging, job retries, monitoring, and the constant pain of debugging a distributed job that fails somewhere in the middle of a long DAG.

DuckDB sits on the opposite side of that spectrum.

It is embedded. It runs inside your process. It reads Parquet beautifully. It speaks SQL. It is fast for analytical workloads. And most importantly, it makes local data processing feel boring again.

That boring part is a compliment.

When I first started using DuckDB seriously, it replaced a lot of small Python scripts in my workflow. Instead of loading CSV or Parquet files into Pandas, fighting memory limits, and then exporting results again, I could write SQL directly over files:

SELECT customer_id, sum(amount) AS total_spent
FROM read_parquet('orders/*.parquet')
GROUP BY customer_id
ORDER BY total_spent DESC
LIMIT 20;

For one-off analysis, this is already great. But Smallpond suggested something bigger: what if DuckDB is not just a local helper tool, but the execution unit of a distributed data system?

Smallpond’s lesson: distribute the plan, not the database

Smallpond is interesting because it does not try to turn DuckDB itself into a distributed database. Instead, it treats DuckDB as a fast local execution engine.

The pattern looks like this:

  1. Split the dataset into partitions.
  2. Send partitions to different workers.
  3. Let each worker run DuckDB locally.
  4. Write intermediate results back to shared storage.
  5. Merge or repartition when needed.

That is not a new idea in distributed systems, but using DuckDB as the local analytical core makes it feel lightweight.

In the Smallpond repository, the basic example is simple: read Parquet, repartition by a key, run SQL, and write Parquet output again. The README also mentions a GraySort benchmark where Smallpond processed more than 100 TiB of data on a cluster. That is a strong reminder that not every scalable system needs to look like the traditional Hadoop/Spark stack.

The deeper lesson for me is this:

Sometimes the best distributed architecture is not one giant distributed database. Sometimes it is thousands of small, predictable local engines coordinated well.

That idea maps nicely to modern AI pipelines.

Training a model is not only about GPUs. Before the GPU sees anything, there is a long chain of data cleaning, deduplication, filtering, tokenization, feature extraction, metadata joins, quality checks, and batch generation. A lot of that work is analytical. A lot of it is file-based. And a lot of it can be pushed close to storage.

DuckDB is very good at that style of work.

Where DuckDB used to hurt

DuckDB’s strength has always been its simplicity: it is an in-process analytical database.

But the same simplicity creates a limitation.

If you have one Python process, one CLI session, or one application working with a DuckDB database file, everything feels clean. But once multiple processes want to write to the same database file, you quickly run into locking and concurrency constraints.

That is not a bug. It is part of the design.

DuckDB was originally optimized for embedded OLAP workloads, not for being a shared multi-client server like PostgreSQL.

In my own projects, I usually solved this by avoiding shared writes completely:

  • write partitioned Parquet instead of writing into one shared database file
  • let each worker produce immutable output
  • use object storage as the coordination layer
  • run a final compaction or merge step later
  • keep DuckDB as the query engine, not the source of truth

This works well, but it has trade-offs. You start building your own small coordination layer. You need naming conventions, idempotent writes, retry logic, cleanup jobs, and sometimes a metadata database just to track what happened.

That is why Quack is so interesting.

Quack: DuckDB starts speaking over the network

In 2026, Hannes Mühleisen introduced Quack, a remote protocol that turns DuckDB into a client-server database.

The idea is elegant: both the client and the server are DuckDB instances, but they communicate through the quack: protocol. The server owns the data. The client sends queries. The heavy work happens near the data, and the result comes back to the client.

A simplified example looks like this:

INSTALL quack FROM core_nightly;
LOAD quack;

CREATE SECRET (
    TYPE quack,
    TOKEN 'super_secret'
);

ATTACH 'quack:bigserver:9494' AS remote;

SELECT customer_id, sum(amount) AS total_amount
FROM remote.transactions
GROUP BY customer_id
ORDER BY total_amount DESC
LIMIT 10;

This is not just a nicer syntax. It changes the deployment model.

Before Quack, DuckDB was mostly local-first. With Quack, DuckDB can become remote-first when needed.

That means:

  • the data can stay on a powerful server
  • laptop clients can query without downloading huge datasets
  • multiple clients can connect to the same DuckDB server
  • DuckDB can be used in more traditional application architectures
  • DuckDB-Wasm and browser-based analytical tools become more interesting

The official DuckDB documentation describes Quack as an RPC protocol for DuckDB and mentions use cases like concurrent read-write access, moving computation closer to data, and querying powerful servers from local clients.

For me, the key phrase is: compute near data.

That is one of the most important ideas in data engineering.

Moving 500 GB to a laptop is a bad plan. Sending a SQL query to the machine that already has the data is a better plan.

A prototype I would actually build

The first thing I wanted to try with this architecture was not a huge AI training pipeline. It was something more realistic: a lightweight analytics service for event data.

Imagine this setup:

  • application events are written as Parquet files to object storage
  • a small ingestion service batches new events
  • DuckDB reads and validates those files locally
  • embeddings are generated for selected text fields
  • analytical metadata is stored in DuckDB or DuckLake
  • vector search is handled by a dedicated vector database
  • Quack exposes the central DuckDB instance to internal tools

This kind of architecture is attractive because each tool does one job well.

DuckDB is great for analytical SQL.

Object storage is great for cheap durable files.

A vector database is great for similarity search.

Quack becomes the bridge that lets multiple clients query the analytical layer without copying everything locally.

Where vector databases fit into this story

A vector database stores embeddings instead of just rows and columns.

An embedding is a numerical representation of text, image, audio, code, or another object. For example, a support ticket like:

“The payment failed after I changed my billing address.”

can be converted into a vector such as:

[0.012, -0.441, 0.087, ...]

The numbers themselves are not meaningful to humans, but their position in vector space captures semantic meaning. Similar texts produce vectors that are close to each other.

That enables queries like:

Find tickets semantically similar to this new complaint.

Traditional SQL is not designed for that kind of similarity search. SQL is excellent when you know the exact fields and predicates:

WHERE status = 'failed'
AND country = 'AM'

Vector search is different:

Find documents close to this embedding.

This is why systems like Qdrant, Milvus, Weaviate, Pinecone, pgvector, and others became popular. They use indexes such as HNSW or IVF to make nearest-neighbor search fast.

But here is the important part: vector search alone is rarely enough.

In production, you usually need hybrid retrieval:

  • vector similarity for semantic meaning
  • SQL filters for structured constraints
  • full-text search for exact keywords
  • metadata joins for permissions, customers, time ranges, or product categories
  • analytical queries to evaluate quality and drift

That is where DuckDB becomes valuable again.

I do not want my vector database to become my entire analytics platform. I want it to retrieve candidates. Then I want SQL to inspect, filter, aggregate, evaluate, and debug the system.

For example:

SELECT source, count(*) AS total, avg(score) AS avg_score
FROM retrieval_logs
WHERE created_at >= now() - INTERVAL '7 days'
GROUP BY source
ORDER BY avg_score DESC;

This kind of query belongs naturally in DuckDB or a lakehouse layer, not inside the vector database.

Why Quack makes this architecture cleaner

Without Quack, I would normally run DuckDB locally inside each service and write files back to object storage. That is still a good pattern. But it makes interactive querying harder.

With Quack, I can imagine a cleaner workflow:

  1. ETL workers process raw data locally with DuckDB.
  2. Processed files are written to object storage.
  3. A central DuckDB/DuckLake server exposes curated tables.
  4. Internal tools connect through Quack.
  5. BI dashboards query the same analytical layer.
  6. Vector search services write retrieval logs back into the lake.
  7. Engineers debug everything with SQL.

This is not a replacement for every data warehouse. It is not a replacement for Kafka, Spark, PostgreSQL, or a vector database.

But it is a powerful middle layer.

It fits the space where many teams actually live: too much data for one Pandas script, but not enough operational complexity to justify a full big-data platform.

The part I like most as an engineer

What I like about this direction is that it respects mechanical sympathy.

DuckDB is fast because it understands analytical execution: vectorized processing, columnar storage, efficient scans, smart Parquet reads, and local execution without network overhead.

Smallpond says: keep that local execution model, but run it many times in parallel.

Quack says: keep DuckDB’s engine, but allow it to communicate when a shared server model is useful.

That is a healthy evolution.

It does not throw away the original design. It extends it.

As someone who has spent too much time debugging over-engineered pipelines, I appreciate systems that scale by composition instead of magic.

What I would be careful about

I would still be cautious before using Quack as the core of a production system today.

The official page describes it as a beta release. That matters.

Before depending on it, I would test:

  • write concurrency under real workload
  • authentication and network exposure
  • backup and restore strategy
  • failure behavior during long-running writes
  • compatibility with existing DuckDB extensions
  • observability and query logging
  • behavior behind load balancers or proxies
  • performance with many small writes versus large batches

I would also avoid pretending DuckDB suddenly became PostgreSQL.

DuckDB is still fundamentally an analytical engine. Even if Quack makes multi-client access possible, I would not immediately use it for high-volume OLTP workloads like payments, orders, or user sessions.

For those, PostgreSQL is still the boring and correct answer.

But for analytical workloads, internal dashboards, data pipelines, AI preprocessing, evaluation datasets, batch transformations, and lakehouse-style metadata, Quack opens a very interesting door.

Final thought

The story from DeepSeek’s Smallpond to DuckDB’s Quack is not just about one tool becoming distributed.

It is about a shift in how we think about data systems.

For years, the default answer to scale was often: use a bigger distributed framework.

Now we are seeing another pattern:

  • keep compute simple
  • keep data in open formats
  • run fast local engines near the data
  • coordinate through lightweight protocols
  • use specialized systems where they actually make sense

That is why this space is exciting.

DuckDB made local analytics feel simple.

Smallpond showed that many local DuckDB jobs can become a serious distributed processing pattern.

Quack now makes DuckDB instances talk to each other.

And when you combine that with object storage, DuckLake, Parquet, and vector databases, you get a very pragmatic architecture for modern AI and data engineering.

Not because it is trendy.

Because it removes unnecessary complexity.

Median of Two Sorted Arrays — LeetCode #4 (Hard)

The Problem

Given two sorted arrays, return the median of all their elements combined, in logarithmic time.

Example

Input: nums1 = [1,3], nums2 = [2]

Output: 2.00000

merged array = [1,2,3] and median is 2.

Constraints

  • 0 <= m, n <= 1000
  • 1 <= m + n <= 2000
  • -10^6 <= nums1[i], nums2[i] <= 10^6
  • Required runtime: O(log(m+n))

The Key Insight

Let’s slow down. Look at what the merge throws away. We carefully ordered all eleven numbers. But we only needed the one in the middle. The rest was wasted effort.

Here’s the real question. What does the median actually tell us about how the numbers are split? The median is the point where the numbers divide into a smaller half and a larger half. Equal sized halves when the total’s even; otherwise the left half gets one extra.

So forget merging. What if we just drew a dividing line through each array, a left part and a right part? Eleven numbers total. We want six on the left, five on the right. That left count never changes.

Here’s the move. If we cut the first array, the cut in the second is forced. Both left parts together must add up to six. So we only choose one thing: where to cut the smaller array. The other cut follows automatically.

When is a cut correct? Every number on the left must be less than or equal to every number on the right. Because both arrays are sorted, we only check the four numbers touching the cut lines: the two ends of the left, the two starts of the right.

The test is simple. The first array’s left edge must not exceed the second array’s right edge, and the other way around too. And to find the right cut, we don’t try every spot. We binary search, like guessing a number while halving the range each time.

Watch out for one trap. You might pick the bigger array to search. Don’t. Cut the smaller one, or its forced cut can fall off the edge. And when a cut sits at the very start or end, there’s no number there. We treat a missing left edge as negative infinity, a missing right edge as positive infinity.

Why It Works

Notice what we never did. We never merged the lists. Each guess threw away half the remaining cut positions, so a few guesses were enough.

Walking Through It

Let’s trace it. First list: one, three, eight, nine, fifteen. Second list: seven, eleven, eighteen, nineteen, twenty-one, twenty-five. Eleven numbers total. The left half needs six. We binary search the cuts of the smaller first array.

The cut in the first array can be anywhere from zero to five. Start the search: low is zero, high is five. Midpoint of the search is cut position two. That puts two numbers from the first array on the left, so the second gives four.

Now the four border numbers. First array: left edge three, right edge eight. Second array: left edge nineteen, right edge twenty-one. Check one: is the first array’s left edge, three, less than or equal to the second’s right edge, twenty-one? Yes.

Check two: is the second array’s left edge, nineteen, less than or equal to the first’s right edge, eight? No. Nineteen is way too big. So this cut is wrong. The second array put too many numbers on its left. We need more from the first array instead.

Move the search to the right. Low becomes three. Try again. New midpoint cut: position four. Four numbers from the first array on the left, so the second gives just two.

Border numbers now. First array: left edge nine, right edge fifteen. Second array: left edge eleven, right edge eighteen. Check one: first array’s left edge nine, less than or equal to the second’s right edge eighteen? Yes.

Check two: second array’s left edge eleven, less than or equal to the first’s right edge fifteen? Yes. Both pass. This cut is valid. The left half holds the six smallest numbers, the right half the five largest.

The total, eleven, is odd. The median is the largest number on the left: the bigger of nine and eleven, which is eleven.

Complexity

Each step halves the cuts still worth considering. So the number of steps grows with the logarithm of the smaller array’s length. And we only ever store a few border values, never a merged list. The memory stays constant no matter how big the inputs grow.

The Code

OK, same logic in Python. Swap so A is the smaller array, work out the left half size, and set the search bounds on A’s cut. Each loop pass picks a cut in A, and the cut in B follows automatically, since the left half size is fixed.

Read the four border values. When a cut sits at an edge, fall back to negative or positive infinity. If both checks pass, the cut is valid. An odd total returns the largest left value, an even total averages the two middle ones.

Otherwise shift the search. If A’s left edge is too big, go left. Otherwise go right, and try again.

class Solution(object):
    def findMedianSortedArrays(self, nums1, nums2):
        A, B = nums1, nums2
        if len(A) > len(B):
            A, B = B, A
        m, n = len(A), len(B)
        half = (m + n + 1) // 2
        lo, hi = 0, m
        while lo <= hi:
            i = (lo + hi) // 2
            j = half - i
            left1 = A[i - 1] if i > 0 else float('-inf')
            right1 = A[i] if i < m else float('inf')
            left2 = B[j - 1] if j > 0 else float('-inf')
            right2 = B[j] if j < n else float('inf')
            if left1 <= right2 and left2 <= right1:
                if (m + n) % 2:
                    return max(left1, left2)
                return (max(left1, left2) + min(right1, right2)) / 2.0
            elif left1 > right2:
                hi = i - 1
            else:
                lo = i + 1

Wrap-up

And that’s the trick. Stop merging, start cutting. When a problem demands O(log n) time, ask what you can throw away each step.

📺 Watch the full walkthrough on YouTube: https://youtu.be/6e5TLbzYyaw

Narration uses an AI-generated voice (Supertonic TTS).

AI โคลนเสียงได้ใน 3 วินาที ทำยังไง?

<!DOCTYPE html>

AI โคลนเสียงได้ใน 3 วินาที ทำยังไง? – AiDevThai

<h1>AI โคลนเสียงได้ใน 3 วินาที ทำยังไง?</h1>

<p>คุณเชื่อหรือไม่ว่าทุกวันนี้คนเราถูกหลอกด้วยเสียง AI ได้ง่ายขึ้น? มีงานวิจัยที่น่าสนใจว่า <strong>Humans now fail voice tests 25% of time</strong> ไม่น่าแปลกใจเลยที่ AI สามารถสร้างเสียงสังเคราะห์ที่เกือบจะแยกไม่ออกกับเสียงมนุษย์จริง โดยเฉพาะความสามารถในการโคลนเสียงได้ภายในเวลาเพียงไม่กี่วินาที ทำให้หลายคนต้องทึ่ง วันนี้ AiDevThai จะพาคุณไปเจาะลึกว่าเทคโนโลยีสุดล้ำนี้ทำงานอย่างไร และมันเข้ามาเปลี่ยนแปลงโลกของเราได้อย่างไรบ้าง</p>

<div class="key-facts" style="background:#fffbeb;border-left:4px solid #f59e0b;padding:16px 20px;margin:20px 0;border-radius:6px;"><strong>Key Facts ที่คนส่วนใหญ่ไม่รู้</strong>
    <ul>
        <li>ElevenLabs' AI ในปี 2023 ทำคะแนน Mean Opinion Score (MOS) ได้ 0.83 ซึ่งเทียบเท่ากับเกณฑ์คุณภาพเสียงของมนุษย์ที่ 0.80 ซึ่งอุตสาหกรรมโทรคมนาคมใช้มาตั้งแต่ปี 1996</li>
        <li>VALL-E ของ Microsoft ต้องการตัวอย่างเสียงเพียง 3 วินาทีเพื่อโคลนเสียงใครบางคน โดยใช้ชุดข้อมูล LibriLight 60,000 ชั่วโมงพร้อมรหัสตัวแปลงสัญญาณแบบ Discrete Codec</li>
        <li>Tacotron 2 สร้าง mel-spectrograms ที่ช่วงเวลาเฟรม 12.5 มิลลิวินาที จากนั้น WaveNet ทำการอัพแซมเปิลเป็น 24kHz โดยใช้เลเยอร์ convolution แบบ dilated 30 ชั้น พร้อมช่องสัญญาณ residual 512 ช่อง</li>
    </ul>
</div>

<h2>AI โคลนเสียงคืออะไร?</h2>
<p>ลองจินตนาการว่าคุณอัดเสียงพูดของตัวเองเพียงประโยคสั้นๆ ไม่กี่วินาที แล้ว AI ก็สามารถนำเสียงของคุณไปสร้างสรรค์คำพูดอะไรก็ได้ที่คุณต้องการ ด้วยน้ำเสียง สำเนียง และอารมณ์ที่คล้ายกับต้นฉบับของคุณอย่างน่าทึ่ง นี่แหละครับคือความสามารถของ AI โคลนเสียง หรือที่เรียกว่า Voice Cloning AI หรือ Text-to-Speech (TTS) Synthesis with voice adaptation</p>
<p>พูดง่ายๆ คือ มันไม่ใช่แค่การสร้างเสียงสังเคราะห์ทั่วไปแบบหุ่นยนต์ แต่เป็นการสร้างเสียงที่มีเอกลักษณ์เฉพาะตัวของคุณขึ้นมาใหม่ให้มากที่สุด ไม่ว่าคุณจะพูดอะไรลงไป ไม่ว่าจะเป็นเรื่องราวใหม่ๆ สารคดี หรือแม้แต่เพลง AI ก็สามารถ "ปลอมเสียง" หรือ "เลียนเสียง" คุณได้อย่างแนบเนียน</p>

<h2>AI โคลนเสียงทำงานอย่างไร? เบื้องหลังเทคโนโลยี</h2>
<p>การโคลนเสียงในเวลาอันสั้นเช่น 3 วินาทีนั้นไม่ใช่เรื่องง่าย และเบื้องหลังความสามารถอันน่าทึ่งนี้คือโครงข่ายประสาทเทียม (Neural Networks) ที่ซับซ้อน โดยเฉพาะอย่างยิ่งสถาปัตยกรรม Model อย่าง Tacotron 2 และ Vocoder อย่าง WaveNet หรือที่พัฒนาขึ้นมาใหม่ในปัจจุบันให้มีประสิทธิภาพยิ่งขึ้น ดังเช่น VALL-E ของ Microsoft ที่ <strong>VALL-E by Microsoft requires only 3 seconds of voice sample to clone anyone, using 60,000 hours of LibriLight dataset with discrete codec codes</strong> นี่คือการทำงานโดยละเอียดในแบบที่เข้าใจง่าย:</p>

<h3>1. การวิเคราะห์เสียงต้นฉบับ (Voice Analysis)</h3>
<p>เมื่อคุณป้อนตัวอย่างเสียงสั้นๆ เข้าไป (เช่น 3 วินาที) AI จะทำการวิเคราะห์คุณสมบัติทางเสียงที่สำคัญทั้งหมด เช่น:</p>
<ul>
    <li><strong>ระดับเสียง (Pitch):</strong> ความสูง-ต่ำของเสียง</li>
    <li><strong>น้ำเสียง (Timbre):</strong> คุณภาพเฉพาะตัวของเสียงที่ทำให้เราแยกแยะเสียงแต่ละบุคคลได้</li>
    <li><strong>ความเร็วในการพูด (Pace):</strong> จังหวะการพูด</li>
    <li><strong>อารมณ์ (Emotion):</strong> AI จะพยายามจับอารมณ์ที่แฝงอยู่ในเสียงต้นฉบับด้วย</li>
    <li><strong>คุณสมบัติทางสัทวิทยา (Phonetic Features):</strong> การออกเสียงพยัญชนะ สระ และเสียงต่างๆ ที่เป็นเอกลักษณ์เฉพาะบุคคล</li>
</ul>
<p>ข้อมูลเหล่านี้จะถูกแปลงเป็น "รูปแบบจำลองเสียง" (Voice Embedding หรือ Voice Print) ซึ่งเป็นข้อมูลเชิงตัวเลขที่เก็บลักษณะเฉพาะของเสียงของคุณไว้ ซึ่งเปรียบเสมือน DNA ของเสียงคุณ</p>

<h3>2. การแปลงข้อความเป็นคุณสมบัติเสียง (Text-to-Spectrogram)</h3>
<ol>
    <li><strong>Step 1: Text encoder converts input characters into 512-dimensional embedding vectors using learned character-to-phoneme mappings</strong> เริ่มต้นด้วยการนำข้อความที่เราต้องการให้ AI พูด เช่น "สวัสดีครับทุกคน" ข้อความนี้จะถูกแปลงเป็นชุดตัวเลขที่เรียกว่า "เวกเตอร์ฝังตัว" (Embedding Vectors) ที่มีมิติ 512 มิติ โดย AI จะเรียนรู้ความสัมพันธ์ระหว่างตัวอักษรกับเสียงต่าง ๆ (Phonemes) ที่จะเกิดขึ้นในคำนั้นๆ</li>
    <li><strong>Step 2: Attention mechanism aligns encoder outputs with decoder timesteps using location-sensitive attention with 32 filters across 31 kernel width</strong> จากนั้นมีกลไกที่เรียกว่า "Attention" ซึ่งจะช่วยให้ AI จับคู่ (align) ข้อมูลจากข้อความที่ถูกเข้ารหัส กับขั้นตอนการสร้างเสียงในส่วนถัดไปได้อย่างแม่นยำ เหมือนกับการที่มนุษย์อ่านข้อความแล้วรู้ว่าจะต้องออกเสียงคำไหนเมื่อไหร่ และแต่ละคำมีความสำคัญต่อเสียงอย่างไร</li>
    <li><strong>Step 3: Decoder LSTM with 1024 units predicts 80-band mel-spectrogram frames autoregressively, outputting one frame per iteration</strong> ส่วนถอดรหัส (Decoder) ซึ่งเป็นโครงข่ายประสาทเทียมชนิดหนึ่ง (LSTM) จะรับข้อมูลจากขั้นตอนก่อนหน้า และเริ่มทำนาย "mel-spectrogram" ทีละเฟรม Mel-spectrogram เป็นการแสดงภาพของความถี่เสียงในช่วงเวลาต่างๆ คล้ายกับแผนที่ความร้อนของเสียง โดยจะทำนายออกมาครั้งละ 80 แบนด์ (ลักษณะความถี่) ที่ 12.5 มิลลิวินาทีต่อเฟรม โดยใช้การทำนายแบบอัตโนมัติ (autoregressively)</li>
    <li><strong>Step 4: Post-net applies 5 convolutional layers with batch normalization to refine mel-spectrogram predictions and reduce artifacts</strong> หลังจากการทำนาย spectrogram เบื้องต้น ก็จะมีส่วนที่เรียกว่า Post-net ซึ่งจะใช้เลเยอร์ convolutional 5 ชั้น พร้อมกับการทำ batch normalization เพื่อปรับปรุงคุณภาพของ mel-spectrogram ที่ทำนายให้ดีขึ้น และลด "สิ่งรบกวน" หรือ "ความเพี้ยน" ของเสียงที่อาจเกิดขึ้น</li>
</ol>
<p>กระบวนการข้างต้นนี้เป็นส่วนสำคัญที่ทำให้ <strong>Tacotron 2 generates mel-spectrograms at 12.5ms frame intervals, then WaveNet upsamples to 24kHz using 30 dilated convolution layers with 512 residual channels</strong></p>

<h3>3. การสังเคราะห์คลื่นเสียง (Waveform Synthesis – Vocoder)</h3>
<p>เมื่อได้ mel-spectrogram ที่สมบูรณ์แล้ว ขั้นตอนสุดท้ายคือการแปลงข้อมูลภาพเสียงนี้ให้กลับมาเป็นคลื่นเสียงที่เราได้ยิน ซึ่งเรียกว่า Voсoder (Voice Coder) สมัยก่อนใช้ WaveNet แต่ปัจจุบันมี Vocoler ที่ทันสมัยขึ้นมาก</p>
<ol start="5">
    <li><strong>Step 5: Neural vocoder splits mel-spectrogram into overlapping 50ms windows with 12.5ms hop length for waveform synthesis preparation</strong> Neural vocoder จะแบ่ง mel-spectrogram ออกเป็นส่วนย่อยๆ หรือ "หน้าต่าง" ที่ทับซ้อนกัน โดยแต่ละหน้าต่างมีความยาว 50 มิลลิวินาที และเลื่อนไปข้างหน้า 12.5 มิลลิวินาที เพื่อเตรียมพร้อมสำหรับการสร้างคลื่นเสียง</li>
    <li><strong>Step 6: WaveNet processes each window through 30 gated activation layers with exponentially increasing dilation rates from 1 to 512</strong> จากนั้น WaveNet (หรือ Vocoder ที่คล้ายกัน) จะประมวลผลแต่ละหน้าต่างเหล่านั้นผ่านเลเยอร์การทำงาน 30 ชั้นที่เรียกว่า “gated activation layers” ซึ่งมีการขยายตัว (dilation rates) ที่เพิ่มขึ้นแบบทวีคูณจาก 1 ไปถึง 512 การขยายตัวนี้ช่วยให้โมเดลสามารถรับรู้บริบทของเสียงในช่วงเวลาที่กว้างขึ้น</li>
    <li><strong>Step 7: Each dilated convolution layer outputs 256 residual and 256 skip channels, summing skip connections across all 30 layers</strong> แต่ละเลเยอร์ convolution แบบ dilated จะสร้างเอาต์พุต 256 ช่องสัญญาณ residual และ 256 ช่องสัญญาณ skip โดยมีการรวม (summing) ช่องสัญญาณ skip เข้าด้วยกันจากทุกๆ 30 เลเยอร์ ช่องสัญญาณเหล่านี้ช่วยให้ข้อมูลไหลผ่านโครงข่ายได้อย่างมีประสิทธิภาพ</li>
    <li><strong>Step 8: Final 1x1 convolution with softmax outputs 256 mu-law quantized amplitude values at 24,000 samples per second</strong> สุดท้ายเลเยอร์ convolution ขนาด 1x1 พร้อมฟังก์ชัน softmax จะสร้างค่าแอมพลิจูดที่เข้ารหัสแบบ mu-law (mu-law quantized amplitude values) จำนวน 256 ค่า ซึ่งเป็นค่าที่ใช้สร้างคลื่นเสียงดิจิทัลที่ความถี่ 24,000 ตัวอย่างต่อวินาที (samples per second) เป็นการแปลงกลับมาเป็นเสียงที่เราได้ยินนั่นเอง</li>
</ol>

<h2>ตัวอย่างการใช้งาน AI โคลนเสียงในชีวิตจริง</h2>
<p>เทคโนโลยีนี้ไม่ได้เป็นเพียงเรื่องในนิยายวิทยาศาสตร์ แต่มันถูกนำมาใช้จริงในหลายๆ แขนงแล้ว:</p>
<ul>
    <li><strong>การสร้างเนื้อหา (Content Creation):</strong> นักสร้างสรรค์วิดีโอ พอดแคสต์ หรือผู้ผลิตหนังสือเสียง สามารถใช้เสียงของตัวเองสร้างเนื้อหาจำนวนมากได้โดยไม่ต้องอัดเสียงใหม่ทั้งหมด</li>
    <li><strong>การพากย์เสียง (Voice Acting/Dubbing):</strong> อำนวยความสะดวกในการพากย์เสียงภาพยนตร์ ซีรีส์ หรือโฆษณาในหลายภาษา โดยยังคงน้ำเสียงและอารมณ์ของนักแสดงต้นฉบับไว้ได้</li>
    <li><strong>ผู้ช่วยส่วนตัว (Personal Assistants):</strong> Siri, Google Assistant หรือ Alexa อาจจะเรียนรู้เสียงของเราและตอบโต้กลับมาด้วยเสียงที่คล้ายคลึงกับเราเองในอนาคต</li>
    <li><strong>การฟื้นฟูเสียง (Voice Restoration):</strong> สำหรับผู้ที่สูญเสียความสามารถในการพูด เสียงของพวกเขาสามารถถูกโคลนเพื่อใช้ในการสื่อสารต่อไปได้ เช่น กรณีของ Stephen Hawking</li>
    <li><strong>การศึกษาและการเรียนรู้ (Education):</strong> สร้างบทเรียนเสียงที่ปรับแต่งให้เข้ากับผู้เรียนแต่ละคน หรือสร้างเสียงอ่านสำหรับหนังสือเรียน</li>
    <li><strong>ธุรกิจและองค์กร:</strong> ระบบตอบรับอัตโนมัติ (IVR) ที่เป็นมิตรและเป็นธรรมชาติมากขึ้น หรือใช้ในการสร้างบทเรียนฝึกอบรมที่น่าสนใจ</li>
</ul>

<h2>ทำไม AI โคลนเสียงถึงสำคัญและน่าจับตา?</h2>
<p>ความสามารถในการโคลนเสียงได้ในเวลาอันสั้นและมีคุณภาพสูงนั้นมีความสำคัญอย่างยิ่งในหลายมิติ</p>
<ol>
    <li><strong>ลดต้นทุนและเวลา:</strong> การอัดเสียงมืออาชีพมีค่าใช้จ่ายสูงและใช้เวลานาน AI ช่วยให้ผลิตเสียงคุณภาพสูงได้เร็วกว่าและถูกกว่ามาก</li>
    <li><strong>สร้างประสบการณ์ที่เป็นส่วนตัวมากขึ้น:</strong> เสียงที่คุ้นเคยหรือเสียงที่ปรับแต่งได้ สามารถเพิ่มความน่าสนใจและความผูกพันกับผู้ใช้งานได้ดีกว่า</li>
    <li><strong>ขยายขอบเขตการเข้าถึง:</strong> ช่วยให้เนื้อหาเข้าถึงผู้คนได้มากขึ้น เช่น การพากย์เสียงหลายภาษา หรือการแปลงข้อความเป็นเสียงสำหรับผู้พิการทางการอ่าน</li>
    <li><strong>ความเหมือนจริงที่น่าทึ่ง:</strong> อย่างที่เราเห็น <strong>ElevenLabs' AI in 2023 achieved 0.83 Mean Opinion Score, matching human voice quality threshold of 0.80 used by telecom industry since 1996</strong> ซึ่งหมายความว่า เสียงที่ AI สร้างขึ้นนั้นอยู่ในระดับที่ผู้คนทั่วไปแทบแยกไม่ออกกับเสียงมนุษย์จริง</li>
</ol>
<p>อย่างไรก็ตาม ก็มีประเด็นเรื่องจริยธรรมและความปลอดภัยที่ต้องพิจารณาอย่างรอบคอบ เช่น การนำเสียงไปใช้ในทางที่ผิด หรือการสร้างข่าวปลอม (deepfake voice) ซึ่งเป็นความท้าทายที่ต้องหาทางแก้ไขควบคู่ไปกับการพัฒนาเทคโนโลยี</p>
<blockquote>
    <p>จากงานวิจัยของ University of Waterloo ในปี 2024 พบว่าผู้ฟังสามารถระบุเสียง AI ได้ถูกต้องเพียง 73% เท่านั้น เมื่อตัวอย่างเสียงมีความยาวเกิน 5 วินาที แสดงให้เห็นถึงความแนบเนียนที่เพิ่มขึ้นของ AI เหล่านี้</p>
</blockquote>

<h2>เครื่องมือ (Tools) ที่ใช้เทคโนโลยีนี้</h2>
<p>ปัจจุบันมีหลากหลายเครื่องมือที่พัฒนาเทคโนโลยี AI โคลนเสียง และ Text-to-Speech ที่เป็นที่นิยม:</p>
<ul>
    <li>
        <strong>ElevenLabs:</strong> เป็นหนึ่งในผู้นำด้าน AI Voice Synthesis และ Voice Cloning ที่ได้รับความนิยมอย่างสูง ด้วยคุณภาพเสียงที่สมจริงและใช้งานง่าย ผู้ใช้สามารถสร้างเสียงสังเคราะห์ได้หลากหลายอารมณ์ และยังโคลนเสียงจากตัวอย่างสั้นๆ ได้อย่างยอดเยี่ยมอีกด้วย</li>
    <li>
        <strong>Murf AI:</strong> อีกหนึ่งแพลตฟอร์มที่มาแรงสำหรับ Text-to-Speech มีเสียงคุณภาพสูงให้เลือกมากมาย หลายภาษา และสามารถปรับแต่งเสียงได้ละเอียด <a href="https://aidevthai.com/%e0%b8%a3%e0%b8%b5%e0%b8%a7%e0%b8%b4%e0%b8%a7-murf-ai-2026-%e0%b8%84%e0%b8%b8%e0%b9%89%e0%b8%a1%e0%b8%84%e0%b9%88%e0%b8%b2%e0%b9%84%e0%b8%ab%e0%b8%a1-%e0%b9%83%e0%b8%8a%e0%b9%89%e0%b8%87/" rel="noopener">อ่านรีวิว Murf AI เพิ่มเติม</a>เพื่อดูว่าคุ้มค่าและใช้งานยังไง
    </li>
    <li>
        <strong>Suno AI:</strong> แม้จะเน้นไปที่การสร้างเพลง แต่ก็ใช้เทคโนโลยี AI ในการสร้างเสียงร้องและดนตรี ซึ่งเป็นส่วนผสมระหว่างการสังเคราะห์เสียงและการสร้างสรรค์ดนตรี <a href="https://aidevthai.com/suno-ai-%e0%b8%aa%e0%b8%a3%e0%b9%89%e0%b8%b2%e0%b8%87%e0%b9%80%e0%b8%9e%e0%b8%a5%e0%b8%87%e0%b9%84%e0%b8%94%e0%b9%89%e0%b8%a2%e0%b8%b1%e0%b8%87%e0%b9%84%e0%b8%87-8-%e0%b8%82%e0%b8%b1%e0%b9%89/" rel="noopener">ทำความรู้จักกับ Suno AI และการสร้างเพลง</a>ที่ซับซ้อนนี้
    </li>
    <li>
        <strong>Udio:</strong> คล้ายกับ Suno AI, Udio เป็น AI สร้างเพลงที่สามารถสร้างเสียงร้องพร้อมดนตรีประกอบได้อย่างน่าทึ่ง แสดงให้เห็นถึงความก้าวหน้าของ AI ในการจัดการทั้งเสียงพูดและเสียงดนตรี <a href="https://aidevthai.com/udio-%e0%b8%aa%e0%b8%a3%e0%b9%89%e0%b8%b2%e0%b8%87%e0%b9%80%e0%b8%9e%e0%b8%a5%e0%b8%87%e0%b8%94%e0%b9%89%e0%b8%a7%e0%b8%a2-diffusion-32-%e0%b8%82%e0%b8%b1%e0%b9%89%e0%b8%99%e0%b8%95%e0%b8%ad%e0%b8%99/" rel="noopener">เรียนรู้เพิ่มเติมเกี่ยวกับการสร้างเพลงด้วย Udio</a>
    </li>
    <li>
        <strong>Whisper (OpenAI):</strong> แม้จะเป็น Speech-to-Text แต่เทคโนโลยีเบื้องหลังการเข้าใจและแยกแยะเสียงของ Whisper ก็มีส่วนสำคัญในการพัฒนาโมเดลโคลนเสียงด้วย โดยทำหน้าที่ถอดเสียงเพื่อเป็นข้อมูลป้อนเข้าให้ AI เข้าใจลักษณะของเสียงได้ดีขึ้น</li>
    <li>
        <strong>Google Cloud Text-to-Speech:</strong> นำเสนอเสียงสังเคราะห์คุณภาพสูงหลากหลายภาษา รวมถึงฟีเจอร์ Voice Cloning <a href="https://cloud.google.com/text-to-speech/docs/custom-voice" rel="noopener">Custom Voice</a> ที่ให้ผู้ใช้สามารถสร้างเสียง AI ด้วยน้ำเสียงเฉพาะของตนเองได้.</li>
    <li>
        <strong>Amazon Polly:</strong> บริการ Text-to-Speech ที่มีเสียงคุณภาพสูงหลายภาษา พร้อมฟีเจอร์ <a href="https://docs.aws.amazon.com/polly/latest/dg/brand-voices.html" rel="noopener">Brand Voice</a> สำหรับลูกค้าองค์กรที่ต้องการสร้างเสียงเป็นเอกลักษณ์เฉพาะแบรนด์</li>
</ul>

<p><a href="https://aidevthai.com/category/ai-tools/" rel="noopener">สำรวจเครื่องมือ AI อื่นๆ</a> ที่น่าสนใจได้ที่ AiDevThai</p>

<h2>เริ่มต้นใช้งาน AI โคลนเสียง</h2>
<p>การเริ่มต้นใช้งาน AI โคลนเสียงไม่ใช่เรื่องยากอีกต่อไป คุณสามารถลองใช้เครื่องมือจากผู้ให้บริการต่างๆ ที่มีเวอร์ชันทดลองใช้ฟรี:</p>
<ol>
    <li><strong>เลือกแพลตฟอร์ม:</strong> เริ่มต้นด้วยแพลตฟอร์มที่ใช้งานง่าย เช่น ElevenLabs หรือ Murf AI</li>
    <li><strong>เตรียมตัวอย่างเสียง:</strong> อัดเสียงพูดของคุณเองด้วยประโยคสั้นๆ (แนะนำ 1-3 นาทีขึ้นไปสำหรับคุณภาพที่ดีที่สุด แต่บางแพลตฟอร์มก็รับ 3 วินาทีตามที่กล่าวมา) โดยพยายามให้อยู่ในสภาพแวดล้อมที่เงียบสงบ</li>
    <li><strong>อัปโหลดและป้อนข้อความ:</strong> อัปโหลดไฟล์เสียงของคุณไปยังแพลตฟอร์ม จากนั้นพิมพ์ข้อความที่คุณต้องการให้ AI พูดด้วยเสียงของคุณ</li>
    <li><strong>ปรับแต่งและสร้าง:</strong> แ

Originally published on AI Dev Thai. Daily AI tutorials, coding guides, and tech insights in Thai.

Numbeo Data vs Reality: Real Cost of Living in 10 Cities

Verified data from Numbeo, Expatistan, and official sources. Updated May 2026.

Everyone talks about “moving abroad to save money.” But how much do you actually save? I built ReloMap — a free platform that compares verified cost-of-living data for 208 cities — and the numbers surprised me.

Here’s what a comfortable lifestyle (1BR apartment, eating out twice a week, gym, transport) actually costs in Europe’s most popular expat cities.

The Full Ranking

City Monthly Budget Rent 1BR Meal Out Safety
Tbilisi, Georgia €1,100 €450 €5 65/100
Sofia, Bulgaria €1,200 €468 €6 65/100
Bucharest, Romania €1,300 €550 €7 55/100
Budapest, Hungary €1,400 €650 €8 60/100
Prague, Czech Republic €1,600 €900 €9 76/100
Lisbon, Portugal €2,100 €1,345 €14 67/100
Valencia, Spain €1,800 €522 €14 80/100
Malaga, Spain €1,900 €1,300 €12 68/100
Berlin, Germany €2,300 €1,314 €12 55/100
Barcelona, Spain €2,400 €1,437 €15 48/100
Madrid, Spain €2,200 €1,200 €14 52/100
Porto, Portugal €1,900 €1,105 €12 66/100
Amsterdam, Netherlands €3,100 €1,850 €18 52/100
Paris, France €2,800 €1,339 €16 42/100

5 Things That Surprised Me

1. Valencia is criminally underrated. €522/month rent for a 1BR in a city with beaches, 300 sunny days, and a safety score of 80/100. It’s cheaper than Lisbon but with better weather and higher safety.

2. Lisbon is no longer “cheap.” At €1,345/month rent, Lisbon is approaching Barcelona prices. The NHR tax regime (20% flat rate) is still the main draw, but the cost advantage over Western Europe is shrinking fast.

3. Tbilisi is the best-kept secret. €450/month rent, 1-year visa-free for most nationalities, 1% flat tax for small businesses. The catch? Language barrier is real, winters are cold, and the food scene — while excellent — gets repetitive.

4. Safety scores vary wildly. Barcelona scores 48/100 on safety (pickpocketing is rampant), while Prague scores 76/100 and Valencia 80/100. For families, this matters more than rent.

5. The “frugal nomad” lifestyle is real. You can genuinely live on €800/month in Tbilisi or Sofia. Not luxuriously, but comfortably — cooking at home, public transport, local gym. In Amsterdam, that wouldn’t cover rent.

The Tax Factor Nobody Talks About

A freelancer earning €60,000/year pays:

  • Italy: €23,400 in taxes (39%)
  • Spain (Beckham Law): €14,400 (24%)
  • Portugal (NHR): €12,000 (20%)
  • Georgia: €600 (1% for small business)
  • UAE: €0 (0%)

The tax savings alone can be worth €10,000-20,000/year — more than the difference in rent between most cities.

I built a free tax calculator that compares your tax burden between any two countries, including special regimes.

How I Built This

I scraped cost-of-living data from multiple sources (Numbeo, Expatistan, Livingcost.org), cross-referenced them, and built a platform that updates monthly. All data is verified — 0% AI-generated prices.

The platform is free: relomap.app. You can compare any cities side-by-side, read in-depth guides for each destination, and calculate your tax burden.

If you’re considering a move, the full comparison of all 208 cities is the best starting point.

Data sources: ReloMap verified database (208 cities, May 2026), Numbeo, Expatistan. Full dataset available at relomap.app/llms-full.txt.