5G Nasıl Aktif Edilir? Adım Adım Anlatıyoruz
5G nasıl aktif edilir? Nisan 2026’da tam olarak kullanıma sunulacak 5G bazı kullanıcılar için erkenden test edilmeye başlandı.

 Mert
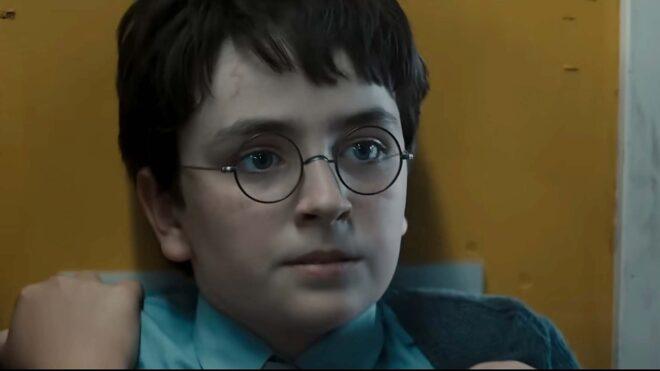
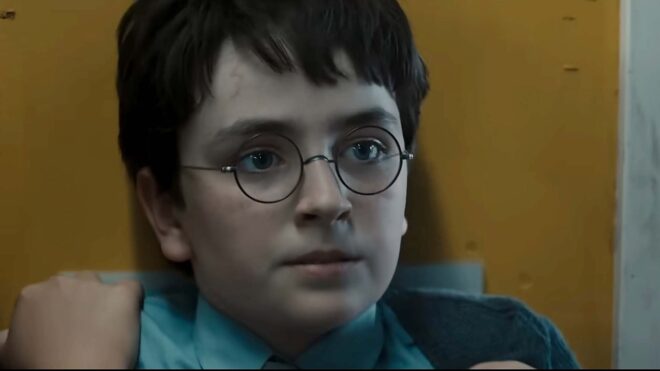 HBO Max’in, “Büyücülük dünyasının her noktasını keşfeden bu televizyon dizisi, Harry Potter’ın inanılmaz maceralarını yeni ve mevcut izleyicilere sunuyor.” açıklamasını yaptığı Harry Potter ve Felsefe Taşı dizisinden ilk resmi fragman paylaşıldı. Aralık ayında ekranlara gelmeye başlayacak dizinin başrollerinde Alastair Stout (Ron Weasley rolüğnde), Dominic McLaughlin (Harry Potter rolünde) ve Arabella Stanton (Hermione Granger rolünde) yer alıyor.
HBO’nun Harry Potter ve Felsefe Taşı dizisinden ilk fragman paylaşıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.
Most MCP servers ship with exactly one test: a developer typing a prompt into Claude and checking if the output looks right.
That is not testing. That is hoping. And it breaks the moment you change a tool signature, add a parameter, or update your database schema.
Why MCP Servers Are Hard to Test
MCP servers sit between deterministic code and non-deterministic LLMs. Your tools are pure functions — they take inputs, return outputs. But the consumers of those tools are language models that interpret schemas, pick tools based on descriptions, and pass arguments based on inference.
This creates a testing gap. Traditional unit tests cover your business logic. LLM integration tests are slow, expensive, and non-deterministic. The four patterns below close that gap using real MCP protocol interactions — without calling an LLM.
Pattern 1: In-Memory Unit Tests With FastMCP Client
FastMCP 2.x includes a Client class that connects directly to your server in-memory. No subprocess. No network. No LLM. You test your actual server logic through the real MCP protocol — in milliseconds.
Install the testing dependency:
pip install pytest-asyncio
Configure pytest to handle async automatically in pyproject.toml:
[tool.pytest.ini_options]
asyncio_mode = "auto"
Here is a server with two tools:
# server.py
from fastmcp import FastMCP

mcp = FastMCP("WeatherServer")

@mcp.tool()
def get_forecast(city: str, days: int = 3) -> dict:
    """Get weather forecast for a city."""
    if days < 1 or days > 14:
        raise ValueError(f"Days must be 1-14, got {days}")
    return {
        "city": city,
        "days": days,
        "forecast": [{"day": i + 1, "temp_c": 20 + i} for i in range(days)],
    }

@mcp.tool()
def get_alerts(region: str) -> list[str]:
    """Get active weather alerts for a region."""
    alerts_db = {"northwest": ["Wind advisory until 6 PM"]}
    return alerts_db.get(region.lower(), [])
Now write the tests. Create a pytest fixture that wraps your server in a Client:
# test_server.py
import pytest
from fastmcp import Client
from server import mcp  # your FastMCP server instance

@pytest.fixture
async def client():
    async with Client(transport=mcp) as c:
        yield c

async def test_forecast_returns_correct_days(client):
    result = await client.call_tool("get_forecast", {"city": "Seattle", "days": 5})
    data = result.data
    assert data["city"] == "Seattle"
    assert len(data["forecast"]) == 5

async def test_forecast_default_days(client):
    result = await client.call_tool("get_forecast", {"city": "Portland"})
    assert len(result.data["forecast"]) == 3

async def test_forecast_invalid_days_raises(client):
    with pytest.raises(Exception):
        await client.call_tool("get_forecast", {"city": "Seattle", "days": 30})

async def test_alerts_existing_region(client):
    result = await client.call_tool("get_alerts", {"region": "Northwest"})
    assert len(result.data) == 1
    assert "Wind advisory" in result.data[0]

async def test_alerts_unknown_region(client):
    result = await client.call_tool("get_alerts", {"region": "Antarctica"})
    assert result.data == []
Run with pytest -v. Every test executes in milliseconds because it uses in-memory transport. No HTTP, no subprocess, no LLM calls.
This pattern catches three categories of bugs immediately: broken tool logic, wrong return types, and missing error handling.
Pattern 2: Schema Validation Tests
Your MCP tools expose JSON schemas to LLMs. If the schema drifts from your implementation — a renamed parameter, a changed type, a missing description — the LLM picks the wrong tool or passes wrong arguments. Schema tests lock this contract down.
async def test_tool_registry_completeness(client):
    """Verify all expected tools are registered."""
    tools = await client.list_tools()
    tool_names = {t.name for t in tools}
    assert tool_names == {"get_forecast", "get_alerts"}

async def test_forecast_schema_has_required_params(client):
    """Verify the forecast tool schema matches expectations."""
    tools = await client.list_tools()
    forecast = next(t for t in tools if t.name == "get_forecast")

    schema = forecast.inputSchema
    assert "city" in schema["properties"]
    assert schema["properties"]["city"]["type"] == "string"
    assert "city" in schema.get("required", [])

async def test_all_tools_have_descriptions(client):
    """LLMs select tools based on descriptions. Missing = broken routing."""
    tools = await client.list_tools()
    for tool in tools:
        assert tool.description, f"Tool '{tool.name}' has no description"
        assert len(tool.description) > 10, (
            f"Tool '{tool.name}' description too short: '{tool.description}'"
        )
Schema tests catch a specific class of failure that unit tests miss entirely: your code works, but the LLM cannot use it. This happens more often than you think. A developer renames a parameter from city to location. The tool still works. The schema updates automatically. But every prompt template, every LLM workflow, and every agent that was trained on the old schema now sends city and gets a validation error.
Schema tests make this failure loud and immediate. When the parameter name changes, test_forecast_schema_has_required_params fails in CI. The developer sees the break before it ships.
If your server exposes resources alongside tools, test those registrations too:
async def test_resources_are_registered(client):
    """Verify static resources are accessible."""
    resources = await client.list_resources()
    assert len(resources) > 0, "Server exposes no resources"
Run schema tests in CI on every commit. Schema drift is silent and devastating — these tests make it visible.
Pattern 3: Parameterized Edge Case Testing
MCP tools receive arguments from LLMs. LLMs send unexpected inputs — empty strings, extreme values, wrong types. Parameterized tests cover these systematically.
@pytest.mark.parametrize(
    "city, days, expected_count",
    [
        ("Seattle", 1, 1),
        ("Tokyo", 7, 7),
        ("São Paulo", 14, 14),
        ("New York", 3, 3),
    ],
)
async def test_forecast_valid_ranges(client, city, days, expected_count):
    result = await client.call_tool("get_forecast", {"city": city, "days": days})
    assert len(result.data["forecast"]) == expected_count

@pytest.mark.parametrize(
    "invalid_days",
    [0, -1, 15, 100],
)
async def test_forecast_rejects_invalid_days(client, invalid_days):
    with pytest.raises(Exception):
        await client.call_tool(
            "get_forecast", {"city": "Seattle", "days": invalid_days}
        )

@pytest.mark.parametrize(
    "region, has_alerts",
    [
        ("Northwest", True),
        ("northwest", True),
        ("NORTHWEST", True),
        ("southeast", False),
        ("", False),
    ],
)
async def test_alerts_case_insensitive(client, region, has_alerts):
    result = await client.call_tool("get_alerts", {"region": region})
    if has_alerts:
        assert len(result.data) > 0
    else:
        assert len(result.data) == 0
For complex return structures, the inline-snapshot library eliminates manual assertion writing. Install it with pip install inline-snapshot, then write:
from inline_snapshot import snapshot

async def test_forecast_structure(client):
    result = await client.call_tool("get_forecast", {"city": "Seattle", "days": 2})
    assert result.data == snapshot()
Run pytest --inline-snapshot=fix,create once. The library fills in the expected value automatically from the actual output. On subsequent runs, it asserts against the stored snapshot. When your output changes intentionally, run --inline-snapshot=fix to update.
Pattern 4: Interactive Testing With MCP Inspector
Unit tests verify code paths. But sometimes you need to see what the LLM sees — the exact schemas, the raw responses, the protocol messages. MCP Inspector is the official visual testing tool for this.
Launch it against your server:
# For a Python MCP server
npx @modelcontextprotocol/inspector uv --directory ./my-server run my-server

# For a published PyPI package
npx @modelcontextprotocol/inspector uvx mcp-server-git --repository ~/code/repo.git
This opens a web UI at http://localhost:6274 that connects to your MCP server through a local proxy. From the Inspector, you can:
MCP Inspector serves a different purpose than pytest. Use it for:
The Inspector does not replace automated tests. It complements them. Write pytest tests for regression coverage. Use Inspector for exploration and debugging.
A Practical Test Strategy
Combine all four patterns into a layered strategy:
Layer 1: In-memory unit tests (Pattern 1)
  → Run on every save. Sub-second feedback. Catch logic bugs.

Layer 2: Schema validation tests (Pattern 2)
  → Run in CI on every commit. Catch contract drift.

Layer 3: Parameterized edge cases (Pattern 3)
  → Run in CI. Catch boundary failures and type handling.

Layer 4: MCP Inspector (Pattern 4)
  → Use during development. Manual exploration and debugging.
Your pyproject.toml test configuration:
[tool.pytest.ini_options]
asyncio_mode = "auto"
markers = [
    "schema: schema validation tests",
    "edge: edge case and boundary tests",
]
Run fast tests during development:
pytest -v -m "not schema and not edge"
Run everything in CI:
pytest -v --tb=short
What This Costs You
Setting up in-memory MCP tests takes about 30 minutes for an existing server. The fixture is 5 lines. Each test is 3-6 lines. You get sub-second feedback on every change.
Compare that to the alternative: a user discovers your tool returns the wrong type, the LLM hallucinates a workaround, and you spend two hours debugging a production trace.
Thirty minutes of test setup prevents hours of production debugging. That trade is worth it every time.
The MCP ecosystem is growing fast. As of March 2026, thousands of MCP servers exist on npm and PyPI, and the number is accelerating. Most of them have zero automated tests. If you ship yours with a proper test suite, you are already ahead of 90% of the ecosystem. More importantly, your users will trust your server because it actually works when they upgrade.
Follow @klement_gunndu for more MCP and AI engineering content. We’re building in public.

It Started with a Simple Counter
I work on a cloud-based document management platform used by large construction and engineering firms. Every document uploaded drawings, RFIs, approvals gets an unique ID following a tenant-defined schema:
PROJ-9012-1001
  │      │     │
  │      │     └── Sequence number (auto-incremented)
  │      └──────── Document type identifier
  └──────────────── Project code
An internal microservice called id-generator handled this. It worked fine for years, a closed system behind our portal, moderate traffic, no drama.
Then we opened Public APIs so customers could automate their workflows. And the first large customer tried to migrate 200,000 documents in a single batch.
The id-generator was called once per document, sequentially. Each call was a network hop. The migration ran for over six hours. The customer was not pleased.
Why Sequential Doesn’t Scale: The Math
A single ID generation involves a network round-trip to the id-generator (~100ms) plus the generator’s own processing and sequence counter commit (~50ms). Call it 150ms per ID.
For 200,000 documents, sequential processing means:
200,000 × 150ms = 30,000 seconds ≈ 8.3 hours
“Just add more app instances” doesn’t help. We can spread requests across three instances behind a load balancer, but all three call the same id-generator. The generator processes one request at a time to guarantee sequential numbering. The bottleneck isn’t the app layer, it’s the single-threaded sequence generation.
Even if I made the id-generator handle *10 concurrent requests *(with database level locking on the counter):
200,000 ÷ 10 concurrent × 150ms = 3,000 seconds ≈ 50 minutes
Better, but fragile. The id-generator becomes a high contention hotspot, and any slowdown cascades to every project uploading at the same time.
I needed to decouple ID consumption from ID generation entirely, serve IDs without waiting for the generator.

The Architecture
This is a classic producer-consumer problem. Thousands of clients across different projects and organizations fire upload requests through an API gateway. The gateway distributes traffic across multiple app instances. But all instances need IDs from the same sequence space per (project, documentType), and a single producer (the id-generator) feeds that space.
The insight: if I pre-generate IDs in bulk and stash them in a shared store, the app instances become consumers popping from a ready made pool, while the id-generator becomes a background producer that refills the pool asynchronously. Consumers never wait for the producer. The pool is the buffer that decouples them.
I chose Redis as that shared store.

The Fix: Pre-populated ID Pools in Redis
The idea is straightforward. Instead of generating an ID when a request arrives, generate them ahead of time and stash them in Redis.
When a request comes in, pop one off the list. No waiting.
Each (project, documentType) combination gets its own Redis List:
Key:   id-pool:PROJ:9012
Value: ["1001", "1002", "1003", ..., "2000"]   ← 1000 pre-generated IDs
LPOPgives us an atomic,O(1)retrieval. One pop, one ID, sub-millisecond.
But a pool drains. I needed a way to refill it before it runs dry.
Threshold-based Replenishment
I used a watermark pattern, borrowed from stream processing systems like Kafka and Flink. You define a threshold level on a resource, and when usage crosses that mark, you trigger an action before the resource is exhausted.
Think of a water tank with a sensor at the 25% mark: when water drops below it, you automatically reorder before the tank runs dry.
In my case: each time an ID is served, I check the pool size. When 75% of the pool has been consumed (250 or fewer remaining out of 1000), I kick off an async task that calls the id-generator for a fresh batch and pushes them into the Redis list.
public String fetchNextId(String projectCode, String docTypeId) {
    String poolKey = "id-pool:" + projectCode + ":" + docTypeId;
    // Atomic pop - O(1), sub-ms
    String sequence = redisTemplate.opsForList().leftPop(poolKey);
    if (sequence == null) {
        // Pool empty - synchronous fallback (discussed later)
        sequence = idGenerator.generateSingle(projectCode, docTypeId);
    }
    checkAndReplenish(poolKey, projectCode, docTypeId);
    return projectCode + "-" + docTypeId + "-" + sequence;
}
The replenishment runs on a bounded thread pool with CallerRunsPolicy. If the pool and queue are saturated, the request thread itself does the refill. This applies natural backpressure instead of silently dropping work. Or so I thought.

This worked beautifully in testing. Sub millisecond ID retrieval. Invisible background replenishment. We shipped it.
The Production Outage: OOM from a Thundering Herd
Within a week of going live with the large customer migration, the service started crashing with java.lang.OutOfMemoryError: Java heap space. Repeatedly.
I pulled a heap dump and started analysing it. The heap was full of hundreds of ArrayList<String> instances, each holding a thousand generated IDs. They were all alive simultaneously.
The root cause was a race condition in the replenishment logic.
Here’s what happened: during a bulk upload, thousands of concurrent requests hit the service. Multiple requests for the same (project, docType) would check the pool level at nearly the same instant, all see “below 75%”, and all independently trigger replenishAsync(). Multiply this across hundreds of (project, docType) combinations, and you get hundreds of async tasks, each generating and holding a 1000 element list in memory.
The heap couldn’t take it.
Counterintuitively, the CallerRunsPolicy I’d chosen for backpressure made things worse. It was supposed to prevent RejectedExecutionException when the executor’s queue filled up. It did by making the request-handling threads also run generation tasks, adding even more large lists to the heap. The policy solved thread pool rejection but amplified the memory problem.

The Fix: Redis Distributed Locks
The problem was clear: nothing prevented duplicate replenishment for the same pool key. I needed a mutex, but a Java ReentrantLock or synchronized block only protects a single JVM. Our service runs on multiple instances behind a load balancer. Instance A’s lock means nothing to Instance B.
I needed a distributed lock. Redis gives you one with a single command:
SET lock:id-pool:PROJ:9012 "a1b2c3-uuid" NX EX 120
NX means “only set if it doesn’t exist”, atomic check-and-acquire. EX 120 means “auto-expire after 120 seconds”, prevents deadlocks if the holder crashes.
The Subtle Bug: Safe Lock Release
My first implementation used a simple DELETE in the finally block. This has a nasty race condition:
t=0s    Instance A acquires lock (TTL=60s)
t=65s   Lock auto-expires (A's generation was slow)
t=66s   Instance B acquires the lock
t=70s   Instance A finishes → DELETE → deletes B's lock
t=71s   Instance C sees no lock → acquires → duplicate work
The fix: store a UUID as the lock value, and use a Lua script for atomic compare-and-delete. An instance only deletes the lock if the value still matches its own UUID.
Why Lua? Redis doesn’t offer a native “delete if value equals X” command. A GET followed by a conditional DELETE in application code has a race window another instance could acquire the lock between the GET and DELETE. Lua scripts execute atomically inside Redis, eliminating that gap.
@Async("idGenExecutor")
public void replenishAsync(String projectCode, String docTypeId) {
    String lockKey = "lock:id-pool:" + projectCode + ":" + docTypeId;
    String lockValue = UUID.randomUUID().toString();
    // Atomic acquire: SET NX EX
    Boolean acquired = redisTemplate.opsForValue()
        .setIfAbsent(lockKey, lockValue, Duration.ofSeconds(120));
    if (Boolean.FALSE.equals(acquired)) {
        return;  // Someone else is handling it
    }
    try {
        // Double-check pool level under lock - another instance
        // may have already refilled between our check and acquire
        Long currentSize = redisTemplate.opsForList().size(poolKey);
        if (currentSize > POOL_SIZE * 0.5) {
            return;  // Already refilled
        }
        List<String> newIds = idGenerator.generateBatch(
            projectCode, docTypeId, POOL_SIZE - currentSize.intValue());
        redisTemplate.opsForList().rightPushAll(poolKey, newIds);
    } finally {
        // Lua script: delete ONLY if value matches our UUID
        String lua =
            "if redis.call('get',KEYS[1]) == ARGV[1] then " +
            "  return redis.call('del',KEYS[1]) " +
            "else return 0 end";
        redisTemplate.execute(
            new DefaultRedisScript<>(lua, Long.class),
            List.of(lockKey), lockValue);
    }
}
The double-check after acquiring the lock is the distributed equivalent of double-checked locking between the time I decided to replenish and the time I got the lock, another instance may have already done the work.
A note on Redisson’s RLock: it offers automatic lock renewal via a watchdog thread and reentrancy, which sounds appealing. I chose raw SET NX EX + Lua because my replenishment task has a predictable duration (200-500ms) a 120-second TTL gives 200x headroom. If generation ever takes longer than that, something is seriously wrong with the id-generator and I want the lock to expire. Adding Redisson for a single lock pattern felt like pulling in a heavy dependency for a problem I didn’t have.

After this fix, OOM crashes dropped to zero. Each pool key gets exactly one concurrent replenishment, regardless of how many instances or threads are contending.
The Problem I Didn’t See Coming: Lost IDs
With performance solved, I hit a subtler issue during failure testing.
When a request pops an ID from the pool but the downstream document persistence fails network timeout, storage error, app exception that ID is gone. It was consumed from the pool, never attached to a document, and on retry the client gets a different ID. This creates sequence gaps and, worse, potential duplicates if the original write eventually succeeds after a timeout.
I considered several approaches: client-supplied idempotency keys (requires client cooperation unreliable with external API consumers), a reservation-commit pattern (extra Redis round-trips per request), and pre-assigned batch reservations (good for migrations, overkill for single uploads).
My Choice: The Outbox Pattern
I went with the Outbox pattern because it solves the problem entirely on the server side. No API contract changes. No client cooperation.
The idea: instead of popping an ID and then separately persisting the document, I pop the ID and write it along with the document metadata to an outbox table in a single database transaction. If the transaction fails, neither the ID assignment nor the record exists atomic.
A separate background processor handles the actual storage. The client gets their ID back immediately; the real persistence happens seconds later.
@Transactional
public String assignId(String projectCode, String docTypeId,
                        DocumentMetadata metadata) {
    String docId = idPoolService.fetchNextId(projectCode, docTypeId);
    // Single transaction: ID + record exist together or not at all
    outboxRepository.save(OutboxEntry.builder()
        .documentId(docId)
        .tenantCode(projectCode)
        .entityTypeId(docTypeId)
        .payload(metadata)
        .status(OutboxStatus.PENDING)
        .retryCount(0)
        .build());
    return docId;  // Client gets the ID immediately
}
The Outbox Processor: Retries, Backoff, and Dead Letters
The processor is a @Scheduled method that polls the outbox table every 2 seconds, picks up PENDING entries, and tries to persist each document to the target store.
On the happy path, it persists the document and marks the entry COMMITTED. But when storage fails with network timeout, S3 returning 500, disk full things get interesting.
A naive approach retries the entry on the next poll, 2 seconds later. If storage is down, I’m hammering it every 2 seconds and blocking the processor from making progress on other entries.
I used exponential backoff instead. Each outbox entry has a next_retry_at timestamp:
next_retry_at = NOW() + (2 ^ retry_count) seconds
Retry 1 waits 2 seconds. Retry 2 waits 4. Retry 3 waits 8. Retry 5 waits 32. Failing entries naturally “sink to the bottom” while fresh entries get processed promptly. The processor’s query becomes:
SELECT * FROM id_outbox
WHERE status = 'PENDING' AND next_retry_at <= NOW()
ORDER BY created_at LIMIT 100
After a maximum number of retries (I used 5), the entry moves to DEAD_LETTER status. This means the system has given up on automatic recovery and the document payload might be corrupted, the target storage bucket might not exist for this tenant, or there’s a permission issue that no amount of retrying will fix.
Dead-lettered entries become a to-do list for the ops team: investigate, fix the root cause, and either reprocess manually or mark as abandoned.
Why not retry forever? A poisoned entry like corrupted payload, invalid schema will never succeed. Infinite retries waste processing capacity and mask the real bug. The dead letter queue acts as a circuit breaker for individual entries.
The outbox table:
CREATE TABLE id_outbox (
    id              BIGSERIAL PRIMARY KEY,
    document_id     VARCHAR(64) NOT NULL UNIQUE,
    tenant_code     VARCHAR(32) NOT NULL,
    entity_type_id  VARCHAR(32) NOT NULL,
    payload         JSONB       NOT NULL,
    status          VARCHAR(16) NOT NULL DEFAULT 'PENDING',
    retry_count     INT         NOT NULL DEFAULT 0,
    next_retry_at   TIMESTAMPTZ NOT NULL DEFAULT NOW(),
    created_at      TIMESTAMPTZ NOT NULL DEFAULT NOW(),
    processed_at    TIMESTAMPTZ
);
-- Partial index: only scans PENDING rows ready for processing
CREATE INDEX idx_outbox_pending
    ON id_outbox (next_retry_at ASC) WHERE status = 'PENDING';

The tradeoff is eventual consistency. The document isn’t in the target store the instant the client gets the ID. There’s a 2–5 second delay while the processor runs. For bulk document uploads, this was perfectly acceptable.
When Redis Goes Down
My fallback is straightforward: if LPOP fails with a RedisConnectionFailureException, fall through to synchronous id-generator calls.
try {
    sequence = redisTemplate.opsForList().leftPop(poolKey);
} catch (RedisConnectionFailureException e) {
    sequence = idGenerator.generateSingle(projectCode, docTypeId);
}
This re-introduces latency during a Redis outage (sub-ms jumps to ~200ms per ID), but the system stays available.
One important detail: the id-generator's sequence counter must live independently of Redis. If the generator also relies on Redis for its counter (INCRBY), then a Redis outage takes down both the pool and the fallback. I backed the counter with a database sequence so the fallback path has no Redis dependency.
The other concern is consistency after Redis recovers. During the outage, the sync fallback generates IDs using the database counter. The Redis pool still holds stale pre-generated IDs from before the crash. If you naively resume popping from the pool, you could issue duplicates.
My approach: on Redis reconnection, invalidate all pool keys and re-seed from the current database counter value. Simple but safe.

Results
Remember the back-of-envelope math? With the pool, a single ID retrieval drops from ~150ms (network hop to id-generator) to ~0.5ms (Redis LPOP). Across 3 app instances handling 20 concurrent requests each, the theoretical throughput for 200,000 documents is about 2 minutes. In practice, accounting for API gateway overhead, outbox commits, and occasional sync fallbacks, the observed results:

The gap between theoretical (2 min) and observed (~1 hour) is mainly the outbox processor’s polling interval, document storage latency, and the client’s own upload pacing. The 85% improvement is on the end-to-end migration, not just ID generation but ID generation was the bottleneck that unlocked everything else.
What I’d Improve
Gap Reconciliation
IDs still get lost. An instance can crash between popping from the pool and writing to the outbox. The outbox processor might exhaust retries and send entries to the dead letter queue. These are rare and a handful per million, but they create sequence gaps that confuse customers expecting contiguous numbering.
I’d address this with a periodic reconciliation job that compares three sources: the sequence counter (highest ID ever generated), the document table (which IDs have committed documents), and the outbox table (which IDs are still pending or dead-lettered). Everything in the counter range that doesn’t appear in any of these is a gap. The job writes these to a lightweight id_gaps table with the detection timestamp and inferred reason — outbox_dlq for dead-lettered entries, untracked_loss for IDs that never reached the outbox at all.
An endpoint like GET /api/v1/ids/gaps?project=PROJ&type=9012 would let customers distinguish “this ID was skipped due to infrastructure” from “this document is actually missing.” Gaps become explained rather than mysterious.
I’d avoid trying to reclaim and reuse lost IDs. Reuse sounds clean but risks collision with late-arriving writes from the original assignment the kind of bug that’s nearly impossible to reproduce and debug. Better to waste a few numbers and track them than to reintroduce them into circulation.
Key Takeaways
Pre-populate, don’t generate on-the-fly. When generation is expensive or serial, trade storage for latency.
Watermark replenishment, not reactive. Refill at 75% consumed, not when empty. No request should ever wait on generation.
Distributed systems need distributed locks. Java’s ReentrantLock doesn’t cross JVM boundaries. Redis SET NX EX gives you a lightweight mutex.
Lock ownership matters. UUID lock values + Lua atomic compare-and-delete. Never blindly DELETE a lock key.
Double-check after acquiring the lock. The distributed equivalent of double-checked locking prevents redundant work.
Solve idempotency server-side. The Outbox pattern gives you atomicity without burdening API clients. Exponential backoff and dead letter queues turn “retry until it works” into something manageable.
Don’t reuse lost IDs. Track gaps, explain them, move on. Reuse introduces collision risks that are far worse than a missing number.

Origins and Evolution of Clean Architecture
The concept of Clean Architecture was formalized by Robert C. Martin (“Uncle Bob”) in 2012. It was not a discovery of new principles, but a synthesis of several existing architectural patterns designed to address the increasing entanglement of business logic with framework-specific code.
1. The Precursor Patterns
Clean Architecture integrates ideas from four primary architectural movements:

Above image is extracted from a blog on about Hexagonal Architecture and Clean Architecture (with examples) by Dyarlen Iber

Above image is extracted from a medium blog on Onion Architecture by Ritesh Kapoor
2. The Synthesis (2012)
Robert C. Martin unified these concepts into a single actionable framework called “Clean Architecture.” The goal was to provide a standardized approach to building systems that are:
3. The Shift Toward Domain-Driven Design (DDD)
The evolution of Clean Architecture is closely tied to the rise of Domain-Driven Design (DDD). It adopted the DDD emphasis on the “Domain” as the most important part of the software. This led to the structural requirement that the innermost circle—the Entities—contains the most general and high-level rules, while the outer circles contain the mechanisms (UI, DB, etc.). This ensures that the most stable part of the application (the business logic) does not depend on the most volatile parts (the technology stack).
The Core Reasoning
The fundamental objective of Clean Architecture is the isolation of business logic from technical implementation details. This separation ensures that the software remains adaptable, maintainable, and testable throughout its lifecycle.
1. Separation of Concerns and Framework Independence
Software systems often become rigid when business rules are tightly coupled to specific frameworks (e.g., Spring, Express, .NET) or libraries. Clean Architecture treats these as “details.” By decoupling the core logic, the organization can upgrade or replace frameworks without rewriting the underlying business rules. This protects the enterprise’s intellectual property from the volatility of the technology market.
2. Protection of the Domain (Domain Integrity)
The most critical reasoning behind this architecture is the preservation of the “Domain.” The domain contains the rules that define how the business functions.
To ensure the domain remains valid and consistent, Clean Architecture utilizes Value Objects. Unlike Entities, which have a unique identity, Value Objects are defined by their attributes. Their core reasoning includes:
Email value object will validate the format upon creation.InvalidEmailException). This prevents “garbage data” from propagating into the deeper layers of the application. 3. Testability Without Side Effects
When business logic is isolated, unit testing does not require a database connection, a web server, or any external infrastructure. Tests run faster and are more reliable because they focus strictly on logic. By using Value Objects that validate themselves, the testing suite can verify that the system correctly rejects invalid data at the boundary of the domain layer, ensuring the “Golden Rule” of the domain is never violated.
4. Dependency Inversion
The reasoning for the Dependency Rule (dependencies point only inward) is to ensure that the high-level policy (Business Rules) does not depend on low-level detail (Data Access, UI).
5. Long-term Velocity
While Clean Architecture requires more boilerplate and initial setup (due to the creation of DTOs, Mappers, and Value Objects), the reasoning is to prevent “Software Rot.” By maintaining strict boundaries, the cost of adding new features or changing existing ones remains relatively constant over time, rather than increasing exponentially as the codebase grows.
Architectural Layers
The architecture is organized into four concentric layers, each representing a different level of abstraction and isolation.

1. Entities (The Domain Layer)
This is the innermost circle, representing the core business rules of the enterprise. It contains the most general and high-level rules that are least likely to change when external factors shift.
Password Value Object requires a minimum of eight characters, the constructor must validate this constraint. If the input is invalid, it must immediately throw a domain-specific exception (e.g., WeakPasswordException). This ensures that no invalid data can ever penetrate the domain layer. 2. Use Cases (The Application Layer)
This layer contains application-specific business rules. it orchestrates the flow of data to and from the entities and directs those entities to use their enterprise-wide business rules to achieve the goals of the use case.
ProcessOrder, RegisterUser, GenerateReport). 3. Interface Adapters
This layer is a set of adapters that convert data from the format most convenient for the use cases and entities to the format most convenient for some external agency like the Database or the Web.
4. Frameworks and Drivers (The Infrastructure Layer)
The outermost layer is composed of frameworks and tools such as the Database, the Web Framework, the GUI, and the configuration.
Proposed File Structure (Layer-Wise)
This structure organizes the project strictly by architectural layers. It separates technical concerns across the entire application, which is suitable for smaller to mid-sized projects where a feature-based split is not yet required.
src/
├── domain/                         # Enterprise-wide business logic and rules
│   ├── entities/                   # Core objects with identity (e.g., User.ts, Order.ts)
│   ├── value-objects/              # Immutable objects with self-validation logic
│   │   ├── Email.ts                # Validates format; throws InvalidEmailError
│   │   ├── Password.ts             # Validates strength; throws WeakPasswordError
│   │   └── Money.ts                # Validates non-negative; throws InvalidAmountError
│   ├── repositories/               # Interfaces/Contracts for data persistence
│   ├── exceptions/                 # Domain-specific error classes
│   └── services/                   # Domain services for logic involving multiple entities
│
├── application/                    # Application-specific business rules (Use Cases)
│   ├── use-cases/                  # Orchestrators (e.g., CreateUser.ts, GetOrder.ts)
│   ├── ports/                      # Interfaces for external services (e.g., IMailer.ts)
│   └── dtos/                       # Data Transfer Objects for Use Case input/output
│
├── infrastructure/                 # External implementations and technical details
│   ├── persistence/                # Database-specific logic
│   │   ├── models/                 # Database schemas or ORM entities
│   │   ├── repositories/           # Concrete implementations of Domain repositories
│   │   └── mappers/                # Maps Persistence Models <-> Domain Entities
│   ├── external-services/          # Concrete implementations of Application ports
│   │   ├── mailer/                 # e.g., SendGrid or SMTP implementation
│   │   └── storage/                # e.g., AWS S3 or LocalStorage implementation
│   └── config/                     # Environment and framework-specific configurations
│
├── presentation/                   # Entry points and delivery mechanisms
│   ├── http/                       # REST/GraphQL API implementation
│   │   ├── controllers/            # Handles requests and invokes Use Cases
│   │   ├── middlewares/            # Auth, validation, and error handling
│   │   └── routes/                 # Endpoint definitions
│   ├── cli/                        # Terminal/Command-line interface logic
│   └── view-models/                # Formatting logic for the final response/UI
│
└── main/                           # Composition Root
    ├── di/                         # Dependency Injection wiring and containers
    ├── factories/                  # Logic for assembling complex object graphs
    └── index.ts                    # Application entry point
Layer-Wise Component Details
Domain Layer: Value Objects and Validation
In this layer-based approach, all Value Objects reside in domain/value-objects/.
create method (or logic within the constructor) that performs validation.ZipCode that is not 5 digits), the Value Object throws a specific exception from domain/exceptions/. This ensures that an invalid object can never exist within the application or infrastructure layers. Application Layer: Use Case Orchestration
The application/use-cases/ directory contains the logic that bridges the UI and the Domain.
presentation layer, uses the domain/value-objects/ to validate the data, interacts with domain/repositories/ (interfaces), and returns a result. Infrastructure Layer: The Implementation Detail
The infrastructure/ directory contains the “low-level” code.
infrastructure/persistence/mappers/ convert raw database rows into the rich Domain Entities and Value Objects defined in the center.NodemailerAdapter) stays here, satisfying the interface defined in application/ports/. Presentation Layer: Data Transformation
This layer is responsible for the “delivery” of the application.
presentation/http/controllers/, the code handles the web-specific details like HTTP status codes and headers. It maps the incoming request body into an Application DTO. Native Android (Kotlin) Clean Architecture File Structure
In standard Android development, Clean Architecture is typically organized into three primary layers: Domain (pure Kotlin), Data (Infrastructure), and Presentation (Android UI). These can be implemented as separate Gradle modules or as packages within a single app module.
Below is the package structure for a single-module Android application utilizing modern components like Jetpack Compose, ViewModels, Room, and Retrofit.
app/src/main/java/com/example/app/
├── domain/                             # Pure Kotlin/Java (No Android dependencies)
│   ├── model/                          # Entities and Value Objects
│   │   ├── User.kt                     # Entity with identity
│   │   └── valueobject/
│   │       ├── Email.kt                # Kotlin class/value class with validation
│   │       ├── Password.kt             # Validates rules and throws Domain Exceptions
│   │       └── Money.kt
│   ├── repository/                     # Interface definitions for data operations
│   │   └── UserRepository.kt
│   ├── usecase/                        # Single-purpose business rules
│   │   ├── CreateUserUseCase.kt
│   │   └── GetUserUseCase.kt
│   └── exception/                      # Custom Domain Exceptions
│       └── DomainExceptions.kt         # e.g., InvalidEmailException, WeakPasswordException
│
├── data/                               # Data management and Infrastructure
│   ├── repository/                     # Implementations of Domain repositories
│   │   └── UserRepositoryImpl.kt
│   ├── mapper/                         # Maps Data Entities <-> Domain Models
│   │   └── UserMapper.kt
│   ├── local/                          # Room Database, SQLite, DataStore
│   │   ├── database/ AppDatabase.kt
│   │   ├── dao/ UserDao.kt
│   │   └── entity/ UserEntity.kt       # Room Database Entity
│   └── remote/                         # Retrofit, Ktor, API Clients
│       ├── api/ UserApiService.kt
│       └── dto/ UserResponseDto.kt     # Network response objects
│
├── presentation/                       # Android UI and ViewModels
│   ├── common/                         # Reusable UI components, themes
│   ├── user/                           # Grouped by screen/flow
│   │   ├── UserViewModel.kt            # Orchestrates Use Cases and manages UI state
│   │   ├── UserUiState.kt              # Data class representing the screen state
│   │   └── UserScreen.kt               # Jetpack Compose UI (or Fragment/Activity)
│   └── mapper/                         # UI Mappers (Domain -> UI State)
│
└── di/                                 # Dependency Injection (Hilt, Koin, or Dagger)
    └── AppModule.kt                    # Provides DB, API, and Repository singletons
Domain Layer: Code Samples (Kotlin/Android)
The Domain Layer is pure Kotlin and contains zero dependencies on Android frameworks, databases, or network libraries.
1. Custom Domain Exceptions
Define specific exceptions to represent business rule violations.
sealed class DomainException(message: String) : Exception(message)

class InvalidEmailException(email: String) :
    DomainException("The provided email '$email' is not a valid format.")

class WeakPasswordException(reason: String) :
    DomainException("Password does not meet security requirements: $reason")

class NegativeAmountException :
    DomainException("Monetary amounts cannot be negative.")
2. Value Objects with Validation
Value Objects encapsulate validation logic. They are immutable and ensure that the system never processes “garbage” data.
@JvmInline
value class Email(val value: String) {
    init {
        val emailRegex = "^[A-Za-z0-9+_.-]+@(.+)$".toRegex()
        if (!value.matches(emailRegex)) {
            throw InvalidEmailException(value)
        }
    }
}

data class Password(val value: String) {
    init {
        if (value.length < 8) {
            throw WeakPasswordException("Must be at least 8 characters.")
        }
        if (!value.any { it.isDigit() }) {
            throw WeakPasswordException("Must contain at least one digit.")
        }
    }
}
3. Entities
Entities have a unique identity (ID) and encapsulate enterprise-wide business rules.
data class User(
    val id: String,         // Unique Identity
    val email: Email,       // Value Object
    val password: Password, // Value Object
    val isActive: Boolean = true
) {
    // Business logic within the entity
    fun deactivate(): User {
        return this.copy(isActive = false)
    }
}
4. Repository Interfaces (Ports)
These interfaces define the contracts for data operations. The implementation resides in the Infrastructure/Data layer.
interface UserRepository {
    suspend fun save(user: User)
    suspend fun findByEmail(email: Email): User?
    suspend fun exists(email: Email): Boolean
}
5. Use Cases (Application-Specific Rules)
Use Cases orchestrate the flow of data. They use the Repository interfaces and Domain Entities to perform a specific task.
class RegisterUserUseCase(
    private val userRepository: UserRepository
) {
    suspend operator fun invoke(emailInput: String, passwordInput: String) {
        // 1. Validation happens automatically during Value Object instantiation
        val email = Email(emailInput)
        val password = Password(passwordInput)

        // 2. Business Rule Check
        if (userRepository.exists(email)) {
            throw DomainException("A user with this email already exists.")
        }

        // 3. Entity Creation
        val newUser = User(
            id = java.util.UUID.randomUUID().toString(),
            email = email,
            password = password
        )

        // 4. Persistence via Interface
        userRepository.save(newUser)
    }
}
Key Implementation Principles in this Layer
Email and Password objects cannot be created in an invalid state. If the RegisterUserUseCase receives bad strings, the code crashes (with a caught DomainException) before any business logic is executed.Context, Parcelable, JSONObject, or Room annotations (@Entity, @PrimaryKey). This ensures the core logic is 100% unit-testable on a standard JVM without an emulator.value classes are used to ensure that once a domain object is validated and created, its state cannot be modified unpredictably. Data Layer: Code Samples (Kotlin/Android with API)
The Data Layer (Infrastructure) implements the interfaces defined in the Domain Layer. It handles the technical details of communicating with external APIs using libraries like Retrofit and mapping external data formats into Domain Entities and Value Objects.
1. Data Transfer Objects (DTOs)
These classes represent the structure of the JSON data returned by the API. They are annotated with serialization metadata and remain separate from Domain Entities.
import com.google.gson.annotations.SerializedName

data class UserResponseDto(
    @SerializedName("id") val id: String,
    @SerializedName("email_address") val email: String,
    @SerializedName("is_active") val isActive: Boolean,
    @SerializedName("created_at") val createdAt: String
)

data class UserRequestDto(
    @SerializedName("email") val email: String,
    @SerializedName("password_hash") val passwordHash: String
)
2. Retrofit API Service
This interface defines the HTTP endpoints. It uses the DTOs for requests and responses.
import retrofit2.http.Body
import retrofit2.http.GET
import retrofit2.http.POST
import retrofit2.http.Path

interface UserApiService {
    @GET("users/{id}")
    suspend fun getUserById(@Path("id") id: String): UserResponseDto

    @POST("users/register")
    suspend fun registerUser(@Body request: UserRequestDto): UserResponseDto
}
3. Data Mappers
Mappers are responsible for converting DTOs into Domain Entities. During this conversion, strings from the API are passed into Value Objects, which triggers the domain-level validation.
// Extension functions for mapping
fun UserResponseDto.toDomain(): User {
    return User(
        id = this.id,
        // Passing raw API string into the Value Object constructor
        // If the API returns an invalid email, the Value Object throws an exception here
        email = Email(this.email),
        password = Password("dummy_api_password"), // Passwords typically aren't returned by APIs
        isActive = this.isActive
    )
}

fun User.toRequestDto(): UserRequestDto {
    return UserRequestDto(
        email = this.email.value,
        passwordHash = this.password.value // Simplified for example
    )
}
4. Repository Implementation
This class implements the UserRepository interface from the Domain Layer. It uses the UserApiService to fetch data and the mappers to return domain objects to the application layer.
class UserRepositoryImpl(
    private val apiService: UserApiService
) : UserRepository {

    override suspend fun findByEmail(email: Email): User? {
        return try {
            // Note: In a real scenario, you would have an endpoint to find by email
            val response = apiService.getUserById(email.value)
            response.toDomain()
        } catch (e: Exception) {
            // Log error or handle network-specific exceptions
            null
        }
    }

    override suspend fun save(user: User) {
        val requestDto = user.toRequestDto()
        apiService.registerUser(requestDto)
    }

    override suspend fun exists(email: Email): Boolean {
        return try {
            apiService.getUserById(email.value)
            true
        } catch (e: Exception) {
            false
        }
    }
}
Key Implementation Principles in this Layer
UserResponseDto can change its field names (e.g., from email_address to contact_email) without affecting the User entity in the Domain Layer. Only the Mapper needs to be updated.response.toDomain() is called, the Email(this.email) constructor is invoked. If the server sends an invalid email format, the system throws a DomainException at the boundary of the Data Layer, preventing invalid data from entering the application core.UserRepository interface (Domain) to know what methods to implement, but the Domain does not depend on this implementation. Presentation Layer: Code Samples (Kotlin/Android)
The Presentation Layer is responsible for rendering data to the screen and capturing user interactions. In modern Android development, this involves a ViewModel to manage state and a UI Component (Jetpack Compose or Fragments) to display it.
1. UI State Representation
The UI state is a data class or sealed class that represents exactly what the user sees on the screen at any given moment.
sealed class RegistrationUiState {
    object Idle : RegistrationUiState()
    object Loading : RegistrationUiState()
    object Success : RegistrationUiState()
    data class Error(val message: String) : RegistrationUiState()
}
2. ViewModel Implementation
The ViewModel interacts with the Use Cases. It is responsible for catching DomainException thrown by Value Objects or Use Cases and converting them into human-readable error messages for the UI.
import androidx.lifecycle.ViewModel
import androidx.lifecycle.viewModelScope
import kotlinx.coroutines.flow.MutableStateFlow
import kotlinx.coroutines.flow.StateFlow
import kotlinx.coroutines.launch

class RegistrationViewModel(
    private val registerUserUseCase: RegisterUserUseCase
) : ViewModel() {

    private val _uiState = MutableStateFlow<RegistrationUiState>(RegistrationUiState.Idle)
    val uiState: StateFlow<RegistrationUiState> = _uiState

    fun onRegisterClicked(emailInput: String, passwordInput: String) {
        viewModelScope.launch {
            _uiState.value = RegistrationUiState.Loading

            try {
                // The Use Case is called with raw strings.
                // Internally, the Use Case creates Value Objects (Email, Password).
                // If validation fails, a DomainException is thrown immediately.
                registerUserUseCase(emailInput, passwordInput)

                _uiState.value = RegistrationUiState.Success
            } catch (e: DomainException) {
                // Catch specific domain errors and update the UI state
                _uiState.value = RegistrationUiState.Error(e.message ?: "Invalid Input")
            } catch (e: Exception) {
                // Catch unexpected system/network errors
                _uiState.value = RegistrationUiState.Error("An unexpected error occurred")
            }
        }
    }
}
3. UI Component (Jetpack Compose)
The UI observes the uiState from the ViewModel and reacts to changes. It does not contain any business logic or validation logic; it simply passes strings to the ViewModel.
@Composable
fun RegistrationScreen(viewModel: RegistrationViewModel) {
    val state by viewModel.uiState.collectAsState()
    var email by remember { mutableStateOf("") }
    var password by remember { mutableStateOf("") }

    Column {
        TextField(
            value = email,
            onValueChange = { email = it },
            label = { Text("Email") }
        )

        TextField(
            value = password,
            onValueChange = { password = it },
            label = { Text("Password") },
            visualTransformation = PasswordVisualTransformation()
        )

        Button(onClick = { viewModel.onRegisterClicked(email, password) }) {
            Text("Register")
        }

        // Display state-specific UI
        when (state) {
            is RegistrationUiState.Loading -> CircularProgressIndicator()
            is RegistrationUiState.Success -> Text("Account Created Successfully!", color = Color.Green)
            is RegistrationUiState.Error -> Text("Error: ${(state as RegistrationUiState.Error).message}", color = Color.Red)
            else -> {}
        }
    }
}
Key Implementation Principles in this Layer
RegistrationScreen does not check if the email is valid. It delegates that responsibility to the Domain layer (via the ViewModel and Use Case). This ensures that validation rules are never duplicated in the UI code.RegistrationUiState. This makes the UI highly predictable and easy to test with Compose UI tests.WeakPasswordException) and transforms them into a state that the UI can render (an error message string).UserRepository or the UserApiService.I needed to swap 0.003 ETH (on Base) to MYST tokens (on Polygon) for an AI agent I was building. Simple enough, right?
Two hours later, I had manually:
amountOutMin wrong and got sandwichedThere was no single tool that handled all of this. So I built one.
What is AutoSwap?
AutoSwap is a cross-chain swap SDK built specifically for AI agents. It wraps the entire swap pipeline — DEX routing, bridging, native gas resolution, and slippage protection — into a single function call.
from autoswap import swap

result = swap(
    from_token="ETH",
    from_chain="base",
    to_token="MYST",
    to_chain="polygon",
    amount=0.003,
    slippage_max=2.0,
    dry_run=True,  # simulate first — always
)

print(result.route_taken)
# → "ETH→USDC (base) | bridge USDC base→polygon | USDC→MYST (polygon)"

print(f"~{result.amount_out:.4f} MYST")
# → "~47.3281 MYST"
That’s it. One call.
The Problems AutoSwap Solves
1. The Cold Start Gas Problem
This is the most under-discussed problem in cross-chain DeFi.
You bridge USDC from Base to Polygon. It arrives. Now you need to swap it to MYST. But you have zero POL on Polygon. Your USDC is stuck, and you can’t do anything without gas.
AutoSwap detects this automatically and resolves it via a gasless relay before executing your swap. You never have to think about it.
2. amountOutMin=0 (The MEV Sandwich Attacker’s Best Friend)
Every tutorial, every StackOverflow answer, every quick script I’ve seen sets amountOutMin=0 “for simplicity.” This is the #1 way to get sandwiched.
AutoSwap never sets amountOutMin=0. Period. Slippage is calculated against real liquidity data from the DEX. The hard maximum is 50% — any route exceeding that is rejected outright.
3. Best Route Selection
AutoSwap queries both Paraswap (50+ DEX aggregation) and Uniswap V3 in parallel, picks the highest expected output, and validates it before building the transaction.
4. Bridge Complexity
Cross-chain routing via Across Protocol with ~2-5 second fills, automatic fallback if the primary route fails, and USDC as the default bridge token (deepest liquidity).
Architecture
autoswap/
├── src/
│   ├── swap.py      ← Orchestrator
│   ├── router.py    ← DEX routing (Paraswap + Uniswap V3)
│   ├── bridge.py    ← Cross-chain bridge (Across Protocol)
│   ├── gas.py       ← Native gas resolver
│   └── safety.py    ← Slippage + sandwich protection
├── autoswap/        ← Python package
├── npm/             ← JavaScript wrapper
└── mcp-tool.json    ← MCP tool descriptor (for AI agents)
MCP Native: Claude/Cursor/Cline Can Call It Directly
This is where it gets interesting for AI agent builders.
AutoSwap ships as an MCP (Model Context Protocol) tool. Add this to your Claude Desktop or Cursor config:
{
  "mcpServers": {
    "autoswap": {
      "command": "python3",
      "args": ["-m", "autoswap.mcp_handler"],
      "env": {
        "ETH_PRIVATE_KEY": "your_key"
      }
    }
  }
}
Now Claude can execute cross-chain swaps directly in conversation:
User: "Swap 0.003 ETH on Base to MYST on Polygon, show me the route first"

Claude: [calls autoswap.swap with dry_run=true]
→ Route: ETH→USDC (base) | bridge USDC base→polygon | USDC→MYST (polygon)
→ Expected output: ~47.3 MYST
→ Bridge fee: 0.08 USDC

"Execute it."

Claude: [calls autoswap.swap with dry_run=false]
→ Received: 47.1 MYST ✅
No manual steps. No fumbling with raw transaction builders. The agent just calls swap() and gets a result.
Dry-Run Mode: Safe by Default
AutoSwap is designed for agents that need to verify before executing. dry_run=True builds the entire transaction pipeline, checks liquidity, calculates fees, and returns the full route — without submitting anything to the blockchain.
# Always dry-run first
result = swap("ETH", "base", "MYST", "polygon", 0.003, dry_run=True)
print(f"Route: {result.route_taken}")
print(f"Expected: {result.amount_out:.4f} MYST")
print(f"Bridge fee: {result.fees.get('bridge_fee', 0):.4f} USDC")

# Only execute if the numbers look right
if result.success and result.amount_out > 40:
    live = swap("ETH", "base", "MYST", "polygon", 0.003, dry_run=False)
    print(f"TX: {live.tx_hashes}")
JavaScript / npm
There’s a thin JS wrapper for Node.js environments:
npm install autoswap
const { swap, quote } = require('autoswap');

const result = await swap({
  fromToken: 'ETH',
  fromChain: 'base',
  toToken: 'MYST',
  toChain: 'polygon',
  amount: 0.003,
  dryRun: true,
});

console.log(result.routeTaken);
Supported Networks
| Chain | Status |
|---|---|
| Base | ✅ Full support |
| Polygon | ✅ Full support |
| Arbitrum | ✅ Full support |
| Optimism | ✅ Full support |
| Ethereum | 🔜 Coming soon |
Comparison
| Feature | AutoSwap | Li.Fi | 1inch | Relay.link |
|---|---|---|---|---|
| Single function call | ✅ | ❌ | ❌ | ❌ |
| Cold start gas fix | ✅ automatic | ❌ manual | ❌ | ❌ |
| Sandwich protection | ✅ built-in | ⚠️ | ✅ | ⚠️ |
| amountOutMin=0 guard | ✅ always | ⚠️ | ✅ | ⚠️ |
| MCP / AI agent ready | ✅ native | ❌ | ❌ | ❌ |
| Dry-run simulation | ✅ | ⚠️ | ❌ | ❌ |
| No API key needed | ✅ | ❌ | ❌ | ❌ |
| Open source (MIT) | ✅ | ✅ GPL | ❌ | ❌ |
Install
pip install autoswap
# or
npm install autoswap
GitHub: https://github.com/fino-oss/autoswap
Built from real pain. If you’ve ever manually sent POL to unstick a bridged USDC, this is for you.
Happy to answer questions — especially if you’re building AI agents that need DeFi access.
Most of us are used to the “standard” flow: push to GitHub, auto-deploy to a big-name provider, and hope the free tier doesn’t vanish or the bill doesn’t suddenly spike.
Flux Cloud is a decentralized computing network (thousands of independent nodes) which makes it significantly cheaper than the “Big 3” clouds. They just released a Deploy with Git feature that makes it as easy as any other PaaS.
Here is a quick guide on how to get a Vue app live on a decentralized network in a few minutes.
Step 1: Prepare your Vue project
You don’t need to change much in your code. Just make sure your package.json has the standard scripts. Flux will look for these to build your project.
If you are using Vite (the Vue standard), ensure your build output is set to the default dist folder.
Step 2: The Flux Configuration
Flux uses a simple setup to understand how to run your app. You can find the boilerplate for this in the official Vue deployment guide here.
Essentially, you are just telling Flux:
Which branch to watch (e.g., main).
The build command (e.g., npm run build).
The port to serve it on.
Step 3: Connect and Deploy
Because it’s decentralized, your app is “spawned” across the network. Once the build finishes, you’ll get a global URL.
Step 4: Automatic Updates
The best part is that it stays synced. Whenever you push a change to your GitHub repo, Flux detects the commit, rebuilds the project, and updates the nodes. If a build ever fails, it automatically rolls back to the previous working version so your users never see a broken site.
Resources
Full Vue.js Guide: View on GitHub
Official Documentation: Flux Deploy with Git Intro

Understanding CodeRabbit’s Pricing Model

CodeRabbit has grown into the most widely installed AI code review tool in the market, with over 2 million repositories connected and more than 13 million pull requests reviewed. A significant driver of that adoption is its pricing structure – specifically, a genuinely useful free tier that requires no credit card, paired with a Pro plan that scales predictably as teams grow.
But understanding what you actually pay for CodeRabbit – and whether it is worth it – requires looking beyond the headline numbers. The pricing page lists $24/user/month for Pro, but how that translates to real cost depends on how CodeRabbit counts users, what the free tier actually delivers, where the upgrade triggers hit, and how the Enterprise tier stacks up against self-hosted alternatives.
This guide breaks down every CodeRabbit pricing tier in detail, calculates the real cost at different team sizes, compares it against every major competitor, and helps you determine whether the free tier is enough or whether upgrading to Pro delivers meaningful ROI.
CodeRabbit Free Tier: What You Get at Zero Cost
CodeRabbit’s free tier is one of the most generous in the AI developer tools space. Unlike competitors that gate free usage behind public-repository-only restrictions or severe feature limitations, CodeRabbit’s free plan covers both public and private repositories with no cap on the number of repos or team members.
Features Included in the Free Tier
AI-powered PR summaries. Every pull request gets an automatically generated walkthrough summary describing what changed and why. These summaries parse the diff, understand the semantic intent of changes, and produce a human-readable overview that helps reviewers quickly grasp the scope of a PR without reading every line. This feature alone saves significant time for teams where reviewers need to context-switch between multiple PRs daily.
AI review comments. CodeRabbit’s LLM-powered engine analyzes your PR diff within the context of your repository and posts inline review comments identifying bugs, security issues, style violations, and logic errors. Free-tier reviews use the same AI models as Pro – the quality of individual comments is not degraded on the free plan. The difference is in rate limits and advanced features, not in the intelligence of the analysis.
Support for all Git platforms. The free tier works with GitHub, GitLab, Azure DevOps, and Bitbucket. This is notable because many competitors restrict their free tiers to GitHub only or limit platform support to paid plans. A team using GitLab or Azure DevOps can still use CodeRabbit at zero cost.
Unlimited repositories and team members. There is no cap on how many repos you connect or how many developers on your team can receive reviews. Every connected repository gets reviewed, and every team member who opens a PR gets feedback. This makes the free tier viable for organizations with hundreds of repos and dozens of developers – subject only to rate limits.
VS Code, Cursor, and Windsurf extension. CodeRabbit’s free IDE extension works for all users regardless of plan. It provides real-time inline review comments on staged and unstaged changes before you even open a PR, catching issues at the earliest possible point.
Free Tier Rate Limits
The free tier imposes two rate limits:
In practice, these limits rarely impact small teams. A 5-person team submitting 1-2 PRs per developer per day would need all developers to simultaneously open PRs within the same hour to hit the 4 PR/hour limit. The 200-file limit only triggers on large monorepo PRs or bulk refactoring changes.
For teams that occasionally spike above these limits – say, during a release rush or a large migration – the experience is not a hard block. Reviews queue and process as capacity frees up. You are never charged for overages, and no reviews are dropped.
Who the Free Tier Is Perfect For
Solo developers and freelancers. If you are working alone or with one or two other developers, the free tier is effectively unlimited. You get the same AI review quality as Pro users, and the rate limits are well above what a small team produces.
Open-source maintainers. CodeRabbit Pro is free forever for public repositories. This means open-source projects get the full Pro feature set – auto-fix suggestions, 40+ linters, custom review instructions – at no cost. CodeRabbit has also distributed over $600,000 in sponsorships to open-source maintainers, demonstrating a genuine commitment to the community.
Teams evaluating AI code review. The free tier lets you install CodeRabbit across your entire organization and run it for weeks or months before deciding whether to upgrade. Unlike Greptile’s 14-day trial or GitHub Copilot’s premium request limits, CodeRabbit’s free plan has no expiration and no credit card requirement.
Startups in early stages. A pre-seed or seed-stage startup with 3-8 developers can run CodeRabbit’s free tier indefinitely and redirect that budget toward infrastructure or hiring. The rate limits are a non-issue at this team size.
CodeRabbit Pro Plan: Full Feature Breakdown
The Pro plan at $24/user/month (annual billing) or $30/user/month (monthly billing) unlocks the complete CodeRabbit feature set. Here is everything that Pro adds beyond the free tier.
Advanced AI Reviews with Auto-Fix
Pro unlocks CodeRabbit’s most powerful review capabilities. The AI engine performs deeper analysis with more context, and when it identifies an issue, it frequently provides a ready-to-apply code fix directly in the PR comment. Developers can accept these fixes with a single click, eliminating the back-and-forth of traditional code review. Auto-fix is particularly valuable for straightforward improvements like null-check additions, type narrowing, import cleanup, and error handling improvements.
40+ Built-In Linters
Beyond AI-driven analysis, Pro users get access to CodeRabbit’s full suite of over 40 linters covering ESLint, Pylint, Golint, RuboCop, and many more. These linters provide deterministic, zero-false-positive checks for style consistency, naming conventions, and known anti-patterns. The combination of probabilistic AI analysis and deterministic linting creates a layered review system that catches both subtle logic issues and concrete rule violations.
This is a significant differentiator. Most AI code review tools provide only AI-generated comments. CodeRabbit’s linter layer means you get the equivalent of a lightweight static analysis tool bundled with your AI reviewer.
Custom Review Instructions
Pro users can customize CodeRabbit’s review behavior by writing plain-English instructions in a .coderabbit.yaml configuration file or through the web dashboard. Examples include:
This removes the need to write complex rule configurations or learn a domain-specific language. You express your team’s standards in natural language, and CodeRabbit enforces them during every review.
Learnable Review Preferences
CodeRabbit Pro adapts over time based on how your team interacts with its suggestions. When developers consistently dismiss a certain type of comment, the system learns to deprioritize it. When they accept suggestions, it reinforces that pattern. Over weeks and months, this creates a feedback loop that makes the tool increasingly aligned with your team’s specific coding standards and preferences.
Jira, Linear, and Slack Integrations
Pro connects CodeRabbit with your project management and communication tools. When reviewing a PR, CodeRabbit can pull context from linked Jira or Linear tickets to understand the intent behind changes. Slack integration delivers review notifications to your team channels. These integrations help CodeRabbit produce more contextually accurate reviews and keep your team informed without requiring developers to check the PR interface manually.
No Rate Limits
Pro removes the 200-file-per-hour and 4-PR-per-hour rate limits entirely. Reviews process immediately regardless of volume. For teams with active development workflows, CI/CD pipelines that trigger multiple PRs, or monorepos with large changesets, this unlimited throughput is the most tangible operational difference from the free tier.
Priority Support
Pro users get priority access to CodeRabbit’s support team. While the free tier relies on community support and documentation, Pro users can reach human support for configuration assistance, integration issues, and review quality concerns.
Annual vs. Monthly Billing
| Billing Cycle | Cost Per User | Annual Cost (10 devs) | Annual Cost (50 devs) | Annual Cost (100 devs) |
|---|---|---|---|---|
| Monthly | $30/user/month | $3,600 | $18,000 | $36,000 |
| Annual | $24/user/month | $2,880 | $14,400 | $28,800 |
| Savings | $6/user/month | $720/year | $3,600/year | $7,200/year |
Annual billing saves 20%, which scales meaningfully at larger team sizes. A 100-developer team saves $7,200 per year simply by choosing annual over monthly billing.
CodeRabbit Enterprise: Pricing and What You Get
CodeRabbit Enterprise is designed for large organizations with strict security, compliance, and deployment requirements. Pricing is custom and negotiated directly with CodeRabbit’s sales team.
Known Enterprise Pricing Details
Based on publicly available information, Enterprise pricing starts at approximately $15,000 per month for organizations with 500 or more users. This works out to roughly $30/user/month at the minimum seat count, though per-seat costs likely decrease at higher volumes through negotiated discounts.
Enterprise contracts are available through AWS Marketplace and GCP Marketplace, which allows organizations to apply existing cloud spending commitments toward CodeRabbit costs.
Enterprise Features
Self-hosted deployment. The most significant Enterprise-only feature. Organizations can deploy CodeRabbit on their own infrastructure, ensuring that source code never leaves their network. This is critical for regulated industries including finance, healthcare, defense, and government.
SSO/SAML authentication. Enterprise supports single sign-on through your existing identity provider, enabling centralized access management and automatic user provisioning.
Custom AI models. Enterprise customers can configure CodeRabbit to use custom or fine-tuned AI models tailored to their specific codebase, domain, or coding standards.
Multi-organization support. Large enterprises with multiple GitHub or GitLab organizations can manage them under a single CodeRabbit Enterprise account.
Dedicated customer success manager. Enterprise customers get a named contact who understands their deployment, assists with configuration, and advocates for feature requests internally.
SLA-backed support. Guaranteed response times and resolution commitments, which is essential for organizations where code review tool downtime impacts deployment velocity.
Compliance and audit logs. Detailed logging of all review activity, configuration changes, and access events for compliance and audit requirements.
VPN connectivity. For self-hosted deployments that require secure network connectivity.
Self-Hosted Infrastructure Costs
Beyond the software license, self-hosted deployment adds infrastructure costs that vary by scale:
| Team Size | Estimated Monthly Infrastructure Cost |
|---|---|
| 500 users | $500 – $2,000 |
| 1,000 users | $1,500 – $4,000 |
| 5,000+ users | $4,000 – $8,000+ |
These costs cover compute, storage, and networking for the CodeRabbit services running on your cloud infrastructure. Actual costs depend on PR volume, review frequency, and the cloud provider you use.
Is Enterprise Worth It?
Enterprise makes sense for organizations that meet two criteria: they have 500 or more developers who create pull requests, and they have a hard requirement for on-premises deployment or advanced compliance features. If you do not need self-hosted deployment, the Pro plan provides the same review quality at $24/user/month without the minimum seat commitment.
For organizations that need self-hosted AI code review but do not meet the 500-seat minimum, PR-Agent by Qodo is a free open-source alternative that can be self-hosted with your own LLM API keys.
Cost Per Developer at Different Team Sizes
Understanding the true cost of CodeRabbit requires factoring in that only developers who create pull requests are counted as seats. In a typical engineering organization, not everyone opens PRs. Project managers, QA engineers who only review, engineering managers, and designers are not billed.
Real-World Seat Calculations
| Total Team Size | Estimated PR Creators | Monthly Cost (Pro Annual) | Annual Cost | Cost Per Total Team Member |
|---|---|---|---|---|
| 5 | 4-5 | $96 – $120 | $1,152 – $1,440 | $19.20 – $24.00 |
| 10 | 7-9 | $168 – $216 | $2,016 – $2,592 | $16.80 – $21.60 |
| 25 | 18-22 | $432 – $528 | $5,184 – $6,336 | $17.28 – $21.12 |
| 50 | 35-45 | $840 – $1,080 | $10,080 – $12,960 | $16.80 – $21.60 |
| 100 | 70-85 | $1,680 – $2,040 | $20,160 – $24,480 | $16.80 – $20.40 |
| 200 | 140-170 | $3,360 – $4,080 | $40,320 – $48,960 | $16.80 – $20.40 |
The effective cost per total team member drops when you account for non-PR-creating members. For a 50-person engineering organization where 40 developers actively create PRs, the annual cost is $11,520 – roughly $230 per total team member per year, or about $19.20 per month.
Cost Scaling Characteristics
CodeRabbit’s per-seat pricing is linear, meaning there are no volume discounts on the Pro plan (discounts may be available through direct negotiation for larger teams). This makes budgeting predictable: adding one developer always adds $24/month on annual billing. For very large organizations, the Enterprise plan likely includes negotiated per-seat rates that decrease with volume.
CodeRabbit Free vs. Pro: Detailed Comparison
The decision between free and Pro is the most common question teams face with CodeRabbit. Here is a comprehensive feature-by-feature comparison.
| Feature | Free | Pro ($24/user/month) |
|---|---|---|
| AI PR summaries | Yes | Yes |
| AI review comments | Yes | Yes (deeper analysis) |
| Auto-fix suggestions | No | Yes |
| Built-in linters (40+) | No | Yes |
| Custom review instructions | No | Yes |
| Learnable preferences | No | Yes |
| GitHub support | Yes | Yes |
| GitLab support | Yes | Yes |
| Azure DevOps support | Yes | Yes |
| Bitbucket support | Yes | Yes |
| VS Code / Cursor extension | Yes | Yes |
| Jira integration | No | Yes |
| Linear integration | No | Yes |
| Slack integration | No | Yes |
| Rate limit – files/hour | 200 | Unlimited |
| Rate limit – reviews/hour | 4 | Unlimited |
| Priority support | No | Yes |
| Number of repos | Unlimited | Unlimited |
| Number of team members | Unlimited | Unlimited |
| Open-source repos (public) | Full Pro features | Full Pro features |
What You Lose on the Free Tier
The five most impactful features missing from the free tier are:
1. Auto-fix suggestions. This is arguably the highest-value Pro feature. When CodeRabbit identifies an issue, Pro users see a ready-to-apply fix that can be merged with one click. Free-tier users see the issue identified but must write the fix themselves. For teams processing dozens of PRs daily, auto-fix alone can save hours of developer time per week.
2. 40+ built-in linters. The free tier relies entirely on AI-generated analysis, which is probabilistic and can occasionally miss concrete style or pattern violations. Pro’s linter layer adds deterministic checks that catch issues the AI might overlook – things like ESLint violations, Pylint warnings, and language-specific best practice deviations. This is effectively a free static analysis tool bundled with your AI reviewer.
3. Custom review instructions. Free-tier users get CodeRabbit’s default review behavior. Pro users can tell it exactly what to look for, what to ignore, and what standards to enforce. For teams with established coding conventions, this customization is the difference between generic AI feedback and feedback aligned with your specific standards.
4. Learnable preferences. Pro’s learning capability means the tool gets smarter the longer you use it. It adapts to which comments your team finds valuable and which are noise. Free-tier users get the same default behavior indefinitely, which means a consistently higher noise-to-signal ratio compared to a tuned Pro instance.
5. Rate limits. The 4-PR-per-hour limit is fine for small teams but becomes restrictive for teams of 10 or more active developers. During busy periods – release weeks, sprint endings, large feature merges – hitting rate limits means delayed feedback when you need it most. Pro’s unlimited throughput eliminates this bottleneck entirely.
When to Stay on Free
Stay on the free tier if:
When to Upgrade to Pro
Upgrade to Pro when:
The general rule of thumb: if CodeRabbit’s free tier is saving your team time but you wish it were faster, smarter, and more aligned with your standards, Pro is the natural upgrade.
ROI Calculation: Is CodeRabbit Pro Worth $24/User/Month?
The cost justification for CodeRabbit Pro comes down to developer time savings. Here is a framework for calculating whether the investment pays off for your team.
The Math Behind CodeRabbit ROI
Average senior developer cost. In the US market, a senior developer’s fully loaded cost (salary, benefits, overhead) is approximately $150,000 – $200,000 per year, or roughly $75 – $100 per hour.
Time spent on manual code review. Studies consistently show that developers spend 4-8 hours per week on code review activities, including reading diffs, writing comments, discussing changes, and waiting for reviews. For a senior developer earning $87/hour (midpoint), that is $348 – $696 per week spent on review.
CodeRabbit’s impact on review time. Users report 50% or greater reduction in manual review effort and up to 80% faster review cycles. Conservatively estimating a 30% reduction in review time:
| Metric | Without CodeRabbit | With CodeRabbit Pro |
|---|---|---|
| Weekly review hours per dev | 6 hours | 4.2 hours |
| Time saved per dev per week | – | 1.8 hours |
| Time saved per dev per month | – | 7.2 hours |
| Value of time saved per dev per month | – | $626 |
| CodeRabbit Pro cost per dev per month | – | $24 |
| Net monthly savings per developer | – | $602 |
| ROI multiple | – | 26x |
Even at a very conservative 10% reduction in review time:
| Metric | Value |
|---|---|
| Time saved per dev per month | 2.4 hours |
| Value of time saved per dev per month | $209 |
| CodeRabbit Pro cost per dev per month | $24 |
| Net monthly savings per developer | $185 |
| ROI multiple | 8.7x |
ROI at Different Team Sizes
| Team Size (PR creators) | Annual CodeRabbit Cost | Estimated Annual Time Savings (conservative) | Net Annual Savings |
|---|---|---|---|
| 5 developers | $1,440 | $12,528 | $11,088 |
| 10 developers | $2,880 | $25,056 | $22,176 |
| 25 developers | $7,200 | $62,640 | $55,440 |
| 50 developers | $14,400 | $125,280 | $110,880 |
| 100 developers | $28,800 | $250,560 | $221,760 |
These calculations use a conservative 30% review time reduction. Teams that report 50% or greater improvements see even stronger returns.
Beyond Time Savings
The ROI calculation above only accounts for direct time savings. CodeRabbit also delivers value through:
Reduced bug escape rate. Bugs caught during PR review cost 10-100x less to fix than bugs discovered in production. Even if CodeRabbit catches just a few additional bugs per month that would have reached production, the cost avoidance can exceed the tool’s entire annual license cost.
Faster onboarding. New developers get immediate, consistent feedback on their PRs without waiting for senior team members to be available. This accelerates ramp-up time and reduces the burden on experienced developers who currently serve as primary reviewers.
Consistent review quality. Human reviewers have variable focus, energy, and availability. CodeRabbit provides the same depth of review on every PR regardless of time of day, reviewer workload, or team dynamics. This consistency reduces the variance in code quality that enters your main branch.
Reduced context-switching. When CodeRabbit handles the first pass of review, human reviewers can focus on higher-level architectural and design feedback rather than catching typos, missing null checks, and style violations. This makes the human review process faster and more satisfying for senior developers.
Competitor Pricing Comparison
Understanding CodeRabbit’s pricing in isolation is not enough. Here is how it stacks up against every major AI code review tool in the market.
Pricing Overview Table
| Tool | Free Tier | Paid Starting Price | Billing Model | Platforms |
|---|---|---|---|---|
| CodeRabbit | Unlimited repos (rate-limited) | $24/user/month | Per PR creator | GitHub, GitLab, Azure DevOps, Bitbucket |
| GitHub Copilot | 50 premium requests | $10/month (Pro) / $19/user/month (Business) | Per user + overages | GitHub only |
| Greptile | None (14-day trial) | $30/seat/month | Per seat + overages | GitHub, GitLab |
| Sourcery | OSS repos only | $12/user/month | Per user | GitHub, GitLab |
| Codacy | IDE extension only | $15/user/month | Per user | GitHub, GitLab, Bitbucket |
| DeepSource | Individual devs only | $30/user/month | Per committer | GitHub, GitLab, Bitbucket |
| PR-Agent / Qodo Merge | Self-hosted (unlimited) | $30/user/month (hosted) | Per user + credits | GitHub, GitLab, Bitbucket, Azure DevOps |
CodeRabbit vs. GitHub Copilot Pricing
GitHub Copilot’s pricing structure is fundamentally different from CodeRabbit’s. Copilot is a full AI development platform – code completion, chat, agents, and code review – with code review being one feature among many. CodeRabbit is a dedicated code review tool.
Copilot pricing tiers relevant to code review:
The hidden cost of Copilot’s premium request model. Each code review consumes premium requests from your monthly allocation. Heavy review usage can exhaust your allocation, triggering $0.04-per-request overages. For a team that relies heavily on AI code review, these overages can push the effective cost well above the headline price.
The value comparison. If your team already uses Copilot for code completion and you are on a Business or Enterprise plan, code review is effectively “free” since it is bundled. In that case, adding CodeRabbit means paying $24/user/month for a second tool. The question becomes whether CodeRabbit’s deeper review capabilities, 40+ linters, multi-platform support, and custom review instructions justify the additional cost.
If you are choosing between the two exclusively, CodeRabbit provides more comprehensive code review at $24/user/month versus Copilot Business at $19/user/month. But Copilot at $19/user/month also gives you code completion, chat, and agents – a broader feature set. The right choice depends on whether you are optimizing for the best possible code review (CodeRabbit) or the most capable all-in-one AI platform (Copilot).
For a 20-developer team on annual billing:
| Tool | Monthly Cost | Annual Cost |
|---|---|---|
| CodeRabbit Pro | $480 | $5,760 |
| GitHub Copilot Business | $380 | $4,560 |
| Both combined | $860 | $10,320 |
CodeRabbit vs. Greptile Pricing
Greptile represents the premium end of AI code review pricing, justified by its industry-leading 82% bug catch rate achieved through full codebase indexing.
Greptile pricing:
The overage cost factor. Greptile’s base price of $30/seat/month includes 50 reviews per seat. For most teams, 50 reviews per developer per month is sufficient, but active developers who submit multiple PRs daily can exceed this limit. Each additional review costs $1. For a developer who opens 3 PRs per day (roughly 65 per month), the monthly cost per seat becomes $45.
CodeRabbit has no per-review overages. At $24/user/month, you get unlimited reviews with no usage caps. This makes CodeRabbit’s cost completely predictable, while Greptile’s cost can vary month to month.
For a 20-developer team:
| Scenario | CodeRabbit Pro | Greptile Cloud |
|---|---|---|
| Base monthly cost | $480 | $600 |
| With moderate overages (10 extra reviews/dev) | $480 | $800 |
| Annual cost (base) | $5,760 | $7,200 |
| Annual cost (with overages) | $5,760 | $9,600 |
The quality tradeoff. Greptile catches 82% of bugs versus CodeRabbit’s 44% in independent benchmarks. However, Greptile also produces significantly more false positives (11 versus CodeRabbit’s 2 in benchmark testing). You are paying more per seat for deeper analysis, but receiving more noise along with it. Whether the additional bug detection justifies the 25-100% price premium depends on how critical your codebase is and how much noise your team can tolerate.
CodeRabbit vs. Sourcery Pricing
Sourcery is the most affordable dedicated AI review tool, making it the primary budget alternative to CodeRabbit.
Sourcery pricing:
At half the price of CodeRabbit Pro. Sourcery Pro at $12/user/month is exactly half of CodeRabbit’s $24/user/month. For budget-conscious teams, this is compelling. However, the feature sets differ meaningfully:
For a 20-developer team:
| Tier | CodeRabbit Pro | Sourcery Pro | Sourcery Team |
|---|---|---|---|
| Monthly cost | $480 | $240 | $480 |
| Annual cost | $5,760 | $2,880 | $5,760 |
If your primary language is Python and budget is tight, Sourcery Pro at $12/user/month delivers solid value at half the cost. For polyglot teams that need broader coverage and deeper contextual review, CodeRabbit Pro justifies the higher price.
CodeRabbit vs. Codacy Pricing
Codacy is not a direct competitor to CodeRabbit – it is an all-in-one code quality and security platform that includes AI review as one feature among many. The pricing comparison is useful because Codacy can potentially replace CodeRabbit plus a separate static analysis tool.
Codacy pricing:
At $15/user/month, Codacy bundles more features. For $9 less per user per month than CodeRabbit Pro, Codacy provides SAST, SCA, secrets detection, AI code review, code coverage tracking, duplication analysis, and quality gates across 49 languages. If you are currently paying for CodeRabbit plus a separate static analysis tool, Codacy could replace both.
The tradeoff is review depth. Codacy’s AI review capabilities are less advanced than CodeRabbit’s dedicated AI engine. CodeRabbit provides deeper, more contextual feedback with learnable preferences and natural language instructions that Codacy does not match. If AI code review quality is your primary concern, CodeRabbit delivers more value per dollar spent on review specifically.
For a 20-developer team wanting review + static analysis:
| Approach | Monthly Cost | Annual Cost | What You Get |
|---|---|---|---|
| CodeRabbit Pro only | $480 | $5,760 | Best AI review |
| Codacy Pro only | $300 | $3,600 | AI review + SAST + SCA + secrets + coverage |
| CodeRabbit Pro + SonarQube Cloud | $480+ | $5,760+ | Best AI review + best static analysis |
| Codacy Pro + CodeRabbit Free | $300 | $3,600 | Comprehensive analysis + free AI review |
The last option – Codacy Pro paired with CodeRabbit’s free tier – is an efficient combination that provides broad code quality coverage through Codacy and supplementary AI review through CodeRabbit at the cost of only one paid tool.
CodeRabbit vs. DeepSource Pricing
DeepSource is the closest competitor to CodeRabbit in the “static analysis plus AI review” category, with its sub-5% false positive rate being a key differentiator.
DeepSource pricing:
DeepSource is 25% more expensive than CodeRabbit Pro at $30/user/month versus $24/user/month. However, DeepSource includes 5,000+ static analysis rules, AI code review with five-dimension PR report cards, Autofix AI, and secrets detection – features that CodeRabbit does not provide. Similar to Codacy, DeepSource can potentially replace CodeRabbit plus a separate analysis tool.
For a 20-developer team:
| Tool | Monthly Cost | Annual Cost |
|---|---|---|
| CodeRabbit Pro | $480 | $5,760 |
| DeepSource Team | $600 | $7,200 |
| Difference | $120/month more for DeepSource | $1,440/year more for DeepSource |
If you need both AI review and static analysis, DeepSource at $30/user/month may be cheaper than CodeRabbit Pro ($24) plus a separate analysis tool. If you only need AI code review, CodeRabbit Pro at $24/user/month is the more focused and affordable choice.
CodeRabbit vs. PR-Agent / Qodo Merge Pricing
PR-Agent by Qodo deserves special mention because its open-source version is free to self-host, making it the only zero-software-cost alternative to CodeRabbit.
Qodo Merge (hosted) pricing:
PR-Agent self-hosted: Free (with LLM API costs).
The self-hosted option runs on your own infrastructure with your own LLM API keys. The software is free. You pay only for LLM API calls, which typically cost $0.02 – $0.10 per review depending on PR size and model choice. For a team processing 500 PRs per month, LLM API costs might range from $10 – $50/month total – dramatically cheaper than any SaaS option.
For a 20-developer team:
| Option | Monthly Cost | Annual Cost |
|---|---|---|
| CodeRabbit Pro | $480 | $5,760 |
| Qodo Merge Teams (hosted) | $600 | $7,200 |
| PR-Agent self-hosted | ~$20 – $80 (LLM API only) | ~$240 – $960 |
If your organization has the DevOps capacity to self-host and manage infrastructure, PR-Agent delivers AI code review at a fraction of CodeRabbit’s cost. The tradeoff is setup complexity, ongoing maintenance, and a review experience that is less polished than CodeRabbit’s out-of-the-box offering.
Annual Cost Comparison for a 50-Developer Team
Here is the full annual cost picture for a 50-developer team on each tool’s standard paid plan:
| Tool | Plan | Annual Cost (50 devs) | Includes |
|---|---|---|---|
| Sourcery | Pro | $7,200 | AI review (file-level) |
| Codacy | Pro | $9,000 | AI review + SAST + SCA + secrets + coverage |
| GitHub Copilot | Business | $11,400 | Code completion + review + chat + agents |
| CodeRabbit | Pro | $14,400 | AI review + 40+ linters |
| Greptile | Cloud | $18,000+ | Deep AI review (full codebase indexing) |
| DeepSource | Team | $18,000 | AI review + 5,000+ static analysis rules |
| PR-Agent / Qodo Merge | Teams | $18,000 | AI review + PR automation |
CodeRabbit Pro sits in the middle of the market at $14,400/year for 50 developers. It is more expensive than the budget options (Sourcery, Codacy) but meaningfully cheaper than the premium options (Greptile, DeepSource, Qodo Merge hosted). It is also cheaper than GitHub Copilot Enterprise ($23,400/year for 50 devs) while providing deeper review capabilities.
Open Source Project Pricing
CodeRabbit’s approach to open-source pricing is one of its strongest competitive advantages.
Pro Is Free Forever for Public Repositories
Open-source projects with public repositories get the full CodeRabbit Pro feature set at no cost. This includes:
This is not a limited trial or a reduced-feature free tier – it is the complete Pro plan, indefinitely, for any public repository. CodeRabbit is effectively subsidizing open-source AI code review through revenue from its paid plans on private repositories.
CodeRabbit’s Open-Source Commitment
Beyond free tooling, CodeRabbit has distributed over $600,000 in sponsorships to open-source maintainers. In Q1 2026, the company announced it was giving away $100,000 to the tools that its team and community rely on. This financial commitment, combined with the free Pro tier for open-source repos, makes CodeRabbit the most generous AI code review tool for open-source projects.
How This Compares to Competitor Open-Source Policies
| Tool | Open-Source Offering |
|---|---|
| CodeRabbit | Full Pro features, free forever for public repos |
| Sourcery | Full features, free for open-source repos |
| GitHub Copilot | Free tier with 50 premium requests (not OSS-specific) |
| Greptile | Free access for qualified open-source projects (application required) |
| DeepSource | Free plan for public repos with 1,000 analysis runs/month |
| Codacy | Free IDE extension only |
| PR-Agent | Fully open-source and self-hostable (free) |
| SonarQube | Free Community Build (self-hosted) and Cloud Free for OSS |
CodeRabbit and Sourcery lead the market in open-source generosity, both providing their full paid feature sets for free on public repositories with no application process or qualification requirements. PR-Agent takes a different approach by being open-source itself, meaning maintainers can self-host it entirely.
When to Upgrade: Decision Framework
Stay on CodeRabbit Free If…
Your team is small and low-volume. With fewer than 5 active PR creators and infrequent large PRs, the free tier’s rate limits (4 PRs/hour, 200 files/hour) are unlikely to impact your workflow. You get genuinely useful AI reviews at zero cost.
You are still evaluating. The free tier has no expiration. Run it for months to assess whether CodeRabbit’s review quality justifies the Pro upgrade. Track metrics like bugs caught, review cycle time, and developer satisfaction during the evaluation period.
Budget is extremely tight. If $24/user/month is not feasible, the free tier still provides meaningful value. Pair it with free tools like SonarQube Community Build or Codacy’s IDE extension for broader coverage at zero cost.
Your project is open-source. You already have full Pro features for free on public repositories. There is nothing to upgrade to unless you also work on private repos.
Upgrade to CodeRabbit Pro If…
You are hitting rate limits regularly. If your team’s development pace means reviews are being queued because of the 4-PR-per-hour limit, the Pro plan’s unlimited throughput eliminates this bottleneck.
Auto-fix would save meaningful time. If your team spends significant time implementing the fixes CodeRabbit suggests, auto-fix’s one-click resolution can reclaim hours per week.
You need custom review enforcement. Teams with established coding standards, security requirements, or domain-specific patterns benefit significantly from custom review instructions. The free tier’s generic review behavior cannot enforce your specific standards.
Review noise is a problem. Learnable preferences on Pro adapt to your team’s feedback patterns, reducing the noise-to-signal ratio over time. On the free tier, noise levels remain static.
You need Jira/Linear/Slack integration. If your workflow depends on linking code review to project management or receiving notifications in Slack, these integrations are Pro-only.
Your team has 10+ developers. At this scale, the rate limits become more likely to impact workflow, the ROI calculation strongly favors the upgrade, and the consistency benefits of custom instructions and learnable preferences compound across more developers.
Move to CodeRabbit Enterprise If…
You require self-hosted deployment. This is the only path to running CodeRabbit on your own infrastructure. If regulatory compliance, data residency, or security policy demands that source code stays within your network, Enterprise is required.
You have 500+ developers. The Enterprise plan’s minimum seat requirement means it only makes sense at this scale. The per-seat cost likely decreases through negotiation at higher volumes.
You need SSO/SAML, audit logs, or SLA-backed support. Enterprise compliance features are not available on Pro. If your organization requires these for vendor approval, Enterprise is the only option.
Hidden Costs and Considerations
Beyond the sticker price, several factors affect the total cost of ownership for CodeRabbit.
Configuration and Tuning Time
While CodeRabbit works out of the box, teams that invest time in custom review instructions, learnable preferences, and .coderabbit.yaml configuration get significantly better results. Plan for 2-4 hours of initial setup and ongoing tuning as your team’s standards evolve. This is a time investment, not a monetary one, but it affects the speed to full ROI.
Developer Adoption and Change Management
CodeRabbit delivers value only if developers engage with its reviews. Teams need to establish norms around how to interact with AI review comments – which to address, which to dismiss, and how to use the @coderabbitai mention for follow-up questions. Budget time for an internal rollout including documentation and team discussion.
No Lock-In Risk
CodeRabbit does not modify your code, your CI/CD pipeline, or your repository configuration (beyond the optional .coderabbit.yaml file). If you cancel, your workflow returns to its pre-CodeRabbit state with no migration effort. The only “loss” is the learned preferences that CodeRabbit has built up over time, which cannot be exported. This low switching cost reduces the risk of the initial purchase decision.
Comparison with Building In-House
Some engineering organizations consider building internal review tooling using LLM APIs directly. A rough cost comparison:
| Approach | Monthly Cost (20 devs) | Includes |
|---|---|---|
| CodeRabbit Pro | $480 | Managed service, 40+ linters, integrations |
| In-house (LLM API + engineering time) | $200 – $500 in API costs + 1-2 engineers maintaining | Requires ongoing maintenance, no linters |
Building in-house costs less in API fees but requires dedicated engineering time for development, maintenance, prompt engineering, and platform integration. For most teams, CodeRabbit’s managed service is more cost-effective when you factor in the opportunity cost of engineering time.
Practical Recommendations by Team Profile
Solo Developer or Freelancer
Recommendation: CodeRabbit Free tier.
At zero cost, you get AI-powered review on every PR you open. The rate limits are irrelevant for a single developer. If your projects are open-source, you get full Pro features for free. There is no reason for a solo developer to pay for CodeRabbit unless they are working on a high volume of private repository PRs and want auto-fix and linting – and even then, the free tier covers most needs.
Startup (3-10 Developers)
Recommendation: Start with Free, upgrade to Pro when hitting rate limits or wanting auto-fix.
Run the free tier for your first few months. As your team grows and PR volume increases, the 4-PR-per-hour limit will start to bite. The tipping point typically comes around 8-10 active developers. At that scale, Pro at $24/user/month costs $192 – $240/month – less than two hours of a senior developer’s time.
Mid-Size Team (10-50 Developers)
Recommendation: CodeRabbit Pro on annual billing.
This is the sweet spot for CodeRabbit Pro. At $24/user/month with annual billing, the cost is predictable and the ROI is strong. A 25-developer team pays $7,200/year and likely saves $50,000+ in developer review time. Invest the first week in configuring custom review instructions aligned with your team’s standards for maximum impact.
Large Engineering Organization (50-200 Developers)
Recommendation: CodeRabbit Pro on annual billing, with potential Enterprise evaluation.
At 50-200 developers, the annual cost ranges from $14,400 to $48,960. This is still well within ROI territory. Evaluate whether you need Enterprise features (self-hosted, SSO, compliance logs) or whether Pro meets your needs. Many large organizations run Pro successfully without Enterprise. Only escalate to Enterprise if your security or compliance team requires self-hosted deployment or SSO.
Enterprise (500+ Developers)
Recommendation: Negotiate Enterprise pricing directly.
At 500+ seats, negotiate directly with CodeRabbit’s sales team. The published $15,000/month starting price for Enterprise is a floor, not a fixed rate. Leverage your volume for per-seat discounts, extended trial periods, and bundled implementation support. Consider purchasing through AWS or GCP Marketplace if your organization has cloud spending commitments to offset.
Open-Source Project
Recommendation: CodeRabbit Free tier (which gives you Pro features on public repos).
You already have the best deal in the market. CodeRabbit Pro is free forever on public repositories. Install it and benefit from auto-fix, 40+ linters, and custom review instructions at zero cost. If your project has a private staging repo or internal fork, the free tier covers those with rate limits.
Conclusion
CodeRabbit’s pricing structure is one of its key competitive advantages. The free tier is genuinely useful – not a crippled demo version designed to frustrate you into upgrading – and covers unlimited repositories and team members with AI-powered review. For small teams and open-source projects, the free tier may be all you ever need.
The Pro plan at $24/user/month sits in the middle of the AI code review market. It is more expensive than Sourcery ($12/user/month) and Codacy ($15/user/month for an all-in-one platform), but cheaper than Greptile ($30/seat/month with overage charges), DeepSource ($30/user/month), and Qodo Merge hosted ($30/user/month). The key differentiator at this price point is the combination of deep AI review, 40+ built-in linters, four-platform support, and the learnable preferences system that improves over time.
Enterprise pricing at approximately $15,000/month for 500+ seats is steep and prices out smaller organizations that need self-hosted deployment. For teams in that gap – needing on-premises but below 500 seats – PR-Agent self-hosted is the practical alternative.
The ROI math strongly favors CodeRabbit Pro for teams with 10 or more active developers. At $24/user/month, the tool needs to save each developer roughly 15-20 minutes per month to break even – and teams consistently report saving hours per week. The combination of auto-fix suggestions, deterministic linting, and reduced review cycle time delivers returns that make the pricing decision straightforward for most engineering organizations.
Start with the free tier, evaluate for a few weeks, and upgrade when the rate limits or feature gaps start costing more than the Pro subscription would. That is the most rational path, and CodeRabbit’s pricing structure is deliberately designed to support it.
Frequently Asked Questions
How much does CodeRabbit cost per developer?
CodeRabbit Pro costs $24 per developer per month on annual billing, or $30 per developer per month on monthly billing. The free tier covers unlimited public and private repositories with AI-powered PR summaries and review comments at no cost. You are only charged for developers who actually create pull requests – reviewers, managers, and other team members who do not open PRs are not counted toward your seat total.
Is CodeRabbit free?
Yes, CodeRabbit offers a genuinely useful free tier that covers unlimited public and private repositories with AI-powered PR summaries, review comments, and basic analysis. Free-tier users are subject to rate limits of 200 files per hour and 4 PR reviews per hour. There is no cap on the number of repositories or team members. Additionally, CodeRabbit Pro is free forever for open-source projects with public repositories.
What is the difference between CodeRabbit Free and Pro?
The CodeRabbit free tier provides AI-powered PR summaries, basic review comments, and support for unlimited repos with rate limits of 200 files per hour and 4 PR reviews per hour. The Pro plan at $24/user/month removes all rate limits and adds auto-fix suggestions, 40+ built-in linters, custom review instructions in natural language, learnable review preferences, Jira/Linear/Slack integrations, and priority support. Pro users also get access to the full suite of advanced AI analysis capabilities including deeper security and performance detection.
Does CodeRabbit charge for all team members?
No. CodeRabbit only charges for developers who create pull requests. Reviewers, project managers, QA engineers, and other team members who do not open PRs are not counted toward your seat total. This means your actual cost may be lower than multiplying the per-seat price by your total team size, since not every member of an engineering organization actively opens PRs.
How much does CodeRabbit Enterprise cost?
CodeRabbit Enterprise pricing is custom and starts at approximately $15,000 per month for organizations with 500 or more users. Enterprise includes everything in Pro plus self-hosted deployment, SSO/SAML authentication, custom AI models, multi-organization support, a dedicated customer success manager, SLA-backed support, compliance and audit logs, and VPN connectivity. Enterprise contracts are available through AWS and GCP Marketplace.
Is CodeRabbit free for open-source projects?
Yes. CodeRabbit Pro is free forever for open-source projects with public repositories. This means open-source maintainers get access to the full Pro feature set – including auto-fix suggestions, 40+ linters, and custom review instructions – at no cost. CodeRabbit has also distributed over $600,000 in sponsorships to open-source maintainers as part of its commitment to the open-source community.
Is CodeRabbit worth the price?
For most teams with 5 or more active developers, CodeRabbit Pro provides strong ROI. At $24/user/month, the cost is roughly equivalent to 15-30 minutes of a senior developer’s time per month. Teams report 50% or greater reduction in manual review effort and up to 80% faster review cycles. If CodeRabbit saves each developer even 2 hours per month in review time, the tool pays for itself many times over. The free tier also lets teams evaluate the tool without any financial commitment before upgrading.
How does CodeRabbit pricing compare to GitHub Copilot?
CodeRabbit Pro at $24/user/month is more expensive than GitHub Copilot Business at $19/user/month, but they serve different purposes. Copilot Business includes code completion, chat, and code review as part of a broader AI platform, while CodeRabbit is a dedicated code review tool with deeper review capabilities, 40+ built-in linters, and support for GitHub, GitLab, Azure DevOps, and Bitbucket. Copilot’s code review uses a premium request system with $0.04 overage charges that can increase costs for heavy users. CodeRabbit’s free tier with unlimited repos is more generous than Copilot’s 50-premium-request free limit.
How does CodeRabbit pricing compare to Greptile?
Greptile costs $30 per seat per month with 50 reviews per seat included and $1 per additional review after that. CodeRabbit Pro at $24/user/month has no per-review overage charges. For a 20-developer team, CodeRabbit Pro costs $480/month versus Greptile’s $600/month base cost before overages. Greptile offers deeper bug detection (82% catch rate versus CodeRabbit’s 44%) but produces more false positives and has no free tier. CodeRabbit’s free tier lets teams start at zero cost, while Greptile only offers a 14-day trial.
Can I try CodeRabbit Pro before paying?
Yes. CodeRabbit offers a 14-day free trial of the Pro plan with no credit card required. During the trial, you get full access to all Pro features including auto-fix suggestions, 40+ linters, custom review instructions, and integrations. After the trial, you can continue on the free tier with rate limits or upgrade to Pro. There is also a forever-free tier for evaluation and ongoing use if you do not need the advanced features.
Does CodeRabbit offer annual billing discounts?
Yes. CodeRabbit Pro costs $24/user/month on annual billing versus $30/user/month on monthly billing, which is a 20% discount. For a 50-developer team, this saves $3,600 per year. Annual billing is recommended for teams that have evaluated the tool and are committed to using it long-term.
What happens if I exceed CodeRabbit’s free tier limits?
On the free tier, CodeRabbit rate-limits you to 200 files per hour and 4 PR reviews per hour. If you exceed these limits, additional reviews are queued until the rate limit resets. You will not be charged anything – the free tier has no overage fees. Your reviews simply wait until capacity is available. For most small teams submitting fewer than 4 PRs per hour, these limits rarely matter in practice.
How does CodeRabbit’s self-hosted pricing work?
Self-hosted deployment is only available on the Enterprise plan, which requires a minimum of 500 seats and starts at approximately $15,000 per month. In addition to the software license, self-hosted infrastructure costs typically range from $500 to $8,000+ per month depending on scale and cloud provider. Enterprise contracts are available through AWS and GCP Marketplace. For organizations that need on-premises deployment but do not meet the 500-seat minimum, PR-Agent by Qodo is a free open-source alternative that can be self-hosted with your own LLM API keys.
Originally published at aicodereview.cc
The agent that forgets everything and remembers everything
Week 13, Post 3 — 2026-03-26 | Tags: ai-agent, memory, infrastructure, openClaw, automation
The paradox
Every session, m900 — the OpenClaw agent running on this machine — wakes up with zero memory of what happened yesterday. Blank slate. No recollection of the bot status, no idea what we discussed, no continuity at all.
And yet, it picks up exactly where we left off.
That’s not magic. It’s a design pattern that took a while to get right.
Stateless runtime, stateful files
The trick is that the agent doesn’t store memory — it reads it. Every session starts with:
SOUL.md       → who the agent is
USER.md       → who it's helping
MEMORY.md     → curated long-term knowledge
memory/YYYY-MM-DD.md → today's + yesterday's raw notes
These files are the brain. The agent is just the reader.
It’s the same architecture as a well-structured codebase: stateless functions, persistent data layer. You wouldn’t blame a function for “forgetting” the previous call — you’d ask why the state wasn’t stored correctly.
The agent isn’t broken. The question is always: “Did I write it down?”
What breaks this
The failure mode isn’t the agent forgetting. It’s the human not writing things down.
When Julio asks “what’s the status of the Arbitrum bot?” and nothing was logged after the last trade cycle, the agent has to infer. Inference is expensive — both in tokens and in correctness risk.
The fix is boring: log the outcome. Every significant event, decision, or configuration change goes into memory/YYYY-MM-DD.md. The agent reads it, the human doesn’t have to re-explain context, and the next session starts with full awareness.
This is identical to writing a proper incident report: not for you-now, but for you-tomorrow.
The token cost of forgetting
There’s a concrete cost to poor memory hygiene: context bloat.
If MEMORY.md is never pruned, it grows. Old entries about infrastructure decisions from three months ago stay in context alongside today’s questions. The model reads all of it — every call. At ~116k tokens per turn at peak, a significant portion of that is noise.
The discipline:
Prune the memory file the same way you’d prune a dependency list: if you can’t explain why it’s there, it probably shouldn’t be.
What this changes for human-AI workflows
Most AI assistant setups treat memory as a product feature (“remember my preferences”). That’s fine for consumer tools.
For infrastructure-grade AI workflows — agents running on a dedicated machine, processing real bot alerts, managing actual configuration — memory is an engineering problem.
Questions worth asking:
m900 handles the daily log writes autonomously. Julio handles the things only he knows. MEMORY.md gets reviewed in heartbeats. It’s a split responsibility, and it’s been working.
Where this is going
The grid bots are in steady state. The infrastructure isn’t changing. The next layer of experimentation is here: how do you make an AI agent reliably operational over months, not just sessions?
File-based memory is Phase 1. It works. Phase 2 will probably involve structured event logs that the agent can query rather than read linearly — more like a database, less like a journal.
That’s Aether Dynamo territory. Not started yet. But the pattern is forming.
Infrastructure: M900 Tiny (Ubuntu 24.04), system cron every 5 min, Python 3.12
Agent: OpenClaw / m900 | Channel: Telegram
Source: github.com/jmolinasoler/build-log

Yesterday we got started with a single-node vind cluster. That’s great for basic development, but if you want to test pod scheduling, node affinity, anti-affinity, topology constraints, or node drains, you need multiple nodes.
With KinD, multi-node configs work but you’re still limited to local Docker containers with no external node support. vind gives you the same multi-node Docker setup, plus the option to add real cloud nodes later (we’ll cover that in Day 4).
Today, let’s create a 4-node cluster and put it through its paces.
The Configuration
Create a multi-node.yaml file:
experimental:
  docker:
    nodes:
      - name: worker-1
      - name: worker-2
      - name: worker-3
That’s it. This tells vind to create 3 additional worker nodes alongside the control plane. Each worker runs as its own Docker container with kubelet, kube-proxy, and Flannel.

Create the Cluster
Command:
vcluster create multi-node -f multi-node.yaml
Output:
12:57:42 info Using vCluster driver 'docker' to create your virtual clusters, which means the CLI is managing Docker-based virtual clusters locally
12:57:42 info If you prefer to use helm or the vCluster platform API instead, use '--driver helm' or '--driver platform', or run 'vcluster use driver helm' or 'vcluster use driver platform' to change the default
12:57:42 info Ensuring environment for vCluster multi-node...
12:57:43 done Created network vcluster.multi-node
12:57:47 warn Load balancer type services are not supported inside the vCluster because this command was executed with insufficient privileges. To enable load balancer type services, run this command with sudo
12:57:48 info Will connect vCluster multi-node to platform...
12:57:49 info Starting vCluster standalone multi-node
12:57:51 info Adding node worker-1 to vCluster multi-node
12:57:52 info Joining node vcluster.node.multi-node.worker-1 to vCluster multi-node...
12:58:17 info Adding node worker-2 to vCluster multi-node
12:58:17 info Joining node vcluster.node.multi-node.worker-2 to vCluster multi-node...
12:58:24 info Adding node worker-3 to vCluster multi-node
12:58:24 info Joining node vcluster.node.multi-node.worker-3 to vCluster multi-node...
12:58:31 done Successfully created virtual cluster multi-node
12:58:31 info Finding docker container vcluster.cp.multi-node...
12:58:31 info Waiting for vCluster kubeconfig to be available...
12:58:32 info Waiting for vCluster to become ready...
12:58:32 done vCluster is ready
12:58:32 done Switched active kube context to vcluster-docker_multi-node
- Use `vcluster disconnect` to return to your previous kube context
- Use `kubectl get namespaces` to access the vcluster
Each node takes about 10 seconds to join. Let’s verify:
Command:
kubectl get nodes -o wide
Output:
NAME         STATUS   ROLES                  AGE    VERSION
multi-node   Ready    control-plane,master   122m   v1.35.0
worker-1     Ready    <none>                 122m   v1.35.0
worker-2     Ready    <none>                 122m   v1.35.0
worker-3     Ready    <none>                 122m   v1.35.0
Four nodes, one control plane and three workers. Each has its own IP on the Docker network, running Kubernetes v1.35.0. This looks exactly like a real multi-node cluster.
Deploy and Watch Pod Distribution
Let’s deploy 6 replicas and see how Kubernetes distributes them:
kubectl create deployment web --image=nginx:latest --replicas=6
deployment.apps/web created
After a few seconds:
kubectl get pods -o wide
Output:
NAME                  READY   STATUS    RESTARTS   AGE   IP           NODE         NOMINATED NODE   READINESS GATES
web-ff44d897b-5ffqt   1/1     Running   0          8s    10.244.5.2   worker-3     <none>           <none>
web-ff44d897b-7vm76   1/1     Running   0          8s    10.244.2.3   worker-1     <none>           <none>
web-ff44d897b-hpf9d   1/1     Running   0          8s    10.244.5.3   worker-3     <none>           <none>
web-ff44d897b-l4c7t   1/1     Running   0          8s    10.244.4.2   worker-2     <none>           <none>
web-ff44d897b-p276z   1/1     Running   0          8s    10.244.2.2   worker-1     <none>           <none>
web-ff44d897b-z77gm   1/1     Running   0          8s    10.244.0.4   multi-node   <none>           <none>
Look at the NODE column, pods are distributed across all 4 nodes: – worker-1: 2 pods (10.244.2.x subnet) – worker-2: 1 pod (10.244.3.x subnet) – worker-3: 2 pods (10.244.4.x subnet) – multi-node (control plane): 1 pod (10.244.0.x subnet)
Each node has its own Flannel subnet. The Kubernetes scheduler is doing real scheduling across real (containerized) nodes.
Test Node Drain
This is where multi-node really shines. Let’s drain worker-3 and watch pods get rescheduled:
Command:
kubectl drain worker-3 --ignore-daemonsets --delete-emptydir-data
Output:
Warning: ignoring DaemonSet-managed Pods: kube-flannel/kube-flannel-ds-fpr8n, kube-system/kube-proxy-dsg8b
evicting pod default/web-ff44d897b-hpf9d
evicting pod default/web-ff44d897b-5ffqt
pod/web-ff44d897b-5ffqt evicted
pod/web-ff44d897b-hpf9d evicted
node/worker-3 drained
Both pods on worker-3 were evicted. Where did they go?
Command:
kubectl get pods -o wide
Output:
NAME                   READY   STATUS    RESTARTS   AGE     IP           NODE         NOMINATED NODE   READINESS GATES
NAME                  READY   STATUS    RESTARTS   AGE   IP           NODE         NOMINATED NODE   READINESS GATES
web-ff44d897b-7vm76   1/1     Running   0          20m   10.244.2.3   worker-1     <none>           <none>
web-ff44d897b-hchpq   1/1     Running   0          19m   10.244.4.3   worker-2     <none>           <none>
web-ff44d897b-l4c7t   1/1     Running   0          20m   10.244.4.2   worker-2     <none>           <none>
web-ff44d897b-p276z   1/1     Running   0          20m   10.244.2.2   worker-1     <none>           <none>
web-ff44d897b-pc4cx   1/1     Running   0          19m   10.244.0.5   multi-node   <none>           <none>
web-ff44d897b-z77gm   1/1     Running   0          20m   10.244.0.4   multi-node   <none>           <none>
The scheduler created new pods on worker-2 and the control plane node. Zero pods on worker-3. This is exactly how it works in production.
Uncordon when you’re done:
Command:
kubectl uncordon worker-3
Output:
node/worker-3 uncordoned
Testing Node Affinity
With multi-node, you can test real node affinity rules:
apiVersion: apps/v1
kind: Deployment
metadata:
  name: worker-only
spec:
  replicas: 3
  selector:
    matchLabels:
      app: worker-only
  template:
    metadata:
      labels:
        app: worker-only
    spec:
      affinity:
        nodeAffinity:
          requiredDuringSchedulingIgnoredDuringExecution:
            nodeSelectorTerms:
            - matchExpressions:
              - key: node-role.kubernetes.io/control-plane
                operator: DoesNotExist
      containers:
      - name: nginx
        image: nginx:latest
This ensures pods only run on worker nodes, not the control plane, something you can only test with multiple nodes.
kubectl apply -f affinity.yaml
deployment.apps/worker-only created
kubectl get po -owide
worker-only-86dd84d489-6v98m   1/1     Running   0          15s   10.244.5.4   worker-3     <none>           <none>
worker-only-86dd84d489-hmbq4   1/1     Running   0          15s   10.244.4.4   worker-2     <none>           <none>
worker-only-86dd84d489-xdttw   1/1     Running   0          15s   10.244.2.4   worker-1     <none>           <none>
Pod Anti-Affinity
Force pods to spread across different nodes:
apiVersion: apps/v1
kind: Deployment
metadata:
  name: spread-app
spec:
  replicas: 3
  selector:
    matchLabels:
      app: spread-app
  template:
    metadata:
      labels:
        app: spread-app
    spec:
      topologySpreadConstraints:
      - maxSkew: 1
        topologyKey: kubernetes.io/hostname
        whenUnsatisfiable: DoNotSchedule
        labelSelector:
          matchLabels:
            app: spread-app
      containers:
      - name: nginx
        image: nginx:latest
With 3 replicas and 3 workers, each worker gets exactly one pod. Try doing that with a single-node cluster.
kubectl apply -f antiaffinity.yaml
deployment.apps/spread-app created
kubectl get po  -owide | grep spread
spread-app-596d884c4d-hp585    1/1     Running   0          10s   10.244.4.5   worker-2     <none>           <none>
spread-app-596d884c4d-j4hcm    1/1     Running   0          10s   10.244.5.5   worker-3     <none>           <none>
spread-app-596d884c4d-lj7c5    1/1     Running   0          10s   10.244.2.5   worker-1     <none>           <none>
Environment Variables for Workers
You can pass environment variables to worker containers:
experimental:
  docker:
    nodes:
      - name: worker-1
        env:
          - "CUSTOM_VAR=value1"
      - name: worker-2
        env:
          - "CUSTOM_VAR=value2"
      - name: worker-3
These are Docker container environment variables, useful for differentiating nodes in testing scenarios.
Cleanup
Command:
vcluster delete multi-node
16:18:36 info Using vCluster driver 'docker' to delete your virtual clusters, which means the CLI is managing Docker-based virtual clusters locally
16:18:36 info If you prefer to use helm or the vCluster platform API instead, use '--driver helm' or '--driver platform', or run 'vcluster use driver helm' or 'vcluster use driver platform' to change the default
16:18:36 info Removing vCluster container vcluster.cp.multi-node...
16:18:39 info Removing vCluster node worker-3...
16:18:40 info Removing vCluster node worker-2...
16:18:42 info Removing vCluster node worker-1...
16:18:44 info Delete virtual cluster instance p-default/multi-node in platform
16:18:44 info Deleted kube context vcluster-docker_multi-node
16:18:44 done Successfully deleted virtual cluster multi-node
Tomorrow: External Nodes
Multi-node with Docker containers is powerful, but what if you need real cloud resources? A GPU instance? A specific CPU architecture? Tomorrow, we’ll add a GCP Compute Engine instance as an external worker node to a vind cluster, all connected via VPN. That’s something KinD simply cannot do.
All commands tested on macOS (Apple Silicon M1) with Docker Desktop and vCluster CLI v0.31.0.