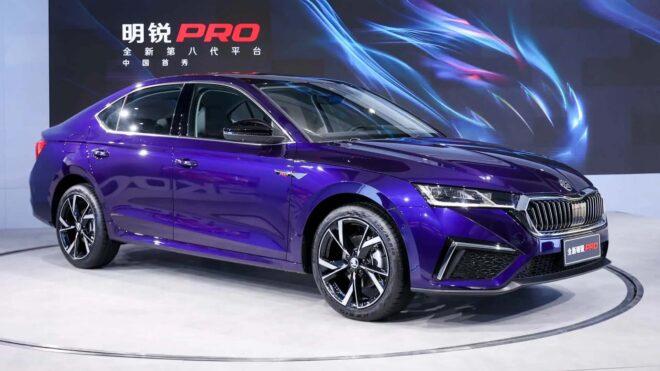
Volkswagen, Skoda’yı Çin pazarından çekme kararı aldı

Skoda Volkswagen

Skoda VolkswagenBugün yapılan resmi açıklamaya göre Volkswagen, çatısı altında yer alan markalardan Skoda’yı Çin pazarından çekme kararı aldı. Çin’de 2021 yılında 71.000 adet, 2022 yılında 44.600 adet, 2023 yılında 22.800 adet, 2024 yılında 17.500 adet, 2025 yılında ise 15.000 adet araç sattığı açıklanan marka, yerli üreticilerin çok iddialı elektrikli otomobilleriyle domine ettiği Çin otomobil pazarındaki rekabet gücünü tamamen kaybetmiş durumda.

Volkswagen, Skoda’yı Çin pazarından çekme kararı aldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

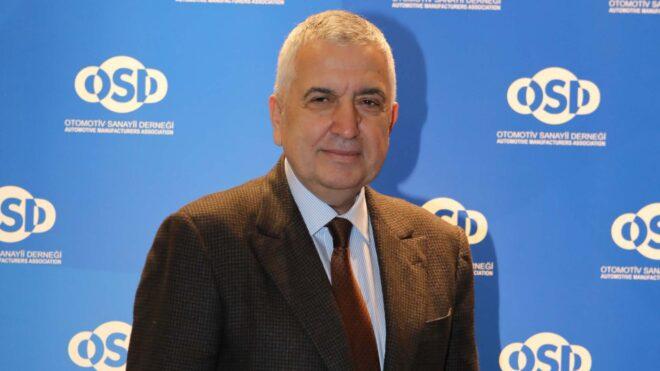
OSD’nin Yönetim Kurulu Başkanlığı’na yeniden Cengiz Eroldu seçildi

OSD’nin Yönetim Kurulu Başkanlığı’na yeniden Cengiz Eroldu seçildi

OSD’nin Yönetim Kurulu Başkanlığı’na yeniden Cengiz Eroldu seçildiOtomotiv Sanayii Derneği (OSD), 51’inci Olağan Genel Kurulu’nu gerçekleştirdi. Cengiz Eroldu beşinci döneminde yeniden Başkan olarak seçilirken, Başkan Vekili Süer İsmail Sülün, Başkan Yardımcıları Güven Özyurt, Lionel Jaillet ve Murat Bülbül, Muhasip Üye Yusuf Tuğrul Arıkan oldu. T.C. Sanayi ve Teknoloji Bakanı Mehmet Fatih Kacır, Bakan Yardımcısı Zekeriya Coştu ve T.C. Ticaret Bakan Yardımcısı Özgür Volkan Ağar’ın katıldığı Genel Kurul’da konuşan OSD Başkanı Cengiz Eroldu, “2025 yılı, Türk otomotiv sanayisinin yatırımlarına devam ettiği, yeni projelerini hayata geçirdiği, üretim ve mühendislik gücü ile ihracat kapasitesini bir kez daha ortaya koyduğu bir yıl oldu. 41,5 milyar dolarlık rekor seviyede gerçekleşen ihracat, sanayinin uluslararası pazarlardaki güçlü konumunu teyit etti. İçinde bulunduğumuz dönemde küresel ortamda yaşanan ticaret savaşları ve değişen dünya düzeni bizleri daha belirsiz, daha rekabetçi ve daha yerelleşme odaklı politikalar ile karşı karşıya bırakıyor. Bu yeni dönemde de önceliğimiz, kamu başta olmak üzere tüm paydaşlarımız ile iş birliği içerisinde, sanayimizin güçlü yönlerini […]

OSD’nin Yönetim Kurulu Başkanlığı’na yeniden Cengiz Eroldu seçildi yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

OpenAI, ChatGPT’nin “yetişkin” modunu daha çıkmadan rafa kaldırdı

OpenAI ChatGPT LOG Tasarım

OpenAI ChatGPT LOG TasarımOpenAI şirketinin CEO’su Sam Altman, geçtiğimiz yıl X hesabından yaptığı bir açıklamada, “ChatGPT’yi başlangıçta ruh sağlığıyla ilgili konularda dikkatli olmak adına daha kısıtlayıcı bir biçimde tasarladık. Bunun, ruhsal sorunu olmayan kullanıcıların elde ettiği deneyimi bozduğunu biliyoruz. Ancak konunun ciddiyeti nedeniyle her şeyi doğru yapmamız gerekiyordu. Geliştirme çalışmalarıyla ruh sağlığıyla ilgili büyük riskleri azalttık ve artık elimizde bu sürece karşı oldukça güçlü yeni araçlar var. Bu sayede getirdiğimiz kısıtlamaları çoğu durumda güvenli bir şekilde gevşetebileceğiz. Aralık ayında yaş doğrulama sisteminin tam olarak devreye alınmasıyla birlikte, ‘yetişkin kullanıcılara yetişkin gibi davranma’ ilkemiz kapsamında doğrulanmış yetişkin kullanıcılar için erotik içerikler de dâhil olmak üzere daha geniş etkileşim özgürlükleri sağlayacağız.” demişti. Altman, cinselleştirilmiş yapay zeka içeriklerinin toplum üzerinde yaratabileceği zararlı etkiler nedeniyle çalışanlar ve yatırımcıların tepkisini çektiği için tamamen rafa kaldırıldığı aktarılan altyapıya ilişkin yaptığı son açıklamada ise, “Yetişkin modunun çıkışını biraz erteliyoruz. Odağımızı kullanıcılar için daha önemli olan konulara çevirdik. Genel zekayı artırmaya, […]

OpenAI, ChatGPT’nin “yetişkin” modunu daha çıkmadan rafa kaldırdı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

How I Built White-Label Document Sharing for Client-Facing Docs

When people send proposals, pitch decks, NDAs, and other client-facing documents, they usually want the recipient focused on their brand, not the software powering the experience.

That was the motivation behind a feature I recently shipped in DocBeacon: white-label document sharing for Pro users.

The idea sounds simple:

Let users attach a custom brand name, logo, and website URL to shared documents.

But once I got into implementation, it turned into an interesting mix of product design, access control, storage, validation, and fallback behavior.

This post is a short breakdown of how I approached it.

The problem

Before this feature, a shared document was still visually branded as DocBeacon throughout the viewing flow.

That was fine for some use cases, but not ideal for teams sending:

consulting proposals
investor decks
sales documents
sensitive client materials

In those workflows, brand consistency matters. If someone is sharing a high-value proposal, they usually want the experience to reinforce their credibility, not mine.

So the requirement became:

Let eligible users show their own branding across the document viewing experience, while keeping the system safe and predictable.

What the feature needed to support

At a high level, I wanted users to be able to configure:

a display name
a logo
a website URL
an on/off toggle for branding

And once enabled, that branding should appear in places like:

the document viewer header
attribution text
shared document metadata
other client-facing viewer touchpoints

I also wanted a clean fallback path. If branding data was incomplete, invalid, or the user’s plan didn’t allow the feature, the system should quietly fall back to the default DocBeacon brand.

The core design decision: resolve branding once

One of the first decisions I made was to avoid scattering branding logic across multiple rendering layers.

Instead of asking every page or component to figure out branding on its own, I used a single resolution step:

Check whether the user is allowed to use the feature
Check whether branding is enabled
Check whether enough valid branding data exists
Return either:
the user’s brand config, or
the default platform brand

In pseudocode:

**function resolveBranding(user):
    canBrand = planAllowsBranding(user.plan)
    hasIdentity = user.displayName OR user.logoPath
    enabled = user.brandingEnabled AND canBrand AND hasIdentity

    if enabled:
        return {
            name: user.displayName,
            logoUrl: buildAssetUrl(user.logoPath),
            websiteUrl: normalizeUrl(user.websiteUrl)
        }

    return defaultBrand**

This helped keep the rest of the system simple. Viewer pages didn’t need to know all the rules. They just consumed a resolved branding object.

Access control

This feature is only available on Pro+ plans, so access control had to be built into the feature itself, not just the UI.

That means even if someone somehow submits branding settings through an API call or stale client state, the backend still needs to enforce eligibility.

The check is conceptually simple:

canUseBranding(user):
    return user.plan in ["pro", "business", "enterprise"]

I treated this as a server-side rule first, and a UI rule second.

That’s important because frontend gating alone is never enough for plan-restricted features.

Asset storage for logos

For logo uploads, I wanted a storage layer that was simple, cheap, and fast to serve publicly.

I used Cloudflare R2 for uploaded branding assets.

The flow looks roughly like this:

User uploads a PNG or JPG
Backend validates file type and size
File is stored under a user-scoped path
The app stores only the storage path in the user record
A helper builds the public asset URL when needed

In pseudocode:

uploadLogo(file, user):
    assert file.type in ["image/png", "image/jpeg"]
    assert file.size <= MAX_LOGO_SIZE

    path = "branding/" + user.id + "/" + generateFileName(file)
    storage.put(path, file)

    saveUserBranding(user.id, { logoPath: path })

And later:

buildAssetUrl(path):
    return CDN_BASE_URL + "/" + path

I preferred storing the path rather than a fully expanded URL in the database, because it keeps storage concerns separate from delivery concerns.

URL validation was the trickiest part

The hardest part of this feature was not rendering a logo.

It was letting users attach a website URL safely.

On the surface, “enter your website” sounds trivial. In practice, it needs guardrails.

I did not want to allow:

localhost
private network IPs
credential-based URLs like user:[email protected]
unsafe schemes like javascript: or file:

So I treated URL handling as a normalization + validation pipeline.

The job of that pipeline is:

parse the input
normalize format
require http or https
reject unsafe hosts
reject credentials
return either a safe URL or null

In pseudocode:

normalizeUrl(input):
    if input is empty:
        return null

    parsed = parseUrl(input)

    if parsed.scheme not in ["http", "https"]:
        return null

    if parsed.hasCredentials:
        return null

    if isLocalhost(parsed.host) or isPrivateIp(parsed.host):
        return null

    return parsed.normalizedHref

This kind of defensive validation matters because branding fields are user-controlled input, and user-controlled input always deserves scrutiny.

Fallback behavior matters more than people think

A lot of polish in a feature like this comes from handling invalid states well.

For example:

branding is toggled on, but no logo is uploaded yet
the user entered an invalid URL
the user downgraded from Pro to Free
an asset was deleted or unavailable
branding data is partially filled out

In all of those cases, I wanted the document experience to remain stable.

So instead of letting the UI break or showing half-configured branding, I default to the platform brand whenever the custom brand can’t be resolved safely.

That gives the system a predictable contract:

Either show a fully valid custom brand, or show the default brand.

No broken middle state.

Why I like this implementation

What I like about this feature is that it makes the product less visible in the right places.

For this use case, that’s the goal.

The product should support the sender’s identity, not compete with it.

From an engineering point of view, I also like that the system is built around a few clear principles:

central branding resolution
server-side plan enforcement
explicit URL normalization
safe asset handling
reliable fallback behavior

The final result feels simple to the user, which usually means the internal rules are doing their job.

What I’d improve next

A few things I’d likely add next:

custom domains for shared links
better branding previews in settings
image processing for uploaded logos
audit logging for branding changes
more granular per-document branding controls

That would take it from “account-level branding” to a more flexible identity layer.

Final thought

This started as a branding feature, but it ended up being a good reminder that “simple UX” often sits on top of a lot of backend discipline.

If you’re building anything user-configurable and client-facing, the hard part usually isn’t just rendering the settings.

It’s defining the rules for what’s allowed, what’s safe, and what happens when the input is incomplete.

If you’re curious, the product is DocBeacon: https://docbeacon.io

Understanding a Real-World Spring Boot Project Structure (Best Practices)

🧩 Understanding a Real-World Spring Boot Project Structure (Best Practices)

When you start working with Spring Boot, everything feels simple… until your project grows.

Then suddenly:

😵Too many files
😵‍💫Confusing structure
❌Hard to maintain code

In this article, I’ll walk you through a clean and scalable Spring Boot project structure based on a real example.

📁 Project Overview

Here’s a simplified view of the structure:

src/main/java/org.sid
├── controllers
├── dto
├── entities
├── enums
├── mappers
├── repositories
├── securityKeycloak
├── services

Each layer has a clear responsibility, which makes the application maintainable and scalable.

🎯 1. Entities (entities)

Represents database tables.

🧠 2. Repository Layer (repositories)

This layer communicates with the database.

👉 Uses Spring Data JPA

✅ No implementation needed — Spring generates it automatically!

🗄️ 3. DTOs (dto)

DTO = Data Transfer Object
👉 Used to send data between layers safely

✅ Why use DTOs?
_Protect sensitive Data:_
In a Spring Boot application, a DTO (Data Transfer Object) is used to transfer data between layers, especially between the backend and the client.
It is used to protect sensitive data: entities often contain sensitive fields such as passwords. If you return these entities directly, it can create a security risk.

Control API response:
A DTO (Data Transfer Object) allows you to decide exactly what data is sent to the client instead of exposing your full Entity.

🔁 4. Mappers (mappers)

Convert between Entity ↔ DTO

public class AccountMapper {
public static AccountDTO toDTO(Account account) {
// mapping logic
}
}

💡 You can also use MapStruct for cleaner code.

🔄 5. Service Layer (services)

This is where business logic lives.

👉 Acts as a bridge between controller and repository

@Service
public class AccountService {

public List<AccountDTO> getAllAccounts() {
    // business logic here
}

}
example:

✅ Responsibilities:

-    Business rules
-    Data processing
-    Validation

📦 6.Controllers Layer (controllers)

This is the entry point of your application.

👉 Handles HTTP requests (GET, POST, PUT, DELETE)

Example:

✅ Best Practice:
Keep controllers thin , No business logic here

⚠️ Important:
Do NOT expose entities directly in APIs

🔢 7. Enums (enums)

Used for fixed values like:

🔐 8. Security (securityKeycloak)

Handles authentication & authorization.

👉 In my case: Keycloak integration

Responsibilities:

  • JWT validation
  • User roles
  • Secure endpoints

🔄 How Everything Works Together

Here’s the flow:


spring Boot Flow Architecture

  1. Client sends HTTP request
  2. Controller receives it
  3. Service processes logic
  4. Repository fetches data
  5. Mapper converts Entity → DTO
  6. Response returned to client

🚀 Best Practices Recap

  ✅ Use layered architecture
  ✅ Never expose entities
  ✅ Keep controllers clean
  ✅ Use DTOs + Mappers
  ✅ Separate business logic in services

🎯 Conclusion

A well-structured Spring Boot project is the key to building scalable and maintainable applications.

Happy coding 🚀

Amazon MQ Pricing: What’s Really on Your Bill

Amazon MQ looks simple on the bill until you pull it apart. Most teams spin up a managed ActiveMQ or RabbitMQ broker, send a few messages, and move on. Then the invoice arrives with line items they didn’t expect.

Let’s break down exactly where the money goes — and what catches people off guard.

The Broker Instance: It’s Not a Flat Rate

Amazon MQ charges per broker instance-hour based on the instance type and engine. There’s no single “broker fee.” The range is wide:

Instance Type Engine Hourly Rate Monthly (730 hrs)
mq.t3.micro ActiveMQ $0.034 $24.82
mq.t3.micro RabbitMQ $0.034 $24.82
mq.m5.large ActiveMQ $0.276 $201.48
mq.m5.large RabbitMQ $0.276 $201.48
mq.m5.xlarge ActiveMQ $0.552 $402.96
mq.m5.2xlarge ActiveMQ $1.104 $805.92
mq.m5.4xlarge ActiveMQ $2.208 $1,611.84

Prices shown for us-east-1, On-Demand.

A common mistake is assuming the smallest broker is “cheap.” Even an mq.t3.micro runs 24/7, costing roughly $25/month before anything else. An mq.m5.large — the default many teams pick — is over $200/month per broker.

High Availability Doubles the Compute Cost

ActiveMQ supports active/standby deployment for high availability. This means two broker instances in different Availability Zones. Your compute cost doubles immediately:

  • Single-instance mq.m5.large: $201.48/month
  • Active/standby mq.m5.large: $402.96/month

RabbitMQ achieves HA through a three-node cluster deployment, which means you’re paying for three instances. An mq.m5.large RabbitMQ cluster costs roughly $604/month in compute alone.

Teams often enable HA for production brokers and forget about it on dev/staging environments — where a single instance would be fine.

Storage: EBS vs. EFS Is a 3× Price Difference

ActiveMQ brokers on Amazon MQ offer two storage backends:

Storage Type Cost Use Case
EBS $0.10/GB-month Standard durability, faster throughput
EFS $0.30/GB-month Shared storage for active/standby pairs

EFS is required for active/standby deployments since both brokers need access to the same persistent store. That’s a 3× premium over EBS.

A broker with 50 GB of message storage on EFS costs $15/month in storage alone. Not huge, but it adds up across multiple brokers and environments.

RabbitMQ brokers use EBS exclusively — no EFS option.

Data Transfer: The Silent Multiplier

Standard AWS data transfer charges apply to Amazon MQ:

  • Same AZ: Free
  • Cross-AZ (typical for HA): $0.01/GB each way
  • Cross-Region: $0.02/GB
  • Internet outbound: $0.09/GB (first 10 TB)

For active/standby deployments, replication traffic between AZs is cross-AZ data transfer. High-throughput brokers processing millions of messages per day can accumulate meaningful cross-AZ charges that don’t appear under the “AmazonMQ” line item on your bill — they show up under general data transfer.

The Real Problem: Idle Brokers

Here’s what actually burns money with Amazon MQ: brokers that nobody is using.

It’s remarkably common. A team provisions a broker for a proof of concept, connects a few services, then the project pivots. The broker sits there at $200+/month with zero messages flowing through it. No consumers, no producers, no connections — just a running instance charging by the hour.

Unlike Lambda or SQS, Amazon MQ has no scale-to-zero capability. A broker with zero messages costs the same as one processing thousands per second.

The pattern we see most often:

  1. Dev/staging brokers left running after the sprint ends
  2. Migration brokers kept “just in case” after switching to SQS or EventBridge
  3. HA-enabled brokers in non-production environments

How to Spot the Waste

Look at these CloudWatch metrics for each broker:

  • TotalMessageCount: If this is zero over 7–14 days, the broker is idle
  • CurrentConnectionsCount: Zero connections means nothing is even trying to talk to it
  • TotalConsumerCount / TotalProducerCount: Both at zero confirms no active clients

If all three are zero for more than a week, you’re paying for a parking spot nobody is using.

CloudWise detects idle Amazon MQ brokers automatically by analyzing CloudWatch connection and message metrics. If your broker has had zero activity for 14 days, CloudWise flags it with the full monthly cost so you can decide whether to keep it or shut it down.

CloudWise automates AWS cost analysis across 145+ waste detectors. Try it at cloudcostwise.io

Ask Your CSV Anything: Build a Data Analysis Agent in Python

Every data scientist has the same ritual. Load a CSV. Write df.describe(). Squint at column names. Write 14 lines of pandas to answer one question. Repeat.

What if an LLM could write those 14 lines for you — and run them?

That is exactly what data analysis agents do. You ask a question in English. The agent writes pandas code, executes it in a sandboxed Python environment, reads the output, and returns a plain-language answer. No manual wrangling. No copy-pasting between notebook cells.

Here are 4 patterns that make this work in production — from a 5-line quick start to a fully custom analysis pipeline.

Pattern 1: The Pandas DataFrame Agent

LangChain’s create_pandas_dataframe_agent is the fastest path from CSV to answers. It wraps your DataFrame in a tool-calling agent that writes and executes pandas code through a sandboxed Python REPL.

Install the dependencies:

pip install langchain-experimental langchain-openai pandas

Load your data and create the agent:

import pandas as pd
from langchain_openai import ChatOpenAI
from langchain_experimental.agents.agent_toolkits import (
    create_pandas_dataframe_agent,
)

df = pd.read_csv("sales_data.csv")

llm = ChatOpenAI(model="gpt-4o", temperature=0)

agent = create_pandas_dataframe_agent(
    llm,
    df,
    agent_type="tool-calling",
    verbose=True,
    allow_dangerous_code=True,
)

The allow_dangerous_code=True flag is mandatory. The agent executes real Python code against your DataFrame, so it must be opted into explicitly. Run this only in a sandboxed environment — never on a production server with sensitive data.

Now ask questions:

result = agent.invoke("What are the top 5 products by total revenue?")
print(result["output"])

The agent inspects the DataFrame’s columns and dtypes, writes a pandas expression like df.groupby('product')['revenue'].sum().nlargest(5), executes it, and returns the result as natural language.

Multi-DataFrame support. Pass a list of DataFrames to compare datasets:

df_2024 = pd.read_csv("sales_2024.csv")
df_2025 = pd.read_csv("sales_2025.csv")

agent = create_pandas_dataframe_agent(
    llm,
    [df_2024, df_2025],
    agent_type="tool-calling",
    verbose=True,
    allow_dangerous_code=True,
)

result = agent.invoke(
    "Which products grew more than 20% between 2024 and 2025?"
)

When to use this pattern: Small to medium datasets (under 1 million rows) that fit in memory. Quick exploratory analysis. Prototyping.

Limitation: The agent sends the first few rows and column names to the LLM as context. For wide DataFrames with 100+ columns, this context can overwhelm the model’s attention. For large datasets, use Pattern 2.

Pattern 2: The SQL Agent for Larger Datasets

When your data outgrows a DataFrame — millions of rows, multiple related tables, or anything that benefits from indexing — convert it to SQLite and let a SQL agent handle the queries.

pip install langchain-community langchain-openai sqlalchemy

Load your CSV into SQLite and create the agent:

import pandas as pd
import sqlalchemy
from langchain_community.utilities import SQLDatabase
from langchain_community.agent_toolkits import create_sql_agent
from langchain_openai import ChatOpenAI

engine = sqlalchemy.create_engine("sqlite:///analysis.db")

df_orders = pd.read_csv("orders.csv")
df_customers = pd.read_csv("customers.csv")
df_orders.to_sql("orders", engine, if_exists="replace", index=False)
df_customers.to_sql("customers", engine, if_exists="replace", index=False)

db = SQLDatabase(engine)
print(f"Tables: {db.get_usable_table_names()}")

llm = ChatOpenAI(model="gpt-4o", temperature=0)

agent = create_sql_agent(
    llm,
    db=db,
    agent_type="tool-calling",
    verbose=True,
)

Now ask questions that span multiple tables:

result = agent.invoke(
    "What is the average order value per customer segment?"
)
print(result["output"])

The agent inspects the database schema, writes a SQL query with the appropriate JOINs, executes it, and translates the result into English.

Why SQL beats pandas at scale:

  1. Indexing. SQLite creates indexes that make filtering and joining fast. Pandas scans the full DataFrame.
  2. Memory. SQLite reads from disk. Pandas loads everything into RAM.
  3. Joins. SQL JOINs are declarative and optimized. Pandas merges require explicit column mapping and can be memory-intensive.
  4. Audit trail. Every query the agent writes is a valid SQL statement you can review and rerun.

Safety note: The SQL agent generates and executes queries against your database. Use a read-only connection or a copy of your data for analysis. Never point it at a production database with write access.

engine = sqlalchemy.create_engine(
    "sqlite:///analysis.db",
    connect_args={"check_same_thread": False},
)

# For read-only protection, use a copy of the database
# or set PRAGMA query_only = ON
with engine.connect() as conn:
    conn.execute(sqlalchemy.text("PRAGMA query_only = ON"))

Pattern 3: Custom Analysis Tools With Tool-Calling

The pre-built agents handle common cases. But real data analysis needs domain-specific operations — statistical tests, time series decomposition, custom visualizations. Build a custom tool-calling agent that exposes exactly the operations your analysts need.

pip install langchain-openai langgraph scipy

Define your analysis tools as Python functions with clear docstrings — the LLM reads these to decide which tool to call:

import pandas as pd
import json
from scipy import stats
from langchain_openai import ChatOpenAI
from langchain_core.tools import tool

df = pd.read_csv("experiment_results.csv")


@tool
def describe_dataset(column: str) -> str:
    """Get summary statistics for a specific column in the dataset.
    Returns count, mean, std, min, 25%, 50%, 75%, max."""
    if column not in df.columns:
        return f"Column '{column}' not found. Available: {list(df.columns)}"
    return df[column].describe().to_json()


@tool
def compare_groups(
    group_column: str, value_column: str, group_a: str, group_b: str
) -> str:
    """Run a two-sample t-test comparing two groups on a numeric column.
    Returns t-statistic, p-value, and whether the difference is
    statistically significant at alpha=0.05."""
    a = df[df[group_column] == group_a][value_column].dropna()
    b = df[df[group_column] == group_b][value_column].dropna()
    t_stat, p_value = stats.ttest_ind(a, b)
    significant = p_value < 0.05
    return json.dumps({
        "group_a_mean": round(a.mean(), 4),
        "group_b_mean": round(b.mean(), 4),
        "t_statistic": round(t_stat, 4),
        "p_value": round(p_value, 6),
        "significant_at_0.05": significant,
        "n_a": len(a),
        "n_b": len(b),
    })


@tool
def correlation_matrix(columns: list[str]) -> str:
    """Calculate pairwise Pearson correlations between specified columns.
    Returns a correlation matrix as JSON."""
    valid = [c for c in columns if c in df.columns]
    if not valid:
        return f"No valid columns found. Available: {list(df.columns)}"
    corr = df[valid].corr()
    return corr.to_json()


@tool
def filter_and_aggregate(
    filter_column: str,
    filter_value: str,
    agg_column: str,
    agg_function: str,
) -> str:
    """Filter the dataset by a column value, then aggregate another column.
    Supported agg_function values: mean, sum, count, min, max, median."""
    valid_aggs = {"mean", "sum", "count", "min", "max", "median"}
    if agg_function not in valid_aggs:
        return f"Invalid agg_function. Use one of: {valid_aggs}"
    filtered = df[df[filter_column] == filter_value]
    result = getattr(filtered[agg_column], agg_function)()
    return json.dumps({
        "filter": f"{filter_column} == {filter_value}",
        "rows_matched": len(filtered),
        "aggregation": f"{agg_function}({agg_column})",
        "result": round(float(result), 4),
    })

Wire the tools into a tool-calling agent:

from langchain_core.messages import SystemMessage

tools = [describe_dataset, compare_groups, correlation_matrix, filter_and_aggregate]

llm = ChatOpenAI(model="gpt-4o", temperature=0)
llm_with_tools = llm.bind_tools(tools)

system_prompt = """You are a data analysis assistant. You have access to a dataset
with these columns: {columns}

When the user asks a question:
1. Identify which tools can answer it
2. Call the appropriate tool(s)
3. Interpret the results in plain language
4. Note statistical significance, sample sizes, and caveats

Always mention sample sizes when reporting statistical results.""".format(
    columns=list(df.columns)
)

from langgraph.prebuilt import create_react_agent

agent = create_react_agent(llm, tools)

Ask domain-specific questions:

result = agent.invoke({
    "messages": [
        {"role": "system", "content": system_prompt},
        {
            "role": "user",
            "content": "Is there a significant difference in conversion rate between the control and treatment groups?",
        },
    ]
})

print(result["messages"][-1].content)

Why custom tools beat the generic pandas agent:

  1. Controlled operations. The agent can only call functions you defined. No arbitrary code execution.
  2. Domain language. Tool descriptions use your team’s terminology. The LLM maps natural language to the right operation.
  3. Safety. No Python REPL. No allow_dangerous_code. Each tool validates its inputs and returns structured output.
  4. Reproducibility. Every tool call is logged with exact parameters. You can replay any analysis.

Pattern 4: Output Validation and Guardrails

An analysis agent that returns wrong numbers is worse than no agent at all. These guardrails catch errors before they reach your stakeholders.

Guardrail 1: Schema validation on tool inputs.

Use Pydantic to enforce that tool arguments match expected types and ranges:

from pydantic import BaseModel, field_validator


class AggregationRequest(BaseModel):
    filter_column: str
    filter_value: str
    agg_column: str
    agg_function: str

    @field_validator("agg_function")
    @classmethod
    def validate_agg(cls, v: str) -> str:
        allowed = {"mean", "sum", "count", "min", "max", "median"}
        if v not in allowed:
            raise ValueError(f"Must be one of {allowed}, got '{v}'")
        return v

    @field_validator("filter_column", "agg_column")
    @classmethod
    def validate_columns(cls, v: str) -> str:
        if v not in df.columns:
            raise ValueError(
                f"Column '{v}' not in dataset. "
                f"Available: {list(df.columns)}"
            )
        return v

Guardrail 2: Result sanity checks.

Wrap your agent’s output with automatic validation:

def validate_numeric_result(result: dict, column: str) -> dict:
    """Check that a computed result falls within the column's actual range."""
    col_min = float(df[column].min())
    col_max = float(df[column].max())
    value = result.get("result")

    if value is not None and not (col_min <= value <= col_max):
        result["warning"] = (
            f"Result {value} is outside the column range "
            f"[{col_min}, {col_max}]. Verify the calculation."
        )
    return result

Guardrail 3: Row count assertions.

Catch empty results before they produce misleading statistics:

def safe_aggregate(
    filtered_df: pd.DataFrame,
    column: str,
    operation: str,
    min_rows: int = 5,
) -> dict:
    """Aggregate with a minimum sample size requirement."""
    n = len(filtered_df)
    if n == 0:
        return {"error": "Filter returned zero rows. Check filter criteria."}
    if n < min_rows:
        return {
            "warning": f"Only {n} rows matched (minimum {min_rows}). "
            "Results may not be statistically meaningful.",
            "result": getattr(filtered_df[column], operation)(),
            "n": n,
        }
    return {
        "result": getattr(filtered_df[column], operation)(),
        "n": n,
    }

Guardrail 4: Query logging for audit.

Log every tool call so analysts can verify what the agent actually computed:

import logging
from datetime import datetime, timezone

logger = logging.getLogger("analysis_agent")
handler = logging.FileHandler("agent_audit.log")
handler.setFormatter(
    logging.Formatter("%(asctime)s | %(message)s")
)
logger.addHandler(handler)
logger.setLevel(logging.INFO)


def log_tool_call(tool_name: str, params: dict, result: dict):
    logger.info(
        f"TOOL={tool_name} | PARAMS={params} | "
        f"RESULT_KEYS={list(result.keys())} | "
        f"TIMESTAMP={datetime.now(timezone.utc).isoformat()}"
    )

These guardrails are not optional extras. In any workflow where analysis drives decisions — A/B test results, revenue forecasts, user segmentation — a wrong number costs more than a slow answer.

Which Pattern Fits Your Data

Scenario Pattern Why
Quick CSV exploration 1 (Pandas Agent) Five lines to first answer
Multiple related tables, millions of rows 2 (SQL Agent) Indexing, joins, disk-based
Domain-specific analysis (stats, experiments) 3 (Custom Tools) Controlled operations, no REPL
Production pipeline with stakeholders 3 + 4 (Custom + Guardrails) Validated, audited, reproducible

Start with Pattern 1 to prototype. Move to Pattern 2 when data gets large. Move to Pattern 3 when you need control. Add Pattern 4 when wrong answers have consequences.

What to Watch Out For

Code execution risks. Patterns 1 and 2 execute generated code. Run them in Docker containers or sandboxed environments — never on the same machine as production data without isolation.

LLM hallucination in analysis. The agent can write syntactically valid pandas code that answers the wrong question. Always log the generated code (verbose=True) and spot-check against manual queries.

Token costs scale with data context. The pandas agent sends column names, dtypes, and sample rows to the LLM on every call. Wide DataFrames with 100+ columns burn tokens fast. Use Pattern 3’s targeted tools to control exactly what context the LLM sees.

Statistical literacy. The LLM knows how to call scipy.stats.ttest_ind. It does not always know when a t-test is the wrong test for your data distribution. Domain expertise still matters — the agent accelerates the workflow, it does not replace the analyst.

Every analyst spends more time wrangling data than analyzing it. These 4 patterns shift that ratio. The LLM handles the pandas syntax, the SQL joins, and the boilerplate. You handle the questions that matter.

Follow @klement_gunndu for more AI engineering content. We’re building in public.

Building a Lightweight, Zero-Config H.265 Batch Converter with Go and FFmpeg

Introduction
Video storage is a constant struggle. While H.265 (HEVC) offers incredible compression, most conversion tools are either too complex or too bloated. I wanted something simple: Drag, Drop, and Done.

That’s why I built EZ265, a native Windows batch converter designed for speed and simplicity.

The Tech Stack
To keep the application snappy and portable, I chose:

Go: For its excellent concurrency (ideal for job queues) and easy Windows API integration.

lxn/walk: A native Windows GUI toolkit that keeps the binary size small and the UI responsive.

FFmpeg: The industry-standard engine, but with a twist.

Key Technical Challenges

  1. Smart Hardware Acceleration
    I implemented auto-detection for NVIDIA NVENC. The app probes the system’s capabilities at runtime; if a compatible GPU is found, it uses hardware acceleration. If not, it seamlessly falls back to CPU-based x265 encoding.

  2. Native Windows Integration
    To make the workflow truly “EZ,” I integrated the app directly into the Windows Shell. Users can right-click any video file in Explorer to add it to the encoding queue instantly via Registry manipulation.

Features at a Glance
Batch Processing: Queue multiple files with pause/resume support.

Single Instance IPC: Uses TCP IPC to ensure new files are sent to the already running window.

Low Priority Mode: Encodes in the background without lagging your PC.

Bilingual UI: Auto-detects Japanese/English system settings.

Open Source & Support
EZ265 is fully open-source under the MIT License. Check out the code and the build process on GitHub:

👉 ServalC4t/EZ265 on GitHub

If you find this tool useful for your workflow, feel free to support the development!

We Built a LlamaIndex Integration. They Closed the PR. The Code Still Works.

Last week, a maintainer at LlamaIndex closed our pull request. Not because of code quality. Not because of test failures. The reason: “We are pausing contributions that contribute net-new packages.”

This is a story about what happens when open-source frameworks become gatekeepers in the agent ecosystem — and why it matters less than you’d think.

What we built

GPU-Bridge is an inference API — 30 services, 98 models, 8 backends. We built a LlamaIndex integration package that added:

  • Custom embeddings provider (BGE-M3, Qwen3-Embedding, E5-Large via our unified API)
  • Reranker integration (Jina, BGE via single endpoint)
  • Standard LlamaIndex interfaces, full test coverage, docs

The PR (#21014) followed their contribution guidelines. Tests passed. The integration worked.

What happened

Logan (logan-markewich), a core maintainer, closed it with a clear explanation: they’re pausing all net-new package contributions. Not a quality judgment — a policy freeze.

Fair enough. Their repo, their rules.

Why this matters

LlamaIndex has become infrastructure for thousands of agent builders. When they freeze contributions, they’re not just managing their codebase — they’re deciding which services get first-class status in the agent ecosystem.

This is the tension at the heart of open source in AI:

  1. Frameworks become platforms. LlamaIndex started as a library. Now it’s a platform that shapes which tools agents can easily use.

  2. Contribution freezes are invisible moats. The existing integrations (OpenAI, Cohere, Pinecone) are grandfathered in. New providers need to wait. The longer the freeze, the wider the gap.

  3. The code doesn’t care about the PR status. Our integration works. You can install it independently. The PR was about convenience and discoverability, not functionality.

The real question

Should agent frameworks curate their integration ecosystem, or should they be open rails?

There’s a legitimate argument for curation: quality control, maintenance burden, security reviews. LlamaIndex has hundreds of integration packages. Each one is a surface area for bugs, breaking changes, support requests.

There’s also a legitimate argument for openness: the value of an agent framework is proportional to what it can connect to. Every closed PR is a connection that didn’t happen.

What we did instead

We published the integration as a standalone npm package. It works with LlamaIndex without being in their monorepo. We listed on MCP Registry, Smithery, Glama (triple-A security/license/quality rating). We built direct REST endpoints that don’t need any framework at all.

The lesson: don’t build your distribution strategy on a single framework’s merge queue.

For other infrastructure providers

If you’re building compute, storage, or any other service that agents need:

  1. Ship standalone packages first. Framework integrations are a bonus, not a requirement.
  2. Protocol > platform. MCP, x402, A2A — these are open protocols that no single maintainer can freeze.
  3. Direct API access is the floor. If an agent can make an HTTP request, they can use your service. Everything else is convenience.

The agent ecosystem is young enough that today’s framework decisions shape tomorrow’s defaults. Build for the protocols, and the frameworks will follow.

GPU-Bridge provides unified inference across 98 models and 30 services, with native x402 payments for autonomous agents. gpubridge.io

I Audited 214 Claude Code Skills — 73% Were Silently Broken

I ran a single command against my Claude Code skills directory last week. Out of 47 skills I’d written over three months, 31 had structural problems that degraded how often Claude actually triggered them. Two had never fired at all. Their descriptions were so vague that Claude’s skill-matching logic couldn’t determine when to use them.

The fix took 20 minutes once I knew what was wrong. Here’s the full setup.

TL;DR: npx pulser@latest audits your Claude Code skills against Anthropic’s documented principles — frontmatter structure, description specificity, body quality, reference coverage. It scores each skill 0–100, flags exact issues, and generates fix commands. 73% of 214 community skills I tested scored below 60. Free, open-source, MIT-licensed, runs in under 5 seconds.

The Problem: Skills That Silently Fail

Claude Code skills fail silently. A bad SKILL.md doesn’t throw an error — it just never gets invoked. The description field in your frontmatter is what Claude uses at runtime to decide whether to activate a skill. Too vague, and Claude skips it. Every time. No warning.

I spent two weeks wondering why my api-testing skill wasn’t firing during debugging sessions. The description read:

description: Helps with API testing

Five words. Claude had no idea when to use it. The fix was embarrassingly simple:

yaml
description: This skill should be used when the user asks to “test an API endpoint”, “write integration tests for REST APIs”, “debug a failing HTTP request”, or “generate API test fixtures”. Activate when the conversation involves HTTP status codes, request/response payloads, or API authentication flows.

The difference between a working skill and a dead one is often a single frontmatter field. When you have 30, 50, or 100+ skills across plugins, manual auditing doesn’t scale. That’s why I built pulser.

What pulser Actually Checks

pulser reads your SKILL.md files and validates them against 14 weighted criteria drawn directly from Anthropic’s official plugin development documentation. Not guessing at best practices — checking against the published source. Each skill receives a 0–100 score based on frontmatter completeness, description quality, body structure, and reference coverage.

1. Frontmatter Validation

The minimum viable frontmatter needs name and description. But “minimum viable” and “actually works reliably” are different things.

npx pulser@latest ./my-plugin/skills/

Output for a broken skill:

  ✗ api-testing                              22/100
    ├─ WARN  description too short (5 words, need 20+)
    ├─ FAIL  no trigger phrases in description
    ├─ WARN  missing version field
    └─ INFO  no references/ directory found

  ✓ hook-management                          87/100
    ├─ PASS  description contains 4 trigger phrases
    ├─ PASS  frontmatter complete
    └─ INFO  3 reference files detected

**pulser checks 14 frontmatter attributes**, weighted by their measured impact on skill invocation reliability:

| Check | Weight | What It Catches |
|-------|--------|-----------------|
| Description length | 20% | Under 20 words = Claude can't match it |
| Trigger phrases | 25% | No quoted phrases = no reliable activation |
| Name present | 10% | Missing name = skill won't load |
| Description format | 15% | First-person instead of third-person |
| Version field | 5% | Missing = no change tracking |
| Body content length | 15% | Under 200 words = insufficient guidance |
| Reference files | 10% | No examples = Claude guesses patterns |

### 2. Description Quality Analysis

**The most critical check: descriptions must use third-person format and include exact quoted phrases that users would say.** This is in Anthropic's plugin development guidelines. It's also where 68% of community skills fail.

Bad:

yaml
description: A skill for handling database migrations

Good:

description: This skill should be used when the user asks to "create a migration", "run database migrations", "rollback a migration", or "check migration status". Activate for any task involving schema changes, Prisma migrate, or Knex migrations.

pulser counts quoted trigger phrases, checks for third-person voice, and measures description specificity. **A description without trigger phrases scores 0 on the most heavily weighted check — that's 25% of your total score, gone.**

### 3. Body Content Scoring

**The body of `SKILL.md` is the actual instruction set Claude follows when the skill activates.** pulser evaluates four dimensions:

- **Word count**: Under 200 words means Claude is flying blind. Over 3,000 means you probably need to split content into reference files.
- **Code block presence**: Skills without code examples force Claude to improvise patterns from scratch.
- **Section structure**: Headers, lists, and structured content score higher than walls of prose.
- **Actionable instructions**: Lines starting with imperative verbs ("Use", "Create", "Check") score higher than descriptive text.

Body Analysis: api-testing/SKILL.md
  Words: 142 (WARN: below 200 minimum)
  Code blocks: 0 (FAIL: no examples)
  Sections: 1 (WARN: no sub-sections)
  Imperative ratio: 0.12 (WARN: mostly descriptive)
  Score: 18/100

### 4. The eval Subcommand

**`pulser eval` detects whether skills fire correctly in realistic scenarios — without manually testing every prompt combination.** It sends synthetic prompts to your skill set and checks whether Claude activates the right skill. This is what caught my two permanently-dead skills.

bash
npx pulser@latest eval ./skills/ –prompts 10

Evaluating skill activation with 10 synthetic prompts…

“Create a new database migration for adding user roles”
Expected: database-migrations Actual: database-migrations ✓

“Help me debug this flaky test”
Expected: debugging Actual: (none) ✗
→ No skill matched. Check debugging/SKILL.md description.

“Set up a pre-commit hook for linting”
Expected: hook-management Actual: git-workflow ✗
→ Wrong skill activated. Descriptions overlap.

Results: 7/10 correct (70%)
2 skills never activated
1 skill conflict detected

Skill conflicts are the silent killer. Two skills with overlapping descriptions compete, and Claude picks whichever seems closest — which might be wrong. This is how git-workflow eats prompts meant for hook-management.

5. The Prescriber

Once pulser identifies issues, it generates exact fixes:

npx pulser@latest --prescribe ./skills/

Prescriptions for api-testing/SKILL.md:

  1. Replace description with:
     ---
     description: This skill should be used when the user asks to
     "test an API endpoint", "write API integration tests",
     "mock HTTP responses", or "validate API contracts". Activate
     when the task involves REST, GraphQL, HTTP clients, or
     API authentication.
     ---

  2. Add version field:
     version: 1.0.0

  3. Create references/ directory with:
     - references/rest-patterns.md
     - references/auth-flows.md

  4. Add code examples to body (minimum 2 blocks)

The generated descriptions aren't perfect — you'll want to customize the trigger phrases for your actual workflow. **But a prescriber-generated description is a massive upgrade over "Helps with API testing," and it typically pushes a skill past the 70-point threshold where reliable activation begins.**

## What I'd Do Differently

**I should have built eval first.** I started with frontmatter validation because it was measurable and straightforward, but eval catches the problems that actually matter — skills that don't fire when they should. A skill can score 90/100 on frontmatter and still be functionally dead.

**I over-indexed on word count.** Early versions penalized short skills too heavily. Some skills genuinely need to be brief — a 150-word skill that's all actionable instructions beats a 500-word skill that's mostly context. v0.4.0 weighs *instruction density* instead of raw word count.

**The prescriber needs user context.** Right now it generates generic trigger phrases. A future version should analyze actual conversation history to suggest phrases you *actually use* when you want a particular skill.

## The Numbers

### Cost Comparison

| Approach | Cost | Time per Skill | Catches Conflicts |
|----------|------|----------------|-------------------|
| Manual review | $0 | 2–3 minutes | No |
| pulser audit | $0 | ~0.3 seconds | No |
| pulser eval | $0 | ~2 seconds | Yes |
| Paid linter + manual QA | $20+/month | ~1 minute | Sometimes |

### Audit Results Across 214 Community Skills

| Metric | Value |
|--------|-------|
| Skills audited | 214 |
| Average score | 48/100 |
| Skills scoring below 60 | 73% |
| Missing trigger phrases | 68% |
| Description under 20 words | 41% |
| No code examples in body | 55% |
| Missing version field | 62% |
| Skill conflicts detected (eval) | 12 pairs |
| Time to audit all 214 | 47 seconds |

**The #1 failure mode: vague descriptions with no trigger phrases (68% of audited skills).** It's also the highest-impact fix — adding quoted trigger phrases typically raises a skill's score by 20–35 points in a single edit.

## FAQ

### Does pulser modify my files?

**No — pulser is read-only by default.** The `--prescribe` flag generates suggestions but writes nothing. Your skills stay untouched until you decide to apply changes.

### What's the minimum score I should target?

**70 is the reliability threshold.** Below 60, you're gambling on whether Claude picks up the skill. Above 80, you're consistently solid. I've seen skills score 95+ and still have edge cases — don't chase perfection, chase "fires when it should."

### Does this work with the new plugin system?

**Yes — pulser reads any `SKILL.md` file regardless of directory structure.** It works with both the legacy `~/.claude/skills/` layout and proper plugin structures under `.claude-plugin/`. It follows the directory convention from Anthropic's plugin-dev reference: `skills/skill-name/SKILL.md` with optional `references/`, `examples/`, and `scripts/` subdirectories.

### Can I run this in CI?

**Yes — `npx pulser@latest` returns a non-zero exit code when skills fall below a configurable threshold.** I run it as a pre-commit check on every plugin repo.

yaml

.github/workflows/skill-lint.yml

  • name: Audit skills
    run: npx pulser@latest ./skills/ –min-score 65 –exit-code

How is this different from just reading Anthropic’s docs?

It’s the difference between knowing the speed limit and having a speedometer. The docs tell you what good looks like. pulser tells you where your skills fall short right now — with scores, flagged lines, and fix suggestions. I read Anthropic’s docs three times before building this and still shipped 31 broken skills out of 47.

Try It

30 seconds to your first audit:

npx pulser@latest ./path/to/skills/

Then dig deeper:

bash

Check for skill conflicts

npx pulser@latest eval ./skills/ –prompts 20

Generate fixes for anything below 70

npx pulser@latest –prescribe –min-score 70 ./skills/

Add to CI to prevent regressions

npx pulser@latest ./skills/ –min-score 65 –format json –exit-code

Most skills jump 20–30 points just from fixing the description field. Re-run after fixes to see the difference.

What’s the worst score you’ve found in your own setup? I had a skill with a 4-word description and zero code examples — it scored 8/100. Drop your worst score in the comments.

If this saved you debugging time, run npx pulser@latest before your next skill lands in production. Your future self will thank you.

I write about AI tooling, Claude Code workflows, and the unglamorous parts of making LLMs actually work. Follow me here — next post covers how to structure skill references so Claude stops hallucinating file paths.

pulser is free, open-source, and MIT-licensed. Contributions and bug reports welcome on GitHub.