Clone Hermes Agent’s Architecture for Your Own AI Assistant

Your AI assistant forgets the conversation context after three exchanges. The tool calling fails when you chain multiple operations. The memory system breaks when handling complex workflows that span multiple sessions.

You’re cobbling together OpenAI function calls with custom prompt engineering while fighting race conditions in multi-step processes. The assistant that worked for simple Q&A completely falls apart when you need it to research, analyze, and execute a series of dependent tasks.

Meanwhile, Nous Research’s Hermes Agent handles complex workflows flawlessly. Multi-turn conversations maintain perfect context. Tool execution chains together seamlessly. The architecture scales from simple queries to sophisticated automation.

The Idea (60 Seconds)

You’ll reverse-engineer Hermes Agent’s core design patterns to build a production-grade AI assistant framework. The implementation uses a modular plugin system, persistent memory management, and standardized tool interfaces that handle complex workflows reliably. Setup takes 2 hours. The result gives you an assistant architecture that scales from basic chat to autonomous task execution.

Why This Architecture, Beyond Simple Function Calling

Memory persistence solves context degradation. Standard chat implementations lose context as conversations grow. Hermes uses structured memory that maintains conversation state, user preferences, and task history across sessions. Your assistant remembers what you discussed yesterday and builds on previous work.

Plugin modularity enables unlimited expansion. Function calling requires hardcoded tool definitions. The Hermes pattern uses a plugin interface where tools register themselves dynamically. Add new capabilities by dropping Python files into a plugins directory. Zero core code changes.

Execution planning prevents tool chaos. Naive implementations call tools randomly based on user input. Hermes creates execution plans that sequence tool calls logically, handle dependencies, and recover from failures. The difference between “search for Python tutorials” and “search for Python tutorials, summarize the top 3, create a learning plan, and schedule practice sessions.”

ArchonHQ is a reader-supported publication. To receive new posts and support my work, consider becoming a free or paid subscriber.

Walkthrough

1. Core Agent Framework

Create the base agent class that handles conversation flow and tool coordination:

# agent.py
import json
import asyncio
from typing import Dict, List, Any, Optional
from dataclasses import dataclass
from datetime import datetime

@dataclass
class Message:
    role: str
    content: str
    timestamp: datetime
    metadata: Dict[str, Any] = None

class HermesAgent:
    def __init__(self, model_client, memory_store, plugin_manager):
        self.model = model_client
        self.memory = memory_store
        self.plugins = plugin_manager
        self.conversation_id = None

    async def process_message(self, user_input: str) -> str:
        # Load conversation context
        context = await self.memory.get_context(self.conversation_id)

        # Create execution plan
        plan = await self.create_execution_plan(user_input, context)

        # Execute plan steps
        results = []
        for step in plan.steps:
            result = await self.execute_step(step)
            results.append(result)

        # Generate response
        response = await self.synthesize_response(results, user_input)

        # Store conversation state
        await self.memory.store_exchange(
            self.conversation_id, user_input, response, results
        )

        return response

2. Memory Management System

Implement persistent memory that maintains context across sessions:

# memory.py
import sqlite3
import json
from typing import Dict, List, Optional

class MemoryStore:
    def __init__(self, db_path: str):
        self.db_path = db_path
        self.init_database()

    def init_database(self):
        conn = sqlite3.connect(self.db_path)
        conn.execute('''
            CREATE TABLE IF NOT EXISTS conversations (
                id TEXT PRIMARY KEY,
                created_at TIMESTAMP,
                last_active TIMESTAMP,
                context_summary TEXT
            )
        ''')
        conn.execute('''
            CREATE TABLE IF NOT EXISTS messages (
                id INTEGER PRIMARY KEY,
                conversation_id TEXT,
                role TEXT,
                content TEXT,
                timestamp TIMESTAMP,
                metadata TEXT,
                FOREIGN KEY (conversation_id) REFERENCES conversations (id)
            )
        ''')
        conn.commit()
        conn.close()

    async def get_context(self, conversation_id: str) -> Dict:
        conn = sqlite3.connect(self.db_path)

        # Get recent messages
        messages = conn.execute('''
            SELECT role, content, timestamp, metadata 
            FROM messages 
            WHERE conversation_id = ? 
            ORDER BY timestamp DESC 
            LIMIT 20
        ''', (conversation_id,)).fetchall()

        # Get conversation summary
        summary = conn.execute('''
            SELECT context_summary 
            FROM conversations 
            WHERE id = ?
        ''', (conversation_id,)).fetchone()

        conn.close()

        return {
            'messages': [
                {
                    'role': msg[0], 
                    'content': msg[1], 
                    'timestamp': msg[2],
                    'metadata': json.loads(msg[3] or '{}')
                } 
                for msg in reversed(messages)
            ],
            'summary': summary[0] if summary else None
        }

3. Plugin System Architecture

Build the modular tool interface that enables dynamic capability expansion:

# plugins.py
import importlib
import os
from abc import ABC, abstractmethod
from typing import Dict, Any, List

class Plugin(ABC):
    @property
    @abstractmethod
    def name(self) -> str:
        pass

    @property
    @abstractmethod
    def description(self) -> str:
        pass

    @abstractmethod
    async def execute(self, parameters: Dict[str, Any]) -> Any:
        pass

    @abstractmethod
    def get_schema(self) -> Dict:
        pass

class PluginManager:
    def __init__(self, plugins_dir: str):
        self.plugins_dir = plugins_dir
        self.plugins: Dict[str, Plugin] = {}
        self.load_plugins()

    def load_plugins(self):
        for filename in os.listdir(self.plugins_dir):
            if filename.endswith('.py') and filename != '__init__.py':
                module_name = filename[:-3]
                spec = importlib.util.spec_from_file_location(
                    module_name, 
                    os.path.join(self.plugins_dir, filename)
                )
                module = importlib.util.module_from_spec(spec)
                spec.loader.exec_module(module)

                # Find Plugin subclasses
                for attr_name in dir(module):
                    attr = getattr(module, attr_name)
                    if (isinstance(attr, type) and 
                        issubclass(attr, Plugin) and 
                        attr != Plugin):
                        plugin_instance = attr()
                        self.plugins[plugin_instance.name] = plugin_instance

    def get_available_tools(self) -> List[Dict]:
        return [
            {
                'name': plugin.name,
                'description': plugin.description,
                'schema': plugin.get_schema()
            }
            for plugin in self.plugins.values()
        ]

4. Example Plugin Implementation

Create a web search plugin that follows the standard interface:

# plugins/web_search.py
import aiohttp
import json
from plugins import Plugin

class WebSearchPlugin(Plugin):
    @property
    def name(self) -> str:
        return "web_search"

    @property
    def description(self) -> str:
        return "Search the web for current information"

    async def execute(self, parameters):
        query = parameters.get('query')
        max_results = parameters.get('max_results', 5)

        # Use your preferred search API
        async with aiohttp.ClientSession() as session:
            url = f"https://api.search.brave.com/res/v1/web/search"
            headers = {"X-Subscription-Token": "your_api_key"}
            params = {"q": query, "count": max_results}

            async with session.get(url, headers=headers, params=params) as response:
                data = await response.json()

        results = []
        for item in data.get('web', {}).get('results', []):
            results.append({
                'title': item.get('title'),
                'url': item.get('url'),
                'description': item.get('description')
            })

        return {'results': results, 'query': query}

    def get_schema(self):
        return {
            'type': 'object',
            'properties': {
                'query': {'type': 'string', 'description': 'Search query'},
                'max_results': {'type': 'integer', 'description': 'Maximum results to return'}
            },
            'required': ['query']
        }

5. Execution Planning

Implement the planning system that sequences tool calls intelligently:

# planner.py
from typing import List, Dict
from dataclasses import dataclass

@dataclass
class ExecutionStep:
    tool_name: str
    parameters: Dict
    depends_on: List[str] = None
    step_id: str = None

class ExecutionPlanner:
    def __init__(self, model_client, plugin_manager):
        self.model = model_client
        self.plugins = plugin_manager

    async def create_plan(self, user_input: str, context: Dict) -> List[ExecutionStep]:
        available_tools = self.plugins.get_available_tools()

        planning_prompt = f"""
        User request: {user_input}
        Available tools: {json.dumps(available_tools, indent=2)}

        Create a step-by-step execution plan. Each step should use one tool.
        Consider dependencies between steps.

        Respond with a JSON array of steps:
        [
            {{
                "step_id": "step_1",
                "tool_name": "web_search",
                "parameters": {{"query": "Python tutorials"}},
                "depends_on": []
            }}
        ]
        """

        response = await self.model.complete(planning_prompt)
        steps_data = json.loads(response)

        return [ExecutionStep(**step) for step in steps_data]

Caveats

Model quality determines planning effectiveness. The execution planner relies on the language model understanding tool capabilities and sequencing logic. Weaker models create inefficient plans or miss dependencies. GLM-5.1 level capability becomes essential for complex workflows.

Memory storage grows indefinitely. The SQLite implementation accumulates conversation history permanently. Add cleanup routines for conversations older than 30 days or implement conversation archiving to prevent database bloat.

Plugin isolation remains minimal. Plugins execute in the same Python process with full system access. Malicious or buggy plugins can crash the entire agent. Consider sandboxing for production deployments handling untrusted plugins.

Philosophy

Building your own agent architecture creates compound advantages over time. Each plugin you add increases the system’s capabilities exponentially. The memory system learns your preferences and work patterns. The execution planner gets better at sequencing tasks for your specific use cases.

The Hermes architecture pattern scales from personal assistant to team automation platform. Start with web search and file operations. Add calendar integration, code analysis, and deployment tools. The modular design grows with your needs while maintaining reliability.

You own the entire stack. Zero vendor dependencies. Zero API rate limits. Zero feature deprecation risk.

Build Yours

Start with the core agent framework and memory system. Build one plugin. Test the execution planning with simple two-step workflows. The architecture becomes clear once you see it running.

What’s the first capability you’ll add to your agent? Drop your plugin ideas in the comments.

Subscribe now

This article was originally published on ArchonHQ — practical AI that wins every day. Subscribe free to get new articles in your inbox.
VPC Peering: El puente de red para que recursos aislados se comuniquen

¡Bienvenidos todos a un nuevo workshop sobre redes! El día de hoy vamos a trabajar con VPC Peering: aprenderemos qué es, cuándo podemos usarlo, cuáles son sus beneficios e inclusive cuándo es mejor evitarlo. Pero no nos quedaremos solo en la teoría; implementaremos esta solución conectando dos redes totalmente aisladas y realizaremos pruebas para mover tráfico real entre los recursos desplegados en cada VPC.

¿Qué es un VPC Peering?

Un VPC Peering (o interconexión de VPC) es una conexión de red entre dos VPC que permite el enrutamiento de tráfico entre ellas utilizando direcciones IPv4 o IPv6 privadas. Los recursos desplegados en estas redes pueden comunicarse entre sí como si estuvieran dentro de la misma red local. Lo mejor de todo es que permite conectar VPC que están en la misma región, en regiones distintas e, inclusive, pertenecientes a cuentas de AWS diferentes.

Alcance del workshop

Nos enfocaremos en cómo establecer la interconexión y las reglas de seguridad necesarias para mover el tráfico de una VPC a otra de manera segura, aplicando el principio de mínimo privilegio.

Como en guías anteriores ya aprendimos los conceptos fundamentales de VPC y sus componentes, no repetiremos ese trabajo de forma manual. Para centrar nuestra atención únicamente en la interconexión, las rutas y la seguridad, he preparado una plantilla de CloudFormation en formato YAML. Con ella desplegaremos automáticamente las VPC que vamos a interconectar y los recursos que intercambiarán tráfico una vez establecido el peering.

Plantilla cloudformation para desplegar recursos

AWSTemplateFormatVersion: '2010-09-09'
Description: 'Infraestructura base para Workshop de VPC Peering y EIC Endpoint - Entorno Privado'

Parameters:
  LatestAmiId:
    Type: 'AWS::SSM::Parameter::Value<AWS::EC2::Image::Id>'
    Default: '/aws/service/ami-amazon-linux-latest/al2023-ami-kernel-6.1-x86_64'
    Description: "AMI mas reciente de Amazon Linux 2023"

  InstanceType:
    Type: String
    Default: t3.micro
    Description: "Tipo de instancia para el laboratorio"

Resources:
  # --- INFRAESTRUCTURA VPC 01 ---
  VPC01:
    Type: AWS::EC2::VPC
    Properties:
      CidrBlock: 10.0.0.0/24
      EnableDnsSupport: true
      EnableDnsHostnames: true
      Tags:
        - Key: Name
          Value: vpc-01-workshop

  Subnet01:
    Type: AWS::EC2::Subnet
    Properties:
      VpcId:
        Ref: VPC01
      CidrBlock: 10.0.0.0/25
      AvailabilityZone: !Select [ 0, !GetAZs "" ]
      Tags:
        - Key: Name
          Value: subnet-01-privada

  RouteTable01:
    Type: AWS::EC2::RouteTable
    Properties:
      VpcId:
        Ref: VPC01
      Tags:
        - Key: Name
          Value: rt-01-privada

  SubnetRouteTableAssociation01:
    Type: AWS::EC2::SubnetRouteTableAssociation
    Properties:
      SubnetId:
        Ref: Subnet01
      RouteTableId:
        Ref: RouteTable01

  # --- SEGURIDAD VPC 01 ---
  SGEIC01:
    Type: AWS::EC2::SecurityGroup
    Properties:
      GroupDescription: "Security Group para EIC Endpoint 01"
      VpcId:
        Ref: VPC01
      Tags:
        - Key: Name
          Value: sg-eic-01

  SGInstance01:
    Type: AWS::EC2::SecurityGroup
    Properties:
      GroupDescription: "Security Group para Instancia 01"
      VpcId:
        Ref: VPC01
      SecurityGroupIngress:
        - IpProtocol: tcp
          FromPort: 22
          ToPort: 22
          SourceSecurityGroupId:
            Ref: SGEIC01
      Tags:
        - Key: Name
          Value: sg-instance-01

  # Regla de salida para que el EIC llegue a la instancia
  EIC01Egress:
    Type: AWS::EC2::SecurityGroupEgress
    Properties:
      GroupId:
        Ref: SGEIC01
      IpProtocol: tcp
      FromPort: 22
      ToPort: 22
      DestinationSecurityGroupId:
        Ref: SGInstance01

  # --- RECURSOS VPC 01 ---
  EICEndpoint01:
    Type: AWS::EC2::InstanceConnectEndpoint
    Properties:
      SubnetId:
        Ref: Subnet01
      SecurityGroupIds:
        - Ref: SGEIC01
      Tags:
        - Key: Name
          Value: eic-endpoint-01

  Instance01:
    Type: AWS::EC2::Instance
    Properties:
      InstanceType:
        Ref: InstanceType
      ImageId:
        Ref: LatestAmiId
      SubnetId:
        Ref: Subnet01
      SecurityGroupIds:
        - Ref: SGInstance01
      Tags:
        - Key: Name
          Value: instancia-01-requester

  # --- INFRAESTRUCTURA VPC 02 ---
  VPC02:
    Type: AWS::EC2::VPC
    Properties:
      CidrBlock: 11.0.0.0/24
      EnableDnsSupport: true
      EnableDnsHostnames: true
      Tags:
        - Key: Name
          Value: vpc-02-workshop

  Subnet02:
    Type: AWS::EC2::Subnet
    Properties:
      VpcId:
        Ref: VPC02
      CidrBlock: 11.0.0.0/25
      AvailabilityZone: !Select [ 0, !GetAZs "" ]
      Tags:
        - Key: Name
          Value: subnet-02-privada

  RouteTable02:
    Type: AWS::EC2::RouteTable
    Properties:
      VpcId:
        Ref: VPC02
      Tags:
        - Key: Name
          Value: rt-02-privada

  SubnetRouteTableAssociation02:
    Type: AWS::EC2::SubnetRouteTableAssociation
    Properties:
      SubnetId:
        Ref: Subnet02
      RouteTableId:
        Ref: RouteTable02

  # --- SEGURIDAD VPC 02 ---
  SGEIC02:
    Type: AWS::EC2::SecurityGroup
    Properties:
      GroupDescription: "Security Group para EIC Endpoint 02"
      VpcId:
        Ref: VPC02
      Tags:
        - Key: Name
          Value: sg-eic-02

  EIC02Egress:
    Type: AWS::EC2::SecurityGroupEgress
    Properties:
      GroupId:
        Ref: SGEIC02
      IpProtocol: tcp
      FromPort: 22
      ToPort: 22
      DestinationSecurityGroupId:
        Ref: SGInstance02

  SGInstance02:
    Type: AWS::EC2::SecurityGroup
    Properties:
      GroupDescription: "Security Group para Instancia 02"
      VpcId:
        Ref: VPC02
      SecurityGroupIngress:
        - IpProtocol: tcp
          FromPort: 22
          ToPort: 22
          SourceSecurityGroupId:
            Ref: SGEIC02
      Tags:
        - Key: Name
          Value: sg-instance-02


  # --- RECURSOS VPC 02 ---
  EICEndpoint02:
    Type: AWS::EC2::InstanceConnectEndpoint
    Properties:
      SubnetId:
        Ref: Subnet02
      SecurityGroupIds:
        - Ref: SGEIC02
      Tags:
        - Key: Name
          Value: eic-endpoint-02

  Instance02:
    Type: AWS::EC2::Instance
    Properties:
      InstanceType:
        Ref: InstanceType
      ImageId:
        Ref: LatestAmiId
      SubnetId:
        Ref: Subnet02
      SecurityGroupIds:
        - Ref: SGInstance02
      Tags:
        - Key: Name
          Value: instancia-02-accepter

Outputs:
  Instancia01ID:
    Description: "ID de la Instancia 01"
    Value:
      Ref: Instance01
  Instancia02ID:
    Description: "ID de la Instancia 02"
    Value:
      Ref: Instance02

Que despliega exactamente esta plantilla?

Para garantizar un entorno seguro y portátil, el código automatiza la infraestructura base bajo un modelo 100% privado:

2 VPC aisladas: vpc-01-workshop (10.0.0.0/24) y vpc-02-workshop (11.0.0.0/24), configuradas sin salida a internet (sin Internet Gateways ni NAT Gateways).

2 Subredes privadas: subnet-01-privada y subnet-02-privada, segmentadas con máscaras /25 en la primera zona de disponibilidad de la región.

2 Tablas de rutas base: rt-01-privada y rt-02-privada asociadas a sus respectivas subredes, listas para recibir las rutas del peering manualmente.

2 EC2 Instance Connect (EIC) Endpoints: eic-endpoint-01 y eic-endpoint-02. Estos componentes actúan como el puente seguro para conectarnos por SSH desde nuestra terminal sin usar IPs públicas ni llaves .pem.

2 Instancias EC2: instancia-01-requester e instancia-02-accepter con Amazon Linux 2023, ubicadas en el corazón de sus redes privadas.

4 Grupos de Seguridad (Security Groups): Dos para los endpoints (con reglas de salida en el puerto 22) y dos para las instancias, configurados bajo el principio de mínimo privilegio para aceptar conexiones SSH únicamente si provienen de su respectivo EIC Endpoint.

Paso 1: Despliegue de la infraestructura base

Guarda la plantilla anterior en un archivo .yaml y abre CloudFormation en la consola de AWS. Aunque el código funciona en cualquier región, te recomiendo usar N. Virginia (us-east-1) para que tu pantalla coincida exactamente con las imágenes de referencia que verás en cada paso.

Crea el Stack siguiendo estos pasos rápidos:

Haz clic en Create stack (With new resources).

Selecciona Choose an existing template -> Upload a template file y sube tu archivo .yaml.

Asigna un nombre a tu Stack y avanza presionando Next (deja el resto de opciones por defecto).

Haz clic en Submit.

El aprovisionamiento tomará un par de minutos. Una vez que el estado cambie a CREATE_COMPLETE, la automatización habrá terminado y estaremos listos para iniciar la configuración manual de nuestro VPC Peering.

Paso 2: Comprobar el aislamiento (El fallo esperado)

Con nuestro Stack desplegado, el primer paso será conectarnos a nuestra instancia-01-requester ubicada (en la vpc-01-workshop). Lo haremos a través del EIC Endpoint (EC2 Instance Connect) que automatizamos con la plantilla. Esto representa una excelente práctica de seguridad: eliminamos por completo la gestión de llaves de acceso .pem y añadimos una capa de protección adicional, si nunca has manejado los EIC te dejo el enlace al workshop anterior donde explicamos todos los endpoint incluyendo los EIC y ademas usamos cada uno de ellos en un ejemplo: Workshop VPC Endpoints.

  • Dirígete al servicio de EC2, selecciona la instancia instancia-01-requester y haz clic en el botón Connect.

En la próxima pantalla notarás algunos mensajes de advertencia como: «No public IPv4 or IPv6 address assigned» e «Instance is not in a public subnet». ¡No te preocupes! Lejos de ser un error, esto es una excelente señal: nos confirma que nuestras subredes y recursos están completamente aislados del mundo exterior.

  • En la pestaña de EC2 Instance Connect, cambia el tipo de conexión a Connect using EC2 Instance Connect Endpoint.
  • Verás que el sistema seleccionará automáticamente nuestro eic-endpoint-01 en la lista desplegable.
  • TPara finalizar, haz clic en el botón Connect.

Una vez dentro de la terminal de la instancia-01-requester, ejecutaremos un comando para intentar comunicarnos con la instancia-02-accepter. (Ve a la consola de EC2 y copia la dirección IP privada de esa segunda instancia, la vas a necesitar).

ping -c 4 <IP_PRIVADA_DE_INSTANCIA_02>

Nota rápida: El comando ping se utiliza para verificar la conectividad básica entre dos recursos. La bandera -c 4 (count) le indica al sistema que envíe exactamente 4 paquetes de prueba hacia la IP de destino.

Ejecuta el comando y observa el resultado:

El diagnóstico es claro: 4 paquetes transmitidos, 0 paquetes recibidos (100% packet loss). El comando se queda congelado y expira.

¿Por qué pasa esto? Porque ambas VPC están en un aislamiento absoluto. En términos de redes, el router de nuestra vpc-01-workshop recibe el paquete con destino a la red 11.0.0.x, revisa su tabla de rutas local y, al no encontrar ninguna instrucción que le diga cómo llegar allá, simplemente descarta el paquete. Para él, esa dirección IP no existe.

Ahora si viene lo bueno…

Paso 3: Creacion de un VPC Peering

A continuación, vamos a construir el puente entre ambas redes para que nuestros servidores dejen de estar aislados.

  • Dirígete al servicio de VPC en la consola de AWS.

  • En la columna izquierda, busca y selecciona Peering connections.

  • Haz clic en el botón Create peering connection.

  • Colocale un nombre, yo usare: pc-vpc1-to-vpc2

  • VPC ID (Requester): Selecciona vpc-01-workshop. Esta será la red encargada de iniciar la solicitud de interconexión.

  • Para este laboratorio, deja seleccionadas las opciones por defecto: My account (Mi cuenta) y This region (Esta región).

  • En el campo VPC ID (Accepter), selecciona vpc-02-workshop.

  • Finaliza haciendo clic en Create peering connection en la parte inferior.

Nota de Arquitecto: En este ejercicio ambas VPC conviven en la misma cuenta y región, pero ten en cuenta que el proceso es idéntico si decidieras interconectar redes en zonas geográficas o estructuras corporativas distintas; en ese caso, simplemente elegirías las opciones Another account o Another region según corresponda.

Ya creamos nuestro peering, pero ¡ATENCIÓN! Falta un paso crucial. Recuerda que al configurar esta conexión establecimos un solicitante (Requester) y un aceptador (Accepter). Esto significa que la solicitud está flotando en el aire y la vpc-02-workshop debe aceptarla formalmente para que el estado pase de Pending acceptance a Active.

En la misma pantalla donde acabas de crear el peering (justo debajo del banner verde de éxito): haz clic en el menú desplegable Actions (en la esquina superior derecha), elige la opción Accept request y confirma.

Nota de Arquitecto: Estamos aceptando la solicitud nosotros mismos porque ambas VPC están en nuestra cuenta de AWS. Si la VPC de destino perteneciera a otra cuenta corporativa o a un cliente externo, el administrador de esa cuenta tendría que iniciar sesión en su propia consola para aceptar tu conexión.

Paso 4: Configuración de Tablas de Rutas (El Mapa de Red)

Ya tenemos nuestro puente construido y activo (VPC Peering), pero si intentas hacer ping nuevamente, notarás que sigue fallando. ¿Por qué? Porque aunque el enlace lógico ya existe, los routers de nuestras VPC todavía no saben que deben usarlo. Nos falta configurar las instrucciones de navegación: las Tablas de Rutas.

Comenzaremos configurando el camino de ida. Vamos a dirigirnos al servicio VPC, tabla de rutas y seleccionamos la asociada a nuestra subred origen (rt-01-privada) para especificarle que cuando un recurso intente comunicarse con el bloque CIDR 11.0.0.0/24 (la red de la VPC-02), redirija ese tráfico utilizando nuestra Peering Connection (pc-vpc1-to-vpc2).

  • Selecciona la tabla de rutas rt-01-privada y dirígete a la pestaña Routes en la parte inferior.

Nota de observación: Verás que de momento solo existe una ruta con el destino (Target) configurado como local. Esta regla por defecto le indica a la VPC que cualquier tráfico dirigido al bloque CIDR 10.0.0.0/24 debe quedarse dentro de su propia red local.

  • Haz clic en el botón Edit routes (esquina superior derecha de la pestaña).

  • En el editor de rutas, haz clic en Add route y configura los siguientes campos:

  1. – Destination: Coloca el bloque CIDR completo de la VPC-02 (11.0.0.0/24). Con esto le indicas al router el “rango de red de destino”. Le estás diciendo: «Cualquier paquete que intente ir a cualquier recurso dentro de la VPC-02, debe aplicar esta regla». (Ojo: no colocamos la IP de la instancia individual, sino el rango de toda la red vecina).
  • Target: Selecciona Peering Connection en la lista desplegable. Al hacer clic en el cuadro de búsqueda vacío, el sistema te mostrará automáticamente el ID de nuestro peering pc-vpc1-to-vpc2

  • Por último, haz clic en Save changes (Guardar cambios) para fijar el mapa de ida.

El “muro” del laboratorio

Ok, tenemos el peering activo y nuestra ruta definida. Si volvemos a la terminal e intentamos ejecutar el comando nuevamente:

ping -c 4 IP_PRIVADA_DE_INSTANCIA_02

¿Qué sucede? Sí, nos topamos exactamente con el mismo mensaje: 4 packets transmitted, 0 received, 100% packet loss, time 3153ms.

Este es el típico escenario de redes que suele frustrar a la mayoría y hacerlos dudar de su configuración. ¡Pero hoy no será nuestro caso! Si nuestra conexión de peering está OK y la tabla de rutas de origen está OK, ¿qué otro elemento nos está bloqueando? Debemos revisar al guardián que protege directamente al recurso: el Security Group de la instancia-02-accepter.

  • Selecciona la pestaña Inbound rules (Reglas de entrada). Notarás que este grupo de seguridad fue creado por nuestra plantilla de CloudFormation con una única regla: permitir tráfico SSH en el puerto 22 exclusivamente desde el EIC Endpoint. Por eso podemos conectarnos sin problemas, pero cualquier otro tipo de acceso está denegado por defecto.

Para que nuestra instancia de destino acepte y responda a las solicitudes de eco (Echo Requests) que le envía el comando ping, necesitamos habilitar el protocolo ICMP (Internet Control Message Protocol). A diferencia de los servicios web comunes, este tráfico no utiliza puertos TCP o UDP, sino que opera directamente a nivel de red para enviar mensajes de diagnóstico. Como los Security Groups bloquean todo el tráfico entrante por defecto, debemos añadir una regla explícita para permitirlo. ¡Vamos a hacerlo!.

  • Haz clic en Edit inbound rules y luego en el botón Add rule.

  • Configura los siguientes campos en la nueva fila:

  • Type: Selecciona All ICMP – IPv4.

  • Source: Déjalo en Custom y en el cuadro de texto ingresa el bloque CIDR de la VPC-01 (10.0.0.0/24).

  • Haz clic en Save rules.

  • Source Custom: Agregamos el CIDR de la vpc-01 que es donde habita la instancia instancia-01-requester desde donde estamos ejecutado el comando ping y queremos que pueda comunicarse y ademas recibir respuesta de la instancia instancia-02-accepter a la que protege este grupo de seguridad.

¿Qué acabamos de hacer? Le indicamos al grupo de seguridad de la instancia-02-accepter que permita la entrada de paquetes de diagnóstico (ping), siempre y cuando provengan de algún recurso ubicado dentro de la red de la VPC-01.

El segundo ping

Con el grupo de seguridad con las reglas correctas, estamos listos para volver a ejecutar nuestro comando en la terminal:

ping -c 4 IP_PRIVADA_DE_INSTANCIA_02

Y el resultado es… ¡otra vez lo mismo!: 4 packets transmitted, 0 received, 100% packet loss, time 3100ms.

Te debes estar preguntando: «A ver, el peering está activo, la ruta de ida está lista y el Security Group ya permite el ping… ¿Qué rayos sucede? Javier, ¿acaso quieres estresarme?»

La realidad es que no, pero en la arquitectura de redes la mejor manera de aprender es fallando, entendiendo el porqué de las cosas y corrigiendo. Lo que estamos experimentando aquí es un concepto vital: el enrutamiento en AWS no es bidireccional por defecto.

Para que un ping sea exitoso, el paquete necesita un camino de ida y un camino de vuelta. Analicemos qué está pasando en este instante tras bambalinas:

  • El viaje de ida: El paquete sale de la instancia-01, el router de la VPC-01 ve la ruta hacia el peering, el puente cruza con éxito, llega a la VPC-02, el Security Group valida que es un paquete ICMP permitido y se lo entrega a la instancia-02. ¡La ida funciona perfecto!

  • El viaje de vuelta: La instancia-02 recibe el paquete y, como es educada, genera una respuesta (Echo Reply) con destino a la IP de la VPC-01.

  • El problema: Cuando este paquete de regreso llega al router de la VPC-02, este revisa su propia tabla de rutas. Como no hemos tocado la tabla de rutas de la VPC-02, el router solo ve su regla local (11.0.0.0/24). Al no tener una instrucción explícita que le diga cómo regresar a la red 10.0.0.0/24, el router no sabe qué hacer y tira la respuesta a la basura.

En resumen: la instancia-02 sí recibe el mensaje, pero sus respuestas se quedan atrapadas en su propia red. La instancia-01 se queda esperando eternamente un eco que jamás va a volver.

Configurando el camino de regreso

¿Qué debemos hacer entonces para solucionar el problema del paquete atrapado? Exacto: ir a la tabla de rutas rt-02-privada (asociada a la VPC-02) y repetir el mismo procedimiento que hicimos al principio. Esta vez, agregaremos una regla que especifique que todo el tráfico dirigido a la red de la VPC-01 (10.0.0.0/24) debe salir a través de nuestra Peering Connection.

Guarda los cambios y, ahora sí, regresemos a la terminal de nuestra primera instancia para lanzar el comando de nuevo:

ping -c 4 IP_PRIVADA_DE_INSTANCIA_02

¡Victoria! Respuesta totalmente satisfactoria: 4 packets transmitted, 4 received, 0% packet loss, time 3126ms. Oficialmente, este es el momento de poner a sonar de fondo We Are the Champions de Queen. ¡Ja, ja!

Probando la bidireccionalidad

Al configurar las rutas en ambos sentidos, el puente de red ha quedado completamente establecido de forma bidireccional, sin importar qué recurso inicie la comunicación. Esto significa que si nos conectamos a la instancia-02-accepter en la VPC-02, podríamos hacerle un ping de vuelta a la instancia-01-requester en la VPC-01.

Eso sí… espero que te hayas acordado del detalle vital que acabamos de aprender con los grupos de seguridad (firewall). Para que la instancia-01 pueda procesar esa solicitud, su propio Security Group debe permitirlo.

Dirígete al grupo de seguridad sg-instance-01 (el que protege a la instancia en la VPC-01) y añade la regla correspondiente en las Inbound rules:

  • Type: All ICMP – IPv4

  • Source: El CIDR de la VPC-02 (11.0.0.0/24)

Ahora, conéctate a la instancia de la VPC-02 (usando su pestaña de EC2 Instance Connect como hicimos en el Paso 1) y ejecuta el ping apuntando al origen:

ping -c 4 IP_PRIVADA_DE_INSTANCIA_01

¡Resultados impecables! 4 packets transmitted, 4 received, 0% packet loss, time 3114ms.

¡Lo hemos logrado! Conseguimos establecer una comunicación fluida, privada y segura entre recursos que habitan en redes totalmente aisladas gracias a VPC Peering y a una correcta gestión de enrutamiento y seguridad.

Cuándo usar (y cuándo evitar) un VPC Peering?

El VPC Peering es la herramienta ideal cuando necesitas una conexión directa, UNO a UNO, entre dos redes. Sin embargo, hay una regla de oro a nivel de infraestructura que es imprescindible recordar: las conexiones de Peering NO son transitivas.

¿Qué significa esto en la práctica? Imagina el siguiente escenario:

Tienes un Peering que conecta la VPC-A con la VPC-B.

Tienes otro Peering que conecta la VPC-B con la VPC-C.

Es muy común que los principiantes supongan que, como la VPC-B está en el medio, la red A podría comunicarse con la C utilizándola como puente. Pero en AWS esto no es posible. Debido a que el ruteo no es transitivo, para que la VPC-A y la VPC-C se puedan hablar, tendrías que crear obligatoriamente un tercer Peering directo entre ellas.

El problema de la escala:

Por esta misma naturaleza, el VPC Peering se recomienda únicamente cuando manejas un número pequeño de redes. Si tu infraestructura crece y necesitas interconectar 10, 20 o 50 VPCs entre sí, configurar conexiones “uno a uno” creará una telaraña inmanejable de enlaces y tablas de rutas, convirtiéndose en una pesadilla de administración.

Nota de Arquitecto: Cuando te enfrentes a un escenario donde necesitas interconectar muchas redes a gran escala, la solución ya no es el VPC Peering; en ese caso, debes dar el salto a un servicio de enrutamiento centralizado como AWS Transit Gateway que aprovecho para haceres spoiler, sera nuestro proximo workshop.

Paso Final: Eliminación de recursos (¡No olvides este paso!)

Después de que interactúes y pruebes todo lo que acabamos de construir, es fundamental eliminar los recursos para evitar costos innecesarios en tu cuenta de AWS. Sigue este orden específico para garantizar una limpieza exitosa:

  • VPC Peering: Dirígete al servicio de VPC, selecciona Peering connections en la columna izquierda, busca el peering que creamos (pcx-vpc01-to-vpc02), selecciónalo y haz clic en Delete.

  • CloudFormation Stack: Una vez borrado el peering, ve al servicio de CloudFormation, selecciona el Stack que desplegamos al inicio y haz clic en Delete. AWS se encargará de borrar las instancias, VPCs, tablas de rutas y Security Groups automáticamente.

¡Con esto habremos terminado! Espero sinceramente que hayas aprendido algo nuevo el día de hoy sobre enrutamiento y seguridad en nubes privadas virtuales.

Si tienes alguna opinión, feedback o duda, no olvides dejarla en la sección de comentarios. Además, te invito a compartir este contenido técnico; ¡podría ser de gran ayuda para otras personas en su camino de aprendizaje!

Nos vemos en el próximo workshop, donde abordaremos el siguiente nivel: AWS Transit Gateway.

google i/o 2026 just changed everything – here’s what i learned after testing

this is a submission for the google i/o writing challenge

i spent 100 hours testing everything google announced at i/o 2026. what started as curiosity turned into a full-blown obsession. here’s what i found.

google i/o 2026 wasn’t just another conference. it was a fundamental shift in how ai integrates into our daily workflows. the announcements weren’t incremental improvements – they were paradigm changes.

the big picture

before diving into specifics, let me share what stood out most:

i) gemini 3.5 flash – the agentic and coding model that actually delivers on its promises
ii) antigravity 2.0 – standalone desktop app with multi-agent teams that work seamlessly
iii) gemini omni – creates anything from any input, starting with video
iv) spark – your 24/7 personal ai agent that never forgets context

these four represent the core of what makes this year’s conference different. but there’s more

gemini 3.5 flash

google claims gemini 3.5 flash is their strongest agentic and coding model, with 4x speed improvements. i was skeptical. after two weeks of daily use, i’m converted.

the benchmark numbers look good on paper, but the real test is in everyday use. i’ve been using it for:

[1] code review and optimization
[2] debugging complex multi-file projects
[3] generating documentation from scratch
[4] refactoring legacy codebases

the difference from previous versions is noticeable. where earlier models would get stuck on context windows or lose track of requirements, gemini 3.5 flash maintains coherence across longer conversations. the coding output is cleaner, more efficient, and requires less iteration.

i tested it on a project with over 50,000 lines of code. the model understood the architecture, identified performance bottlenecks, and suggested optimizations that saved me hours of manual work. it’s not perfect, but it’s close..

antigravity 2.0

i’ve been using antigravity for scheduled tasks, and the 2.0 reinstallation was a game-changer. the new standalone desktop app feels completely redesigned.

the multi-agent team capabilities are exactly what i needed. i can set up complex workflows that run automatically, and the system handles dependencies between tasks intelligently. here’s what i set up:

✅ automated daily code analysis
✅ weekly dependency updates
✅ monthly security audits

the interface is cleaner, the response times are faster, and the error handling is much more robust. it’s amazing how much smoother everything runs compared to the previous version.

one thing i love is how it learns from my patterns. after a few weeks, it started suggesting optimizations i hadn’t even considered. the system feels less like a tool and more like a collaborator.

my favorite features

after diving deep into all the announcements, here are the features that stood out to me:

gemini omni – the ability to create anything from any input, starting with video, is genuinely impressive. if you have access to gemini omni, play with the video creation features. they’re surprisingly intuitive.

spark – having a 24/7 personal ai agent that remembers context across sessions changes how i work. it’s like having a research assistant who never forgets anything.

gemini search with canvas artifacts – the ability to interact with something in canvas while searching makes research so much more efficient. you can see the results, manipulate them, and iterate in real-time.

amszig – i haven’t tried amszig yet, but from what i’ve seen, it looks like it could be a powerful addition to the ecosystem.

other notable announcements

the conference had a lot more to offer beyond the headline models:

  • google flow – a creative platform with tools and agent capabilities that could reshape how we approach content creation
  • neural expressive – the redesigned gemini app with fluid animations feels like a glimpse into the future of ai interfaces
  • daily brief – personalized morning digest sounds useful for staying updated
  • google pics – image creation and editing directly in workspace could streamline workflows
  • universal cart – a shopping hub across google services is a bold move
  • android halo – agent visibility on android devices brings ai to the mobile experience
  • intelligent eyewear – partnerships with samsung, gentle monster, and warby parker show google’s commitment to wearables
  • ask youtube – conversational search on youtube changes how we discover content
  • stitch – collaborative design agent could transform team workflows
  • ai search box – reimagined with gemini 3.5 flash as default
  • gemini for science – experimental tools for scientific exploration open new possibilities

the numbers

the scale of adoption is staggering:

  • 900 million+ gemini app users (doubled in one year)
  • 13 products with over 1 billion users each
  • ai ultra plan: $100/month new tier, $200/month reduced top tier

final thoughts

google i/o 2026 wasn’t just about incremental improvements. it was a statement that ai is becoming the foundation of everything we do online. the integration across products, the speed improvements, and the focus on practical applications show that google is serious about making ai useful, not just impressive.

for developers, the opportunities are enormous. whether you’re building with gemini 3.5 flash, automating workflows with antigravity 2.0, or exploring the creative possibilities of google flow, there’s never been a better time to be building with ai.

what about you? what aspects of google i/o 2026 are you most excited about? drop a comment below and let’s discuss.

thanks for reading, and happy building

Reserved Instances sound like an easy win at first.

There’s a moment almost every cloud team hits eventually.

You look at AWS Reserved Instances and think:

“Wait… we could save that much just by committing upfront?”

And technically, it’s true.

Reserved Instances can reduce compute costs dramatically compared to On-Demand pricing. That’s why so many FinOps teams adopt them in the first place.

But what starts as a cost optimization strategy can quietly turn into a forecasting problem.

Because the second you buy Reserved Instances, you’re no longer just managing infrastructure.

You’re predicting the future.

The Part Nobody Mentions About Reserved Instances

Reserved Instances work best when workloads stay predictable for long periods of time.

The problem is… modern infrastructure rarely behaves that way anymore.

Teams resize instances.
Autoscaling changes usage patterns.
Architectures evolve.
Services migrate.
Traffic shifts unexpectedly.

And suddenly, the commitment that looked “optimized” six months ago becomes partially unused capacity sitting on your bill.

That’s where a lot of organizations get stuck.

The savings are real.
But so is the risk of getting the commitment wrong.

Cloud Optimization Has Become a Prediction Game

One thing this blog highlights really well is that Reserved Instances aren’t just discounts.

They’re financial commitments tied to technical assumptions.

You’re essentially betting that:

  • your workloads will remain stable,
  • your architecture won’t shift dramatically,
  • and your future usage will resemble your past usage.

That sounds reasonable in theory.

Until engineering teams start moving fast again.

The faster infrastructure changes, the harder long-term commitments become to manage manually.

Why Teams End Up Underutilizing Commitments

Most companies don’t intentionally waste Reserved Instances.

The waste usually happens gradually.

A workload gets rightsized.
A service gets deprecated.
Traffic patterns change.
A migration pauses halfway through.

Now you’re paying for resources your environment no longer fully needs.

And the frustrating part is that this often happens while teams still feel pressure to optimize more aggressively.

That tension sits at the center of a lot of FinOps stress:

  • finance wants deeper savings,
  • engineering wants flexibility,
  • and cloud usage refuses to stay predictable.

The Real Problem Isn’t Discounts — It’s Maintenance

Buying Reserved Instances is actually the easy part.

Maintaining high utilization over time is the hard part.

That’s why more teams are moving toward continuous optimization instead of treating commitments like a one-time purchasing decision.

The article frames this well: cloud cost optimization works more like an ongoing control system than a quarterly cleanup exercise.

Because infrastructure changes continuously.

Optimization has to change with it.

Final Thought

Reserved Instances absolutely can reduce cloud spend.

But they also expose something uncomfortable about modern infrastructure:

Cloud environments evolve faster than long-term commitments do.

And that’s why cloud cost optimization today is less about finding discounts — and more about adapting before yesterday’s assumptions become tomorrow’s waste.

For more information you can check out this blog https://www.usage.ai/blogs/aws/reserved-instances/

Understanding Correlation in PHP: Pearson vs Spearman vs Kendall Tau

Correlation helps you understand whether two variables move together and how strongly they are related. In this article, you’ll learn how Pearson, Spearman, and Kendall tau correlation work, when to use each method, and how to calculate them in PHP with practical examples.

Understanding Correlation

Correlation measures whether two variables tend to change together.

You use correlation when you have two variables describing the same observations. For example:

  • hours studied and exam scores for the same students
  • age and finish time for the same runners
  • product price and units sold for the same products
  • elevation gain and pace for the same running splits

Each value must correspond to the same observation in both datasets.

$hoursStudied = [1, 2, 3, 4, 5];
$testScores = [55, 62, 70, 78, 85];

Here, the first student studied 1 hour and scored 55, the second studied 2 hours and scored 62, and so on. Correlation summarizes the strength and direction of the relationship between paired observations.

A positive correlation means that larger values in one dataset usually go with larger values in the other. A negative correlation means larger values in one dataset usually go with smaller values in the other. A correlation close to zero means the method does not detect a strong relationship.

Correlation does not prove causation. If study hours and test scores are correlated, it does not automatically prove that study hours are the only reason scores improved. Other factors may be involved. Still, correlation is useful for discovering relationships, validating assumptions, comparing signals, and choosing the right model.

The examples in this article use the PHP package hi-folks/statistics https://github.com/Hi-Folks/statistics, which provides statistical functions for PHP developers, including descriptive statistics, probability distributions, regression, and correlation analysis.

This package supports three correlation methods:

  • Pearson
  • Spearman
  • Kendall tau

Pearson Correlation

Pearson correlation measures how strongly two variables follow a straight-line relationship.

Use it when both variables are numeric, and you expect a linear relationship.

Result range:

  • +1: perfect positive linear relationship. As one value increases, the other increases in a straight-line pattern.
  • 0: no linear association detected. The variables may still have a nonlinear relationship.
  • -1: perfect negative linear relationship. As one value increases, the other decreases in a straight-line pattern.

Pearson correlation produces a correlation coefficient between -1 and +1.

Correlation measures the strength of a relationship, not the size of the effect or the rate of change between variables.

Pearson correlation is sensitive to outliers because extreme values can strongly affect the correlation coefficient.

Pearson is useful for:

  • age vs marathon finish time
  • temperature vs energy usage
  • advertising spend vs revenue
  • elevation gain vs running pace, if the effect is roughly linear
use HiFolksStatisticsStat;

$hoursStudied = [1, 2, 3, 4, 5];
$testScores = [55, 62, 70, 78, 85];

$correlation = Stat::correlation($hoursStudied, $testScores);

// Close to +1: more study hours strongly align with higher scores.

Use Pearson when you care about whether the relationship is linear.

Spearman Correlation

Spearman’s correlation measures whether one variable generally increases or decreases as the other changes, using ranked values rather than raw numbers.

Use it when values move together consistently, but not necessarily in a straight line.

Result range:

  • +1: perfect positive monotonic relationship. As one variable increases, the other always increases in rank order.
  • 0: no clear monotonic relationship detected.
  • -1: perfect negative monotonic relationship. As one variable increases, the other always decreases in rank order.

Spearman is useful for:

  • ranked or ordinal data
  • satisfaction scores
  • performance benchmarks
  • nonlinear growth, like experience vs salary
  • cases where outliers could distort Pearson correlation
use HiFolksStatisticsStat;

$experienceYears = [1, 2, 3, 4, 5];
$salary = [30_000, 40_000, 55_000, 80_000, 120_000];

$correlation = Stat::correlation($experienceYears, $salary, 'ranked');

// +1: salary consistently increases with experience rank.

Use Spearman when you care about whether one variable generally increases as the other increases.

Kendall Tau Correlation

Kendall’s tau measures the consistency of two rankings by comparing pairs of observations.

Use it when the dataset is ordinal, contains many tied ranks, or when you want a robust measure of rank agreement.
It is often more robust and easier to interpret for ranked data.

Result range:

  • +1: perfect agreement. Every pair of observations has the same order in both datasets.
  • 0: no clear pairwise rank agreement detected.
  • -1: perfect disagreement. Every pair of observations has the opposite order in the two datasets.

Kendall tau is useful for:

  • ordinal data
  • survey ratings
  • judge rankings
  • race placements
  • preference lists
  • small datasets with repeated values
use HiFolksStatisticsStat;

$judgeA = [1, 2, 3, 4, 5];
$judgeB = [1, 3, 2, 4, 5];

$correlation = Stat::kendallTau($judgeA, $judgeB, 4);

// High positive value: the judges mostly agree.

You can also use Kendall tau through correlation():

$correlation = Stat::correlation($judgeA, $judgeB, 'kendall');

Use Kendall tau when you care about whether two rankings agree pair by pair.

Choosing the Right Correlation Method

  • Use Pearson when the relationship is numeric and roughly linear.
  • Use Spearman when values move consistently but not necessarily linearly.
  • Use Kendall tau for rankings, ordinal data, small datasets, or datasets with many ties.

Using the hi-folks/statistics package, you can calculate these correlation coefficients directly in PHP and integrate statistical analysis into your applications, reports, or experiments.

You can find the package, documentation, and source code on GitHub:

https://github.com/Hi-Folks/statistics

If you find the package useful, consider giving the repository a ⭐ on GitHub.

What schools get wrong about cybersecurity education?

My perspective as a Year 13 student.

I am a Year 13 student (equivalent to US 12th Grade) based in the United Kingdom. I aspire to be a future ethical hacker which is the act of a cybersecurity expert being legally authorized to locate vulnerabilities within a systems organization. To achieve this, I took it upon myself to complete many TryHackMe/HacktheBox rooms, completing projects and coursework to the highest possible grade and reading on relevant topics such as real-world attack techniques and red team security basics.

I have noticed the obvious gap between school teaching and real cybersecurity. From my perspective, the education relating to cybersecurity feels very surface-level. Most of my lessons were spent having to go over content and memorize key terms and their definitions like phishing, malware and firewall etc. It felt as if the curriculum was tailored to help us pass the cybersecurity exam rather than understanding how real cyberattacks occur and defend against them. And for students that wanted to pursue a career within cybersecurity it meant that vital knowledge was left over for them to go over themselves, and while that is not an issue itself it meant that students would not have the teachers knowledge or presence to further strengthen their understanding which can heavily deter them from wanting to even bother researching more about the relevant topics.

Because of these issues, I feel as if my perspective matters to a great extent as I have and currently am experiencing the system first hand. And below I will discuss more about what I personally want to change and why.

I’m aware on how the curriculums do differ from countries and the content taught to students my age can also be varying but this post will be tailored to my experience and honest opinions.

My Experience Learning Cybersecurity in School

Now let’s be honest.

Its tiring hearing the same few questions when being taught cybersecurity content.

What is a firewall?

What is a virus?

What is encryption?

What is a vulnerability?

The list goes on and on.

Sure, it’s important to understand the basics as with any subject. But it gets to a point. My first few lessons consisted of going over ‘new’ content but to me it was topics I had already knew about like heuristic and signature-based detections, DNS and the varying types of attack methods. See, these topics I had went over myself so what would I do during these lessons? And of course, exceptions cannot be made for a singular student like me but without any clear steps or guidance on what to do next could have led to mistakes like revising incorrect content, going off on a tangent or mixing up definitions taught by the teacher with other sources. I had already prepared for the upcoming cybersecurity exam but was eager to learn more in depth about these topics. And that was the issue. Since the curriculum itself was not in-depth it meant that us students would have to research independently but that was not sufficient enough as students would have vast amounts of questions that could not be answered during lessons as they were deemed ‘irrelevant’ or ‘difficult to understand’, so how would we learn more?

The basics were done with. I wanted to learn more and more, it was my goal to become more knowledgeable regarding cybersecurity content, but it was virtually impossible to do so with my teacher having to go over the same content over and over again so that it was drilled into our heads to prepare us for the exam. It felt as if any questions I had they wouldn’t be appropriate for the lesson so I would avoid asking them at all.

Being taught basics meant our understanding was limited. Of course, this would lower our chances of explaining notions in greater depth, but this issue could have been easily solved if we were taught in-depth detailed content which would secure our understanding in cybersecurity. Don’t we want knowledgeable students that would strive into the future with confidence about what they are most passionate about? With all these issues apparent are we to blame how we are taught the curriculum and its cybersecurity content?

Another issue which was evident was the gap in student’s knowledge. All students were taught in equal manner; everyone had to attend lessons and were given the same resources to support them in studies. There were students that understood the content to its minimum level, enough to get them to pass the exams and on the other hand a small group of students would struggle to understand the basics of cybersecurity or even how to convert word documents into PDF format. But when it came to end of topic exams or the genuine exam itself it was clear that students simply did not grasp the topics or retain any knowledge. Now, why was that? Was it the teachers fault? Was the content too difficult for students? the questions remain unanswered. But it clearly meant there were students with gaps in their knowledge and thus their grades and performance were impacted greatly.

Lastly, the exaggeration of how difficult the course is, and unplanned teaching lessons was another issue. Sure, the course itself and its content were not simple and did take some independent time to understand it. But with a vast amount of content at hand, stress is the last thing you want crawling down your spine and lingering around. I remember our class being shown a slideshow with over 400 slides and told that we must understand each slide in great amount of detail. Now 400 slides may not sound impressive but considering majority of our class were still struggling with the basics it meant that even more pressure were put onto them.

The Reality Behind BTEC Cyber Security Results

I pondered whether it was just students in my school that struggled. Or was it just students in my school receiving low results in both mock exams and the real exam itself. So, I came across the official Pearson Grade Boundaries for the cyber security exam unit 11 (Cyber Security and Incident Management) displayed below:

Here, it’s evident that to reach a Pass grade students only needed to secure 27/80 marks. Why is this? With the pass grade being extremely low we can argue that many students struggle with the exam and its difficult compared to the lessons which they are taught. This alone had answered my question and would be one of the main reasons I wrote this post.

What Needs to Change in Cybersecurity Education?

So, what would reduce the gaps that student have when it comes to cybersecurity knowledge? and how can we enhance the student’s capabilities and improve their grades?

Firstly, to counter the gap between students that seem to understand the basics and those who struggle to grasp the concept of simple digital tasks there should be practical hands-on learning experience. This would consist of a few days where students would get to analyse logs, explore vulnerabilities first hand and go over many other scenarios and this allows everyone to see what goes on within cybersecurity and how it actually works rather than being reliant upon a teacher. And this is specifically tailored to the curricula. You may ask how?

I remember an exam I sat had shown us a firewall log which the organization had taken a screenshot of, we were tasked to identify any suspicious activities which was not an issue for me but what about the other students that have never browsed through a firewall or acknowledge anomalies within the logs? But with practical, hands-on experience it means we can tackle this issue and target those students who may struggle more with memorization and perform better when physically interacting with a task, and those students which are more advanced would finally get their depth which they have wanted.

Secondly, teachers must move beyond definitions. What does this mean? One of the alarming challenges within the teaching methods is simple definitions. The curriculum focuses more on memorizing the key term and applying it into context rather than knowing how they work or why they matter within the situation. When students are taught basic definitions their understanding remains shallow, which means they may be able to explain what a DDoS attack is but not how unauthorized users compromise multiple devices (forming a botnet) and send a large volume of data packets to overwhelm a network or the targeted system. Or teachers should further explore and show students how network traffic spikes can be located within a monitoring tool, and that’s the level of details which teachers should be aiming for.

This approach alone will transform the way which students learn from passive to active. And that means students will be able to understand how cybersecurity concepts connect to each other and stop memorizing just definitions which does not cover the same amount of detail. This deeper understanding will improve the student’s grade as they will be able to explain the entirety of processes and not just briefly repeat terms which won’t get them the marks they need during exams or solidify their understanding for the future.

Conclusion: Why Student Voices Matter?

I believe that student voices matter the most. We are the ones experiencing the system as it is and we get to see first-hand the gaps that both teachers may overlook and the curriculum itself. With cybersecurity being both a content-based subject and skills-based it’s vital we understand where students are struggling the most and what the curriculum succeeds in.

Each of our experiences are the reality of what occurs behind the classroom. The repetitive definitions, the lack of depth, overwhelming content to some students and the widening gaps between students that grasp the basics and those that fall behind. By listening to student’s personal notions, newer curriculums can be introduced that are more engaging and practical which would enhance us student’s confidence instead of giving us words to memorize.

What are your thoughts?

Sanity SEO done right: Open Graph, JSON-LD, fallbacks

Every Sanity project we ship starts with the same SEO baseline: a title and description on the document, an SEO tab that overrides them when needed, and Open Graph fields one layer deeper. Fallbacks all the way down, so the page always renders something sensible even when an editor forgets a field. Here’s the exact pattern we use, and where to find it in Turbostart Sanity if you want to copy it.

FAQs

Why does Sanity feel so unopinionated about SEO?

Because Sanity has to model anything — a blog, an e-commerce catalogue, a screen that shows live train times. The trade-off for that range is that the platform won’t pick an SEO pattern for you. You bring the opinion; Sanity gives you the schema.

What fields should every page document have as an SEO baseline?

Title and description at the top level, used as both the page heading/blurb and the default meta. A fallback SEO image. Then a separate SEO tab with seoTitle, seoDescription, seoImage, seoNoIndex, and seoHideFromLists for overrides. Open Graph fields sit a layer deeper for the cases where you want social cards to differ from search snippets.

Why have an SEO tab if the title and description already exist on the document?

Consistency. Editors get one place to write the page copy and one place to override the meta when SEO needs something different — without leaving fields blank or duplicating data. The top-level fields always act as the fallback, so nothing renders empty.

Should JSON-LD live in the CMS or be generated automatically?

Generate it. If the author, title, description, and publish date are already structured in Sanity, map them straight into JSON-LD in your Next.js page. Set and forget. Editors never touch it, and the structured data stays in lockstep with the content.

What does seoHideFromLists actually do?

It’s a flag that lets editors keep a page indexable but exclude it from listing pages. Useful for landing pages tied to paid campaigns, or one-off blog posts you don’t want surfacing on the blog index. Filter on it in your GROQ query and the page disappears from lists without needing noIndex.

Transcript

Hey bud, how you doing? So, first of all, I wanted to put this on YouTube so everybody else can actually see the answer to this question because I get asked this so many times on a daily basis, but I thought it might be helpful for you.

Uh, so in short, and this is a very very common thing that we get: has anybody done SEO work on Sanity before? It doesn’t really go too much into what’s actually built into the model, but I hear this time and time again. Um, and the reason why you have this happen so much is because Sanity is very very unopinionated. And the reason why it’s very very unopinionated is because it can create models that can do anything — genuinely anything when it comes to just writing a blog, or it can be more complex as to running an entire, like, e-commerce system, or it can be as simple as creating, like, a terminal that tells you the latest train times at a train station. It’s really really um scalable.

Anyway, so what I’ll talk about is a little bit of this. So this is an old learn article that we wrote with Sanity, which is really helpful. It tells you about how you should opinionate your actual SEO, and it’s all good and fine if you want to take the time out to go look through this, that’s great. You’ve got a lot more time than I have, so that’s fantastic.

Now, I’m going to show you something totally different. This is actually the Turbo Art, and this is the way that we do it. It’s the same thing that’s in the Sanity learn documentation. Um, but I know how low people’s attention spans are today, so very, very quickly, I’ll show you how this works. This is how we opinionate SEO and we do the exact same on every single one of our projects.

So, when we build a page for a page builder or for a blog or any other document type, it has a title. Okay? And you can do validation. You can do things like, oh, it has to be x number of characters. You can do that. That’s really cool if you think it would help the client. But for the simplicity of this, we don’t have, like, that little number underneath um because we’re trying to be unopinionated.

Um, and description, which is going to be effectively used as your meta description on the page. This can also double up. So if, for example, it’s a blog, um, the title of the blog could also be the title that sits inside of here, and the description could be the little blurb that you get just before you click into the blog on a card. That’s one thing to know. So this becomes our baseline. The same with images. So you may see an image in here as well. Um, which I believe is an SEO — so ours is a SEO image override. Um, however, sometimes we actually include the image in here as well. It could be that it should be in here. Nope. Okay. Um, that might get tweaked on the Turbo Art Sanity, but essentially I like to have an image inside of here as well as part of the pages as a fallback image.

However, we have this secondary tab which is SEO. This is your SEO, your meta title. So your title tags at the top, um, and the meta description which would be in the meta description section. Um, and these will override the title and the description. And you might ask, hold up, if we’ve got the title and description, then what’s going to happen if we override them? Then there surely there’s no reason to have these in the first place. Well, the reason we have these is because they’re always a fallback. So it means that you have a consistent way of editing your pages, whether that’s a page with page builder blocks or a blog which has, like, the blog title, blog description. So it may not appear on all pages.

Now we’ve got our SEO. So our metas, what about our open graph? Well, makes perfect sense. Let’s do open graph title, open graph description. And you can go a step further and also do, I think there’s a separate open graph image. Uh, you can separate it out down to as granular level as here’s what we want to have on Twitter, here’s what we want to have on Facebook, and I think LinkedIn does it as well, just off the top of my head. Um, this is kind of like our de facto baseline. So I would highly, highly recommend doing it this way. Um, however, you can go a lot more granular. You can put JSON LD in there. You can do all sorts of things. However, a note on JSON LD, and I’ve said this to a lot of different people: I much, much prefer set and forget JSON LD. So if you’re already putting all this data, like titles and descriptions and things like that, in there, and authors — if you’re on a blog page — then if you’re on a blog page, let me show you a quick example of this. Um, I’m wondering if we have authors on here. I hope we do. If we don’t, I’m going to tell you how to do it. Uh, we do. Great. So if we’ve got all of these authors that are inside of here, why don’t we just pull those authors into JSON LD by default, which is set and forget? So you don’t have to think about it. You just enter the data inside of Sanity, and a like-for-like pair comes up with JSON LD. And it’s not so complicated these days with AI. So you can even do this relatively quickly. Um, but yeah, this is what I’m talking about when I talk about a de facto default SEO experience. What you should use as a baseline for every single Sanity website that is going to be a website. This obviously differs if it’s going to be a different function. But if you’re looking to start this straight away, or in your case, I would just literally go to the Sanity exchange, go find Turbo Art Sanity. You can also find this on GitHub. Um, go view the repo and tell the developer to just go look inside of here. Um, and pay special attention to two files. One of them is query. So query shows you how we handle our GROQ queries. And GROQ is the query language from Sanity. And then the second thing you want to pay attention to inside of here, um, is — let me see if I can find it for you. Let me just press up top any second now — is the SEO. I think it’s SEO fields, which you can see. You can reuse this. This is what we use on ours where it’s the SEO title, SEO description. Makes perfect sense. SEO image, SEO no index, and SEO hide from lists. And the reason we have these two left is because obviously you want to have a no index. Sometimes maybe it’s a pay-per-click content page that you very specifically want to, like, tunnel down um a specific person that’s coming to your website. And the second one is SEO hide from lists because, for example, you have a blog post. It may be that you don’t want that blog post to show up on certain lists. It may be that you have a no index and you also don’t want it to show up on certain lists, or vice versa. That’s the reason why we do this because if you have SEO hide from lists inside of your GROQ, you can say give me all the blogs except for the ones that are getting hidden from lists, and it’s really nice and easy to work with.

Uh, there’s some very basic validation here, but I hope this helps with you trying to solve this SEO problem. If it continues, just give us a shout. We’re more than happy to try and help and give you pointers in the right direction. Thanks a lot. Have a great day. Take care. Bye-bye.

Lazy-Loading AI Skills in n8n with the Data Table Node

When building AI agent workflows in n8n, one of the first problems you run into is token bloat. If your agent needs to know about a set of reusable instruction sets (skills), the naive approach is to dump all of them into the system prompt. That works — until you have 10, 20, or 50 skills. Suddenly your context is huge and most of it is irrelevant to the current task.

Here’s a minimal, native n8n solution that solves this with zero custom code.

The Idea: Give the LLM a Menu, Not the Full Kitchen

Instead of sending all skill content to the AI upfront, you send only a lightweight catalog — just names and short descriptions. The LLM reads the menu and calls for exactly what it needs.

Startup  →  LLM gets: skill names + when to use them
On demand →  LLM calls Get("create-report") → receives full instructions

This is lazy loading for AI skills.

The Setup

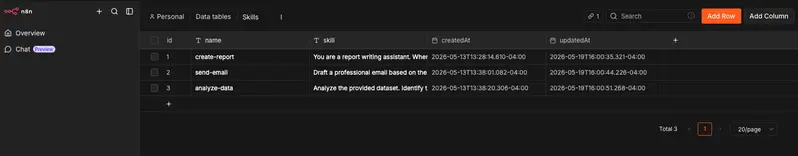
1. Data Table Node

Create a Data Table node with two columns:

name skill
create-report You are a report writing assistant. When given data, structure it into…
send-email Draft a professional email based on the context provided. Always…
analyze-data Analyze the provided dataset. Identify trends, outliers and…
  • name — short identifier the LLM will use to request the skill
  • skill — full instruction text, only loaded when requested

2. Node Description

In the Data Table node description, write the catalog for the LLM — names and short hints only:

Available skills:
- create-report: use when the user wants a report, summary or data overview
- send-email: use when a message or notification needs to be sent
- analyze-data: use when processing numbers, trends or comparisons

To load a skill, call the Get function with the skill name.

This is all the LLM sees at startup. The actual skill content stays hidden.

3. Get Function

Wire up a Get operation on the Data Table node. When the LLM calls Get("create-report"), it receives only that row — the full skill content for that one skill.

Why This Works

The LLM reads the catalog, understands the context from the description, and autonomously decides which skill to load. It then calls Get with the exact name. No guessing, no ID numbers to remember — just semantic names.

The result:

  • Minimal tokens on startup — catalog only
  • Full content on demand — loaded exactly when needed
  • Zero custom code — pure native n8n nodes
  • Easy to maintain — add or edit skills directly in the Data Table

The Flow

User message
    ↓
AI Agent reads catalog from Data Table description
    ↓
Agent decides which skill is relevant
    ↓
Agent calls Get("skill-name")
    ↓
Full skill instructions loaded
    ↓
Agent follows the instructions

Takeaway

Sometimes the simplest solution is already there in the tool you’re using. The Data Table node in n8n wasn’t designed for this — but it fits perfectly. A catalog in the description, a Get call for the content, and you have a lightweight skill system with native nodes.

No npm packages. No custom code. No external databases. No MCPs.

This is a prototype approach. A more robust solution would involve a custom n8n node with built-in skill management UI — but for getting the concept working quickly, this is hard to beat.

What’s Next

Based on this exact principle, I’ve built a native n8n community node that takes this concept further — with a proper skill management UI built directly into the node, so you can add, edit and delete skills without touching the Data Table at all.

It’s currently in testing and will be released soon.

If you want to be the first to know when it drops — follow me here on dev.to or on X. More details coming shortly.