I scanned 10 UK web agency websites for WCAG 2.2 violations — here’s what I found

I’m 15, and I recently built an accessibility scanner that checks websites against WCAG 2.2 standards. To stress-test it, I decided to scan the websites of 10 UK web development agencies — the companies that build websites for a living.

The setup

I ran a single-page scan (homepage only) on each agency’s site using axe-core, checking against 90+ WCAG 2.2 rules. No full crawls — just the home page.

The results were as follows:

Agency A: 8 violations (2 critical, 5 serious)
Agency B: 8 violations (2 critical, 3 serious)
Agency C: 8 violations (1 critical, 2 serious)
Agency D: 7 violations (2 critical, 2 serious)
Agency E: 5 violations (2 critical, 2 serious)
Agency F: 5 violations (0 critical, 1 serious)
Agency G: 4 violations (0 critical, 1 serious)
Agency H: 4 violations (0 critical, 1 serious)
Agency I: 2 violations (0 critical, 1 serious)
Agency J: 0 violations — clean pass

9 out of 10 failed. Only one agency had a completely clean homepage.

Totals across all 10 sites:

51 violations
9 critical
18 serious
21 moderate
3 minor

The most common violations
Colour contrast failures — showed up on 5 out of 10 sites. Text that doesn’t meet the minimum contrast ratio against its background. This is the single most common accessibility issue on the web, and agencies are no exception.
Links without discernible text — 5 out of 10 sites. Screen readers can’t tell users where a link goes if it has no accessible name. Usually caused by icon links or image links with no alt text.
Missing lang attribute — 2 out of 10 sites didn’t declare a language on their HTML element. This tells screen readers which language to use for pronunciation. Takes 10 seconds to fix.
Zooming disabled — 2 out of 10 sites used meta viewport settings that prevent users from zooming in. This is a critical violation because it blocks people with low vision from enlarging text.
Images without alt text — one agency had 272 images on their homepage with no alt text. Two hundred and seventy-two.

Why this matters

These are the companies businesses hire to build their websites. If their own sites don’t pass basic accessibility checks, what does that say about the sites they’re building for clients?

This isn’t about shaming anyone — most of these are easy fixes. But with accessibility lawsuits increasing every year (8,600+ ADA lawsuits in 2025, with ecommerce sites being the primary target), it’s worth paying attention to.
94.8% of websites fail basic accessibility checks according to WebAIM’s 2025 report. Agencies aren’t immune.

What I built

I built the scanner as a side project called Vía. It scans websites for WCAG 2.2 violations, ranks them by legal risk, explains each one in plain English, and generates AI-powered code fixes.
Not an overlay widget — actual code changes you can copy and implement.
Free to try on any site: viascan.dev
Would love to hear from other devs — do you check accessibility before shipping client work? What tools do you use? What’s missing from the current options?

I built a TOML-based task runner in Rust

demo

Every project I work on has the same problem. There’s always a set of commands I run in the same order every time, setting up dependencies, building, running checks. I got tired of either remembering them or keeping a random notes file.

Makefiles work but feel wrong outside of C projects. npm scripts are JavaScript-only. just is great but it’s another syntax to learn on top of everything else.

So I built xeq.

demo

You define named scripts in a xeq.toml file and run them with one command:

[check]
run = [
    "cargo fmt --check",
    "cargo clippy -- -D warnings",
    "cargo test"
]

[build]
run = [
    "xeq:check",
    "cargo build --release"
]
xeq run build

That’s it. No new syntax, just TOML that any project already understands.

It supports variables with fallback values, positional and named arguments, environment variables, nested script calls, parallel execution with thread control, and on_success/on_error event hooks.

The feature I’m most happy with is xeq validate, it catches undefined variables, missing nested scripts, circular dependencies, and parallel conflicts before you run anything.

There are also 30+ init templates so you can get started instantly:

xeq init rust
xeq init docker
xeq init nextjs

It works on Linux, macOS, and Windows.

Still early but functional. Would love feedback❤️

7 Mac Apps for Developers Getting Back Into Coding After a Break in 2026

Whether you took time off for burnout, a career pivot, parental leave, or just life happening — getting back into coding can feel overwhelming. The ecosystem moves fast, and your old setup probably feels stale.

I came back after a few months away recently and realized my biggest wins weren’t learning new frameworks. They were setting up the right environment so I could focus and build momentum again.

Here are 7 Mac apps that made my return to coding way smoother.

1. Raycast — Your New Command Center

Download Raycast

If you’ve been away, Raycast is what Spotlight wishes it was. It’s a launcher, clipboard manager, snippet expander, and window manager rolled into one app. The plugin ecosystem has exploded — you can search GitHub repos, manage Jira tickets, and even run AI prompts without leaving the keyboard. It cuts the friction of re-learning where everything is on your machine.

2. Warp — A Terminal That Doesn’t Punish Rust

Download Warp

Coming back to the terminal after a break used to mean staring at a blank prompt wondering what you were doing. Warp changes that — it has AI command suggestions, proper block-based output so you can actually read what happened, and built-in workflows. It’s like pair programming with your shell. If your muscle memory for CLI commands is rusty, Warp fills the gaps without making you feel dumb.

3. Obsidian — Rebuild Your Second Brain

Download Obsidian

After a break, your notes are probably scattered across three apps and a dozen browser bookmarks you forgot about. Obsidian gives you a local-first markdown vault where you can dump everything: project ideas, API references, learning notes, daily logs. The graph view helps you reconnect thoughts you’ve forgotten. I use it as my re-onboarding journal every time I come back to a project.

4. TokenBar — Know What Your AI Tools Actually Cost

Download TokenBar

Here’s something that changed while you were away: AI coding tools are everywhere now, and they all burn tokens. TokenBar ($5, lifetime) sits in your menu bar and tracks your LLM token usage across providers in real time. When you’re ramping back up and leaning heavily on Copilot, Claude, or ChatGPT to fill knowledge gaps, it’s easy to accidentally blow through $50 in a week. TokenBar keeps that visible so there are no surprises.

5. Monk Mode — Block the Feeds, Not the Apps

Download Monk Mode

The hardest part of coming back isn’t the code — it’s the distractions. Your brain wants to ease back in with Twitter, Reddit, and YouTube instead of actually writing code. Monk Mode ($15, lifetime) blocks feeds at the content level without blocking the apps themselves. You can still use YouTube for tutorials but can’t fall into the recommendation hole. It’s the guardrails you need when your discipline muscles are still warming up.

6. Rectangle — Instant Window Management

Download Rectangle

Free and open source. After a break, you probably forgot whatever window management shortcuts you used to know. Rectangle gives you keyboard shortcuts and snap zones to tile windows instantly — editor on the left, terminal on the right, docs on the second monitor. It takes 30 seconds to set up and immediately makes your workspace feel organized again. One less thing to figure out when you’re already re-learning everything else.

7. Homebrew — Get Your Dev Environment Back Fast

Download Homebrew

If you did a clean macOS install (or your old setup rotted while you were gone), Homebrew is how you get everything back in minutes instead of hours. brew install node python git gh and you’re halfway there. Pro tip: if you had a Brewfile from before, brew bundle restores your entire toolchain in one command. Future-you will thank past-you for that.

The Comeback Strategy

Coming back to code after a break isn’t about catching up on every new framework and tool that launched while you were gone. It’s about:

  1. Reducing friction — make your environment work for you, not against you
  2. Protecting focus — block the distractions before they block your progress
  3. Building momentum — ship something small in the first week, even if it’s ugly

The right tools don’t replace the work, but they make starting way less painful.

What apps helped you get back into coding? Drop them in the comments — always looking for tools that make the return smoother.

I tracked every token my AI coding agent consumed for a week. 70% was waste.

Last week Anthropic announced tighter usage limits for Claude during peak hours. My timeline exploded with developers asking why they’re hitting limits after 2-3 prompts.

I’m the developer behind vexp, a local context engine for AI coding agents. Before building it, I did something nobody seems to do: I actually measured what’s happening under the hood.

The experiment

I tracked token consumption on FastAPI v0.115.0 — the real open-source framework, ~800 Python files. Not a toy project.

7 tasks (bug fixes, features, refactors, code understanding). 3 runs per task. 42 total executions. Claude Sonnet 4.6. Full isolation between runs.

What I found

Every single prompt, Claude Code did this:

  1. Glob pattern * — found all files
  2. Glob pattern **/*.{py,js,ts,...} — found code files
  3. Read file 1
  4. Read file 2
  5. Read file 3
  6. …repeat 20+ times
  7. Finally start thinking about my actual question

Average per prompt:

  • 23 tool calls (Read/Grep/Glob)
  • ~180,000 tokens consumed
  • ~50,000 tokens actually relevant to the question
  • 70% waste rate

That 70% is why you’re hitting usage limits. You’re not asking too many questions. Your agent is reading too many files.

Why this happens

AI coding agents don’t have a map of your codebase. They don’t know which files are relevant to your question before they start reading. So they do what any new developer would do on their first day: read everything.

The difference is that a new developer reads the codebase once. Your AI agent reads it on every single prompt.

And it gets worse. As your session continues, context accumulates. By turn 15, each prompt is re-processing your full conversation history plus the codebase reads. The cost per prompt grows exponentially, not linearly.

What actually helps

Free fixes (do these today):

  1. Scope your prompts. “Fix the auth error in src/auth/login.ts” triggers 3-5 file reads. “Fix the auth error” triggers 20+.

  2. Short sessions. Start a new session for each task. Don’t do 15 things in one conversation.

  3. Use /compact before context bloats. Don’t wait for auto-compaction at 167K tokens.

  4. Audit your MCPs. Every loaded MCP server adds token overhead on every prompt, even when you don’t use it.

  5. Use /model opusplan. Planning with Opus, implementation with Sonnet.

These get you 20-30% savings. The structural fix gets you 58-74%.

What I built

The idea: instead of letting the agent explore your codebase file-by-file, pre-index the project and serve only the relevant code per query.

I built this as an MCP server called vexp. Rust binary, tree-sitter AST parsing, dependency graph, SQLite. Runs 100% locally. Your code never leaves your machine.

Here’s what changed on the FastAPI benchmark:

Metric Before After Change
Tool calls/task 23 2.3 -90%
Cost/task $0.78 $0.33 -58%
Output tokens 504 189 -63%
Task duration 170s 132s -22%

Total across 42 runs: $16.29 without vexp, $6.89 with.

The output token drop surprised me. Claude doesn’t just read less — it generates less irrelevant output too. Focused input context leads to focused responses. I didn’t design for that, but it makes sense: less noise in, less noise out.

The output quality didn’t drop. It improved.

I also ran this on SWE-bench Verified — 100 real GitHub bugs, Claude Opus 4.5, same $3 budget per task:

  • 73% pass rate (highest in the lineup)
  • $0.67/task vs $1.98 average
  • 8 bugs only vexp solved

Same model. Same budget. The only variable was context quality.

What this means for the usage limits debate

Everyone’s arguing about whether Anthropic should raise limits or lower prices. Both miss the point.

The real issue is architectural: AI coding agents don’t know your codebase. They compensate by reading everything. You pay for that compensation with tokens — and now, with tighter session limits.

Cheaper tokens help. Higher limits help. But reducing what goes into the context window in the first place is the only fix that works regardless of what Anthropic does with pricing or limits.

Full benchmark data (open source, reproducible): https://vexp.dev/benchmark

FastAPI methodology: https://www.reddit.com/r/ClaudeCode/comments/1rjra2w/i_built_a_context_engine_that_works_with_claude/

Free tier available, no account needed. I’m curious what numbers you see on your own projects — especially on repos larger than FastAPI.

Building Beautiful AI Chat UIs in Flutter: A Developer’s Guide

Building Beautiful AI Chat UIs in Flutter: A Developer’s Guide

The AI revolution has transformed how users interact with applications, and chat interfaces have become the new standard for AI-powered apps. But building a polished, production-ready chat UI in Flutter? That’s where things get tricky.

After building countless chat interfaces and seeing developers struggle with the same problems over and over, I want to share the patterns and techniques that actually work in production.

The Chat UI Challenge

Most developers underestimate chat UI complexity. It’s not just about displaying messages—you need:

  • Smooth animations for message bubbles
  • Real-time typing indicators
  • Message states (sending, delivered, failed)
  • Auto-scrolling behavior that feels natural
  • Rich content support (images, code blocks, buttons)
  • Responsive design across different screen sizes
  • Accessibility for all users

And that’s just the basics. Modern AI chat UIs also need streaming text, regeneration buttons, conversation management, and seamless integration with AI services.

The Traditional Approach (And Why It Falls Short)

Most Flutter developers start with a basic ListView and ListTile combination:

ListView.builder(
  itemCount: messages.length,
  itemBuilder: (context, index) {
    final message = messages[index];
    return ListTile(
      title: Text(message.content),
      trailing: message.isUser ? Icon(Icons.person) : Icon(Icons.smart_toy),
    );
  },
)

This works for a proof of concept, but quickly breaks down when you need:

  • Custom message bubbles with proper alignment
  • Typing animations
  • Message state management
  • Rich content rendering

You end up with hundreds of lines of custom widgets, complex state management, and a codebase that’s hard to maintain.

Enter Component Libraries: The Modern Solution

Just like how shadcn/ui revolutionized React development by providing beautiful, composable components, Flutter needs similar solutions for AI chat interfaces.

This is where component libraries specifically designed for AI chat UIs become game-changers. Instead of reinventing the wheel, you get:

  • Pre-built, tested components that handle edge cases
  • Consistent design language across your app
  • Built-in animations and micro-interactions
  • Accessibility features out of the box
  • Easy customization while maintaining quality

Building Your First AI Chat Interface

Here’s how a modern approach looks with proper component architecture:

class ChatScreen extends StatelessWidget {
  @override
  Widget build(BuildContext context) {
    return Scaffold(
      body: ChatContainer(
        messages: messages,
        messageBuilder: (message) => MessageBubble(
          content: message.content,
          isUser: message.isUser,
          timestamp: message.timestamp,
          status: message.status,
        ),
        inputBuilder: () => ChatInput(
          onSendMessage: _handleSendMessage,
          isLoading: _isGenerating,
        ),
        typingIndicator: TypingIndicator(
          isVisible: _isTyping,
        ),
      ),
    );
  }
}

Notice how clean and declarative this is? Each component has a single responsibility:

  • ChatContainer manages the overall layout and scrolling behavior
  • MessageBubble handles individual message rendering
  • ChatInput manages user input and send functionality
  • TypingIndicator shows AI processing state

Key Features to Look For

When evaluating chat UI solutions, prioritize these features:

1. Streaming Text Support

Modern AI APIs stream responses token by token. Your UI should support this natively:

MessageBubble(
  content: message.content,
  isStreaming: message.isStreaming,
  streamingCursor: true,
)

2. Rich Content Rendering

Support for code blocks, images, and interactive elements:

MessageBubble(
  content: message.content,
  contentType: message.type, // text, code, image, etc.
  actions: message.actions, // buttons, quick replies
)

3. Message State Management

Clear visual feedback for message states:

MessageBubble(
  content: message.content,
  status: MessageStatus.sending, // sending, sent, failed, retrying
  onRetry: _handleRetry,
)

4. Conversation Management

Easy handling of conversation context and history:

ChatContainer(
  conversationId: currentConversation.id,
  messages: messages,
  onLoadMore: _loadMoreHistory,
)

Performance Considerations

Chat UIs can quickly become performance bottlenecks. Here’s what to watch for:

Efficient List Rendering

Use proper list virtualization for long conversations:

ChatContainer(
  messages: messages,
  itemExtent: null, // Dynamic height
  cacheExtent: 1000, // Reasonable cache
)

Memory Management

Implement message pagination and cleanup:

// Load messages in chunks
void _loadMoreMessages() {
  if (messages.length > MAX_MESSAGES_IN_MEMORY) {
    _cleanupOldMessages();
  }
  _fetchMoreMessages();
}

Animation Performance

Use efficient animations that don’t cause jank:

MessageBubble(
  animationDuration: Duration(milliseconds: 200),
  useNativeAnimations: true,
)

Common Pitfalls to Avoid

  1. Over-animating: Too many animations create a chaotic experience
  2. Ignoring accessibility: Always test with screen readers
  3. Poor error handling: Network failures should be gracefully handled
  4. Inconsistent spacing: Maintain consistent visual rhythm
  5. Missing loading states: Users need feedback during AI processing

The Future of Flutter AI Chat UIs

The AI chat interface space is evolving rapidly. We’re seeing trends toward:

  • Multi-modal interfaces (voice, text, images)
  • Contextual actions based on message content
  • Advanced formatting for AI responses
  • Real-time collaboration features
  • Integration with vector databases for RAG applications

Getting Started

Ready to build your AI chat interface? Here are your next steps:

  1. Choose your component library carefully—look for active maintenance and good documentation
  2. Start with a simple implementation and iterate based on user feedback
  3. Test on real devices to catch performance issues early
  4. Implement proper error handling from day one
  5. Plan for internationalization if you’re targeting global users

Wrapping Up

Building great AI chat UIs in Flutter doesn’t have to be complicated. By leveraging modern component libraries and following established patterns, you can create beautiful, performant chat interfaces that users love.

The key is focusing on user experience while maintaining clean, maintainable code. Don’t reinvent the wheel—use the tools and patterns that have been proven in production.

Want to see these patterns in action? Check out the examples and dive deeper into the techniques we’ve covered. The future of Flutter development is component-driven, and AI chat interfaces are leading the way.

Building AI-powered Flutter apps? Share your experiences and challenges in the comments below. Let’s learn from each other and push the boundaries of what’s possible in mobile AI interfaces.

Why Your SaaS Node Backend Will Fail at 10k Requests/Minute (and How to Stress‑Proof It Without Rewriting)

At 1k active users, your Node backend feels like a rock.

At 3k–5k users, Stripe webhooks start retrying, background jobs pile up, and you notice the first “duplicate charge” ticket.

At 8k–10k requests per minute, you’re in a live incident: jobs vanish on deploy, webhook duplicates double‑bill customers, and MFA state drifts, leaving users locked out.

Node is great—but naïve implementations won’t survive SaaS‑scale.

Here’s exactly what breaks and how to stress‑proof it without a full rewrite.

If you’re:

  • building a Node.js + TypeScript SaaS backend,
  • handling Stripe webhooks, background jobs, and auth,
  • and worried that your current architecture will fall apart at 3k–10k requests per minute,

then this post is for you.

What Actually Breaks at 10k RPM in Node

1. Silent Job Loss & Race Conditions

If your background jobs rely on setTimeout or an in‑memory array, a simple git push will wipe them out.

But the real pain starts when workers race for the same job.

Example: A Stripe checkout.session.completed event triggers a job to deliver a license.

Two workers both see the job as “pending” → both claim it → customer receives two licenses.

Pattern that fails:

// Naive in‑memory queue
const jobs = [];

setInterval(() => {
  const job = jobs.shift();
  if (job) process(job);
}, 1000);

What survives:

  • Persistent queue (Redis, RabbitMQ, Postgres with SKIP LOCKED).
  • Atomic claim: the first worker to “lock” the job wins; others skip it.
  • Crash recovery: jobs are persisted before execution, so a worker crash doesn’t lose them.

2. Stripe Webhook Race Conditions

Stripe retries slow webhooks. If your handler is not idempotent, each retry creates a new charge, subscription, or email.

Fragile handler:

app.post('/stripe-webhook', async (req, res) => {
  const event = req.body;
  await db.invoices.insert({ stripeId: event.id });
  await sendReceiptEmail();
  res.sendStatus(200);
});

If two identical events arrive concurrently, both will insert duplicate rows.

Idempotency fix:

  • Use a unique constraint on (stripe_event_id, event_type).
  • Or wrap the handler in an atomic guard that checks a “processed” flag before doing work.

3. Auth & MFA State Drift

When your authentication relies on in‑memory sessions or local cookies without server‑side validation, you risk:

  • Users being able to bypass MFA after a session token is stolen.
  • “MFA required” being enforced only in the UI, not on the API.

Example: A user enables MFA, but the API still allows them to change their billing email without a second factor. An attacker with a stolen session can compromise the account.

What’s needed:

  • Stateless tokens (JWT) with explicit permissions.
  • Per‑action MFA enforcement on sensitive routes (e.g., POST /api/billing/change-email), not just a flag in the UI.

How to Stress‑Test Your SaaS Node Backend

Before you hit 10k RPM, know where you’ll break. Here’s a simple stress‑test recipe you can run today:

Tools

  • autocannon or hey for HTTP load.
  • Stripe CLI to replay webhooks.
  • A script to kill workers randomly.

Tests to Run

  1. Auth endpoint
    autocannon -c 100 -p 10 http://localhost:3000/api/v1/auth/login
    Watch for 5xx errors and 99th‑percentile latency. If you see spikes >1s, your session store might be the bottleneck.

  2. Concurrent Stripe webhooks
    Use Stripe CLI to fire 50 identical events simultaneously:
    stripe trigger checkout.session.completed --repeat 50
    Then check your DB for duplicate records. If you see any, your webhook handler isn’t idempotent.

  3. Crash recovery
    Start a long‑running job (e.g., 10s sleep).
    While it’s running, kill the worker process (kill -9).
    Verify the job is retried or resumed, not lost.

What to Measure

  • Error rate (should stay at 0%).
  • Job loss count (should be 0).
  • Duplicate transaction count (should be 0).

How KeelStack Already Hardens This

KeelStack Engine was built to survive exactly these failure modes on a production‑like SaaS workload. It ships with:

  • Atomic job queue using Redis‑Lua or PostgreSQL SKIP LOCKED. Jobs are persisted before execution; if a worker crashes, they’re re‑claimed by another worker with exponential backoff.
  • Idempotency guard for all mutating endpoints. Stripe webhooks are wrapped with a composite key (event_id + event_type), and the result is cached. Duplicate events return a 200 without re‑executing business logic. In stress‑tests with KeelStack, we see <1% error rate and zero duplicate transactions even when firing 100 identical Stripe webhooks per second.
  • Per‑action MFA enforcement at the API level. The auth module includes a requireMfaFor(route) helper that validates the MFA token on sensitive operations—not just on login.

These aren’t marketing claims; they’re the exact patterns you’d need to implement yourself. KeelStack ships them by default so you can focus on your unique product logic.

Practical Checklist: Hardening Your Node SaaS Before 10k RPM

  1. Use persistent queues – Redis, RabbitMQ, or Postgres with SKIP LOCKED. Never rely on in‑memory arrays or setTimeout for jobs.
  2. Idempotency keys on all webhooks and billing actions – store the result of every mutating operation keyed by a unique identifier (e.g., Stripe event ID + user ID).
  3. Stateless sessions + per‑action MFA enforcement – store only a JWT; validate MFA on sensitive API endpoints, not just in the UI.
  4. Crash‑safe job runners – jobs should be saved to the database before execution starts, and marked as done after success.
  5. Stress‑test with 2–3x your expected peak – use autocannon and simulate webhook floods to catch race conditions early.
  6. Add structured logging – correlate logs with request IDs so you can trace a job from creation to completion across worker restarts.
  7. Enforce test coverage – write integration tests for failure scenarios (e.g., duplicate webhooks, worker crashes). If you can’t reproduce it in CI, it will happen in production.

For deep‑dives on each of these topics, check out our previous posts:

Ship Safe, Not Just Fast

If you’re building a SaaS backend in Node, you don’t have to rediscover these hard‑earned lessons at 3am when your first real‑world traffic spike hits. The patterns above are proven and can be integrated incrementally—or you can start from a foundation that already has them built in.

KeelStack Engine is a production‑tested Node + TypeScript starter that includes idempotency, persistent job queues, per‑user LLM token budgets, and a full auth/billing stack. It’s 100% source code you can access under license terms and deploy anywhere.

👉 Get instant access to KeelStack Engine – skip the weeks of wiring and jump straight to building features that matter.

Claude Code 2.1.85: My Python Project Setup After Six Months of Daily Use

Claude Code just hit v2.1.85 — it skipped 2.1.82 entirely and pushed three patch versions in roughly 24 hours before promoting 2.1.85 to latest. Whatever was getting fixed, it was getting fixed fast.

I’ve been using Claude Code as my primary AI coding tool for Python projects for about six months now. The rapid patch cycle is a good moment to write up what I’ve actually learned — the setup that works, the patterns that save time, and the things that looked useful but weren’t.

This isn’t a “Claude Code is amazing” post. It’s the practical stuff I wish someone had written when I started.

The thing most people skip: CLAUDE.md

Claude Code reads a CLAUDE.md file at the root of your project before every session. Most tutorials mention it briefly and move on. It’s actually the highest-leverage configuration you can do.

Without it, Claude Code is making educated guesses about your project. With a good one, it knows exactly how to run your tests, what your linting setup is, which files to avoid, and how you prefer to structure code.

Here’s the template I use for Python projects:

# Project: [name]

## Stack
- Python 3.12
- pytest + pytest-cov for testing
- ruff for linting/formatting (replaces black + flake8)
- mypy for type checking (strict mode)
- [any frameworks: FastAPI / SQLAlchemy / etc]

## Commands
- Run tests: `pytest tests/ -x --tb=short`
- Run single test: `pytest tests/test_foo.py::test_bar -v`
- Lint: `ruff check . && ruff format --check .`
- Type check: `mypy src/`
- All checks: `make check`

## Project structure
- `src/[package]/` — main package code
- `tests/` — pytest tests (mirrors src/ structure)
- `scripts/` — one-off scripts, not production code

## Conventions
- Type hints on all public functions
- Docstrings on public classes and non-obvious functions
- Tests use fixtures from conftest.py — check there before creating new ones
- No bare `except:` — always catch specific exceptions

## Don't touch
- `migrations/` — hands off unless explicitly asked
- `.env` files — never read or modify
- `pyproject.toml` dependency versions — propose changes, don't apply

The “Don’t touch” section is underrated. Claude Code is eager to help, which means it’ll sometimes edit things adjacent to what you asked for. Explicit boundaries save time.

The three commands I use every day

1. claude (plain, in project root)

Opens an interactive session with full project context. This is my primary mode. I describe what I want, it proposes changes, I approve or reject. The approval flow feels slow the first week, then becomes natural — you’re reviewing diffs, not babysitting output.

2. claude -p "task description"

One-shot mode. I use this for well-defined tasks where I know exactly what I want:

claude -p "Write a pytest fixture that creates a temp SQLite database for testing, tears it down after each test, and lives in tests/conftest.py"

One-shot is faster than interactive for tasks that are specific enough to describe completely. The key is being precise — vague one-shot prompts produce vague results.

3. claude --continue

Resumes the previous session. More useful than I expected. When I leave something half-done and come back, --continue picks up the thread. It’s not perfect context restoration, but it’s better than re-explaining everything.

Patterns that actually work

Test-first, always

The single most effective workflow I’ve found: describe the behavior you want as a test, then let Claude Code implement the function.

Me: Write the test first. I want a function `parse_config(path: str) -> Config`
that reads a YAML file and returns a validated Config dataclass.
The test should cover: valid input, missing required field,
invalid type for a field, and file not found.

Claude: [writes tests/test_config.py]

Me: Now implement parse_config to pass those tests.

This works because tests constrain the solution space. Claude Code is much better at implementing against a spec than guessing what you want.

Ask for the plan before the code

For anything non-trivial, I ask “what’s your plan?” before “write the code.” This takes an extra exchange but prevents long stretches of code I’d reject immediately.

Me: I need to add rate limiting to our API endpoints.
What's your plan before you write anything?

You’ll catch misunderstandings early. “I’d add a Redis-backed rate limiter using…” when you don’t have Redis in your stack is much cheaper to correct as text than as 200 lines of code.

Keep sessions focused

Claude Code’s context window is large but not infinite, and performance degrades as context fills. I’ve learned to:

  • Start a new session for each distinct task
  • Not drag in unrelated files “just in case”
  • Use --continue only for the same task, not for adjacent ones

One task per session. It sounds inefficient but it’s faster in practice.

The prompt library problem

Claude Code is a tool, not a solution. The quality of what it produces is directly proportional to the quality of what you ask for.

After a few months of using it, I noticed I was writing the same types of prompts repeatedly — for test generation, for refactoring, for API design, for documentation. I started keeping a local file of prompts that had worked well.

That file turned into the AI Developer Toolkit, which I published last week — 272 prompts organized by task type (testing, refactoring, debugging, architecture decisions, code review, etc.). It’s what I actually use, not a “1000 ChatGPT prompts” dump.

The relevant point here: the prompts that work best with Claude Code are the ones that give it a clear output format, explicit constraints, and an example or two. Generic prompts get generic code.

What doesn’t work

Asking it to “look at the codebase and suggest improvements”

You’ll get a list of things that are either obvious, wrong for your context, or technically correct but not worth doing. Claude Code is good at executing specific tasks. It’s not good at prioritizing.

Letting it run multiple steps without checkpoints

I have autoAcceptEdits: false in my settings. Some people turn this on for speed. My experience: you end up reviewing three interdependent changes at once instead of one at a time, and when something is wrong it’s harder to identify where.

Using it for first drafts of complex architecture

For a simple CRUD endpoint, first draft is fine. For something genuinely complex — a custom event loop, a tricky state machine, distributed coordination — I’ve had better results sketching the design myself first and using Claude Code to fill in the implementation.

The stable vs latest question

Claude Code ships stable, latest, and next tags via npm. I run latest (currently 2.1.85). stable is still pinned at 2.1.77 — well behind.

For daily use on Python projects, I haven’t hit stability issues on latest. If you’re running it in CI or as part of automated workflows, I’d be more conservative. But for interactive development sessions, latest is fine.

The 2.1.85 patch cycle

I don’t know what’s in 2.1.83 through 2.1.85 specifically — the npm metadata doesn’t include changelogs. But three patches in 24 hours before promotion suggests something was wrong and then fixed. That pattern is familiar to anyone who’s shipped software: sometimes you catch a regression mid-release and hotfix until it’s stable.

Whatever it was, the tool feels solid on my current Python projects. I’ll update this if anything notable surfaces.

Quick-start CLAUDE.md for a Python package

If you’re starting from scratch, here’s the minimal version:

# [Package Name]

## Test command
pytest tests/ -x

## Lint command
ruff check . && ruff format --check .

## Python version
3.12

## Don't modify
- pyproject.toml (propose changes only)

Add more as you learn what Claude Code consistently gets wrong for your project. The CLAUDE.md is a living document — I update mine every few weeks.

That’s what six months of daily Python use has taught me. The tool is good. The setup matters more than most people realize.

If you’re using Claude Code on Python projects and have patterns that work for you, I’d like to hear them in the comments — especially around testing workflows and larger codebases.

Вайбкодинг с Claude | Создание Telegram-ботов

Введение

Программирование прямо сейчас переживает сдвиг в подходе к работе.

Если раньше основной процесс выглядел как «сел и пишешь код руками»: продумываешь архитектуру, разбираешься с документацией и часами ищешь ошибки, то теперь всё чаще сценарий другой — ты формулируешь задачу, а реализацию на себя берёт ИИ.

Это и называют вайбкодингом.

Ты не работаешь на уровне синтаксиса — ты работаешь на уровне идеи. Задаёшь направление, описываешь поведение, уточняешь детали, а модель превращает это в код и структуру проекта.

Но здесь важно не попасть в иллюзию. Это не автоматическая разработка и не кнопка «сделать всё». Это инструмент, который даёт ускорение, но только если ты контролируешь процесс и понимаешь, что происходит.

Как всё изменилось за последний год

Если откатиться буквально на год назад, ИИ уже умел писать код, но это было скорее про отдельные функции или простые скрипты.

Собрать нормальный Telegram-бот, сайт или приложение целиком было сложно:

  • модели теряли контекст
  • путались в архитектуре
  • ломали уже написанное

С выходом новых версий вроде Claude Sonnet 4.6 и Claude Opus 4.6 ситуация сильно изменилась.

Модели стали:

  • лучше держать большой проект
  • понимать структуру
  • работать с кодом как с системой

Они дольше сохраняют контекст, лучше планируют шаги и реже требуют переписывания всего с нуля.

В результате то, что раньше требовало полноценной разработки, теперь можно собрать через диалог — от идеи до работающего бота или сервиса за один вечер.

О чём эта статья

В этой статье я разберу, как это работает на практике на примере Telegram-бота через Claude.

Без демонстрационных сценариев и «идеальных кейсов» — только реальный процесс, включая моменты, где всё идёт не так.

Дисклеймер

Я не пытаюсь продать идею, что вайбкодинг заменит разработчиков.

На практике он работает иначе:

  • убирает рутину
  • ускоряет старт
  • но не снимает ответственность

Если ты не понимаешь, что происходит в коде, ты просто переносишь проблему с «написать» на «разобраться, что он написал».

Поэтому важно воспринимать это как инструмент усиления, а не как замену навыков.

Бум вайбкодинга

Начнём с фактов.

Бот @BotFather — это инструмент для создания Telegram-ботов.

Ранее у него было около 4.1 млн пользователей в месяц.

Спустя примерно 2 месяца — уже 8.26 млн пользователей.

Фактически рост в 2 раза за короткий период.

Важно:

  • BotFather был создан в 2015 году
  • резкий рост произошёл именно сейчас

Это напрямую связано с развитием ИИ-моделей.

Раньше они не могли стабильно собирать проекты — сейчас могут.

Почему Claude хорошо подходит под Telegram-ботов

Claude ощущается не как генератор текста, а как разработчик, который просто сидит рядом.

1. Мышление структурой

Он не просто пишет код — он:

  • делит проект на файлы
  • выносит конфигурацию
  • разделяет логику

В итоге ты сразу получаешь более чистую архитектуру.

2. Контекст

При росте проекта многие модели начинают ломать старый код.

Claude:

  • держит больше контекста
  • лучше понимает связи
  • позволяет постепенно наращивать проект

3. Предсказуемость

Код:

  • менее хаотичный
  • более стабильный
  • ближе к тому, что можно поддерживать

Это не идеал, но уже рабочий уровень.

Подготовка

Для старта нужно:

  • Telegram-бот (через BotFather)
  • Python
  • доступ к Claude

Если нужен деплой — добавляется VPS, но это не обязательно на старте.

Интересный момент — выбор стека

Вместо ресёрча я просто делегировал это модели.

В ответ получил:

  • aiogram 3
  • SQLite
  • dotenv

И этого оказалось достаточно для старта.

Это и есть суть вайбкодинга:

ты не выбираешь идеально — ты получаешь рабочую базу и корректируешь её по ходу.

Как реально выглядит разработка

Главное изменение — формат работы.

Ты не пишешь код напрямую, ты ведёшь диалог.

Пример стартового запроса

Напиши мне тг бота:
aiogram3, python3, html теги, бд sqlite, logging, апи в env,
со всеми зависимостями. суть в том что …

Такой запрос сразу задаёт:

  • стек
  • окружение
  • поведение

И модель даёт уже основу проекта.

Критически важный приём

Добавляешь инструкцию:

Не переписывай всю программу, выпиши коды и скажи,
куда что добавить, как будто я новичок.

После этого:

  • модель перестаёт пересобирать проект
  • начинает работать точечно
  • даёт изменения, а не переписывание

Это превращает процесс в итеративную разработку, а не хаос.

Как растёт проект

Процесс выглядит так:

  1. Базовый бот
  2. Добавление базы данных
  3. Усложнение логики
  4. Сценарии взаимодействия

По мере роста Claude сам:

  • делит код
  • выносит обработчики
  • разделяет ответственность

Ты при этом видишь всю структуру и можешь вмешиваться.

Где начинаются проблемы

Ошибки появляются при усложнении логики.

Основные проблемы:

  • устаревший синтаксис
  • несуществующие методы
  • логические допущения
  • ошибки в датах и состояниях

На простом уровне это почти незаметно, но дальше начинает накапливаться.

Как я решаю ошибки через Claude

Вместо ручного поиска:

  1. Вставляешь лог ошибки
  2. Добавляешь инструкцию:

Не переписывай весь код, напиши отдельно что нужно добавить,
понятно как новичку, с конкретными шагами

Результат:

  • анализ стек-трейса
  • точечные правки
  • без разрушения проекта

Без этой инструкции модель часто пытается «переписать всё».

Сравнение моделей

На практике:

  • Claude — лучше для ведения проекта
  • ChatGPT — лучше для точечных задач

Разница не в «лучшести», а в подходе:

  • один — про процесс
  • другой — про быстрые решения

Деплой

Claude обычно даёт базовые шаги:

  • создать виртуальное окружение
  • установить зависимости
  • запустить бота

Это работает, но:

  • могут быть проблемы с путями
  • правами доступа
  • сервером

Финальная настройка почти всегда требует ручного контроля.

Плюсы и минусы вайбкодинга

Плюсы

  • высокая скорость
  • быстрый старт
  • меньше рутины

Минусы

  • нужно понимать код
  • возможны скрытые ошибки
  • сложнее поддержка без контроля

Как с этим работать нормально

Рабочий подход:

  • разбивай задачи на части
  • не пиши огромные запросы
  • контролируй формат ответа
  • читай код

Фраза вроде:

“не переписывай код, а добавь изменения”

— резко повышает качество взаимодействия.

Заключение

Вайбкодинг — это не замена разработчика.

Это инструмент ускорения.

Claude:

  • помогает собрать проект
  • предлагает структуру
  • берёт на себя рутину

Но итог всегда зависит от тебя:
насколько ты понимаешь и контролируешь процесс.

Новый уровень

Следующий шаг — автоматизация разработки.

Я сделал Telegram-бота, который:

  • генерирует ботов под ключ
  • с ИИ или без
  • по описанию идеи

Что он делает:

  • создаёт структуру проекта
  • добавляет логику
  • настраивает БД
  • подключает logging
  • формирует .env, README, зависимости

Результат:

  • ZIP или набор файлов
  • запуск за несколько минут

Ты управляешь не кодом — ты управляешь созданием ботов.

Продолжение

Это первая часть.

В следующей статье разберём:

  • UX бота
  • inline-кнопки
  • сценарии взаимодействия

Why We’re Writing This (And Why Now)

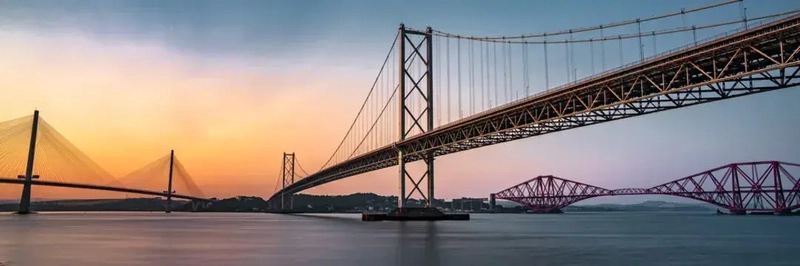
The three Forth bridges at sunset — Queensferry Crossing, Forth Road Bridge, and Forth Bridge spanning the Firth of Forth

The three Forth bridges at sunset — Queensferry Crossing, Forth Road Bridge, and Forth Bridge spanning the Firth of Forth

In 2017, Scotland opened the Queensferry Crossing. Not because the Forth Road Bridge had failed – it hadn’t. The old bridge still stands, still carries traffic, still does the job it was designed for decades ago. But the demands had changed. The volume of traffic, the weight of modern vehicles, the expectations of what a crossing should handle – the original bridge couldn’t grow into that future. So they built a new one alongside it.

We found ourselves thinking about that bridge quite a lot last year.

The System That Works

At Tribepad, we have a product that works. Customers use it daily. It’s reliable, it’s popular, and it does what recruitment software needs to do. We’re not writing this because we escaped from something broken.

But if you’ve ever maintained software that evolved over a decade, you’ll recognise the pattern. Procedural PHP that grew into Laravel. Twig templates sitting next to Smarty, sitting next to React components, sitting next to Vue. Each layer made sense at the time. Each decision was reasonable given what we knew then.

The system isn’t bad. It’s just… full. Every feature touches three different paradigms. Every change requires archaeology. Bespoke permissions and customer-specific branches that seemed manageable at ten clients become labyrinthine at a hundred. The velocity slows not because anyone made mistakes, but because the structure wasn’t built for this scale.

And then there’s the thing nobody planned for: we weren’t building for a world where AI could help us write, review, and maintain code.

The Moment Everything Shifted

We’d been watching AI tooling evolve for years. Copilot suggesting autocomplete. ChatGPT explaining stack traces. Interesting, occasionally useful, not transformative.

Then something changed. The suggestions got better. The context windows got larger. The tools started understanding not just syntax but intent. And we noticed a pattern during experiments: AI assistance was dramatically more effective on well-structured code.

Not clever code. Not complex abstractions. Just code with clear boundaries. Consistent patterns. Explicit types. Separation of concerns that meant context could be gathered without reading everything.

The messy corners of our legacy codebase? AI struggled. The cleaner modules? AI accelerated us noticeably.

This wasn’t about “vibe coding” – letting AI generate features while developers nod along. That path leads somewhere unpleasant, probably a production incident at 3am with nobody understanding what the code actually does. This was about AI as a genuine tool for skilled developers. The kind of tool that multiplies velocity when you know exactly what you’re building.

The realisation came gradually, over dog walks and too many coffees: if we structured things deliberately, AI could help us move faster. And if we were going to restructure anyway, why patch the old bridge? Why not build the crossing we actually needed?

Writing for Two Audiences

We made a decision early: this new architecture would be written for two audiences.

The first audience is obvious – developers. Us, today. Future team members who’ll inherit this codebase. The patterns need to be learnable, the conventions consistent, the reasoning documented.

The second audience is less obvious but equally important: AI assistants.

Not because we think AI replaces developers. It doesn’t. But because AI that understands your codebase is dramatically more useful than AI that’s guessing. So we write detailed CLAUDE.md files. We enforce strict typing. We maintain clear module boundaries. We document not just what the code does, but why we chose this approach over alternatives.

It sounds like overhead. In practice, it’s an investment that pays back constantly. The AI makes better suggestions. New developers onboard faster. The documentation that helps AI also helps humans. Turns out writing clearly for machines forces you to write clearly, full stop.

The Four Pillars

We kept encountering false trade-offs. Enterprise software that was accessible or fast. Maintainable or feature-rich. Scalable or developer-friendly. As if quality was a zero-sum game where you had to sacrifice something.

We decided to reject the premise.

Performance – Not as an afterthought or an optimisation pass before release. Baked into the architecture. Lazy loading by default. Bundle splitting that happens automatically. The kind of speed that doesn’t require heroics because the structure makes slowness difficult.

Scalability – Not “we’ll cross that bridge when we come to it.” Built for multi-tenant enterprise from day one. Microservice-separable architecture even if we’re not splitting services yet. The ability to grow without rewriting, because we’ve done enough rewrites.

Accessibility – This one’s personal. I’ve spent time with people who rely on screen readers, who navigate with keyboards alone, who need high contrast or different colour palettes to use software at all. I’ve watched them struggle with websites that technically passed audits but were practically unusable.

We build recruitment software. The point is helping people find jobs. If someone can’t complete an application because we couldn’t be bothered with proper focus management, that’s on us. That’s a person who didn’t get a fair shot because we were lazy. “Fairer, faster, better hiring” isn’t just the company tagline – it’s a constraint that shapes every component we build.

Maintainability – Code that teaches itself. Patterns so consistent that understanding one module means understanding them all. Tests that catch regressions before they ship. Documentation that stays current because it’s part of the development process, not an afterthought someone writes reluctantly before a release.

Four pillars. Not four options where you pick two.

Why Document This Publicly

The architecture we’re building isn’t specific to recruitment software. The patterns – multizone micro-frontends, accessible component libraries, event-driven systems, multi-tenant theming – they’re applicable anywhere you’re building enterprise software that needs to scale.

We learned from others who documented their decisions. Now it’s our turn.

This blog series is partly for the developer community. Here’s what we tried, here’s what worked, here’s what we’d do differently. Take what’s useful, ignore what isn’t, improve on our approaches.

It’s partly for our team. When someone joins six months from now and wonders why we structured authentication this way, the reasoning is documented. Not just what we built, but the trade-offs we considered and rejected.

And it’s partly for anyone who cares how their software is built. Not every customer reads technical blogs. But for those who do, for those who want to know that the platform they’re trusting with their hiring actually considered accessibility and security and maintainability – here’s the evidence.

What’s Coming

This is the first post in an ongoing series. We’ll cover architecture decisions like why we split one application into five independent zones. Component library philosophy – building accessible primitives that don’t make you choose between delight and inclusion. The event system that decouples everything. How we structured code so AI assistants can genuinely help.

Each post follows a simple pattern: here’s the problem, here’s what we considered, here’s what we built, here’s what we learned. No fluff, no self-congratulation, just reasoning you can evaluate and adapt.

Some of it will be wrong. We’ll find better approaches. When we do, we’ll document those too. This isn’t a monument to our brilliance – it’s a journal of decisions made with the best information we had at the time.

The Bridge We’re Building

The Forth Road Bridge still works. It still carries traffic. Nobody demolished it when the Queensferry Crossing opened – they just redirected the demands it couldn’t handle.

That’s roughly our situation. The legacy system continues. Customers depend on it. But alongside it, we’re building something that can handle what’s coming. Enterprise scale. AI-assisted development. Accessibility that isn’t an afterthought. The kind of architecture you’d design if you knew then what we know now.

We’re writing this because we hope it helps someone. Maybe you’re facing the same decision – patch forever or build fresh. Maybe you’re wrestling with accessibility in a codebase that wasn’t designed for it. Maybe you’re wondering how to structure code so AI tooling actually helps rather than hallucinates.

We don’t have all the answers. But we’ve got some decisions we’re confident about, some experiments that worked, and some failures that taught us things. Seems worth sharing.

The dogs heard a lot about software architecture on our walks this year. Now it’s your turn.

Technical Notes

This post is part of the “Architecting for Everything” series, documenting the frontend architecture decisions for a modern enterprise application.

Coming up:

  • Multizone architecture and why we split into independent deployable zones
  • Component library philosophy with React Aria primitives
  • Accessibility patterns that don’t compromise on design
  • Event-driven systems for decoupled, testable code
  • AI-assisted development practices that actually work

All code and patterns discussed in this series are production implementations, not theoretical exercises.

A Note on How This Was Written

In the spirit of transparency – and because it rather proves the point – this blog series was written with AI assistance. The ideas, experiences, and architectural decisions are mine. The writing style was sculpted through detailed guidelines to match how I’d explain things if I were better at putting words together. I’m an architect, not a writer, and keeping with the bridge analogy, AI helps bridge that gap.

Every post has been checked for accuracy against the actual codebase and reviewed by a colleague before publishing. Nothing here is AI hallucination dressed up as expertise. But the fluency? The structure? That’s AI doing what we’ve been talking about: multiplying the output of someone who knows what they want to say but struggles with saying it.