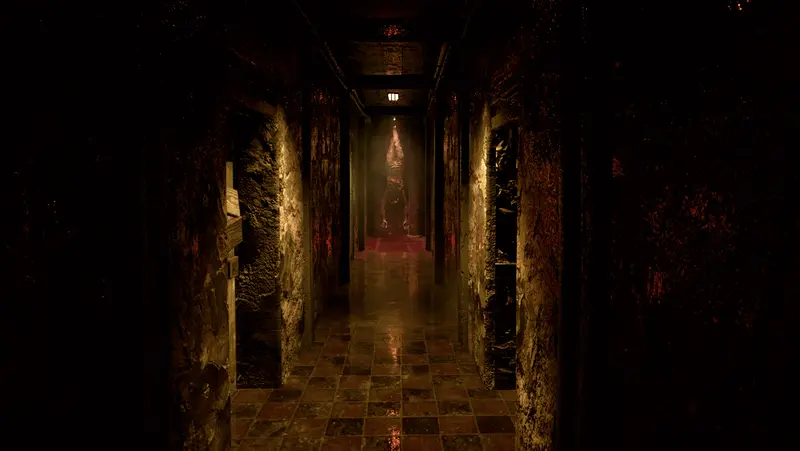
Fire and Ashes — our new immersive horror that hears you

**Fire and Ashes **is an immersive horror experience where madness and reality intertwine, and every sound can give you away. The monsters hear your screams… even beyond the hospital.

📌 1977. Henry Grey wakes up in the Paul Staderbeiger Psychiatric Hospital. Haunted by the ghosts of his past, he finds himself in a place where everything around him becomes harder and harder to explain.

The hospital is only the beginning. Henry descends into distorted worlds where fear, memories, and reality merge into one.


Exploring ruined corridors and the strange spaces beyond them, he gradually uncovers the truth about his past — a truth that may be worse than any nightmare.

Key Features:

  • Advanced voice integration — the game reacts to your breathing, whispers, and screams
  • Use your voice to survive — hide, distract enemies, or provoke them
  • Constant tension — enemies can hear you and will hunt you down
  • Journey beyond the hospital into worlds where logic breaks down
  • Survival and combat using whatever you can find
  • Exploration, puzzles, and gradual story discovery
  • Uncertainty of reality — is this still real, or pure madness?
  • The demo is already available.

Modifying Tables in SQL using ALTER

1. Making a Column NOT NULL

Suppose we already created a customers table, but now we want to ensure that email is always provided.

ALTER TABLE customers ALTER COLUMN email SET NOT NULL;

2. Adding UNIQUE Constraint

To make sure no two users have the same username:

ALTER TABLE users
ADD CONSTRAINT unique_username UNIQUE (username);

3. Adding CHECK Constraint

We want to ensure product price is always greater than 0:

ALTER TABLE products
ADD CONSTRAINT check_price CHECK (price > 0);

4. Setting DEFAULT Value

To make status = 'pending' by default:

ALTER TABLE orders
ALTER COLUMN status SET DEFAULT 'pending';

5. Adding a Column with Constraints

Now we add a salary column to employees:

ALTER TABLE employees
ADD COLUMN salary DECIMAL(10,2) NOT NULL CHECK (salary > 10000);

6. Modifying Foreign Key with CASCADE

To automatically delete employees when a department is deleted:

ALTER TABLE employees
DROP CONSTRAINT employees_department_id_fkey;

ALTER TABLE employees
ADD CONSTRAINT employees_department_id_fkey
FOREIGN KEY (department_id)
REFERENCES departments(id)
ON DELETE CASCADE;

7. Dropping a CHECK Constraint

To remove the balance restriction:

ALTER TABLE accounts
DROP CONSTRAINT accounts_balance_check;
d accounts;

8. Adding Composite UNIQUE Constraint

To ensure a combination is unique:

ALTER TABLE payments
ADD CONSTRAINT unique_user_transaction
UNIQUE (user_id, transaction_id);

I was tired of manual SQL introspection, so I built Legacy Lens (MCP Server)

We’ve all been there. You’re staring at a legacy database. 400 tables. Cryptic column names like FLG_Z_99. No documentation. You try to explain it to an AI agent like Claude or Cursor, and it starts hallucinating JOINs that don’t exist.

I was tired of copy-pasting DDL exports and manually explaining schemas. So, I built Legacy Lens.

The Problem: The “Context Gap”

AI models are smart, but they are “blind” to your local infrastructure. To make an LLM actually useful for database engineering, it needs more than just a connection string; it needs a semantic map of the data.

In a world of “AI Wrappers,” we often forget that the bottleneck isn’t the AI’s intelligence—it’s the precision of the context we provide.

The Solution: Model Context Protocol (MCP)

I decided to leverage the Model Context Protocol. Instead of a simple wrapper, I built a dedicated introspection engine that acts as the AI’s “eyes” inside the database.

What Legacy Lens does:

  • Deep Introspection: It doesn’t just list tables. It maps foreign keys, schemas, and constraints across PostgreSQL, MySQL, SQLite, and MS SQL Server.
  • Smart Sampling: It provides 5-10 sample rows per call. This gives the AI the “vibe” of the data (date formats, nullability, categorical values) without blowing up the context window.
  • Security First: I implemented a “Least Privilege” approach. The server defaults to READ ONLY transactions and provides SQL snippets to help users create restricted database roles.

Architecture: Why I split the logic

I care about modularity and reusability. I didn’t just build one monolithic script. I split the project into two scoped NPM packages:

  1. @legacy-lens/db-introspect: A standalone, dialect-agnostic library. You can use it for migrations, custom dashboards, or any tool that needs to “understand” a DB structure without the AI part.
  2. @legacy-lens/mcp-server: The bridge. It uses the introspection layer to expose tools (list_tables, describe_table, sample_rows) to any MCP-compliant client like Cursor, Claude Desktop, or custom agents.

Try it out

If you’re dealing with a database that makes you want to quit your job, give this a spin:

npx @legacy-lens/mcp-server

I’m currently looking for feedback on which engine to support next. Oracle? (Only if I’m feeling particularly brave).

Check out the project on GitHub:

GitHub logo

baqqa
/
LegacyLens

An MCP that allows to search you’re db with you’re AI

Legacy Lens

Legacy Lens is an MCP (Model Context Protocol) server that lets AI assistants in Cursor and other hosts inspect legacy SQL databases safely. It answers questions about structure and sample data: schemas, tables, columns, foreign keys, and a small number of sample rows per request (default 5, maximum 10). It is meant for understanding old systems before you change them—not for arbitrary read/write SQL from the model.

Supported databases: PostgreSQL, MySQL / MariaDB, SQLite, Microsoft SQL Server. Oracle is not supported.

Install (npm)

You need Node.js 20+.

npm install -g @legacy-lens/mcp-server

If the package is not yet on the public registry, install from your team’s tarball, GitHub Packages, or private registry the same way you install other scoped packages.

After install, the legacy-lens-mcp command is available. The MCP host must run it with no arguments (stdio mode). Subcommands are only for setup from a…

What’s missing in your current JSON log filtering setup?

I debug microservice logs daily and kept running into the same gaps with existing tools — hl, humanlog, lnav all pretty-print JSON well but none of them let me
trace a full request flow across services with a single pattern, or save my filter setup between sessions.

Built something that solves these specifically and wanted to get feedback from people who deal with this daily before I invest more time into it.

Three things I built around:

  • Hier path filter: –hier “payment.**” to trace an entire flow across services instead of grepping service by service
  • Named profiles: tired of retyping –service X –level warn –hier “Y” every session
  • TTL noise suppression: kills repeated log spam by fingerprinting message patterns, not exact strings

Genuinely curious whether these match real pain points or if I’m solving the wrong problems. What does your log debugging workflow actually look like? What do you reach for and what frustrates you about it?

If anyone wants to poke at it and tell me what’s broken or missing, happy to share access. it would be helpful to get real feedback from people who live in logs.
I’m doing a beta right now and it’s completely free at https://bearking11.gumroad.com/l/logr.
Would really appreciate any feedback on whether it actually helps the devs.

How to Store Secrets in the Mac Keychain (and Use Them Like Environment Variables)

I used to keep API keys in .env because it was fast. Then I caught myself grepping my home folder for something unrelated and watching paths scroll past that file, or almost committing a backup copy. None of that is catastrophic every time, but it’s a bad habit. On a Mac you already have a place meant for secrets: Keychain.

This isn’t a pitch for a fancy secrets vault. It’s about the security tool that ships with macOS—handy for local dev tokens, DB URLs, signing keys, that sort of thing.

One thing to get straight up front: Keychain doesn’t literally store “environment variables.” It stores items (usually generic passwords) keyed by service name and account. You pull the value out with security and export it when you need it. Day to day it behaves like env vars; under the hood it’s a lookup, not a magic .env replacement.

You’ll need a Mac, a terminal, and if you want secrets to load automatically, willingness to touch ~/.zshrc or similar.

Save and read a secret

Add a generic password (Terminal may ask for Keychain permission the first time):

security add-generic-password 
  -a "$USER" 
  -s "myapp-dev-api-key" 
  -w "sk_live_xxxxxxxx"
  • -a — account; often your macOS username or an app name.
  • -s — service string; this is the handle you’ll use later. Make it unique, e.g. myapp-dev-api-key.
  • -w — the secret. The problem is anything after -w can land in shell history (see below).

Read it (prints to stdout):

security find-generic-password -s "myapp-dev-api-key" -w

Use it as an env var for this shell only:

export MYAPP_API_KEY="$(security find-generic-password -s "myapp-dev-api-key" -w)"

After that, anything that reads MYAPP_API_KEY behaves as if you’d sourced a .env—except the value never had to live in a plaintext file on disk.

Avoiding shell history when you add the secret

Apple’s own usage text says bluntly that -p / -w on the command line is insecure. Two patterns that actually work:

Built-in prompt (often the nicest): put -w last and omit the value. security will prompt for the password; that path doesn’t shove the secret into your history the way -w "secret" does.

security add-generic-password -a "$USER" -s "myapp-dev-api-key" -w

(When it asks, type or paste the secret; it’s the usual “no echo” style prompt.)

Shell-side prompt if you prefer to stay in bash/zsh:

printf 'Paste secret (hidden): '
read -rs SECRET
echo
security add-generic-password -a "$USER" -s "myapp-dev-api-key" -w "$SECRET"
unset SECRET

Keychain Access still counts: File → New Password Item… and line up the fields with whatever you pass as -a / -s so find-generic-password can find the item later.

Wiring it into how you actually work

Every new terminal (Zsh snippet in ~/.zshrc):

export MYAPP_API_KEY="$(security find-generic-password -s "myapp-dev-api-key" -w 2>/dev/null)"

2>/dev/null just keeps noise down if the item doesn’t exist yet.

Per project, a small scripts/load-secrets.sh that exports what that repo needs is reasonable—don’t commit values; document the service names in the README so someone else can add their own copy to Keychain.

One shot:

MYAPP_API_KEY="$(security find-generic-password -s "myapp-dev-api-key" -w)" uv run python -m myapp

What you gain, what you’re signing up for

You lose the plaintext secret sitting in .env (and in a lot of accidental greps and backups). It’s built in, no extra install, and Keychain can nudge or block access per app if you tune Access Control on the item. For “this laptop only” dev keys, that’s often plenty.

The flip side is boring but real: Linux and Windows won’t help you here—those teammates need 1Password CLI, Doppler, SOPS, cloud IAM, whatever your team standard is. There’s no automatic team sync; new machine usually means re-adding items (iCloud Keychain exists but that’s a deliberate trust choice). If you echo secrets or log them, you’ve undone the point. CI wants provider-native secrets, not interactive Keychain. Onboarding is also slightly worse than “copy .env.example”—people need the exact service strings and commands written down somewhere.

I still reach for this for solo Mac dev and small personal projects where I want fewer sensitive files lying around. For shared, audited, rotated secrets at work, use the thing your platform team points you at.

So: you store with security, load with export and $(security find-generic-password … -w), and you get env-var ergonomics without a plaintext .env for that value. The cost is macOS-only, a bit more documentation, and discipline around history and logging.

Telegram Bridges for Gemini CLI and Codex After Hitting Claude Code Limits

Claude Code usage limits forced me into an annoying realization: the thing I had become dependent on was not just the model. It was the workflow.

Once you get used to sending work to an agent from your phone, waiting for the reply, then sending the next step while you are away from your desk, normal terminal-only usage starts to feel primitive. So instead of waiting for official remote workflows to improve, I built a small Telegram bridge for two tools I already had locally:

  • Gemini CLI
  • Codex

This is not a polished platform. It is a local-first workaround. But it brought back the async loop I actually cared about.

The problem was not “which model”

Claude Code Channels changed how I work on side projects.

I could be in a cafe, walking outside, or traveling, and still move a repo forward from Telegram. That changes the whole shape of development. You stop thinking “I need to sit down and code now” and start thinking “I can send the next instruction right now and review the result later.”

When I hit usage limits, I did not really want a different chatbot. I wanted that loop back.

Gemini CLI and Codex were already on my machine. What they did not have was the same remote, async, mobile-friendly interaction model.

So I built a bridge.

The architecture is intentionally boring

The whole thing is small:

  • a local Node.js process polls the Telegram Bot API
  • it accepts prompts from a specific chat
  • it runs Gemini CLI or Codex against a local repository
  • it sends stdout and stderr back to Telegram

That is basically it.

I ended up with two integrations:

  • codex-telegram-integration
  • gemini-telegram-integration_v2

I published the repo here:

github.com/0xkaz/codex-gemini-telegram-bridge

I like this design because it stays easy to inspect. No hosted backend. No extra control plane. No mystery service between Telegram and the machine where the repo already lives.

For this kind of tool, that matters. The simpler the chain, the easier it is to trust and debug.

Session continuity is what makes it useful

The first version could have been a dumb “Telegram to shell” relay. That would have been enough for a quick demo. It would not have been enough for actual use.

The real requirement was session continuity.

If I send a follow-up prompt, I do not want the assistant to forget what happened two messages ago. I want it to continue the current session, keep recent context, and move forward from there. Without that, the UX collapses into repetitive setup messages and wasted tokens.

That turned out to be the difference between “interesting hack” and “something I actually keep using.”

I also made plain non-command messages behave like prompts by default. I did not want to type slash commands every single time. That small choice made the Telegram chat feel much closer to a real agent interface.

Telegram formatting matters more than I expected

Raw CLI output looks much worse in chat than it does in a terminal.

That sounds trivial, but it is not. If replies wrap badly, file links are unreadable, or errors dump full stack traces into Telegram, the workflow becomes annoying fast.

So I added a few quality-of-life features:

  • typing indicators while the command is running
  • session commands like /sessions, /resume, and /reset-session
  • cleaner error summaries
  • cleanup for markdown-style file links

None of this is glamorous. All of it matters.

Gemini quota errors exposed a product problem

One of the most useful failures happened while testing the Gemini side.

I hit quota exhaustion. That exposed a bad assumption in the bridge: terminal-grade errors are acceptable in a shell, but often terrible in chat. Dumping a raw quota stack trace into Telegram is not useful. It is just noise.

So I added error summarization instead of forwarding everything blindly.

That changed how I thought about the bridge. Once a CLI tool starts replying inside Telegram, the output itself becomes part of the UX. A raw stack trace is acceptable in a terminal. In chat, it just feels broken.

What this bridge restores

It does not reproduce Claude Code Channels exactly.

What it does restore is the part I cared about most:

  • sending prompts from my phone
  • letting the machine at home do the work
  • reading a useful reply later
  • continuing in the same thread without resetting context

For side projects, that is enough.

What I would warn people about

  • This is a stopgap, not a finished platform.
  • You should strictly limit which Telegram chat is allowed to talk to it.
  • Destructive actions like commit, push, or deploy need extra care.
  • Model quotas still apply, especially on Gemini.

I would still take this over being locked back into terminal-only usage.

Why I think this category matters

I do think Gemini CLI and Codex will eventually get better official remote workflows. That feels inevitable.

But “eventually” is not very useful when the workflow break is happening right now.

This bridge is exactly the kind of engineering I like: not the final version, not especially elegant, but good enough to restore a missing capability immediately.

If you got used to Claude Code Channels and want something similar for Gemini CLI or Codex today, a local-first Telegram bridge is a surprisingly practical answer.

HPE Morpheus Enterprise & VM Essentials SAML Integration with Keycloak: A Complete Technical Guide

1. Introduction

1.1 What is SAML 2.0?

SAML (Security Assertion Markup Language) 2.0 is an XML-based open standard for exchanging authentication and authorization data between two parties: an Identity Provider (IdP) that authenticates users, and a Service Provider (SP) that hosts the application. Instead of every application managing its own username/password database, SAML lets you delegate authentication to a central IdP. When a user logs in once at the IdP, they get access to all connected SPs without entering credentials again — this is Single Sign-On (SSO).

In practical terms: the user clicks “Login with SSO” on the application, gets redirected to the IdP login page, authenticates there, and is sent back to the application with a cryptographically signed XML document (the “SAML assertion”) that proves who they are and what groups they belong to.

1.2 Why Keycloak?

There are several IdP options available (Okta, Azure AD, ADFS, Ping Identity, etc.), so why Keycloak?

  • Open-source and free — No per-user licensing costs, which matters at scale
  • Self-hosted — Full control over your identity infrastructure; no dependency on external SaaS providers
  • Protocol versatility — Supports SAML 2.0, OpenID Connect, and OAuth 2.0 in a single platform
  • LDAP/AD federation — Connects directly to Active Directory without migrating users
  • Kubernetes-native — Runs well as a containerized deployment with built-in clustering
  • CNCF project — Active community, regular releases, and long-term sustainability

1.3 What We Will Build

Enterprise environments demand centralized identity management. When you operate HPE Morpheus Enterprise as your cloud management platform, integrating it with a dedicated Identity Provider (IdP) via SAML 2.0 eliminates password sprawl and gives you single sign-on (SSO) across the entire infrastructure stack.

In this post, we walk through the entire journey: understanding how Morpheus handles SAML under the hood, deploying Keycloak on Kubernetes as your IdP, wiring the two together, and diagnosing issues when things do not go as planned. Every configuration value and YAML snippet comes from a real lab deployment, so you can replicate it in your own environment.

Lab environment: Kubernetes (single-node / Minikube compatible), Keycloak 26.x, Morpheus Enterprise 8.x, Active Directory for user federation.

2. Morpheus SAML Architecture

HPE Morpheus Enterprise supports SAML 2.0 as an Identity Source type within its Administration panel. Understanding how Morpheus participates in the SAML exchange is essential before configuring anything on the Keycloak side.

📸 IMAGE: Morpheus > Login Screen

📸 IMAGE: Morpheus > Forward Keycloak Login Screen

2.1 Morpheus as a SAML Service Provider (SP)

Morpheus acts exclusively as a SAML Service Provider. It does not function as an Identity Provider itself. When a user attempts to log in via SSO, Morpheus generates a SAML AuthnRequest, redirects the browser to the configured IdP, and then consumes the SAML Response (assertion) returned by the IdP.

2.2 Key SAML Endpoints in Morpheus

When you create a SAML Identity Source in Morpheus, the platform automatically generates two critical values:

Endpoint Description
SP Entity ID A unique identifier for Morpheus as a Service Provider. Auto-generated from the hostname, e.g. https://morpheus-url/saml/<uniqueID>
SP ACS URL The callback URL where the IdP posts the SAML Response after authentication, e.g. https://morpheus-url/externalLogin/callback/<uniqueID>
Login Redirect URL The IdP’s SAML SSO endpoint where Morpheus sends the AuthnRequest
SAML Logout Redirect URL The IdP’s SAML SLO endpoint for single logout

Note: The SP Entity ID and ACS URL are generated only after you save the Identity Source for the first time. You must save first, then copy these values to configure the IdP.

2.3 SAML Request and Response Configuration

Morpheus provides granular control over how SAML requests are signed and responses are validated:

Setting Options & Description
SAML Request No Signature / Self Signed / Custom RSA Signature — Controls whether AuthnRequest messages are signed
SAML Response Do Not Validate / Validate Assertion Signature — Controls signature validation on the IdP’s assertion
POST Binding Mode ON/OFF — Uses HTTP-POST binding instead of HTTP-Redirect
Includes SAML Request Parameter Yes/No — Whether the SAML request is included in the redirect

2.4 Assertion Attribute Mappings

Morpheus maps SAML assertion attributes to internal user fields:

Morpheus Field Expected SAML Attribute
Given Name firstName
Surname lastName
Email email (or NameID)

2.5 Role Mapping Mechanism

Morpheus supports role-based access control through SAML group assertions:

Role Mapping Field Description
Default Role The role assigned to all authenticated users (e.g., Standard User)
Role Attribute Name The SAML attribute containing group/role info (e.g., groups)
Required Role Attribute Value A group name the user must belong to for authorization (e.g., mspusers)

📸 IMAGE: Morpheus > Identity Sources > Keycloak

Morpheus SAML SSO Configuration

3. Keycloak-SAML Ecosystem: How It Works

Keycloak is an open-source Identity and Access Management (IAM) solution maintained by the CNCF. It supports OpenID Connect, OAuth 2.0, and SAML 2.0 protocols natively. In our setup, Keycloak serves as the SAML Identity Provider (IdP) that authenticates users against an Active Directory backend via LDAP federation.

3.1 Core Keycloak Concepts

Concept Description
Realm A tenant-level isolation boundary. Each realm has its own users, clients, roles, and identity providers. Our realm: morpheus-lab
Client An application that delegates authentication to Keycloak. Morpheus is registered as a SAML client
User Federation Allows Keycloak to pull users from LDAP/Active Directory without duplicating credentials
Protocol Mappers Transform user attributes and group memberships into SAML assertions
Roles & Groups Realm-level and client-level roles. AD groups can be synced and mapped into assertions

3.2 SAML 2.0 Authentication Flow (SP-Initiated SSO)

The diagram below illustrates the SP-Initiated SAML SSO flow between Morpheus and Keycloak:

SAML 2.0 SP-Initiated SSO Flow Diagram

Step-by-step:

  1. The user navigates to the Morpheus login page and clicks the SSO login button.
  2. Morpheus generates a SAML AuthnRequest and redirects the user’s browser to Keycloak’s SAML endpoint: https://keycloak-server:30443/realms/morpheus-lab/protocol/saml
  3. Keycloak presents the login form. The user enters their AD credentials.
  4. Keycloak authenticates the user against the federated LDAP/AD backend.
  5. On successful authentication, Keycloak constructs a SAML Response containing signed assertions with user attributes (firstName, lastName) and group memberships (groups).
  6. Keycloak POSTs the SAML Response to the Morpheus ACS URL.
  7. Morpheus validates the assertion signature, maps attributes and roles, creates or updates the user session, and grants access.

3.3 Authentication vs Authorization

Authentication (Who are you?)

  • Keycloak acts as the authentication broker, sitting between the application (Morpheus) and the identity store (Active Directory).
  • User Federation (LDAP) allows Keycloak to verify credentials against AD without storing passwords locally. Keycloak performs LDAP BIND operations to authenticate users.
  • MFA can be layered on top through Keycloak’s authentication flow configuration.
  • Session Management: Once authenticated, Keycloak creates a session. Subsequent SAML requests within the session’s lifetime do not require re-authentication (SSO behavior).

Keycloak authentication flow diagram

Authorization (What can you do?)

  • Keycloak syncs AD groups via the LDAP Group Mapper (mspusers, apparchitech, selfservice).
  • The SAML Group List Mapper serializes group memberships into the SAML assertion as a groups attribute.
  • Morpheus reads the groups attribute and maps it to internal roles:
    • mspusers → authorized user (Required Role)
    • apparchitech → Application Architect role
    • selfservice → Self-Service User role
  • Users not in the required group are denied access even if authentication succeeds.

3.4 Single Logout (SLO) Flow

User clicks Logout → Morpheus sends LogoutRequest → Keycloak terminates session
→ Keycloak POSTs LogoutResponse to /login/auth → User lands on login page

Warning: The Logout Service POST Binding URL must be set to /login/auth (the login page), NOT the ACS callback URL. Morpheus’s ACS handler cannot process LogoutResponse objects and throws a GroovyCastException.

4. Deploying Keycloak on Kubernetes

This section walks through deploying a production-grade Keycloak cluster on Kubernetes using a single YAML manifest.

The complete Kubernetes manifest used in this guide is available on GitHub:
keycloak.yaml on GitHub

4.1 Architecture Overview

The deployment stack:

  • Keycloak StatefulSet (2 replicas) with Infinispan clustering for HA
  • PostgreSQL Deployment with PersistentVolumeClaim (10Gi)
  • Kubernetes Secret for admin and database passwords
  • Self-signed TLS certificates generated by init containers
  • NodePort Service for external HTTPS access on port 30443
  • Headless Service for Infinispan/JGroups cluster discovery

4.2 Prerequisites

Infrastructure:

  • A running Kubernetes cluster or Minikube instance
  • kubectl configured and connected to your cluster
  • At least 4GB RAM and 2 CPU cores available for the Keycloak + PostgreSQL pods
  • A storage provisioner (default StorageClass or Rook-Ceph). For Minikube, enable it with:
minikube addons enable default-storageclass
minikube addons enable storage-provisioner

Minikube users: Start Minikube with sufficient resources:
minikube start --cpus=4 --memory=8192 --driver=docker

Network & DNS requirements:

  • The Kubernetes node IP must be reachable from the Morpheus server (for SAML redirects)
  • The Morpheus server hostname (e.g., morpheus-server) must be resolvable from both the user’s browser and the Keycloak pods. If you’re using a local domain, add entries to /etc/hosts on the machines or configure your internal DNS
  • Firewall rules: Ensure these ports are open between the components:
Source Destination Port Protocol Purpose
User Browser Morpheus Server 443 HTTPS Access Morpheus UI
User Browser K8s Node 30443 HTTPS Keycloak login page (SAML redirect)
Morpheus Server K8s Node 30443 HTTPS SAML backchannel (POST binding)
K8s Pod Network AD Domain Controller 389 LDAP User federation / authentication

Active Directory requirements:

  • A dedicated service account for Keycloak LDAP binding (e.g., svc-keycloak). This account needs read-only access to the Users container (CN=Users,DC=yourdomain,DC=local). It does not need Domain Admin privileges — basic “Read all user information” permission is sufficient
  • AD groups that will map to Morpheus roles (e.g., mspusers, apparchitech, selfservice) must exist and users must be members of the appropriate groups

4.3 Step 1: Prepare Secrets

The YAML uses a Kubernetes Secret to store sensitive credentials. The passwords are Base64-encoded:

# Encode your passwords
echo -n 'YourAdminPassword!' | base64
# Output: WW91*****UGFzc3***cmQh

echo -n 'YourDBPassword!' | base64
# Output: WW9************mQh

The Secret resource in the YAML:

apiVersion: v1
kind: Secret
metadata:
  name: keycloak-secret
  namespace: keycloak
type: Opaque
data:
  admin-password: <base64-encoded-admin-password>
  db-password: <base64-encoded-db-password>

Note: Never commit plain-text passwords to version control. Use a secrets manager (Vault, Sealed Secrets) in production.

4.4 Step 2: Namespace and Storage

apiVersion: v1
kind: Namespace
metadata:
  name: keycloak
  labels:
    app.kubernetes.io/part-of: sso-stack
---
apiVersion: v1
kind: PersistentVolumeClaim
metadata:
  name: postgres-pvc
  namespace: keycloak
spec:
  accessModes: [ReadWriteOnce]
  resources:
    requests:
      storage: 10Gi

4.5 Step 3: PostgreSQL Database

Keycloak requires an external database in production mode. Key points from our manifest:

containers:
  - name: postgres
    image: postgres:17
    env:
      - name: POSTGRES_USER
        value: keycloak
      - name: POSTGRES_PASSWORD
        valueFrom:
          secretKeyRef:
            name: keycloak-secret
            key: db-password
      - name: POSTGRES_DB
        value: keycloak
      - name: PGDATA
        value: /var/lib/postgresql/data/pgdata
    readinessProbe:
      exec:
        command: ["pg_isready", "-U", "keycloak"]
      initialDelaySeconds: 10
      periodSeconds: 5
    resources:
      requests:
        memory: 256Mi
        cpu: 100m
      limits:
        memory: 512Mi
        cpu: 500m

4.6 Step 4: Keycloak StatefulSet

The Keycloak deployment uses a StatefulSet with 2 replicas for high availability.

Init Containers:

  1. wait-for-postgres: Polls PostgreSQL port 5432 before Keycloak starts
  2. generate-tls-cert: Generates a self-signed TLS certificate (10 years validity)
initContainers:
  - name: generate-tls-cert
    image: alpine:3.19
    command: ["sh", "-c"]
    args:
      - |
        apk add --no-cache openssl
        openssl req -x509 -nodes -days 3650 
          -newkey rsa:2048 
          -keyout /certs/tls.key 
          -out /certs/tls.crt 
          -subj "/CN=keycloak-morpheus-lab/O=Lab/C=TR"

Key Environment Variables:

Variable Purpose
KC_BOOTSTRAP_ADMIN_USERNAME Initial admin username (admin)
KC_BOOTSTRAP_ADMIN_PASSWORD Admin password from Secret
KC_DB / KC_DB_URL_HOST Database type and host (postgres)
KC_HTTPS_CERTIFICATE_FILE Path to TLS certificate
KC_HTTPS_CERTIFICATE_KEY_FILE Path to TLS key
KC_CACHE Clustering mode (ispn = Infinispan)
KC_HOSTNAME_STRICT Disabled for NodePort/self-signed setups
KC_FEATURES Additional features (token-exchange)
KC_HEALTH_ENABLED Enables /health/* endpoints for probes

Health Probes:

  • startupProbe: /health/started — 1s interval, 600 retries (10-minute startup window)
  • readinessProbe: /health/ready — Every 10s, 3 failures to mark unready
  • livenessProbe: /health/live — Every 10s, 3 failures to restart pod

4.7 Step 5: Services

Service Type & Purpose
keycloak (ClusterIP) Internal access: ports 8080 (HTTP) and 8443 (HTTPS)
keycloak-discovery (Headless) JGroups cluster member discovery on port 7800
keycloak-nodeport (NodePort) External access: port 30080 (HTTP) and 30443 (HTTPS)

4.8 Step 6: Deploy

# Apply the complete manifest
kubectl apply -f keycloak.yaml

# Watch the rollout
kubectl rollout status statefulset/keycloak -n keycloak --timeout=10m

# Verify all pods are running
kubectl get pods -n keycloak

# Access the admin console
# https://<node-ip>:30443/admin

Tip: For Minikube, use minikube ip to get the node IP. For a multi-node cluster, any node’s IP will work with NodePort.

📸 IMAGE: Terminal output of kubectl get pods -n keycloak showing all pods running

Terminal output of kubectl get pods -n keycloak showing all pods running

5. Keycloak-Morpheus SAML Integration Guide

With Keycloak deployed and running, we can now configure the SAML integration. The configuration involves both the Keycloak side (IdP) and the Morpheus side (SP), and the order matters.

Important — Configuration Order:
There is a chicken-and-egg situation here. Keycloak needs the SP Entity ID and ACS URL to create the SAML client, but these values are auto-generated by Morpheus only after you save an Identity Source. The correct order is:

  1. Create the Keycloak Realm and LDAP Federation first (Steps 1-2)
  2. Create a preliminary Identity Source in Morpheus to obtain the SP Entity ID and ACS URL (Step 3)
  3. Use those values to create the SAML Client in Keycloak (Steps 4-7)
  4. Come back to Morpheus and complete the Identity Source configuration (Step 8)

5.1 Step 1: Create the Keycloak Realm

  1. Log in to Keycloak Admin Console at https://keycloak-server:30443/admin
  2. Click the realm dropdown (top-left) and select “Create Realm”
  3. Set Realm Name to: morpheus-lab
  4. Click Create

📸 IMAGE: Keycloak Admin Console > Manage Realm > Create Realm

Keycloak Admin Console > Create Realm dialog

5.2 Step 2: Configure LDAP User Federation

Navigate to morpheus-lab > User Federation > Add New provider > LDAP and configure:

Setting Value
Name LAB AD
Vendor Active Directory
Connection URL ldap://active-directory:389
Bind Type simple
Bind DN CN=svc-keycloak,CN=Users,DC=domain,DC=domain
Users DN CN=Users,DC=domain,DC=domain
Username LDAP Attribute sAMAccountName
Edit Mode READ_ONLY
Import Users ON

Add Group Mapper (Mappers > Add mapper):

Setting Value
Mapper Type group-ldap-mapper
Groups DN CN=Users,DC=domain,DC=domian
Group Name LDAP Attribute cn
Membership LDAP Attribute member
Mode READ_ONLY
User Roles Retrieve Strategy LOAD_GROUPS_BY_MEMBER_ATTRIBUTE

Note: After saving, click ‘Sync all users’ and ‘Sync LDAP groups to Keycloak’ to import users and groups from Active Directory.

📸 IMAGE: Keycloak > User Federation > LAB AD settings

LDAP 1

LDAP 2

5.3 Step 3: Create Preliminary Identity Source in Morpheus (Get SP Entity ID)

Before creating the SAML client in Keycloak, we need to obtain the SP Entity ID and ACS URL from Morpheus. These values are auto-generated and unique to your Morpheus instance.

  1. Log in to Morpheus at https://morpheus-server
  2. Navigate to Administration > Identity Sources
  3. Click + Add Identity Source
  4. Set Type to SAML SSO
  5. Set Name to Keycloak-SSO
  6. For now, enter any placeholder URL in Login Redirect URL (e.g., https://placeholder.local) — we will update this later
  7. Click Save Changes

After saving, Morpheus generates and displays two critical values in the Identity Source list:

  • SP Entity ID — e.g., https://morpheus-server/saml/N3h***B***O
  • SP ACS URL — e.g., https://morpheus-server/externalLogin/callback/N***3***O

Copy both of these values! You will need them in the next step to configure the SAML client in Keycloak. The N3****BO part is a unique identifier generated by your Morpheus instance — yours will be different.

📸 IMAGE: Morpheus > Identity Sources list showing the auto-generated SP Entity ID and ACS URL

5.4 Step 4: Create the SAML Client in Keycloak

Now go back to the Keycloak Admin Console and create the SAML client using the values from the previous step:

  1. Navigate to morpheus-lab > Clients > Create Client
  2. Set Client Type to SAML
  3. Set Client ID to the SP Entity ID you copied from Morpheus: https://morpheus-server/saml/N3h**K**5**
  4. Set Name to: Morpheus Enterprise

Access Settings:

Setting Value
Root URL https://morpheus-server
Valid Redirect URIs (ACS URL) https://morpheus-server/externalLogin/callback/N3h**K**5**
Master SAML Processing URL https://morpheus-server/externalLogin/callback/N3h**K**5**
IDP-Initiated SSO URL Name morpheus

SAML Capabilities:

Setting Value
Name ID Format username
Force POST Binding ON
Include AuthnStatement ON

Signature & Encryption:

Setting Value
Sign Documents ON
Sign Assertions ON
Signature Algorithm RSA_SHA256
Client Signature Required OFF (CRITICAL!)
Encrypt Assertions OFF

Warning: Client Signature Required must be OFF. Morpheus signs requests with a self-signed certificate that does not match the certificate registered in Keycloak. If this is ON, every SAML request from Morpheus will be rejected.

📸 IMAGE: Keycloak > Clients > Morpheus Enterprise > Settings

5.5 Step 5: Configure Logout (Advanced Settings)

Navigate to Advanced tab > Fine Grain SAML Endpoint Configuration:

Setting Value
Logout Service POST Binding URL https://morpheus-server/login/auth

This is crucial! Setting this URL to /login/auth prevents the GroovyCastException bug. The Morpheus ACS callback handler cannot process SAML LogoutResponse objects.

5.6 Step 6: Configure SAML Mappers

Navigate to Client Scopes > dedicated > Mappers and add:

Mapper 1: Groups (Group List)

Setting Value
Mapper Type Group list
SAML Attribute Name groups
SAML Attribute NameFormat Basic
Single Group Attribute OFF
Full Group Path OFF

Mapper 2: firstName (User Attribute)

Setting Value
Mapper Type User Attribute
User Attribute firstName
SAML Attribute Name firstName

Mapper 3: lastName (User Attribute)

Setting Value
Mapper Type User Attribute
User Attribute lastName
SAML Attribute Name lastName

📸 IMAGE: Keycloak > Client Scopes > dedicated > Mappers list

5.7 Step 7: Copy the Realm Certificate

  1. Navigate to morpheus-lab > Realm Settings > Keys
  2. Find the RS256 key row and click the Certificate button
  3. Copy the entire certificate string

📸 IMAGE: Keycloak > Realm Settings > Keys > RS256 certificate

5.8 Step 8: Complete the Morpheus Identity Source Configuration

Now go back to the preliminary Identity Source you created in Step 3 and update it with the real values. Navigate to Administration > Identity Sources > Keycloak-SSO > Edit:

Setting Value
Login Redirect URL https://keycloak-server:30443/realms/morpheus-lab/protocol/saml
SAML Logout Redirect URL https://keycloak-server:30443/realms/morpheus-lab/protocol/saml
Includes SAML Request Parameter Yes
POST Binding Mode ON
SAML Request Self Signed
SAML Response Validate Assertion Signature
SAML Response Public Key (paste RS256 certificate from Keycloak)

Assertion Attribute Mappings:

Morpheus Field Value
Given Name Attribute Name firstName
Surname Attribute Name lastName

Role Mappings:

Morpheus Field Value
Default Role Standard User
Role Attribute Name groups
Required Role Attribute Value mspusers
Application Architect Role apparchitech
Self Service User Role selfservice

Click Save Changes.

📸 IMAGE: Morpheus > Identity Sources > Keycloak-SSO configuration

5.9 Step 9: Test the Integration

  1. Open a new browser / incognito window
  2. Navigate to https://morpheus-server
  3. Click the SSO login option (Keycloak-SSO should appear)
  4. You will be redirected to Keycloak’s login page
  5. Enter an AD username (e.g., emre.baykal) and password

6. On success, you will be redirected back to Morpheus and logged in

6. Troubleshooting SAML Integration

SAML integrations can fail silently or produce cryptic errors. This section covers the most common issues.

6.1 Diagnostic Tools

Tool Usage
SAML Tracer (Browser Extension) Captures SAML requests/responses in real-time. Available for Firefox and Chrome
Keycloak Events Enable in Realm Settings > Events. Shows auth attempts and errors
Keycloak Logs kubectl logs statefulset/keycloak -n keycloak -f
Morpheus Logs /var/log/morpheus/morpheus-ui/current
Base64 Decoder `echo ”

6.2 Common Issues and Solutions

Issue 1: ‘Invalid Requester’ Error

Symptom Keycloak returns ‘Invalid requester’ or ‘Client not found’
Cause SP Entity ID in Morpheus doesn’t match Client ID in Keycloak
Solution Copy the exact SP Entity ID from Morpheus Identity Source and use it as Client ID in Keycloak

Issue 2: Signature Validation Failure

Symptom ‘Signature validation failed’ or ‘Invalid signature’
Cause SAML Response Public Key in Morpheus doesn’t match Keycloak’s RS256 certificate
Solution Copy fresh certificate from Keycloak > Realm Settings > Keys > RS256 > Certificate. Must be updated after every Keycloak redeployment

Issue 3: User Authenticated but Access Denied

Symptom User authenticates at Keycloak but gets ‘Access Denied’ in Morpheus
Cause User not in the required group, or Group List mapper missing
Solution 1) Verify user is in {% raw %}mspusers AD group. 2) Check Group List mapper in client scopes. 3) Use SAML Tracer to verify groups attribute in assertion

Issue 4: GroovyCastException on Logout

Symptom 500 error on logout with GroovyCastException in logs
Cause LogoutResponse sent to ACS URL instead of login page
Solution Set Logout Service POST Binding URL to https://morpheus-server/login/auth in Keycloak Advanced settings

Issue 5: Login Loop / Redirect Loop

Symptom Browser keeps redirecting between Morpheus and Keycloak
Cause Mixed HTTP/HTTPS, clock skew, or invalid ACS URL
Solution 1) Ensure both use HTTPS. 2) Verify NTP sync (SAML assertions are time-sensitive). 3) Check Valid Redirect URIs matches exactly

Issue 6: Attributes Not Mapped

Symptom firstName/lastName are empty, roles not assigned
Cause SAML mappers missing or attribute names don’t match
Solution 1) Add User Attribute mappers for firstName and lastName. 2) Names are case-sensitive. 3) Use SAML Tracer to verify attributes in assertion XML

Issue 7: LDAP Users Not Appearing

Symptom No users appear after LDAP federation setup
Cause Wrong Bind DN, Users DN, or network connectivity
Solution 1) Test connectivity from pod. 2) Verify Bind DN has read access. 3) Click ‘Sync all users’. 4) Check Keycloak logs for LDAP errors

6.3 SAML Assertion Debugging Checklist

When debugging, use SAML Tracer to capture the assertion and verify:

  • NameID: Present and in expected format (username)?
  • Issuer: Matches the Keycloak realm URL?
  • AudienceRestriction: Audience matches Morpheus SP Entity ID?
  • Conditions/NotBefore/NotOnOrAfter: Valid timestamps? Check for clock skew
  • AuthnStatement: Present? (Required by Morpheus)
  • AttributeStatement: firstName, lastName, groups attributes present with correct values?
  • Signature: Assertion signed? Certificate matches?

6.4 Useful Debug Commands

# Check Keycloak pod logs
kubectl logs -f statefulset/keycloak -n keycloak

# Decode a SAML Response from browser
echo '<base64-saml-response>' | base64 -d | xmllint --format -

# Test LDAP connectivity from inside the cluster
kubectl exec -it keycloak-0 -n keycloak -- 
  sh -c 'nc -zv domain-controller 389'

# Check Keycloak health
kubectl exec -it keycloak-0 -n keycloak -- 
  curl -sk https://localhost:8443/health/ready

7. Conclusion

Integrating Morpheus Enterprise with Keycloak via SAML provides a robust, centralized authentication solution for enterprise cloud management. Key takeaways:

  • Morpheus acts as a SAML SP; Keycloak acts as the SAML IdP with AD backend
  • The Kubernetes deployment uses a StatefulSet with Infinispan clustering for HA
  • Self-signed TLS certificates are generated by init containers — no external cert-manager required for lab environments
  • Client Signature Required must be OFF in Keycloak for Morpheus compatibility
  • The Logout Service POST Binding URL must point to /login/auth to avoid the GroovyCastException bug
  • Always update the SAML Response Public Key in Morpheus after redeploying Keycloak

Have questions or ran into a different issue? Drop a comment below!

Written by Emre Baykal — March 2026

How to Test Stripe Webhooks Without Deploying Code

You’re integrating Stripe. You need to handle payment_intent.succeeded. Before you write a single line of handler code, you need to know exactly what Stripe sends.

The classic approach:

  1. Deploy a temporary endpoint with logging
  2. Configure it in Stripe Dashboard
  3. Trigger a test event
  4. Dig through logs
  5. Tweak your code, repeat

That’s 15 minutes of plumbing before you write any real logic. Every time you need to check a different event type, you do it again.

There’s a better way.

The fast approach: use a webhook inspector

A webhook inspector gives you an instant HTTPS URL. Point your webhook provider at it, trigger an event, and see the full payload — headers, body, timing — immediately in your browser. No deploy, no logging setup, no waiting.

For this walkthrough I’ll use HookTest — a free tool I built for exactly this workflow. No account required.

Step 1: Get your endpoint URL

Open HookTest and click New Endpoint. You’ll get a URL like:

https://hooktest.peakline-ops.workers.dev/w/abc123xyz

That’s it. Your endpoint is live.

Step 2: Add it to Stripe

  1. Go to Stripe Dashboard → Developers → Webhooks
  2. Click Add endpoint
  3. Paste your HookTest URL
  4. Select the events you care about — or just pick All events for exploration
  5. Click Add endpoint

Now trigger a test event. In Stripe, find the webhook you just created and click Send test webhook. Pick payment_intent.succeeded.

Step 3: See what Stripe actually sends

Switch back to HookTest. The request appears immediately:

POST /w/abc123xyz
stripe-signature: t=1711641600,v1=3c5d8f...
content-type: application/json

{
  "id": "evt_3OqABC2eZvKYlo2C1711641600",
  "object": "event",
  "api_version": "2024-04-10",
  "created": 1711641600,
  "type": "payment_intent.succeeded",
  "data": {
    "object": {
      "id": "pi_3OqABC2eZvKYlo2C1711641600",
      "object": "payment_intent",
      "amount": 2999,
      "amount_received": 2999,
      "currency": "usd",
      "status": "succeeded",
      "customer": "cus_ABC123",
      "metadata": {},
      "payment_method": "pm_1OqABC2eZvKYlo2C..."
    }
  },
  "livemode": false
}

Now you know exactly what fields exist and what types they are. Write your handler with confidence.

Step 4: Replay to your local dev server

Once your handler is written and running on localhost:3000, you don’t need to re-trigger the event in Stripe. Click Replay on the captured request, enter your local URL:

http://localhost:3000/webhooks/stripe

HookTest re-sends the exact payload with all original headers — including the Stripe-Signature header. Your local handler sees a real request.

This is the part that saves the most time. Iterate on your handler by replaying the same payload over and over, without touching Stripe each time.

What about ngrok?

ngrok tunnels traffic to your local server — useful when you want Stripe to hit localhost directly. But that means your server needs to be running and accessible before you can see anything.

Webhook inspection flips this: capture first, understand the payload, then write the handler. Use both tools for different stages:

Stage Tool
Exploring payload structure HookTest (inspect)
Iterating on your handler HookTest (replay)
End-to-end integration test ngrok / stripe listen

Stripe-specific tips

Verify signatures in your handler. Every Stripe webhook includes a Stripe-Signature header. Your handler should validate it:

const stripe = require('stripe')(process.env.STRIPE_SECRET_KEY);

app.post('/webhooks/stripe', express.raw({ type: 'application/json' }), (req, res) => {
  const sig = req.headers['stripe-signature'];

  let event;
  try {
    event = stripe.webhooks.constructEvent(req.body, sig, process.env.STRIPE_WEBHOOK_SECRET);
  } catch (err) {
    return res.status(400).send(`Webhook Error: ${err.message}`);
  }

  switch (event.type) {
    case 'payment_intent.succeeded':
      const paymentIntent = event.data.object;
      // fulfill order
      break;
  }

  res.json({ received: true });
});

Note: When replaying from HookTest, the signature won’t verify unless you disable signature checking in dev mode — that’s fine for development. In production, always verify.

Watch for event versions. Stripe sends api_version in every event. If your Stripe account is on a different API version than what you’re testing, the payload shape can differ. Check this in your Stripe Dashboard under Developers → API keys.

Other webhook providers

This exact workflow works with any webhook-based API:

Provider Where to configure Test event trigger
GitHub Settings → Webhooks “Redeliver” button
Shopify Partners → App → Webhooks Test notification
Twilio Console → Phone Numbers Use ngrok + real SMS
Slack App config → Event Subscriptions Slash command or action
SendGrid Settings → Mail Settings → Event Webhook Send a test email

Summary

The next time you need to integrate a webhook:

  1. Open HookTest → get an endpoint URL (5 seconds, no account)
  2. Paste it into your provider’s webhook config
  3. Trigger a test event → see the full payload immediately
  4. Write your handler with real field names and types
  5. Replay from HookTest → iterate without re-triggering the source

No deploy cycle. No log parsing. No guessing.

Try HookTest free →

Built HookTest because I was tired of re-deploying logging endpoints every time I integrated a new webhook provider. The free tier is genuinely useful — no account, no credit card, 100 requests before anything expires.

Claude Dispatch Tutorial: Control Your MacBook Remotely from iPhone (OpenClaw Alternative)

Claude Dispatch lets you remotely control your MacBook from your iPhone using Anthropic’s Computer Use feature. Unlike traditional remote desktop tools, you give natural language commands — and Claude AI executes them on your machine. It’s a powerful alternative to OpenClaw with smarter, AI-driven automation.

TL;DR

  • Remote Control: Control your MacBook from your iPhone using Claude AI’s Computer Use
  • OpenClaw Alternative: Natural language commands instead of script-based automation
  • Easy Setup: Install Claude Desktop app, enable Computer Use, connect your iPhone

What is Claude Dispatch?

Claude Dispatch is Anthropic’s approach to remote computer control. Instead of mirroring your screen and tapping buttons manually (like traditional remote desktop), you tell Claude what to do in plain English — and it executes the task on your MacBook.

This is a fundamentally different approach from tools like OpenClaw. You’re not remotely controlling a mouse cursor — you’re delegating tasks to an AI agent.

Claude Dispatch vs OpenClaw

Feature Claude Dispatch OpenClaw
AI Integration Advanced Claude AI Basic automation
Command Interface Natural language Script-based
Setup Complexity Moderate Simple
Automation Level Intelligent Rule-based

How to Set Up Claude Dispatch

Step 1: Install Claude Desktop App

Download and install the Claude Desktop application on your MacBook. This is the foundation that enables the Computer Use feature.

Step 2: Enable Computer Use

Configure Computer Use settings to allow communication between your devices. This establishes secure remote access.

Step 3: Connect Your iPhone

Link your iPhone through the Claude interface for seamless command execution from mobile.

Real-World Use Cases

  • Access your IDE and run code remotely
  • Execute deployment scripts from anywhere
  • Manage files and organize project directories
  • Monitor system resources while away from your desk

Watch the Full Setup + Demo

The video walks through 3 live scenarios:

  1. Remote code repository access
  2. System administration tasks
  3. Automated multi-step workflows

Should You Switch from OpenClaw?

If you want basic, reliable remote control — OpenClaw works fine.

If you want intelligent automation where you describe what you want and AI handles the execution — Claude Dispatch is the better choice. The natural language interface makes complex tasks trivial.

Conclusion

Claude Dispatch is a glimpse into the future of developer productivity — AI agents that control your computer on your behalf. For software engineers who work remotely or need mobile access to their dev environment, it’s worth trying.

Originally published at prograamer.com. Follow me for more AI tool tutorials!

Streaming AI Responses in Flutter: Beyond setState and into StreamBuilder

Most Flutter developers build AI chat interfaces like regular chat apps. They collect the full response, then display it all at once. But AI responses aren’t like human messages—they stream in token by token, creating that characteristic “typing” effect that users expect from ChatGPT, Claude, and other AI assistants.

The problem isn’t just user experience. When you wait for complete responses before updating your UI, users stare at loading spinners for 10-20 seconds. They assume your app is frozen and start tapping frantically. Meanwhile, your AI provider is already streaming the first words of the answer.

I’ve seen Flutter developers try to solve this with setState, updating the UI every time a new token arrives. The result? Janky animations, dropped frames, and chat bubbles that grow and shrink unpredictably. There’s a better way.

The setState Trap

Here’s how most developers first attempt streaming AI responses:

class ChatScreen extends StatefulWidget {
  @override
  _ChatScreenState createState() => _ChatScreenState();
}

class _ChatScreenState extends State<ChatScreen> {
  String currentResponse = '';

  void sendMessage() async {
    final stream = openAI.sendMessageStream('Hello, AI!');

    await for (final token in stream) {
      setState(() {
        currentResponse += token; // This triggers rebuild on every token
      });
    }
  }

  @override
  Widget build(BuildContext context) {
    return Column(
      children: [
        // Chat history
        ChatBubble(text: currentResponse), // Rebuilds constantly
      ],
    );
  }
}

This approach has three major problems:

  1. Performance: setState rebuilds the entire widget tree on every token
  2. Visual glitches: Chat bubbles resize constantly, causing layout shifts
  3. Lost scroll position: ListView jumps around as content changes

Every token arrival triggers a full rebuild. If your AI streams 100 tokens, that’s 100 widget rebuilds for a single response.

StreamBuilder: The Right Tool for Streaming Data

Flutter gives us StreamBuilder specifically for handling streaming data. Instead of managing state manually, let StreamBuilder subscribe to your AI response stream and rebuild only the relevant parts of your UI.

class StreamingChatBubble extends StatelessWidget {
  final Stream<String> responseStream;

  const StreamingChatBubble({required this.responseStream});

  @override
  Widget build(BuildContext context) {
    return StreamBuilder<String>(
      stream: responseStream,
      initialData: '',
      builder: (context, snapshot) {
        final text = snapshot.data ?? '';

        return Container(
          padding: EdgeInsets.all(12),
          margin: EdgeInsets.symmetric(vertical: 4, horizontal: 8),
          decoration: BoxDecoration(
            color: Colors.grey[100],
            borderRadius: BorderRadius.circular(12),
          ),
          child: Column(
            crossAxisAlignment: CrossAxisAlignment.start,
            children: [
              Text(
                text,
                style: TextStyle(fontSize: 16),
              ),
              if (snapshot.connectionState == ConnectionState.waiting)
                Container(
                  margin: EdgeInsets.only(top: 8),
                  child: Row(
                    children: [
                      SizedBox(
                        width: 12,
                        height: 12,
                        child: CircularProgressIndicator(strokeWidth: 2),
                      ),
                      SizedBox(width: 8),
                      Text(
                        'AI is typing...',
                        style: TextStyle(
                          fontSize: 12,
                          color: Colors.grey[600],
                        ),
                      ),
                    ],
                  ),
                ),
            ],
          ),
        );
      },
    );
  }
}

This StreamBuilder approach gives you:

  • Isolated rebuilds: Only the chat bubble rebuilds, not the entire screen
  • Connection state awareness: Show typing indicators while streaming
  • Error handling: Built-in error states for network issues
  • Clean completion: Automatically stops listening when stream closes

Building a Complete Streaming Chat Interface

Let’s build a complete chat interface that handles multiple streaming responses elegantly. We’ll use a combination of StreamBuilder for active responses and a regular list for completed messages.

class StreamingChatInterface extends StatefulWidget {
  @override
  _StreamingChatInterfaceState createState() => _StreamingChatInterfaceState();
}

class _StreamingChatInterfaceState extends State<StreamingChatInterface> {
  final TextEditingController _controller = TextEditingController();
  final List<ChatMessage> _messages = [];
  Stream<String>? _currentResponseStream;

  void _sendMessage() async {
    final userMessage = _controller.text.trim();
    if (userMessage.isEmpty) return;

    setState(() {
      _messages.add(ChatMessage(
        text: userMessage,
        isUser: true,
        isComplete: true,
      ));
      _controller.clear();
    });

    // Start streaming AI response
    final responseStream = _getAIResponseStream(userMessage);
    setState(() {
      _currentResponseStream = responseStream;
    });

    // Collect the complete response
    String completeResponse = '';
    await for (final token in responseStream) {
      completeResponse += token;
    }

    // Replace streaming response with final message
    setState(() {
      _currentResponseStream = null;
      _messages.add(ChatMessage(
        text: completeResponse,
        isUser: false,
        isComplete: true,
      ));
    });
  }

  Stream<String> _getAIResponseStream(String prompt) async* {
    // Simulate AI response streaming
    final words = 'This is a simulated AI response that streams word by word to demonstrate the streaming chat interface.'.split(' ');

    for (int i = 0; i < words.length; i++) {
      await Future.delayed(Duration(milliseconds: 100));
      if (i == 0) {
        yield words[i];
      } else {
        yield ' ${words[i]}';
      }
    }
  }

  @override
  Widget build(BuildContext context) {
    return Scaffold(
      appBar: AppBar(title: Text('Streaming AI Chat')),
      body: Column(
        children: [
          Expanded(
            child: ListView.builder(
              reverse: true,
              itemCount: _messages.length + (_currentResponseStream != null ? 1 : 0),
              itemBuilder: (context, index) {
                // Show streaming response at the top
                if (index == 0 && _currentResponseStream != null) {
                  return StreamingChatBubble(
                    responseStream: _currentResponseStream!,
                    isUser: false,
                  );
                }

                // Show completed messages
                final messageIndex = _currentResponseStream != null ? index - 1 : index;
                final message = _messages[_messages.length - 1 - messageIndex];

                return ChatBubble(
                  text: message.text,
                  isUser: message.isUser,
                );
              },
            ),
          ),
          Container(
            padding: EdgeInsets.all(16),
            child: Row(
              children: [
                Expanded(
                  child: TextField(
                    controller: _controller,
                    decoration: InputDecoration(
                      hintText: 'Type a message...',
                      border: OutlineInputBorder(
                        borderRadius: BorderRadius.circular(20),
                      ),
                    ),
                    onSubmitted: (_) => _sendMessage(),
                  ),
                ),
                SizedBox(width: 8),
                FloatingActionButton(
                  onPressed: _sendMessage,
                  mini: true,
                  child: Icon(Icons.send),
                ),
              ],
            ),
          ),
        ],
      ),
    );
  }
}

class ChatMessage {
  final String text;
  final bool isUser;
  final bool isComplete;

  ChatMessage({
    required this.text,
    required this.isUser,
    required this.isComplete,
  });
}

class StreamingChatBubble extends StatelessWidget {
  final Stream<String> responseStream;
  final bool isUser;

  const StreamingChatBubble({
    required this.responseStream,
    required this.isUser,
  });

  @override
  Widget build(BuildContext context) {
    return StreamBuilder<String>(
      stream: responseStream,
      initialData: '',
      builder: (context, snapshot) {
        return ChatBubble(
          text: snapshot.data ?? '',
          isUser: isUser,
          isStreaming: snapshot.connectionState == ConnectionState.active,
        );
      },
    );
  }
}

class ChatBubble extends StatelessWidget {
  final String text;
  final bool isUser;
  final bool isStreaming;

  const ChatBubble({
    required this.text,
    required this.isUser,
    this.isStreaming = false,
  });

  @override
  Widget build(BuildContext context) {
    return Container(
      margin: EdgeInsets.symmetric(vertical: 4, horizontal: 16),
      child: Row(
        mainAxisAlignment: isUser ? MainAxisAlignment.end : MainAxisAlignment.start,
        children: [
          Flexible(
            child: Container(
              padding: EdgeInsets.symmetric(horizontal: 16, vertical: 12),
              decoration: BoxDecoration(
                color: isUser ? Colors.blue[500] : Colors.grey[200],
                borderRadius: BorderRadius.circular(16),
              ),
              child: Column(
                crossAxisAlignment: CrossAxisAlignment.start,
                children: [
                  Text(
                    text,
                    style: TextStyle(
                      color: isUser ? Colors.white : Colors.black87,
                      fontSize: 16,
                    ),
                  ),
                  if (isStreaming)
                    Container(
                      margin: EdgeInsets.only(top: 8),
                      child: SizedBox(
                        width: 12,
                        height: 12,
                        child: CircularProgressIndicator(
                          strokeWidth: 2,
                          valueColor: AlwaysStoppedAnimation<Color>(
                            isUser ? Colors.white : Colors.grey[600]!,
                          ),
                        ),
                      ),
                    ),
                ],
              ),
            ),
          ),
        ],
      ),
    );
  }
}

Performance Considerations and Best Practices

When implementing streaming AI responses, keep these performance tips in mind:

1. Debounce Token Updates

If your AI provider sends tokens very rapidly, consider debouncing updates to avoid excessive rebuilds:

Timer? _debounceTimer;
String _accumulatedTokens = '';

void _handleToken(String token) {
  _accumulatedTokens += token;

  _debounceTimer?.cancel();
  _debounceTimer = Timer(Duration(milliseconds: 50), () {
    // Update UI with accumulated tokens
    setState(() {
      currentResponse = _accumulatedTokens;
    });
  });
}

2. Memory Management

Long conversations can accumulate large amounts of data. Consider implementing message pagination or limiting the number of visible messages:

class ChatController {
  static const int maxVisibleMessages = 100;
  final List<ChatMessage> _allMessages = [];

  List<ChatMessage> get visibleMessages {
    if (_allMessages.length <= maxVisibleMessages) {
      return _allMessages;
    }
    return _allMessages.sublist(_allMessages.length - maxVisibleMessages);
  }
}

3. Error Handling

Streams can fail. Always handle errors gracefully:

StreamBuilder<String>(
  stream: responseStream,
  builder: (context, snapshot) {
    if (snapshot.hasError) {
      return ChatBubble(
        text: 'Sorry, something went wrong. Please try again.',
        isUser: false,
        isError: true,
      );
    }

    return ChatBubble(
      text: snapshot.data ?? '',
      isUser: false,
      isStreaming: snapshot.connectionState == ConnectionState.active,
    );
  },
)

Connecting to Real AI Providers

The examples above use simulated streaming, but connecting to real AI providers follows the same pattern. Here’s how to integrate with OpenAI’s streaming API:

Stream<String> _getOpenAIStream(String prompt) async* {
  final client = http.Client();

  try {
    final request = http.Request('POST', Uri.parse('https://api.openai.com/v1/chat/completions'));
    request.headers.addAll({
      'Authorization': 'Bearer $openAIKey',
      'Content-Type': 'application/json',
    });

    request.body = json.encode({
      'model': 'gpt-3.5-turbo',
      'messages': [{'role': 'user', 'content': prompt}],
      'stream': true,
    });

    final streamedResponse = await client.send(request);

    await for (final chunk in streamedResponse.stream.transform(utf8.decoder)) {
      final lines = chunk.split('n');

      for (final line in lines) {
        if (line.startsWith('data: ') && !line.contains('[DONE]')) {
          final data = line.substring(6);
          try {
            final json = jsonDecode(data);
            final content = json['choices'][0]['delta']['content'];
            if (content != null) {
              yield content;
            }
          } catch (e) {
            // Skip malformed chunks
          }
        }
      }
    }
  } finally {
    client.close();
  }
}

Next Steps

You now have a solid foundation for building streaming AI chat interfaces in Flutter. The key insight is using StreamBuilder instead of setState—it gives you better performance, cleaner code, and built-in connection state management.

From here, consider adding:

  • Message persistence: Save conversations to local storage
  • Rich message types: Support images, code blocks, and markdown
  • Conversation branching: Let users retry or edit previous messages
  • Voice input: Add speech-to-text for voice conversations

The patterns shown here scale to complex chat applications. Whether you’re building a customer service bot or an AI assistant, StreamBuilder gives you the foundation for smooth, responsive streaming interfaces.

Remember: AI responses should feel immediate and natural. Users expect that characteristic streaming effect, and with the right implementation, your Flutter app can deliver it without performance compromises.