Hey! So if you’ve been following CFFBRW since the Blockly days (DOUBT IT!), things have… changed a lot. Like, “I threw away the entire visual editor” level of change. 😅
Remember when I was all excited about snapping blocks together like LEGO? Turns out, when AI agents can write code better than I can drag blocks around, maybe the blocks aren’t the product anymore.
What happened
So I’ve been reading a lot about the whole “SaaS is dead” thing (I wrote some research notes about it). The basic idea: value is moving UP to the agent layer and DOWN to the data layer. The middle — dashboards, drag-and-drop UIs, per-seat pricing — is getting crushed.
And I looked at CFFBRW and thought… wait. My visual builder IS the middle layer. 🙈
So I rebuilt the whole thing around one idea: what if you just write what you want in plain English, and AI compiles it into a workflow?
Before:  Drag blocks → Configure each one → Deploy
Now:     Write markdown → AI compiles → Deploy

The markdown is the source of truth. Not a config file, not YAML, not blocks.
The AI compiler runs once per workflow version, caches the result, and then execution is fully deterministic. No AI involved at runtime = fast and cheap.
The part I’m most excited about: BYOM MCP Server
BYOM = Bring Your Own Model. I exposed the entire platform as an MCP server at /mcp. Any AI — Claude, Gemini, whatever — can compile, validate, deploy, and run workflows. Not through the dashboard. Through MCP tools.
This is… kind of the whole point? If agents are the future users, the MCP server IS the product. The dashboard is just nice-to-have.
Here’s what the MCP server gives you:
Resources (so the AI understands the system before acting):
-
cffbrw://schema/execution-plan — the JSON format it needs to generate
-
cffbrw://schema/step-types — all 9 step types (http_request, ai_call, transform, conditional, loop, etc.)
-
cffbrw://tools/available — what external MCP tools you’ve registered
-
cffbrw://examples/plans — examples from simple to complex
Tools (what the AI can actually do):
-
validate_plan — submit JSON, get errors or a validated plan
-
deploy_workflow / update_workflow — create or update workflows
-
run_workflow — execute, get back a run ID and WebSocket URL
-
get_run_status — poll until it’s done
- Plus
get_workflow, list_runs, list_workflows
There’s also a compile prompt that tells the AI “read the resources, take this markdown, give me valid JSON.” But honestly the resources contain everything — the prompt is optional.
The auth model (learned this the hard way)
Remember the voucher race condition? Yeah, I’ve gotten more careful about security since then.
Two access levels:
-
wfk_ API keys — scoped to ONE specific workflow. Can read, update, and run it (only if published). Cannot see other workflows or create new ones. If this key leaks, damage is contained.
-
Clerk JWT — full workspace access. Everything works. For the dashboard and admin stuff.
So a CI/CD key can trigger your workflow but can’t create arbitrary new ones. That felt important after the voucher incident taught me that “it’ll probably be fine” is not a security strategy 😄
Expression eval: because eval() doesn’t work on Cloudflare (not any more)
This was a fun rabbit hole. Workflows need to evaluate expressions — like referencing a previous step’s output or doing a conditional check. But Cloudflare Workers blocks eval() and new Function(). Just… doesn’t work. I learned this the hard way (as I learn most things).
So I built a three-tier system:
-
Tier A — Simple string templates like
"Hello ${steps.step_0.name}". Parsed by an AST walker (jsep). Under 1ms. Handles most cases.
-
Tier B — More complex expressions. Tries the AST walker first, falls back to a Dynamic Worker sandbox if it’s too gnarly. ~10-30ms for the fallback. And I cannot stress this enough Dynamic Worker is a game-changer. So try it.
-
Tier C — Full JavaScript code blocks in a Dynamic Worker. Network blocked by default. The escape hatch.
And I cannot stress this enough Dynamic Worker is a game-changer. So try it.
The AI compiler is told to prefer Tier A/B. Only use complex JS when you actually need multi-statement logic. Because honestly, most workflow expressions are just “get this value from the previous step.”
The stack (for the curious)
Everything runs on Cloudflare:
-
API: Hono
-
Validation: Zod everywhere — schemas are the single source of truth, TypeScript types derived from them.
-
AI: Claude (primary) + Gemini (fallback). Strategy pattern, so they’re swappable.
-
Storage: D1 for workflows/runs, KV for compilation cache, R2 for artifacts
-
Real-time: Cloudflare Agents SDK —
NotebookAgent for WebSocket streaming, WorkflowRunner for durable execution. They talk via RPC.
-
Dashboard: TanStack Start + React Flow for DAG visualization
-
Auth: Clerk with organizations for multi-tenant
The Agents SDK was… an experience. The TypeScript types are incomplete, routeAgentRequest() doesn’t work with custom URL patterns, and you need a magic x-partykit-room header that isn’t documented anywhere. I ended up reading node_modules/agents/dist/index.js more than the actual docs. Classic Cloudflare beta experience 😅
So where’s the value now?
🤖 Agent Layer    → BYOM MCP server (any AI can use it)
🔌 Protocol Layer → 8 tools + 4 resources + compile prompt
🖥️ UI Layer       → Dashboard (nice but not the moat)
🗄️ Data Layer     → Run history, step logs, compilation cache (the actual moat)
The dashboard looks cool. But an AI agent talking to the MCP server can do literally everything the dashboard does. The data — workflow definitions, historical runs, step-level logs — is what compounds over time. That’s what no agent can replicate from the outside.
Still building. Still learning. If you want to try the MCP server or have thoughts on how agent-native products should work, I’d love to hear it.
And I believe any builder should use Gstack from Garry Tan. Old news I know, but for people who live under a rock like I do.
So cheers! ☕


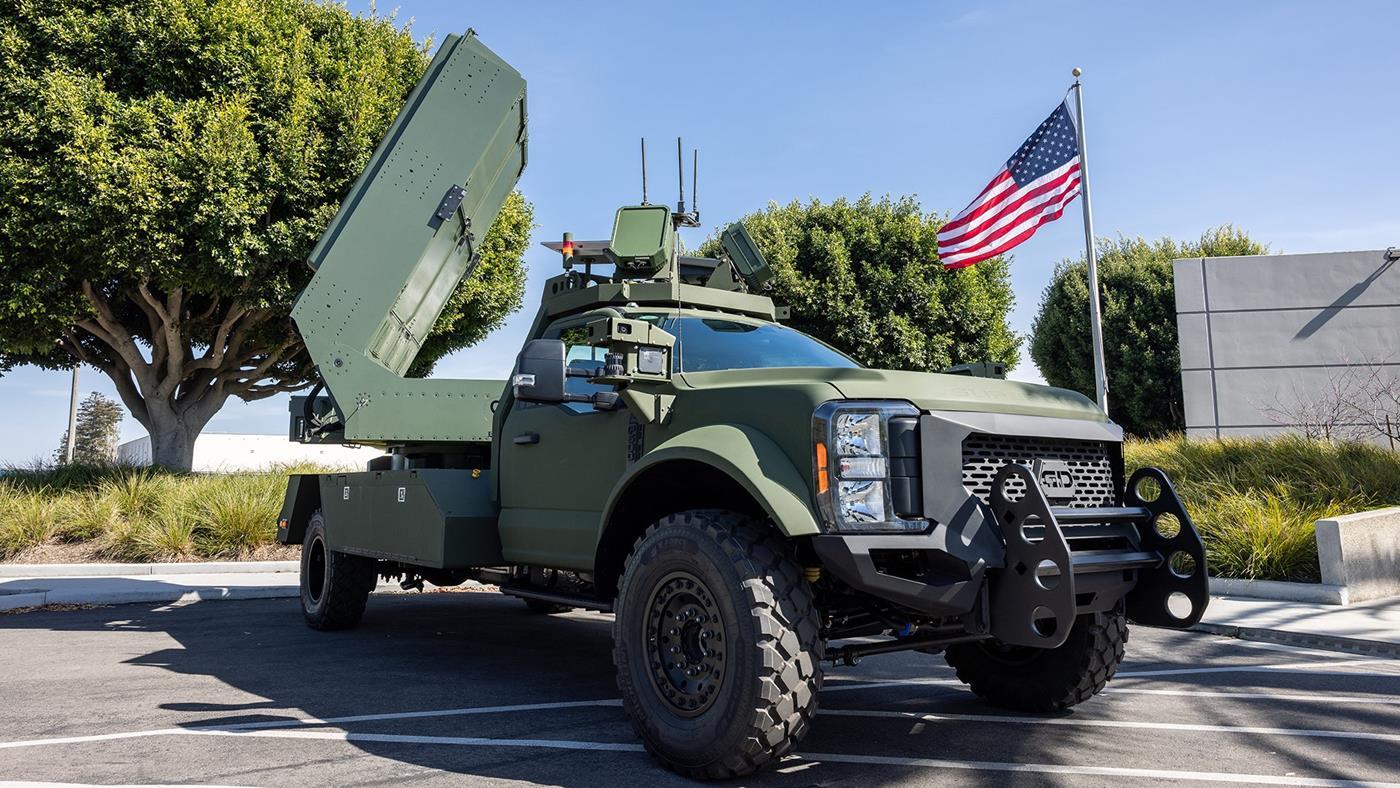
 ABD, tanıttığı Leonidas AGV ile dron sürülerine karşı otonom mikrodalga silah sistemi geliştirdi. Geliştirilen otonom araç sistemi dron sürülerini kısa sürede etkisiz hale getirebiliyor.
 Volkswagen, tüm tepkilere rağmen İsrail ile ortaklık kurmaya kararlı görünüyor. Volkswagen CEO’su Oliver Blume, Alman basınından gelen sorular üzerine konuya dair önemli açıklamalar yaptı.
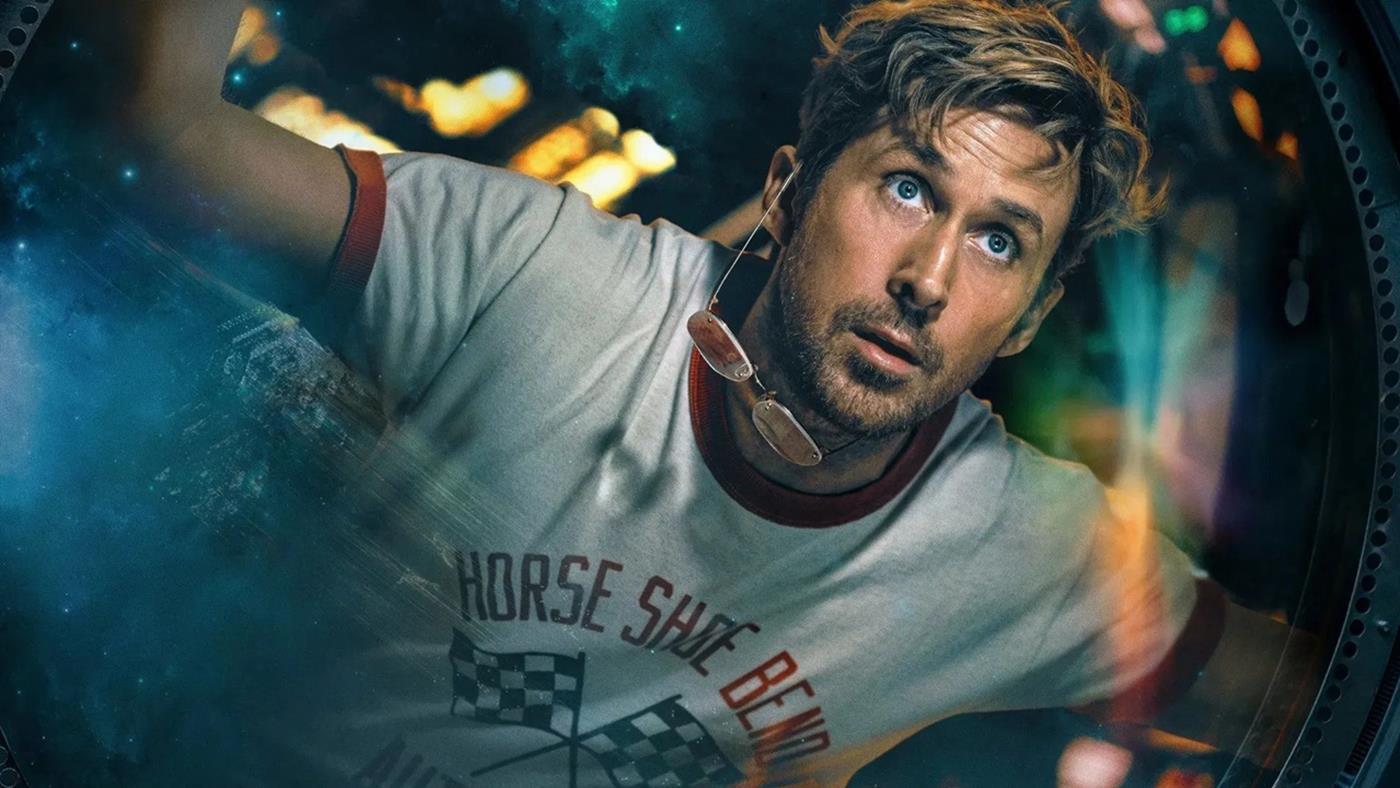
 Bilim kurgu filmi Kurtuluş Projesi (Project Hail Mary) adından övgüyle söz ettirmeye devam ederken, Amazon da devam filmi için de nabız yoklamaya başladı. Son sözü Andy Weir söyleyecek.