Linux Shell Shortcuts That Will Save You Hours Every Week

Linux Shell Shortcuts That Will Save You Hours Every Week

If you spend any significant time in the terminal, you’ve probably wondered if there’s a faster way to do things. Spoiler: there absolutely is. Most developers use only a fraction of their shell’s capabilities, leaving serious productivity gains on the table.

Let me show you the keyboard shortcuts, history tricks, and workflow optimizations that collectively save me hours every week. These work in both bash and zsh, so whether you’re on Ubuntu, macOS, or a Raspberry Pi, you’re covered.

Why Shell Shortcuts Matter

Before diving into specific shortcuts, let’s talk about why this matters. The average developer runs hundreds of commands daily. If each command takes even 5 seconds longer than necessary due to retyping, scrolling through history manually, or losing your place—those seconds add up to real hours.

Shell shortcuts aren’t just about speed. They reduce cognitive load. When you can recall a complex command instantly instead of reconstructing it from memory, you keep your focus on the problem you’re solving, not the mechanics of your tools.

The Essentials: Navigation Shortcuts

Let’s start with the fundamentals that you’ll use constantly.

Moving Around the Command Line

Shortcut Action
Ctrl + A Jump to beginning of line
Ctrl + E Jump to end of line
Ctrl + B Move back one character (←)
Ctrl + F Move forward one character (→)
Alt + B Move back one word
Alt + F Move forward one word

These seem simple, but here’s the key insight: keeping your hands on the home row is faster than reaching for arrow keys. Once these become muscle memory, you’ll navigate commands at the speed of thought.

# Example: You typed a long command but need to fix the first flag
$ docker run --name myapp -p 8080:80 -v /data:/app/data -e NODE_ENV=production node:18

# Instead of holding ← for 10 seconds, press Ctrl+A and you're there instantly
# Then Alt+F to jump by words to the exact spot

Editing on the Line

Shortcut Action
Ctrl + U Cut from cursor to beginning of line
Ctrl + K Cut from cursor to end of line
Ctrl + W Cut the word before cursor
Ctrl + Y Paste (yank) last cut text
Ctrl + _ Undo last edit

The cut and paste shortcuts are incredibly powerful. Cut text with Ctrl+U or Ctrl+K, and it goes into a clipboard-like buffer. Ctrl+Y brings it back.

# You're editing a command and want to try a different flag
$ kubectl get pods -n production --field-selector=status.phase=Running

# Press Ctrl+W to remove "Running", type "Pending" instead
$ kubectl get pods -n production --field-selector=status.phase=Pending

# Need the original back? Ctrl+_ undoes the change

History Search: The Game Changer

This is the single most impactful shortcut in my toolkit.

Reverse Incremental Search

Press Ctrl + R and start typing. Your shell searches backward through your history, showing matches in real-time.

$ # Press Ctrl+R
(reverse-i-search)``: 
$ # Start typing 'docker'
(reverse-i-search)`docker': docker-compose -f docker-compose.prod.yml up -d
$ # Press Ctrl+R again to cycle through older matches
(reverse-i-search)`docker': docker exec -it mycontainer bash

Press Enter to execute the found command, or Ctrl+C to cancel.

Pro tip: In zsh with the excellent Oh My Zsh framework, you can use the up/down arrows after a partial command to search history matching what you’ve typed:

$ docker  # Press ↑ to cycle through all docker commands in history

History Expansion Shortcuts

Shortcut Action
!! Repeat last command
!$ Last argument of previous command
!* All arguments of previous command
!n Command number n in history
!pattern Last command starting with pattern

These look cryptic but are incredibly useful:

$ ls /very/long/directory/path/that/took/forever/to/type
$ cd !$    # Expands to: cd /very/long/directory/path/that/took/forever/to/type

$ apt update
Permission denied
$ sudo !!   # Repeats last command with sudo: sudo apt update

$ git commit -m "Fix bug" && git push origin main
$ !*        # Would expand to: commit -m "Fix bug" && git push origin main

The Alt + . shortcut is my personal favorite—it inserts the last argument from the previous command:

$ mkdir -p ~/projects/awesome-new-project/src/components
$ cd Alt+.   # Expands to: cd ~/projects/awesome-new-project/src/components

You can press Alt + . repeatedly to cycle through previous commands’ last arguments.

Process Control Shortcuts

Shortcut Action
Ctrl + C Send SIGINT (interrupt/kill current process)
Ctrl + Z Suspend current process
Ctrl + D Send EOF (close shell/logout)
Ctrl + L Clear screen (faster than typing clear)

The suspension with Ctrl+Z is particularly powerful when combined with job control:

$ vim config.yaml          # Editing a file
# Press Ctrl+Z
[1]+  Stopped                 vim config.yaml
$ grep "error" /var/log/app.log   # Run another command
$ fg                       # Return to vim (foreground)

Use jobs to see suspended processes, fg %1 to bring job 1 to foreground, bg %1 to run job 1 in background.

Tmux: The Session Manager

If you’re not using tmux (or screen), you’re missing out on one of the biggest productivity boosters available.

Why Tmux?

  1. Persistent sessions: Your terminals survive SSH disconnections, computer restarts (with configuration), and accidental terminal window closes
  2. Multiple windows: Organize related terminals in one place
  3. Split panes: View multiple terminals simultaneously
  4. Session sharing: Pair program with remote colleagues

Essential Tmux Shortcuts

Tmux uses a prefix key (default Ctrl+B), followed by a command key:

Shortcut Action
Ctrl+B C Create new window
Ctrl+B N Next window
Ctrl+B P Previous window
Ctrl+B % Split pane vertically
Ctrl+B " Split pane horizontally
Ctrl+B D Detach from session
Ctrl+B [ Enter copy mode (scroll)

A Practical Tmux Workflow

# Start a named session for your project
$ tmux new -s myproject

# Inside, create windows for different tasks
Ctrl+B C    # New window - maybe for running the dev server
Ctrl+B C    # Another window - for git operations
Ctrl+B 2    # Jump to window 2

# Split a window for side-by-side viewing
Ctrl+B %    # Vertical split - now you have two panes
Ctrl+B "    # Horizontal split in one pane

# When done, detach (session keeps running)
Ctrl+B D

# Later, reattach
$ tmux attach -t myproject

# List sessions
$ tmux ls

Detaching Saves the Day

# You're running a long database migration on a remote server
$ ./migrate-production-db.sh
# Suddenly your VPN drops
# With tmux, the process continues
# Reconnect, then:
$ tmux attach -t migration
# You're right where you left off

Real-World Scenarios

Scenario 1: Debugging a Container

You’re debugging why a Docker container keeps crashing:

# Run the container
$ docker run -d --name debug-container myapp:latest

# It crashes. Check logs
$ docker logs debug-container
Error: Database connection failed

# You need to tweak the connection string
# Instead of retyping everything:
$ docker run -d --name debug-container -e DB_HOST=10.0.0.5 myapp:latest
# Oops, need to remove the old container first
$ docker rm -f debug-container && Alt+. Alt+.  # Reuses arguments cleverly

# Or use history search
Ctrl+R, type 'docker run', find the command, edit it

Scenario 2: Long-Running Process on Remote Server

You need to run a data processing script on a production server that takes hours:

# SSH into server
$ ssh production-server

# Start tmux first!
$ tmux new -s data-process

# Run your script
$ python3 process_large_dataset.py --input /data/raw --output /data/processed

# Detach when you need to step away
Ctrl+B D

# You can even close your laptop, go home
# Later, from home:
$ ssh production-server
$ tmux attach -t data-process
# Process is still running, output visible

Scenario 3: Fixing a Typo Mid-Command

$ kubectrl get pods -n kube-system   # Typo: 'kubectrl' instead of 'kubectl'

# Don't delete and retype! Use navigation
Ctrl+A    # Go to beginning
Alt+F     # Jump forward one word (now at 'get')
Alt+F     # Jump to 'pods'
Alt+F     # Jump to '-n'
Alt+F     # Jump to 'kube-system'
Ctrl+B Ctrl+B  # Back up two characters to the 'l' in kubectrl
# Delete 'r' and 'l', add 'l' and 'e' to fix

Troubleshooting FAQ

Q: These shortcuts aren’t working on my system!

A: Check your shell. Run echo $0 or ps -p $$. If you’re not using bash or zsh, these shortcuts may differ. On some systems, Alt is Option (macOS) or Esc (press and release, then the key).

For zsh, ensure you’re using Emacs keybindings (the default):

bindkey -e  # Emacs mode
bindkey -v  # Vi mode (different shortcuts)

Q: My history isn’t being saved between sessions!

A: Add these to your ~/.bashrc or ~/.zshrc:

# Ignore duplicates and commands starting with space
export HISTCONTROL=ignoredups:ignorespace
# Increase history size
export HISTSIZE=10000
export HISTFILESIZE=20000
# Append to history file, don't overwrite
shopt -s histappend  # bash only

Q: Tmux says “no server running” but I had a session!

A: If your system rebooted, tmux sessions are lost (they’re stored in memory, not persisted to disk). For persistence across reboots, consider:

  1. Using tmux plugins like tmux-resurrect and tmux-continuum (via TPM)
  2. Running critical processes as systemd services or in Docker containers
  3. Using terminal multiplexing tools designed for persistence

Q: Can I customize these shortcuts?

A: Absolutely! In bash, use the bind command. In zsh, use bindkey:

# Make Ctrl+Shift+R search forward (in addition to Ctrl+R backward)
bindkey '^R' history-incremental-search-backward
bindkey -s '^S' '!!n'  # Ctrl+S repeats last command

Conclusion

Shell shortcuts aren’t flashy. They won’t impress anyone at a demo. But they’re the compound interest of developer productivity: small gains, applied thousands of times, accumulating into serious time savings.

Start small. Pick three shortcuts—Ctrl+R, Alt+., and Ctrl+A/Ctrl+E—and commit to using them for a week. Once they become automatic, add more. Consider setting up tmux for your next project.

The terminal is where developers live. Make yourself at home.
The JSON Parsing Problem That’s Killing Your AI Agent Reliability

Every AI agent operator hits this wall: you prompt your LLM to return structured data, and it gives you something almost right—but not quite. Maybe it added a trailing comma. Maybe it wrapped a string in quotes when you needed a number. Whatever the specific failure mode, your agent pipeline breaks at the parse step.

I’ve been building AI agent tools for the past year, and this was my single biggest source of runtime failures. Here’s the pattern I landed on that solved it permanently.

The Problem with Pure Prompting

You can spend hours crafting the perfect system prompt. You can add examples. You can beg the model to “always return valid JSON”. But probabilistic outputs mean probabilistic results—eventually you’ll get back something that breaks your parser.

The real fix isn’t a better prompt. It’s moving the contract enforcement out of the prompt and into your code.

The Solution: Schema-Guided Extraction

Instead of asking the LLM to output JSON directly, ask it to output a plain text description, then parse that into your schema. Here’s the pattern:

import json
from typing import Type
from pydantic import BaseModel, ValidationError

def extract_structured(model_output: str, schema: Type[BaseModel]) -> BaseModel | None:
    """Try to parse model output into the target schema."""
    try:
        data = json.loads(model_output)
        return schema(**data)
    except (json.JSONDecodeError, ValidationError):
        return None

def extract_with_fallback(model_output: str, schema: Type[BaseModel]) -> BaseModel:
    """Attempt extraction, raise with context on failure."""
    result = extract_structured(model_output, schema)
    if result is not None:
        return result

    # Fallback: try stripping markdown code blocks
    cleaned = model_output.strip()
    if cleaned.startswith('```

'):
        cleaned = 'n'.join(cleaned.split('n')[1:])  # Remove first line
        cleaned = cleaned.removesuffix('

```').strip()

    result = extract_structured(cleaned, schema)
    if result is not None:
        return result

    raise ValueError(f"Could not parse output into {schema.__name__}")

The key insight: your extraction layer handles all the edge cases (trailing commas, markdown wrapping, quote style variations). Your prompt just asks for the data—it doesn’t need to worry about format.

Apply This to Your Agent Pipeline

from pydantic import BaseModel

class ArticleMetadata(BaseModel):
    title: str
    tags: list[str]
    reading_time_minutes: int

def parse_article_suggestion(raw_output: str) -> ArticleMetadata:
    return extract_with_fallback(raw_output, ArticleMetadata)

# In your agent loop:
response = llm.complete(prompt)
metadata = parse_article_suggestion(response)
# metadata is guaranteed to be valid

This pattern has eliminated parse failures in my agent pipelines. The LLM focuses on understanding. The extraction layer focuses on correctness. Each layer has one job.

Full catalog of my AI agent tools at https://thebookmaster.zo.space/bolt/market

I Built an AI Tool That Dubs Any YouTube Video Into 50+ Languages

There are millions of great YouTube videos out there. Tutorials, podcasts, documentaries, lectures. But most of them are locked behind a language barrier.

I built TubeVoice to fix that.

What it does

Paste any YouTube URL, pick a target language, and TubeVoice generates a fully dubbed version in minutes. The original background music and ambient sounds stay intact — only the voice changes.

Try it free: tubevoice.io

How it works

  1. Transcription — AI transcribes the original audio (Whisper)
  2. Translation — Neural machine translation to your chosen language
  3. Voice Synthesis — Natural-sounding TTS generates the dubbed voice
  4. Audio Mixing — AI separates vocals from background using source separation (Demucs), then mixes the new voice with the original background audio

The result sounds surprisingly natural. The timing is preserved, background music plays through, and the dubbed voice matches the original pacing.

Tech Stack

  • Frontend: Next.js + Tailwind CSS (deployed on Vercel)
  • Backend: Python + Celery workers (Railway)
  • Transcription: OpenAI Whisper
  • Translation: GPT-4o
  • TTS: Google Chirp3-HD (Basic), ElevenLabs (Standard/Premium)
  • Audio Separation: Demucs (htdemucs model)
  • Database: Supabase (PostgreSQL)
  • Payments: Stripe

Three quality tiers

Tier Voice Engine Credits/min Best for
Basic Google Chirp3-HD 1 Casual listening
Standard ElevenLabs Flash 3 Good quality dubbing
Premium ElevenLabs Dubbing API 6 Professional results

Challenges I faced

  • Audio sync — Matching dubbed speech timing to the original is hard. Different languages have different word lengths. The TTS engine handles this reasonably well, but it’s not perfect.
  • Background preservation — Using Demucs for source separation was a game-changer. It cleanly separates vocals from music/ambience, so the dubbed version retains the original feel.
  • Cost optimization — Running Whisper + GPT-4o + TTS + Demucs adds up. I optimized by running Demucs locally on Apple Silicon (MPS) instead of cloud GPU.

What’s next

  • More voice options and voice cloning
  • Subtitle generation alongside dubbing
  • API for developers
  • Mobile app (PWA)

Would love to hear your feedback. What features would make this useful for you?

🔗 tubevoice.io — Free tier available (3 free credits to try it out)

Show HN: I made an AI that reviews iPhone apps – 1h of autonomous GUI work

I ran a GUI agent for ~1 hour that installs and reviews iPhone apps on a real device. Understudy: browses the App Store in Chrome, mirrors a real iPhone via macOS, explores the app, records screenshots/video, stitches a narrated review with FFmpeg, uploads to YouTube.

Key architecture: split the work into typed child sessions so context doesn’t explode. Six stages: scrape listing, install via mirroring, exploratory testing, targeted checks, media capture, compose+upload+cleanup. Workers = deterministic I/O. Skills = agentic decisions.

Robustness wins here. Re‑ground every action from the live screenshot so unexpected dialogs don’t kill the run. Keep device control deterministic, collect screenshots + UI dumps + logs, and compose media locally (FFmpeg) for an auditable pipeline. MIT license.

Takeaway for builders: long GUI agents need clear separation — deterministic workers for device/browser ops, agentic skills for discovery, session isolation, and artifact bundling + human review before publish. Repo + process vids: https://understudy-ai.github.io/understudy/

Artifact Management: Docker Registry, Nexus, and Artifactory

Artifact Management: The Foundation of Modern DevOps Workflows

Picture this: Your team just pushed a critical hotfix to production, but the deployment failed. The Docker image that worked perfectly in staging is nowhere to be found in production. Your build artifacts from last week’s release have mysteriously vanished. Sound familiar?

This scenario plays out in engineering teams worldwide, and it highlights a fundamental truth: without proper artifact management, even the most sophisticated CI/CD pipelines crumble. Whether you’re dealing with Docker images, JAR files, npm packages, or any other build artifacts, having a robust artifact management strategy is the difference between smooth deployments and 3 AM firefighting sessions.

Today, we’ll explore the three heavyweight champions of artifact management: Docker Registry, Nexus Repository, and JFrog Artifactory. You’ll learn when to use each one, how they fit into your broader system architecture, and the design decisions that can make or break your artifact strategy.

Core Concepts

What Is Artifact Management?

Artifact management is the practice of storing, organizing, versioning, and distributing the binary outputs of your build processes. Think of it as a sophisticated warehouse for your software components. Just as Amazon tracks every package from receipt to delivery, artifact repositories track every version of every component your teams produce and consume.

The core components of any artifact management system include:

  • Repository Storage: The actual storage layer where artifacts live
  • Metadata Database: Tracks versions, dependencies, and artifact relationships
  • Access Control: Authentication and authorization mechanisms
  • API Layer: RESTful interfaces for programmatic access
  • Web Interface: User-friendly dashboards for browsing and management
  • Cleanup Policies: Automated retention and deletion rules

Docker Registry: The Container Specialist

Docker Registry serves as the reference implementation for container image storage. It’s lightweight, focused, and does one thing exceptionally well: storing and serving Docker images.

Key characteristics:

  • Single Format Focus: Only handles Docker/OCI container images
  • Stateless Design: No built-in user management or complex metadata
  • Cloud-Native: Designed for horizontal scaling and cloud deployment
  • Minimal Overhead: Lightweight resource requirements

Docker Registry shines in environments where you need simple, reliable container storage without the complexity of a full-featured repository manager.

Nexus Repository: The Enterprise Workhorse

Sonatype Nexus Repository takes a broader approach, supporting dozens of package formats while providing enterprise-grade features. It’s the Swiss Army knife of artifact management.

Core components include:

  • Format Support: Maven, npm, Docker, NuGet, PyPI, and 20+ other formats
  • Repository Types: Hosted (your artifacts), proxy (cache external repos), and group (virtual aggregation)
  • Security Integration: LDAP, Active Directory, and role-based access control
  • Component Intelligence: Vulnerability scanning and license analysis

Artifactory: The Universal Solution

JFrog Artifactory positions itself as the “universal artifact repository,” supporting virtually every package format while providing advanced DevOps integration capabilities.

Distinguishing features:

  • Metadata Database: Rich metadata storage enabling advanced queries
  • Build Integration: Deep integration with CI/CD tools and build information tracking
  • High Availability: Native clustering and replication capabilities
  • Advanced Security: Fine-grained permissions, access tokens, and audit trails

How It Works

System Architecture Patterns

Most artifact management systems follow a similar architectural pattern, though implementations vary significantly. You can visualize these architectures using InfraSketch to better understand how components interact in your specific environment.

The typical flow involves several key stages:

Artifact Publishing: Developers or CI systems authenticate with the repository and upload artifacts using standard protocols (Docker push, Maven deploy, npm publish). The repository validates the artifact, stores the binary data, and updates its metadata database.

Dependency Resolution: When applications or build processes need dependencies, they query the repository through its API. The repository checks permissions, resolves the requested version, and serves the artifact. Proxy repositories add an extra layer by caching external dependencies locally.

Cleanup and Maintenance: Background processes enforce retention policies, remove unused artifacts, and perform housekeeping tasks. This prevents repositories from growing indefinitely and consuming excessive storage.

Version Management Strategies

Effective versioning strategies are crucial for artifact management success. Most organizations adopt one of several approaches:

Semantic Versioning: Using major.minor.patch format for releases with clear backward compatibility semantics. This works well for libraries and components consumed by other teams.

Build-Based Versioning: Incorporating build numbers or commit hashes into version strings. This provides precise traceability but can complicate dependency management.

Environment Promotion: Using the same artifact across environments with different tags or metadata. This ensures what you test is exactly what you deploy.

Security and Access Control

Modern artifact repositories implement sophisticated security models. Understanding these patterns helps you design appropriate access controls for your organization.

Authentication typically integrates with existing identity providers through LDAP, SAML, or OAuth. This centralizes user management and leverages existing security infrastructure.

Authorization operates at multiple levels: repository-level permissions control who can read or write to entire repositories, while path-based permissions provide fine-grained access control over specific artifacts or versions.

Design Considerations

Choosing the Right Solution

The choice between Docker Registry, Nexus, and Artifactory depends on several factors that you should evaluate carefully.

Team Size and Complexity: Small teams with simple needs might find Docker Registry sufficient for container-only workflows. As organizations grow and adopt multiple technologies, the comprehensive format support of Nexus or Artifactory becomes valuable.

Technology Stack: If you’re working exclusively with containers, Docker Registry provides simplicity and performance. Multi-language environments benefit from unified artifact management across all package formats.

Security Requirements: Highly regulated industries often require the advanced security features and audit capabilities that enterprise solutions provide. Tools like InfraSketch can help you map out security boundaries and access patterns in your artifact management architecture.

Scaling Strategies

Artifact repositories face unique scaling challenges as they store large binary files and serve high-volume download requests.

Storage Scaling: Most repositories support pluggable storage backends, allowing you to leverage cloud object storage for cost-effective capacity scaling. Consider data locality and transfer costs when choosing storage locations.

Read Performance: Implementing caching layers and geographically distributed replicas reduces latency for global teams. CDN integration can dramatically improve download performance for frequently accessed artifacts.

High Availability: Critical artifact repositories require redundancy and failover capabilities. Evaluate each solution’s clustering and replication features against your availability requirements.

Operational Considerations

Running artifact repositories in production requires careful attention to several operational aspects.

Backup and Recovery: Artifacts represent significant investment in build time and often cannot be easily recreated. Implement comprehensive backup strategies covering both artifact data and metadata.

Monitoring and Alerting: Track repository health through metrics like storage utilization, request latency, and error rates. Failed artifact retrievals can cascade into widespread build failures.

Cleanup Policies: Unchecked artifact accumulation quickly consumes storage and degrades performance. Design retention policies that balance storage costs with the need to maintain historical artifacts for debugging and rollback scenarios.

Integration Patterns

Artifact repositories rarely operate in isolation. They integrate with numerous other systems in your development workflow.

CI/CD Pipeline Integration: Build systems must authenticate with repositories, publish artifacts, and trigger downstream processes. Consider how credential management and build metadata flow through your pipelines.

Developer Workflow: Developers need easy access to browse artifacts, understand dependencies, and troubleshoot issues. Balance security requirements with developer productivity needs.

Deployment Automation: Deployment systems pull artifacts and promote them through environments. Design clear promotion workflows that maintain traceability from source to production.

Key Takeaways

Artifact management forms the backbone of modern software delivery, and choosing the right solution requires understanding both your current needs and future growth trajectory.

Start with your requirements: Docker Registry excels for container-focused teams prioritizing simplicity. Nexus Repository provides comprehensive format support with strong enterprise features. Artifactory offers the most advanced DevOps integration and metadata capabilities.

Design for growth: What works for a 5-person team may not scale to 500 developers. Consider how your chosen solution will handle increased load, additional package formats, and more complex security requirements.

Automate everything: Manual artifact management doesn’t scale. Implement automated cleanup policies, security scanning, and deployment promotion from day one.

Security is paramount: Artifacts often contain proprietary code and sensitive dependencies. Implement proper access controls, vulnerability scanning, and audit logging regardless of which solution you choose.

Plan your architecture: Understanding how artifact repositories fit into your broader system architecture is crucial for making informed decisions about placement, scaling, and integration patterns.

Try It Yourself

Ready to design your own artifact management architecture? Whether you’re planning a simple Docker Registry setup or a complex multi-region Artifactory deployment, visualizing your architecture helps identify potential issues before implementation.

Consider factors like team distribution, security boundaries, integration points with CI/CD systems, and disaster recovery requirements. Think about how artifacts flow from development through testing to production, and where caching or replication might improve performance.

Head over to InfraSketch and describe your system in plain English. In seconds, you’ll have a professional architecture diagram, complete with a design document. No drawing skills required. Start with something like “Design an artifact management system with Nexus Repository, integrated with Jenkins CI/CD, supporting Docker images and Maven artifacts, with backup to AWS S3” and watch your architecture come to life.

Built an AI Engine That Turns Your GitHub + Resume Into a Full Notion Portfolio — Powered by MCP

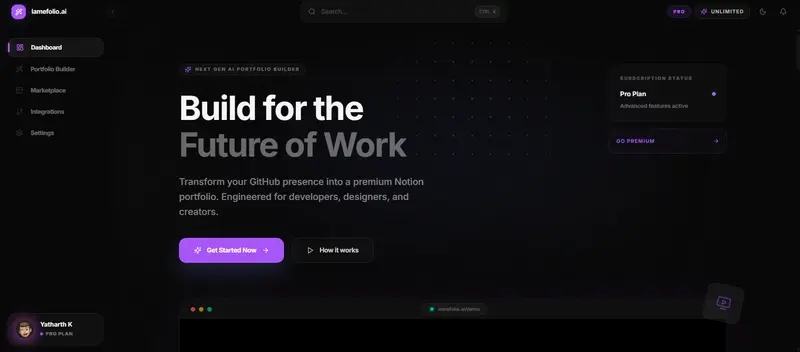
dashboard

Try it live:

What I Built
Every developer needs a portfolio. And every developer hates building one.

You spend hours picking a template, manually copying project descriptions from GitHub, formatting your skills section, and writing an “About Me” that doesn’t sound like a chatbot wrote it. Then you do it again six months later because your old one is stale.

I got tired of that cycle. So I built Lamefolio AI — an MCP-powered portfolio engine that fetches your entire GitHub profile, optionally ingests your resume (PDF, images — full multimodal), feeds everything through Gemini 2.5 Flash, and outputs a beautifully structured Notion portfolio page. One conversation. One click. Done.

No more copy-pasting. No more stale portfolios. The AI builds it, and you own it in Notion.

What it actually does

  • Fetches your GitHub data — repos, languages, READMEs, and project metadata via Octokit REST
  • Analyzes your resume (optional) — full multimodal parsing via Gemini. PDFs, images, even photos of printed resume
  • Generates a semantic portfolio schema — Gemini takes the raw data and creates a structured JSON: hero section, skills breakdown, project cards, experience timeline, achievements
  • Transforms to Notion blocks — a dedicated Transformer service converts the schema into Notion’s block format, with multiple template styles
  • Publishes to Notion — creates the page, appends blocks in batches, sets cover images, and delivers a live URL
  • AI Chat for live editing — after generation, chat with the AI to search, append, delete, or update content on your portfolio page using function callinge

dashboard

Key Features

  • 🪄 5-Service Pipeline — GitHub → AI → Transformer → Notion, orchestrated by a central service
  • 🤖 Gemini 2.5 Flash — portfolio schema generation, resume analysis (multimodal), chat with function calling, dev docs generation
  • 📋 MCP Server — full Model Context Protocol server exposing generate_portfolio and generate_docs as callable tools via stdio transport
  • 🎨 4 Template Styles — Default, Designer-Minimal, Hacker-Dark, Dev-Pro—each with distinct visual identity
  • 💬 AI Chat with Function Calling — Gemini calls Notion tools (search, fetch, append, delete, update, comment) autonomously in a multi-turn loop
  • 📄 Multimodal Resume Ingestion — upload PDFs or images; Gemini extracts structured career data and persists it to your profile
  • 🔐 OAuth Integration — both GitHub and Notion OAuth flows with dynamic redirect URI detection for dev/production parity
  • 🛒 Template Marketplace — browse and apply premium portfolio templates
  • 💳 Billing System — credit-based generation with Razorpay integration
  • 📊 Dynamic Dashboard — track credits, view analytics, manage portfolios

Architecture

The architecture follows a service-oriented pipeline where each service does exactly one thing. The Orchestrator Service is the central coordinator — it chains GitHub data fetching, AI schema generation, block transformation, and Notion publishing into a single sequential pipeline.

The critical design decision: Gemini is only used where creativity matters (schema generation, resume parsing, chat). Everything else — data fetching, block transformation, Notion API calls — is deterministic. Zero token overhead, zero hallucination risk.

Architecture Deep-Dive
Why a 5-service architecture?
I could’ve built one monolithic service that does everything. But that’s a recipe for:

Burnt tokens — fetching GitHub data doesn’t need an LLM
Hallucinated URLs — the Notion publishing step should never make things up
Debugging nightmares — which part of the monolith failed?

Instead, each service is a specialist:

typescript

Four steps, each handled by a dedicated service. The Orchestrator chains them together and handles error propagation.

GitHub Service: Deterministic Data, Zero LLM
The GitHub service calls Octokit REST directly — no agent reasoning needed:

typescript

One REST call per repo pulls metadata + deep data. The response goes straight into the AI pipeline. No LLM in the loop — this is pure data fetching.

Gemini AI: The Creative Engine
This is where the LLM earns its keep. The AI service has four distinct responsibilities:

  1. Portfolio Schema Generation — takes raw GitHub + resume data and produces structured JSON
  2. Resume Analysis — full multimodal parsing of PDFs/images into career data
  3. Chat with Function Calling — multi-turn conversation with autonomous Notion tool use
  4. Dev Docs Generation — creates documentation from repo READMEs

typescript

The function calling loop in the Orchestrator’s (getChatResponsemethod) is the most interesting part — Gemini decides which Notion tools to call, the Orchestrator executes them, sends results back, and Gemini decides what to do next. Up to 5 iterations per conversation turn.

Transformer: Schema → Notion Blocks
The Transformer converts the AI-generated schema into Notion’s block API format. It supports 4 template styles, each with a distinct visual identity:

typescript

How I Used Notion & MCP

This is the part I’m most excited about. Lamefolio AI integrates with Notion in two complementary ways: through the official MCP server for extensibility, and through the Notion Client SDK for the core pipeline.

  1. MCP Server via @modelcontextprotocol/sdk

The MCP server wraps the entire Orchestrator pipeline as callable tools. Any MCP-compatible client (Claude Desktop, Cursor, custom agents) can trigger portfolio generation:

typescript

Two tools exposed: generate_portfolio (GitHub handle → full Notion portfolio) and generate_docs (repo URL → technical documentation). The MCP layer is a thin wrapper around the Orchestrator — all the heavy lifting happens in the service pipeline underneath.

  1. AI Chat with Notion Function Calling
    The real power is in the chat interface. After generating a portfolio, users can chat with Gemini to live-edit their Notion pages. Gemini has access to 6 Notion tools:

Table

The Orchestrator runs a multi-turn function calling loop:

typescript

Gemini decides which tools to call. The Orchestrator executes them, sends results back, and Gemini decides what to do next — up to 5 iterations per turn. It’s autonomous Notion editing through natural conversation.

  1. Notion Client SDK — The Core Pipeline
    For the portfolio generation pipeline itself, we use @notionhq/client directly:

typescript
The 500ms delay between batches isn’t just for rate limits — it makes the frontend feel like the AI is “building” the portfolio in real-time. Small UX detail, big perceived quality difference.

Lessons Learned
Multimodal resume parsing is surprisingly reliable
I expected Gemini to struggle with varied resume formats — fancy PDFs, scanned images, two-column layouts. It handles all of them. The key was giving it a strict JSON output schema with clear field definitions. Even blurry phone photos of printed resumes get parsed correctly.

Function calling beats prompt engineering for Notion edits
My first attempt at the chat feature used prompt engineering — telling Gemini to output structured edit commands that I’d parse. It was fragile and unpredictable. Switching to native function calling was night and day. Gemini decides which Notion tools to call, and the results go back into the conversation. No parsing, no regex, no hoping the model follows the format.

Template engines are more valuable than you’d think
I almost skipped templates and went with a single layout. But adding the template system (default, designer-minimal, hacker-dark, dev-pro) was worth every line of code. Users don’t just want a portfolio — they want their portfolio. The hacker-dark template renders the entire portfolio as JSON code blocks. Someone will love that.

Batched block appending is essential
Notion’s API has strict rate limits (3 requests/second). Sending 50+ blocks one-at-a-time will get you throttled immediately. Batching in groups of 10 with a 500ms delay keeps you safely under limits and creates a satisfying “building” animation on the frontend.

Notion doesn’t support real-time streaming — and that changed my UX plans
I originally wanted a typewriter effect — the portfolio building itself in real-time on the Notion page as the user watches, block by block, with live character-by-character rendering. It would’ve been the killer demo moment.

Notion’s API doesn’t support this at all. There are no WebSocket endpoints, no SSE-based push, no streaming block update APIs. The API is purely REST: you write blocks, you read blocks. That’s it. The SSE/Streamable HTTP transports mentioned in some docs are specifically for MCP server communication (how an MCP client talks to an MCP server), not for real-time Notion content streaming.

To simulate anything close to a typewriter effect, you’d have to repeatedly call the Update a block endpoint yourself — appending one character at a time to a block’s rich_text. At Notion’s rate limit of 3 req/s, a 500-character paragraph would take ~2.7 minutes of API calls. Not exactly “real-time.”

So I pivoted: instead of streaming to Notion, I stream the frontend experience. The batched block appending with 500ms delays creates the illusion of the AI building the portfolio progressively, and the frontend shows a premium loading skeleton with a real-time progress bar while the backend does its work. The end result feels just as magical — the user just doesn’t see individual characters appearing on the Notion page. Sometimes the API’s limitations push you toward a better UX anyway.

OAuth redirect URIs are a deployment landmine
The number of hours I spent debugging OAuth failures across local dev vs. Vercel production was embarrassing. The fix: a
@getRedirectUri
function that dynamically detects the frontend origin from request headers. No more hardcoded URLs, no more broken deploys.

typescript

Tech Stack

Table

Built with Gemini, Notion API, Model Context Protocol, and an unhealthy amount of TypeScript. If you’ve ever procrastinated on building a portfolio, let the AI do it for you.

GitHub: Yatharth4005/Lamefolio-ai

Building Zenvest: Instant Insurance Payouts Using AI & Real-Time Triggers

Building Zenvest: Parametric Insurance for India’s Gig Workers

Hackathons are intense. Ideas fly in every direction, the clock is merciless, and the pressure to ship something meaningful is real.

This time, one simple question changed everything:

What happens when a delivery partner can’t work because of things completely outside their control?

Rain. Toxic air. Platform outages.

That question became Zenvest – India’s first parametric insurance platform built specifically for gig workers.

Day 0: The Problem That Hit Us Hard

We started by looking closely at the lives of gig economy delivery partners.

  • Their income is 100% tied to daily rides and deliveries
  • No work = zero earnings
  • External disruptions (weather, AQI spikes, app downtime) destroy their day

Traditional insurance fails them completely:

  • Claims take days or weeks
  • Endless documentation and proof of loss
  • Payouts are uncertain and delayed

The entire system was broken. We decided it was time to rebuild it.

Day 1: Flipping the Insurance Model

Instead of the usual question insurance companies ask —

“Can the user prove their loss?”

— we asked a better one:

“Can we detect the loss automatically and pay instantly?”

This led us straight to parametric insurance.

If predefined triggers are met:

  • Rainfall exceeds a threshold
  • AQI crosses dangerous levels
  • Platform experiences confirmed downtime

→ Instant payout.

No claims. No paperwork. No waiting.

Day 2: Designing the Core User Flow

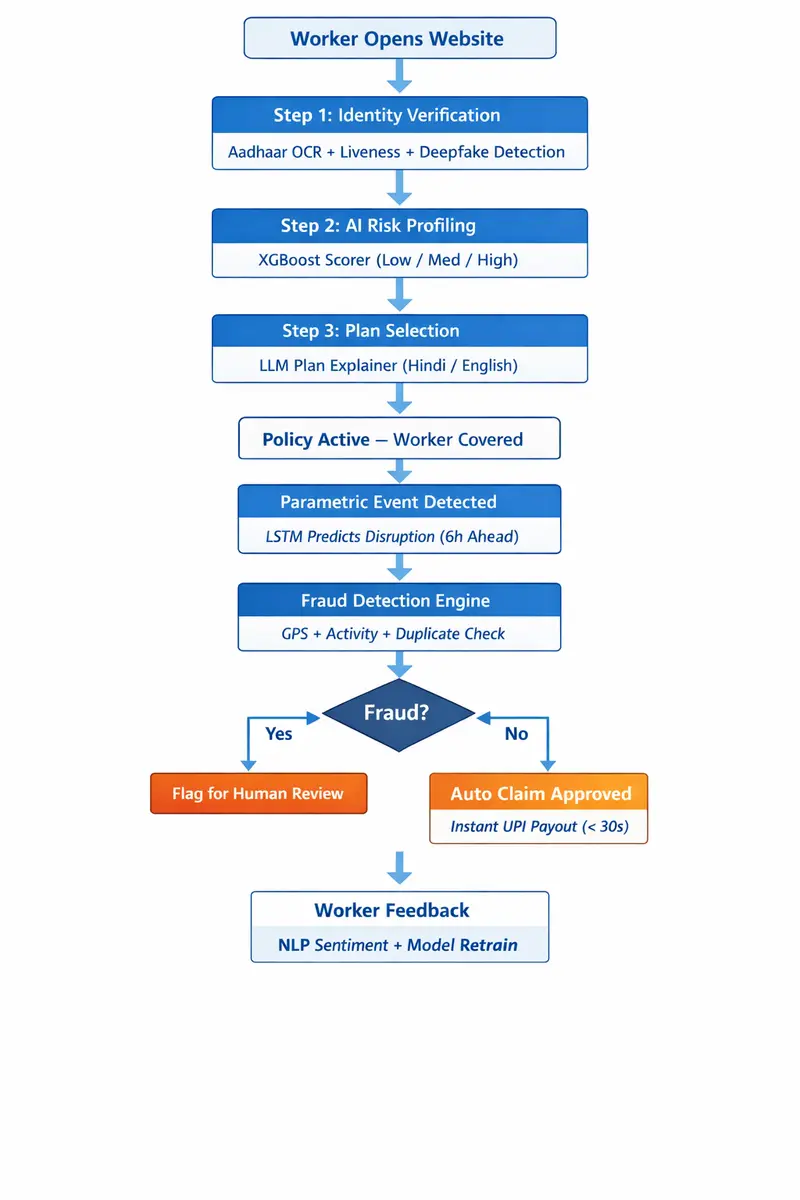
We kept the experience dead simple and powerful:

  1. User signs up (Aadhaar + platform partner ID)
  2. Background risk profiling runs instantly
  3. AI recommends a personalized weekly plan
  4. User subscribes via UPI
  5. System continuously monitors real-world data
  6. Trigger met → instant payout

The entire journey had to feel automatic, invisible, and trustworthy.

Day 3: Adding Intelligence with AI/ML

We refused to settle for static rules. The system had to be smart and adaptive.

Here’s what we built:

  • Risk Profiling — XGBoost model classifying users into dynamic risk tiers
  • Weather & Disruption Forecasting — LSTM-based prediction engine
  • Fraud Detection — Isolation Forest + custom anomaly detection
  • Plan Recommendation Engine — personalized weekly plans that evolve with user behavior

Every week the models retrain and improve. The system literally gets smarter over time.

Day 4: Why We Chose a Progressive Web App (PWA)

We made a very deliberate technical decision: no native app.

Our users typically run low-end Android devices, have limited storage, and need instant access. So we built a blazing-fast PWA:

  • Zero installation friction
  • Works offline where possible
  • Instant updates without Play Store delays
  • Can still be “installed” to the home screen

Sometimes the simplest technical choice is the most user-centric one.

Day 5: The Magic Moment – Instant Payouts

This is where everything clicks.

Real-world example:

Heavy rain hits a city. Rainfall crosses the threshold. The system pulls live data from IMD and CPCB APIs, verifies conditions, and triggers a UPI payout in seconds.

No forms.

No approvals.

No stress.

Just money in the partner’s account when they need it most.

Under the Hood: The Tech Stack

Frontend

  • React.js + Tailwind CSS
  • Full PWA implementation (service workers, offline support, install prompts)

Backend

  • Node.js (Fastify for performance) + Express where needed

Database & Infrastructure

  • MongoDB (flexible schemas)
  • Redis (caching + rate limiting + session management)
  • AWS (EC2, ECS, S3, CloudWatch)

Key Integrations

  • Aadhaar eKYC via UIDAI sandbox
  • Razorpay UPI for instant payouts
  • IMD Weather API + CPCB Air Quality API

Sentinel: Our Fraud Detection Layer

Automation is powerful -but only when it’s safe.

We built Sentinel, a dedicated fraud prevention engine that:

  • Detects GPS spoofing in real time
  • Flags unnatural activity patterns
  • Identifies duplicate or suspicious accounts
  • Routes clean claims for instant approval
  • Flags high-risk cases for human review

Trust without naivety.

📊 Real Impact Scenario

Picture a delivery partner earning ₹600–800 per day.

When heavy rain washes out the entire evening shift, Zenvest automatically detects the trigger and credits the payout within seconds.

No panic.

No lost income.

Just dignity and continuity.

Phase 1 Results & What’s Next

We’re proud to share that Zenvest scored 4/5 stars in Phase 1 of the hackathon.

The judges loved the real-world problem, the parametric approach, and the technical depth. But more importantly, the idea clearly resonated.

This was just the beginning.

🤝 We Want Your Feedback, Dev Community

We’re still early and actively iterating. If you’ve made it this far, we’d genuinely love your thoughts:

  • What would you improve in the architecture?
  • Better approaches for fraud detection at scale?
  • Ideas for expanding parametric triggers?
  • UI/UX suggestions for gig workers?

Drop your comments below. We’re building this in public and learning with every conversation.

Thanks for reading.

If this story or the problem resonates with you, let’s connect. Whether you’re a developer, designer, gig worker, or just someone who believes technology should solve real Indian problems — we’d love to hear from you.

Let’s build something that actually matters.

— The Zenvest Team

I Got Tired of Switching Between curl and Postman — So I Built My Own CLI

I didn’t start this project to build “another HTTP tool.”

I started it because I was frustrated.

Github : https://github.com/I-invincib1e/Httli

Every time I worked with APIs, I found myself stuck between two extremes:

  • curl → powerful, but painful to reuse, ugly output, hard to manage workflows
  • Postman → beautiful and powerful, but not scriptable, not terminal-friendly

And I kept thinking…

Why do I have to choose between these two worlds?

The Real Problem

The issue wasn’t making a single API request.

It was everything around it:

  • Reusing requests
  • Extracting values (like tokens)
  • Running flows (login → fetch → update)
  • Using it inside scripts or CI

With curl, I ended up writing messy bash scripts.
With Postman, I was clicking around with no automation.

There was no clean bridge between the two.

The Idea

I wanted something simple:

A CLI tool that feels like Postman… but behaves like curl.

That’s how Httli started.

What Httli Became

Over time, it turned into something much more than I expected.

Not just a request tool — but a workflow engine inside the terminal.

🔧 Real Example

Here’s the kind of flow I always wanted:

# Save a request
httli collection save auth/login 
  -u https://api.example.com/login 
  -m POST 
  -d @payload.json

# Run it and extract token
TOKEN=$(httli collection run auth/login -x .data.token)

# Run full workflow
httli collection run-all auth/ --fail-fast

That’s it.

No switching tools.
No messy scripts.
No manual copying.

✨ Key Features

1. JSON Output for Automation

httli request send -u https://httpbin.org/get --format json | jq '.ok'

Clean, structured output — perfect for scripts and CI.

2. Native Data Extraction

httli request send -u /login -x .data.token

No need for jq if you don’t want it.

3. Proper Failure Handling

httli request send -u /404 --fail

Exits with code 22 (like curl), making it CI-friendly.

4. Project-Based Workflows

Just create a .httli/ folder:

mkdir .httli

Now your collections live inside your project.

  • Share with your team
  • Commit to Git
  • Run anywhere

5. Namespaced Collections

httli collection save auth/login ...
httli collection save auth/refresh ...

Grouped automatically:

auth/
  - login
  - refresh

6. Batch Execution (run-all)

httli collection run-all auth/ --fail-fast

Run full API flows with built-in chaining:

  • HTTLI_LAST_STATUS
  • HTTLI_LAST_JSON
  • HTTLI_LAST_BODY_PATH

🧠 How It Evolved

This project didn’t start clean.

At first, it was:

  • hardcoded command handling
  • limited depth
  • basic output

Then I rebuilt the core using a recursive command walker.

That changed everything.

Now:

  • commands can be nested infinitely
  • logic is clean and modular
  • new features don’t break old ones

🤖 Yes, I Used AI

I’ll be honest — I used AI heavily while building this.

But not in the way people assume.

AI didn’t “build it for me.”

It helped me:

  • move faster
  • explore ideas
  • refine implementations

The real challenge was still:

  • designing the system
  • making tradeoffs
  • deciding what should exist

And honestly, that’s the part I enjoyed the most.

🚀 Why I’m Sharing This

Right now, Httli is at a stage where it’s:

  • stable
  • scriptable
  • actually useful

But tools only get better when people use them.

🤝 I’d Love Your Feedback

If this sounds interesting, try it out:

go install github.com/I-invincib1e/httli@latest

And tell me:

  • what feels good
  • what feels missing
  • what breaks

🔮 What’s Next

I’m thinking about adding:

  • smarter workflows
  • maybe AI-assisted request generation
  • deeper automation features

But for now, I want to focus on making the current experience solid.

Final Thought

I didn’t build Httli to replace curl or Postman.

I built it because I needed something in between.

If you’ve ever felt that gap too —
this might be useful to you.

Github : https://github.com/I-invincib1e/Httli

⭐ If you like it, consider starring the repo
🤝 And if you want to contribute, I’d love that even more

From Naive to Agentic: A Developer’s Guide to RAG Architectures

If you’ve built even one LLM application, you’ve likely encountered the hallucination problem. Your model sounds confident but makes things up. Or worse, it knows nothing about your company’s private data because its training cutoff was two years ago.

Enter RAG (Retrieval-Augmented Generation).

RAG is the standard pattern for connecting LLMs to external knowledge. But here’s the catch: Not all RAG pipelines are created equal. A simple “retrieve-and-read” setup might work for a demo, but it will fail in production.

In this article, we’ll break down the 4 main types of RAG architectures, what specific problems they solve, and how to choose the right one for your use case.

🧱 1. Naive RAG (The “Hello World”)

This is the baseline implementation you see in most tutorials.

The Flow:

User Query → Vector Search → Top K Chunks → LLM → Answer

The Problem It Solves (and Creates)

  • Solves: Basic knowledge grounding. It stops the model from relying solely on parametric memory.
  • Creates: Low precision and recall. You often retrieve irrelevant chunks or miss critical info due to poor chunking. It struggles with ambiguous queries.

🛠️ When to Use

  • Prototyping MVPs.
  • Simple Q&A over clean, well-structured documents.
  • Low-stakes internal tools.

🚀 2. Advanced RAG (The Production Standard)

Advanced RAG takes the naive pipeline and optimizes every stage: Pre-retrieval, Retrieval, and Post-retrieval.

The Flow:

Query → [Rewriting/Expansion] → Hybrid Search → [Re-Ranking] → LLM → Answer

The Problem It Solves

  • Noise Reduction: Naive RAG sends irrelevant context to the LLM, confusing it. Advanced RAG uses re-ranking models (like Cross-Encoders) to sort results by relevance before generation.
  • Semantic Gap: Users ask questions differently than documents are written. Advanced RAG uses query transformation (HyDE, step-back prompting) to bridge this gap.
  • Chunking Issues: Solves the “lost in the middle” phenomenon by optimizing chunk sizes and using parent-document retrievers.

🛠️ When to Use

  • Customer-facing support bots.
  • Enterprise search where accuracy is critical.
  • When you notice the LLM ignoring relevant context or hallucinating despite retrieval.

🧩 3. Modular RAG (The Composable Architecture)

Modular RAG treats retrieval as a set of interchangeable functions rather than a linear pipeline. You can mix and match modules like search, memory, fusion, and routing.

The Flow:

Query → [Router] → [Search Module OR Memory Module OR API] → [Fusion] → LLM

The Problem It Solves

  • One-Size-Fits-All Failure: Some queries need SQL, others need vector search, others need keyword search. Modular RAG uses a router to pick the right tool.
  • Complex Context: It enables patterns like Recursive Retrieval (fetching small chunks, then their parent documents) or Iterative Retrieval (searching multiple times based on previous findings).

🛠️ When to Use

  • Systems with multiple data sources (SQL + PDFs + APIs).
  • Complex domains where queries vary wildly in intent.
  • When you need fine-grained control over the retrieval logic.

🤖 4. Agentic RAG (The Autonomous Workflow)

This is the bleeding edge. Here, the LLM isn’t just a generator; it’s an agent that plans, executes, and reflects.

The Flow:

Agent Plans → Tool Use (Search/Calc) → Self-Correction → Final Answer

The Problem It Solves

  • Multi-Hop Reasoning: Naive RAG fails when the answer requires combining info from Document A and Document B. Agentic RAG can retrieve A, realize it needs B, retrieve B, then synthesize.
  • Dynamic Verification: The agent can critique its own retrieved context. If the info looks outdated or conflicting, it can self-correct and search again.
  • Tool Selection: It decides dynamically whether to search the vector DB, query a SQL database, or call a web search API.

🛠️ When to Use

  • Complex research assistants.
  • Financial or legal analysis requiring multi-step verification.
  • Workflows where latency is less critical than accuracy and reasoning depth.

📊 Quick Comparison Table

Architecture Complexity Latency Accuracy Best For
Naive Low Low Medium MVPs, Demos
Advanced Medium Medium High Production Apps
Modular High Medium High Multi-source Data
Agentic Very High High Very High Complex Reasoning

🧭 How to Choose? (A Decision Framework)

Don’t start with Agentic RAG. You’ll overengineer it. Follow this ladder:

  1. Start with Naive: Build a basic pipeline with LangChain or LlamaIndex. Evaluate it.
  2. Move to Advanced: If accuracy is <80%, add Hybrid Search and a Re-Ranker. Optimize your chunking strategy.
  3. Go Modular: If you have diverse data types (tables + text), implement a Router to direct queries to the right retriever.
  4. Evolve to Agentic: Only if users need multi-step reasoning (e.g., “Compare Q1 sales to Q2 marketing spend”) should you introduce agent loops.

💡 Key Takeaway

RAG isn’t a single technique; it’s a spectrum of architectures.

  • Naive proves connectivity.
  • Advanced ensures reliability.
  • Modular ensures flexibility.
  • Agentic ensures reasoning.

Most production systems today thrive with Advanced RAG. Save the complexity of Agentic workflows for problems that truly require reasoning, not just retrieval.

DevOS: Notion MCP Challenge

Project Demo

This is a submission for the Notion MCP Challenge

Project Demo

Workflow

Workflow

What I Built

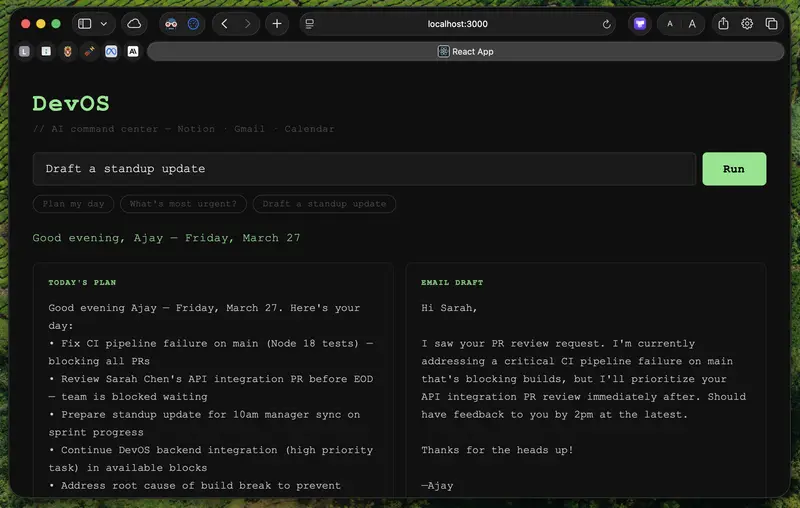
DevOS is an AI-powered daily command center for software engineers. You type one natural language command — like “Plan my day” or “What’s most urgent?” — and it pulls your real tasks from Notion via MCP, cross-references your Gmail inbox and Google Calendar, and uses Claude to synthesize everything into:

  • A prioritized daily plan
  • An email draft for your most urgent message
  • A reasoning explanation of why your top task matters most right now

The plan is then automatically written back to your Notion workspace as a “Today’s Plan” page — creating a live read-write loop between your AI assistant and your actual work context.

No tab-switching, no copy-pasting context into a chatbot. One prompt, full context, actionable output.

Show us the code

GitHub logo

AjayMaan13
/
DevOS

An AI-powered command center that turns your Notion, email, calendar, and code into one intelligent workflow.

DevOS

AI-powered command center for software engineers. One prompt. Live context from Notion, Gmail, and Google Calendar.

DevOS Screenshot

Workflow

DevOS Workflow

What It Does

DevOS is a local AI assistant that reads your actual work context — not a generic chatbot making things up. Type one natural language command and it simultaneously reads your Notion tasks, Gmail inbox, and Google Calendar. Claude synthesizes everything into a daily plan, an email draft, a priority explainer that tells you why a specific task matters most right now, and writes the plan back to your Notion workspace automatically.

How It Works

  1. You type a command in the React frontend (localhost:3000)
  2. Frontend POSTs to an Express backend on port 3001
  3. Backend makes a live call to Notion MCP — fetching your real tasks from your workspace
  4. Claude receives Notion data plus email and calendar context
  5. Claude returns a JSON object with four fields: plan…

How I Used Notion MCP

Notion MCP is the core data source. When you run a command, the Express backend makes a live call to mcp.notion.com/mcp using Anthropic’s MCP client beta — fetching your real tasks with their status and priority directly from your workspace. No hardcoded mock data, no manual Notion API pagination. MCP handles the tool discovery and execution.

That Notion context is then fed into a Claude synthesis call alongside email and calendar data. Claude returns structured JSON, and the frontend renders each field in its own panel.

The write-back side uses the Notion REST API to create a new “Today’s Plan” page under a configurable parent page after every run. So Notion isn’t just a data source — it’s also the destination. Your AI-generated plan lives right alongside your tasks in the same workspace.

What MCP unlocks here is the ability to treat Notion as a live, queryable context layer for AI — not just a static database you export from. The AI reads your workspace, reasons over it, and writes back to it, all in a single command cycle.