The Trust Layer Nobody Built: Why AI Agents Need Verification Before They Can Spend

The Trust Layer Nobody Built: Why AI Agents Need Verification Before They Can Spend

Two developments this week exposed the same gap in agentic infrastructure. Mastercard and Google open-sourced Verifiable Intent, a cryptographic framework that proves an AI agent is doing exactly what its human authorized. Ramp shipped Agent Cards, giving AI agents their own corporate credit lines with built-in spend limits and merchant restrictions.

Different companies. Different approaches. Same realization: the missing piece for autonomous AI commerce is not capability – it is trust.

Here is what the infrastructure layer for agentic payments is actually becoming, and why the companies building verification are positioning themselves at the center of the machine economy.

The Problem No One Talked About

Only about 16% of U.S. consumers trust AI to make payments on their behalf. That is not a marketing problem. It is an architectural one.

When an AI agent spends money, three questions surface immediately:

  1. Authorization: Did the human actually permit this?
  2. Boundaries: Is the agent staying within approved limits?
  3. Auditability: Can we prove what happened after the fact?

Traditional payment infrastructure answers none of these. A credit card transaction shows a merchant and an amount. It does not encode why the purchase happened, who initiated it, or whether it violated any constraints.

For human spending, that ambiguity is tolerable. For agent spending, it is a non-starter.

What Verifiable Intent Actually Does

Mastercard and Google’s framework creates cryptographic proof that an AI agent is operating within bounds a human explicitly set. Think of it as a digitally signed power of attorney with machine-enforceable constraints.

The architecture has three layers:

  • Credential Provider – A bank or wallet binds the user identity
  • Mandate Issuance – The user defines what the agent can do (amount caps, merchant allowlists, time windows)
  • Proof Generation – When the agent transacts, it signs proof of compliance

The agent operates autonomously, but every action leaves a tamper-evident audit trail. Merchants see what they need. Issuers can distinguish legitimate activity from compromise. Disputes become simple: either the cryptographic trail confirms compliance, or it does not.

This is not theoretical. Adyen, Fiserv, Checkout.com, Worldpay, and IBM have already endorsed it. The Python SDK is live under Apache 2.0.

What Ramp Agent Cards Solve

Ramp took a different angle. Instead of building a protocol for the ecosystem, they built a product for their existing customer base. Agent Cards are virtual corporate cards issued directly to AI agents under a business’s Ramp account.

The agent never sees a card number. It calls an API (or uses Anthropic’s Model Context Protocol) to request payment. Ramp’s backend enforces hard constraints:

  • Spend limits
  • Merchant whitelists
  • Category blocks
  • Full transaction logging with reasoning context

The brilliance is integration. Ramp has spent years building AI tools for expense policy enforcement, invoice fraud detection, and automated bookkeeping. Agent Cards close the loop: agents that already read, decide, and reconcile can now pay, all within one platform with one audit trail.

Visa’s Intelligent Commerce sandbox has more live agent transactions, but no equivalent open intent specification. Mastercard is seeding infrastructure while Ramp is capturing immediate enterprise value.

Why Infrastructure Beats Products Here

The strategic divergence matters. Mastercard’s open-source framework can be adopted by any payments company. Ramp’s Agent Cards only work within Ramp’s ecosystem.

History suggests infrastructure wins:

  • EMV chip became ubiquitous because Visa and Mastercard agreed on a standard and pushed it across their networks
  • Tokenization became the default because Apple Pay and the networks aligned on a common approach
  • Verifiable Intent follows the same playbook: open the spec, let adoption spread, sit at the center of verification

Ramp’s data advantage is real. They have billions in monthly spend, GL coding patterns, and vendor relationships across 50,000 businesses. That lets them make smarter authorization decisions than pure card issuers.

But the liability question remains unanswered: when an agent overspends or buys the wrong thing, who is responsible? Ramp? The agent builder? The business?

The framework does not resolve this. It just makes it auditable.

The Real Adoption Path: B2B Procurement

Consumer shopping agents will exist. But the fastest adoption will come from B2B procurement.

A procurement agent that:

  • Stays within pre-approved vendor lists
  • Never exceeds budget thresholds
  • Logs every purchase decision with reasoning
  • Automatically matches invoices to purchase orders

That is a CFO’s dream. The ROI is immediate and measurable. The trust gap is smaller because the human is already authorizing spend policies for human employees.

Agent Cards and Verifiable Intent both start there. Enterprise card programs quietly converting to scoped agent mandates within 18 to 24 months is not a prediction. It is already underway.

What to Watch

Three developments will determine whether this infrastructure layer actually holds:

1. OCC Rulemaking on Stablecoin Rewards
The GENIUS Act gave stablecoins a federal framework. But the OCC’s proposed rules could eliminate deposit-like rewards on stablecoin balances. If PayPal’s 3.7% on PYUSD and Coinbase’s 3.5% on USDC savings disappear, the consumer acquisition lever for stablecoin-based agent spending weakens significantly.

2. Visa’s Response
Visa has Intelligent Commerce live with 100+ partners. They are running live agent transactions. But no open intent spec has emerged. If Mastercard’s Verifiable Intent becomes the de facto standard, Visa either adopts it or builds a competing framework. Fragmentation here would slow enterprise adoption.

3. Liability Precedents
When the first major agent-driven fraud or mistake reaches litigation, the courts will define who owns the risk. The frameworks provide evidence. They do not assign blame.

The Takeaway

Every payments era has a trust primitive that unlocks it:

  • Mag stripes answered “is this card real?”
  • Tokenization answered “can we keep credentials safe online?”
  • Verifiable Intent answers “did this AI agent actually have permission to spend that money?”

The race now is not to build the best AI shopping agent. It is to become the default trust layer those agents rely on.

Mastercard just open-sourced the track and handed out the cars. Ramp built a fast car but locked it to their track. The infrastructure play has more leverage.

Expect both strategies to coexist for a while. But the long-term value capture sits with whoever owns the verification standard, not whoever issues the most agent cards.

The infrastructure for machines spending money is being built right now. The question is whether you are building the track or just driving on someone else’s.

Give Your AI Agent Real-Time Shipping Intelligence in 2 Minutes

If you’re building AI agents that touch logistics, supply chain, or international trade, you’ve probably hit this wall: your agent can reason about shipping but has zero access to actual rate data.

No freight rates. No demurrage charges. No surcharge breakdowns. No port congestion info. Just hallucinated numbers.

I built ShippingRates to fix that — 24 MCP tools that give any AI agent real-time access to ocean shipping data from Maersk, MSC, CMA-CGM, Hapag-Lloyd, ONE, and COSCO across 184 countries.

It’s now live on the Apify Store as a pay-per-event MCP server. No crypto wallet needed. No API key setup. Just connect and query.

What you get

Free tools (no charge):

  • shippingrates_stats — database coverage stats
  • shippingrates_lines — list all carriers
  • shippingrates_search — full-text search across all data
  • shippingrates_fx — currency exchange rates

Paid tools ($0.03 – $0.35 per call):

  • Demurrage & detention calculators (per carrier, per country, per container type)
  • Freight rate lookups by trade lane
  • Surcharge breakdowns (BAF, CAF, GRI, PSS, war risk)
  • Port congestion data and vessel schedules
  • Local charges (THC, documentation fees, seal fees)
  • Inland haulage rates and CFS tariffs
  • Total landed cost calculator
  • Route risk scoring

All data is verified from official carrier tariff PDFs. Zero estimates, zero hallucinations.

Connect to Claude Desktop

Add this to your claude_desktop_config.json:

{
  "mcpServers": {
    "shippingrates": {
      "url": "https://vinaybhosle--shippingrates-mcp.apify.actor/mcp"
    }
  }
}

That’s it. Claude now has access to all 24 shipping tools.

Example: Calculate D&D costs

Once connected, just ask Claude:

“What are the demurrage charges for a 40HC container with Maersk in India if I’m 5 days late?”

Claude calls shippingrates_dd_calculate and returns the actual slab-by-slab breakdown from the carrier’s published tariff — not a guess.

Example: Compare carriers

“Compare detention rates across all 6 carriers for a 20GP container in Germany”

Claude calls shippingrates_dd_compare and returns a side-by-side comparison table showing free days, per-diem rates, and total cost at different day counts.

Why this matters

Container shipping has $2.3 trillion in annual cargo value. The data is fragmented across carrier PDFs, port authority websites, and proprietary systems. AI agents need structured, real-time access to this data to be useful in logistics workflows.

This is the first shipping intelligence MCP server on the Apify Store. If you’re building anything in freight tech, trade compliance, or supply chain automation — this is your data layer.

Links

Developer Productivity in the Age of AI

Authors: Andrew Rutherfoord, Delia Popa, Ioannis Loukas

Introduction

AI coding tools use large language models to generate code to achieve the desired goals of a developer. These tools are increasingly used in the software engineering field, with the goal of accelerating implementation work and reducing developer effort. Despite their rapid adoption, the extent to which these tools improve developer productivity remains unclear. Therefore, we aim to bridge this research gap and study the use of these tools and whether it has a measurable impact on productivity.

Background

Software productivity encompasses objective dimensions (effort vs. output) and subjective perceptions of efficiency (al 2025). We focus on objective metrics—commit frequency, loc modified, and code churn—to measure delivery.

Code churn is “commonly used to capture the intensity of software changes” (Gomes et al. 2026) and excessive churn in code files can be associated with poor design and technical debt. Therefore, churn can be used as an objective metric for code quality by analyzing changes per file over time.

Methodology

In order to assess how AI assisted tools contribute to developer productivity, we aim to answer the following RQs:

  1. To what extent does the adoption of AI programming tools affect developer productivity?

  2. How does the adoption of AI programming tools affect code rework trends?

By analyzing code output and code churn, we can get a full understanding of productivity since raw output volume may be incomplete if that code is being reworked repeatedly.

We hypothesize that the adoption of AI programming tools increases development productivity, but also results in increased code rework.

Productivity metrics

To answer our RQs, we compare metrics before and after AI adoption using statistical testing. We compute metrics per commit (each commit is one observation) and weekly (commits aggregated by week), shown in Tables 1 and 2. These metrics combine raw output and quality of changes. For example, files_touched shows how broad the changes made were, whilst add_delete_ratio provides information about the balance between new code and refactoring.

Code name Definition
churn Lines added + lines removed. (Faragó et al. 2015)
net_added Lines added not removed in the same commit.
net_removed Lines removed not added in the same commit.
files_touched Number of files modified in the commit.
is_net_negative 1 if net_removed > net_added, else 0.

Per-commit productivity metrics.

Code name Definition
gross_churn Weekly total lines added + lines removed.
net_added Weekly total net added lines.
net_removed Weekly total net removed lines.
net_negative_commits net_removed - net_added.
add_delete_ratio total_added / total_removed.
total_commits Number of commits in the week.
files_touched_per_commit Weekly files_touched divided by total_commits.

Weekly productivity metrics (aggregated by week).

Dataset Construction

We constructed a dataset of open-source GitHub repositories, allowing us to analyze productivity before and after AI adoption. Using Google Dorks, we identified 412 repositories containing CLAUDE.md or AGENTS.md files. These artifacts provide context for agentic AI tools, signaling extensive AI integration within the project.

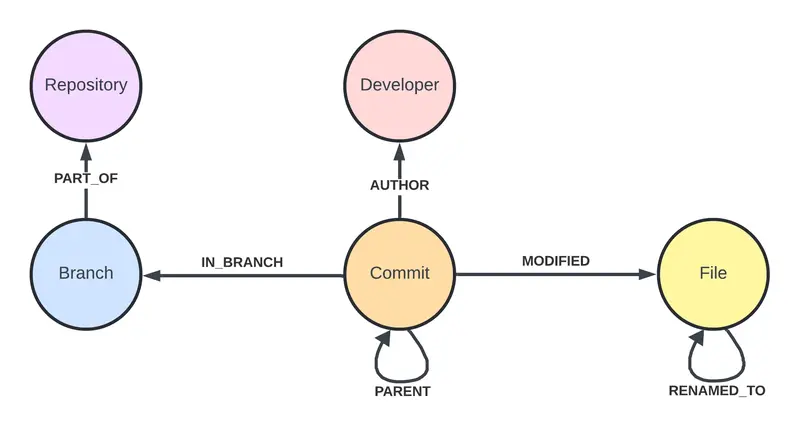
We extracted repository data using NeoRepro 1 which utilizes PyDriller to extract repository data, including file modifications, and stores it in a Neo4j graph database (Rutherfoord, n.d.). Data structure is shown in Figure 1. The tool extracts file modifications, and the git diff for each file and stores it on the MODIFIED relation, allowing us to analyze the code changes for our code churn research question. 2

Structure of Data in Neo4j after extraction using NeoRepro (Rutherfoord, n.d.).

Dataset Cleaning

To provide reliable results we exclude repositories with insufficient data for pre- and post adoption comparison. Therefore, we exclude repositories with fewer than 500 total commits, or fewer than 50 commits before or after AI adoption, leaving 180 repositories.

Proportion of different programming language files used for analysis.

Furthermore, we grouped related programming-language files by related extensions (eg. .c and .h as C) to consolidate analysis of languages. Finally, we limited our analysis to language groups with at least 1000 files in the dataset (Figure 2).

Dataset Overview

Total number of commits before and after creation of AI artifact.

Distribution of artifact age.Dataset overview.

Figure 5 shows commit distribution before and after the creation of the artifact file across all repositories, revealing approximately five times more commits indexed before. Furthermore, Figure 5 show the average age of the artifact is 150 days (approximately 5 months). Although this is not enough time to understand the long term effects of AI tool usage, it is sufficient data to understand the trends after adoption of the artifacts.

Analysis Design

Since our commit data is time-bound, we use method suited to time-series data for analysis. We analyze changes in metrics by comparing trends from pre- and post AI tool adoption, with the artifact creation date as the adoption cutoff. We aggregated the metrics on a weekly basis and performed two tests to ensure reliable results. To understand whether the effects differ between programming languages, we performed analysis on a per language basis, as well as all languages as a baseline. To avoid skew from long pre-adoption histories, we trimmed each repository’s pre adoption history to 1.5 times the length of the post adoption data.

For the analysis, we first perform an intervention analysis using a time-series ARIMAX model (ARIMA with exogenous regressor) (“What Is an ARIMAX Model?” n.d.) to test whether the introduction of AI tools is associated with a change in productivity and churn. This allowed us to estimate whether the adoption was followed by immediate change in the metric and/or a sustained change in the metric weekly trend. For each series, we automatically select the ARIMA parameters (p, d, q) using the pmdarima.autoarima 3 Python package.

Secondly, to ensure reliability, we use a two sample t-test to compare the average metric for each repository’s before and after adoption. Additionally, we apply post adoption offsets of 0, 2 and 4 weeks to reduce sensitivity to short spikes immediately after adoption.

For our statistical analysis we used a significant value of p = 0.1.

Results

Across all analysis, most repositories do not show a significant change post adoption of AI for all metrics. We will review the subset of repositories which showed a statistically significant change, rather than changes across the entire project set.

Direction of post adoption instantaneous changes

The heatmap in Figure 6 shows, per language group, the share of repositories for which the ARIMAX model detects a statistically significant instantaneous post adoption level shift for each metric. Overall, immediate effects are uncommon since for most metrics and languages, less than 10% of repositories show significant changes. This suggests that AI adoption is generally not associated with an immediate change in activity or churn metrics across projects. However, total commit is an exception, with 12% of projects seeing a change across all languages, especially for Python (20%) and Javascript (14%). Furthermore, Python shows comparatively high significance for net added (17%) and gross churn (14%), whereas most other churn metrics remain low.

Repositories with statistically significant immediate post adoption effect per programming language.

Figure 7 further breaks down the immediate effects for Python, showing the direction of the significant changes. For total commits, the significant change is primarily negative, indicating that most projects saw a decrease in commits per week. Conversely, net added shows a balanced change, showing that there was no consistent direction of change. This combination of fewer commits but similar additions suggests that post adoption changes in Python may be associated with fewer, larger commits.

Significant post adoption immediate changes — Python.

Trend changes after adoption

Contrary to the immediate effects, Figure 8 shows that significant post adoption trend changes are more common.

The total commits metric appears to be the most consistently affected one across several programming language groups (27%), with JavaScript (30%), Python (26%), Go (25%), and C (23%) showing the significant changes. This further suggests that artifact creation is often associated with a gradual change in development over time rather than an instantaneous shift at AI adoption.

Furthermore, files touched per commit shows a consistent shift (16% overall), particularly for JavaScript (17%), Python (16%), Go (15%), and CSS (14%), which indicates a notable change in commit breath across languages.

Repositories with statistically significant post adoption trend effect per programming language.

For Python repositories (Figure 9), the most dominant pattern is the negative trend change across most metrics. In particular, total commits, net added, add delete ratio and files touched per commit showed a predominantly negative shift. This suggests that in Python repositories where a significant trend effect is identified, adoption is associated more with an overall decrease in activity rather than sustained increase. A notable exception is net negative, where a positive trend is observed, with deletions increasingly outweighing additions over time. Overall, for Python repositories, there is a generally downward shift in post adoption trajectory in repositories which exhibited a significant trend change.

Significant post adoption trend changes — Python.

For JavaScript repositories (Figure 10), the pattern is somewhat similar to the Python repositories, but less negative overall. The strongest trend effect is again observed for the total commits, where the negative changes account for the largest share of significant results. These trend changes are also quite prominent across gross churn, net added and files touched per commit. Concurrently, net negative and add delete ratio show a rather mixed pattern, where both positive and negative trends are present. This shows that in the case of JavaScript repositories there is a sense of heterogeneity in post AI adoption evolution.

Significant post adoption trend changes — JavaScript.

Paired t-test results

Group Metric Delay Repos number Mean Diff Median Diff Period
All gross churn 0 119 1815.067 197.375 weeks
All net added 0 119 602.957 96.259 weeks
All total commits 0 119 2.511 0.333 weeks
Go net removed 2 13 449.347 7.800 weeks
CSS net removed 2 47 11.798 0.000 weeks
CSS files touched per commit 2 47 0.252 0.106 weeks
Rust is net negative 0 14 -0.023 -0.028 commits
Bash files touched 0 17 -0.376 -0.133 commits
All is net negative 0 112 -0.011 -0.010 commits
Rust is net negative 2 14 -0.022 -0.026 commits
Bash files touched 2 17 -0.360 -0.176 commits
All is net negative 2 112 -0.011 -0.008 commits
Rust is net negative 4 14 -0.019 -0.027 commits
All is net negative 4 112 -0.012 -0.006 commits

Summary of paired t-test pre/post differences.

The paired comparisons shown in Table 3 suggest that, after the AI artifact creation event, some repositories tend to experience higher development activity and code churn, although this pattern is not uniform across all metrics and language groups. Across all languages, we see positive mean and median differences for gross churn, net added and total commits in the weekly analysis with no delay, indicating that, on average, repositories experienced more lines changed and commits per week after AI adoption.

As for language specific weekly results, while CSS specific repositories have increases in both files touched per commit and net removed. This may indicate that for these languages, post adoption work involved more restructuring, editing or clean up activity rather than focusing on the production of new code. Especially in the CSS case, the increase in files touched per commit might suggest that changes became slightly more widespread across files, which might reflect in overall broader modifications per commit.

Conversely, the results at commit level point towards a reduction in rework as is net negative reduces for the overall sample and for Rust repositories across all delays. Similarly, for Bash, the negative differences in files touched at delays 0 and 2 imply that commits affected fewer files on average after the event, which could suggest localized changes.

Threats to Validity

Validity of Artifact Files

Our methodology assumes that the presence of CLAUDE.md or AGENTS.md files indicates meaningful AI usage from creation date. This can be inaccurate since some repositories may have added for experimentation or documentation purposes, rather than development, whereas others may use AI tools without adding an artifact file to their repository. Furthermore, the file may be introduced after AI use has already begun, making the comparisons inconsistent, as the adoption date would be wrong.

Selection Bias

The repositories analyzed were collected via Google Dorks search queries for CLAUDE.md and AGENTS.md files. Due to rate limits, the results were limited to the first few hundred, limiting sample size to what Google ranked as most relevant. Additionally, the dataset is dominated by Python and Javascript repositories (approximately two-thirds), increasing the statistical significance for those languages.

Short post adoption period

For most repositories, the post AI adoption period is 5 months on average, compared to much longer before. Although we mitigated this, the limited post adoption data may not provide enough time for the effects to stabilize. This can reduce the robustness of the post adoption trend.

Conclusion

This study examined whether the adoption of AI development tooling is associated with measurable changes in open-source developer productivity. We used artifact files to identify when AI was adopted, and compared activity before and after this point using the SARIMAX model to analysis immediate and trend changes.

Across language groups and metrics, we find that most repositories do not show a statistically significant change in output or churn metrics after AI adoption. Immediate effects are rare, seeing fewer than 10% of projects with a significant effect for most metrics, but total commits being an exception. Trend changes are more common than immediate shifts, most consistently for total commits, but with more repositories showing significant results. In JavaScript and Python the effects are more consistent, but generally have a negative trend. For Python repositories, commit frequency trends downwards, suggesting a possible shift toward fewer, larger commits in a subset of projects.

Overall, our results do not support the general claim that usage of AI development tools results in a significant increase in output, nor a change in output quality. Rather, when effects are detectable, they generally show a tendency towards fewer, larger commits.

Due to the empirical nature of our findings, the practical implications are not immediately evident. However, we identified two primary strategies for optimizing AI integration. First, given the sparse impact across languages, adoption could be selective, prioritizing languages with proven performance gains when using general purpse tools. Second, as our data shows a shift toward higher-density commits, developers face an increased cognitive burden during review. We recommend enforcing small-batch commit policies to mitigate this complexity, so AI-driven velocity does not compromise architectural clarity or code integrity.

Future work could aim to use a more targeted methodology by selecting repositories with longer post adoption periods, validating adoption time, and focusing on languages where these tools are more prevalent. This would allow for more robust analysis of the effects of longer term AI usage.

Replication package available on GitHub: AndrewRutherfoord/ai-dev-productivity-data-replication-package

References

al, Weisz et. 2025. “Examining the Use and Impact of an AI Code Assistant on Developer Productivity and Experience in the Enterprise.” CHI EA ’25: Extended Abstracts of the CHI Conference on Human Factors in Computing Systems.

Faragó, Csaba, Péter Hegedűs, and Rudolf Ferenc. 2015. “Cumulative Code Churn: Impact on Maintainability.” 2015 IEEE 15th International Working Conference on Source Code Analysis and Manipulation (SCAM), September, 141–50. .

Gomes, Kevin Cerqueira, Elivelton Ramos Cerqueira, Gabriel Moraes, et al. 2026. “Investigating the Relationship Between Churning and Code Smells.” In Software Engineering and Advanced Applications, edited by Davide Taibi and Darja Smite. Springer Nature Switzerland. .

Rutherfoord, Andrew. n.d. NeoRepro: A Tool for Creating Replication Packages for Mining Software Repository Research Using a Graph Database.

“What Is an ARIMAX Model? GeeksforGeeks.” n.d. Accessed March 28, 2026. .

  1. NeoRepro MSR Tool: https://github.com/AndrewRutherfoord/NeoRepro-MSR-Tool ↩

  2. Replication Package with dataset: https://github.com/AndrewRutherfoord/ai-dev-productivity-data-replication-package ↩

  3. Pmdarima package: https://alkaline-ml.com/pmdarima/ ↩

I Built an AI Product Description Generator with Compliance Checking for Japanese E-commerce

The Problem

If you’re an e-commerce seller in Japan, you face two massive challenges:

  1. Writing product descriptions is painfully slow — 30 minutes per product × 1,000 SKUs = 500 hours
  2. Japanese regulations are strict — The Pharmaceutical and Medical Device Act (薬機法) and Act against Unjustifiable Premiums and Misleading Representations (景品表示法) can shut down your listings with a single violation

ChatGPT can help with #1, but it knows nothing about #2.

The Solution: ListingAI

I built ListingAI — an AI-powered product description generator specifically designed for Japanese e-commerce sellers.

What makes it different from ChatGPT?

Feature ChatGPT ListingAI
Single product description ✅ ✅
Bulk generation (1,000+ products) ❌ Manual copy-paste ✅ CSV upload
Platform optimization (Amazon/Rakuten/Shopify) ❌ Generic ✅ Algorithm-specific
Japanese regulatory compliance check ❌ ✅ Automatic
Direct push to Shopify/BASE ❌ ✅ API integration

Regulatory Compliance: The Killer Feature

Japanese e-commerce has unique legal requirements:

  • Pharmaceutical Affairs Act (薬機法): You can’t claim cosmetics “cure” anything or supplements have “anti-aging effects”
  • Premiums and Representations Act (景品表示法): “No.1 in the industry” requires documented proof from a research organization
  • Food Labeling Act (食品表示法): “Additive-free” now requires specifying which additive since April 2025

ListingAI automatically scans generated descriptions for 17+ violation patterns and suggests safe alternatives.

Tech Stack

  • Frontend: Next.js 15 + Tailwind CSS
  • Backend: Next.js API Routes
  • AI: Claude API (Sonnet 4)
  • Database: Supabase (PostgreSQL + Auth)
  • Hosting: Vercel
  • Monthly cost: ~$10-50 (scales with usage)

Programmatic SEO Strategy

I generated 78 static pages targeting long-tail keywords:

  • Platform × Category pages: tools/amazon/beauty, tools/rakuten/supplements (60 pages)
  • Law × Category pages: compliance-guide/yakujihou/beauty (18 pages)

These pages target searches like:

  • “Amazon beauty product description template”
  • “Pharmaceutical Affairs Act cosmetics NG expressions”

All generated at build time via Next.js generateStaticParams().

Results So Far

  • 84 URLs indexed via Google Indexing API
  • 78 pSEO pages targeting long-tail keywords
  • 17 compliance rules for 4 Japanese laws
  • Free tier: 5 generations/month (no credit card required)

Try It

🔗 https://listing-ai-ten.vercel.app

Free to try — 5 product descriptions per month, including compliance checking.

Built with Claude Code in a single session. The entire MVP (AI generation, compliance checking, auth, payments placeholder, pSEO) was built and deployed in one day.

Notion Postmortem Autopilot (Mortis)

Notion Postmortem Autopilot (Mortis)

What We Built

Mortis is an end-to-end incident response system that turns real-world signals into structured postmortems automatically.

When an incident happens (failed deploy, bug, outage), the system detects the signal, generates a structured postmortem draft using AI, writes it into Notion, and routes it through a human approval workflow. Over time, it learns from past incidents and builds organizational memory.

The architecture includes a FastAPI backend for ingestion and orchestration, a Next.js 14 dashboard for review and workflow management, and a shared schema package (JSON Schema and TypeScript types) to keep the frontend and backend aligned.

Mortis also extracts recurring failure patterns into a pattern registry. These patterns are later used to generate pre-mortem warnings during deployments, improving reliability over time.

Problem It Solves

After incidents, teams often lose time gathering context from different tools like Slack, tickets, and logs. Postmortems are frequently delayed, incomplete, or inconsistent, and the insights rarely get reused effectively. As a result, the same issues tend to repeat.

Mortis addresses this by generating a complete first draft instantly, including severity, root cause hypotheses, a five-whys-style analysis, and action items. It integrates directly with Notion, where teams already work, and provides a review queue so humans can approve, reject, or refine the output.

Instead of static documentation, incidents become structured knowledge that compounds over time.

Video Demo

https://drive.google.com/file/d/1oHYhNEyjL__4FjlYfNlXn1I3WBTxZPl_/view

Show Us the Code

Frontend: https://global-hack-week-winning-idea-bq8e-ke4i8jc7z.vercel.app/queue
Backend: https://notion-postmortem-api-production-834e.up.railway.app/

How We Used Notion MCP

Notion MCP is used as the integration layer between the system and Notion.

It enables the backend to create structured postmortem pages with consistent schemas, write incident data directly into Notion databases, and maintain a standardized format across all entries. Teams can then collaborate and make edits inside Notion after the initial draft is generated.

This approach keeps Notion as the system of record, while the backend handles automation and logic, and the frontend handles visibility and approvals. It allows the system to scale without relying on Notion for business logic.

Key Features

  • Automatic postmortem generation
  • Structured root cause analysis (five-whys format)
  • Human-in-the-loop approval workflow
  • Pattern registry for recurring incidents
  • Pre-mortem deployment warnings
  • Shared schema across backend and frontend

Future Vision

The goal is to evolve Mortis into a predictive reliability layer. Instead of reacting to incidents, the system would identify risks before deployments, suggest mitigations, and continuously learn from organizational data.

Built by @topupchips and @kkoorriii

The 15-Millisecond AI: Building “Pre-Cognitive” Edge Caching on AWS

frist image

If you want to watch a product manager’s soul leave their body, sit in on a live demo of a Generative AI feature where the model takes 12 seconds to generate a response.

Typing… typing… typing…

In the world of AI product development, latency is the ultimate UX killer. You can have the smartest prompt and the most expensive foundational model in the world, but if your users have to stare at a spinning loading wheel for 10 seconds every time they click a button, they will abandon your app.

Most engineering teams try to solve this by streaming tokens to the frontend or switching to smaller, less capable models. But as a cloud architect, I prefer a different approach.

What if we stopped waiting for the user to ask the question?

What if we used the user’s application state to predict what they are going to ask, generated the answer in the background, and pushed it to a CDN edge location before their mouse even hovers over the button?

When I sketch this out for engineering leaders, the reaction is almost always the same: “Wait, we can pre-generate AI responses in the background and cache them at the CDN level to completely bypass inference latency?”

Yes. Here is how to build a “Pre-Cognitive” AI architecture using AWS Step Functions, Amazon Bedrock, and Amazon CloudFront with Lambda@Edge.

The Concept: From Reactive AI to Proactive Caching

Think about your favorite SaaS dashboard. When a user logs in on Monday morning, their “next best actions” are highly predictable.

  • They are going to ask for a summary of weekend alerts.
  • They are going to ask for the status of their latest deployment.
  • They are going to ask for a draft reply to their most urgent ticket.

Instead of waiting for the user to click “Summarize Alerts” and forcing them to wait 8 seconds for an LLM to read the data, we move the LLM inference out of the synchronous request path and into an asynchronous background job.

We generate the responses, store them as key-value pairs, and push them to the network edge. When the user finally clicks the button, the response loads in 15 milliseconds. It feels like magic.

The Architecture: Phase 1 (Background Generation)

To make this work without slowing down the initial user login, we decouple the generation using an event-driven flow.

frist image

1. The Trigger: When the user logs in (or enters a specific workflow), your backend fires an event to AWS EventBridge.
2. The Orchestrator: AWS Step Functions takes over. It acts as the background traffic cop, ensuring your API doesn’t hang.
3. The Inference: A Lambda function analyzes the user’s state, grabs the required context, and fires off 3 concurrent prompts to Amazon Bedrock (using a fast, cheap model like Claude 3 Haiku).
4. The Edge Push: Once Bedrock returns the generated text, Lambda pushes these pre-computed AI responses into Amazon CloudFront KeyValueStore (a globally distributed datastore designed specifically for edge functions) keyed by UserID_ActionID.

The Architecture: Phase 2 (The 15ms Delivery)

Now, the user is looking at their dashboard. They see a button that says “✨ Generate Morning Briefing.” They click it.

Because we are using CloudFront and Lambda@Edge (or CloudFront Functions), the request never even reaches your primary backend servers in us-east-1.

second video

1. The Interception: The user’s HTTPS request hits the closest AWS Edge location (e.g., a server in London, Tokyo, or New York). Lambda@Edge intercepts the request.
2. The Edge Lookup: Lambda@Edge checks the attached CloudFront KeyValueStore for the user’s pre-generated response.
3. Instant Delivery: If the response is there, it is returned instantly. The user experiences sub-20ms latency for a complex Generative AI task.
4. The Fallback: If the user asks a completely custom question that we didn’t predict, Lambda@Edge simply forwards the request to your standard API Gateway/Bedrock backend to generate the response synchronously.

The CTO Perspective: Tradeoffs and Reality Checks

As a technology strategist, I will be the first to tell you that “magic” always comes with an engineering invoice. You should only use this pattern if you understand the tradeoffs.

1. The Cost of Wasted Compute

By predicting 3 things the user might ask, you are generating tokens that might never be read. You are trading compute cost for user experience.
The Mitigation: Only use this pattern with ultra-cheap, highly efficient models like Claude 3 Haiku or Llama 3 8B. Do not use Claude 3 Opus or GPT-4o for speculative background generation, or you will torch your AWS bill.

2. State Invalidation

What happens if you pre-generate a “Deployment Summary” at 9:00 AM, but at 9:05 AM a deployment fails, and the user clicks the button at 9:06 AM? The cached AI response is now lying to them.
The Mitigation: Tie your cache invalidation to your application’s critical state changes. If a critical DB row updates, fire an EventBridge rule that immediately deletes the stale key from the CloudFront KeyValueStore.

3. Build Complexity vs. Product Value

Don’t build this for a general-purpose chatbox. Humans are too unpredictable. Build this for highly structured, high-value UX checkpoints—like daily briefings, code review summaries, or personalized dashboard greetings.

The Bottom Line

When we build AI applications, we often forget that the rules of distributed systems still apply. You don’t have to accept the latency of a foundational model as a fixed constraint.

By aggressively predicting user intent and leveraging AWS edge networking primitives like CloudFront and Lambda@Edge, you can completely mask LLM latency.

It takes your application from feeling like a “cool AI wrapper” to feeling like a deeply integrated, hyper-responsive superpower.

Have you struggled with GenAI latency in your production applications? Are you using streaming, or have you started exploring asynchronous generation? Let me know your architecture in the comments below.

Your Data Access Layer Doen’t Understand Databases

Here’s what nobody in the data access space wants to admit: the tools built to simplify database work have quietly offloaded the hardest parts back onto your application. Not by accident — by design. They model a pleasant fiction of what a database is, and when reality diverges, you pay for it in conditionals, workarounds, retries, and production incidents.

This is not a complaint about generated SQL. SQL quality is a separate argument, and an old one. The problem runs deeper.

Connection behavior is not a performance concern. It is a correctness concern.

Most data access layers don’t model that. Your application does — in feature flags, special cases, and debugging sessions you didn’t budget for.

Connection lifetime, concurrency, and identity are not independent concerns. They are the database.

Not all databases are the same machine

Most data access libraries are built around one mental model:

  • The server is already running
  • You connect
  • You execute commands
  • You commit or roll back
  • You disconnect
  • The server waits for the next client

SQL Server, PostgreSQL, Oracle, and MySQL broadly fit that model. For those databases, the standard approach works well enough that the cracks stay hidden for a while.

But not every database works that way.

In-memory embedded databases

SQLite and DuckDB in :memory: mode have a fundamental behavioral difference that most abstractions ignore entirely: the database is the connection.

Open one connection, you have a database. Open a second connection, you don’t get another connection to the same database. You get a different database. Empty. Gone.

That’s not a quirk. That’s the operational model.

A library built around “open and close connections freely per operation” will silently destroy your in-memory database between calls. No error. No warning. Just an empty database where your data used to be.

File-based embedded databases

File-based SQLite and DuckDB are not miniature SQL Servers. Their write behavior is fundamentally different:

  • One writer at a time, enforced at the engine level
  • Concurrent write attempts result in lock contention, busy timeouts, and failures
  • The journal mode and transaction settings interact with connection behavior in ways that bite you if you get them wrong

The standard advice — “open a connection, run a command, close it, repeat” — actively works against you here. Under concurrent load you’ll see lock errors. Under sequential load you’ll see busy timeouts. The “simple” connection pattern creates exactly the contention the database can’t handle.

This is so commonly mishandled that most dedicated SQLite tooling gets it wrong too.

LocalDB

Microsoft’s LocalDB was a genuinely good idea: full SQL Server semantics, no server install, attach a file and go. Great for local development and testing.

Until idle unload enters the picture.

If no connection is held for a configurable period, LocalDB unloads the database. Not an error — an unload. Your next operation reconnects and reattaches, which adds latency and can cause failures during test runs where operations are spaced out.

The fix is a sentinel connection: one persistent connection held open specifically to prevent idle unload. Not for running queries. Just to keep the database alive.

No mainstream data access library models this. You find out about it from a Stack Overflow answer at 11pm.

What the libraries actually do

This is not speculation. Here’s what each major option in the .NET ecosystem actually models.

Entity Framework Core opens and closes connections per query and per SaveChanges() call by default. It delegates pooling entirely to the ADO.NET provider — EF has no awareness of pool pressure or saturation. When you use an in-memory SQLite database with EF, the official workaround documented by Microsoft is to manually open the connection on the DbContext and hold it open for the lifetime of the context. The developer absorbs the problem the library doesn’t solve. There is no connection policy. There is a workaround in the docs.

NHibernate ties connection lifetime to the ISession. It has a more explicit unit-of-work model than EF, which helps with some lifetime issues, but the underlying assumption is unchanged: stable, server-style backend, many connections available, connection lifetime is a performance concern. No single-writer enforcement, no keepalive, no concept of connection-bound database identity.

Dapper doesn’t touch connection lifetime at all. You open it, you pass it in, Dapper runs the command, you close it. That’s the design — deliberately minimal. It’s not a flaw in Dapper. But it means connection policy is 100% on the caller, every time, with no structure and no guardrails.

Raw ADO.NET is the same. The documented guidance is to use using blocks and dispose promptly. That’s the policy: a coding convention. Not a library feature, not an enforced invariant — a convention you either follow or don’t.

None of them model connection policy as a function of database behavior. They model lifetime. They do not model constraints. Connection policy is either delegated to the provider, left to convention, or documented as a workaround.

The connection-per-command trap

Standard advice across almost every data access library is “use one connection per command.” Open, execute, consume results, close. Your DBA will approve. Your server database will be healthier.

That advice has real merit for server databases. It reduces leaks. It shortens connection lifetime. It keeps the pool healthy under normal load.

But follow it everywhere and you create three new problems:

You can’t use in-memory databases for testing. One connection per command means a new empty database on every operation. Your tests pass against nothing.

File-based embedded databases become unreliable. The write serialization problem doesn’t go away because you’re closing connections quickly — it gets worse, because you’re now racing to reacquire write locks constantly.

LocalDB unloads between operations. No persistent connection means no sentinel. Your test suite reconnects and reattaches on every run. Or fails partway through when the unload window closes before your next operation.

So you add feature flags. Database-specific code paths. If-SQLite-do-this, if-LocalDB-do-that. Your business logic now contains your database topology.

That is the abstraction failing at its core job.

Pool saturation: when “doing it right” still breaks

Say you got through all of the above. Feature flags in place. Connection handling tuned per database type. DBA is satisfied, cloud bill is down, everything works.

Then you get a traffic spike.

Requests pile up. Each one opens a connection. The pool has a maximum size — every pool does. Requests start waiting. Wait times compound. At this point you don’t get slow queries — you get connection acquisition failures. SQL Server throws Timeout expired. The timeout period elapsed prior to obtaining a connection from the pool. PostgreSQL reports remaining connection slots are reserved. SQLite escalates busy errors into lock failures.

You need something that governs connections. Not just “open and close promptly” — actual enforcement: when the pool is full, make everything else wait. Bounded concurrency tied to pool size, not just etiquette.

None of the libraries above have this. ADO.NET pooling will queue and timeout, but it doesn’t expose the control surface you need to shape behavior under load. You find out your limits when production hits them.

What you actually need: routing by intent

Databases already differentiate reads and writes. Your access layer doesn’t.

That missing distinction has consequences. If the layer exposed it, it could enforce:

  • Read-only sessions routed to a read replica, drawing from a separate pool
  • Write operations serialized where the database requires it
  • Each pool governed independently, sized to its workload
  • For embedded databases, the write limit set to one — enforced by the layer, not scattered across application code

This isn’t new capability. It’s the modeling that’s missing. Databases have always had these constraints. The access layer just never encoded them.

What modeling it correctly looks like

Connection behavior is a property of the database. It belongs in the data access layer, encoded explicitly, not left to convention or absorbed by the application.

Here’s what that looks like in practice. pengdows.crud exposes connection policy as a first-class configuration decision through DbMode:

Mode What it does When to use it
Standard Pool per operation, open late, close early Server databases: SQL Server, PostgreSQL, Oracle, MySQL
KeepAlive Holds a sentinel connection to prevent idle unload LocalDB
SingleWriter Many concurrent readers, one serialized writer File-based SQLite, file-based DuckDB
SingleConnection One connection, period In-memory :memory: databases
Best Auto-selects the correct mode based on database type When you want the right answer without thinking about it

Best maps automatically: SQLite/DuckDB :memory: gets SingleConnection; file-based SQLite/DuckDB gets SingleWriter; LocalDB gets KeepAlive; everything else gets Standard.

Configuration looks like this:

// File-based SQLite — enforces single writer, concurrent readers
new DatabaseContext(
    new DatabaseContextConfiguration { ConnectionString = connStr, DbMode = DbMode.SingleWriter },
    SqliteFactory.Instance);

// Or let the library decide
new DatabaseContext(connStr, "Microsoft.Data.SqlClient", DbMode.Best);

Correctness is invariant. Performance is tunable. No conditionals. No feature flags. No if-SQLite-else-SqlServer code paths. The layer absorbs the difference because it models the difference.

Pool governance is built in separately from DbMode — a turnstile-based reader/writer governor with bounded permits, drain support, and a telemetry snapshot. When you’re at pool capacity, operations wait in an orderly queue rather than failing. Under contention, the system degrades predictably instead of falling off a cliff.

The real failure

Writing your own SQL does not fix a data access layer that has no opinion about connection policy.

You can drop EF entirely. You can use Dapper. You can write raw ADO.NET. The connection problem follows you. Because the problem isn’t the SQL layer — it’s the operational model underneath it.

The databases have rules. Different rules, depending on the database. Those rules affect correctness, not just performance. A library that doesn’t model them pushes that complexity into your application, where it’s harder to see, harder to test, and easier to get wrong.

Most data access layers don’t understand databases.

They model the happy path of one class of database.

Everything else is your problem.

Beyond the Chatbot: Dhikroh AI — A Framework-Guided Transformation System for Muslimah Women

This is a submission for the Notion MCP Challenge

Most AI tools help you do more.
I built something that helps you become more.
Dhikroh AI is a framework-guided transformation companion for Muslimah women — powered by Notion MCP and the proprietary Becoming Blueprint, a 6-stage inner transformation methodology developed through years of coaching work.
Not generic wellness. Not Islamised self-help. This operates at the level of the nervous system, identity, values, mindset, skills, and behavior — delivering structured inner work for real alignment and lasting evolution.
Because real change doesn’t start with action. It starts with releasing what holds you back.

What I Built

Dhikroh AI guides users through structured inner transformation using four layers of intelligence:

  • 25 named inner shackles with full diagnostic detail and symptom language

  • 7 nervous-system-level identity circuits with spiritual keys

  • 7 transformation stages with readiness mapping

  • 18 reflection prompts, 13 mindset reframe pairings, 13 skills entries
    Three modes make it adaptive:
    Open Companion — She shares what is on her heart. The AI listens, routes to the right framework, retrieves from Notion silently, and responds in a warm, precise, Islamic voice. No generic energy. No hollow affirmations.
    The Becoming Journey — Structured non-linear progression through the Becoming Blueprint. Stage-readiness sensitive. The AI tracks her arc across sessions and coordinates her shackle work so she rises above all of them — not just one.
    Architect Mode — I converse naturally about new insights, client observations, or framework refinements. Dhikroh AI structures them and writes them directly into the Notion knowledge base. No manual database editing. The system learns from me conversationally.
    This is not a demo scaffold. It is a tested methodology delivered through intelligent, context-aware AI.

Video Demo

https://youtube.com/shorts/hVU9htwEy1c?si=tP6eAdBqW5x6vrVv

Show us the code

[https://github.com/tadhy/Dhikroh-ai]
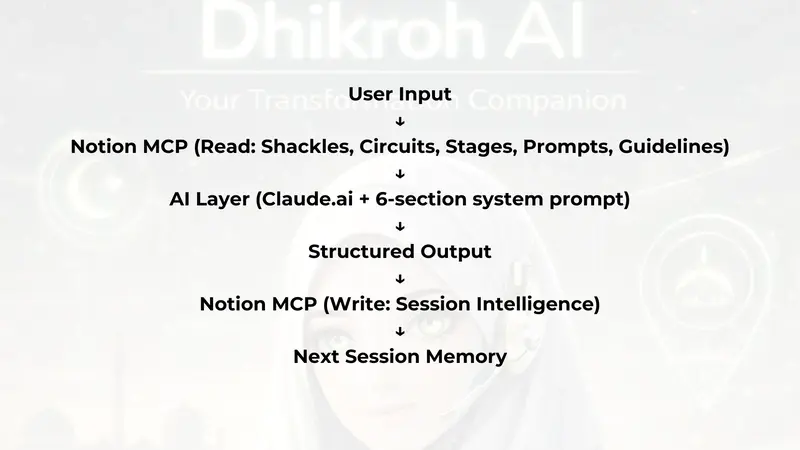
The core of the build is a six-section system prompt governing Dhikroh AI’s identity, voice, operating logic, three-mode detection, nine core principles, and absolute limits — combined with a Notion MCP connection to seven structured databases.

How I Used Notion MCP

Notion MCP is doing two things in this build simultaneously — which is the technical contribution I am most proud of.
Reading — intelligent retrieval:
When a woman shares what is on her heart, Dhikroh AI queries the Inner Shackles database for pattern matches on her symptom language, retrieves relevant circuit roots and diagnostic questions, pulls stage-specific reflection prompts, and checks the Voice and Response Guidelines for how to respond. All of this happens silently. She simply feels understood.
Writing — memory and live growth:
In Architect Mode, Dhikroh AI fetches the Session Intelligence database schema, structures a complete entry from the conversation, presents it for confirmation, and writes it directly to Notion. The knowledge base grows through natural conversation — no manual editing required.

This bidirectional architecture — intelligent retrieval plus live knowledge base updating — is what separates Dhikroh AI from a chatbot with good prompts. Notion is not storage. It is the intelligence layer, the memory layer, and the growth mechanism of the entire system.

Architecture

##The problem
Most AI tools are reactive: you ask → they answer.
Real transformation requires a different flow: awareness → reflection → alignment → direction → action.
Generic tools miss the root — inner conflict, nervous-system-level patterns, values misalignment, the invisible shackles that keep a woman stuck regardless of how much information she has.

##The Insight
Struggle is rarely a lack of information. It is inner blocks.
Dhikroh AI addresses the root first. Why am I stuck? What is misaligned? What needs to be released? Who do I need to become?

## Why It’s Different

  • Alignment-first, not action-first

  • Deep proprietary methodology — not surface prompts

  • Bidirectional MCP: intelligent retrieval + session memory + live knowledge base updates

  • Islamic grounding that is theologically precise — not decorative

  • Built to prevent spiritual bypassing, not enable it

  • The companion holds the framework. The user sets the pace.

## What’s Next

  • Mode 2 fully live — The Becoming Journey with coordinated shackle tracking

  • Coach Intelligence Layer — Dhikroh-trained coaches using the system for personalised client pathway design

  • 21-Day Rebuild Challenge — structured immersive container for the Rebuild stage

  • Standalone interface — a dedicated environment that matches the depth of what lives inside it

  • Integration into the MTT app

## Closing
Dhikroh AI proves that AI can guide genuine reflection, structure real clarity, and support lasting transformation — not just answer questions.

Built by Tadhkirah Yusuf, founder of Dhikroh Co., and Muslimah Tyqoons Trybe.
Becoming Blueprint © Tadhkirah.

AI doesn’t stop at answers. It helps us become more. This is just the beginning.

Deploying Mercure alongside Caddy on a shared VPS

Ahnii!

Mercure is a real-time push protocol built on server-sent events (SSE). It ships as a standalone binary that embeds its own Caddy server. If you already run Caddy as your web server, you now have two Caddy processes fighting over ports. This post covers how to deploy both on the same VPS using Ansible, with solutions for every gotcha that came up.

Prerequisites

  • A VPS with Caddy already serving your sites
  • Ansible for deployment automation
  • The Mercure binary installed on the server
  • A domain with DNS pointed at your VPS

Resolving the port conflict

Mercure’s embedded Caddy wants to bind to port 443 and run its own admin API on port 2019. Your main Caddy already owns both. The fix is to disable auto-HTTPS on Mercure and bind it to a localhost-only port:

{
  auto_https off
  admin localhost:2039
}

http://localhost:3080 {
  mercure {
    publisher_jwt {env.MERCURE_JWT_SECRET}
    subscriber_jwt {env.MERCURE_JWT_SECRET}
    cors_origins https://minoo.live
    publish_origins *
    anonymous
  }
  respond /healthz 200
}

auto_https off prevents Mercure’s Caddy from requesting certificates. admin localhost:2039 moves the admin API off port 2019 where your main Caddy is already listening. Mercure listens on localhost:3080 where only your main Caddy can reach it.

Pick a port that is not already in use on your server. Port 3080 is a safe default since common tools like Docker tend to claim ports in the 3000 range.

Proxying SSE through your main Caddy

Your main Caddy reverse-proxies the Mercure hub URL to the local Mercure instance. The critical detail is flush_interval -1, which tells Caddy to flush response bytes immediately instead of buffering:

@mercure_hub {
  path /.well-known/mercure*
}
handle @mercure_hub {
  reverse_proxy localhost:3080 {
    flush_interval -1
    header_up X-Forwarded-For {remote_host}
  }
}

Without flush_interval -1, Caddy buffers the SSE stream and your clients never receive events. This is the single most common issue when proxying SSE through any reverse proxy.

Excluding SSE routes from gzip

Caddy’s encode directive compresses responses. Compressed SSE streams break because the client cannot decompress a stream that never ends. Exclude the Mercure routes from compression:

@not_mercure {
  not path /.well-known/mercure*
}
encode @not_mercure gzip zstd

This applies gzip to everything except the SSE endpoint. If you do not have Mercure configured, the template falls back to the simpler encode gzip zstd without the matcher.

JWT secret configuration

Both the publisher (your PHP app) and the subscriber (your frontend) authenticate with Mercure using JWTs signed with a shared secret. Store the secret in Ansible Vault:

# defaults/main.yml
mercure_jwt_secret: "{{ vault_mercure_jwt_secret }}"

The environment file that Mercure reads at startup is minimal:

MERCURE_JWT_SECRET=your-secret-here

Both publisher_jwt and subscriber_jwt in the Caddyfile reference this same environment variable. Your PHP publisher generates JWTs with the same secret:

$header = base64UrlEncode(json_encode(['alg' => 'HS256', 'typ' => 'JWT']));
$payload = base64UrlEncode(json_encode([
    'mercure' => ['publish' => ['*']],
    'iat' => time(),
    'exp' => time() + 3600,
]));
$signature = base64UrlEncode(
    hash_hmac('sha256', "{$header}.{$payload}", $jwtSecret, true)
);

return "{$header}.{$payload}.{$signature}";

This generates a JWT that grants publish access to all topics. The exp claim means each token is valid for one hour.

BoltDB data directory

Mercure uses BoltDB for persistence. The Ansible role creates the data directory under the deploy user’s home:

- name: Create Mercure BoltDB data directory
  ansible.builtin.file:
    path: "/home/{{ deploy_user }}/.local/share/caddy"
    state: directory
    mode: "0755"
    owner: "{{ deploy_user }}"
    group: "{{ deploy_user }}"

Mercure’s embedded Caddy writes its BoltDB files here. If the directory does not exist, Mercure fails silently on startup and events are not persisted.

Running as a systemd service

The Ansible role deploys a systemd unit that reads the environment file:

[Service]
Type=simple
ExecStart=/usr/local/bin/mercure run --config /etc/mercure/Caddyfile
EnvironmentFile=/etc/mercure/mercure.env
User={{ deploy_user }}
Restart=always

Set the User to your deploy user so Mercure can access its BoltDB directory.

Health check

The Mercure Caddyfile includes a /healthz endpoint that returns 200. Use this for monitoring:

curl -s -o /dev/null -w "%{http_code}" http://localhost:3080/healthz

If you get anything other than 200, Mercure is down. Wire this into your monitoring tool of choice.

Baamaapii

Rebuilding TLS, Part 1 — Why Encryption Alone Is Not Enough

plain

A year ago I wrote a series about how a web server works.

I started from a very primitive version and step by step moved toward the same core ideas modern production servers rely on. When I finished that series, I thought the next step would be small.

Wrap it in TLS. Make the communication secure.

It did not stay small for long.

What looked like a thin security layer on top of an existing server turned into a much deeper journey into cryptography, authentication, trust, certificates, protocol design, and many details usually hidden behind one familiar phrase: secure connection.

So this series is my attempt to approach TLS the same way I approached the web server: not as a finished black box, but as something we can rebuild from simpler pieces until its shape starts to make sense.

In this first part, we will start with the most naive version of the problem.

We will build a very simple socket-based communication channel, see that it is fully transparent, wrap it in encryption with a shared secret key, and then see why that is still not enough.

That will give us our first fake secure channel.

And that is exactly where we should start.

What we will build in this part

The plan for this article is simple:

  • build a tiny socket-based client and server
  • send plain text between them
  • look at the traffic and see that everything is visible
  • add shared-key encryption with AES-CTR
  • make the traffic unreadable
  • then show why encryption alone still does not give us a trustworthy secure protocol

We are not trying to build real TLS yet.

We are trying to make the first mistake on purpose.

Because once that mistake becomes visible, the next piece of the protocol stops looking optional.

TLS is not SSL

Before we start, one small clarification.

People still often say “SSL” when they talk about secure communication on the web. But SSL is the older family of protocols. TLS is its successor.

So when people say things like “SSL certificate” or “SSL connection,” in practice they usually mean TLS.

For modern systems, the relevant protocols are TLS, especially TLS 1.2 and TLS 1.3. This series is about understanding the ideas behind TLS by rebuilding simpler versions of the problems it solves.

And instead of starting from the finished protocol, we will begin one layer lower — with plain socket communication.

Step 1 — A plain socket-based communication channel

Let’s start with the smallest possible thing: a tiny TCP server and a tiny TCP client.

The client will send an HTTP-like request.

The server will read it and return an HTTP-like response.

Nothing secure yet. Just raw bytes moving over a socket.

Plain server

# server_plain.py
import socket

HOST = "127.0.0.1"
PORT = 8081

with socket.socket(socket.AF_INET, socket.SOCK_STREAM) as server:
    server.bind((HOST, PORT))
    server.listen(1)

    print(f"Listening on {HOST}:{PORT}")
    conn, addr = server.accept()

    with conn:
        print(f"Connected by {addr}")

        data = conn.recv(4096)
        request = data.decode("utf-8")
        print("Received request:")
        print(request)

        response = (
            "HTTP/1.1 200 OKrn"
            "Content-Type: text/plainrn"
            "Content-Length: 13rn"
            "rn"
            "hello, client"
        )
        conn.sendall(response.encode("utf-8"))

Plain client

# client_plain.py
import socket

HOST = "127.0.0.1"
PORT = 8081

request = (
    "GET /transfer?to=bob&amount=100 HTTP/1.1rn"
    "Host: localhostrn"
    "rn"
)

with socket.socket(socket.AF_INET, socket.SOCK_STREAM) as client:
    client.connect((HOST, PORT))
    client.sendall(request.encode("utf-8"))

    response = client.recv(4096)
    print("Received response:")
    print(response.decode("utf-8"))

This is intentionally tiny.

The client sends a request like this:

GET /transfer?to=bob&amount=100 HTTP/1.1
Host: localhost

The server reads it and sends a response back.

That is all.

And because it is all plain TCP, anyone who can observe the traffic can read it directly.

Looking at the traffic

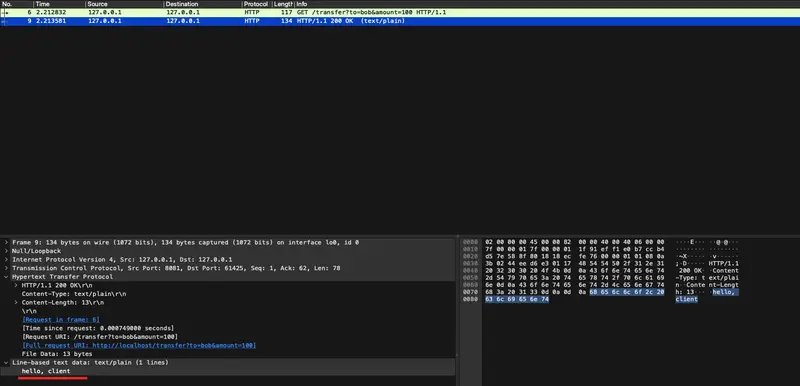
If you capture this communication in Wireshark, the request and response are fully visible in clear text.

plain

That is our baseline.

The client can read it.

The server can read it.

And anyone on the wire can read it too.

So the first obvious idea is also the first naive one:

If the problem is that everyone can read the bytes, let’s encrypt the bytes.

That sounds reasonable.

And it is still not enough.

Step 2 — Turning bytes into records

Before we add encryption, we need one small but important thing: structure.

TCP gives us a byte stream.

It does not give us message boundaries.

So once we stop sending plain text directly and start sending encrypted blobs, we need a way to tell the receiver how many bytes belong to one logical message.

That means even before security, we need a little bit of protocol design.

Let’s define the smallest possible record format:

  • 4 bytes: payload length
  • N bytes: payload

+----------+-----------+
|  length  |  payload  |
| (4 bytes)|  (varies) |
+----------+-----------+

That is enough for our first version.

# framing.py
import struct

def send_record(sock, payload: bytes) -> None:
    header = struct.pack("!I", len(payload))
    sock.sendall(header + payload)

def recv_exact(sock, n: int) -> bytes:
    chunks = []
    remaining = n

    while remaining > 0:
        chunk = sock.recv(remaining)
        if not chunk:
            raise ConnectionError("Connection closed while reading data")
        chunks.append(chunk)
        remaining -= len(chunk)

    return b"".join(chunks)

def recv_record(sock) -> bytes:
    header = recv_exact(sock, 4)
    (length,) = struct.unpack("!I", header)
    return recv_exact(sock, length)

This is not a crypto step.

It is a protocol step.

And that distinction matters more than it first appears. A secure channel is not just “call encrypt on a string.” It is a protocol with structure, state, and rules.

Now that we have a way to send and receive well-defined records, we can finally wrap them in encryption.

Step 3 — Wrapping the channel in shared-key encryption

The most obvious first attempt at secure communication is usually this:

  • both sides already know the same secret key
  • the sender encrypts the message before sending
  • the receiver decrypts it after receiving

That is exactly what we will do.

No handshake yet.

No certificates yet.

No integrity yet.

No authentication yet.

This version is intentionally naive.

For encryption, I will use AES in CTR mode.

Very briefly:

  • AES is a symmetric block cipher
  • CTR mode makes it convenient for encrypting a stream of bytes
  • it gives us confidentiality
  • but it does not give us integrity

That last point is the important one for this article.

If you want a deeper explanation of AES itself, I already wrote about it in my cryptography series: https://www.dmytrohuz.com/p/building-own-block-cipher-part-3, so I will not go into the internals here.

The nonce

CTR mode also needs a nonce.

For now, think of it as a fresh per-message value that must be different for each encryption under the same key.

It is not secret.

It just must not be reused.

So our encrypted payload will look like this:

  • nonce
  • ciphertext

Crypto helper

# crypto.py
import os
from cryptography.hazmat.primitives.ciphers import Cipher, algorithms, modes

# 32-byte shared key for AES-256
SHARED_KEY = b"0123456789ABCDEF0123456789ABCDEF"

def encrypt_message(plaintext: bytes) -> bytes:
    nonce = os.urandom(16)

    cipher = Cipher(algorithms.AES(SHARED_KEY), modes.CTR(nonce))
    encryptor = cipher.encryptor()
    ciphertext = encryptor.update(plaintext) + encryptor.finalize()

    # Encrypted payload format:
    # nonce || ciphertext
    return nonce + ciphertext

def decrypt_message(payload: bytes) -> bytes:
    nonce = payload[:16]
    ciphertext = payload[16:]

    cipher = Cipher(algorithms.AES(SHARED_KEY), modes.CTR(nonce))
    decryptor = cipher.decryptor()
    plaintext = decryptor.update(ciphertext) + decryptor.finalize()

    return plaintext

At this point, our wire format becomes:

  • 4-byte length
  • 16-byte nonce
  • ciphertext
+----------------+----------------+---------------------+
| length (4 B)   | nonce (16 B)   | ciphertext (N bytes)|
+----------------+----------------+---------------------+

That already looks much more like a protocol.

Step 4 — Encrypt the request and response

Now let’s integrate this into the client and server.

Encrypted client

# client_v1.py
import socket

from framing import send_record, recv_record
from crypto import encrypt_message, decrypt_message

HOST = "127.0.0.1"
PORT = 8081

request = (
    "GET /transfer?to=bob&amount=100 HTTP/1.1rn"
    "Host: localhostrn"
    "rn"
).encode("utf-8")

with socket.socket(socket.AF_INET, socket.SOCK_STREAM) as client:
    client.connect((HOST, PORT))

    encrypted_request = encrypt_message(request)
    send_record(client, encrypted_request)

    encrypted_response = recv_record(client)
    response = decrypt_message(encrypted_response)

    print("Received decrypted response:")
    print(response.decode("utf-8"))

Encrypted server

# server_v1.py
import socket

from framing import send_record, recv_record
from crypto import encrypt_message, decrypt_message

HOST = "127.0.0.1"
PORT = 8081

with socket.socket(socket.AF_INET, socket.SOCK_STREAM) as server:
    server.bind((HOST, PORT))
    server.listen(1)

    print(f"Listening on {HOST}:{PORT}")
    conn, addr = server.accept()

    with conn:
        print(f"Connected by {addr}")

        encrypted_request = recv_record(conn)
        request = decrypt_message(encrypted_request)

        print("Received decrypted request:")
        print(request.decode("utf-8"))

        response = (
            "HTTP/1.1 200 OKrnContent-Type: text/plainrn"
            "Content-Length: 13rnrnhello, client"
        ).encode("utf-8")

        encrypted_response = encrypt_message(response)
        send_record(conn, encrypted_response)

Now the communication flow changes in an important way.

Instead of sending readable HTTP-like text directly, the client sends an encrypted record. The server reads the record, decrypts it, and sees the original request.

What changes on the wire

If you capture this version in Wireshark, the traffic is no longer readable.

Instead of clear request and response text, you now see opaque binary data.

encr

So yes, we gained something real.

Let’s stop and say exactly what that is.

What encryption actually gave us

This first version gives us one meaningful property:

confidentiality against passive observers

If someone can only observe the traffic, but cannot modify it, they no longer get the plaintext request and response for free.

That is already better than raw TCP.

And this is why “just add encryption” feels so convincing. It visibly solves a real problem.

But that visible success can hide another, more dangerous failure.

Because a secure channel needs more than secrecy.

It also needs protection against tampering.

And we still do not have that.

Step 5 — Why encryption alone is not enough

This is the real point of Part 1.

We encrypted the messages.

We did not make them trustworthy.

AES-CTR protects confidentiality, but it does not protect integrity.

That means an active attacker may be able to modify ciphertext, and those modifications will flow through into the decrypted plaintext.

Very roughly, CTR mode behaves like this:

ciphertext = plaintext XOR keystream

So if an attacker changes bits in the ciphertext, the corresponding bits change in the plaintext after decryption.

That property is called malleability.

And protocol messages are usually predictable enough that this becomes useful to an attacker.

Our example request already has a very predictable structure:

GET /transfer?to=bob&amount=100 HTTP/1.1
Host: localhost

The exact bytes of amount=100 are not random.

That predictability is enough to hurt us.

A tiny isolated demo

We do not need a full man-in-the-middle proxy to show the problem. A small isolated example is enough.

# ctr_malleability_demo.py
from crypto import encrypt_message, decrypt_message

original = b"amount=100"
encrypted = encrypt_message(original)

nonce = encrypted[:16]
ciphertext = bytearray(encrypted[16:])

# Change '1' -> '9'
# ASCII '1' = 0x31
# ASCII '9' = 0x39
# Difference = 0x08

index_of_digit = len("amount=")
ciphertext[index_of_digit] ^= 0x08

modified = nonce + bytes(ciphertext)
decrypted = decrypt_message(modified)

print("Original :", original)
print("Modified :", decrypted)

Output:

Original : b'amount=100'
Modified : b'amount=900'

And that is the failure.

The attacker did not need the key.

They did not need to fully decrypt the message first.

They only needed the ability to modify the encrypted bytes in transit.

The receiver then decrypts the modified ciphertext and gets modified plaintext — without any built-in indication that anything went wrong.

So even though the message is hidden from passive observers, it is still vulnerable to active tampering.

That is not a secure protocol.

That is only encrypted transport.

What is still broken

At this point, our fake secure channel still has many serious holes.

No integrity protection

The receiver cannot detect that the ciphertext was modified.

No message authentication

The receiver has no cryptographic proof that the message came from the expected sender and arrived unchanged.

No replay protection

An attacker can capture an encrypted message and replay it later.

Static shared key

Both sides use one long-term shared key for everything.

That does not scale, and if it leaks, everything built on top of it collapses.

No handshake

There is no fresh session establishment. The peers do not negotiate anything. They just start encrypting.

No peer identity

The client does not really know who it is talking to beyond “someone who can decrypt with this key.”

So yes, we improved something.

But we are still very far from TLS.

Good.

That is exactly what Part 1 should make visible.

Summary

In this first part, we built a fake secure channel.

We started with plain socket communication and saw that everything was fully transparent. Then we wrapped the communication in shared-key encryption with AES-CTR, which gave us confidentiality against passive observers.

That was real progress.

But it was not enough.

Because encrypting a message is not the same thing as protecting the message from being changed. Our channel still accepts modified ciphertext, decrypts it, and trusts the result.

So the first lesson of this series is simple:

confidentiality is not integrity

And if we want something that starts to deserve the name secure protocol, we need both.

Next part — adding integrity with a MAC

So we stop here.

We now have a channel that can hide bytes from passive observers, but cannot reliably detect tampering.

In the next part, we will keep the same basic setup and fix the biggest hole we exposed here: we will add a MAC — a Message Authentication Code.

That will take us from:

“you probably can’t read this”

to:

“you also can’t silently change this”

That still will not be real TLS.

But it will make our fake secure channel one step less fake.

Final code

I’ll put the full code for this part on GitHub here:

https://github.com/DmytroHuzz/rebuilding_tls/tree/main/part_1