WhatsApp, çoklu sohbet özeti özelliğini test ediyor
 Popüler mesajlaşma uygulaması WhatsApp, çoklu sohbet özeti özelliği ile okunmamış mesajları tek bakışta özetlemeyi hedefliyor. İşte yeni AI tabanlı sistemin detayları:

 Mert
Popüler mesajlaşma uygulaması WhatsApp, çoklu sohbet özeti özelliği ile okunmamış mesajları tek bakışta özetlemeyi hedefliyor. İşte yeni AI tabanlı sistemin detayları:
 Siberpunk türünün en ikonik serilerinden olan Ghost in the Shell yeni bir anime dizisiyle geri dönüyor. Amazon Prime Video’da izleyici ile buluşacak animeden fragman yayınlandı.
This is a submission for the Notion MCP Challenge
Table of Contents
How I Used Notion MCP
The Tech Behind It
What I Built
Explanatory Video
Introduction
NoteRunway: an AI-powered workspace management tool that helps Notion power users clean up, audit, and command their workspace through a single interface.
Think of it as a flight control tower for your Notion workspace. It scans for problems you didn’t know you had, visualizes connections you couldn’t see, and lets you talk to your workspace in plain English.
🔗 Live Demo → noterunway.pilotronica.com

The Backstory
I’m a Notion addict. Not the “I use it for grocery lists” kind, rather the “I have 400+ pages, nested databases inside databases, and a set of half-written ideas from 2 AM” kind.
It all started in 2020, when I decided it was time to bring more order into my life. My notes were scattered everywhere, there was some structure, but not nearly enough. I needed something more powerful… something more organized.
Then I discovered Notion and instantly knew it was exactly what I’d been looking for all along and didn’t know existed.
You know how it goes, at first, you’re fully motivated. Everything’s clean, structured, flawless. You’re convinced this time you’ll manage your notes perfectly.
But sooner or later, every power user ends up in the same place: orphaned pages from long-forgotten projects, duplicate notes written three times because the first two vanished into the void, and dead links leading to pages you archived months ago.
And somewhere in that chaos, there’s probably a note with an API key you definitely didn’t mean to paste and leave it forever. Have you ever pasted an API key or secret thinking “I’m gonna move it somewhere more secure later”? And that “later” doesn’t really come, does it?
I needed a tool that could see the bigger picture, something that could scan everything, something that’d surface what’s broken, and help me fix it without blindly deleting content or forcing me to manually comb through bajillion pages.
When the Notion MCP Challenge dropped, it clicked right away. I could build that tool, and give something back to the Notion community while I’m at it.
The 7 Tools
NoteRunway packs 7 workspace management tools, split between pure scanners and AI-powered analyzers.
Think of it as a crew of seven tools at your disposal, everything you need to keep your Notion workspace in top shape. Each one has a specific role: some scan your workspace to surface hidden issues, others go deeper to analyze patterns and give you smarter insights.
Together, they cut through the clutter, highlight what actually needs attention, and help you clean things up without the risk of losing something important. No guesswork, no endless manual checks, just a clear view of your workspace and the tools to keep it running smoothly.
📊 Workspace Health Dashboard

Your workspace at a glance. Total pages, top-level pages, recently edited, empty pages, and link density (how well-connected your workspace actually is).
It’s the “oh wow, I have how many empty pages?” moment.
🔍 Duplicate Detection

This is where the AI earns its keep. NoteRunway fetches up to 100 pages with their content snippets, sends them to the LLM with a specialized system prompt, and gets back semantic duplicate groups with similarity scores.
Not just “same title” duplicates, it catches pages with different names but overlapping content. The AI picks a recommended “keep” version (⭐), and you choose which ones to archive.
🗑️ Garbage Collector

Rule-based detection across three categories:
Dry-run mode is on by default. You review everything before anything moves.
🔗 Dead Link Detector

Finds @mentions pointing to pages that no longer exist. Every broken mention is tracked back to its source page, so you know exactly where to fix it.
🔐 Sensitive Data Finder

Two-phase security scanner:
Phase 1 (Regex): Scans all pages against 13 patterns: API keys (OpenAI, Anthropic, Stripe, AWS, GitHub), PEM keys, JWTs, database URLs, passwords, credit cards. Findings are always partially redacted, never exposing full values.
Phase 2 (AI Deep Scan): Optionally sends page text to the LLM to catch natural-language secrets that regex misses. Things like “the password is hunter2” or “login: admin/secret123”.
🕸️ Dependency Graph

An interactive force-directed graph of your entire workspace. Pages are nodes (colored by depth), connections are edges (solid for parent-child, dashed for @mentions). Orphaned pages glow red.
You can hover, click, collapse branches, and zoom around. It’s surprisingly therapeutic to see your workspace as a living network.
💬 Semantic Ask (Agentic Chat)

A natural language interface to your workspace, powered by an agentic AI loop.
Type something like “Find all pages about authentication and summarize them” or “Archive everything in the old-project folder.” The AI breaks it into tool calls (search, read, analyze), feeds results back into its context, and proposes structured actions for your approval.
It supports 5 action types: archive, create, rename, append, and update, all with a human-in-the-loop confirmation step. No action executes without your explicit “yes.”
Just a heads-up: be cautious with destructive actions. Avoid updating or archiving critical data.
This project is still in beta, and I don’t want you to risk losing important information. As you know, AI isn’t deterministic, and unexpected outcomes can happen.
Show us the code
Here’s the repository:
Clean, organize, and command your Notion workspace with AI. Powered by the Notion MCP.

🔗 Live Demo → noterunway.pilotronica.com
NoteRunway is a browser-based tool that helps Notion power users clean up, audit, and manage their workspace using a combination of deterministic scans and AI-powered intelligence via the Notion MCP.
It connects to your Notion workspace through OAuth, runs server-side analysis via Next.js API routes, and provides a cyberpunk-themed UI for reviewing findings and approving actions.
| Principle | Description |
|---|---|
| Zero Lock-in | Your data stays in Notion. NoteRunway never stores workspace content. |
| Human-in-the-Loop | No destructive action runs without explicit user approval. |
| Privacy First | AI keys stored only in your browser (BYOK). Sent per-request to NoteRunway APIs and never persisted server-side. |
…
How I Used Notion MCP
This is the core of the whole project. NoteRunway uses the Notion MCP Server as the execution layer for all workspace interactions in the Semantic Ask feature.
The Architecture
Browser → Next.js API (SSE) → Vercel AI SDK → MCP Client → notion-mcp-server (stdio) → Notion API
Here’s the flow:
streamText() and the selected LLMsearch_pages, get_page, get_page_content, run_analysis
propose_actions, which streams proposed actions to the UI for human approval
Why MCP and Not Just the API?
I use both. Here’s the split:
This hybrid approach gives me the speed of direct API access with the safety of MCP’s tool calling protocol.
Destructive Tool Safety
Any tool that modifies workspace data (patch, post-page, delete, move) requires an approved: true flag. The AI can propose actions, but nothing destructive runs without the user clicking “Execute.”
The Tech Behind It
| Layer | Technology | Why |
|---|---|---|
| Framework | Next.js 16 (App Router) | Full-stack React with API routes |
| AI SDK | Vercel AI SDK 6 | Unified streaming + tool calling across 4 providers |
| MCP | @notionhq/notion-mcp-server | Notion workspace access via Model Context Protocol |
| Visualization | React Flow 11 | Force-directed graph for the dependency viewer |
| Validation | Zod 4 | Runtime schema validation for all API inputs/outputs |
| Styling | Tailwind CSS 4 + shadcn/ui | Cyberpunk aesthetic with accessible components |
Multi-Provider AI (BYOK)
NoteRunway supports 4 AI providers with 13 models: OpenAI (GPT-5.4, GPT-5 Mini), Anthropic (Claude Opus 4.6, Haiku 4.5), xAI (Grok 4, Grok 3), and Google (Gemini 2.5 Pro/Flash).
Your API key stays in your browser’s localStorage. It’s sent per-request in an HTTP header, used once to create a provider instance, and discarded. NoteRunway’s server never stores, logs, or persists your key.
The Archive System
Every destructive action creates an audit trail:
NoteRunway Archive/
├── Duplicates/
│   └── [Audit Stub] Original Title
├── Garbage Collection/
│   └── [Audit Stub] Stale Page Name
└── Semantic Ask/
    └── [Audit Stub] Archived via Chat
Each audit stub contains a callout with the archive date, reason, and a faithful copy of the original content. The original page is soft-archived to Notion’s trash (recoverable for 30 days).
Nothing is ever truly deleted without a paper trail.
Wrapping Up
NoteRunway started as a personal itch, a messy workspace and a dev challenge deadline. It turned into something I’m going to use every week.
Building with the Notion MCP was a revelation. The ability to give an AI structured access to a workspace, with tool-level control over what it can read and write, opens up workflows that feel like magic. Ask a question, get an answer sourced from your actual pages. Propose a cleanup, review it, execute it. All in one flow.
If you’re a Notion power user drowning in pages, give it a spin: noterunway.pilotronica.com
And if you find an API key you forgot about in a meeting note… you’re welcome. 😄
Built with ☕ and too many late nights by Giorgi Kobaidze
I’ve been running FastAPI in production for a payment processing platform in Mexico for the past couple of years. We handle SPEI transfers (Mexico’s interbank transfer system), OXXO Pay (cash payments at convenience stores), and crypto on-ramps through multiple PSP integrations.
I wanted to share some real lessons from production that I don’t see discussed much.
The stack
FastAPI + async SQLAlchemy 2.0 + asyncpg
PostgreSQL + Redis (rate limiting + caching)
Docker → AWS ECS Fargate
GitHub Actions CI/CD
Alembic for migrations
Lesson 1: Webhook state machines save your life
When you process payments, you receive webhooks from payment providers. The naive approach is to just update the payment status directly. Don’t do this.
We built a webhook state machine where each payment goes through defined states: pending → processing → completed/failed. Every state transition is logged with timestamps. When a payment provider sends duplicate webhooks (and they will), the state machine just ignores transitions that don’t make sense.
This saved us during a reconciliation where we found timezone boundary issues between UTC and CST that were causing mismatches at midnight.
Lesson 2: Alembic migrations + ECS = restart loops
This one hurt. We had an Alembic migration that was taking too long, and ECS health checks were killing the container before the migration finished. Container restarts, migration starts over, health check fails again. Infinite loop.
Fix: Run migrations as a separate ECS task before deploying the new container. Never run migrations on startup in production.
Lesson 3: psycopg2 + LIKE queries will bite you
If you use % in LIKE queries with psycopg2 and parameterized queries, you need %% for literal percent signs when mixed with %s placeholders. We had a bug where a search endpoint was silently returning empty results.
Wrong
cursor.execute(“SELECT * FROM users WHERE name LIKE ‘%s%'”, (search,))
Right
cursor.execute(“SELECT * FROM users WHERE name LIKE %s”, (f”%{search}%”,))
Lesson 4: VARCHAR timestamps are a trap
One of our PSP integrations stores created_at as VARCHAR instead of TIMESTAMP. Every time we need to do date comparisons, we have to CAST(created_at AS TIMESTAMP). If you’re designing your schema, always use proper TIMESTAMP columns.
Lesson 5: Rate limiting is not optional
We got hit with a brute force attack on our auth endpoints within the first month. Redis-backed rate limiting with SlowAPI saved us. 5 attempts per minute on login, 20 requests per minute on general endpoints.
Lesson 6: Connection pooling matters more than you think
Our KYC service was falling over under load. The fix? Increasing the connection pool from 10 to 50 connections. That’s it. Went from random 500 errors to zero issues.
The architecture pattern that works
After iterating through multiple services, this is the pattern I settled on:
Repository (data access)
→ Service (business logic)
→ Endpoint (HTTP layer)
Each layer only talks to the one below it. Dependencies are injected via FastAPI’s Depends(). Testing becomes trivial — just mock the repository layer.
After refining this over 10+ deployments, I packaged the boilerplate into a starter kit with the full auth system, async DB, Docker, CI/CD, and tests. It’s on my Gumroad if anyone wants it. But the lessons above are the real value — the code is just the implementation.
I also deploy production AWS infrastructure for teams that don’t want to deal with Terraform/ECS — details here if that’s useful.
Happy to answer questions about running FastAPI in production, dealing with Mexican payment providers, or anything else.
If you’ve spent more than a week in web development, you’ve encountered REST APIs. They are the glue of the modern internet, connecting front-end frameworks to back-end databases and enabling third-party integrations that we take for granted.
But there is a massive difference between “making an API call” and “understanding RESTful architecture.” Today, we’re going deep. We’ll start with the basics and move into the advanced patterns that separate junior developers from senior architects.
Want to dive deeper into full-stack patterns? Check out more resources at NeedleCode.
What Exactly is REST?
REST (Representational State Transfer) isn’t a protocol like HTTP; it’s an architectural style. Introduced by Roy Fielding in his 2000 dissertation, it was designed to make the web more scalable and flexible.
When an API is “RESTful,” it means it follows a specific set of rules that allow different systems to communicate seamlessly, regardless of the language they are written in.
The 5 Pillars of RESTful Design
To build a truly RESTful system, you must adhere to these constraints:
The Developer’s Toolbox: HTTP Methods
In REST, we treat everything as a Resource. We manipulate these resources using standard HTTP verbs.
| Method | Action | Idempotent? |
|---|---|---|
| GET | Retrieve a resource | Yes |
| POST | Create a new resource | No |
| PUT | Update/Replace an entire resource | Yes |
| PATCH | Partially update a resource | No |
| DELETE | Remove a resource | Yes |
Pro-Tip: A common interview question is the difference between
PUTandPATCH. Remember:PUTreplaces the entire object, whilePATCHonly modifies the specific fields you send.
Deciphering the Server: Status Codes
As a dev, you need to speak “Status Code.” They tell you exactly what happened without parsing a huge JSON body.
200 OK (Standard success), 201 Created (Success after POST).400 Bad Request (Your JSON is malformed), 401 Unauthorized (You forgot the token), 404 Not Found (Endpoint doesn’t exist).500 Internal Server Error (Your backend code crashed). Moving to Advanced Territory
Once you’ve mastered the basics, you’ll face real-world challenges like performance and scale.
1. Pagination and Filtering
Never return SELECT * FROM users. If you have 100,000 users, your API will crash. Use query parameters:
GET /api/v1/orders?page=2&limit=50&status=shipped
2. Stateless Auth with JWT
Since REST is stateless, we don’t use server-side sessions. Instead, we use JSON Web Tokens (JWT). The client sends the token in the Authorization header with every request.
3. API Versioning
Change is inevitable. To avoid breaking your users’ apps, version your URL:
https://api.needlecode.com/v1/products
https://api.needlecode.com/v2/products
4. The “Final Boss”: HATEOAS
HATEOAS (Hypermedia as the Engine of Application State) means your API provides links to guide the client.
{
  "user_id": 123,
  "name": "Dev",
  "links": [
    { "rel": "self", "href": "/users/123" },
    { "rel": "delete", "href": "/users/123", "method": "DELETE" }
  ]
}
This makes your API self-discoverable, though it is often skipped in simpler internal projects.
Summary
REST APIs are popular because they are predictable and scalable. By mastering these constraints and methods, you aren’t just “coding an endpoint”—you’re designing a system.
What’s your biggest struggle with API design? Let’s chat in the comments!
For more deep dives into system architecture and backend development, visit us at NeedleCode.
The 404 Not Found error is the “Ghost in the Machine” of the web. We’ve all seen it, and as developers, we’ve all accidentally caused it. While it’s the most recognizable HTTP status code, handling it correctly is the difference between a professional, SEO-optimized application and a leaky bucket that loses users.
In this guide, we’re diving deep into the mechanics of the 404 error, how to troubleshoot it, and how to implement robust fixes for modern web stacks.
What is a 404 Error (Technically)?
From an HTTP/1.1 perspective, a 404 Not Found is a client-side error. It indicates that the client (the browser or crawler) could successfully communicate with the server, but the server could not map the requested URI to a specific resource.
Unlike a 500 error (Server Error) or a 403 (Forbidden), a 404 implies that the resource might be missing temporarily or has been moved permanently without a pointer.
Common Root Causes in Development
Before you start debugging, identify where the disconnect is happening:
index.html./Assets/Logo.png and /assets/logo.png are different files. Locally on Windows or macOS, they might work fine—leading to “it works on my machine” syndrome..htaccess: In WordPress or PHP environments, a corrupted .htaccess file often breaks the rewrite rules. How to Fix 404 Errors: The Developer’s Toolkit
1. Server-Side Redirects (The Right Way)
If you’ve moved content, don’t let the old URL die. Use a 301 Permanent Redirect. This preserves “link juice” and SEO authority.
Apache (.htaccess):
Redirect 301 /old-feature-slug /new-feature-slug
Nginx (nginx.conf):
location /old-path {
    return 301 /new-path;
}
2. Handling 404s in Modern Frameworks
Express.js (Node.js):
Always place your 404 handler at the very bottom of your middleware stack, after all defined routes.
// Your routes here...
app.get('/api/data', (req, res) => { ... });

// The Catch-all 404
app.use((req, res, next) => {
  res.status(404).json({
    error: "Resource not found",
    message: "If you think this is a bug, please contact [email protected]"
  });
});
React Router (v6):
<Routes>
  <Route path="/" element={<Home />} />
  <Route path="/about" element={<About />} />
  {/* The 404 "No Match" Route */}
  <Route path="*" element={<NotFoundPage />} />
</Routes>
3. Automation and Monitoring
Don’t wait for users to report broken links.
The Anatomy of a High-Conversion 404 Page
A 404 doesn’t have to be a dead end. From a UX perspective, a great 404 page should:
Impact on SEO
Search engines don’t penalize you for having some 404s—it’s a natural part of the web’s evolution. However, a high volume of 404s from internal links signals a “low-quality” site to crawlers.
Pro-tip: If a high-authority external site links to a page on your site that no longer exists, you are losing valuable SEO equity. Always redirect those specific URLs to the next most relevant page.
Conclusion
Mastering error handling is a core skill for any full-stack developer. By moving from “passive” 404 handling to “active” routing management, you ensure a smoother experience for both users and search bots.
For more deep dives into web performance, backend optimization, and developer tools, visit us at NeedleCode. We help developers bridge the gap between “code that works” and “code that scales.”
Originally published at needlecode.com
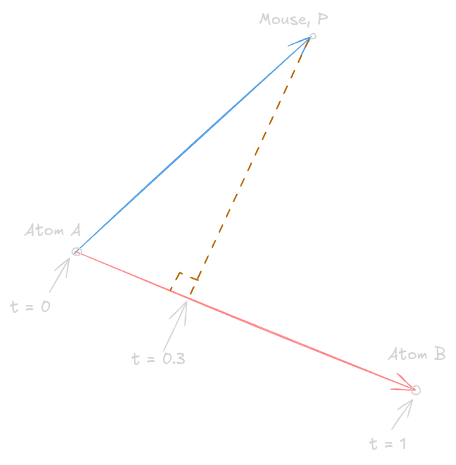
For a chemical draw to be truly functional, drawing isn’t enough; the user must be able to interact with every element on the screen. Selecting an atom is intuitive, but how do you select a chemical bond (a line segment) with pixel-perfect precision? In this post, I’ll break down the mathematical process and the challenges of implementing this collision engine.
Selecting Atoms: The Easy Path
Detecting if the cursor is over an atom is the ideal scenario. Since our domain already stores the (x, y) coordinates of each node, the solution is applying Euclidean distance.
We calculate the separation between the mouse (P) and each atom (A) with the formula:
.
If the distance is shorter than a defined search radius, the atom is considered a candidate. To ensure precision, if multiple atoms are within range, we always select the one with the minimum distance.
class Molecule {
  // ...
  private findClosestAtom(
    x: number,
    y: number,
    radius: number,
  ): { atom: Atom; distance: number } | null {
    const candidates = [...this._atoms.values()]
      .map((atom) => ({
        atom,
        distance: Math.sqrt(Math.pow(atom.x - x, 2) + Math.pow(atom.y - y, 2)),
      }))
      .filter(({ distance }) => distance <= radius)
      .sort((a, b) => a.distance - b.distance);

    return candidates[0] || null;
  }
  // ...
Selecting Bonds: The “Infinite Line” Problem
With bonds, things get complicated. A bond is a line segment, not a single point. My first instinct was to use the classic equation for the distance from a point to a line:
The problem: This formula assumes the line is infinite. If you click miles away but happen to be perfectly aligned with the bond’s trajectory, the formula will trigger a “hit”. In a molecule with hundreds of bonds, this creates “ghost collisions” across the entire canvas.
The Solution: Projection and Clamping
To solve this, we need to find the closest point specifically within the segment bounded by atoms A and B. Here’s where the vector math comes in.
The algorithm projects the mouse coordinates onto the line and calculates the “projection factor” t.

Key here is clamping: forcing t to stay between 0 and 1 using Math.max(0, Math.min(1, t)). This effectively “encloses” the collision logic within the physical boundaries of the bond.
private pointToSegmentDistance(
  px: number, py: number, // Mouse point
  ax: number, ay: number, // Atom A (Start)
  bx: number, by: number  // Atom B (End)
): number {
  const abx = bx - ax;
  const aby = by - ay;
  const apx = px - ax;
  const apy = py - ay;

  const abLengthSq = abx * abx + aby * aby;

  // If atoms overlap, return distance to point A
  if (abLengthSq === 0) return Math.sqrt(apx * apx + apy * apy);

  // Scalar projection restricted to the [0, 1] range (Clamping)
  const t = Math.max(0, Math.min(1, (apx * abx + apy * aby) / abLengthSq));

  // Find the coordinates of the closest point on the segment
  const closestX = ax + t * abx;
  const closestY = ay + t * aby;

  // Final distance between mouse and the closest point on the segment
  return Math.sqrt(Math.pow(px - closestX, 2) + Math.pow(py - closestY, 2));
}
Atoms vs Bonds
A common UX challenge in chemical editors is overlap. What happens if the mouse is near a bond but also directly over an atom?
In chemistry, the atom is the primary unit of interaction. Therefore, I implemented a simple but effective business rule: Atoms always have priority. If the engine detects a collision with both an atom and a bond, the atom “hijacks” the selection event. This prevents users from accidentally deleting a bond when they intended to edit an element.
Conclusion: The “God Object” Warning
While this collision engine works perfectly, it has exposed a growing architectural debt. My Molecule class—which should only care about chemical valences and atoms—is now bloated with 2D geometry formulas and pixel coordinates.
I’ve created a God Object.
In the next post, I’ll perform “major surgery” on this architecture. We will split the system into two Bounded Contexts: a Chemistry context for the logic and a Spatial context for the geometry.
You Shouldn’t Have to Tell the AI Who to Be
Last week I wrote about typing “act as a senior architect” 47 times per week. The friction of manually assigning roles to an AI that should be able to figure it out.
This week I want to go deeper. Not the pitch — the plumbing. How does signal-based routing actually work inside PRISM Forge? What does the routing engine look at? How does it decide?
And — because build-in-public means showing the dents — the 3 times it broke in ways I didn’t expect.
The Core Idea: Intent Detection, Not Commands
Most persona systems work like menus. Pick a role from a list. Type a command. Toggle a mode.
Signal-based routing works differently. You talk naturally. The system listens for signals in your language and assembles the right team.
“I’m stuck on this auth bug” contains two signals: stuck (creative problem-solving) and bug (debugging/validation). The routing engine reads both, decides who leads, and who supports.
No slash commands. No mode toggles. No “act as.”
Anatomy of the Routing Engine
PRISM Forge’s routing engine has four layers that fire on every single message:
Layer 1: Hard Overrides
Three things bypass all logic:
These are cheap checks. If none fire, the engine moves to intent classification.
Layer 2: Intent Classification
Every message maps to one of 9 intent categories:
| Intent | What it means | Who typically leads |
|---|---|---|
| Build | Write code, create files | Amelia (Developer) |
| Investigate | Analyze, explore existing state | Mary (Analyst) |
| Plan | Structure work, break down tasks | Bob (Scrum Master) + John (PM) |
| Validate | Test, verify, review | Quinn (QA Engineer) |
| Create | Brainstorm, ideate, design | Carson (Brainstorm Coach) |
| Challenge | Question approach, simplify | Victor (Strategist) or Jobs (Genius) |
| Orient | Catch up, understand context | Susie (Chief of Staff) |
| Document | Write up, explain, describe | Paige (Technical Writer) |
| Narrate | Tell story, frame metrics | Sophia (Storyteller) |
Here’s the critical design decision: a single message can span multiple intents. “Plan how to refactor the auth module — I think it’s too complex” spans Plan + Build + Challenge. The engine evaluates holistically, not sequentially. It doesn’t stop at the first match.
Layer 3: Signal Detection
This is where it gets interesting. The engine maintains two signal tables:
Shared signals co-activate multiple personas. When someone says “audit,” three personas are relevant: Mary (investigation), Quinn (validation), and Boris (structural conformance). The engine decides who leads based on the full message context.
Specialist signals are exclusive triggers. “First principles” activates Musk (Radical Reductionist). “Hero’s journey” activates Campbell (Mythic Storyteller). These are unambiguous.
There are 24 shared signals and 23 specialist signal groups across all 28 personas. Every persona has a documented activation path. Nothing is magic — it’s a lookup table with contextual judgment on top.
Layer 4: Team Assembly
The engine doesn’t just pick one persona. It assembles a team:
Example: you say “the auth module is too complex, let’s simplify and rebuild it.”
Three perspectives in one response. Each attributed. Each distinct. No blended consensus voice.
The Orchestrator: Susie
All four layers are orchestrated by Susie, the Chief of Staff. She’s not a persona you talk to — she’s the intelligence running behind every turn.
On Turn 1 of every session, Susie activates unconditionally. She scans your project state (git, todos, handoffs, memory) and delivers a sitrep:
After Turn 1, Susie evaluates every message, re-assembles the team if needed, and only announces when the roster changes. If you send 5 messages about planning, the team stays stable. No noise.
The key insight: Susie evaluates holistically. All signals, all domain matches, all cross-workflow hooks are inputs to one team assembly decision. She doesn’t process them sequentially and stop at the first match. She considers everything and picks the best team.
The 3 Times It Broke
Here’s where build-in-public gets honest.
Break 1: Signal Collision
Early in development, I typed: “Let’s brainstorm how to simplify the architecture.”
Three strong signals fired simultaneously:
All three had legitimate claims to lead. The result? A response that tried to be all three at once. Brainstorming structure with simplification opinions wrapped in architectural framing. It was a mess. No clear voice. No clear direction.
The fix: Explicit primary selection with a tiebreaker. The engine now picks ONE primary based on which signal is strongest in context. In this case, “brainstorm” as the verb (the action the user wants) beats “simplify” (the lens) and “architecture” (the domain). Carson leads. Jobs and Winston support. Clear hierarchy, clear voices.
Break 2: The Consensus Trap
I built a “war room” feature where all personas discuss a decision. Early version: everyone agreed with each other.
Jobs would say “simplify.” Victor would say “I agree with Jobs.” Winston would say “Jobs is right, and architecturally this supports his point.” Twenty-seven personas producing one opinion. Useless.
The problem was subtle. The AI’s default behavior is to be agreeable. When you load multiple personas into one context, they naturally converge because the underlying model wants to be helpful and non-contradictory.
The fix: Susie became an active moderator with an explicit mandate: surface disagreement. Her orchestration rules now include: “A war room where everyone agrees is a failed war room.” She actively draws out dissent: “Jobs, would you cut this? Victor, is this the right approach at all? Dali, what assumption are we not questioning?”
The result: war rooms now produce genuine tension. Jobs wants to cut scope. Carson says cutting is premature — we haven’t explored alternatives. Winston sides with Jobs on scope but wants Carson’s option analysis first. Real tradeoffs. Real decisions.
Break 3: Over-Routing
For a while, the engine was too eager. A simple question like “what does this function do?” would activate Mary (investigation), Winston (architecture), Quinn (validation), and Paige (documentation) — four personas to answer what should have been a one-voice response.
The engine was technically correct. The question touches investigation, architecture, validation, and documentation domains. But four voices for a simple question is noise, not depth.
The fix: Team size guidance. Every persona on the team must earn their seat. A team of 2 with genuine perspectives beats a team of 8 with filler. The engine now considers message complexity. Simple questions get one voice. Complex, multi-faceted problems get the full team. The threshold isn’t a rule — it’s judgment, guided by the principle that extra voices must add something the primary couldn’t provide alone.
What I’d Build Differently
If I started over today, three things would change:
1. Signal weights, not signal matches. The current system treats all signal matches equally and relies on contextual judgment for tiebreaking. A weighted system where “the verb matters more than the noun” would have prevented Break 1 from the start.
2. Disagreement scaffolding from day one. I bolted on active moderation after the consensus trap. It should have been foundational. Any multi-agent system that doesn’t explicitly design for disagreement will produce consensus by default. The AI wants to agree. You have to engineer the tension.
3. Graduated complexity. Simple questions should feel simple. Complex questions should feel like a team. The transition between these modes took longer to get right than the routing engine itself.
Try It Yourself
PRISM Forge is MIT licensed and free:
npx prism-forge install
28 personas. Signal-based routing. No commands to memorize.
GitHub: prism-forge/prism-forge
This is part of a 12-post series on building PRISM Forge. Last week: the problem with manual persona prompting. Next week: meet John, the product manager who asks “why are we doing this?” before anyone writes a line of code — and what happens when he clashes with Bob over planning vs simplification.
Follow along: @DrakkoTarkin on X | @drakkotarkin.bsky.social on Bluesky
I used to think “clever code” made me a better developer.
You know the type: 5 layers of abstraction, every design pattern imaginable, optimizations sprinkled everywhere.
It looked impressive. Until a new teammate joined and spent half a day just figuring out how to make a tiny change.
That’s when it hit me:
Readability is the real standard of good code.
The Real Test of a Codebase
Forget patterns, frameworks, or architecture debates for a second. Here’s my rule:
If anyone on your team, new or experienced, can read, understand, and adapt your code within a day, your code is solid.
Everything else, optimization, abstraction, architectural elegance, still matters. But it should support readability, not replace it. Think of readability as the foundation and the fancy stuff sits on top.
This Isn’t About New Developers
A lot of people hear “readable code” and assume it’s a criticism of junior devs. It’s not.
Even the most skilled developer can waste hours untangling overly abstracted or over-engineered code. Readable code is about writing code that communicates intent clearly, so everyone can move fast and safely.
Think of it as writing a story. The plot, your logic, should be clear. The style, patterns and architecture, can be fancy, but no one should need a decoder ring to figure out what’s happening.
Why Readability Works
Readable code makes:
It also doesn’t mean sacrificing good engineering:
Readable first, clever second. Layer sophistication where it genuinely adds value.
Quick Wins for Readable Code
My Personal Rule
Whenever I onboard someone new, I give them a small task.
If they can complete it without me explaining every step, the code passes my readability test.
If not, it’s a signal it’s time to rethink clarity.
Readable code doesn’t mean dumb code.
It means code that anyone can understand, adapt, and maintain, while still being optimized, abstracted, and architecturally elegant.
Software isn’t about showing off cleverness. It’s about solving problems together.
Most AI apps today try to do things for you automatically.
But when it comes to personal data — like money or health — that can feel risky.
So I explored a different pattern:
What if AI suggests actions, but never executes without approval?
🧠 The Idea: Approval-Gated AI
Instead of this:
User → AI → Action happens
I built around this:
User → AI → Draft → User approves → Action happens
💬 Example
You type:
“Add coffee for 40”
The AI:
You:
⚖️ Why This Matters
In domains like:
Users care about control and accuracy.
Problems with full automation
Problems with manual apps
🔄 This Pattern Sits in Between
Approval-gated AI is:
🧪 Where I Applied It
I’ve been prototyping this idea in a small app where AI helps with:
Everything goes through user approval first.
🤔 Trade-offs I Observed
✅ Pros
❌ Cons
🧩 Open UX Questions
This is where I’d love input:
🚀 Implementation Stack
🔗 Demo & Project
💬 Final Thought
AI doesn’t always need to be autonomous.
Sometimes the best UX is:
AI that assists decisively — but lets humans stay in control.
Curious how others are thinking about this pattern.
