Never Miss an AI Hackathon Again: Building an Autonomous Discovery Agent with Notion & Brave MCP

GitHub logo

This is a submission for the Notion MCP Challenge

What I Built

HackathonSniper is an autonomous AI agent designed to eliminate “hackathon fatigue.” If you’re like me, you spend hours every month checking Devpost, DoraHacks, and Dev.to just to find one hackathon that fits your niche.

HackathonSniper turns this manual hunt into an automated pipeline. It doesn’t just “search”—it thinks. It uses the Model Context Protocol (MCP) to bridge the gap between AI reasoning and the real web.

Video Demo

Show us the code

GitHub logo

klee1611
/
HackathonSniper

AI-powered hackathon discovery agent using Brave Search + Notion MCP

🎯 Hackathon Sniper

A sophisticated TypeScript agent that automatically discovers, evaluates, and tracks hackathons using AI-powered analysis. Built with clean architecture patterns, real MCP server integration, and complete environment separation.

✨ Features

  • 🔍 Intelligent Search – Real Brave Search MCP server integration
  • 🤖 AI Evaluation – Groq-powered hackathon qualification analysis
  • 📊 Notion Integration – Real Notion MCP server for storage and tracking
  • 🎭 Test Isolation – Complete environment isolation for testing (zero external dependencies)
  • ⚡ Fast Development – Hot reload, comprehensive Makefile, pnpm package management
  • 🛡️ Type Safety – End-to-end TypeScript with Zod schema validation
  • 🧪 Robust Testing – Unit, integration, and smoke tests

🚀 Quick Start

Prerequisites

  • Node.js 18+
  • pnpm (recommended) or npm

Installation & Setup

# Clone and setup in one command
git clone <repository-url>
cd HackathonSniper
make setup

Development Workflow

# Copy and fill in your API keys
cp .env.example .env
# Run development

…

The Technical Architecture

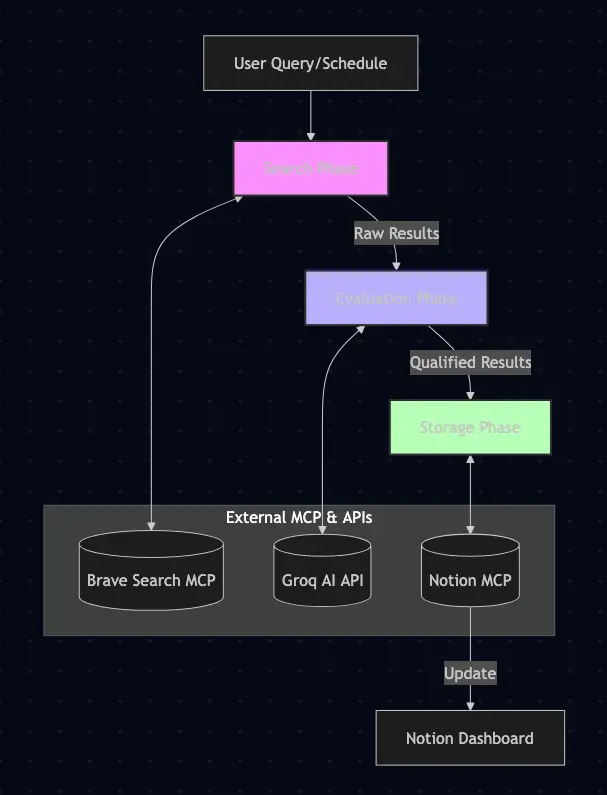
The agent follows a rigorous 3-phase lifecycle:

  1. 🔍 The Hunt (Brave Search MCP): It performs targeted searches across the web to find new hackathon announcements, even those buried in blog posts or obscure landing pages.
  2. 🤖 The Vetting (Groq LLM): Every discovery is analyzed by a Llama-3 model. It evaluates the prize pool, solo-friendliness, AI relevance, and proximity to the deadline.
  3. 📊 The Storage (Notion MCP): Qualified opportunities are instantly synced to a beautifully structured Notion database, complete with metadata, deadlines, and AI-generated summaries.

tech_architecture

How I Used Notion MCP

The Notion MCP Server (@notionhq/notion-mcp-server) is the “nervous system” of this project. It transforms a simple script into a powerful productivity tool by allowing the AI to interact with my Notion workspace as if it were a native application.

Instead of writing complex, boilerplate-heavy API calls to the Notion REST API, the Notion MCP is integrated. This allowed the agent to:

  • Dynamic Schema Mapping: The agent automatically maps structured AI evaluation objects to Notion database properties (Dates, Checkboxes, URLs, and Rich Text).
  • Process Isolation: By using the MCP StdioClientTransport, the Notion integration runs in its own isolated process, managed entirely by the Model Context Protocol.
  • Automated Workflows: The agent uses the create_notion_page tool provided by the MCP server to dynamically populate my “Hackathon Scout” dashboard.

Wrapping Up

This integration unlocks a “set and forget” workflow. I can run HackathonSniper as a background task, and my Notion workspace stays updated with a high-signal, low-noise list of opportunities. It’s not just data entry; it’s an autonomous data clerk powered by Notion MCP.

8 Agentic Coding Patterns That Ship 10x Faster (Cursor, Windsurf, Claude Code)

8 Agentic Coding Patterns That Ship 10x Faster (Cursor, Windsurf, Claude Code)

AI coding tools evolved.

In 2024, we got autocomplete. In 2025, we got inline chat. In 2026, we have autonomous agents that read your codebase, plan multi-file changes, run tests, and iterate until things work.

But here’s the thing — most developers are still using these tools like fancy autocomplete. They type a prompt, get a suggestion, accept or reject, repeat.

That’s like buying a Formula 1 car and driving it in first gear.

Agentic coding means giving the AI enough context, constraints, and autonomy to handle entire tasks end-to-end. The difference isn’t the tool — it’s the patterns you use.

In this article, I’ll share 8 battle-tested agentic coding patterns with real configurations, prompt templates, and workflows that work across Cursor, Windsurf, Claude Code, and Copilot Workspace.

The Agentic Coding Spectrum

Not all AI coding is equal. Here’s where the tools sit in March 2026:

Manual                                          Autonomous
  |                                                  |
  |  Copilot    Cursor     Windsurf    Claude Code   |
  |  (suggest)  (compose)  (cascade)   (agent mode)  |
  |                                                  |
  └──────────────────────────────────────────────────┘
       Tab-complete  →  Multi-file  →  Full autonomy

The patterns in this article work across the spectrum, but they shine brightest in compose/cascade/agent modes where the tool can autonomously execute multi-step plans.

Pattern 1: The AGENTS.md Convention

The single most impactful pattern in agentic coding: give your AI agent a mission briefing file at the root of your project.

# AGENTS.md

## Project Context
This is a Next.js 14 SaaS application for invoice management.
- Framework: Next.js 14 (App Router)
- Database: PostgreSQL via Prisma
- Auth: NextAuth.js v5
- Styling: Tailwind CSS + shadcn/ui
- State: Zustand for client, React Query for server
- Testing: Vitest + Playwright

## Architecture Rules
- All API routes go in `app/api/` — NO pages router
- Database queries ONLY through Prisma — no raw SQL
- All forms use react-hook-form + zod validation
- Server components by default, "use client" only when needed
- Error boundaries on every route segment

## Coding Standards
- TypeScript strict mode — no `any` types
- All functions must have JSDoc comments
- Max file length: 300 lines — split if longer
- Imports: external first, then internal, then relative
- No barrel exports (index.ts re-exports)

## Common Patterns
### Creating a new feature
1. Schema first: `prisma/schema.prisma`
2. Migration: `npx prisma migrate dev`
3. Server action: `app/actions/feature.ts`
4. UI component: `components/feature/`
5. Page: `app/(dashboard)/feature/page.tsx`
6. Tests: `tests/feature.test.ts`

### API Error Handling

typescript
// Always use this pattern for API routes
export async function POST(req: Request) {
try {
const body = await req.json();
const validated = schema.parse(body);
// … logic
return Response.json({ data: result });
} catch (error) {
if (error instanceof z.ZodError) {
return Response.json(
{ error: “Validation failed”, details: error.issues },
{ status: 400 }
);
}
console.error(“[API_ERROR]”, error);
return Response.json(
{ error: “Internal server error” },
{ status: 500 }
);
}
}


## What NOT to Do
- Don't add new dependencies without checking existing ones first
- Don't modify the auth flow without explicit approval
- Don't use `console.log` — use the structured logger
- Don't skip TypeScript types — ever

markdown

Why it works: Every AI coding tool reads project files for context. AGENTS.md gives the agent your team’s knowledge upfront — architecture decisions, conventions, patterns, anti-patterns. Without it, the agent makes reasonable but wrong guesses.

Pro tip: Put AGENTS.md in your .cursorrules or .windsurfrules file for automatic inclusion, or keep it as a standalone file that Claude Code and other tools will discover.

Pattern 2: Task Decomposition Prompts

Don’t ask the AI to “build a feature.” Ask it to decompose first, then execute each step:

# Task Decomposition Template

## Phase 1: Plan (don't write code yet)
Analyze this requirement and create a step-by-step implementation plan:

**Requirement:** [paste requirement]

For each step, specify:
1. Files to create or modify
2. Dependencies on other steps
3. Test criteria (how do we know this step works?)

Output the plan as a numbered checklist. Do NOT write any code yet.

## Phase 2: Execute (one step at a time)
Now implement step [N] from the plan above.

Before writing code:
- Re-read the plan
- Check if previous steps are complete
- List any assumptions

After writing code:
- Verify it compiles (run the appropriate check)
- Run related tests
- Note any issues for the next step

## Phase 3: Verify
All steps are implemented. Now:
1. Run the full test suite
2. Check for TypeScript errors
3. Review all changed files for consistency
4. List any remaining TODOs or known issues

Here’s a real-world example using this pattern in Cursor Composer:

@plan Create a Stripe webhook handler that:
- Validates the webhook signature
- Handles checkout.session.completed
- Updates the user's subscription in our DB
- Sends a welcome email for new subscribers
- Handles subscription.deleted for cancellations
- Has idempotency protection (don't process same event twice)

Output a numbered plan with files and test criteria. Don't code yet.

The agent produces a plan. You review it. Then:

@execute Implement step 1 from the plan: webhook signature validation.
Run the test after implementing.

Why this matters: Agents that try to build everything at once produce worse code than agents that plan first. The plan creates a checkpoint you can review before expensive code generation.

Pattern 3: Context Window Management

The biggest performance killer in agentic coding isn’t the model — it’s what’s in the context window. Here’s a .cursorrules file optimized for context management:

# .cursorrules — Context Window Optimization

# Include only what's relevant per task
context_rules:
  # Always include for every task
  always:
    - AGENTS.md
    - tsconfig.json
    - package.json (dependencies section only)
    - prisma/schema.prisma (model definitions only)

  # Include based on task type
  patterns:
    api_route:
      - app/api/**/*.ts
      - lib/auth.ts
      - lib/db.ts
      - types/api.ts

    ui_component:
      - components/**/*.tsx
      - lib/hooks/*.ts
      - styles/globals.css
      - tailwind.config.ts

    database:
      - prisma/schema.prisma
      - prisma/migrations/
      - lib/db.ts
      - app/actions/*.ts

  # Never include (saves tokens, avoids confusion)
  exclude:
    - node_modules/
    - .next/
    - "*.test.ts"  # unless task is about testing
    - "*.stories.tsx"
    - coverage/
    - dist/

And here’s a prompt pattern that explicitly manages context:

## Context-Aware Task Prompt

**Task:** [description]

**Relevant files (read these):**
- `src/lib/auth.ts` — current auth implementation
- `src/types/user.ts` — User type definition
- `prisma/schema.prisma` — lines 45-80 (User model)

**Reference files (for patterns, don't modify):**
- `src/app/api/invoices/route.ts` — follow this API pattern

**Out of scope (don't touch):**
- Anything in `src/components/`
- The auth flow
- Database schema changes

**Expected output:**
- Modified: `src/app/api/users/route.ts`
- New: `src/app/api/users/[id]/route.ts`
- Modified: `src/lib/validators/user.ts`

Pattern 4: Test-Driven Agent Development (TDAD)

Write the tests first. Then let the agent implement until tests pass. This is the highest-confidence agentic coding pattern:

// tests/invoice-service.test.ts
// Write these FIRST, then let the agent implement

import { describe, it, expect, beforeEach } from "vitest";
import { InvoiceService } from "../src/services/invoice";
import { mockDb } from "./helpers/mock-db";

describe("InvoiceService", () => {
  let service: InvoiceService;

  beforeEach(() => {
    service = new InvoiceService(mockDb());
  });

  describe("createInvoice", () => {
    it("should create an invoice with line items", async () => {
      const invoice = await service.createInvoice({
        customerId: "cust_123",
        lineItems: [
          { description: "Consulting", quantity: 10, unitPrice: 150 },
          { description: "Development", quantity: 20, unitPrice: 200 },
        ],
        dueDate: new Date("2026-04-30"),
      });

      expect(invoice.id).toBeDefined();
      expect(invoice.subtotal).toBe(5500); // 10*150 + 20*200
      expect(invoice.status).toBe("draft");
      expect(invoice.lineItems).toHaveLength(2);
    });

    it("should calculate tax correctly", async () => {
      const invoice = await service.createInvoice({
        customerId: "cust_123",
        lineItems: [
          { description: "Service", quantity: 1, unitPrice: 1000 },
        ],
        taxRate: 0.19,
        dueDate: new Date("2026-04-30"),
      });

      expect(invoice.subtotal).toBe(1000);
      expect(invoice.tax).toBe(190);
      expect(invoice.total).toBe(1190);
    });

    it("should reject invoices with no line items", async () => {
      await expect(
        service.createInvoice({
          customerId: "cust_123",
          lineItems: [],
          dueDate: new Date("2026-04-30"),
        })
      ).rejects.toThrow("Invoice must have at least one line item");
    });

    it("should reject negative quantities", async () => {
      await expect(
        service.createInvoice({
          customerId: "cust_123",
          lineItems: [
            { description: "Bad", quantity: -1, unitPrice: 100 },
          ],
          dueDate: new Date("2026-04-30"),
        })
      ).rejects.toThrow("Quantity must be positive");
    });
  });

  describe("sendInvoice", () => {
    it("should change status from draft to sent", async () => {
      const invoice = await service.createInvoice({
        customerId: "cust_123",
        lineItems: [
          { description: "Work", quantity: 1, unitPrice: 500 },
        ],
        dueDate: new Date("2026-04-30"),
      });

      const sent = await service.sendInvoice(invoice.id);
      expect(sent.status).toBe("sent");
      expect(sent.sentAt).toBeDefined();
    });

    it("should not send an already-sent invoice", async () => {
      const invoice = await service.createInvoice({
        customerId: "cust_123",
        lineItems: [
          { description: "Work", quantity: 1, unitPrice: 500 },
        ],
        dueDate: new Date("2026-04-30"),
      });

      await service.sendInvoice(invoice.id);

      await expect(
        service.sendInvoice(invoice.id)
      ).rejects.toThrow("Invoice already sent");
    });
  });
});

Now the prompt to the agent:

## TDAD Prompt

I've written failing tests in `tests/invoice-service.test.ts`.

Your task:
1. Read the tests carefully
2. Implement `src/services/invoice.ts` to make ALL tests pass
3. Create any necessary types in `src/types/invoice.ts`
4. Run `npx vitest tests/invoice-service.test.ts` after each change
5. Iterate until all tests are green
6. Do NOT modify the test file

Constraints from AGENTS.md:
- Use Prisma for DB operations
- Zod for input validation
- Follow the service pattern in `src/services/customer.ts`

Why TDAD is powerful: The tests are an unambiguous specification. The agent can’t “hallucinate” its way past a failing assertion. It either works or it doesn’t.

Pattern 5: Incremental Migration Agent

Large refactors are where agentic coding shines. This pattern migrates code file-by-file with verification at each step:

# Migration Agent Prompt Template

## Objective
Migrate from [OLD_PATTERN] to [NEW_PATTERN] across the codebase.

## Rules
1. Migrate ONE file at a time
2. After each file:
   - Run type checker: `npx tsc --noEmit`
   - Run related tests: `npx vitest [file]`
   - If either fails, fix before moving on
3. Commit after each successful file migration
4. Keep a migration log in `docs/migration-log.md`

## Migration Spec

### Before (Old Pattern)

typescript
// Old: class-based services with manual DI
class UserService {
private db: Database;
constructor(db: Database) {
this.db = db;
}
async getUser(id: string): Promise {
return this.db.users.findUnique({ where: { id } });
}
}


### After (New Pattern)

typescript
// New: functional with dependency injection via closure
import { type Database } from “@/lib/db”;

export function createUserService(db: Database) {
return {
getUser: async (id: string): Promise => {
return db.users.findUnique({ where: { id } });
},
} as const;
}

// Type helper
export type UserService = ReturnType;


## File Order (migrate in this sequence)
1. `src/services/base.ts` — foundation
2. `src/services/user.ts` — simple, good test case
3. `src/services/invoice.ts` — medium complexity
4. `src/services/payment.ts` — complex, has events
5. `src/services/notification.ts` — has side effects
6. Update all imports in `src/app/` routes
7. Remove old `ServiceBase` class

## Migration Log Format

markdown
| # | File | Status | Tests | Notes |
|—|——|——–|——-|——-|
| 1 | base.ts | ✅ Done | 3/3 | Removed class, exported types |
| 2 | user.ts | ✅ Done | 8/8 | Added return type |
| 3 | invoice.ts | 🔄 In Progress | – | – |

markdown

Key insight: The agent can handle the mechanical work of refactoring, but it needs explicit rules about verification, order, and how to handle failures. Without these constraints, it’ll try to change everything at once and break the build.

Pattern 6: Error Recovery Loops

When the agent hits an error, most developers intervene manually. Instead, teach the agent to self-recover:

# Error Recovery Protocol

When you encounter an error, follow this protocol:

## Level 1: Self-Fix (try 3 times)
1. Read the full error message and stack trace
2. Identify the root cause (not the symptom)
3. Apply the fix
4. Run the check again
5. If still failing after 3 attempts → escalate to Level 2

## Level 2: Context Expansion
1. Read related files that might contain the answer
2. Check if this is a known pattern in AGENTS.md
3. Search for similar patterns in the codebase: `grep -r "pattern" src/`
4. Try the fix with expanded context
5. If still failing → escalate to Level 3

## Level 3: Simplify
1. Revert to the last working state
2. Break the task into smaller sub-tasks
3. Implement the simplest version that could work
4. Add a TODO comment for the full implementation
5. Report what you couldn't complete and why

## NEVER do:
- Suppress errors with try/catch without logging
- Skip tests to "make it work"
- Add `@ts-ignore` or `any` types to bypass type errors
- Delete tests that are failing
- Change the requirement to match your implementation

Here’s how this looks in a Claude Code workflow:

# claude-code-config.yaml
agent:
  name: "feature-builder"
  error_recovery:
    max_self_fix_attempts: 3
    escalation_strategy: "simplify"

  verification:
    after_each_change:
      - "npx tsc --noEmit"
      - "npx vitest --reporter=verbose"

  guardrails:
    forbidden_patterns:
      - "@ts-ignore"
      - "as any"
      - "eslint-disable"
      - "console.log"
    max_files_changed: 10
    require_test_for_new_files: true

Pattern 7: Multi-Agent Code Review

Use one agent to write code and another to review it. This catches issues that a single agent misses:

# multi_agent_review.py
# A simple multi-agent code review pipeline

import subprocess
import json
from pathlib import Path


def get_diff() -> str:
    """Get the current git diff of staged changes."""
    result = subprocess.run(
        ["git", "diff", "--staged"],
        capture_output=True, text=True
    )
    return result.stdout


def agent_review_prompt(diff: str, role: str) -> str:
    """Generate a review prompt for a specific reviewer role."""

    roles = {
        "security": """You are a security reviewer. Examine this diff for:
- SQL injection, XSS, CSRF vulnerabilities
- Hardcoded secrets or credentials
- Insecure deserialization
- Missing input validation
- Auth/authz bypasses
- Information leakage in error messages

For each issue found, specify:
- Severity (critical/high/medium/low)
- File and line number
- Description of the vulnerability
- Suggested fix

If no issues found, say "LGTM — no security issues detected."
""",
        "performance": """You are a performance reviewer. Examine this diff for:
- N+1 query patterns
- Missing database indexes (infer from query patterns)
- Unnecessary re-renders in React components
- Large bundle imports (could be tree-shaken)
- Missing pagination on list endpoints
- Synchronous operations that should be async
- Memory leaks (unclosed connections, missing cleanup)

For each issue, estimate the impact and suggest a fix.
""",
        "architecture": """You are an architecture reviewer. Examine this diff for:
- Violations of the patterns in AGENTS.md
- Tight coupling between modules
- Missing abstractions or leaky abstractions
- Inconsistency with existing codebase patterns
- Business logic in the wrong layer
- Missing error handling
- Proper separation of concerns

Reference existing code patterns when suggesting improvements.
""",
    }

    return f"""{roles[role]}

## Diff to Review

diff
{diff}


## Project Context
{Path("AGENTS.md").read_text() if Path("AGENTS.md").exists() else "No AGENTS.md found."}
"""


def run_review_pipeline():
    """Run all reviewers and aggregate results."""
    diff = get_diff()

    if not diff.strip():
        print("No staged changes to review.")
        return

    results = {}
    for role in ["security", "performance", "architecture"]:
        prompt = agent_review_prompt(diff, role)
        # Send to your preferred LLM API
        # response = llm.complete(prompt, model="claude-sonnet")
        # results[role] = response.text
        print(f"--- {role.upper()} REVIEW ---")
        print(f"Prompt ready ({len(prompt)} chars)")
        print()

    # Aggregate
    blocking_issues = [
        issue for role_results in results.values()
        for issue in role_results
        if issue.get("severity") in ("critical", "high")
    ]

    if blocking_issues:
        print(f"❌ {len(blocking_issues)} blocking issues found!")
        print("Fix these before merging.")
    else:
        print("✅ All reviews passed. Ready to merge.")


if __name__ == "__main__":
    run_review_pipeline()

shell

The power of multi-agent review: A single agent reviewing its own code has blind spots. Using different “reviewer personas” catches security issues that a performance reviewer misses, and vice versa.

Pattern 8: Autonomous Feature Branches

The ultimate agentic coding pattern: the agent creates a branch, implements the feature, writes tests, and opens a PR — all autonomously:

#!/bin/bash
# autonomous-feature.sh
# Fully autonomous feature implementation pipeline

set -euo pipefail

FEATURE_DESC="$1"
BRANCH_NAME="$2"

echo "🚀 Starting autonomous feature implementation"
echo "Feature: $FEATURE_DESC"
echo "Branch: $BRANCH_NAME"

# Step 1: Create branch
git checkout main
git pull origin main
git checkout -b "$BRANCH_NAME"

# Step 2: Plan (using your CLI agent tool)
echo "📋 Phase 1: Planning..."
PLAN=$(cat <<EOF
Read AGENTS.md for project context.
Create a detailed implementation plan for this feature:
$FEATURE_DESC

Output a JSON array of steps, each with:
- "description": what to do
- "files": array of files to create/modify
- "tests": how to verify this step

Do NOT write code yet. Planning only.
EOF
)

# Step 3: Execute each step
echo "⚡ Phase 2: Implementation..."
# The agent executes each planned step

# Step 4: Verify
echo "✅ Phase 3: Verification..."

# Run type checker
if ! npx tsc --noEmit; then
    echo "❌ TypeScript errors found. Attempting auto-fix..."
    # Agent fixes type errors
fi

# Run tests
if ! npx vitest --run; then
    echo "❌ Tests failing. Attempting auto-fix..."
    # Agent fixes failing tests (max 3 attempts)
fi

# Run linter
if ! npx eslint src/ --fix; then
    echo "⚠️ Linting issues found."
fi

# Step 5: Commit and push
echo "📦 Phase 4: Commit..."
git add -A
git commit -m "feat: $FEATURE_DESC

Implemented by autonomous agent pipeline.
- Plan: [N] steps executed
- Tests: all passing
- Types: clean
- Lint: clean"

git push origin "$BRANCH_NAME"

# Step 6: Create PR
echo "🔀 Phase 5: Creating PR..."
# Use GitHub CLI or API to create PR
gh pr create 
    --title "feat: $FEATURE_DESC" 
    --body "## Summary
Autonomous implementation of: $FEATURE_DESC

## Changes
$(git diff main..HEAD --stat)

## Verification
- ✅ TypeScript: clean
- ✅ Tests: all passing
- ✅ Lint: clean

## Review Notes
This PR was autonomously generated. Please review carefully:
- [ ] Business logic correctness
- [ ] Edge cases covered
- [ ] No hardcoded values
- [ ] Error handling appropriate" 
    --base main 
    --head "$BRANCH_NAME"

echo "🎉 Done! PR created for review."

Important: Always require human review before merging autonomous PRs. The agent does the implementation work; a human validates the decisions.

The Configuration Files That Make It Work

Here’s a complete setup for the major tools:

Cursor (.cursorrules)

# .cursorrules

You are an expert TypeScript/Next.js developer.

## Rules
1. Read AGENTS.md before every task
2. Plan before coding — decompose complex tasks
3. Run tests after every change
4. One file at a time for complex changes
5. Never skip types or error handling

## On Error
- Read the full error
- Check if AGENTS.md has guidance
- Fix root cause, not symptoms
- Max 3 self-fix attempts before asking

## Code Style
- Functional over class-based
- Composition over inheritance
- Explicit over implicit
- Small functions (<30 lines)

Windsurf (.windsurfrules)

# .windsurfrules

## Cascade Mode Configuration

### Context Loading
Always read these files first:
- AGENTS.md (project rules)
- relevant test files for the feature

### Execution Mode
- Use "Write" mode for new features
- Use "Edit" mode for refactors
- Always run verification after changes

### Iteration Protocol
When tests fail:
1. Read the test carefully
2. Read the error message
3. Fix the implementation (not the test)
4. Run again
5. After 3 failures, explain the issue

Claude Code (CLAUDE.md)

# CLAUDE.md

## Project
Next.js 14 SaaS — see AGENTS.md for full context.

## Commands
- Type check: `npx tsc --noEmit`
- Test: `npx vitest`
- Test single: `npx vitest path/to/test`
- Lint: `npx eslint src/`
- Dev server: `npm run dev`
- Build: `npm run build`

## Rules
- Follow AGENTS.md strictly
- Run type check + tests after every change
- Commit atomic changes with conventional commit messages
- Ask before adding new dependencies

Real-World Results

Here’s what these patterns look like in practice:

Metric Without Patterns With Patterns Improvement
Feature implementation time 4-8 hours 30-90 min 5-10x faster
First-attempt test pass rate ~40% ~85% 2x better
Code review rounds 3-5 1-2 60% fewer
Agent token waste ~50% of budget ~15% of budget 70% savings
Post-merge hotfixes 1 per 3 PRs 1 per 10 PRs 3x fewer

The key insight: the patterns, not the models, determine your productivity. A well-configured Cursor with good AGENTS.md will outperform raw GPT-5 without structure.

Getting Started Checklist

If you want to adopt agentic coding patterns today:

  • [ ] Create AGENTS.md in your project root (Pattern 1) — 30 minutes
  • [ ] Set up .cursorrules or equivalent for your tool — 15 minutes
  • [ ] Write tests before prompting for your next feature (Pattern 4) — already part of your workflow
  • [ ] Use task decomposition prompts instead of “build X” (Pattern 2) — immediate
  • [ ] Add error recovery rules to your agent config (Pattern 6) — 10 minutes
  • [ ] Try multi-agent review on your next PR (Pattern 7) — 30 minutes

Start with Patterns 1 and 4. They have the highest impact-to-effort ratio.

Key Takeaways

  1. AGENTS.md is the highest-ROI file in your codebase. It turns a generic AI into your team’s expert. Every coding agent reads it.

  2. Plan first, code second. Task decomposition prompts prevent the agent from going down rabbit holes.

  3. Context management is a skill. What you exclude from the context window matters as much as what you include.

  4. TDAD (Test-Driven Agent Development) is the gold standard. Tests are an unambiguous spec. Agents can’t hallucinate past a failing assertion.

  5. Teach your agent to recover from errors. Most developers intervene too early. A good error recovery protocol lets the agent fix itself.

  6. Multi-agent review catches blind spots. One agent writes, multiple agents review from different angles.

  7. Autonomous pipelines need human checkpoints. Full autonomy for implementation, human review before merge.

  8. Patterns beat models. A well-structured workflow with a good model beats a frontier model with no structure.

The era of “type prompt, accept suggestion” is over. Agentic coding is about designing workflows where AI handles execution and humans handle judgment.

These 8 patterns are your starting kit. Adapt them to your stack, refine them with your team, and watch your shipping velocity transform.

Which pattern are you most excited to try? Share your AGENTS.md setup in the comments — I’d love to see how different teams structure their AI coding workflows.

🍕 I Built FoodMine – A Modern Angular 18 Food Ordering App (Help Me Make It Better!)

Hey dev community! 👋

I just launched FoodMine – a dynamic food ordering web app built with Angular 18!

GitHub Repo -> FoodMine

🚀 Key Features

🔍 Search Functionality

Quickly find your desired food items with our intuitive search feature.

🛒 Shopping Cart

Add and manage items effortlessly for a streamlined ordering experience.

📸 Food Images

Browse through vibrant images to get a taste of what you’re ordering.

💻 Tech Stack
Angular 18 – TypeScript – HTML – CSS

🎯 I Need YOUR Help!

Submit an issue for:

  • 🐛 Bugs you find
  • 🚀 New features (payment, auth, order history)
  • ♿ Accessibility improvements
  • 📱 Mobile optimizations
  • 🎨 UI/UX suggestions

Submit a PR for:
✅ Restaurant filtering
✅ User authentication
✅ Payment integration
✅ Order history
✅ Dark mode toggle
✅ Unit tests
✅ Performance optimizations

🤝 Let’s Build Together!

Open Issues
Submit PR

Even a single emoji reaction helps! 🔥

⭐ Star the repo if you find it useful!

👉 Follow me Shubham Pawar for more projects!

The $1,800 Hostile Takeover: How Governance Attacks Are the Cheapest Exploit in DeFi — And 7 Defense Patterns That Actually Work

An attacker spent $1,800 on governance tokens and nearly walked away with $1.08 million in user funds. No flash loan. No smart contract bug. No zero-day. Just buying tokens on the open market and submitting a proposal.

This was Moonwell on Moonriver, March 2026. The attacker acquired 40 million MFAM tokens — enough to meet quorum — and proposed transferring admin control of seven lending markets, the comptroller, and the price oracle to their own address. The entire attack setup took 11 minutes.

Moonwell survived because they had a “Break Glass Guardian” — a 2-of-3 emergency multisig that could veto the proposal. Most protocols don’t have this. And the ones that do often implement it wrong.

Meanwhile, GreenField DAO wasn’t as lucky. In April 2025, an attacker flash-borrowed 9 million GOV tokens, passed a malicious proposal, and drained $31 million from the treasury — all within a single block. Beanstalk’s $182 million governance exploit in 2022 used the same pattern with over $1 billion in flash-loaned tokens.

Governance attacks are now the highest-ROI exploit class in DeFi. They’re cheap, they’re repeatable, and most protocols are still vulnerable. Here’s why, and how to fix it.

Why Governance Is DeFi’s Softest Target

Three structural problems make governance exploits uniquely dangerous:

1. Voting power is purchasable. Unlike exploiting a reentrancy bug (which requires technical skill) or compromising a private key (which requires access), governance attacks just require capital — sometimes very little capital.

2. Low participation is the norm. Most DAOs see 5-15% voter turnout. When quorum is set at 10% of circulating supply and 85% of tokens are dormant, an attacker needs to outbid… nobody.

3. Timelocks provide false security. A 48-hour timelock sounds protective until you realize most governance token holders don’t monitor proposals. The timelock expires, the malicious proposal executes, and nobody noticed.

The Attack Economics

Let’s quantify how cheap governance attacks actually are:

Moonwell (March 2026):
  Attack cost:     $1,800 (bought tokens on open market)
  Potential profit: $1,080,000
  ROI:             600x

GreenField DAO (April 2025):
  Attack cost:     ~$0 (flash loan, repaid in same tx)
  Actual profit:   $31,000,000
  ROI:             Infinite

Beanstalk (April 2022):
  Attack cost:     ~$0 (flash loan)
  Actual profit:   $182,000,000
  ROI:             Infinite

For context, the average smart contract exploit requires weeks of reverse engineering and a deep understanding of the protocol’s internals. A governance attack requires reading the proposal threshold from a public contract and checking token prices on a DEX.

The 5 Governance Attack Vectors

Vector 1: Flash Loan Vote Manipulation

The classic. Borrow governance tokens, vote, return them — all in one transaction.

// VULNERABLE: Governance that reads balanceOf() at vote time
function castVote(uint256 proposalId, bool support) external {
    uint256 votingPower = governanceToken.balanceOf(msg.sender); // ← Flash-loanable
    _recordVote(proposalId, msg.sender, votingPower, support);
}

Why it works: Any governance system that reads token balance at vote time instead of using historical snapshots is exploitable with flash loans.

Vector 2: Low-Quorum Treasury Drain

Moonwell’s pattern. Buy tokens below quorum threshold, submit proposal, wait for timelock to expire while nobody notices.

Required voting power: 40M MFAM (quorum)
Cost of 40M MFAM:     $1,800
Treasury value:        $1,080,000

Why it works: Token liquidity on secondary chains (Moonriver, Fantom, etc.) is often so thin that quorum-level quantities cost less than a used car.

Vector 3: Proposal Payload Obfuscation

The malicious proposal doesn’t say “drain the treasury.” It says “Upgrade proxy to new implementation” with a bytecode payload that nobody reads.

// Looks innocent in the proposal description:
// "MIP-42: Upgrade lending pool to v2.1 for gas optimization"
// Actual calldata:
function execute() external {
    // Step 1: Transfer admin of all markets to attacker
    comptroller._setPendingAdmin(0xAttacker);

    // Step 2: Accept admin (in a follow-up tx after timelock)
    // Step 3: Set price oracle to attacker-controlled contract
    // Step 4: Manipulate prices and drain all collateral
}

Why it works: Most governance participants vote based on the proposal title and forum discussion, not the on-chain calldata. Auditing proposal payloads requires Solidity expertise that most token holders don’t have.

Vector 4: Delegation Accumulation

Instead of buying tokens, slowly accumulate delegation from inactive holders who delegate to “trusted” community members.

// Attacker builds reputation as an active governance participant
// Gets delegated voting power from passive holders over months
// Eventually accumulates enough delegation to pass proposals solo

Why it works: Delegation is designed for efficiency but creates power concentration. A delegatee with 30% of voting power from passive holders is a single point of failure.

Vector 5: Cross-Chain Governance Desync

For protocols with governance on one chain and execution on another, the finality gap creates a voting power fabrication window.

Chain A (governance): Attacker votes with 10M tokens
Bridge message delay: 15 minutes
Chain B (execution):  Attacker has already moved tokens

Result: Voting power counted on Chain A, tokens already 
        transferred on Chain B — double counting

Why it works: Cross-chain message passing has inherent latency. If governance snapshots aren’t synchronized across chains, tokens can be “in two places at once.”

7 Defense Patterns That Actually Work

Pattern 1: Snapshot-Based Voting (Mandatory)

Never read token balance at vote time. Always use historical snapshots.

// SAFE: OpenZeppelin Governor with ERC20Votes snapshots
function _getVotes(
    address account,
    uint256 timepoint,
    bytes memory /*params*/
) internal view override returns (uint256) {
    // Reads balance at proposal creation block, NOT current block
    // Flash loans at vote time are worthless — balance is historical
    return token.getPastVotes(account, timepoint);
}

Implementation: Use OpenZeppelin’s ERC20Votes extension, which tracks voting power at every block via checkpoints. The Governor contract automatically reads from the snapshot at proposal creation time.

// ERC20Votes automatically checkpoints on every transfer
contract GovernanceToken is ERC20, ERC20Votes {
    function _update(address from, address to, uint256 amount) 
        internal override(ERC20, ERC20Votes) 
    {
        super._update(from, to, amount);
        // ERC20Votes._update() writes a checkpoint here
        // Future getPastVotes() calls read from this checkpoint
    }
}

What this prevents: Flash loan voting (Vector 1) — since the attacker didn’t hold tokens at the snapshot block, their voting power is zero.

What this doesn’t prevent: Market purchase attacks (Vector 2) if the attacker buys tokens before the snapshot block.

Pattern 2: Vote Escrow with Lock Period

Require tokens to be locked for a minimum period before they carry voting weight.

contract VoteEscrow {
    uint256 public constant MIN_LOCK_PERIOD = 7 days;

    struct Lock {
        uint256 amount;
        uint256 lockedAt;
        uint256 unlockTime;
    }

    mapping(address => Lock) public locks;

    function lock(uint256 amount, uint256 duration) external {
        require(duration >= MIN_LOCK_PERIOD, "Lock too short");

        token.transferFrom(msg.sender, address(this), amount);
        locks[msg.sender] = Lock({
            amount: amount,
            lockedAt: block.timestamp,
            unlockTime: block.timestamp + duration
        });
    }

    function getVotingPower(address account) external view returns (uint256) {
        Lock memory userLock = locks[account];

        // No voting power if locked less than MIN_LOCK_PERIOD ago
        if (block.timestamp < userLock.lockedAt + MIN_LOCK_PERIOD) {
            return 0;
        }

        // Voting power proportional to remaining lock time (ve-model)
        uint256 remaining = userLock.unlockTime > block.timestamp 
            ? userLock.unlockTime - block.timestamp : 0;
        return (userLock.amount * remaining) / MAX_LOCK_TIME;
    }
}

What this prevents: Both flash loan (Vector 1) and quick market purchase attacks (Vector 2). An attacker must lock capital for 7+ days with no guarantee of success, creating real economic risk.

Trade-off: Reduces participation from casual holders who don’t want to lock tokens. Mitigate with a liquid wrapper (veToken staking derivative) that still requires lock commitment.

Pattern 3: Break Glass Guardian (Emergency Veto)

Moonwell’s saving grace. A multisig with the power to veto malicious proposals outside normal governance flow.

contract BreakGlassGuardian {
    address public immutable GOVERNANCE_TIMELOCK;
    uint256 public constant GUARDIAN_THRESHOLD = 2; // 2-of-3

    address[3] public guardians;
    mapping(bytes32 => uint256) public vetoApprovals;

    function vetoProposal(uint256 proposalId) external {
        require(isGuardian(msg.sender), "Not a guardian");

        bytes32 vetoHash = keccak256(abi.encode(proposalId, "VETO"));
        vetoApprovals[vetoHash]++;

        if (vetoApprovals[vetoHash] >= GUARDIAN_THRESHOLD) {
            // Cancel the proposal in the timelock
            IGovernor(GOVERNANCE_TIMELOCK).cancel(proposalId);
            emit ProposalVetoed(proposalId);
        }
    }

    // Guardian rotation must go through full governance
    // (prevents guardian capture)
    function rotateGuardian(uint256 index, address newGuardian) 
        external 
        onlyGovernance 
    {
        guardians[index] = newGuardian;
    }
}

Critical design decisions:

  • Guardians can only veto, never propose or execute — this preserves decentralization
  • Guardian rotation goes through normal governance — prevents guardian capture
  • Use a 2-of-3 or 3-of-5 threshold — single guardians are a centralization risk
  • Guardians should be geographically and organizationally diverse

What this prevents: Any governance attack that relies on timelock expiration (Vectors 2, 3, 4). Even if the proposal passes, guardians can cancel it.

What this doesn’t prevent: Attacks that bypass governance entirely (key compromise, contract vulnerabilities).

Pattern 4: Proposal Validation Hooks

Automatically verify that proposal calldata doesn’t target critical functions without explicit safeguards.

contract GovernorWithValidation is Governor {
    // Functions that require super-majority (>80%) instead of simple majority
    mapping(bytes4 => bool) public criticalSelectors;

    constructor() {
        // Admin transfers always require super-majority
        criticalSelectors[bytes4(keccak256("_setPendingAdmin(address)"))] = true;
        criticalSelectors[bytes4(keccak256("_setImplementation(address)"))] = true;
        criticalSelectors[bytes4(keccak256("_setPriceOracle(address)"))] = true;
        criticalSelectors[bytes4(keccak256("transferOwnership(address)"))] = true;
        criticalSelectors[bytes4(keccak256("upgradeTo(address)"))] = true;
    }

    function _quorumReached(uint256 proposalId) 
        internal view override returns (bool) 
    {
        if (_containsCriticalAction(proposalId)) {
            // Critical actions need 80% approval, not 50%
            uint256 forVotes = proposalForVotes(proposalId);
            uint256 totalVotes = forVotes + proposalAgainstVotes(proposalId);
            return totalVotes >= quorum() && 
                   forVotes * 100 / totalVotes >= 80;
        }
        return super._quorumReached(proposalId);
    }

    function _containsCriticalAction(uint256 proposalId) 
        internal view returns (bool) 
    {
        (address[] memory targets, , bytes[] memory calldatas, ) = 
            proposals[proposalId].getActions();

        for (uint256 i = 0; i < calldatas.length; i++) {
            if (calldatas[i].length >= 4) {
                bytes4 selector = bytes4(calldatas[i][:4]);
                if (criticalSelectors[selector]) return true;
            }
        }
        return false;
    }
}

What this prevents: Payload obfuscation attacks (Vector 3). Even if token holders don’t read the calldata, the contract itself enforces higher thresholds for dangerous operations.

Pattern 5: Adaptive Quorum with Participation Weighting

Dynamic quorum that increases when voter participation is abnormally low.

contract AdaptiveQuorumGovernor is Governor {
    uint256 public constant BASE_QUORUM_BPS = 1000; // 10%
    uint256 public constant MAX_QUORUM_BPS = 4000;  // 40%

    uint256 public avgParticipationBps;

    function quorum(uint256 timepoint) public view override returns (uint256) {
        uint256 totalSupply = token.getPastTotalSupply(timepoint);

        uint256 adjustedQuorum = BASE_QUORUM_BPS;

        if (avgParticipationBps > 0) {
            adjustedQuorum = BASE_QUORUM_BPS * avgParticipationBps / 
                             _currentParticipationBps();

            if (adjustedQuorum > MAX_QUORUM_BPS) {
                adjustedQuorum = MAX_QUORUM_BPS;
            }
        }

        return (totalSupply * adjustedQuorum) / 10000;
    }
}

What this prevents: Low-quorum treasury drains (Vector 2). When participation drops, quorum rises automatically.

Pattern 6: Time-Weighted Voting Power

Weight voting power by holding duration. Recent purchasers get reduced influence.

function getVotingPower(address account, uint256 proposalBlock) 
    public view returns (uint256) 
{
    uint256 balance = token.getPastVotes(account, proposalBlock);
    uint256 holdingDuration = _getHoldingDuration(account, proposalBlock);

    // Linear ramp: 0% power at 0 days, 100% at 30 days
    uint256 multiplier;
    if (holdingDuration >= 30 days) {
        multiplier = 10000; // 100%
    } else {
        multiplier = (holdingDuration * 10000) / 30 days;
    }

    return (balance * multiplier) / 10000;
}

What this prevents: Market purchase attacks where tokens are bought shortly before a proposal snapshot.

Pattern 7: Optimistic Governance with Challenge Period

Proposals are assumed to pass unless challenged. Challenges trigger full voting.

contract OptimisticGovernor {
    uint256 public constant CHALLENGE_PERIOD = 5 days;
    uint256 public constant CHALLENGE_BOND = 10000e18;

    enum ProposalState { Proposed, Challenged, Executed, Cancelled }

    function challenge(uint256 proposalId) external {
        require(proposals[proposalId].state == ProposalState.Proposed);
        require(block.timestamp < proposals[proposalId].deadline);

        token.transferFrom(msg.sender, address(this), CHALLENGE_BOND);
        proposals[proposalId].state = ProposalState.Challenged;
        _startFullVote(proposalId);
    }
}

What this prevents: Reduces attack surface by requiring active monitoring. Routine proposals execute faster, suspicious ones get escalated.

Implementation Checklist: Defense-in-Depth

Minimum viable defense (all protocols):

  1. ✅ Snapshot-based voting (Pattern 1) — prevents flash loans
  2. ✅ Break Glass Guardian (Pattern 3) — emergency backstop
  3. ✅ Proposal validation hooks (Pattern 4) — auto-detect critical actions

Enhanced defense (>$10M TVL):

  1. ✅ Vote escrow with lock period (Pattern 2)
  2. ✅ Adaptive quorum (Pattern 5)

Maximum security (>$100M TVL):

  1. ✅ Time-weighted voting (Pattern 6)
  2. ✅ Optimistic governance (Pattern 7)

Monitoring (all protocols):

  • Alert on large token transfers to new addresses
  • Monitor proposal creation from recent token acquirers
  • Track delegation concentration changes
  • Alert on proposals targeting admin/upgrade/oracle functions

The Solana Parallel: SPL Governance Risks

Solana’s governance tooling (SPL Governance, Realms) faces the same attack classes with Solana-specific twists:

// Solana SPL Governance: Ensure voting weight uses token lock, not balance
pub fn get_voter_weight(
    governing_token_deposit: &GoverningTokenDeposit,
) -> Result<u64> {
    let deposit_time = governing_token_deposit.deposit_timestamp;
    let current_time = Clock::get()?.unix_timestamp;
    let holding_duration = current_time - deposit_time;

    // Require minimum 3-day deposit before voting weight activates
    if holding_duration < 3 * 86400 {
        return Ok(0);
    }

    Ok(governing_token_deposit.amount)
}

Key differences on Solana:

  • No flash loans in the EVM sense, but atomic CPI chains can achieve similar effects
  • SPL Governance uses explicit deposit/withdrawal of tokens into governance accounts
  • Realms voter weight plugins allow custom weight calculations — use them for time-weighting
  • Account close attacks can disrupt governance records if not properly handled

The Cost of Doing Nothing

The governance attack surface is expanding because:

  1. More DAOs are being created — Aragon, Tally, and Realms make DAO deployment trivial, but don’t enforce security best practices
  2. Token concentration is increasing — Low-float tokens on secondary chains make quorum-level purchases affordable
  3. Cross-chain governance is emerging — Multi-chain voting adds bridge delays, finality gaps, and synchronization vulnerabilities
  4. AI-assisted attacks are coming — LLMs can scan proposal thresholds, model attack economics, and identify vulnerable DAOs automatically

The Moonwell attack cost $1,800. The next one might cost $18. If your protocol uses on-chain governance without at minimum snapshot voting, vote escrow, and an emergency guardian, you’re not “decentralized” — you’re just undefended.

This analysis is part of the DeFi Security Research series. All code examples are for educational and defensive purposes. Previous entries covered the Aave V3 fork epidemic, the zero-cost Solana security pipeline, and custom detector development.

Replacing SCCM with FOG Project

Replacing SCCM with FOG Project

When I moved our infrastructure from Hyper-V to Proxmox, I also took the chance to rip out one of the heaviest pieces of the old stack: SCCM.

For an enterprise with thousands of endpoints and a full Microsoft licensing budget, SCCM can make sense. For four instructional labs with 72 workstations, it was too much. It wanted Windows Server, SQL Server, licensing baggage, and constant babysitting just to do the thing I actually needed: boot a machine over the network, lay down a clean image, put it back in the domain, and get out of the way.

FOG Project was the answer.

This post is the technical deep-dive for the imaging side of the migration. For the full Hyper-V to Proxmox migration story, see the migration deep-dive.

The environment I was replacing

The target was straightforward on paper:

  • 4 classrooms
  • 72 total workstations
  • 3 hardware-specific Windows 11 images
  • 47 machines with known MAC addresses at import time
  • 25 machines that would need to self-register on first PXE boot
  • Active Directory domain join after imaging
  • Room-specific OU placement

The architecture ended up looking like this:

  • FOG server: Debian Trixie 13 LXC on Proxmox, 10.0.1.20
  • Domain controllers / DHCP: Windows Server, 10.0.1.10 and 10.0.1.11
  • Domain: LAB.LOCAL
  • Join account: [email protected]
  • Rooms: Room-A, Room-B, Room-C, Room-D
  • Images: Win11-Lab-G4, Win11-Lab-Ultrawide, Win11-Lab-G9

I did not build images in Proxmox VMs. I built them on reference machines that matched the real lab hardware. The rooms were not identical. One had HP G4s, one had HP G9s, and two rooms had Dell FCT2250s paired with Dell UltraSharp 49″ curved monitors (U4924DW/U4919DW), which needed their own driver set.

Three golden images, three hardware profiles:

Room Image
Room-A Win11-Lab-G4
Room-B Win11-Lab-Ultrawide
Room-C Win11-Lab-Ultrawide
Room-D Win11-Lab-G9

Active Directory prep

The Linux box gets the attention in a FOG write-up, but the boring Windows prep is what made the deployment clean.

I created a least-privilege service account called svc-domainjoin and delegated only what FOG needed on the classroom OUs: create computer objects, delete computer objects, and full control on descendant computer objects.

The OU layout was one OU per room. Then I delegated permissions with dsacls:

dsacls "OU=Room-A,DC=LAB,DC=LOCAL" /I:T /G "LABsvc-domainjoin:CC;computer"
dsacls "OU=Room-A,DC=LAB,DC=LOCAL" /I:T /G "LABsvc-domainjoin:DC;computer"
dsacls "OU=Room-A,DC=LAB,DC=LOCAL" /I:S /G "LABsvc-domainjoin:GA;;computer"

Same pattern on all four classroom OUs.

Before touching imaging at all, I cleaned house in AD: moved 38 misplaced computer objects into the right OUs, deleted 60 stale ones from old naming schemes, unlinked the SCCM GPO from the room OUs, and exported a CSV of all 72 lab machines.

Then I set DHCP options 66 and 67 on the classroom scopes to point to FOG:

  • Option 66: 10.0.1.20
  • Option 67: initially ipxe.efi

Should have been enough. It was not.

The SCCM ghost in DHCP

PXE still misbehaved on some scopes even with the scope-level options pointing to FOG.

The culprit was stale SCCM and WDS policies still attached to several scopes. DHCP policies take priority over scope options. Clients matching the PXE vendor class were quietly getting sent to the retired SCCM server at 10.0.1.14 instead of FOG at 10.0.1.20. The old policies referenced smsbootx64wdsmgfw.efi and smsbootx64wdsnbp.com with the old boot server IP.

Eleven of those policies, spread across five scopes. Once I removed them all, PXE stopped getting hijacked by dead infrastructure.

Note: If PXE settings look right but clients keep booting somewhere else, check DHCP policies before you blame FOG.

FOG on Debian Trixie: three bugs in a trenchcoat

The FOG server was a Debian 13 LXC container on Proxmox. When I first looked at it, the web UI was running, which made it look installed.

It was not. The backend was missing entirely. No TFTP boot files. No NFS exports. No FOG services. The web UI was a shell with nothing behind it.

Re-ran the installer:

cd /tmp/fogproject/bin
bash installfog.sh -y

Trixie had other plans.

Bug 1: wrong osid

FOG had the wrong OS ID in .fogsettings. It detected the machine as Arch Linux instead of Debian. Fix in /opt/fog/.fogsettings:

osid='3'

to:

osid='2'

Without that, every package operation targeted the wrong distro.

Bug 2: libcurl4 renamed on Debian 13

Debian 13’s t64 transition renamed libcurl4 to libcurl4t64. FOG’s installer still asked for the old name. I patched the package check in functions.sh to handle Debian >= 13.

Bug 3: lastlog became lastlog2

FOG’s installer checks lastlog to verify user creation. Trixie dropped it for lastlog2. Quick fix:

apt-get install -y lastlog2
ln -sf /usr/bin/lastlog2 /usr/local/bin/lastlog

Once I patched all three, the installer completed and the backend finally matched the web UI.

NFS inside LXC: the container wall

With the installer patched, the next wall was image storage. FOG uses NFS for capture and deployment. Inside a Proxmox LXC container, kernel NFS does not cooperate:

mount: /proc/fs/nfsd: permission denied

I tried the usual Proxmox container feature flags:

pct set <CTID> -features nesting=1,nfs=1
pct reboot <CTID>

Better, but still not a reliable kernel NFS server. I stopped fighting it and went userspace: nfs-ganesha.

apt install nfs-ganesha nfs-ganesha-vfs

One annoying gotcha: Ganesha’s pseudo paths cannot nest. Having /images and /images/dev as pseudo paths breaks child lookup. I had to flatten the namespace.

The working /etc/ganesha/ganesha.conf:

NFS_CORE_PARAM {
    Protocols = 3,4;
    mount_path_pseudo = true;
    allow_set_io_flusher_fail = true;
}

EXPORT {
    Export_Id = 1;
    Path = /images;
    Pseudo = /images;
    Protocols = 3,4;
    Access_Type = RO;
    Squash = no_root_squash;
    FSAL { Name = VFS; }
    CLIENT { Clients = *; Access_Type = RO; }
}

EXPORT {
    Export_Id = 2;
    Path = /images/dev;
    Pseudo = /imagesDev;
    Protocols = 3,4;
    Access_Type = RW;
    Squash = no_root_squash;
    FSAL { Name = VFS; }
    CLIENT { Clients = *; Access_Type = RW; }
}

The critical line for LXC: allow_set_io_flusher_fail = true;. Without it, Ganesha dies with EPERM on PR_SET_IO_FLUSHER. That flag lets it skip the kernel call and keep running.

Verify with showmount -e localhost and rpcinfo -p localhost. If both look right, NFS is serving.

Note: Kernel NFS in LXC was a dead end. Userspace NFS was the practical way through it.

The golden image pipeline

With the server side stable, the real work was image prep. Same process every time:

  1. clean install Windows 11 on the reference machine
  2. install drivers, software, updates, and room-specific settings
  3. keep it off the domain
  4. install the FOG client if needed for post-deploy tasks
  5. clean it aggressively
  6. sysprep and shut down
  7. PXE boot and capture in FOG

Step 5 became its own thing. The cleanup one-liner I kept copy-pasting between machines. Ugly, but it works:

Stop-Service wuauserv -Force; Remove-Item C:WindowsSoftwareDistribution* -Recurse -Force -EA SilentlyContinue; Start-Service wuauserv; Dism /online /Cleanup-Image /StartComponentCleanup /ResetBase; Remove-Item C:WindowsPanther* -Recurse -Force -EA SilentlyContinue; Remove-Item C:WindowsTemp* -Recurse -Force -EA SilentlyContinue; Remove-Item C:WindowsPrefetch* -Recurse -Force -EA SilentlyContinue; Remove-Item "$env:TEMP*" -Recurse -Force -EA SilentlyContinue; Clear-RecycleBin -Force -EA SilentlyContinue; cleanmgr /sagerun:1; C:WindowsSystem32Sysprepsysprep.exe /oobe /generalize /shutdown

I started calling it the Frankenstein command. It’s stitched together from half a dozen different guides and does way too much in one line. But for repeatable image prep, it earned its place.

Broken down:

  • Stop-Service wuauserv -Force / Remove-Item SoftwareDistribution / Start-Service wuauserv: kill Windows Update, nuke the cache, bring it back.
  • Dism /online /Cleanup-Image /StartComponentCleanup /ResetBase: collapse superseded component versions. Frees real space.
  • The four Remove-Item lines: purge Panther logs, system temp, Prefetch, and user temp.
  • Clear-RecycleBin: self-explanatory.
  • cleanmgr /sagerun:1: Disk Cleanup with preconfigured settings.
  • sysprep.exe /oobe /generalize /shutdown: strip machine identity, stage OOBE, power off.

Note: After sysprep shuts the machine down, do not let it boot back into Windows before capture. If it does, you just spent your sysprep state and get to do it again.

Sysprep on Windows 11: Appx package hell

The worst part of this project was not FOG. It was Sysprep.

If you’ve fought Windows 11 Sysprep before, you know the error. If you haven’t, it looks like this in the Panther logs:

Sysprep was not able to validate your Windows installation.

More specifically:

Package <app> was installed for a user, but not provisioned for all users. This package will not function properly in the sysprep image.
Failed to remove apps for the current user: 0x80073cf2.

On Windows 11 23H2 and 24H2, the Microsoft Store silently updates Appx packages per-user. That creates a version mismatch between the installed state and the provisioned state. Sysprep sees it, panics, refuses to generalize.

What I tried that did not work:

  • Remove-AppxPackage -AllUsers
  • Remove-AppxProvisionedPackage
  • the mythical SkipAppxValidation registry setting
  • editing Generalize.xml
  • renaming AppxSysprep.dll

Some fail outright. Some appear to work, then the packages come back after a reboot. Some just swap one error for a different one.

What actually worked: changing the source image entirely.

I used Chris Titus Tech’s WinUtil to build a MicroWin ISO. Instead of installing stock Windows and spending hours ripping Store junk back out, I started from a clean ISO that never had the Appx baggage in the first place.

Prevention over cleanup:

  1. build MicroWin ISO
  2. install on the reference machine
  3. configure drivers and software
  4. disconnect from the network before sysprep if needed
  5. run the cleanup command
  6. sysprep, shut down, capture immediately

That was the difference between fighting Sysprep every time and having it just work.

PXE on newer hardware: snponly.efi

One more issue that looked like FOG but wasn’t. A newer motherboard would download ipxe.efi, start up, and freeze at:

iPXE initializing devices...

No ok. Just stuck.

iPXE’s built-in NIC driver couldn’t handle the newer chipset. The fix: switch DHCP option 67 from ipxe.efi to snponly.efi.

The difference is simple. ipxe.efi ships its own NIC drivers. snponly.efi delegates to the UEFI firmware’s native SNP driver. On newer boards, the firmware driver works where iPXE’s doesn’t.

One DHCP change, ipxe.efi to snponly.efi, and the machine booted straight to the FOG menu. It became the default for all our UEFI clients.

72 systems, deployed by room

With images captured and PXE stable, FOG could finally do its job.

Bulk imported the workstation list from CSV:

  • 47 had MAC addresses ready for direct import
  • 25 had no active lease at the time, so they were left to auto-register when first PXE booted

Each host got the right image and room group. Deploying a room was: select the group, schedule a deploy task, PXE boot the room. That’s it.

FOG uses Partclone under the hood, so it only transfers used blocks. A 500 GB drive with 30 GB used doesn’t push 500 GB over the wire. It pushes roughly 30 GB, compressed. Room-wide imaging is faster than people expect.

After deployment, the FOG client sets the hostname, joins the domain via svc-domainjoin, and drops the computer object in the correct OU. Multicast is also available for imaging an entire room simultaneously.

What I learned

Setting up FOG is not just “install FOG.” It’s DHCP policy archaeology, AD delegation, Windows image hygiene, boot loader compatibility, and the reality of running services inside Linux containers.

The short list:

  • DHCP policies override scope options. Check for leftover WDS/SCCM policies before blaming FOG.
  • A running web UI does not mean FOG is installed. Verify TFTP, services, and NFS.
  • FOG on Debian Trixie needs manual patches. osid, libcurl4t64, lastlog2.
  • Kernel NFS in Proxmox LXC is a dead end. Use nfs-ganesha.
  • Build images on reference machines. VM images don’t carry driver quirks correctly.
  • Debloat before install, not after. MicroWin saves hours of Appx cleanup.
  • Test Sysprep on something disposable first. Appx breakage on your finished image is a bad time.
  • snponly.efi for newer hardware. If iPXE hangs at device init, switch boot files.
  • Never boot a sysprepped machine before capture. Generalize is one-shot.
  • FOG’s hostName is VARCHAR(16). Plan your naming accordingly.

Once the rough edges were filed down, the day-to-day got simple. Pick the room. PXE boot. Image. Domain join. Done. Way less overhead than SCCM ever was.

That’s the kind of boring I want from lab infrastructure.

This post is part of a larger infrastructure migration series. For the full Hyper-V to Proxmox migration story, see the project page on solomonneas.dev.

Originally published at solomonneas.dev.

CodePen TV secrets

Those seven deadly things you always wanted to know about creating a CRT TV in CSS.

A behind the scenes candid deep dive.

(1) My first vanilla CSS Art project!
Can you actually believe it? Yes. But anyway, I got so into SASS that it wasn’t until… Well I explained it all in my last post but yeah, I guess this is my first actual pure CSS art! I did really want to add white noise and channel clicks, but that would have involved JavaScript, so you shall have to imagine that yourselves. It’s also my first use of corner-shape: squircle. Firefox doesn’t support me on this yet, but oh well! I think squircle is necessary usage for a CRT!

(2) Lighting the CodePen logo.
The spinny cube thing has actual three dimensional light coming from the left, which took blumming ages to do, and it’s barely even noticeable. So I would just like to point that out here 😅

(3) The volume control distorts the scanlines.
I thought this would kind of represent the increase in volume interfering with the tuning, as it would if you didn’t have ground loop isolation.

(4) Rotating knobs.
Getting the knobs look like they rotate when the shine stays top right. It was a tricky one. But the dashed border works hard here.

(5) The glass reflections could not be square!
To replicate the distortion of a cathode ray tube’s shape. The window reflection is made entirely of repeated right dashed borders. These look very different depending on the browser engine. Blink’s dash size is almost perfect for the real window panes. But it’s a strange way to draw windows.

 &, &:before, &:after {
     width: 31rem;
     height: 100rem;
     border: solid 7rem transparent;
     border-right: dashed 7rem hsla( var(--wht-hsl),.05);
     background: transparent;
     border-radius: 50%;
 }

(6) It’s responsive!
The TV changes layout depending on your screen size. I used rems and aspect ratios hard!

(7) The CodePen 2.0 logo.
The rotating 2.0 makes no sense in reality. It does transform:scaleX(-1) exactly at 90 degrees so that 2.0 reads left to right on both the front and back.

Your AI Agent Forgets Everything Between Sessions. I Fixed That.

Every time you start a new session with Claude Code, Cursor, or any AI coding agent, it starts from scratch. It does not remember:

  • Who you are or what you prefer
  • What decisions were made yesterday
  • What corrections you already gave it
  • Where external resources live

I built memorybank to fix this.

What is memorybank?

An MCP server that gives any AI agent persistent, cross-session memory. Zero dependencies, file-based, works with Claude Code, Cursor, Windsurf, and any MCP-compatible tool.

npx @ura-dev/memorybank --help

8 MCP Tools

Tool What it does
memory_store Save a memory (user, project, feedback, reference, custom)
memory_recall Retrieve most relevant memories for a query
memory_list List all memories, filter by type or tag
memory_get Get a specific memory by ID
memory_update Update an existing memory
memory_delete Delete a memory
memory_search Full-text search across all memories
memory_stats Counts, types, storage size

How it works

  1. Your agent encounters something worth remembering
  2. It calls memory_store with a type, name, and content
  3. memorybank saves it as a markdown file with YAML frontmatter
  4. Next session, the agent calls memory_recall to load relevant context
  5. The agent now knows what happened before

Memories are stored locally in ~/.memorybank/, organized by namespace (one per project). No cloud, no database, no API keys.

Setup in 30 seconds

Add to your Claude Code config (~/.claude/settings.json):

{
  "mcpServers": {
    "memorybank": {
      "command": "npx",
      "args": ["-y", "@ura-dev/memorybank", "memorybank-mcp"]
    }
  }
}

Or Cursor (.cursor/mcp.json):

{
  "mcpServers": {
    "memorybank": {
      "command": "npx",
      "args": ["-y", "@ura-dev/memorybank", "memorybank-mcp"]
    }
  }
}

That is it. Your agent now has persistent memory.

Five memory types

  • user — About you: role, preferences, expertise level
  • project — About the work: goals, architecture decisions, deadlines
  • feedback — Corrections you gave: what to avoid, what worked
  • reference — External pointers: URLs, docs locations, API endpoints
  • custom — Anything else

Why not just use CLAUDE.md?

CLAUDE.md is great for static project instructions. memorybank is for dynamic knowledge that evolves during work:

  • User corrections that should persist
  • Architecture decisions made mid-project
  • References discovered during research
  • Project status that changes daily

memorybank complements CLAUDE.md. One for rules, the other for learned knowledge.

CLI too

memorybank store user team-lead "User is the team lead for backend services"
memorybank search "TypeScript preferences"
memorybank list --type=feedback
memorybank store project api-rewrite "Migrating REST to GraphQL" --namespace=myproject

Also: agentrace

If you want to see what your AI agent is doing (not just what it remembers), check out agentrace. Structured observability for AI agents. Same philosophy: MCP server, zero deps, file-based.

Links:

Built with zero dependencies. MIT licensed. Works today.

I Built a Piano Trainer That Measures Stability, Not Just Speed

Most piano practice tools measure speed.

Some measure note accuracy.
Some turn practice into a game.
Some help beginners learn what key to press next.

But there is a problem hidden underneath all of that:

speed is not the same as control.

A pianist can play fast and still sound unstable.
A trill can be quick but uneven.
A repeated-note passage can look impressive on paper, while the actual timing is wobbling underneath.

And that wobble matters.

Especially in repeated notes, trills, and high-pressure fast passages, the real issue is often not whether you can move your fingers fast enough.

It is whether you can stay stable while moving fast.

That question led me to build Piano Virtuoso 18.

Piano Virtuoso 18 is a browser-based piano trainer focused on something that most tools do not treat as the main event:

timing stability.

Instead of rewarding raw speed alone, it evaluates whether the player can maintain control, consistency, and evenness during short high-speed bursts.

You can try it here:

The problem: fast is visible, instability is not

Traditional practice makes it easy to notice obvious mistakes.

You can hear missed notes.
You can hear when the rhythm collapses completely.
You can tell when you simply cannot keep up.

But many technical weaknesses live in a more subtle zone.

A player may think:

  • “I can do this trill.”
  • “I can repeat this note fast enough.”
  • “My right hand is getting faster.”

But when you actually examine the timing at a finer level, a different picture can appear:

  • one note is consistently late
  • alternation becomes uneven under pressure
  • bursts accelerate and then decay
  • intervals drift away from the intended spacing
  • speed rises, but control falls apart

This is the zone I wanted to expose.

Because in real playing, especially in advanced piano technique, fast and unstable is not mastery.

Fast and stable is technique.

Why repeated notes and trills matter so much

Repeated notes and trills are not just “small exercises.”

They reveal the truth about control.

If your motion is unstable, these patterns expose it immediately.
If your timing is uneven, they punish it immediately.
If your hands can generate speed but cannot regulate it, they make that weakness obvious.

That makes them perfect for measurement.

So instead of building a general piano-learning platform, I focused on a narrower and sharper question:

Can timing stability be measured directly during short, fast piano actions?

That became the design center of Piano Virtuoso 18.

The idea behind Piano Virtuoso 18

Piano Virtuoso 18 is not designed as a generic tapping game.

It is not mainly about “how many presses can you do.”
It is not mainly about “did you hit the correct note.”
And it is not trying to behave like a full AI piano teacher.

Its core idea is much more specific:

measure the quality of high-speed timing behavior, not just the quantity of taps.

That means the system cares about things like:

  • micro-timing deviation
  • interval consistency
  • stability score
  • burst-control behavior
  • alternation evenness

The goal is to convert invisible technique problems into visible data.

What the trainer actually does

Piano Virtuoso 18 runs in the browser and works with MIDI input.

Its current design centers on short, measurable performance windows — especially 10-second sprints — because they create a clean situation for observing speed under pressure.

The current core modes are:

Erlkönig Mode

A repeated-note stability challenge centered on C4.

This mode is built for the kind of rapid single-note repetition that appears in advanced piano technique, especially where the issue is not merely speed, but maintaining uniform control.

Trill Mode

An alternation stability challenge using C4 ↔ D4.

This mode evaluates how evenly the player alternates between two notes, and how stable the timing remains during the burst.

These are simple exercises on the surface.

But that simplicity is exactly what makes them useful as a technical lens.

When the task is stripped down, instability has nowhere to hide.

The central metric: stability over time

The most important idea in the project is this:

raw speed is not enough as a score.

A player who produces more taps is not necessarily demonstrating better technique.
They may simply be generating more chaotic motion.

So Piano Virtuoso 18 treats stability as a first-class signal.

That means the score is influenced not only by how fast the notes arrive, but by how evenly they are spaced and how well the performer sustains timing quality across the entire attempt.

This is the real difference between a speed toy and a technique analyzer.

Visualizing the problem

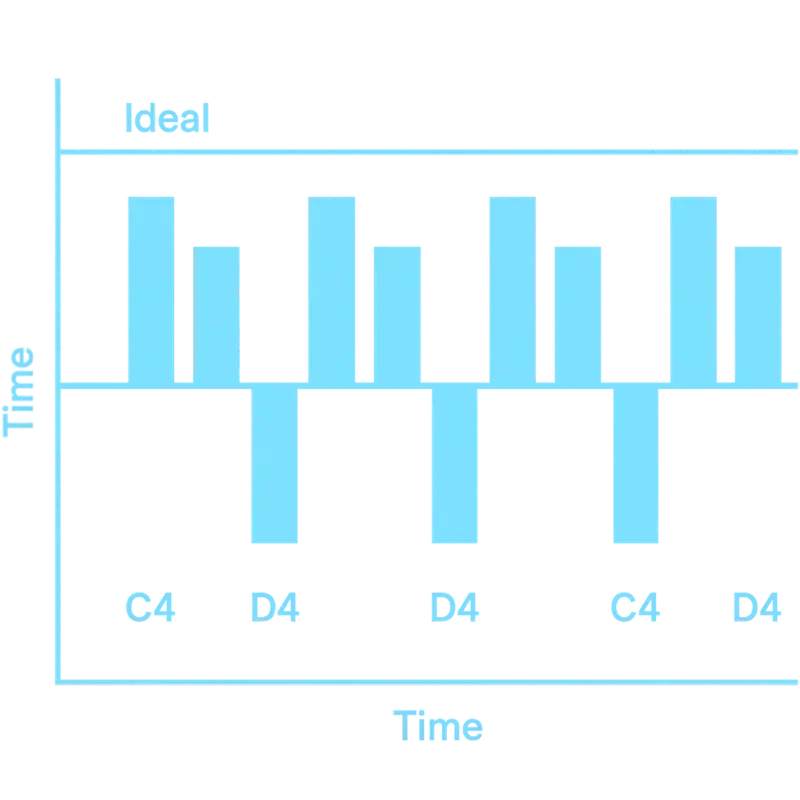
Here is the kind of timing structure the system is built around.

This image represents an idealized view of alternation over time.

The horizontal axis is time.
The vertical structure separates note events in a repeating pattern.
In trill-style alternation, the important question is not only whether the player hits both notes, but whether those events remain evenly spaced and structurally consistent over the full burst.

That is where the interesting information lives.

Not in “did the note happen?”
But in:

  • when it happened
  • how evenly it happened
  • how much the spacing drifted
  • whether the player stayed under control

Once you look at performance this way, many familiar practice tools start to feel incomplete.

Why I built it in the browser

I wanted the system to be immediate, lightweight, and accessible.

That is why Piano Virtuoso 18 runs directly in the browser rather than requiring a heavy native installation.

For this kind of prototype and training system, the browser offers several advantages:

  • instant access
  • simple distribution
  • easy iteration
  • direct MIDI integration
  • no-friction testing across devices

That makes it easier to experiment with measurement ideas quickly.

And more importantly, it keeps the focus on the analysis itself, instead of burying the project under installation friction.

Why this is not just another rhythm game

At a glance, some people might think:
“Isn’t this just a tapping challenge for pianists?”

No.

That interpretation misses the point.

A tapping game usually rewards output volume:
more presses, more points, end of story.

Piano Virtuoso 18 is built around a different assumption:

bad speed should not be rewarded the same way as controlled speed.

That changes the meaning of the entire system.

If a player produces a lot of presses but their interval spacing is collapsing, that is not the same as true control.
If a trill becomes rhythmically unbalanced, that is not a clean success.
If the player’s burst profile shows instability, the score should reflect that.

So the trainer is not merely counting events.

It is judging whether the events remain structurally stable enough to represent real technique.

That is why I describe it less as a game and more as a stability-focused performance analyzer.

What makes this useful for real pianists

Most musicians already know the feeling of “I thought I played that better than I actually did.”

That gap between perception and measurable execution is where useful training tools can matter.

Piano Virtuoso 18 helps by exposing things that are usually buried inside vague intuition:

  • whether your repeated notes are actually even
  • whether your trill alternation is structurally balanced
  • whether your speed is sustainable or collapsing
  • whether your timing control survives pressure

This matters because once a weakness becomes measurable, practice changes.

You stop relying only on mood, self-estimation, or wishful thinking.
You can train against an observed problem instead of a vague feeling.

That is where real feedback begins.

Why I think “stability” deserves more attention

In many practice environments, speed gets the spotlight because it is easy to understand and easy to market.

It is simple to ask:
“How fast are you?”

It is much more interesting to ask:
“How stable are you at speed?”

That second question gets closer to what technique actually is.

Not motion alone.
Not effort alone.
Not excitement alone.

But regulated motion under pressure.

That is the territory Piano Virtuoso 18 is trying to formalize.

The broader idea behind the project

The deeper idea here is larger than one piano trainer.

I think there is room for a whole class of music tools that do not just teach content, but measure structural quality.

Not just:

  • what note was played
  • whether the answer was correct
  • whether the user finished the task

But:

  • whether timing stayed stable
  • whether motion stayed consistent
  • whether performance quality degraded under load
  • whether control survived intensity

That kind of measurement is interesting not only for piano, but for musical technique more broadly.

Piano Virtuoso 18 is one concrete attempt to move in that direction.

Current project links

If you want to look at the project directly:

Final thought

Most people can understand speed.

But in serious playing, speed is the easy part to admire and the dangerous part to overestimate.

The harder question is whether the performance stays stable when speed arrives.

That is the question that led me to build Piano Virtuoso 18.

Not a trainer that simply asks:

“How fast can you go?”

But a trainer that asks:

“How stable are you when you get there?”

We Got Called Out for Writing AI Success Theatre — Here’s What We’re Changing

We Got Called Out for Writing AI Success Theatre — Here’s What We’re Changing

A developer read our Sprint 7 retrospective and compared it to “CIA intelligence histories — designed to make the Agency seem competent and indispensable, even when it isn’t.”

That stung. And then I realized: he’s right.

The Problem He Identified

Nick Pelling is a senior embedded engineer who’s been watching our AI-managed development project. We’ve published retrospective blog posts after every sprint — nine so far. His feedback was blunt:

“The blog’s success theatre has an audience of one.”

“Logging activities is a stakeholder-facing thing, but not very interesting to non-stakeholders.”

“Maybe you need a second blog that other people might be more interested to read.”

He’s pointing at a real failure: we optimized our blogs for internal accountability and accidentally published them as if they were developer content. They aren’t. They’re audit logs wearing a blog post’s clothes.

What Success Theatre Looks Like

Here’s a line from our Sprint 7 retrospective:

“Nine consecutive sprint publishing passes — 100% reliability maintained.”

That’s true. It’s also the kind of thing you put in a status report to your boss. A developer on Dev.to reading that thinks: “Cool. Why should I care?”

Or this: “OAS-124-T2: Pipeline Execution & Artifact Validation — 7 tests pass.”

That’s a ticket ID. Nobody outside our project knows what OAS-124 means. We were writing for ourselves and pretending we were writing for you.

The pattern across nine posts is consistent:

  • Lead with metrics that make us look good
  • Bury failures in a “What Went Wrong” section that’s shorter than the “What We Built” section
  • End with a provenance table that nobody asked for
  • Scatter ticket IDs everywhere like they’re meaningful

What Actually Happened in Sprint 7 (Honest Version)

We’re building an automated marketing platform — an AI-managed “agency” that handles content sourcing, script generation, audio narration, video production, and publishing. Sprint 7 was supposed to prove all the pieces work together.

Here’s what actually happened:

We put 118 services in one file and it’s a problem

Over six sprints, we built 118 backend services — API endpoints for everything from text-to-speech to YouTube uploads. Each one was individually tested and worked fine.

Then we wired them all into a single Express server file (api-server.mjs). All 118 routes, one file. No domain separation, no route modules.

This is the kind of decision that feels pragmatic at the time (“just add it to the server file”) and becomes technical debt the moment someone else has to read it. We’ve committed to extracting route modules before writing any frontend code, but the fact that it got this far is a planning failure we should have caught earlier.

Our tests prove wiring exists, not that anything works

Sprint 7’s big achievement was “118 services wired to production REST routes.” Sounds impressive. But here’s what the tests actually do:

// What our tests do (source inspection)
const src = fs.readFileSync('server.mjs', 'utf-8');
expect(src).toContain('app.post("/api/memory/store"');
// Passes — the route registration exists in the source code

// What our tests DON'T do (runtime validation)
const res = await fetch('http://localhost:3847/api/memory/store', {
  method: 'POST', body: JSON.stringify({ content: 'test' })
});
expect(res.status).toBe(200);
// We never wrote this test

We verified that route registrations exist in the source code. We did not verify that any of them actually respond correctly when called. Source inspection proves the wiring is there. It says nothing about whether the wiring works.

This is the difference between checking that a plug is in the socket and checking that electricity flows through it.

Advisory warnings don’t change behavior

We have a rule (ADR-032) that says AI personas should store what they learn after completing each task. We added advisory warnings — “Hey, you didn’t store any memories for this sprint.”

Three sprints in a row (Sprint 0, Sprint 4, Sprint 7), zero persona memories were stored. The warnings fired. They were ignored. Every time.

This taught us something genuinely useful about AI agent systems: advisory-only governance does not work for AI agents. If you want an AI agent to do something consistently, you need to make it mechanically impossible to skip. Warnings are suggestions. Gates are requirements.

We’re escalating from “warn at completion” to “blocking completion until the requirement is met.” If the pattern holds, this will be the fix. If it doesn’t, we’ll have to rethink the entire memory architecture.

The E2E pipeline test was the real win — and the real lesson

We built a pipeline executor that chains six stages: Source → Script → Audio → Assembly → Quality Gate → RSS. Each stage takes the previous stage’s output as input. If any stage fails, subsequent stages are skipped (not failed — skipped).

class PipelineExecutor {
  private stages: Array<{ name: string; fn: StageFn }> = [];

  run(): Result<PipelineResult> {
    let currentInput = null;
    let failed = false;

    for (const stage of this.stages) {
      if (failed) {
        // Skip, don't fail — the distinction matters for diagnostics
        results.push({ ...stage, status: 'skip' });
        continue;
      }
      try {
        const output = stage.fn(currentInput);
        if (output === null) { failed = true; }
        currentInput = output;
      } catch (e) {
        failed = true;
      }
    }
  }
}

The distinction between “failed” and “skipped” matters more than you’d expect. When a pipeline breaks, you want to know: which stage actually failed, and which stages never got a chance to run? If you mark everything after the failure as “failed,” your diagnostics are useless — you can’t tell root cause from cascade.

This is a pattern worth stealing for any multi-stage pipeline: fail the broken stage, skip the rest, and make the skip reason traceable.

We planned 58 points and delivered ~38

Our sprint planning estimated 58 story points. We delivered about 38. That’s a 34% miss.

The standard response is to spin this as “right-sizing” or “healthy scope management.” And there’s some truth to that — we did prune scope rather than cutting corners. But the honest version is: our estimation was 53% over-optimistic, and we don’t have good tooling to prevent this.

If you’re running AI agents on sprint work, be aware that estimation is harder, not easier, with AI. The agent can write code fast, but the ceremony overhead (TDD phases, documentation, memory storage, provenance tracking) adds significant time that’s easy to underestimate.

What We’re Changing

Starting with Sprint 8, our public blog posts will follow a different structure:

  1. Lead with what went wrong — not what we built. The failures are where the transferable lessons live.
  2. No ticket IDs — if you have to explain what OAS-124 means, it doesn’t belong in a public post.
  3. No provenance tables — these are compliance artifacts, not reader value.
  4. No “publishing streak” metrics — nobody cares how many consecutive blog posts we’ve published. They care if we have something worth reading.
  5. Code that solves problems — show the actual implementation with enough context for someone to reuse it. The pipeline executor pattern above is an example.
  6. Honest failure analysis — not “what went wrong” as a perfunctory section, but failure as the centerpiece of the post.

The internal retrospective (ticket-level accountability, sprint metrics, provenance) will stay in our internal tooling where it belongs.

Thank You, Nick

Nick Pelling’s feedback was the most useful thing anyone has said about this project in months. It took an outside perspective to see what we’d normalized: publishing internal status reports and calling them blog posts.

The previous retrospective posts will stay published — they’re an honest record of where we were, and now they serve as a “before” example of exactly the pattern Nick identified.

If you see us falling back into success theatre, call it out. That’s the most valuable contribution a reader can make.

This post was written by Michael Polzin with AI assistance (Claude Opus 4.6). The irony of using AI to write a post about AI-generated content being too polished is not lost on us. Nick would probably have something to say about that too.

Warp Terminal Has a Free AI That Makes Your Command Line Intelligent

Warp is a modern terminal with AI built in. Ask questions in natural language, get commands. Built-in command palette, blocks (grouped output), and team collaboration.

AI Features

# Type # to ask AI:
# how to find files larger than 100MB
# → Suggests: find . -type f -size +100M

# how to kill process on port 3000
# → Suggests: lsof -ti:3000 | xargs kill -9

# git undo last commit but keep changes
# → Suggests: git reset --soft HEAD~1

Blocks (Grouped Output)

Each command and its output is a “block.” You can:

  • Copy just the output (not the command)
  • Share a block as a link
  • Search within a block
  • Collapse/expand blocks

Workflows (Reusable Commands)

# Save commonly used command sequences
name: Deploy
steps:
  - git pull origin main
  - npm run build
  - npm run test
  - npm run deploy

Warp vs iTerm2 vs Alacritty

Feature Warp iTerm2 Alacritty
AI Built-in No No
Blocks Yes No No
Speed Fast (Rust) Medium Fastest
Collaboration Yes No No
Platform macOS, Linux macOS All

Free Tier

  • Individual: Free forever
  • Team: $15/user/month (sharing, admin)

The Bottom Line

Warp makes the terminal approachable for beginners (AI help) and powerful for pros (blocks, workflows, speed). If you’re on macOS or Linux, try it.

Need to automate data collection or build custom scrapers? Check out my Apify actors for ready-made tools, or email [email protected] for custom solutions.