Mert
xAI’ın son iki kurucu ortağı da şirketten ayrıldı
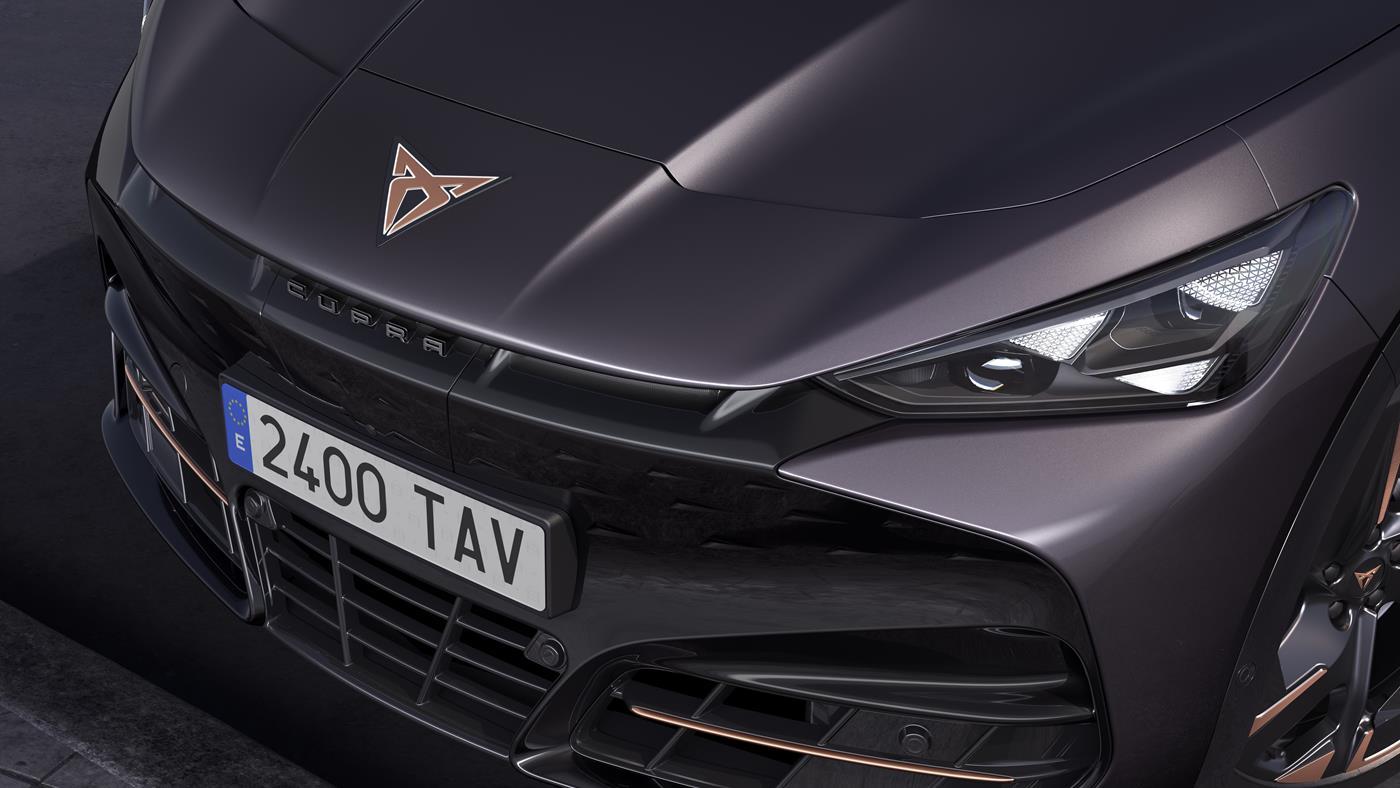
2026 Cupra Tavascan tanıtıldı: Yeni giriş versiyonu ile 435 km menzil
2026 Cupra Tavascan sahneye çıktı. Yeni giriş seviyesi, 435 km menzil, hızlı şarj, dijital kokpit ve V2L teknolojisiyle elektrikli coupe SUV segmentinde iddiasını artırıyor.Türk Telekom CEO’sundan 81 ilde 5G vurgusu!
Türk Telekom CEO’su Ebubekir Şahin, 1 Nisan itibarıyla 81 ilde 5G şebekesi sunulacağını vurguladı ve 5G ile geleceğin inşa edileceğini ifade etti.İran, ABD’nin uçan komuta merkezini yok etti: E-3 Sentry nedir, neden önemli?
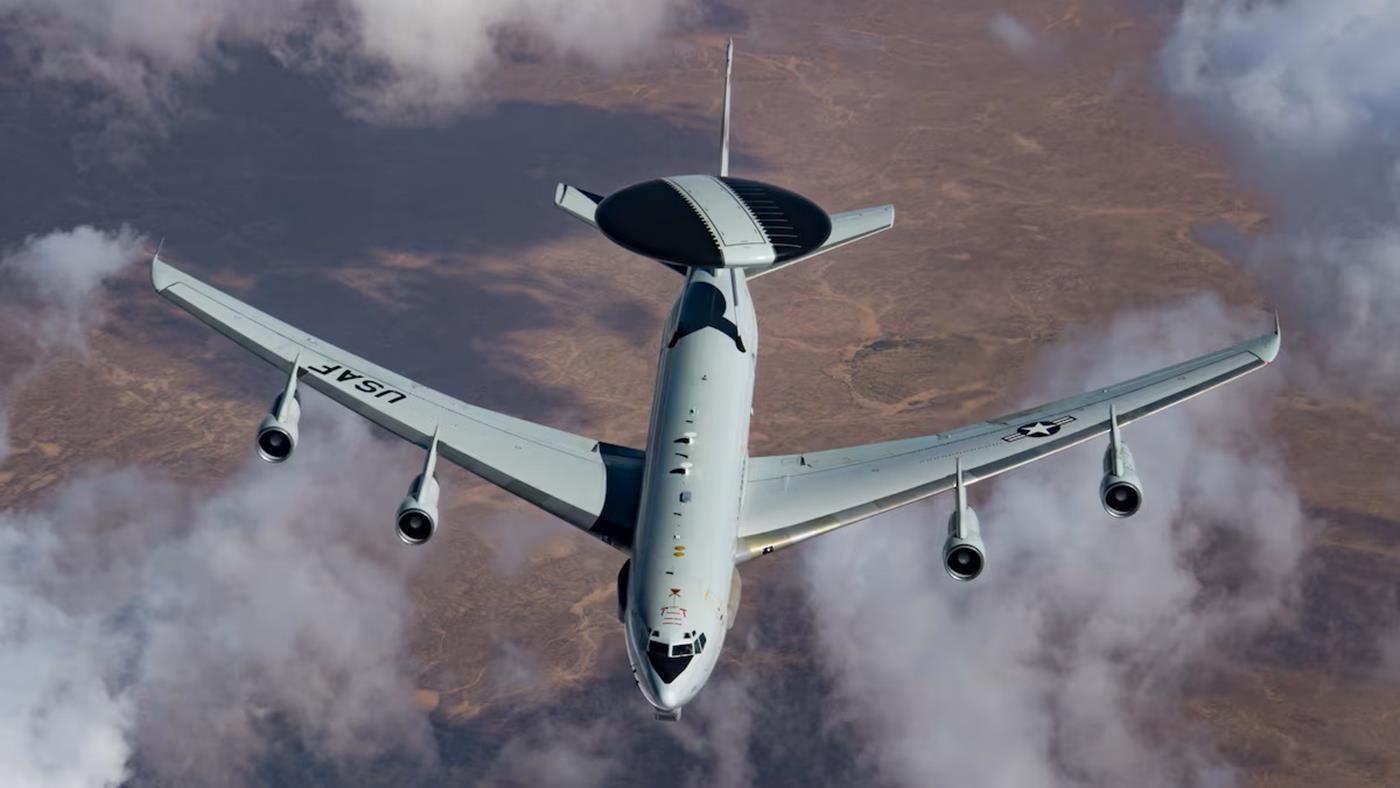
İran saldırısı sonucunda ABD’ye ait E-3 Sentry uçağı yok edildi. Peki bu ABD için ne anlama geliyor? E-3 Sentry AWACS uçağı nedir, neden bu kadar önemli ve değeri ne kadar?Yeni nesil Motorola telefonlar resmi olarak Türkiye’ye geliyor
Hepsiburada tarafından Instagram’da yapılan paylaşıma göre yeni nesil Motorola telefonlar resmi olarak Türkiye’ye geliyor. Henüz tüm detayların aktarılmadığı bu gelişme ilk olarak İndeks Bilgisayar şirketinin KAP bildirimi ile gündeme gelmişti: “Şirketimiz ile Lenovo Ireland International Ltd. arasında Motorola markalı cep telefonları ve cep telefonu aksesuarları ürünlerinin Türkiye distribütörlüğü konusunda görüşmelere başlanmıştır. Motorola, 1928’den beri tasarımla varlığını sürdüren ve kullanıcılarının dünyayı keşfetme, paylaşma ve bağlantı kurma biçimlerini dönüştüren global bir markadır. Markanın amacı, günlük yaşamı herkes için daha kolay ve daha keyifli hale getirmek için daha geniş bir mobil cihaz ve hizmet yelpazesi sunmaktır.” Daha sonra yapılan açıklama ise şöyle olmuştu: “Şirketimiz ile Lenovo Ireland International Ltd. arasında Motorola markalı cep telefonları ve cep telefonu aksesuarları ürünlerinin Türkiye distribütörlüğü konusunda görüşmeler olumlu sonuçlanmıştır. Motorola, 1928’den beri tasarımla varlığını sürdüren ve kullanıcılarının dünyayı keşfetme, paylaşma ve bağlantı kurma biçimlerini dönüştüren global bir markadır. Markanın amacı, günlük yaşamı herkes için daha kolay ve […]
Yeni nesil Motorola telefonlar resmi olarak Türkiye’ye geliyor yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.
OpenClaw AI Agent Review: Does It Actually Cut Cognitive Load for Developers?
Every developer knows the feeling. You’re mid-flow on a hard problem, and then — ping. Slack notification. Browser tab with three open PRs. A reminder to respond to that GitHub issue from last week. By the time you’ve processed each interrupt, the mental model you were holding has evaporated. You’re back at square one.
This isn’t a discipline issue. It’s a cognitive architecture issue.
The prefrontal cortex has a fixed working memory capacity — roughly 4 ± 1 chunks at any given moment, according to Cowan’s model. Every context switch burns a portion of that budget. Development work, which demands maintaining deep hierarchical abstractions, is among the most cognitively expensive tasks humans perform. So when tools promise to “help you work smarter,” the meaningful question is: do they reduce the number of active chunks you need to hold, or do they just add one more interface to manage?
That’s the lens I used when looking at the OpenClaw AI agent.
What OpenClaw Actually Does
OpenClaw is a personal AI agent platform. It runs on your infrastructure (or theirs), connects to your tools — browser, terminal, files, messaging — and handles tasks that you’d otherwise have to juggle yourself. The agent can browse the web, execute code, read and write files, send messages, and chain those actions together without you micromanaging each step.
Compared to a standard chatbot, the difference is meaningful: you delegate a goal, not a query. “Research pricing for X and drop a summary in Slack” is a task. “What’s the pricing for X?” is a query. One frees working memory. The other doesn’t.
Where It Genuinely Reduces Mental Load
Offloading information-gathering loops
One of the highest-friction patterns in dev work is the research loop: open tab, read, switch back, compare, open another tab, forget what you were comparing. This burns working memory fast because you’re holding partial findings while hunting for the next piece.
OpenClaw can handle the full gather-and-summarize cycle. You specify what you need, it retrieves and synthesizes, and you get a structured output you can act on. The difference in subjective experience is noticeable — instead of managing five browser tabs, you’re reading one summary.
Reducing decision fatigue around low-stakes choices
Not all decisions are equal. Choosing between two architectural patterns matters. Choosing which format to use for a meeting summary doesn’t. But both consume cognitive resources if you’re the one making them.
OpenClaw handles the second category well. You can set preferences, and it executes within them. The agent takes on the micro-decisions so you don’t have to.
Maintaining context across async work
Async communication is cognitively expensive because you have to reload context every time a thread resurfaces. OpenClaw can monitor channels, summarize what’s happened since you last looked, and flag items that actually need your attention. That’s not a convenience feature — it’s a genuine reduction in the number of context reloads your brain performs per day.
Where the Cognitive Overhead Lives
No tool is without cost. OpenClaw has a real learning curve in the setup phase. Connecting tools, defining workflows, understanding what the agent can and can’t do reliably — that’s a front-loaded investment of mental energy.
There’s also a trust calibration period. You need to spot-check outputs until you’ve built a model of the agent’s reliability across different task types. That’s not unreasonable — it’s the same process you’d go through with a new junior developer — but it’s work.
And occasionally the agent misunderstands scope. Not often, but enough that you can’t fully disengage. You still need to review outputs, especially on anything that touches external communication or code changes.
The Practical Calculus
Here’s the honest breakdown:
Cognitive load reduced:
- Research and information synthesis loops
- Notification triage and async context reloads
- Repetitive task execution (reporting, file organization, routine checks)
- Micro-decisions on low-stakes formatting and scheduling
Cognitive load added (front-loaded):
- Initial setup and tool integration
- Trust calibration across task types
- Prompt design for complex workflows
After a few weeks of use, the net direction is clearly positive for most developers doing information-heavy work. If you’re writing pure code in a focused environment, the marginal gain is smaller. If you’re coordinating across tools, managing communication alongside technical work, or doing any kind of research-heavy development, the reduction in working memory pressure is real.
Verdict
OpenClaw is one of the few AI tools I’ve seen that engages seriously with the task-delegation model rather than the query-response model. That distinction matters for cognitive load. Queries keep the burden on you. Task delegation shifts it.
It’s not magic. The setup investment is real, and you need to stay in the loop on anything consequential. But for developers whose days involve constant context-switching between building, researching, communicating, and triaging — which is most developers — it delivers measurable relief on the working memory front.
If you want to see how other developers are configuring it for their workflows, the OpenClaw community on Skool is worth browsing. A lot of the practical setup knowledge lives there, not in the official docs.
Marcus Reid holds a PhD in cognitive psychology and focuses on how digital tool design affects attention, decision fatigue, and flow states in knowledge workers.
The Compound Interest of AI Context: Why Your Knowledge Layer Will Be Your Most Valuable Business Asset
There’s an idea I can’t stop thinking about.
Every time you explain your business to an AI — your clients, your stack, your project history, your preferences — that context evaporates when the session ends. You explain it again tomorrow. And again next week. And the week after that.
Now imagine a different world. One where every session deposits context into a persistent layer. Where future sessions withdraw from that layer automatically. Where the balance only grows.
That’s compound interest applied to AI context. And I think it’s going to be the most underrated competitive advantage of the next decade.
The Gap Nobody’s Talking About
ChatGPT has “memory.” It remembers you prefer dark mode and that you’re a Python developer. That’s nice. That’s a preference store.
What it doesn’t do is build a knowledge graph of your entire business. It doesn’t know that Client A’s project was delayed because Vendor B missed a deadline, and that’s relevant because you’re about to pitch Client C on a similar timeline.
Notion and Obsidian organize what you already know. They’re filing cabinets. Great ones, but filing cabinets.
CLAUDE.md files are the right idea — persistent context for a single repo. But if you work across 10, 20, 50 repos? If you’re running a business, not just writing code?
There’s a gap. A big one.
What I Built
I built BizBrain OS, a Claude Code plugin that creates a persistent knowledge brain on your machine. It’s open source (AGPL v3), free, and you can install it in about 30 seconds:
claude plugin add TechIntegrationLabs/bizbrain-os-plugin
Then start Claude Code and run:
/brain setup
It asks your name, business, and role. Then it scans your machine — repos, tools, services — and builds a structured brain:
~/bizbrain-os/
├── launchpad/ # Session start context (~120 lines)
├── workspaces/ # Code repos (ultra-lean context)
└── brain/ # Full business intelligence
├── Knowledge/ # Decisions, references, reports
├── Entities/ # Clients, partners, vendors, people
├── Projects/ # Project records and action items
├── Operations/ # Credentials, todos, configurations
└── _intake-dump/ # Drop files here, they get routed
From that point on, every Claude Code session starts pre-loaded with your business context. Not a summary — the actual structured knowledge.
How Compounding Actually Works Here
Day 1. Claude knows your file structure, your repos, your installed tools. Basic stuff.
Week 2. You’ve had a few client calls. The Entity Watchdog — a background agent that monitors your conversations — has automatically captured that Client A’s contact changed roles, that you quoted Vendor B a specific price, that Partner C wants a follow-up next Tuesday.
Month 1. Claude knows the full relationship graph. When you start a session about Project X, it already knows which client it’s for, what decisions were made, what the blockers are, and who’s responsible.
Month 6. You’ve got institutional memory that would take a new employee months to absorb. Every decision recorded. Every client preference captured. Every project’s full history accessible.
Year 1. The brain has context that no single person in your organization could hold. And it cost you nothing to maintain, because it captured it as a side effect of doing your actual work.
That’s compound interest. Small deposits, automatic growth, exponential value.
The Architecture (For the Curious)
The plugin ships 23 skills, 16 slash commands, and 5 background agents:
- Brain Orchestrator — coordinates all agents through an event queue with conflict detection
- Entity Watchdog — monitors conversations for entity mentions, auto-updates records
- Brain Learner — captures decisions, patterns, and preferences across sessions
- Brain Gateway — full brain access from any repo or directory
- Visual Presenter — pushes diagrams, dashboards, and mockups to a browser companion
The three-zone architecture keeps context costs minimal. Your launchpad injects ~120 lines. Workspaces add ~80. The full brain loads ~300 lines when you need deep context. Claude Code’s context window isn’t wasted on things you don’t need right now.
Why Free, Why Open Source
Because I think every business will need a persistent AI knowledge layer in 2-3 years. Like CRM was optional in 2005 and mandatory by 2015. Like version control was optional in 2000 and mandatory by 2010.
The businesses that start building their brain now will have a compounding advantage that latecomers literally cannot catch up to. You can’t fast-forward a year of accumulated institutional knowledge.
I’d rather this tool exists and people use it than charge $20/month and watch the concept die from friction.
Also — and I’ll be honest about this — the brain is just the beginning. There’s a bigger second phase. But I’m keeping that close until I find the right partners.
Try It
# Install
claude plugin add TechIntegrationLabs/bizbrain-os-plugin
# Setup (takes ~5 minutes)
/brain setup
# See what it built
/dashboard
Website: bizbrainos.com
GitHub: TechIntegrationLabs/bizbrain-os-plugin
Discord: discord.gg/ph9D5gSgW3
I’m Will Welsh — solo dev, Tech Integration Labs. Happy to answer questions — [email protected]
The compound interest of AI context is real. The only question is when you start depositing.
Vivo, Turkish Cargo ile iş birliği gerçekleştirdi
Çinli akıllı telefon üreticisi Vivo, bugün yapılan resmi açıklamaya göre Turkish Cargo ile iş birliği gerçekleştirdi. “Türk Hava Yolları’nın kargo markası Turkish Cargo, global teknoloji liderlerinden Vivo’nun hassas elektronik ürünlerinin dünya genelindeki sevkiyat süreçlerini kapsayan stratejik bir iş birliğine imza attı.” diyen Vivo Türkiye, gelişme hakkında ek olarak şunları aktardı: “Çin’in en çok satan yerel teknoloji markalarından Vivo ile Türk Hava Yolları’nın hızlı büyüyen hava kargo markası Turkish Cargo arasında teknoloji ürünlerinin küresel çapta güvenli ve hızlı bir şekilde taşınması amacıyla iş birliğine gidildi. İş birliği kapsamında, Turkish Cargo’nun hassas gönderilere özel sunduğu TK Vulnerable hizmeti kullanılacak. Bu sayede Vivo, hassas elektronik ürünlerini dünya genelindeki müşterilerine daha hızlı ulaştırırken hasar riskini de minimuma indirecek ve uluslararası pazarlara daha etkin şekilde erişim sağlayacak. Elektronik ürünlere yönelik küresel talep hızla artarken, güçlü ve güvenilir lojistik çözümleri artık her zamankinden daha kritik bir rol oynuyor. Hassas ve yüksek değerli ürünlerin taşınması özel bir […]
Vivo, Turkish Cargo ile iş birliği gerçekleştirdi yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.
Amazon Bedrock Beginner Guide: A Complete Deep Dive into AWS Generative AI
👋 Hey there! This is Pratik, a Senior DevOps Consultant with a strong background in automating and optimizing cloud infrastructure, particularly on AWS. Over the years, I have designed and implemented scalable solutions for enterprises, focusing on infrastructure as code, CI/CD pipelines, cloud security, and resilience. My expertise lies in translating complex cloud requirements into efficient, reliable, and cost-effective architectures.
In this guide, we’ll take a beginner-friendly deep dive into Amazon Bedrock, explaining how it works, its features, costs, and use cases.
🔍 How a Simple Problem Introduced Me to Amazon Bedrock
A while ago, I was trying to find a solution for simple problem:
How to make systems understand files and data intelligently, not just match keywords.
When I started exploring AI solutions, things quickly became complicated.
Hosting models, managing infrastructure, and scaling felt like too much work for what I wanted to create.
That’s when I discovered Amazon Bedrock.
What stood out wasn’t just the ability to generate text, it was the flexibility.
It could handle chat, text, images, and more, all through simple APIs. I didn’t have to worry about infrastructure, thanks to Amazon Web Services.
That shift from managing systems to building solutions is what this article is all about.
🧠 What is Amazon Bedrock?
Amazon Bedrock is a fully managed AWS service that allows developers to build and scale generative AI applications using foundation models (FMs).
What are Foundation Models?
Foundation Models are large AI models trained on extensive datasets that can:
- Understand text
- Analyze images
- Generate content
- Answer questions
Why Use Bedrock?
- No need to manage infrastructure
- Built for security and scalability
- Cost-effective with a pay-as-you-go model
- Seamlessly integrates with the AWS ecosystem
Popular Models Available
- Anthropic Claude
- Meta Llama
- Amazon Titan
🧠 What Can You Do with Amazon Bedrock?
The range of AI capabilities that Amazon Bedrock provides through a single API layer is one of its main advantages.
Let’s divide it up into the main categories of capabilities:
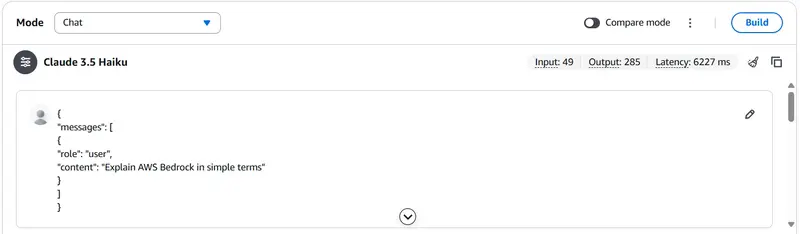
💬 1. Chat (Conversational AI)
Chat is the most common way to interact with Amazon Bedrock.
You simply type a question or instruction, and the model responds just like a conversation.
It’s perfect for building chatbots, assistants, or automating responses.
Bedrock supports building intelligent chat systems using models like:
• Claude 3.5 Haiku
• Claude 3 Sonnet
– What you can build:
• Customer support bots
• Internal enterprise assistants
• DevOps copilots
– Example Prompt:
{
"messages": [
{
"role": "user",
"content": "Explain AWS Bedrock in simple terms"
}
]
}
👉 Best practice:
• Use structured conversation format (messages) instead of plain prompt
• Maintain chat history for context
✍️ 2. Text Generation
Text generation is used when you want the AI to create content.
This can include summaries, articles, code, or structured outputs like JSON.
It’s ideal for automation tasks, documentation, and content creation.
– Supported Models:
• Amazon Titan Text
• Claude 4 Sonnet
– What you can build:
• Blog/article generation
• Code generation
• Email drafting
• Summarization
– Example Use Case:
{
"prompt": "Write a professional email for leave request",
"max_tokens": 150,
"temperature": 0.7
}
🖼️ 3. Image Generation
With image input, you can send pictures to the model and ask questions about them.
The AI can analyze visuals, detect objects, or extract information from images.
This is useful for use cases like document verification, image matching, and visual inspection.
Bedrock also supports text-to-image generation.
– Supported Model:
• Amazon Titan Image Generator
– What you can build:
• AI-generated designs
• Marketing creatives
• Thumbnails and banners
– Example Prompt:
{
"textToImageParams": {
"text": "A futuristic city with flying cars at sunset"
}
}
⚙️ Understanding Bedrock API Parameters
When you work with Amazon Bedrock, you basically send a request to the AI saying:
“Here’s what I want and here’s how I want you to respond.”
A typical request looks like this:
{
"anthropic_version": "bedrock-2023-05-31",
"max_tokens": 1000,
"temperature": 0,
"top_p": 1,
"messages": [...]
}
Let’s break this down 👇
1. anthropic_version – [ Which rulebook to follow ]
• Defines the API schema version
• It’s required for Anthropic models (like Claude)
• Always keep this fixed unless AWS updates it
2. max_tokens – [ How long should the answer be? ]
This controls the length of the response.
-
Higher value → longer answer
-
Lower value → short and precise
Quick tips:
-
Use 200–500 → for JSON / short answers
-
Use 800+ → when you want detailed explanations
3. temperature – [ How creative should the AI be? ]
This controls how predictable or creative the response is.
-
0 → very strict, same answer every time
-
0.5 → balanced
-
1 → more creative and random
4. top_p – [ How many options should the AI consider? ]
This one sounds complex, but it’s actually simple.
• Controls token probability sampling
• Limits how “wide” the model thinks
Value Behavior
1 Consider all possibilities
<1 More focused output
Best practice:
• Use top_p = 1 with temperature = 0
5. messages – [ What do you actually want? ]
This is the most important part.
This is where you:
-
Ask your question
-
Give instructions
-
Provide input (text, image, etc.)
"messages": [
{
"role": "user",
"content": [...]
}
]
📌 Types of input you can send
Inside messages, you can include:
-
text → normal instructions
-
image → for image understanding
-
document → structured files (limited use)
💰 Amazon Bedrock Pricing
When you first look at Bedrock pricing, it can feel confusing but the idea is actually very simple:
You only pay for what you use (pay-as-you-go)
No upfront cost, no subscription required.
1. The Most Important Concept: Tokens
Bedrock pricing is mainly based on tokens.
- What is a token?
A token is a piece of text (word or part of a word)
Example: “Hello world” ≈ 2–3 tokens
- You are charged for:
Input tokens (what you send)
Output tokens (what AI generates)
2. Pricing Depends on the Model
Different models = different pricing
For example:
- Anthropic Claude
~$6 per 1M input tokens
~$30 per 1M output tokens
- Smaller / cheaper models
Can be 10x cheaper
Example: some models start around $0.07 per 1M tokens
3. Image Pricing
For image-based tasks:
You are charged per image processed
Example: ~$0.03 to $0.60 per image depending on operation
For detailed pricing information, click here 👉 AWS Bedrock Pricing
✨Final Thoughts
Amazon Bedrock makes it extremely simple to get started with generative AI without worrying about the infrastructure or complexity.
With multiple models available, flexible pricing options, and support for text, chat, and image-based applications, it provides the ability to create highly scalable applications.
The key here is to understand how to effectively tune parameters, select the most appropriate model, and manage costs effectively for your application.
Start simple, experiment, and scale as needed and that’s where Bedrock shines.
🔜 What’s Next
In our next article, we’ll work on a hands-on example of a real-world use case involving Amazon Bedrock and AWS Lambda.
The example will be a solution to verify if a reference image exists within a target file, such as a document or PDF.
💬 Let’s Keep the Conversation Going
Have thoughts, questions, or any experience with Event driven architectures to share? I would love to hear from you! Feel free to leave a comment or connect with me on LinkedIn. Let’s learn and grow together as a community of builders.
Keep exploring, keep automating and see you in the next one!