I train self-supervised models on chess game data. My Python pipeline using python-chess took 25 minutes to parse and tokenize 1M games from Lichess PGN dumps. I rewrote it in Rust. It now takes 15 seconds.
This post covers the architecture, why Rust was the right choice, and what I learned.
The problem
Training a chess move predictor requires converting PGN (Portable Game Notation) files into tokenized sequences — arrays of integer IDs that a neural network can consume. A typical Lichess monthly dump has 5M+ games in a zstd-compressed PGN file.
My Python pipeline had three bottlenecks:
-
PGN parsing — python-chess parses SAN notation, validates moves on a board, handles edge cases. Correct, but slow. ~15 minutes for 1M games.
-
Tokenization — converting validated UCI moves to token IDs, tracking piece types and turns. ~10 minutes.
-
Memory — all games loaded into a Python list of dicts. 1M games = ~4GB RAM.
The Rust rewrite
The tool is called ailed-soulsteal (named after a Castlevania ability — the project has a theme).
Architecture
Three layers, each a clean boundary:
Input Layer → Filter Layer → Output Layer
(PGN parser)   (ELO, result)  (.somabin binary)
Everything streams — games are parsed, filtered, tokenized, and written one at a time. Memory usage stays constant regardless of input size.
PGN parsing
PGN is a messy format. Tags, comments, variations, NAGs, move numbers, results — all interleaved. I wrote a simple streaming parser that yields one RawGame at a time:
struct PgnIterator<R> {
    reader: R,
    line_buf: String,
}

impl<R: BufRead> Iterator for PgnIterator<R> {
    type Item = RawGame;
    fn next(&mut self) -> Option<RawGame> {
        // Read tags until blank line, then movetext until next blank line
        // Strip comments, NAGs, variations, move numbers
        // Return (tags, moves, result)
    }
}
No allocations per game beyond the reused line buffer. The RawGame struct holds tags as a HashMap<String, String> and moves as Vec<String>.
Move validation with shakmaty
shakmaty is a pure Rust chess library. It handles SAN parsing, move validation, and piece type lookup — the same things python-chess does, but at native speed.
let san: shakmaty::san::San = san_str.parse().ok()?;
let m = san.to_move(&pos).ok()?;
let uci = uci_string(&m);
let category = role_to_category(m.role());
pos = pos.play(&m).ok()?;
This is where most of the speedup comes from. shakmaty’s play() is essentially a few bitboard operations — no Python overhead, no GC pressure.
Binary output format
Instead of writing JSON or CSV, I designed a binary format (.somabin) optimized for ML training:
Header (64 bytes): magic, version, vocab_size, num_games, ...
Index Table:       byte offset for each game (enables random access)
Data Section:      per game: [seq_len, token_ids, turn_ids, category_ids, outcome]
The index table is the key insight. A PyTorch Dataset.__getitem__(i) can seek directly to game i via mmap without scanning the file. Loading 50K games takes 20ms. Random access runs at 500K games/sec.
The Python reader is 30 lines:
class SomabinDataset:
    def __init__(self, path):
        self._file = open(path, "rb")
        self._mm = mmap.mmap(self._file.fileno(), 0, access=mmap.ACCESS_READ)
        self.header = read_header(self._mm)
        self._index = read_index(self._mm, self.header)

    def __getitem__(self, idx):
        offset = int(self._index[idx])
        return read_game(self._mm, offset)
Zstd decompression
Lichess distributes PGN files as .pgn.zst. The zstd crate handles decompression transparently:
if path.extension() == Some("zst") {
    let decoder = zstd::Decoder::new(file)?;
    Ok(Box::new(BufReader::with_capacity(1024 * 1024, decoder)))
} else {
    Ok(Box::new(BufReader::with_capacity(1024 * 1024, file)))
}
Auto-detected from the file extension. No separate decompression step needed.
Filtering
Games are filtered by metadata before tokenization — no wasted work:
pub trait GameFilter {
    fn accept(&self, game: &RawGame) -> bool;
}

// Chain of filters — all must pass
filters.add(Box::new(EloFilter::new(1000, 1800)));
filters.add(Box::new(MovesFilter::new(Some(4), None)));
filters.add(Box::new(ResultFilter::Decisive));
Filters operate on PGN tags (strings), not board positions. Checking WhiteElo >= "1000" is effectively free compared to move validation.
Benchmarks
Processing Lichess monthly dumps (zstd compressed) on an M1 MacBook:
| Month |
Input |
Games (1000-1800) |
Time |
Rate |
| 2016-01 |
831 MB .zst |
2,060,197 |
45s |
46K/s |
| 2016-02 |
866 MB .zst |
2,071,332 |
46s |
45K/s |
| 2016-03 |
994 MB .zst |
2,399,234 |
54s |
45K/s |
| 2016-04 |
1.0 GB .zst |
2,438,621 |
55s |
44K/s |
| 2016-07 |
1.0 GB .zst |
2,598,733 |
59s |
44K/s |
11.6M games in 4.3 minutes. The equivalent Python pipeline would take roughly 5 hours.
What I learned
Streaming wins. The biggest architectural decision was making everything an iterator. Games flow through parse → filter → tokenize → write without buffering. Memory usage is constant at ~10MB regardless of input size.
Binary formats beat JSON for ML. My first version wrote JSONL. A 1M-game JSONL file was 2GB and took 30 seconds to load in Python. The .somabin binary for the same data is 550MB and loads in 20ms via mmap.
shakmaty is excellent. Chess move validation is the bottleneck in any PGN pipeline. shakmaty’s bitboard implementation made this a non-issue. The crate is well-documented and the API maps cleanly to what you need for tokenization.
Rust’s type system caught real bugs. The GameParser and GameTokenizer traits enforce separation between parsing (text → structured data) and tokenization (structured data → integers). When I mixed them up during development, the compiler told me immediately.
Try it
cargo install ailed-soulsteal

# Generate vocabulary
soulsteal vocab --generate -o vocab.json

# Tokenize a Lichess dump
soulsteal tokenize lichess_2016-02.pgn.zst
  -o train.somabin
  --vocab vocab.json
  --elo 1000:1800

# Inspect
soulsteal info train.somabin
soulsteal stats train.somabin
Pre-tokenized datasets are available on Hugging Face.
The tool is designed to support any turn-based game — Go (SGF), Shogi (KIF), etc. Chess is the v1 implementation, but the GameParser and GameTokenizer traits are game-agnostic.
Source: github.com/Ailed-AI/ailed-soulsteal
crates.io: ailed-soulsteal
License: MIT


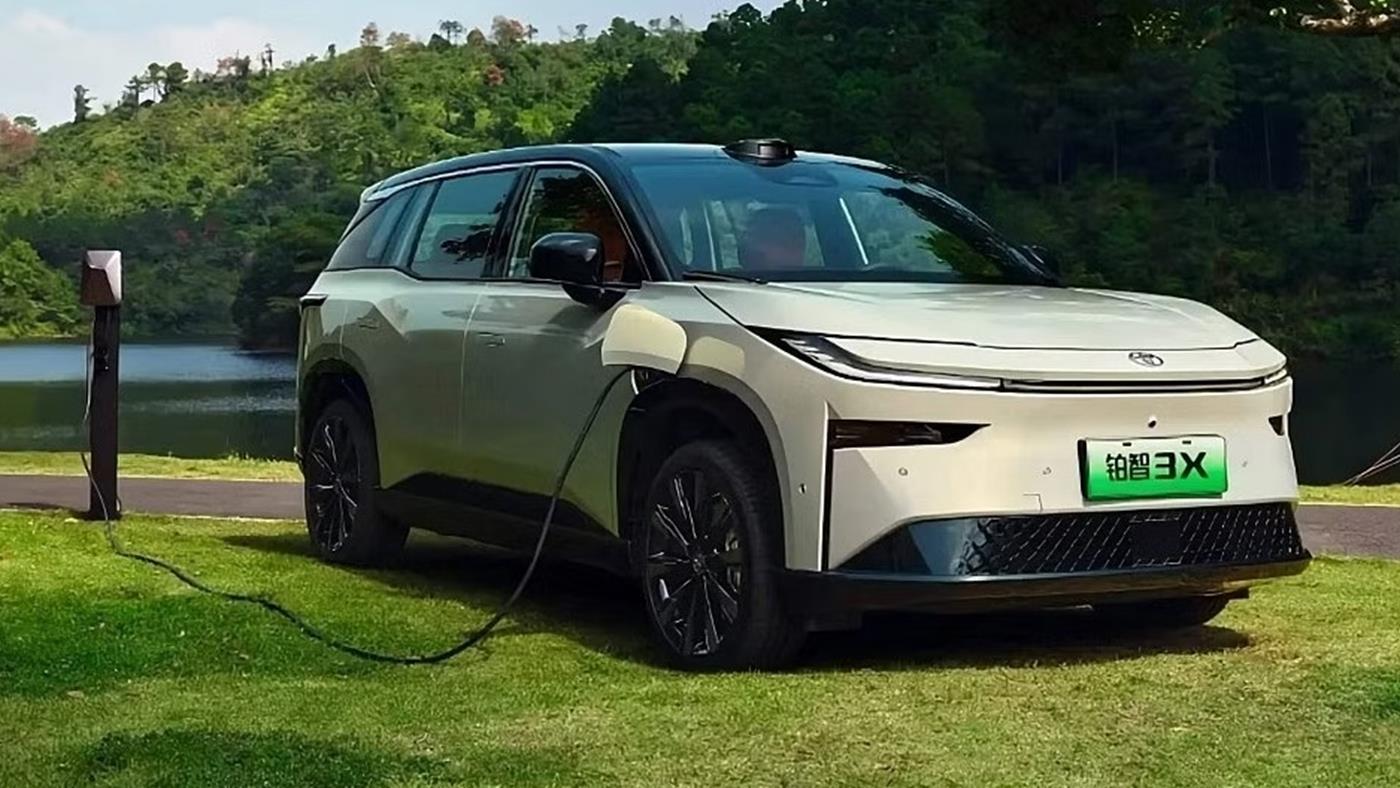
 Toyota, Çin’de elektrikli bZ3 ve bZ3X modellerinin fiyatlarında indirime gitti. Söz konusu modeller, bazı pazarlardaki 15 yıllık ikinci el Corolla modellerinden bile daha ucuza satılıyor.
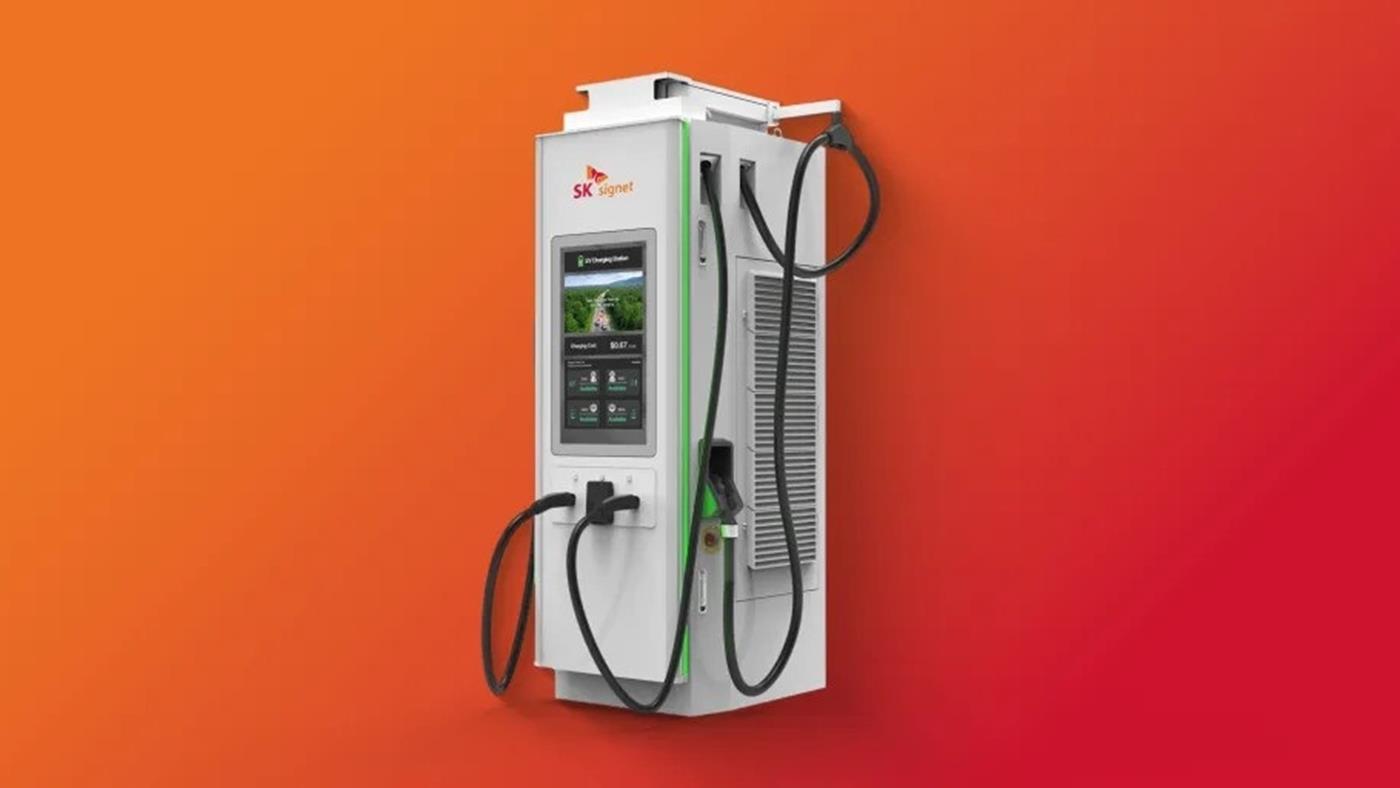
 Güney Koreli SK Signet, elektrikli araçlara yönelik 400 kW gücünde ultra hızlı şarj cihazını tanıttı. Yeni sistem, önceki çözümlere kıyasla çok daha az yer kaplamasıyla ön plana çıkıyor.
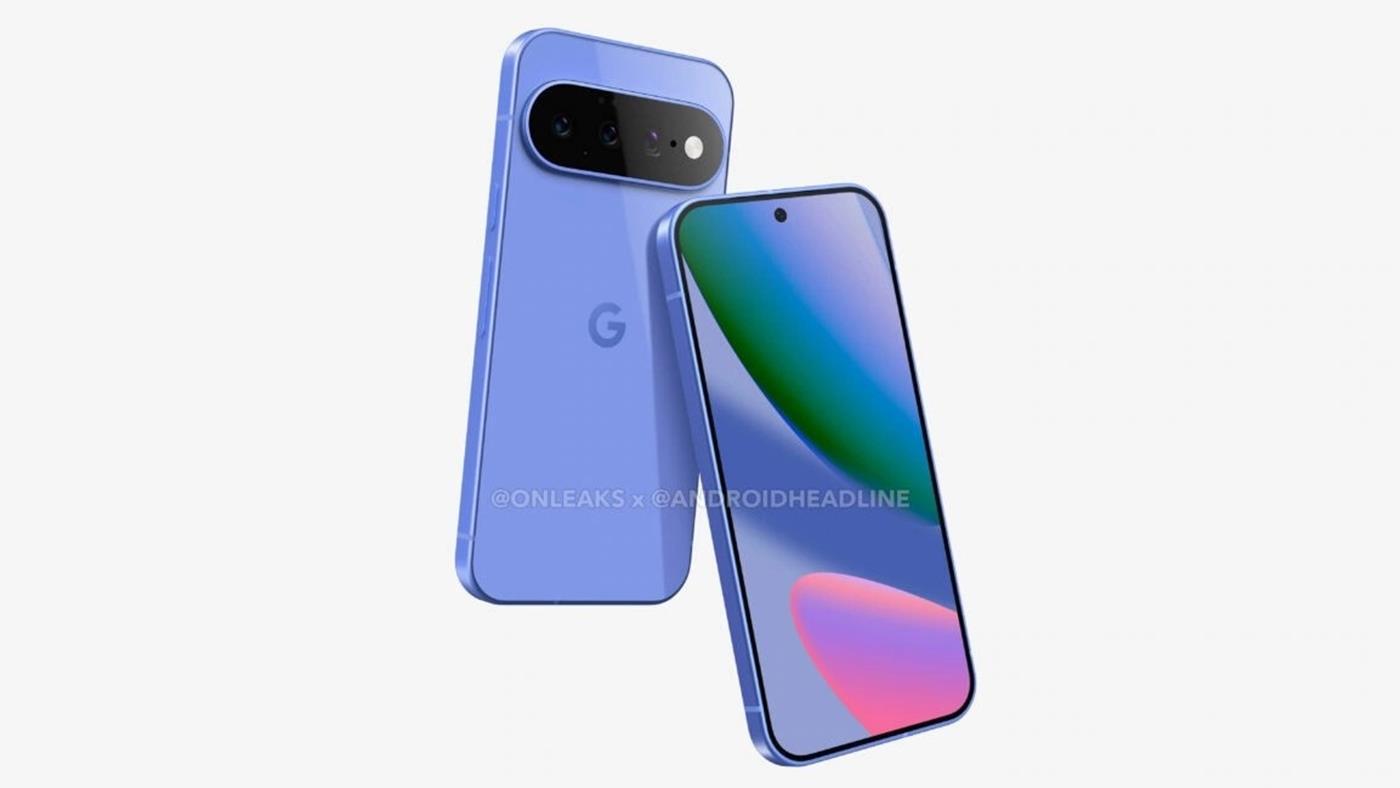
 Yaklaşmakta olan Pixel 11 serisinin standart modelinin CAD tabanlı görselleri ortaya çıktı. Selefiyle aynı tasarım dilini koruyan cihaz, bazı küçük dokunuşlara sahip olacak.
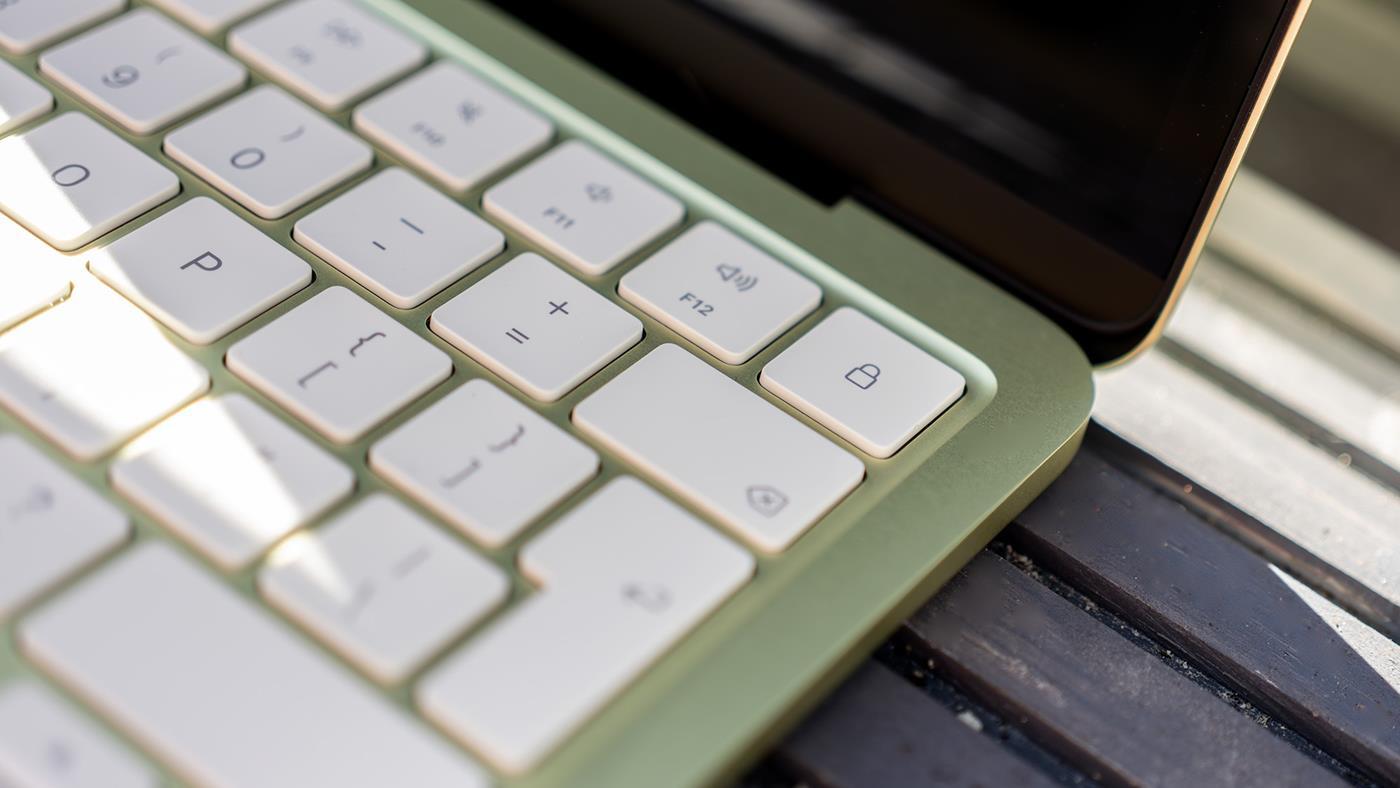
 Apple’ın yeni piyasaya sürdüğü MacBook Neo rekor hızda satıyor. Tedarik zinciri kaynaklarına göre teknoloji devi, üretim siparişlerini hedeflediği 10 milyon adede çıkardı.