What you will learn
This guide walks through every step of integrating CodeRabbit with GitHub – from installing the GitHub App to configuring advanced review behavior with .coderabbit.yaml. By the end, you will have CodeRabbit automatically reviewing every pull request in your selected repositories, posting inline comments on code issues, and learning from your team’s feedback to improve over time.
Here is what this guide covers:
- Installing the CodeRabbit GitHub App and granting the correct permissions
- Selecting which repositories CodeRabbit should review
- Understanding the permissions CodeRabbit requests and why each one is needed
- Triggering your first automated PR review
- Customizing review behavior with
.coderabbit.yaml including review profiles, path filters, and natural language instructions
- Advanced configuration for auto-review settings, monorepos, and integrations
- Troubleshooting common issues with the GitHub integration
- Alternative tools if CodeRabbit does not fit your workflow
If you are looking for a broader overview of CodeRabbit’s features and pricing before setting up the GitHub integration, start with our CodeRabbit review or CodeRabbit pricing breakdown.
Prerequisites
Before setting up the CodeRabbit GitHub integration, confirm you have the following:
- A GitHub account (personal or organization) with at least one repository
- Admin or owner permissions on the repositories where you want to install CodeRabbit – this is required to authorize GitHub Apps
- At least one open pull request or the ability to create one for testing the integration (optional but recommended)
- A modern web browser – the entire setup happens through the browser with no local tooling required
No CI/CD pipeline, Docker installation, API keys, or command-line tools are needed. CodeRabbit runs on its own infrastructure as a native GitHub App, which means it does not consume your GitHub Actions minutes or require workflow YAML files.

Step 1 – Install the CodeRabbit GitHub App
The GitHub App installation is the core of the CodeRabbit GitHub integration. This is what connects CodeRabbit’s AI review engine to your repositories and pull requests. Unlike tools that run as GitHub Actions, CodeRabbit operates as a standalone GitHub App – similar to how Slack, Jira, or Vercel integrate with GitHub.
Here is how to install it:
- Open coderabbit.ai in your browser and click the “Get Started Free” button
- Select GitHub as your Git platform
- Authorize CodeRabbit using the standard GitHub OAuth screen – this grants CodeRabbit access to your identity so it can create your account
- After landing on the CodeRabbit dashboard, click “Add Repositories” or “Install GitHub App”
- GitHub will redirect you to the App installation page
The OAuth authorization in step 3 and the App installation in step 4 are two separate operations. The OAuth grants CodeRabbit access to your identity (who you are). The App installation grants it access to your repositories and pull requests (what it can read and comment on). Both are required for the integration to work.
If you are installing CodeRabbit for an organization rather than a personal account, you may need an organization owner to approve the installation. If you see a “Request” button instead of “Install,” the request will be sent to your organization owner for approval. Ask them to check the GitHub organization settings under Third-party access to approve the CodeRabbit app.
For a deeper walkthrough of the sign-up and account creation process, see our CodeRabbit setup guide.
Step 2 – Select repositories
During installation, GitHub asks you to choose which repositories CodeRabbit should have access to. You have two options:
-
All repositories – CodeRabbit gets access to every repository in the organization or account, including any repositories created in the future. This is convenient for teams that want full coverage without manual configuration, but it means CodeRabbit will start reviewing PRs on every repository immediately.
-
Only select repositories – You choose specific repositories from a searchable list. This is the recommended approach for teams that want to start with a pilot before expanding. You can always add more repositories later from your GitHub settings or the CodeRabbit dashboard.
For most teams, the best approach is to start with two or three active repositories that have regular pull request activity. This lets you evaluate the review quality, tune your .coderabbit.yaml configuration, and get team feedback before rolling CodeRabbit out more broadly.
After selecting your repositories, click “Install” to complete the installation. The CodeRabbit App now appears in your GitHub organization settings under Settings, then GitHub Apps (or in your personal account under Settings, then Applications, then Installed GitHub Apps).
Managing repositories after installation
You can change which repositories CodeRabbit has access to at any time:
-
From GitHub: Go to your organization or account settings, navigate to GitHub Apps, find CodeRabbit, and click “Configure.” You can add or remove repositories from this screen.
-
From CodeRabbit: Log in to app.coderabbit.ai and navigate to the “Repositories” tab. Toggle individual repositories on or off to control which ones CodeRabbit actively reviews.
The GitHub-level setting controls access (can CodeRabbit see the repository), while the CodeRabbit dashboard setting controls activation (should CodeRabbit review PRs on this repository). A repository must have both access and activation enabled for reviews to work.
Step 3 – Configure permissions
The CodeRabbit GitHub App requests a specific set of permissions during installation. Understanding what each permission does helps you evaluate whether the integration meets your security and compliance requirements.
Here are the permissions CodeRabbit requests and why each one is necessary:
| Permission |
Access level |
Purpose |
| Repository contents |
Read |
Allows CodeRabbit to read the code diff and surrounding context in your repository to perform meaningful reviews |
| Repository metadata |
Read |
Lets CodeRabbit access basic repository information like the default branch name and repository settings |
| Pull requests |
Read and Write |
Read access lets CodeRabbit see PR details including title, description, and changed files. Write access lets it post review comments and review summaries |
| Checks |
Write |
Allows CodeRabbit to create check runs that appear in the PR status section showing review progress |
| Webhooks |
Receive |
CodeRabbit subscribes to pull request events (opened, updated, reopened) so it knows when to start a review |
CodeRabbit does not request write access to your repository contents. It cannot push commits, create branches, modify files, or merge pull requests. The integration is strictly read-only for your code and write-only for review comments.
For organizations with strict security policies, CodeRabbit also offers SOC 2 Type II compliance on its Enterprise plan and provides data processing agreements. Code is processed in memory during review and is not stored permanently on CodeRabbit’s servers.
Step 4 – First PR review
Once the GitHub App is installed and repositories are selected, open a pull request to trigger your first CodeRabbit review. This is where you verify that the integration is working correctly.
- Create a new branch in one of your enabled repositories
- Make a meaningful code change – adding a new function, refactoring a method, or fixing a bug works well for testing
- Push the branch and open a pull request targeting your default branch
- Wait 1 to 5 minutes for CodeRabbit to complete its review
When the review finishes, CodeRabbit posts several elements on your pull request:
A walkthrough summary appears as the first comment on the PR. It describes what changed across all files, organized by file and purpose. This summary helps reviewers quickly understand the scope of the PR without reading every line of the diff.
Inline review comments appear directly on specific lines in the diff, just like comments from a human reviewer. Each comment describes the issue, explains why it matters, and often includes a suggested fix. On the Pro plan, these suggestions appear as GitHub suggested changes that you can commit with one click.
A review status indicator shows whether the review is complete and how many comments were generated. This appears in the PR’s checks section.
If CodeRabbit does not post any comments within 5 minutes, jump to the troubleshooting section below. Common causes include the PR being a draft, the repository not being activated in the CodeRabbit dashboard, or permission issues with the GitHub App installation.
Interacting with CodeRabbit comments
CodeRabbit comments are not one-way notifications – they are the start of a conversation. You can reply to any comment to ask for clarification, request an alternative approach, or explain why the suggestion does not apply to your codebase:
-
Ask why: “Can you explain why this is a security risk? We validate this input in the middleware layer.”
-
Request alternatives: “This approach would break our caching layer. What is another way to handle this?”
-
Trigger actions: Comment
@coderabbitai review on the PR to trigger a full re-review, or @coderabbitai resolve to dismiss a specific comment
Every interaction teaches CodeRabbit about your preferences. When you dismiss a comment with an explanation, CodeRabbit stores that as a learning and adjusts future reviews accordingly. Teams that actively reply during the first two weeks of adoption see significantly fewer false positives by the end of the first month.
Step 5 – Customize with .coderabbit.yaml
The .coderabbit.yaml file is where you tailor CodeRabbit’s GitHub integration to match your team’s workflow. While CodeRabbit works out of the box with sensible defaults, the configuration file gives you fine-grained control over what gets reviewed, how strictly, and with what focus areas.
Create a file named .coderabbit.yaml in the root of your repository and commit it to your default branch (usually main):
# .coderabbit.yaml
language: en-US

reviews:
  profile: chill
  request_changes_workflow: false
  high_level_summary: true
  poem: false
  review_status: true
  collapse_walkthrough: false
  sequence_diagrams: true
  changed_files_summary: true
  path_filters:
    - "!**/*.lock"
    - "!**/*.generated.*"
    - "!**/dist/**"
    - "!**/node_modules/**"
    - "!**/coverage/**"
    - "!**/__snapshots__/**"

chat:
  auto_reply: true

knowledge_base:
  opt_out: false
  learnings:
    scope: auto
CodeRabbit reads this configuration on every PR and applies your settings immediately – no restart, reinstallation, or dashboard change is required. Each repository can have its own .coderabbit.yaml with different settings, which is especially useful for organizations that have repositories with different languages, frameworks, or review standards.
Review profiles explained
The profile setting controls how verbose and strict CodeRabbit’s reviews are:
-
chill – Focuses only on significant issues like bugs, security vulnerabilities, and logic errors. Produces fewer comments and is the best starting point for teams new to AI code review. Most teams find this strikes the right balance between catching real issues and avoiding noise.
-
assertive – Reviews more comprehensively, covering style, naming, documentation, performance, and best practices in addition to bugs and security. Produces more comments and is best for teams that want thorough feedback on every PR.
-
followup – Similar to assertive but also checks whether previous review comments were addressed in subsequent commits. This is the strictest mode and is best for teams that want to ensure review feedback is acted on.
Start with chill and switch to assertive after your team is comfortable with the tool – typically after two to four weeks.
Path filters for excluding files
The path_filters section controls which files CodeRabbit analyzes. Use negation patterns (prefixed with !) to exclude files that do not benefit from AI review:
reviews:
  path_filters:
    - "!**/*.lock"           # Package lock files
    - "!**/*.min.js"         # Minified JavaScript
    - "!**/dist/**"          # Build output
    - "!**/vendor/**"        # Vendored dependencies
    - "!**/*.generated.*"    # Auto-generated code
    - "!**/migrations/**"    # Database migrations (optional)
    - "!**/*.snap"           # Test snapshots
Excluding these files reduces noise and speeds up reviews because CodeRabbit does not spend time analyzing files where its feedback would not be actionable.
Advanced configuration
Once you have the basic .coderabbit.yaml working, these advanced settings let you get more value from the CodeRabbit GitHub integration.
Review instructions for specific paths
The path_instructions feature is one of CodeRabbit’s most powerful capabilities. It lets you provide natural language instructions that CodeRabbit follows when reviewing files matching specific patterns:
reviews:
  path_instructions:
    - path: "src/api/**"
      instructions: |
        Review all API endpoints for:
        - Input validation on all request parameters
        - Proper error handling with appropriate HTTP status codes
        - Authentication and authorization checks
        - Rate limiting considerations
    - path: "src/db/**"
      instructions: |
        Review database code for:
        - SQL injection prevention using parameterized queries
        - Proper connection handling and cleanup
        - Transaction usage for multi-step writes
    - path: "**/*.test.*"
      instructions: |
        For test files, focus on:
        - Edge case coverage
        - Proper assertion usage
        - Mock cleanup and test isolation
This means your API code gets reviewed for authentication gaps, your database code gets checked for SQL injection, and your tests get evaluated for missing edge cases – all automatically based on the file path.
Global review instructions
Add a top-level instructions field to guide CodeRabbit’s behavior across all files in the repository:
reviews:
  profile: assertive
  instructions: |
    This is a TypeScript backend service using Express and PostgreSQL.
    Our conventions:
    - All async functions must use try/catch with proper error logging
    - Database queries must use parameterized statements
    - API responses follow the format: { data, error, meta }
    - Do not comment on import ordering (handled by ESLint)
    - Do not comment on line length (handled by Prettier)
    - Focus on bugs, security issues, and logic errors
Global instructions are especially useful for preventing false positives. If your linter already handles import ordering and your formatter handles line length, telling CodeRabbit to skip those categories eliminates a common source of noise.
Auto-review settings
Control whether CodeRabbit reviews PRs automatically or only when requested:
reviews:
  auto_review:
    enabled: true
    drafts: false
    base_branches:
      - main
      - develop
Setting drafts: false means CodeRabbit skips draft PRs, which is the default behavior. The base_branches setting limits auto-review to PRs targeting specific branches – useful if you only want CodeRabbit to review PRs going into your main branches and not PRs between feature branches.
Path filters for monorepos
If your repository is a monorepo with multiple services, combine path instructions with path filters to apply different review criteria to each service:
reviews:
  path_instructions:
    - path: "services/auth/**"
      instructions: |
        Authentication service - focus on token validation,
        password hashing (bcrypt only), and OWASP compliance
    - path: "services/payments/**"
      instructions: |
        Payment service - focus on PCI DSS patterns,
        idempotency of operations, and decimal precision
    - path: "packages/shared/**"
      instructions: |
        Shared library - focus on backward compatibility,
        type safety, and performance implications
Each service gets reviewed with context-specific criteria, which dramatically improves review quality compared to generic instructions applied uniformly across a monorepo.
Integrating with issue trackers
CodeRabbit can read linked Jira or Linear issues to understand the context behind a PR. When it knows the ticket description and acceptance criteria, it can validate whether the code changes actually address the requirements:
integrations:
  jira:
    enabled: true
    project_keys:
      - "BACKEND"
      - "FRONTEND"
  linear:
    enabled: true
Troubleshooting the CodeRabbit GitHub integration
If the integration is not working as expected, work through these issues in order.
CodeRabbit is not reviewing PRs
-
Check the GitHub App installation. Go to your GitHub organization settings, then Applications, then Installed GitHub Apps. Verify that CodeRabbit is listed and has access to the repository. If you chose “Only select repositories” during installation, the repository might not be included.
-
Check repository activation. Log in to app.coderabbit.ai and verify that the repository is toggled on in the Repositories tab.
-
Check if the PR is a draft. CodeRabbit skips draft PRs by default. Mark the PR as ready for review, or add
drafts: true under auto_review in your .coderabbit.yaml.
-
Check path filters. If your
.coderabbit.yaml excludes all the paths that changed in the PR, CodeRabbit will have nothing to review.
-
Check rate limits. On the free tier, you are limited to 4 PR reviews per hour and 200 files per hour. If you have hit these limits, reviews are queued until capacity is available.
-
Check webhook delivery. In your GitHub repository settings, navigate to Webhooks and inspect recent deliveries for the CodeRabbit webhook. Failed deliveries indicate a connectivity issue.
YAML configuration is not taking effect
- Verify the file name is exactly
.coderabbit.yaml – not .coderabbit.yml and not coderabbit.yaml
- Verify the file is in the repository root, not in a subdirectory
- Verify the file is on the default branch (usually
main), not on a feature branch
- Validate the YAML syntax using an online YAML validator – indentation errors are the most common cause
- Comment
@coderabbitai review on a PR to force CodeRabbit to re-read the configuration
Permission errors
-
For personal accounts: Only the account owner can install GitHub Apps. Verify you own the account.
-
For organizations: App installations require organization owner approval. If you see “Request” instead of “Install,” the request is pending approval from your org owner.
-
For repositories with access restrictions: Some organizations use GitHub App policies to restrict which apps can access specific repositories. Check your organization settings under Third-party access.
Too many or irrelevant comments
- Switch the review profile from
assertive to chill
- Add path filters to exclude generated files, lock files, and build artifacts
- Add global instructions telling CodeRabbit what not to comment on
- Reply to irrelevant comments with explanations – CodeRabbit learns from your feedback
- Enable the knowledge base so CodeRabbit builds repository-specific context over time
Alternative tools for GitHub code review
If CodeRabbit does not fit your needs, several alternatives provide AI-powered code review for GitHub repositories.
CodeAnt AI ($24-40/user/month) is a Y Combinator-backed platform that combines AI PR reviews with SAST scanning, secret detection, IaC security, and DORA metrics in a single tool. The Basic plan at $24/user/month covers AI PR reviews with line-by-line feedback across 30+ languages. The Premium plan at $40/user/month adds security scanning, compliance reporting (SOC 2, HIPAA), and engineering dashboards. CodeAnt AI is a strong alternative for teams that want to consolidate multiple security and review tools into one platform rather than running CodeRabbit alongside separate SAST tools.
GitHub Copilot code review is built directly into the GitHub PR interface and requires no additional app installation for teams already on Copilot Business or Enterprise plans. It provides AI-powered review comments but offers less configuration depth than CodeRabbit – there is no equivalent to .coderabbit.yaml path instructions or review profiles.
PR-Agent by Qodo is an open-source option that runs as a GitHub Action. It gives you full control over the LLM provider and can be self-hosted for teams with strict data residency requirements. You pay for your own LLM API keys rather than a per-user subscription.
For a comprehensive comparison of all available options, see our guide on CodeRabbit alternatives. If you are specifically interested in using GitHub Actions for code review automation, our AI code review in GitHub Actions guide covers multiple tools with production-ready workflow configurations.
Conclusion
The CodeRabbit GitHub integration gives your team instant AI-powered code review on every pull request with a setup process that takes under 10 minutes. Install the GitHub App, select your repositories, open a PR, and CodeRabbit starts posting review comments – no CI/CD configuration, no workflow files, no API keys.
The real value comes from customization. A .coderabbit.yaml file with review instructions tailored to your codebase structure, coding conventions, and security requirements turns CodeRabbit from a generic code reviewer into a context-aware team member that knows your API routes need authentication checks and your database code needs parameterized queries.
Start with the chill review profile on one or two repositories. Let your team interact with CodeRabbit’s comments for two weeks. Then tune the configuration based on real feedback – add path instructions for your most critical directories, exclude files that generate noise, and expand to additional repositories as confidence grows.
For next steps, explore our CodeRabbit setup guide for additional onboarding tips, our CodeRabbit pricing guide to understand when it makes sense to upgrade from the free tier, and our AI code review in GitHub Actions guide to see how CodeRabbit fits alongside other tools in your review pipeline.
Further Reading
Frequently Asked Questions
How do I integrate CodeRabbit with GitHub?
Go to coderabbit.ai and click Get Started Free. Sign in with your GitHub account and authorize the CodeRabbit GitHub App. Select the repositories you want CodeRabbit to review – either all repositories or specific ones. Once installed, CodeRabbit automatically reviews every new pull request within minutes. No GitHub Actions workflow or CI/CD pipeline is required.
Is the CodeRabbit GitHub App free?
Yes. CodeRabbit offers a free tier that covers unlimited public and private repositories with AI-powered PR summaries and review comments. The free tier includes rate limits of 200 files per hour and 4 PR reviews per hour. The Pro plan at $24/user/month removes these limits and adds features like auto-fix suggestions and 40+ built-in linters. Pro is free forever for open-source repositories.
What GitHub permissions does CodeRabbit need?
CodeRabbit requires read access to repository contents, metadata, and pull requests so it can analyze code changes. It also needs write access to pull request comments and checks so it can post review feedback. Finally, it requires webhook events for pull request creation and updates so it knows when to start a review. These are standard permissions for any code review GitHub App.
Does CodeRabbit work with GitHub Enterprise?
Yes. CodeRabbit supports GitHub Enterprise Cloud out of the box. For GitHub Enterprise Server (self-hosted), CodeRabbit offers an Enterprise plan with on-premises deployment options. Contact the CodeRabbit sales team to set up integration with self-hosted GitHub instances that are not publicly accessible.
How do I configure CodeRabbit for specific GitHub repositories?
You can select specific repositories during the GitHub App installation by choosing Only select repositories instead of All repositories. After installation, toggle individual repositories on or off from the CodeRabbit dashboard at app.coderabbit.ai. You can also create a .coderabbit.yaml file in each repository root to apply repository-specific review settings.
What is the .coderabbit.yaml file and where does it go?
The .coderabbit.yaml file is CodeRabbit’s repository-level configuration file. Place it in the root of your repository on the default branch (usually main). It controls review behavior including the review profile (chill, assertive, or followup), path filters for excluding files, path-specific review instructions, and feature toggles like sequence diagrams and PR summaries. CodeRabbit reads this file on every PR automatically.
Why is CodeRabbit not reviewing my GitHub pull requests?
Check these causes in order: the CodeRabbit GitHub App may not be installed on the repository, the repository may be toggled off in your CodeRabbit dashboard, the PR may be marked as a draft (CodeRabbit skips drafts by default), or your path_filters in .coderabbit.yaml may exclude the changed files. Also verify that the app has the necessary permissions in your GitHub Settings under Applications. On the free tier, exceeding 4 reviews per hour queues additional reviews.
Can I use CodeRabbit alongside GitHub Copilot code review?
Yes. CodeRabbit and GitHub Copilot code review serve complementary roles and can run simultaneously on the same repository without conflicts. CodeRabbit provides deeper contextual analysis with customizable review instructions and learning capabilities, while Copilot code review is tightly integrated into the GitHub UI. Many teams run both to get broader coverage.
How do I exclude files from CodeRabbit reviews on GitHub?
Add a path_filters section under reviews in your .coderabbit.yaml file. Use negation patterns with an exclamation mark prefix to exclude paths. For example, adding ‘!/*.lock’ excludes lock files, ‘!/dist/‘ excludes build output, and ‘!/node_modules/**’ excludes dependencies. Changes to path filters take effect on the next PR without any restart.
Does CodeRabbit support GitHub Actions workflows?
CodeRabbit does not run as a GitHub Actions step. Instead, it runs as a standalone GitHub App on its own infrastructure, which means it does not consume your GitHub Actions minutes or require YAML workflow files. It works alongside any existing GitHub Actions workflows you have. If you prefer a GitHub Actions-based approach, consider alternatives like PR-Agent which runs as an Action.
How long does CodeRabbit take to review a GitHub pull request?
CodeRabbit typically completes its review within 1 to 5 minutes after a pull request is opened or updated. Small PRs with fewer than 100 changed lines usually finish in under 2 minutes. Larger PRs with thousands of lines may take up to 5 minutes. On the free tier, if you exceed 4 reviews per hour, additional reviews are queued until capacity is available.
What alternatives to CodeRabbit exist for GitHub code review?
Top alternatives include CodeAnt AI ($24-40/user/month) which combines AI PR reviews with SAST and DORA metrics, GitHub Copilot code review which is built into GitHub natively, PR-Agent (by Qodo) which is open source and runs as a GitHub Action, and Sourcery which specializes in Python code review. Each tool has different strengths depending on your team size, language, and compliance needs.
Originally published at aicodereview.cc


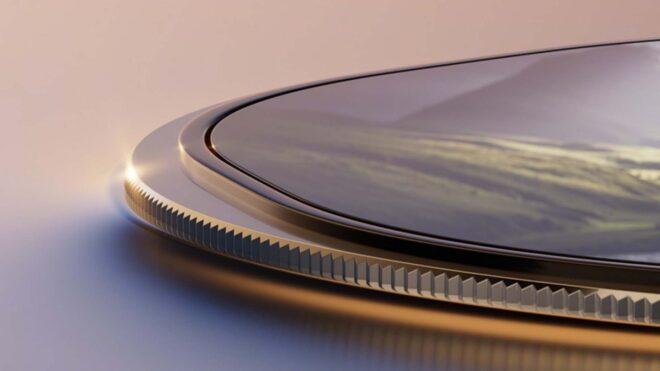
 OPPO tarafından yapılan resmi açıklamaya göre OPPO Find X9 Ultra ve Find X9s Pro, 21 Nisan tarihli Çin etkinliğinde tanıtılacak. Şimdiye kadar çok sayıda sızıntıyla gündeme gelen telefonlardan Find X9 Ultra’nın küresel olarak satışa sunulacağı belirtiliyor. Find X9s Pro ise aktarıldığı kadarıyla Çin pazarına özel bir seçenek olacak. Find X9 Pro’yu Türkiye’de resmi olarak satan OPPO, yeni üst seviye amiral gemisi Find X9 Ultra’yı da Türkiye pazarına getirebilir.
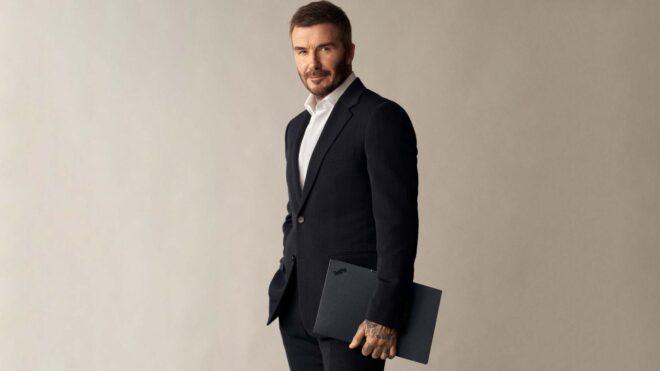
 Lenovo, dünyaca ünlü futbolcu David Beckham ile iş birliği gerçekleştirdiğini duyurdu. Resmi açıklamaya göre Beckham; kulüplerden oyunculara, hakemlerden taraftarlara kadar geniş bir ekosistemi kapsayan, yapay zeka destekli çözümler üzerinde Lenovo ile birlikte çalışacak. Yapılan bu anlaşma teknoloji ile sporun kesişiminde yeni bir dönemin kapılarını aralarken; Lenovo’nun yalnızca cihaz üreticisi değil küresel ölçekte deneyimleri dönüştüren bir teknoloji sağlayıcısı olan konumunu da pekiştiriyor. Gelişme hakkında konuşan Lenovo Türkiye Genel Müdürü Emre Hantaloğlu; “Lenovo Türkiye olarak bu iş birliğini, yapay zekanın günlük hayat ve iş süreçlerine somut katkısını görünür kılan güçlü bir platform olarak değerlendiriyoruz. Spor gibi yüksek tempo ve veri yoğunluğu barındıran bir alanda geliştirilen çözümler; karar alma hızından operasyonel verimliliğe kadar pek çok başlıkta yeni standartlar oluşturuyor. David Beckham ile hayata geçen bu küresel iş birliği, yapay zekanın yalnızca ilham veren bir kavram olmadığını; ölçülebilir fayda üreten, ölçeklenebilir bir teknoloji olduğunu net biçimde ortaya koyuyor. Biz de Türkiye’de bu yaklaşımı iş […]
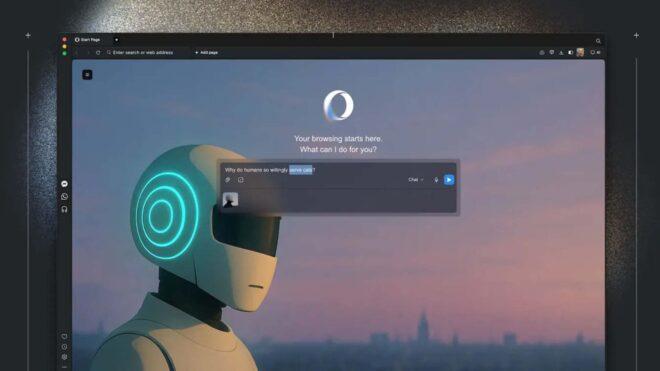
 Şirket tarafından “Ajan tarayıcısı” olarak tanımlanan Opera Neon, Anthropic tarafından geliştirilen açık kaynak MCP (Model Context Protocol) protokolüne destek vermeye başladı. Bu destek sayesinde ChatGPT, Claude, Lovable, n8n ve OpenClaw gibi yapay zeka araçları sekmelere rahatlıkla erişebiliyor, sayfalarla etkileşim kurabiliyor ve kullanıcı adına işlem gerçekleştirebiliyor. MCP; yapay zeka asistanlarının farklı sistemlerdeki verilere (içerik depoları, iş araçları, geliştirme ortamları gibi) kolaylıkla bağlanmasını sağlayan evrensel bir protokol olarak görev yapıyor. Amaç, yapay zeka modellerinin daha anlamlı ve bağlama uygun yanıtlar üretebilmesini sağlamak. Anthropic, yapay zeka modellerinin kendi başlarına güçlü olsalar da veri kaynaklarından kopuk olmaları nedeniyle potansiyellerine kıyasla kısıtlı kaldıklarını; her yeni veri kaynağı için ayrı entegrasyon gerekmesinin ölçeklenebilirliği zorlaştırdığını aktarıyor. MCP, bunu ortadan kaldırarak tek bir açık standart üzerinden daha basit, güvenilir ve yaygın bir çözüm sunuyor. MCP desteğiyle daha da güçlenen Opera Neon hakkında şirketten yapılan resmi açıklamada şunlara yer verilmişti: “Neon, yalnızca web’de gezinmeyi sağlamakla kalmıyor; aynı zamanda kullanıcıların […]
 Spor platformu Strava, aralarında Türkçenin de bulunduğu 10 yeni dil desteğini yayına alarak platformdaki toplam dil sayısını 24’e çıkardı. Bu konuda yapılan resmi açıklamada, “Aktif bireylerin bir araya geldiği ve 195 milyondan fazla kullanıcısı bulunan dünyanın lider spor platformu Strava, aralarında Türkçenin de yer aldığı on yeni dil desteğini sunduğunu duyurdu. Bu önemli adım, şirketin yerel toplulukların kendi dillerinde bağ kurmalarını sağlama, motivasyonlarını artırma ve sportif hedeflerine ulaşmalarına destek olma konusundaki küresel kararlılığını bir kez daha ortaya koyuyor. Platforma Türkçe ile birlikte eklenen yeni diller Çekçe, Danimarkaca, Malayca, Norveççe Bokmal, Lehçe, İsveççe, Tagalogca, Tayca ve Vietnamca olarak açıklandı. Bu genişleme sayesinde Strava, desteklediği toplam dil sayısını 24’e çıkararak küresel erişilebilirliğini en üst seviyeye taşıdı.” ifadelerine yer verildi. Gelişme hakkında konuşan Strava Pazarlama Direktörü (CMO) Louisa Wee ise yeni dillerin eklenmesiyle platformun her zamankinden daha uluslararası bir yapıya büründüğünü belirterek, kullanıcıların artık tam Strava deneyimini kendi ana dillerinde yaşayabileceklerini ifade etti. Wee […]
 Vodafone Türkiye CEO’su Engin Aksoy, kişisel X hesabından “5G” teknolojisi için iddialı açıklamalarda bulundu. “Bugün öğleden sonra 5G teknolojisiyle tanışıyoruz” diyen Aksoy, “81 ile ve 922 ilçede aynı anda 5G hizmetini vererek en geniş kapsamayı sağlamayı hedefliyoruz.Vodafone’nun dünyada yaptığı en büyük 5G lansmanını yapacağız. Bakanlığımızın 2 yılda yurt geneline yayma hedefine ilk günden büyük oranda ulaşacağız. Bugüne kadar Türkiye’ye 500 milyar TL’nin üzerinde yatırım yaptık. Cumhuriyet tarihinin en büyük 2 uluslararası yatırımından birisiyiz. 2025 yılında iki farklı uluslararası kuruluşun yaptığı ölçümlerde Türkiye’nin en iyi mobil altyapısına sahip olduğumuz tescillendi. 5G’ye hazırız.” diye konuştu. “İnanması zor ama gerçek; Vodafone 5G altyapısı ilk günden Almanya’nın 5 yılda ulaştığı ölçek ve kalitede hizmet verecek.” diyen Aksoy, “Sınırsız internet paketlerinden, indirimli cep telefonlarına, evde fiber kalitesinde “tak-çalıştır” mobil internet ürünümüz Redbox’a sayısız fırsatı tüm müşterilerimize sunmaya başladık. Ülkemize hayırlı olsun.” dedi.
 2027 ya da 2028 yılında satışa sunulması beklenen PlayStation 6 için güvenilir kaynak Kepler_L2 tarafından yeni iddialar ortaya atıldı. Modelin disk sürücüsü olmadan 1 TB SSD ile geleceğine ve 700 dolardan satışa sunulabileceğine (mevcut parça maliyeti 760 dolar olarak hesaplanıyor; toplu alım indirimiyle Sony’nin konsolu 700 dolara satabileceği düşünülüyor) işaret eden kaynak, PS6 SDK’sinin nöral doku sıkıştırma altyapısına destek vermesi halinde oyun boyutlarının hatırı sayılır oranda azaltılabileceğini de belirtiyor. “Oyun boyutları PS5’tekinden bile daha küçük olabilir.” diyen kaynak, 1 TB SSD’nin bu konuda beklenen adım atılırsa büyük bir sorun olmayacağını aktarıyor. SSD ve RAM fiyatlarındaki artış nedeniyle PS6’ya satış fiyatını aşırı artırmadan 2 TB SSD koyması çok olası görünmeyen Sony, geçtiğimiz hafta PlayStation 5 serisine zam yaptığını duyurmuştu.